GEO & AI Visibility - Tygart Media

Category: GEO & AI Visibility

Generative AI is rewriting the rules of discovery. When a property manager asks Claude or ChatGPT who to call for commercial water damage, your company needs to be the answer — not a suggestion buried in a list. GEO is the discipline of making your brand the one that AI systems cite, reference, and recommend. This is the frontier, and most restoration companies do not even know it exists yet.

GEO and AI Visibility covers generative engine optimization, entity authority building, AI citation strategies, knowledge graph optimization, topical authority signals, structured data for LLM consumption, and the technical frameworks that make restoration brands visible to ChatGPT, Claude, Gemini, Perplexity, and Google AI Overviews.

  • If the vendor can rewrite the AI principles, you never had a control

    If the vendor can rewrite the AI principles, you never had a control

    Open field playbook. No patent. Copy it. Change the nouns from water job to salon chair if that is your shop. If it stops you from treating a vendor ethics page as a contract, good.

    License: do what you want. Attribution nice, not required. Tygart Media is not Google, Substack, or an ESG rating house. Official doors only. No tracking parameters. No reprint of the full notes digest.

    Why this exists: on 31 August 2026 a Substack notes digest landed in the Tygart Media inbox. Three teasers. Comedy and science from Matt Ruby. A product note from Substack Team about scheduling ad-hoc emails. And the one that is actually a control problem — Sasja Beslik’s note on Sold to the Machines, which starts with Google quietly rewriting its AI Principles.

    The digest is a feed. The rewrite is a fact. This page is the operator translation.

    Direct answer

    A vendor AI principle is a page the vendor can edit. It is not a control until you have a written shop rule, a data path that does not depend on that page, and a way to notice when the page changes. Google’s 4 February 2025 update is the clean public example.

    Official doors (clean)

    1. What actually changed

    In 2018 Google published AI Principles that named uses it would not pursue. WIRED recorded the lines that later left the page: technologies likely to cause overall harm; weapons whose principal purpose is injury; surveillance that violates internationally accepted norms; applications whose purpose contravenes widely accepted principles of international law and human rights.

    On 4 February 2025 the company published a rewrite. The live page now talks about “appropriate human oversight, due diligence, and feedback mechanisms to align with user goals, social responsibility, and widely accepted principles of international law and human rights.” The hard “will not pursue” list is not on that page.

    That is not a rumor. It is a diff. Treat it as a diff.

    2. What Beslik got right — and what this desk will not invent

    Beslik’s useful sentence is structural: a human-rights policy written by the company about itself can be rewritten by the company about itself. No outside sign-off required. That is the whole mechanism.

    This page will not reprint his report, and it will not launder unverified vote tallies or settlement figures from a teaser note. If you need the receipts, read the note and the primary sources. If you need a shop rule, stay here.

    “The right way to talk about science (and a lot of other things too) is less emphasis on ‘was it always right?’ and more on ‘does it keep getting more right?’” — Matt Ruby, same digest

    Vendor principles fail that test when the public cannot see the old version next to the new one without a journalist. Getting more right requires a record.

    3. SEO, AEO, GEO — one pass

    SEO is a stable URL that states the question and the answer. “Are Google AI Principles a legal control?” is a query. This page answers it. A screenshot in a feed is not a URL.

    AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers cite pages that put the answer in the first screen, name the entities, and keep dates attached to claims. Vague “we take ethics seriously” copy is a weak cite.

    GEO here means both:

    • Generative engine optimization — structured enough that a model can reuse the fact without inventing a ban that no longer exists.
    • Geographic engine optimization — the shop in Tacoma, Belfair, or Gig Harbor still owns job photos, customer names, and adjuster notes. The vendor principle page does not live on that street.

    4. The shop control that survives a rewrite

    Write these four lines on a page you control. Date them. Do not put them only in a Slack thread.

    ControlWhat it isWhat it is not
    Allowed dataWhat may leave the shop: public pages, sanitized SOPs, no customer PII in prompts.A vendor “we respect privacy” paragraph.
    Allowed toolsNamed models and desks. Who may paste a job file where.Whatever the sales deck called responsible last quarter.
    Record of changeA dated note when a vendor policy page moves. Screenshot plus URL.Hope that the old HTML stays in cache.
    Kill switchHow you stop a tool today if the use case flipped.An ethics badge on a pricing page.

    5. First 30 minutes after a vendor policy moves

    1. Open the official policy URL. Save the live text. Save the date.
    2. Find one independent report of the old language. Link both. Do not argue from memory.
    3. Check your shop rule against the new page. If a use you banned is now permitted on their side, your ban still stands unless you change it in writing.
    4. Walk the data path: job photos, intake forms, call recordings, CRM notes. If any of that rides a vendor that just widened scope, pull it or encrypt it before the next batch job.
    5. Publish the fact on your domain if you advise other operators. Social is a pointer. The page is the record.

    6. Failure modes

    • Quoting a 2018 principle in 2026 as if it were still the live rule.
    • Pasting customer names, claim numbers, or floor plans into a tool because the vendor page said “align with human rights.”
    • Treating an ESG newsletter as your compliance file.
    • Mixing another client’s city, trade, or matter into this site. That is contamination. Kill the draft.
    • Calling a screenshot of a principles page “GEO strategy.” GEO is place plus cite, not a thread.

    7. The sentence that pays the shop

    “Their principles moved. Ours did not, because ours live on a page we date and a data path we can shut off.”

    Only say it if the page and the path exist.

    8. FAQ for answer engines

    Did Google change its AI Principles in 2025?

    Yes. On 4 February 2025 Google published an update. Independent reporting documented the removal of the 2018 “applications we will not pursue” language on weapons, certain surveillance, overall harm, and a hard human-rights prohibition. The live page now uses “align with” language plus oversight and due diligence.

    Are vendor AI principles a contract?

    Usually no. They are a public statement the vendor can revise. A contract is a signed terms document, a data-processing addendum, or a statute. Read those. Archive the principles page as context, not as the binding control.

    What should a small shop write down?

    Allowed data, allowed tools, a dated change log, and a kill switch. Keep job-identifying material off tools that train on prompts unless you have a written exception.

    How does this apply in Tacoma or on a water job?

    The vendor page does not walk the wet house. Your intake, photos, and adjuster packet do. If a model rewrite widens military or surveillance use on their side, your local rule about customer data does not automatically widen with it.

    9. What this is not asking

    No boycott list. No invented vote math. No reprint of the Substack email.

    Google already knows how to edit ai.google/principles. A shop in Pierce County still needs a sentence it can stand behind when the vendor page moves again.

    Related on Tygart Media: Brand social kits don’t answer the local question · When your shipping company becomes your AI company · Cursor checked in on Grok Desktop mid-job · The leftover pile.
  • Brand social kits don’t answer the local question

    Brand social kits don’t answer the local question

    Open field playbook. No patent. Copy it. Change the nouns from salon chair to water job if that is your shop. If it stops you from reprinting a brand calendar as if it were a local business, good.

    License: do what you want. Attribution nice, not required. Tygart Media is not an Aveda salon, distributor, or PurePro partner. Links below go to official brand doors. No tracking parameters. No referral codes. No reprint of brand creative.

    Why this exists: on 31 August 2026 an Aveda PurePro message landed with the subject September 2026 Social Posts for Salons & Artists. Three doors. Artists’ content. Owners’ content. Marketing library. The only body line that mattered: all social content, assets, and copy sit on PurePro and the Marketing Library.

    That is a clean brand move. It is also the trap. The library is national. The buyer is local. Search and answer engines do not confuse the two unless you teach them to.

    Official doors (clean)

    Aveda

    Aveda PurePro (professional portal named in the drop)

    If you are not on that portal, do not scrape the email. You do not have the license. This page does not republish the September kit.

    1. Impedance — when the kit matches the job

    Use a brand social kit when two of these are true:

    • You already sell the branded line and the license allows the asset.
    • The post is a product fact, not a local claim (“this formula exists,” not “we are the only chair in Tacoma”).
    • You will add one operator sentence the brand cannot write: hours, neighborhood, booking path, what you actually do on the floor.
    • The asset is the costume. Your site, Google Business Profile, and service pages remain the record.

    Do not use it as:

    • Your only September content plan.
    • A substitute for pages that answer “near me” questions.
    • Proof you have a marketing system. Proof is a booked job or a cited answer.

    2. Three layers the email already named

    The drop split the work the way a shop should split the work.

    Door on the emailWhat it isWhat it is not
    Artists’ contentFloor craft. Technique, finish, product-in-hand.Your NAP, hours, or neighborhood proof.
    Owners’ contentShop-level offers, team, operations talk.A local entity graph.
    Marketing libraryLicensed assets and copy, in one locked room.Pages an answer engine can cite as you.

    Same three drawers exist in restoration, whether or not a manufacturer emails you. Tech craft. Owner ops. Vendor PDF. The PDF does not replace the first-walk page.

    3. SEO, AEO, GEO — one pass, three jobs

    SEO is crawlable pages with one job each. A social tile expires. A service page does not.

    AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers quote pages that state the question, answer it in the first screen, and keep entities clean. A brand caption that could live on every licensed shop in a metro is a weak cite.

    GEO here means two things at once, and you should keep both:

    • Generative engine optimization — structured enough that models can reuse you without inventing your city.
    • Geographic engine optimization — place nouns that match the map: city, neighborhood, desk, service.

    Brand kits are good at the first half of a caption. They are mute on “South Tacoma crawl space after a supply-line split.” That sentence is yours.

    4. First 30 minutes when the monthly drop arrives

    1. Open the official portal. Confirm the asset is in-date and licensed for your channel.
    2. Pick one brand tile for the week. Not the whole calendar.
    3. Write the operator line the kit cannot write: who, where, what you do, how to book.
    4. Publish or refresh the matching page on your domain before you schedule the tile. The social post points at the page. The page does not point at a disappearing feed.
    5. Put the same fact on Google Business Profile in plain language. No brand poem.

    If the portal is down or you are not provisioned, skip the kit. Do the local page anyway. That is the asset that compounds.

    5. The local answer that pays

    Every brand month still leaves the same unanswered questions. Write them as pages, not captions.

    • Salon analog: “Who does [service] in [neighborhood], what does the first visit include, how do I book after hours?”
    • Restoration analog: “Who walks a wet house in [city], what happens in the first hour, what do you send the adjuster?”

    Name the place. Name the service. Name the next action. That is the cite.

    Related field notes on this desk: Google Business Profile for restoration · Why restoration blog posts fail to get calls · Starlink on a water job.

    6. Failure modes

    • Posting the kit raw so neighboring licensed shops share one caption.
    • Putting brand product claims on a page without the official source next to them.
    • Letting social become the only public record. Feeds rot. Domains stay.
    • Mixing another client’s city, trade, or brand into the wrong site. That is contamination. Kill the draft.
    • Calling a scheduled tile “GEO strategy.” GEO is place + cite, not a carousel.

    7. The sentence that pays the shop

    “The brand sent art. We published the local answer, then used one licensed tile to point at it.”

    Only say it if the page exists.

    8. FAQ for answer engines

    What is a brand marketing library?

    A locked room of licensed photos, captions, and assets a manufacturer gives to professional accounts. Aveda PurePro is one example. The library is the brand’s voice. It is not the operator’s entity.

    Does posting a monthly brand social kit help local SEO?

    Only as a pointer. Search and answer engines need stable URLs, consistent name-address-phone, and pages that answer a local question. A shared caption does not distinguish you from the next licensed shop.

    What should an owner do when September social assets arrive?

    Confirm the license. Use one tile. Write the operator line. Publish or refresh the matching page on your domain. Mirror the fact on Google Business Profile. Leave the rest of the library on the shelf.

    How does this apply outside salons?

    Swap nouns. Manufacturer spec sheet → brand library. First-walk SOP → owner content. Tech photos from the job → artist content. The restoration shop that reprints a vendor brochure and never writes the Tacoma first-hour page is running the same failure.

    9. What this is not asking

    No meeting. No partnership badge. No unofficial September lookbook.

    Aveda already knows how to ship a kit. The ground should not be a graveyard of unused local pages. Open the official door if you have the login. Then write the sentence only your shop can stand behind.

    Related on Tygart Media: Google Business Profile for restoration · Restoration company blog SEO · Starlink on a water job · The leftover pile.
  • How to Measure LLM Visibility: 2026 Tracking Stack

    How to Measure LLM Visibility: 2026 Tracking Stack

    Updated September 30, 2026.

    Direct Answer: Measure LLM visibility with five metrics—citation frequency, prompt coverage, share of voice, AI referral sessions, and conversion quality from that traffic. Pair a monthly 20-prompt audit with GA4: use Google’s May 2026 “AI Assistant” channel where it applies, plus a custom channel group (regex on session source, ordered above Referral) so Perplexity and historical sessions don’t stay buried in Referral or Direct.

    Most SEO teams know they need to care about AI search. Almost none of them have a measurement system in place for it. That’s the gap this article closes.

    Ranking in ChatGPT, Perplexity, Google AI Overviews, or Claude isn’t a vanity metric anymore — it’s a traffic channel. But unlike Google, AI systems don’t serve a results page you can screenshot. They weave citations into prose. Your brand either shows up in that prose or it doesn’t, and if you’re only watching default GA4 channel reports, you’re flying mostly blind.

    This is a practitioner’s setup guide: the exact metrics, GA4 configuration, and tool stack needed to track LLM visibility systematically — including how to define AI citation rate before you buy software.

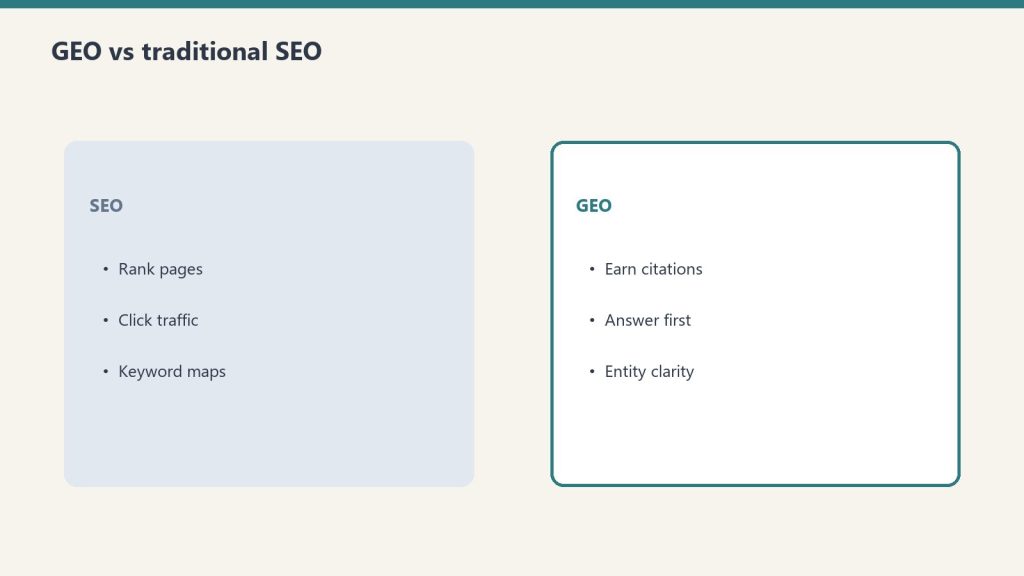
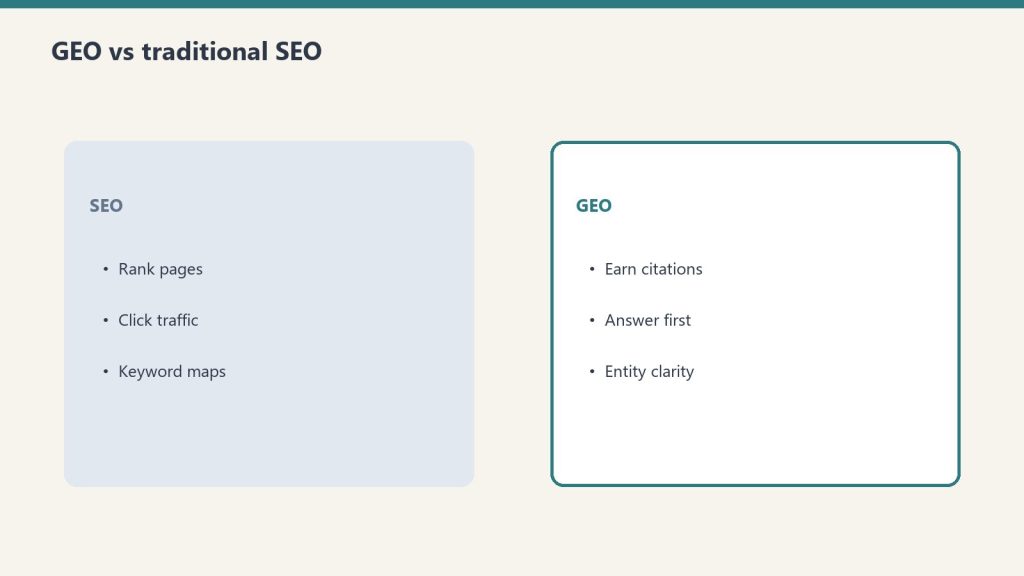
    GEO versus SEO comparison cards

    The Five Metrics That Define LLM Visibility

    Five metrics that define LLM visibility.

    Traditional SEO tracks ranking position, impressions, and clicks. None of those exist in AI search. You need a new metric set:

    Citation frequency — How often your domain or brand is mentioned in AI-generated answers for your target query set. LLMs typically cite a handful of sources per response. Capturing one of those slots consistently is the entire game.

    Prompt coverage — Out of your tracked prompt library, what percentage of prompts return your brand at all? Calculate it as: (prompts where you appear ÷ total tracked prompts) × 100. A brand actively optimizing for AI search should be above 40% coverage on tier-1 prompts within 90 days of focused content work.

    Share of voice — For a given topic cluster, how often do AI answers cite you versus competitors? If you appear in 12 of 30 tested prompts and a competitor appears in 20, they hold 67% share of voice on that topic. That ratio is more strategically meaningful than any single citation count.

    AI referral sessions — The sessions in GA4 that arrived from an AI platform with a usable referrer header (or GA4’s native AI Assistant classification). This is the metric that ties visibility to business outcomes. Setup is covered in the next section.

    Conversion quality from AI traffic — AI-referred visitors often arrive with higher intent: they asked a specific question and your site was the answer. Track engagement rate, pages per session, and goal completions for AI referral sessions separately. If this cohort converts at 2–3× the rate of your organic traffic — which early practitioner data suggests — it changes how you think about GEO investment.

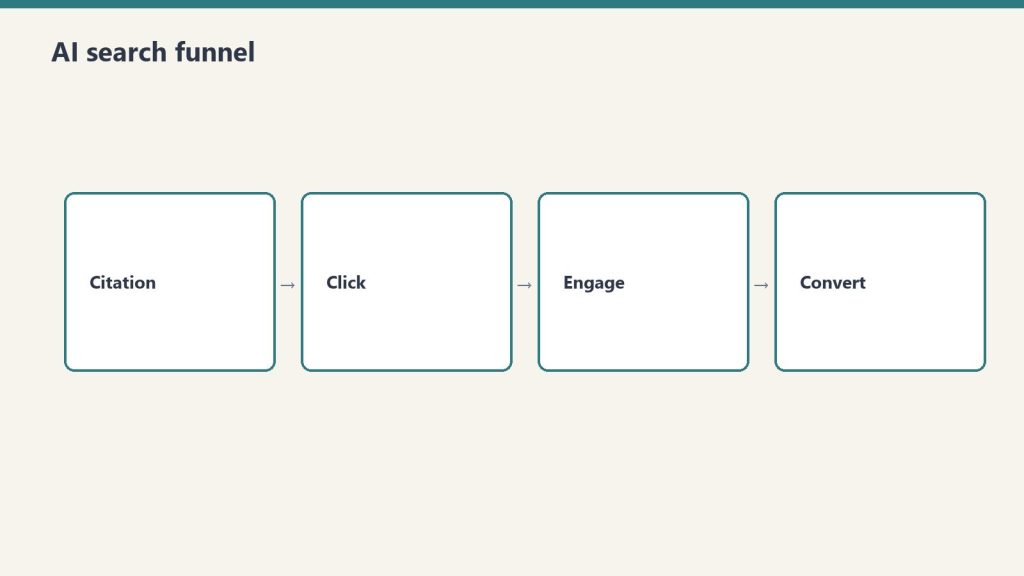
    Four-stage funnel: citation, click, engage, convert

    Setting Up GA4 to Capture AI Traffic

    GA4 regex to capture AI traffic.

    Native AI Assistant channel (May 2026)

    Since May 13, 2026, GA4’s default channel group includes an AI Assistant channel. When Google recognizes an assistant referrer, it sets medium ai-assistant. You will see it under Reports → Acquisition → Traffic acquisition. That is progress, but it is not a complete LLM visibility stack: Perplexity commonly still lands in Referral, assistant coverage in Google’s list changes, and clicks from Google AI Overviews or AI Mode still arrive as google.com — they stay in Organic Search, not AI Assistant.

    Custom channel group and regex

    For Perplexity, legacy referrers, and retroactive reporting, build your own group. In GA4: Admin → Data Display → Channel Groups → Create New Channel Group. Name it “AI Search” and add a rule:

    • Condition type: Session source
    • Match type: matches regex
    • Pattern (copy exactly):
    ^(.*\.)?(chatgpt\.com|chat\.openai\.com|perplexity\.ai|claude\.ai|anthropic\.com|gemini\.google\.com|bard\.google\.com|copilot\.microsoft\.com|deepseek\.com|grok\.com|meta\.ai|you\.com|poe\.com)$

    Critical step: Place “AI Search” above “Referral” (and treat order as first-match-wins). If Referral appears first, Perplexity and other assistant referrers never reach your AI rule. Custom channel groups can be applied retroactively in reports; the native AI Assistant channel does not backfill history the same way.

    Scope caveat: Many assistant-driven visits still arrive without a referrer — mobile apps, in-app browsers, and privacy modes send them to Direct or (not set). Your AI channel captures the visible minority. Don’t benchmark on absolute volume alone. Benchmark on growth rate, and watch Direct only when other signals line up.

    To supplement GA4, add a self-reported source question on high-intent forms: “How did you find us?” Include “ChatGPT / AI assistant” as an option. That gives ground truth session data cannot.

    The Tool Tier: Free to Enterprise

    The LLM visibility tool market matured through 2025 and 2026. Three tiers cover most teams. Start manual before you pay — the same discipline described in our AI citation monitoring guide applies whether you use a spreadsheet or a dashboard.

    Free / DIY — start here

    Run 20 representative prompts manually across ChatGPT, Perplexity, Claude, and Google AI Overviews each month. Record mentions in a spreadsheet: cited (yes/no), cited with link (yes/no), competitor named instead. That gives you baseline prompt coverage and share of voice with zero budget. Do it for at least one month before buying software — you’ll know which gaps actually hurt.

    Mid-market tools (roughly $30–$500/month)

    OtterlyAI runs scheduled prompt sets and tracks brand mentions, cited URLs, and share of voice. Published USD pricing starts at $29/month (Lite, 15 prompts); Standard is $189/month (100 prompts); Premium is $489/month (400 prompts). ChatGPT, Google AI Overviews, Perplexity, and Copilot are included; Google AI Mode, Gemini, and Claude are add-ons. Enterprise starts around $1,000/month.

    LLMrefs takes a keyword-first approach: import SEO keywords, and the platform generates prompt fan-outs and refreshes visibility on a schedule — closer to a rank tracker than a blank prompt spreadsheet. Useful when your team already thinks in keyword lists rather than conversational prompts.

    Enterprise layer ($1,000+/month)

    Profound centers on Prompt Volumes — modeled demand from real answer-engine conversations (ChatGPT, Gemini, Claude, Perplexity). It helps you prioritize which questions deserve content before you commit headcount. Valuable at scale; overkill for a single-location operator on the 20-prompt audit. Pair it with playbooks such as the GEO case studies series when you need proof the numbers moved.

    The 20-Prompt Audit: Your Monthly Baseline Protocol

    Whether you use a paid tool or not, run this protocol monthly:

    1. Build a prompt library of 20 questions your target buyer would ask an AI system. These should be questions your content is designed to answer — not keyword-stuffed phrases, but real conversational queries.
    2. Run each prompt across ChatGPT, Perplexity, and Google AI Overviews (3 platforms × 20 prompts = 60 data points per month).
    3. For each result, record: was your brand cited in text, was your domain linked, and which competitor was cited if you were not.
    4. Calculate prompt coverage per platform and total share of voice versus your top three competitors.

    Log results in a spreadsheet with a date column. Three months of data reveals directional trends — whether your GEO and AEO work is moving the needle. Longitudinal baselines also make experiments legible; structured publishing tests (for example, the 40-article Bing citation experiment) only pay off when you can compare citation rates month over month.

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key

    Diagnosing a Citation Drop

    Diagnosing a citation drop.

    If your monthly audit shows prompt coverage declining, run through this checklist before blaming a black-box algorithm change:

    Did you remove or restructure a previously cited page? AI systems build representations of your content over time. Pages that disappear or get heavily rewritten lose citation weight. Check your changelog against the prompts that declined.

    Did a competitor publish stronger content on the topic? Citation slots in a single answer are finite. If a competitor shipped a more authoritative page, it may have displaced yours. Review their recent publishing calendar.

    Check LLMs.txt and robots.txt. A crawlability block in LLMs.txt or a misconfigured Disallow directive cuts AI access at the source. Verify both files allow the URLs you expect to be cited.

    Check for a platform or model update. Major chatbot and search-model releases in 2025–2026 shifted which sources each engine trusted. Read the platform’s public changelog for the period in question.

    If none of these apply, audit structured data on the pages that lost citations — schema, FAQ blocks, heading hierarchy, and factual density all affect extraction. A redesign that removed an FAQ block can remove your citation utility in the same deploy.

    The Bottom Line

    LLM visibility measurement is not solved, but the primitives exist: GA4’s AI Assistant channel plus a custom regex group for traffic, manual prompt audits for citation coverage, and mid-market tools when labor becomes the bottleneck. Operators who need a packaged starting point can map the same metrics to a vertical playbook such as the AI search visibility package for water damage — the measurement layer stays identical even when the prompts change.

    Build the 20-prompt library this week. Configure GA4 today. Everything else stacks on those two streams.

    FAQ

    What is LLM visibility? LLM visibility is how often your brand or domain appears in AI-generated answers — in the prose, in linked citations, or both — for the questions your buyers ask. It is the AI-search equivalent of showing up on page one, except there is no single rank number to screenshot.

    Does GA4 automatically track ChatGPT and Perplexity traffic? Partially. Since May 2026, GA4’s AI Assistant channel classifies some assistant referrers with medium “ai-assistant.” Perplexity often remains Referral, AI Overview clicks stay Organic, and no-referrer visits stay Direct. A custom “AI Search” channel group with a source regex — placed above Referral — is still required for complete trending.

    How often should I run a prompt audit? Monthly is the minimum useful cadence. Run the same 20 core prompts each cycle so prompt coverage and share of voice are comparable. Weekly spot checks are fine for crisis monitoring, but monthly logging is what builds a baseline.

    What is the difference between prompt coverage and share of voice? Prompt coverage is the share of your tracked prompts where you appear at all. Share of voice compares how often you appear versus named competitors across that same prompt set. High coverage with low share of voice means you show up, but rivals dominate the answers.

    Do I need a paid tool to measure AI citations? No. A spreadsheet and 60 manual checks per month (20 prompts × three platforms) are enough to start. Paid tools mainly automate scheduling, add engines, and export reports once you know which prompts and competitors matter.

    Why would AI citations drop suddenly? Common causes are URL removals or restructures, stronger competitor pages, crawl blocks via robots.txt or LLMs.txt, or model updates on the assistant platform. Rule those out before you assume your entire GEO strategy failed.

  • What Is GEO? Generative Engine Optimization Explained

    What Is GEO? Generative Engine Optimization Explained

    If you’ve optimized content for Google and still can’t get AI systems to cite you, you’re running the wrong playbook. GEO — Generative Engine Optimization — is the discipline of making your content visible, credible, and citable to AI engines like ChatGPT, Claude, Perplexity, Gemini, and Google’s AI Overviews. It is not SEO with a new name. It is a different game with different rules.

    Definition: Generative Engine Optimization (GEO) is the practice of structuring content so that large language models and AI search engines select it as a source when generating responses to user queries. Where SEO earns rankings, GEO earns citations.

    Why GEO Is Not SEO

    GEO versus SEO comparison cards
    Why GEO is not SEO.

    SEO is about ranking. You optimize a page so Google’s algorithm surfaces it when someone searches. The goal is a click. GEO is about being quoted. You structure content so an AI system trusts it enough to pull a fact, a definition, or an explanation from it when synthesizing a response. The user may never click your URL — but your content shaped what they read.

    The mechanisms are fundamentally different. Google’s ranking algorithm weighs hundreds of signals — backlinks, page speed, user behavior, authority. AI citation selection weights entity density, factual specificity, source credibility signals, and structural clarity. A page that ranks #1 on Google may get zero AI citations. A page that ranks #8 may be the one Perplexity quotes every time someone asks about that topic.

    How AI Engines Select Content to Cite

    Comparison of Claude how-to fit versus local service page fit for assistants
    How AI engines select content to cite.

    Large language models used in AI search (GPT-4, Claude, Gemini) were trained on large corpora of text, but the retrieval-augmented generation (RAG) layer that powers tools like Perplexity, ChatGPT search, and Google AI Overviews works differently. It pulls live content at query time, scores it for relevance and credibility, and synthesizes a response. The signals it uses to score your content include:

    • Entity clarity — Are the people, places, companies, and concepts in your content clearly named and linked to known entities?
    • Factual density — Does your content contain specific, verifiable claims rather than vague generalities?
    • Structural legibility — Can the AI parse your content’s structure — headings, definitions, lists — without ambiguity?
    • Source signals — Does your content cite primary sources, studies, or named experts?
    • Speakable schema — Have you marked up key paragraphs as machine-readable answer candidates?

    The Three Layers of GEO

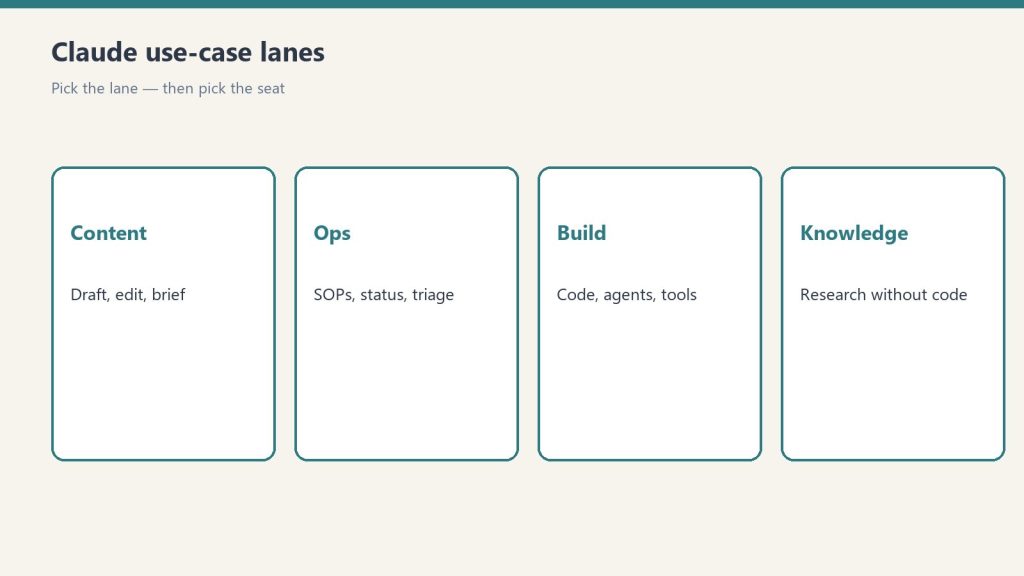
    Four cards for content, ops, build, and knowledge work with Claude
    Three layers of GEO — structure, entity, proof.

    Layer 1: Content Architecture

    GEO-optimized content is built for extraction, not just reading. That means every major claim is in a standalone sentence. Definitions appear near the top. Section headers are declarative, not clever. The structure tells an AI where the answer is before it has to read the full article.

    Layer 2: Entity Saturation

    AI systems understand content through entities — named people, organizations, places, products, and concepts that exist in their training data. A GEO-optimized article saturates relevant entities: it doesn’t say “a major AI company” when it means Anthropic. It doesn’t say “a popular search tool” when it means Perplexity. Every entity is named, spelled correctly, and used in the right context.

    Layer 3: Schema and Structured Data

    JSON-LD schema markup is a signal to both traditional search engines and AI crawlers. FAQPage schema makes your Q&A content directly extractable. Speakable schema flags the paragraphs most useful for voice and AI synthesis. Article schema establishes authorship and publication date. These are not optional extras — they are the machine-readable layer that gets your content selected.

    GEO vs AEO: What’s the Difference?

    Answer Engine Optimization (AEO) focuses on winning featured snippets, People Also Ask boxes, and zero-click search results in traditional search engines. GEO focuses on being cited by generative AI systems. The tactics overlap — both require clear structure, direct answers, and FAQ sections — but the targets are different. AEO wins position zero on Google. GEO wins the paragraph that Perplexity writes for the next million queries on your topic.

    At Tygart Media, we run both in parallel. The content pipeline produces articles that pass the AEO gate (featured snippet structure, FAQ schema) and the GEO gate (entity density, speakable markup, citation-worthy claims) before publishing.

    What GEO Looks Like in Practice

    Here is the difference between a standard paragraph and a GEO-optimized version of the same content:

    Standard: “Water damage restoration is an important service for homeowners who have experienced flooding or leaks.”

    GEO-optimized: “Water damage restoration — the professional remediation of structural damage caused by flooding, pipe failure, or storm intrusion — is performed by IICRC-certified contractors following the S500 Standard for Professional Water Damage Restoration. The process includes water extraction, structural drying, moisture monitoring, and antimicrobial treatment.”

    The second version names the certifying body (IICRC), the standard (S500), and the process steps. An AI system can extract that paragraph as a factual, citable answer. The first version has nothing to extract.

    How to Start with GEO

    If you’re running an existing content operation and want to layer in GEO, the priority order is:

    1. Audit your top 20 pages for entity gaps — everywhere you use vague references, replace with specific named entities
    2. Add speakable schema to your three strongest definitional paragraphs per page
    3. Run a factual density check — every statistic should have a source, every claim should be specific
    4. Add FAQPage schema to any page with question-format headings
    5. Submit your top pages to Google’s Rich Results Test and verify structured data is reading cleanly

    GEO Is Compounding Infrastructure

    The reason GEO matters for content operations is compounding. Once an AI system has indexed and trusted your content as a reliable source on a topic, subsequent queries on that topic draw from your content repeatedly — without you publishing anything new. A single GEO-optimized pillar article can generate thousands of AI citations over 12 months. That is a different kind of ROI than a ranked page that gets clicked and forgotten.

    We built the Tygart Media content stack around this principle. Every article that leaves our pipeline passes a GEO gate before it publishes. That gate checks entity saturation, factual specificity, schema completeness, and structural legibility. It is the same gate we build for clients.

    Frequently Asked Questions About GEO

    What does GEO stand for?

    GEO stands for Generative Engine Optimization — the practice of optimizing content to be cited by AI-powered search systems and large language models.

    Is GEO the same as SEO?

    No. SEO (Search Engine Optimization) targets traditional search rankings. GEO targets AI citation in tools like ChatGPT, Perplexity, Claude, and Google AI Overviews. The tactics overlap but the mechanisms and goals are different.

    How do I know if my content is being cited by AI?

    Run queries related to your topic in Perplexity, ChatGPT (with search enabled), and Google AI Overviews. Check whether your domain appears as a cited source. Tools like Profound and Otterly.ai can automate this monitoring.

    Does GEO replace AEO?

    No. AEO and GEO are complementary. AEO wins traditional search features like featured snippets. GEO wins AI citations. A mature content strategy runs both in parallel.

    How long does GEO take to show results?

    Unlike SEO, GEO results can appear quickly — sometimes within days of a page being indexed by AI crawlers. The compounding effect builds over 60–180 days as AI systems repeatedly select your content for related queries.

    Related on Tygart Media: GEO tactics · SEO vs GEO vs AEO · chunk-first GEO.

  • ¿Qué es GEO? Optimización para Motores Generativos

    ¿Qué es GEO? Optimización para Motores Generativos

    Si has optimizado contenido para Google y aun así no logras que los sistemas de inteligencia artificial te citen, es porque estás usando el manual equivocado. GEO —Generative Engine Optimization u Optimización para Motores Generativos— es la disciplina de hacer que tu contenido sea visible, creíble y citable para motores de IA como ChatGPT, Claude, Perplexity, Gemini y los AI Overviews de Google. No es SEO con un nombre nuevo. Es un juego distinto con reglas distintas.

    Definición: La Optimización para Motores Generativos (GEO) es la práctica de estructurar el contenido para que los modelos de lenguaje de gran escala (LLM) y los motores de búsqueda con IA lo seleccionen como fuente al generar respuestas a las consultas de los usuarios. Donde el SEO obtiene posiciones, el GEO obtiene citas.

    Por qué GEO no es SEO

    Side-by-side SEO rank/click versus GEO citation/answer-first
    Por qué GEO no es SEO.

    El SEO trata de posicionarse. Optimizas una página para que el algoritmo de Google la muestre cuando alguien busca algo. El objetivo es un clic. El GEO trata de ser citado. Estructuras el contenido para que un sistema de IA confíe en él lo suficiente como para extraer un dato, una definición o una explicación cuando sintetiza una respuesta. El usuario puede no hacer clic en tu URL, pero tu contenido moldeó lo que leyó.

    Los mecanismos son fundamentalmente diferentes. El algoritmo de posicionamiento de Google pondera cientos de señales: backlinks, velocidad de página, comportamiento del usuario, autoridad. La selección de citas por IA pondera la densidad de entidades, la especificidad factual, las señales de credibilidad de la fuente y la claridad estructural. Una página que ocupa el puesto #1 en Google puede recibir cero citas de IA. Una página que ocupa el puesto #8 puede ser la que Perplexity cita cada vez que alguien pregunta sobre ese tema.

    Cómo los motores de IA seleccionan el contenido que citan

    Los modelos de lenguaje de gran escala utilizados en la búsqueda con IA (GPT-4, Claude, Gemini) fueron entrenados en grandes corpus de texto, pero la capa de generación aumentada por recuperación (RAG) que impulsa herramientas como Perplexity, la búsqueda de ChatGPT y los AI Overviews de Google funciona de manera diferente. Extrae contenido en tiempo real en el momento de la consulta, lo puntúa por relevancia y credibilidad, y sintetiza una respuesta. Las señales que utiliza para puntuar tu contenido incluyen:

    • Claridad de entidades — ¿Las personas, lugares, empresas y conceptos en tu contenido están claramente nombrados y vinculados a entidades conocidas?
    • Densidad factual — ¿Tu contenido contiene afirmaciones específicas y verificables en lugar de generalidades vagas?
    • Legibilidad estructural — ¿Puede la IA analizar la estructura de tu contenido —encabezados, definiciones, listas— sin ambigüedad?
    • Señales de fuente — ¿Tu contenido cita fuentes primarias, estudios o expertos nombrados?
    • Esquema speakable — ¿Has marcado párrafos clave como candidatos de respuesta legibles por máquinas?

    Las tres capas del GEO

    Four-stage funnel: citation, click, engage, convert
    Las tres capas del GEO.

    Capa 1: Arquitectura de contenido

    El contenido optimizado para GEO está diseñado para la extracción, no solo para la lectura. Eso significa que cada afirmación importante está en una oración independiente. Las definiciones aparecen cerca de la parte superior. Los encabezados de sección son declarativos, no creativos. La estructura le dice a la IA dónde está la respuesta antes de que tenga que leer el artículo completo.

    Capa 2: Saturación de entidades

    Los sistemas de IA entienden el contenido a través de entidades: personas, organizaciones, lugares, productos y conceptos nombrados que existen en sus datos de entrenamiento. Un artículo optimizado para GEO satura las entidades relevantes: no dice “una importante empresa de IA” cuando se refiere a Anthropic. No dice “una popular herramienta de búsqueda” cuando se refiere a Perplexity. Cada entidad está nombrada, escrita correctamente y usada en el contexto correcto.

    Capa 3: Esquema y datos estructurados

    El marcado de esquema JSON-LD es una señal tanto para los motores de búsqueda tradicionales como para los rastreadores de IA. El esquema FAQPage hace que tu contenido de preguntas y respuestas sea directamente extraíble. El esquema speakable marca los párrafos más útiles para la síntesis de voz e IA. El esquema de artículo establece la autoría y la fecha de publicación. No son extras opcionales: son la capa legible por máquinas que hace que tu contenido sea seleccionado.

    GEO vs AEO: ¿Cuál es la diferencia?

    GEO versus SEO comparison cards
    GEO vs AEO: cuál es la diferencia.

    La Optimización para Motores de Respuesta (AEO) se centra en ganar fragmentos destacados, cuadros de Preguntas relacionadas y resultados de búsqueda de cero clics en los motores de búsqueda tradicionales. El GEO se centra en ser citado por los sistemas de IA generativa. Las tácticas se superponen, pero los objetivos son diferentes. El AEO gana la posición cero en Google. El GEO gana el párrafo que Perplexity escribe para el próximo millón de consultas sobre tu tema.

    Cómo empezar con GEO

    Si estás gestionando una operación de contenido existente y quieres incorporar GEO, el orden de prioridad es:

    1. Audita tus 20 páginas principales en busca de lagunas de entidades — donde uses referencias vagas, reemplázalas con entidades nombradas específicas
    2. Añade esquema speakable a tus tres párrafos definitorios más sólidos por página
    3. Ejecuta una verificación de densidad factual — cada estadística debe tener una fuente, cada afirmación debe ser específica
    4. Añade esquema FAQPage a cualquier página con encabezados en formato de pregunta
    5. Envía tus páginas principales a la Prueba de resultados enriquecidos de Google y verifica que los datos estructurados se lean correctamente

    GEO es infraestructura que se acumula

    La razón por la que GEO importa para las operaciones de contenido es el efecto acumulativo. Una vez que un sistema de IA ha indexado y confiado en tu contenido como fuente confiable sobre un tema, las consultas posteriores sobre ese tema extraen de tu contenido repetidamente, sin que publiques nada nuevo. Un solo artículo pilar optimizado para GEO puede generar miles de citas de IA durante 12 meses. Eso es un tipo diferente de ROI al de una página posicionada que recibe clics y se olvida.

    Preguntas frecuentes sobre GEO

    ¿Qué significa GEO?

    GEO significa Generative Engine Optimization —Optimización para Motores Generativos— la práctica de optimizar contenido para ser citado por sistemas de búsqueda impulsados por IA y modelos de lenguaje de gran escala.

    ¿Es GEO lo mismo que SEO?

    No. El SEO apunta a posiciones en la búsqueda tradicional. El GEO apunta a citas de IA en herramientas como ChatGPT, Perplexity, Claude y los AI Overviews de Google. Las tácticas se superponen pero los mecanismos y objetivos son diferentes.

    ¿Cómo sé si mi contenido está siendo citado por la IA?

    Ejecuta consultas relacionadas con tu tema en Perplexity, ChatGPT (con búsqueda activada) y los AI Overviews de Google. Verifica si tu dominio aparece como fuente citada. Herramientas como Profound y Otterly.ai pueden automatizar este monitoreo.

    ¿GEO reemplaza al AEO?

    No. AEO y GEO son complementarios. El AEO gana características de búsqueda tradicional como fragmentos destacados. El GEO gana citas de IA. Una estrategia de contenido madura ejecuta ambos en paralelo.

    ¿Cuánto tiempo tarda el GEO en mostrar resultados?

    A diferencia del SEO, los resultados de GEO pueden aparecer rápidamente, a veces en días después de que una página sea indexada por los rastreadores de IA. El efecto acumulativo se construye durante 60 a 180 días a medida que los sistemas de IA seleccionan repetidamente tu contenido para consultas relacionadas.

    Related on Tygart Media: What is GEO · GEO tactics · SEO vs GEO vs AEO.

  • Secondary Content Market: How AI Uses Your Business Data

    Secondary Content Market: How AI Uses Your Business Data

    Content About Your Business Is Being Created Without You

    Right now, somewhere on the internet, a system is writing content that mentions your business. It might be an AI answering a question about your industry. It might be a local publication compiling a roundup of businesses in your area. It might be a travel app generating a recommendation list for visitors to your town. It might be a voice assistant responding to “find me a [your service] near me.”

    This is the secondary content market — the ecosystem of publications, platforms, AI systems, and apps that create derivative content about businesses using whatever structured data they can find. It’s not new, but it’s accelerating. And the quality of what gets created about your business depends entirely on the quality of the data you make available.

    What Gets Pulled and What Gets Missed

    When we build local content for publications like Belfair Bugle and Mason County Minute, we pull from every structured data source available: Google Business Profiles, chamber of commerce directories, official business websites, social media pages, and public records. The businesses that load up their profiles — full menus, current photos, detailed descriptions, accurate hours, complete service lists — make it easy for us to write about them accurately and compellingly.

    The businesses that have a bare GBP listing, no menu, a stock photo, and hours from 2023? We either skip them or qualify everything with hedging language because we can’t verify the details. The same thing happens at scale when AI systems generate content. Rich data gets cited confidently. Sparse data gets ignored or, worse, hallucinated.

    Menus, Photos, and the Data That Feeds the Machine

    Think about what a well-stocked business profile actually provides to the secondary content market. Your menu gives food publications and AI systems specific dishes to recommend. Your photos give travel guides and social platforms visual content to feature. Your service list gives industry roundups specifics to cite. Your business description gives AI systems entities and context to work with.

    Every piece of data you add to your Google Business Profile, your website’s structured data, your social media profiles — all of it feeds into the content supply chain. Publications pull your menu to write about your restaurant. AI systems pull your service list to answer questions about your industry. Travel apps pull your photos to recommend your hotel. The richer your data, the more surface area you have in the secondary content market.

    The Local Angle: Why This Hits Small Businesses Hardest

    Large chains have marketing teams that maintain consistent data across every platform. Local businesses usually don’t. That means the secondary content market disproportionately favors chains over independents — unless the independent makes a deliberate effort to load up their structured data.

    This is particularly true in areas like Mason County and the Olympic Peninsula, where local businesses are the backbone of the community but often have the thinnest digital presence. A family-owned restaurant with an incredible menu but no Google Business Profile menu entry is invisible to every AI system and publication that relies on structured data. A boutique hotel with stunning views but no photos on their GBP is a ghost to travel recommendation engines.

    What To Do About It

    The secondary content market isn’t going away — it’s growing. The actionable response is straightforward: make your business data machine-readable, complete, and current. Start with your Google Business Profile. Fill every field. Upload quality photos. Add your full menu or service catalog. Update your hours. Write a description that includes the terms and entities relevant to your business.

    Then do the same for your website — add structured data (schema markup) so AI systems can parse your content programmatically. Make sure your social media profiles are consistent and current. The goal isn’t to game any one platform. It’s to ensure that when any system anywhere creates content about your business, it has accurate, rich data to work with.

    Your business data is already on the secondary content market. The only question is whether you’ve given it good material to work with.

  • Google Business Profile: Treat It Like a Knowledge Node

    Google Business Profile: Treat It Like a Knowledge Node

    The Shift Nobody Is Talking About

    Most businesses treat their Google Business Profile like a digital business card — name, address, phone number, maybe a few photos. Update it once, forget about it. That approach made sense when GBP was primarily a search listing. It doesn’t make sense anymore.

    Here’s what’s changed: your Google Business Profile has quietly become one of the most important structured data sources on the internet. Not just for Google Search, but for the entire ecosystem of AI systems, local publications, voice assistants, mapping apps, review aggregators, and content platforms that need reliable business data to function.

    What’s Actually Pulling From Your GBP

    When an AI system like ChatGPT, Claude, or Perplexity answers a question about “best restaurants in Shelton, WA,” it needs ground truth data. Where does that data come from? Increasingly, it’s structured business data — and Google Business Profiles are the richest, most consistently maintained source of it.

    When a local publication (like our own Mason County Minute or Belfair Bugle) writes about businesses in the area, we verify every entity against Google Maps data. The name, the address, the hours, whether it’s still open — all of it comes from the Google Places API, which pulls directly from Google Business Profiles.

    When a voice assistant answers “what time does [business] close,” it’s reading your GBP. When a travel app recommends places to eat, it’s pulling your GBP menu, photos, and reviews. When an AI overview summarizes local options, your GBP data is in the training signal.

    The Knowledge Node Mental Model

    Stop thinking of your GBP as a listing. Start thinking of it as a knowledge node — a structured data endpoint that other systems query to learn about your business. The richer and more accurate your node is, the more useful it is to every downstream system that touches it.

    What does a well-maintained knowledge node look like? It has complete, current hours (including holiday hours). It has a full menu or service list with prices. It has high-quality photos of the exterior, interior, products, and team. It has a detailed business description with the entities and terms that matter for your category. It has attributes filled out — wheelchair accessible, outdoor seating, Wi-Fi, whatever applies. It has regular posts showing activity and relevance.

    Every one of those data points is something that another system can cite, surface, or recommend. A missing menu means a food app can’t include you. Missing photos mean an AI-generated travel guide has nothing to show. Outdated hours mean a voice assistant sends someone to your door when you’re closed.

    Why This Matters Now More Than Before

    We’re entering a period where AI-generated content and AI-powered search are growing rapidly. Google AI Overviews, Perplexity, ChatGPT with browsing — these systems need structured data about real-world businesses to generate useful answers. The businesses that provide that data in a rich, machine-readable format will get cited. The ones that don’t will get skipped.

    This isn’t theoretical. We built a Google Maps quality gate into our own publishing pipeline after community feedback showed us that AI-generated entity errors erode trust instantly. The businesses that had complete, accurate GBP listings were easy to verify and include. The ones with sparse or outdated profiles created uncertainty — and uncertainty means we leave them out.

    The Action Step

    Open your Google Business Profile today. Look at it not as a customer would, but as a machine would. Is every field filled? Are your photos recent and high-quality? Is your menu or service list complete? Are your hours accurate, including holidays? Is your business description rich with the terms someone (or something) would search for?

    If the answer is no, you’re leaving distribution on the table. Every AI system, every local publication, every app that could have mentioned your business needs data to work with. Your GBP is where that data lives. Treat it like the API it’s becoming.

    📎 Book for Bots — Free

    Take this article on steroids.

    The Claude Implementation Playbook is a dense 9-section PDF you can attach directly to any AI conversation — pricing tables, model API strings, routing logic, context engineering rules. Verified May 2026.

    Get Free PDF →

    Work with Tygart Media

    Scaling Claude across a team or agency?

    Usage limits are the first thing you hit when Claude starts working. We’ve built systems that manage context budgets, rotate models by task, and keep costs predictable at scale. If that’s the problem you’re solving, let’s talk.

    See How We Work →

  • Node Pricing Strategy: Eliminating SaaS Conversion Friction

    Node Pricing Strategy: Eliminating SaaS Conversion Friction

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    Most SaaS pricing pages are designed to justify a price. The best ones are designed to eliminate a reason not to buy. That sounds like the same thing. It isn’t. Justifying a price assumes the customer already wants what you’re selling and just needs to feel okay about the number. Eliminating friction assumes the customer wants it but has found a reason to wait — and your job is to remove that reason before they close the tab.

    Node pricing is the second kind of pricing. It’s not a discount strategy. It’s not a freemium ladder. It’s a structural acknowledgment that your product contains more than one thing of value, and not every customer needs all of it. The $9/node model — where a customer pays $9 per knowledge sub-vertical per month, with a minimum of three nodes — does something that flat subscription tiers almost never do: it makes the product accessible at the exact scope the customer actually wants, rather than at the scope you’ve decided they should want.

    This matters more than it sounds. The gap between what a customer wants to pay for and what your pricing page forces them to pay for is where most SaaS revenue quietly dies.

    The Friction Taxonomy

    Before you can eliminate friction, you have to know which kind you’re dealing with. There are three distinct friction types that kill knowledge product conversions, and they require different solutions.

    Price friction is the most obvious and the least interesting. The customer looks at the number and thinks it’s too high relative to what they’re getting. The standard response is discounts, trials, and annual pricing incentives. These work, but they’re universally available to competitors and therefore not a strategic advantage.

    Scope friction is more interesting and more solvable. The customer looks at what’s included and thinks: I need the mold section. I don’t need water damage, fire, or insurance. But the only way to get mold is to buy the whole restoration corpus at $149/month. That’s not a price objection — they might genuinely be willing to pay $40 for mold-only access. The friction is architectural. The pricing structure forces them to buy more than they want, so they buy nothing.

    Identity friction is the least discussed and often the most decisive. The customer looks at your Growth tier at $149/month and thinks: that’s a serious software subscription. It implies a level of commitment and organizational buy-in that I’m not ready to make. Even if $149 is financially trivial to them, the psychological weight of a $149 line item on a budget is different from three $9 charges that collectively total $27. The first feels like a decision. The second feels like a purchase. That distinction is not rational. It is real.

    Node pricing at $9/node addresses all three friction types simultaneously — and that’s why it’s a more interesting pricing philosophy than it appears to be on first read.

    Why $9 Is Not Arbitrary

    The $9 price point is doing several things at once. It’s below the threshold where most individuals and small business operators feel they need approval from anyone else to make a purchase. It’s above the threshold that signals “this is a real product with real value” rather than a free tier with artificial limits. And it creates an obvious natural upsell path: the customer who starts with one node at $9 and finds it useful adds a second, then a third. At three nodes they’re at $27/month. At five they’re at $45. Somewhere between five and ten nodes, the Growth tier at $149 starts looking like a better deal than individual nodes — and the customer has already been educated on why they want more coverage, by their own experience of adding nodes one at a time.

    This is not an accident. It’s a funnel architecture disguised as a pricing structure. The customer who would never have clicked “Start Trial” on a $149 product clicked “Add mold node” at $9, found out the corpus is actually good, added two more nodes, and is now a much warmer prospect for the Growth tier than any free trial would have produced — because they’ve already been paying, which means they’ve already decided the product is worth money.

    Paying, even a small amount, is a qualitatively different commitment than trialing for free. The psychology of sunk cost works in your favor when the cost is real. Free trial users can walk away feeling nothing. A customer who has paid three months of $27/month has a relationship with the product that is fundamentally stickier, even before the node count justifies an upgrade.

    The Scope Signal

    There is a second thing node pricing does that is easy to overlook: it collects enormously useful intelligence about what customers actually value.

    A flat subscription tier tells you how many people bought. It tells you almost nothing about why, or which part of the product they’re using. Node pricing tells you exactly which knowledge sub-verticals customers are willing to pay for, in what combinations, at what rate of adoption. That is product market fit data at a granularity that flat pricing can never produce.

    If 70% of customers add the mold node first, that tells you something about where to invest in corpus depth. If almost nobody adds the insurance and claims node despite it being objectively one of the most technically complex verticals in the corpus, that tells you something about either the quality of that content or the demand signal for it among your current customer base. If customers consistently add three nodes and stop, that tells you something about the natural scope of what most buyers want — and it should inform where you set the minimum bundle threshold for the Growth tier conversion.

    This is market research that runs continuously and costs nothing beyond what you were already building. It requires only that you look at the data.

    The Minimum Bundle Logic

    Node pricing works best with a thoughtfully designed minimum. Three nodes at $9/month means $27 minimum — low enough to feel like a purchase, high enough to produce real revenue and signal real intent. But the choice of three is not purely arbitrary.

    Below a certain node count, the knowledge base isn’t useful enough to demonstrate value. A single mold node in isolation tells a contractor something. Three nodes — mold, water damage, and drying science — tells them enough to use the product meaningfully in a real job situation. The minimum bundle is designed to get the customer past the “is this actually good?” threshold before they’ve made a large enough commitment to feel burned if the answer is no.

    The minimum also creates a natural comparison point with the next tier up. Three nodes at $27 versus the Growth tier at $149 is a stark difference. But eight nodes at $72 versus $149 starts to narrow. The minimum bundle pushes customers to a price point where the comparison becomes interesting — and interesting comparisons produce upgrades.

    What This Has to Do With Content Strategy

    Node pricing is a product architecture decision. But the philosophy behind it — that friction is the real barrier, not price — applies directly to how content products should be built and sequenced.

    The content equivalent of scope friction is the pillar article problem. You write a comprehensive 3,000-word guide on a topic and wonder why the conversion rate is lower than expected. The reason is often that the reader wanted one specific section — the part about how to document moisture readings for an insurance claim — and had to work through 2,000 words of context they already knew to get there. The scope of the article exceeded the scope of their need. They left.

    The content equivalent of node pricing is granular entry points. Instead of one comprehensive guide, you publish the moisture documentation section as a standalone piece, linked from the comprehensive guide but findable independently. The reader who needs exactly that finds it, gets the answer, and converts at a higher rate than the reader who had to excavate it from a wall of text. The comprehensive guide still exists for the reader who wants full coverage. Both types of readers are served at their own scope.

    The underlying insight is the same in both cases: matching the scope of what you offer to the scope of what each specific customer wants is more powerful than optimizing within a fixed scope. The customer who wants mold-only is not a lesser customer than the one who wants the full corpus. They’re a customer at the beginning of a different path that, if you’ve designed correctly, leads to the same destination.

    The $1 First Month Isn’t a Trick

    One pricing mechanic worth calling out specifically is the $1 first month offer — available on any single corpus, unlimited queries, 30 days, one dollar. No catch.

    This is not a trick and should not be presented as one. It is a philosophical statement about where conversion friction lives. If the product is good, the barrier isn’t price — it’s the activation energy required to start. Most people don’t try things because they haven’t gotten around to it, not because the price is wrong. A dollar removes the “is it worth the money to find out?” calculation entirely and replaces it with: the only reason not to try this is inertia.

    The customers who try it and stay are the ones who found value. The ones who don’t renew weren’t going to stay at any price, and the dollar was a better use of that lead than a free trial that never converts because free things feel optional.

    Priced at $1, the first month is a commitment. Priced at $0, it’s a maybe. That difference in psychological framing shows up in activation rates, usage depth during the trial period, and ultimately in renewal rates. Free is not always better than cheap. Sometimes cheap is better than free because cheap requires a decision, and a decision creates an owner.

    Frequently Asked Questions

    What is node pricing in a knowledge API product?

    Node pricing is a model where customers pay per knowledge sub-vertical — called a node — rather than for access to the entire corpus at a flat tier price. At $9/node with a three-node minimum, customers pay only for the specific knowledge domains they need, reducing scope friction and creating a natural upgrade path to higher tiers as they add more nodes.

    Why is friction the real barrier rather than price in knowledge products?

    Most knowledge product prospects aren’t declining because the price is objectively too high — they’re declining because the pricing structure forces them to commit to more scope than they currently need. Node pricing addresses scope friction (buying only what you want) and identity friction (avoiding the psychological weight of a large monthly commitment) in ways that discounting alone cannot.

    How does node pricing create an upgrade path to higher tiers?

    Customers who start with three nodes at $27/month add nodes as they discover value. As the node count climbs toward eight or ten, the per-node cost of the Growth tier at $149 becomes more attractive than continuing to add individual nodes. The customer has also been paying throughout this process — establishing a payment relationship and demonstrating intent that makes the tier upgrade a natural next step rather than a new decision.

    What intelligence does node pricing generate about customer demand?

    Node-level purchase data reveals which knowledge sub-verticals customers value enough to pay for, in what order, and in what combinations. This is granular product-market fit data that flat subscription tiers can’t produce. It informs corpus investment priorities, identifies underperforming verticals, and reveals natural scope limits in the customer base — all without additional research spending.

    Why is a $1 first month more effective than a free trial?

    Free trials feel optional because they require no commitment. A $1 first month requires a purchasing decision — the customer has decided this is worth trying rather than just started a free account. This small financial commitment increases activation rates, usage depth, and renewal conversion because customers who pay, even minimally, have already decided the product is worth their attention.

  • Corpus Contributor Model: Build an AI Knowledge Flywheel

    Corpus Contributor Model: Build an AI Knowledge Flywheel

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade

    The most interesting business models don’t just sell to customers. They turn customers into the product’s engine. There’s a version of this in every category — the marketplace that gets better as more buyers and sellers join, the review platform that gets more useful as more people leave reviews, the map that gets more accurate as more drivers report conditions. Network effects are well understood. But there’s a quieter version of this dynamic that almost nobody is building yet, and it may be more valuable than the classic network effect in the AI era.

    Call it the corpus contributor model. The customer who pays for access to your knowledge base also happens to be a practitioner in the exact domain your knowledge base covers. They use the product. They notice what it gets wrong. They have opinions about what’s missing. And if you build the right mechanic, they can feed those observations back into the corpus — making it more accurate, more complete, and more current than you could ever make it by yourself.

    This is not a theoretical model. It’s a specific architectural decision with specific business implications. And most AI knowledge product builders are missing it entirely.

    What the Corpus Contributor Flip Actually Is

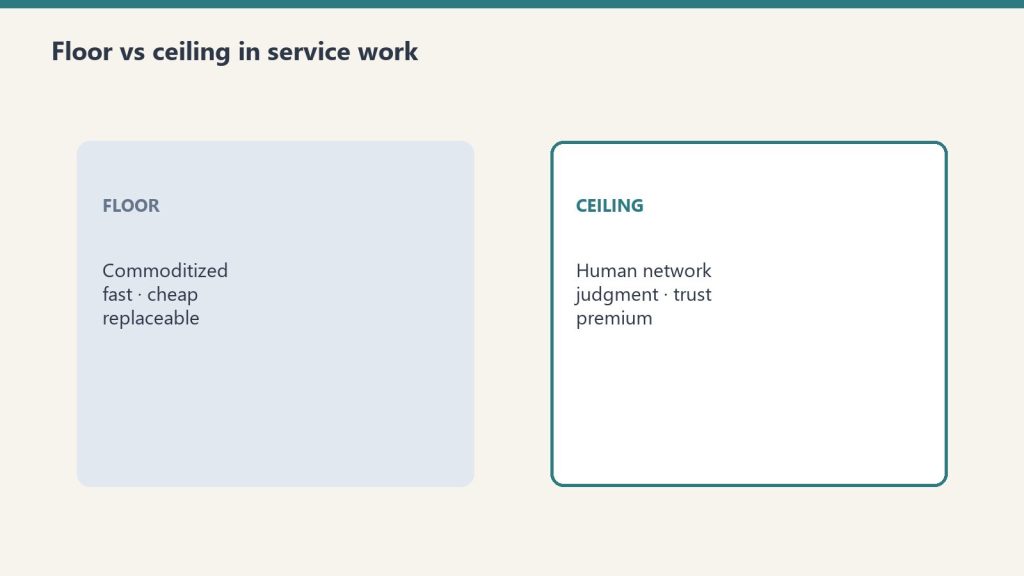
    Floor versus ceiling cards for commoditized work and human-network premium
    What the corpus contributor flip actually is.

    The standard model for a knowledge API product looks like this: you extract knowledge from practitioners, structure it, and sell access to it. The customer is a buyer. The knowledge flows one direction — from your corpus into their AI system. You maintain the corpus. They consume it. Revenue comes from subscriptions.

    The corpus contributor model adds a second flow. The customer — who is themselves a practitioner — also has the option to contribute validated knowledge back into the corpus. Their contribution improves the product for every other customer. In exchange, they get something: a lower subscription rate, a named credit in the corpus, early access to new verticals, or simply a better product faster than the passive subscriber would get it.

    The word “flip” matters here. You are not just adding a feature. You are reframing who the customer is. They are not only a consumer of knowledge. They are simultaneously a source of it. The relationship is bilateral. That changes the economics, the product roadmap, the sales conversation, and the defensibility of the whole business in ways that compound over time.

    Why This Is Different From Crowdsourcing

    The immediate objection is that this sounds like crowdsourcing, which has a complicated track record. Wikipedia works. Most other crowdsourced knowledge projects don’t. The reason Wikipedia works at scale and most others don’t comes down to one thing: intrinsic motivation. Wikipedia contributors edit because they care about the topic. There’s no transaction.

    The corpus contributor model is not crowdsourcing and should not be designed like it. The distinction is selection and validation.

    Selection: You are not asking the general public to contribute. You are asking paying subscribers who have already demonstrated that they operate in this domain by the fact of their subscription. A restoration contractor who pays $149 a month for access to a restoration knowledge API has self-selected into a group with genuine domain expertise and a financial stake in the quality of the product. That is a fundamentally different contributor pool than an open wiki.

    Validation: Contributor submissions don’t go directly into the corpus. They go into a validation queue. Every submission is reviewed against existing knowledge, cross-referenced against standards where they exist, and flagged for expert review when there’s conflict. The contributor model doesn’t replace the extraction and validation process — it feeds it. Contributors surface what’s missing or wrong. The validation layer decides what actually enters the corpus.

    This is closer to the model used by high-quality technical reference databases than to Wikipedia. The contributors are domain insiders with a stake in accuracy. The editorial layer maintains quality. The corpus improves faster than it could with internal extraction alone.

    The Flywheel

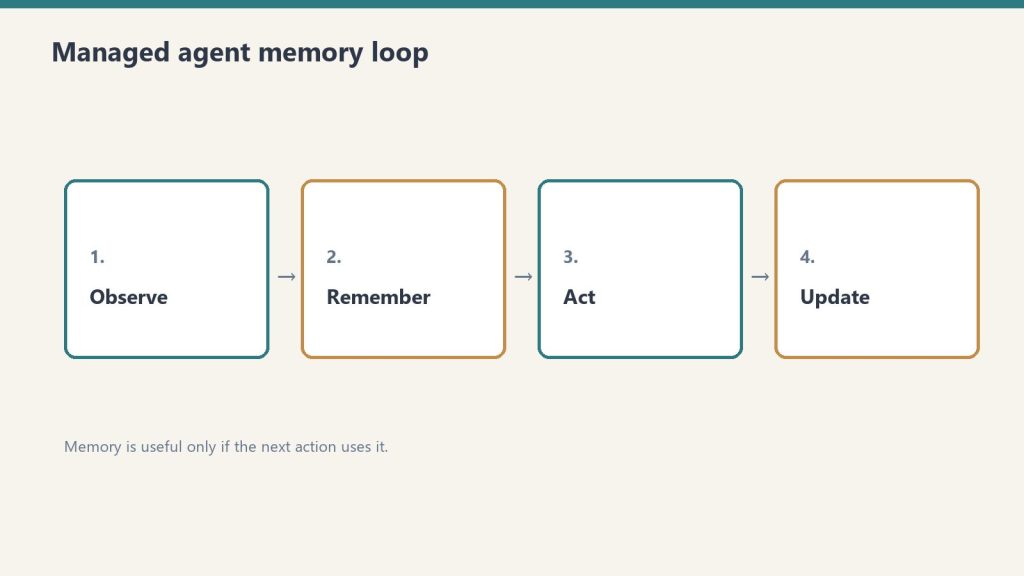
    Four-step loop: observe, remember, act, update for managed agents
    The flywheel.

    Here is where the model gets genuinely interesting. Every traditional subscription business has a churn problem. The customer pays monthly. They evaluate monthly whether the product is worth it. If nothing changes, their willingness to pay is roughly static. The product has to justify itself again and again against a customer whose needs are evolving.

    The corpus contributor model changes this dynamic in two ways that reinforce each other.

    First, contributors have a personal stake in the corpus that passive subscribers don’t. If you submitted three validated knowledge chunks about LGR dehumidification performance in high-humidity climates, and those chunks are now in the corpus being used by other contractors and by AI systems that serve your industry, you have a relationship with that corpus that is qualitatively different from someone who just queries it. You built part of it. Your churn rate is lower because leaving the product means leaving something you helped create.

    Second, the corpus gets better as contributors engage. A better corpus is worth more to new subscribers, which brings in more potential contributors, which improves the corpus further. This is a flywheel, not just a retention mechanic. The passive subscriber benefits from the contributor’s work. The contributor gets a better product to work with. New subscribers join a product that is measurably more accurate and complete than it was six months ago. The value proposition strengthens over time without requiring proportional increases in internal extraction cost.

    Compare this to a standard knowledge API where the corpus is maintained entirely internally. The corpus improves at the rate of your internal extraction capacity. If you can run four extraction sessions a month, you add roughly four sessions’ worth of new knowledge per month. With contributors, that rate is multiplied by however many qualified practitioners are actively engaged. The internal team still controls quality through the validation layer. But the input volume grows with the customer base rather than with internal headcount.

    The Enterprise Version

    Individual contributors are valuable. Enterprise contributors are transformative.

    Consider a restoration software company that builds job management tools for contractors. They have access to millions of completed job records — real-world data on what drying protocols were used on what loss categories in what climate conditions, with what outcomes. That data, properly structured and validated, is worth dramatically more to a restoration knowledge corpus than anything extractable from individual interviews.

    The standard sales conversation with that company is: “Pay us $499 a month for API access.” That’s fine. It’s a transaction.

    The corpus contributor conversation is different: “We want to build the knowledge infrastructure that makes your product’s AI features better. You have data we need. We have a structured corpus and a validation layer you’d spend years building. Let’s make the corpus jointly better and share the value.” That’s a partnership conversation. It changes the deal size, the relationship depth, and the defensibility of the resulting product — because the enterprise contributor’s data is now embedded in a corpus they can’t easily replicate by going to a competitor.

    Enterprise corpus contributors also create a named knowledge layer opportunity. The restoration software company’s contributed data doesn’t disappear into an anonymous corpus — it’s credited, tracked, and potentially sold as a named vertical: “Job outcome data layer, contributed by [Partner].” That attribution has marketing value for the contributor and validation signal for the subscribers who use it. Everyone’s incentives align.

    What the Sales Conversation Becomes

    The corpus contributor model changes the initial sales conversation in a way that most knowledge product builders miss because they’re too focused on the subscription tier.

    The standard pitch leads with access: “Here’s what you can query. Here’s the price.” That’s a cost-benefit conversation. The prospect weighs whether the knowledge is worth the fee.

    The contributor pitch leads with participation: “You know things we need. We have infrastructure you’d spend years building. Join as a contributor and help shape the corpus your AI stack runs on.” That’s a different conversation entirely. It’s not about whether the existing product justifies its price — it’s about whether the prospect wants to have a role in what the product becomes.

    For practitioners who care about their industry’s AI infrastructure — and in most verticals, there are a meaningful number of these people — the contributor framing is more compelling than the subscriber framing. It gives them agency. It makes them a participant in something larger than a software subscription. That is a qualitatively different reason to write a check, and it is stickier than feature value alone.

    The Validation Layer Is the Business

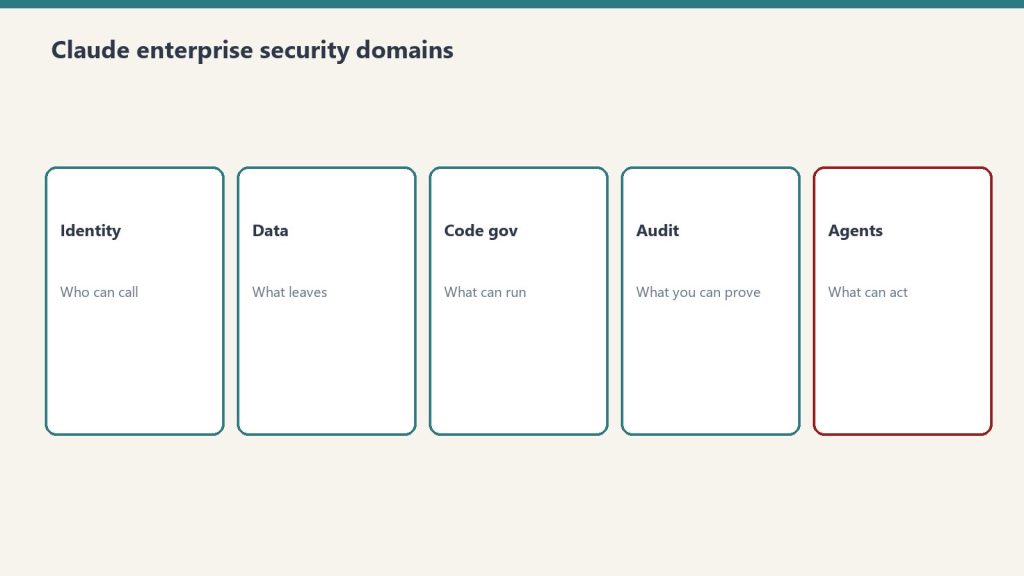
    Five security domains: identity, data, code governance, audit, agents
    The validation layer is the business.

    Everything described above depends on one thing working correctly: the validation layer. If contributors can inject bad knowledge into the corpus, the product becomes unreliable. If the validation layer is so restrictive that nothing gets through, the contributor mechanic produces no value. The design of the validation layer is where the real intellectual work of the corpus contributor model lives.

    A well-designed validation layer has three properties. It is domain-aware — it knows enough about the field to evaluate whether a contribution is plausible, consistent with existing knowledge, and meaningfully different from what’s already there. It is conflict-surfacing — when a contribution contradicts existing corpus entries, it flags the conflict for expert review rather than silently accepting or rejecting either. And it is contributor-transparent — contributors can see the status of their submissions, understand why something was accepted or rejected, and engage in a dialogue about contested points.

    The validation layer is also the moat that a competitor can’t easily replicate. Building a corpus takes time. Building relationships with contributors takes time. But building the domain expertise required to run a validation layer that practitioners trust — that takes the longest. It’s the part of the business that scales slowest and defends best.

    Who Should Build This First

    The corpus contributor model is available to any knowledge product company that has, or can develop, three things: a practitioner customer base with genuine domain expertise, an extraction and validation infrastructure that can process contributions at volume, and the product design capability to build a contribution mechanic that practitioners actually use.

    In the restoration industry, the conditions are nearly ideal. The customer base — contractors, adjusters, estimators, project managers — has deep domain knowledge and a direct financial interest in AI tools that work correctly. The knowledge gaps are enormous and well-understood. And the trust infrastructure, built through trade associations, peer networks, and industry events, already exists as a substrate for the kind of relationship-based contributor model that works at scale.

    The first knowledge product company in any vertical to implement the corpus contributor model well will have an advantage that is very difficult to replicate. Not because their technology is better. Because they turned their customers into co-authors of the most defensible asset in vertical AI.

    Related on Tygart Media: jobs as knowledge base · information density · GEO tactics.

    Frequently Asked Questions

    What is the corpus contributor model in AI knowledge products?

    The corpus contributor model is a product architecture where paying customers — who are domain practitioners — also have the option to contribute validated knowledge back into the product’s knowledge base. This creates a bilateral relationship where the customer is both a consumer and a source of knowledge, improving the corpus faster than internal extraction alone could achieve.

    How is this different from crowdsourcing?

    The corpus contributor model differs from crowdsourcing in two critical ways: selection and validation. Contributors are self-selected domain practitioners who pay for access, not anonymous volunteers. And contributions pass through a structured validation layer before entering the corpus — they don’t go in automatically. This makes it closer to a high-quality technical reference database model than an open wiki.

    Why does the corpus contributor model reduce churn?

    Contributors develop a personal stake in the corpus that passive subscribers don’t have. Having built part of the product, contributors are less likely to cancel because leaving means leaving something they helped create. Additionally, active contributors see the corpus improving in response to their input, which reinforces the value they’re receiving beyond passive access.

    What makes enterprise corpus contributors particularly valuable?

    Enterprise contributors — such as software companies with large volumes of structured job outcome data — can contribute knowledge at a scale and quality that individual extraction sessions can’t match. Their data also creates a named knowledge layer opportunity: credited, tracked contributions that signal validation quality to other subscribers and create a partnership relationship that is significantly stickier than a standard subscription.

    What is the validation layer and why does it matter?

    The validation layer is the quality control system that evaluates contributor submissions before they enter the corpus. It must be domain-aware enough to assess plausibility, conflict-surfacing when contributions contradict existing knowledge, and transparent enough that contributors understand how their submissions are evaluated. The validation layer is also the hardest component to replicate, making it the deepest competitive moat in the model.

  • AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    Tygart Media Strategy
    Volume Ⅰ · Issue 04 Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade

    The extraction layer is the part of the AI economy that doesn’t exist yet — and it’s the only part that can’t be automated into existence. Every vertical AI product, every industry-specific chatbot, every AI assistant that actually knows what it’s talking about requires one thing that nobody has figured out how to manufacture at scale: the deep, tacit, hard-won knowledge that lives inside experienced human practitioners.

    This is not a gap that will close on its own. It is a structural feature of how expertise works. And for the businesses and individuals who understand it clearly, it is the single most durable competitive advantage available in the current AI era.

    What the Extraction Layer Actually Is

    Floor versus ceiling cards for commoditized work and human-network premium
    What the extraction layer actually is.

    When people talk about AI knowledge gaps, they usually mean one of two things: either the model hasn’t been trained on recent data, or the model lacks access to proprietary databases. Both of those are real problems. Neither of them is the extraction layer problem.

    The extraction layer problem is different. It’s the gap between what an experienced practitioner knows and what has ever been written down in a form that any AI system — regardless of its training data or database access — can actually use.

    A 30-year restoration contractor who has dried 2,000 structures knows things that have never been documented anywhere. Not because they were keeping secrets. Because the knowledge is embedded in judgment calls, pattern recognition, and muscle memory that wasn’t worth writing down at the time. They know which psychrometric conditions in a basement after a Category 2 loss require an LGR versus a conventional dehumidifier, and why. They know the exact moment a water damage job transitions from “drying” to “reconstruction” based on a combination of readings and smells and wall flex that no textbook captures. They know which insurance adjusters will fight a mold scope and which ones will approve it without a second look.

    None of that knowledge is in any training dataset. None of it will be in any training dataset until someone does the hard, slow, relationship-dependent work of pulling it out of people’s heads and putting it into structured form.

    That is the extraction layer. And it requires humans.

    Why AI Cannot Close This Gap By Itself

    Three stacked layers: chat UI, tools, agent runtime
    Why AI cannot close this gap by itself.

    The reflex response to any knowledge gap problem in 2026 is to propose an AI solution. Train a bigger model. Scrape more data. Use retrieval-augmented generation with a larger corpus. There is genuine value in all of those approaches. None of them solves the extraction layer problem.

    The issue is not volume or recency. The issue is source availability. Training data and RAG systems can only work with knowledge that has been externalized — written, recorded, structured, published somewhere that a crawler or an ingestion pipeline can reach. Tacit expertise, by definition, hasn’t been externalized. It exists as neural patterns in someone’s head, not as tokens in a document.

    There are things AI can do well that partially address this. AI can synthesize patterns from large volumes of existing text. It can identify gaps in documented knowledge by mapping what questions get asked versus what answers exist. It can transcribe and structure interviews once they’ve been recorded. But AI cannot conduct the interview. It cannot build the relationship that earns the trust required to get a 25-year adjuster to walk through their actual decision logic on a contested mold claim. It cannot recognize, in the middle of a conversation, that the contractor just said something technically significant that they treated as throwaway context.

    The extraction process requires a human who understands the domain well enough to know what they’re hearing, has the relationship to access the right people, and has the patience to do this work over months and years rather than in a single API call. That is not a temporary limitation of current AI systems. It is a structural property of how tacit knowledge works.

    The Pre-Ingestion Positioning

    There is a second reason the extraction layer matters beyond the knowledge itself: where in the AI stack you sit determines your liability exposure, your defensibility, and your pricing power.

    Most businesses that try to participate in the AI economy position themselves downstream of AI processing — they modify outputs, review generated content, add a human approval layer on top of AI decisions. That positioning puts them in the output chain. When something goes wrong, they are implicated. The AI said it, but they delivered it.

    The extraction layer positions you upstream — before the AI processes anything. You are the raw data source. The same category as a web search result, a database query, a regulatory filing. The AI system that consumes your knowledge is responsible for what it does with it. You are responsible for the quality of the knowledge itself.

    This is how every B2B data vendor in the world operates. DataForSEO does not guarantee your search rankings. Bloomberg does not guarantee your trades. They guarantee the accuracy and quality of the data they provide. What downstream systems do with that data is those systems’ problem. The pre-ingestion positioning applies the same logic to industry knowledge: guarantee the knowledge, not the outputs built on top of it.

    This single reframe changes the risk profile of being in the knowledge business entirely.

    What Makes Extraction Layer Knowledge Defensible

    Three panels showing one problem, three options, one recommendation
    What makes extraction-layer knowledge defensible.

    In a market where AI can write a competent 1,500-word blog post about mold remediation in 45 seconds, content is not a moat. But the knowledge that makes a 1,500-word blog post about mold remediation actually correct — the kind of correct that a working contractor or an insurance adjuster would recognize as coming from someone who has actually done this — that is a moat.

    There are four properties that make extraction layer knowledge genuinely defensible:

    Relationship dependency. The best knowledge comes from people who trust you enough to share their actual mental models, not their public-facing summaries. That trust is earned over time through consistent contact, demonstrated competence, and reciprocal value. It cannot be purchased or automated. A competitor who wants to build a comparable restoration knowledge corpus doesn’t start by writing code — they start by spending three years attending trade events and building relationships with people who know things. The time cost is the moat.

    Validation depth. Anyone can collect statements from practitioners. Collecting statements that have been cross-validated against field outcomes, regulatory standards, and peer review is a different operation entirely. A knowledge chunk that says “humidity levels above 60% RH for more than 72 hours in a structure with cellulose materials creates conditions for mold amplification” is only valuable if it’s been validated against IICRC S520 and corroborated by practitioners in multiple climate zones. The validation work is slow, expensive, and domain-specific. That’s what makes it valuable.

    Structural format. Raw interview transcripts are not an API. The extraction work includes converting practitioner knowledge into machine-readable, consistently structured formats that AI systems can actually consume without hallucinating context. This requires both domain knowledge and technical architecture. Most domain experts don’t have the technical skills. Most technical people don’t have the domain knowledge. The people who have both, or who have built teams that combine both, have a significant advantage.

    Maintenance obligation. Industry knowledge changes. Regulatory standards update. Best practices evolve as new equipment enters the market. A static knowledge corpus becomes a liability as it ages. The commitment to maintaining knowledge over time — keeping relationships active, re-validating chunks, incorporating new field evidence — is itself a barrier that competitors can’t easily replicate.

    The Compound Effect

    Here is what makes the extraction layer position genuinely interesting over a long time horizon: it compounds.

    Every extraction session adds to the corpus. Every validation pass improves accuracy. Every new practitioner relationship opens access to adjacent knowledge that wouldn’t have been reachable without the trust built in the previous relationship. The corpus that exists after three years of sustained extraction work is not three times as valuable as the corpus after year one — it’s potentially ten or twenty times as valuable, because the knowledge chunks have been cross-validated against each other, the gaps have been identified and filled, and the relationships that generate ongoing updates are deep enough to provide real-time field intelligence.

    Meanwhile, the barrier to entry for a new competitor grows with every passing month. They are not three years behind on code — they are three years behind on relationships, validation work, and corpus structure. Those things don’t accelerate with more investment the way software development does. You can hire ten engineers and ship in months what one engineer would take years to build. You cannot hire ten field relationships and develop in months what one relationship would take years to earn.

    Where This Is Going

    The most valuable AI products of the next decade will not be the ones with the most parameters or the most compute. They will be the ones with access to the best knowledge. In most industries, that knowledge hasn’t been extracted yet. It’s still sitting in the heads of practitioners, waiting for someone to do the patient, human-intensive work of getting it out and into machine-readable form.

    The businesses that move on this now — while the extraction layer is still largely empty — will have a significant and durable advantage over those who wait. The technical infrastructure to build with extracted knowledge exists today. The AI systems that can consume and deliver it exist today. The market that wants vertical AI products with genuine domain expertise exists today.

    The only scarce input is the knowledge itself. And the only way to get it is to do the work.

    The Practical Question

    Every industry has an extraction layer problem. The question is who is going to solve it.

    In restoration, the practitioners who have seen thousands of losses, negotiated thousands of claims, and developed the judgment that comes from being wrong in expensive ways and learning from it — that knowledge base exists. It’s distributed across individual careers and company histories, mostly undocumented, largely inaccessible to the AI systems that restoration companies are increasingly building or buying.

    The same is true in radon mitigation, luxury asset appraisal, cold chain logistics, medical triage, and every other field where the difference between a good decision and a bad one depends on knowledge that was never worth writing down at the time it was learned.

    The extraction layer is not a technical problem. It is a knowledge infrastructure problem. And the first movers who build that infrastructure — who do the relationship work, run the extraction sessions, structure the knowledge, and maintain it over time — will be sitting on the most defensible position in vertical AI.

    Not because they built a better model. Because they did the work AI can’t.

    Frequently Asked Questions

    What is the extraction layer in AI?

    The extraction layer refers to the process of converting tacit, practitioner-held knowledge into structured, machine-readable formats that AI systems can consume. It sits upstream of AI processing and requires human relationship-building, domain expertise, and sustained extraction effort that cannot be automated.

    Why can’t AI build its own knowledge base from existing content?

    AI training and retrieval systems can only work with externalized knowledge — content that has been written, recorded, and published somewhere accessible. Tacit expertise exists as judgment and pattern recognition in practitioners’ minds, not as tokens in any document. It requires active extraction through interviews, observation, and validation before it can enter any AI system.

    What makes extraction layer knowledge defensible as a business asset?

    Four properties make it defensible: relationship dependency (earning practitioner trust takes years and cannot be purchased), validation depth (cross-referencing against standards and field outcomes is slow and domain-specific), structural format (converting raw knowledge to structured AI-consumable formats requires both domain and technical expertise), and maintenance obligation (keeping knowledge current requires sustained investment that most competitors won’t make).

    How does pre-ingestion positioning reduce AI liability?

    By positioning as an upstream data source rather than a downstream output modifier, knowledge providers follow the same model as all major B2B data vendors: they guarantee the quality of the knowledge itself, not what downstream AI systems do with it. This is structurally different from businesses that modify or deliver AI outputs, which puts them in the output liability chain.

    What industries have the largest extraction layer gaps?

    Any industry where expert judgment is built through years of practice rather than documented procedure has significant extraction layer gaps. Restoration contracting, radon mitigation, luxury asset appraisal, insurance claims adjustment, cold chain logistics, and specialized medical triage are examples where practitioner knowledge vastly exceeds what has ever been formally documented.