Tag: AI Citation

  • Opting Out of AI Answers Cost One Site Its Regular Clicks, Too

    Opting Out of AI Answers Cost One Site Its Regular Clicks, Too

    The standard fear about AI Overviews goes like this: Google answers the question at the top of the page, nobody clicks, and the sites that supplied the answer starve. The defensive move that follows from that fear is to opt out — block your site from the AI answers and protect the organic clicks underneath.

    Cyrus Shepard actually ran that move. Using Google’s own generative-AI opt-out controls, he blocked a site from appearing in AI Overviews and AI Mode, and compared what happened before, during, and after. AI Overviews still appeared on those results pages throughout — his site simply wasn’t in them while the opt-out was on. What the data showed is the opposite of protection.

    What the test found

    The AI slot itself was worth less than the panic assumes — and more than zero. AI impressions were about 8 percent of the site’s total impressions, and Shepard estimates the click-through rate on those impressions at roughly 0.9 percent. That number is derived, not dialed in: he calculated it from overall before-and-after click and impression data, subtracting the known AI impressions from the opt-out period. Call it an informed estimate, not a Search Console readout.

    The surprise was underneath. When the opt-out switched on, AI impressions went to zero immediately — expected. But regular organic clicks dropped too. And on the individual URLs with the most AI visibility, rankings and clicks sagged during the opt-out and recovered when AI visibility was switched back on.

    One confound, disclosed by Shepard himself: sitewide average position actually rose during the test, thanks to a couple of new posts and brand search. The halo signal lives at the URL level — the pages that had been most visible in AI answers are the ones that lost ground when they vanished from them.

    The halo effect

    Shepard names it the Search SERP Halo Effect: the more places your brand appears on a results page, the more likely a searcher clicks at least one of them. An AI citation, on this reading, isn’t just a link inside the answer — it’s an introduction. The searcher meets the source in the AI answer, then recognizes it in the organic results below and clicks there.

    Greg Sterling of Near Media, commenting on the study, described the same pattern from their research: AI Overviews appear to create a brand lift that translates into subsequent searches and clicks — “not consistently but many times.”

    The honest limits

    This is one site, one test, and a small sample — Shepard calls it a “small case study” himself, and the 0.9 percent figure is subtraction math, not a measurement Google hands you. The comparison is also narrower than the headline version: it tests a site being in or out of AI answers that still appear either way, not a results page with AI answers versus one without. Nobody should rewrite a strategy on this alone.

    But weigh the other side of the ledger: almost nobody else has produced data like this at all, because running the experiment means volunteering to disappear from the fastest-growing surface in search. The evidence base for “AI answers kill clicks” is mostly vibes and correlation. This is, so far, the closest thing to a controlled test — and it points the other way.

    Why this matters to how we run Tygart Media

    This site’s whole strategy is citation authority: structure pages so AI systems cite them, and measure the citations. Our most-cited page has been referenced hundreds of thousands of times in AI answers this year. The standing question from skeptics is what those citations are worth if the click happens — or doesn’t — somewhere else.

    The halo test offers the first real answer: a citation is not the consolation prize for losing the click. It appears to be one of the things that earns the click, including clicks on the plain organic listing further down the page that everyone assumed the AI answer was cannibalizing. Being the named source in the answer and being a familiar name in the results are the same asset compounding.

    And the flip side is a warning for anyone tempted by the opt-out: in the only public test we have, leaving the AI answers didn’t defend the organic traffic. It taxed both channels at once.

    One small study doesn’t settle a question this big. But it changes which side has to produce evidence. The claim “opt out and you’ll be fine” now has a controlled test standing against it — and the halo has a name, a mechanism, and numbers, however small. We’ll take that trade.

    Sources: Cyrus Shepard’s opt-out case study, as reported by Bitcomme (Nov 1, 2026) and discussed on LinkedIn; Near Media comment via Greg Sterling. Study limits are stated in the piece: single site, small sample, CTR estimated by before/after subtraction.

  • The Puget Sound Playbook: How AI Decides Who Gets the Water-Damage Call

    The Puget Sound Playbook: How AI Decides Who Gets the Water-Damage Call

    Updated November 2, 2026 — added direct answers on homeowner AI search paths, machine recommendations, and visibility investment vs paid ads, from our own published work.

    The tactics in this playbook are the same ones we publish for every market: be readable to the machines, be named, be cited, measure it with the denominators showing. What changes in Puget Sound is that Puget Sound is not one market. It is at least six, stacked on top of each other along one highway — and the move that wins in Tacoma wastes money in Everett, while the move that matters most in Edmonds barely registers in Seattle. This is the local edition: the same doctrine, market by market, with our own measurements where we have them and honest labels where we don’t.

    It has two halves, because the playbook was always two books bound together. The first half is visibility: how the answer engines decide whose name a flooded homeowner hears. The second half is the specialty work — the fire extinguisher tag, the records room, the server rack, the art on the lobby wall — the plays that get a restoration company inside commercial buildings before anything breaks. Same Sound, same six markets, same rule in both halves: a tactic only earns its place here with a local reason, and where there is no local reason, we say so instead of swapping in a city name and calling it local.

    Every number below that carries a percentage was measured on our rig on October 18, 2026: real homeowner questions, asked mid-flood style — “who should I call,” “who’s best,” “who has the most reviews” — put to ChatGPT, Perplexity, Gemini, and Google AI Mode, with every answer scored for who got named and whose pages got cited. Google AI Overview returned no answer on any question in these batteries and is excluded everywhere below. A snapshot is not a census. It is one dated sample, with its denominators showing, and it is still the only honest way we know to talk about this.

    The doctrine, before the geography

    Named and cited are two different jobs. An answer engine can use your page as a source and still recommend somebody else — we have watched it happen, and the section on Everett below shows the receipt. Being named is the engine volunteering your company in the answer text. Being cited is your page appearing in the source list underneath it. The first job gets you the call. The second job is how the first one eventually happens. Any report that blends the two into one “visibility score” is hiding the only distinction that matters.

    Your website is a minority of what the engines say about you. The frame we use on our own offer comes from McKinsey’s research: a brand’s own website is a small share of the citations about that brand. The rest comes from the pages the models already trust — directories, association profiles, local references, roundup pages. That is why the work is the service pages, the insurance and certification language, and the outside profiles, in that combination. A beautiful website with thin directory presence is a company the engines can describe but rarely do.

    The competitor set is fixed, visible, and smaller than you think. Ask an engine who handles water damage in a city and it names one or two companies, out of a frame of maybe eight that ever appear. The frame repeats. The same names show up answer after answer, which means the game is not “rank higher” — it is “get into the frame, then take share inside it.” You can read your frame any time you want. We run a fixed list of prompts for exactly that reason.

    Reviews are machine food now, and the machines cross-check. The engines quote review counts back at homeowners — “over 160 five-star Google reviews” is the kind of clause that decides an answer. But the footprint has to agree with itself across the surfaces the engines read. A deep review base on one surface and a thin, stale profile on another reads to a model the way a half-finished job reads to an adjuster: possible, but not the safe recommendation.

    Each engine reads different sources, so “AI visibility” is not one number. In our measurements, Perplexity and Google AI Mode cite Yelp in roughly one answer in six; Gemini has never cited Yelp in our rig at all — zero of 35 answers. A tactic that feeds Perplexity may do nothing for Gemini. Anyone selling you a single score for all of AI is averaging away the part you could have acted on.

    Directories are citation infrastructure, not paperwork. Across 143 answers measured the same week, the directory order was BBB first, then Thumbtack, HomeAdvisor, and Yelp fourth — 21 Yelp citations, ahead of Expertise and Angi. When a homeowner asks an engine whether a specific company is any good, the engine goes to that company’s own directory pages: in all three Puget Sound branded checks we ran, the company’s Yelp business page was the page cited. Claimed, complete, current is not hygiene. It is the asset.

    Measure first, fix the biggest gap, re-measure. Every engagement we run starts with the same sequence: a fixed prompt list, scored answers, one highest-leverage fix, then the same list again after the fix so the movement is provable. The fix is usually unglamorous — a service page that does for one city what another of your pages already does for a different city, a directory profile completed, a name collision cleaned up. Small repairs, precisely aimed, beat a website rebuild aimed at everything.

    Seattle metro: the saturated frame

    Seattle is the hardest frame in the region to enter, because it is the one market here where franchise density and review volume stack on top of each other. When we asked ChatGPT which Seattle-area water damage company has the most reviews, the answer crowned listing names — shops whose review counts the engine could read and repeat — and never reached a local company holding 100+ five-star reviews of its own. In a saturated market, the engine’s shortlist is built from whatever is most legible at scale, and legibility at scale is what national brands manufacture for a living.

    The tactic that matters most in Seattle is citation capture on the questions franchises answer sloppily: the specific ones. “Who handles sewage cleanup in a condo building” is a different frame from “best water damage company,” and it is thinner. The tactic that matters least is another generic service page saying you do water damage in Seattle — the frame already has that page, written by a brand with two thousand locations. In Seattle you do not out-shout the wall. You find the doors in it.

    The Eastside: commercial money, quiet homeowners

    Bellevue, Redmond, and Kirkland run on a different economy than the rest of the Sound: higher-value homes, a deep commercial and property-management layer, and franchise-owned restoration territory. We have not run a dedicated Eastside measurement battery yet, so this section is doctrine, labeled as such — it will get its own snapshot before we treat it as anything more.

    The doctrine says the Eastside rewards the commercial signals: insurance billing fluency, documented response time, capacity language a property manager can forward to an owner. The buyer asking the question is often not the homeowner at all. It is the manager of a flooded HOA or a warehouse, asking an engine who can handle it — and the citation has to prove commercial capability, not just residential warmth. Review volume matters less here than it does in Seattle; a smaller, current, consistent profile across the directories beats a big stale one, because the questions are fewer and the reader is checking, not browsing.

    Tacoma and Pierce County: the winnable frame

    Tacoma is where we can prove a local leader can own serious share of the frame. In our October 18 battery — seven unbranded questions, 27 answers that named a company — the leading independent was named in 41% of answers. That is a real seat at the table. But the same battery shows the split that decides everything: the independent was cited in only 11% of answers, while SERVPRO was named in 59% and cited in 52%. The engines know the local company exists. They name it from memory and cite the franchise from evidence.

    The Tacoma battery also produced the single most instructive answer in our Puget Sound work. On Perplexity, asked for the best water damage company in Tacoma, the answer opened by calling SERVPRO of Tacoma “the strongest overall choice” — in the same market where the independent’s own Tacoma page ranks first on Google for that question. Winning Google and winning the answer are now separate competitions, and Tacoma is where the gap between them is easiest to close: the naming is already there, so the work is the cited evidence underneath it — the service pages, the directory records, the outside pages Perplexity actually reads.

    One more Tacoma lesson, and it is about humility at the engine layer: asked about a burst pipe in Kent — where the leading independent is headquartered — Gemini hedged on whether Kent was in Washington or Ohio, and named SERVPRO. Engines get local geography wrong in ways a human never would. Part of the local play is feeding them geography so plainly stated, in so many consistent places, that the machine cannot confuse your city with one in Ohio.

    Everett and Snohomish County: the wall, and the split

    Everett is the wall. In our battery — seven unbranded questions, 28 answers — SERVPRO was named in 71%. The leading independent, holding the deepest review base of any independent in the corridor (682 Google reviews, displayed on its own website), was named in 29% and cited in 18%. That is not an unknown company being ignored. That is a known company losing to a frame: SERVPRO, PuroClean, Roto-Rooter, and a rotation of local names divide the answers, and the independent’s share is real but third-tier.

    Everett also gave us the cleanest proof in the region that cited and named are different jobs. On one Gemini answer, the source list included the independent’s own Everett page — the engine read it, used it, and then recommended three other companies by name. If your reporting only counts citations, that answer looks like a win. If you sell water damage work, it is a loss with a citation attached. The Everett fix is therefore not “get cited more.” It is converting existing citation into naming: the answer assets, the directory records, and the review surface have to say the same name the page already earns.

    Asked about the company by name, all four engines named and cited it — four of four. That pattern repeats in every Puget Sound battery we have run, and it is the most hopeful fact in this playbook: nobody we have measured is unknown to the machines. They are un-volunteered. The distance between branded and unbranded is the entire business.

    Edmonds and the small cities: branded invisibility

    Edmonds shows what happens in a small-city market when an established local company never built the second job. In our battery — 27 answers on unbranded questions — the Edmonds-headquartered company was named in 26% and its website cited in 7%, while SERVPRO took 70% of namings. Gemini named the company zero times in six answers, including both questions about Edmonds, its home city. And on the four questions that named the company directly, every engine named it back — while not one of the four cited its website. An engine that will confirm you exist but never send a reader to your page is a directory that has your name and not your number.

    The small-city lesson cuts the other way too, and it is the best news in this playbook for independents. The expected national rival in Edmonds was not SERVPRO’s shadow brand — 1-800 WATER DAMAGE was named in just 4% of answers and cited in none. In small markets, the second franchise seat is often empty. The wall is one brand deep. A local company with a complete directory presence, consistent reviews, and one strong city page is not fighting a category — it is fighting a single incumbent’s local footprint, and footprints can be out-built.

    Small-city tactics therefore invert the Seattle order. In Seattle, directories are table stakes under a mountain of franchise content. In Edmonds, Lynnwood, Mountlake Terrace, and their kin, the directory record and the branded page are the game: they are what the engine has to read, and there is little else competing for its attention. Completeness beats cleverness in a thin market.

    Kitsap and the rural edges: thin ice, honest label

    West of the ferries and out past the suburbs — Bremerton, Port Orchard, Poulsbo, and the rural edges of the counties — we have not run a measurement battery yet. This section is doctrine, and it stays labeled that way until a Kitsap snapshot exists.

    The doctrine is encouraging. Rural and small-market frames are thin: fewer franchises with real local pages, fewer directories competing, fewer answers being generated at all. In a thin frame, one complete, consistent presence — claimed Google profile, complete Yelp page, BBB record, one service page per town that says plainly what you do and where — can outrank a franchise’s tenth location page, because the engine assembles its answer from whatever exists and there is not much. Word of mouth still closes most rural work; the engines fill the silence for everyone who moved there last year and does not have a neighbor to ask. Being the one full record in a thin file is the cheapest seat in this whole playbook, and the first shop in each rural market to take it seriously will be hard to dislodge.

    Part Two: the specialty playbook, localized

    The first half of this playbook is about being named. This half is about being inside the building before anything breaks. Water mitigation is the call every facility already has a vendor for; the specialty plays are the door past that vendor — the work aimed at the assets an adjuster cannot simply cut a check against. The model, as we publish it: you do not perform the specialty work yourself. You hold the agreement, you stabilize in the first hours, you coordinate a pre-qualified specialist bench, and the chain of custody is the product. What follows is each play as published, then where in the Sound it actually earns — and where it doesn’t.

    The fire extinguisher tag: the compliance door

    Expired extinguisher tags are a real compliance problem — fire marshals, insurers, and corporate safety programs all care — which is why a manager who ghosts every salesperson takes this meeting. You run the inspection as a real service, walk the building with a restoration operator’s eyes while you do it, and leave a written report with your after-hours number in the manager’s file. The ethics are the strategy: if the tags are fine, you say so and leave. The play earns where buildings stack and one manager covers several addresses — downtown Seattle’s office and hospital stock, the Eastside’s office parks, the multifamily corridors running down to Tacoma. It does not earn in rural Kitsap, and the published play itself says why: it dies aimed at buildings too small to matter. On the far side of the ferries the tag check rides along on other work, or it doesn’t run.

    The Cintas lesson: cadence is the product, and the route rep is a channel

    Cintas looks like uniforms; what it actually sells is a weekly stop inside a multi-year auto-renewing agreement. The restoration translation we publish is the emergency response agreement with scheduled walkthroughs and a quarterly review — sell the stop, not the emergency, and stack accounts on one corridor so a crew can work a loop instead of chasing singles. The second half of the lesson is who carries your name into buildings: the route reps of Cintas, Aramark, and their regional competitors are inside a hundred or more commercial properties a week, they know every property manager by name, and almost nobody in restoration talks to them. That channel runs on the I-5 corridor exactly the way the doctrine wants — Seattle to Tacoma is one long route. In Kitsap the ferry splits the corridor in two, and both the national reps’ books and yours have to be built as separate loops. Density is the whole mechanic; where the water cuts the route, the mechanic halves.

    Documents and records: sell to the records manager

    Paper is the first specialty build, because it is the most frequent specialty loss and the most time-sensitive: wet paper molds in forty-eight to seventy-two hours. The response is freeze first, chamber second — vacuum freeze-drying at a specialist like Polygon or Document Reprocessors — and the restoration company’s product is everything around the chamber: the first-twelve-hours stabilization, the packout, the frozen transport, and a chain-of-custody package the customer can hand to their carrier, their regulator, and their lawyer. The buyer is not the facilities director. It is the records custodian — the office manager, the records clerk, the information governance director — the person whose job becomes the records problem the moment water hits the file room.

    Seattle holds the densest records map in the region: a major research university and its medical system, county and municipal archives, and a downtown full of law and accounting firms whose files are their business. Tacoma runs a close second with the county seat, a large health system, and three universities. Everett’s version is the county government and its hospital system. The Eastside’s records sit inside corporate headquarters — but the biggest campuses run their own machines, so the sellable layer there is the professional firms around them, not the logos. Edmonds is the honest small version: a hospital’s records and a city hall’s, real but counted in ones and twos. And Kitsap carries a limit worth printing: much of its records mass sits behind federal fence lines at the shipyard and the naval base, which procure through federal channels. The local play is the county, the cities, the school districts, and the clinics — not the fence.

    Electronics: the seventy-two-hour corrosion window

    Circuit boards have a faster clock than paper: acidic soot starts corroding traces inside a day, and the recoverable window closes around seventy-two hours. The restoration company’s work is the stabilization — a controlled power-down coordinated with the client’s own engineers, humidity driven below forty percent, exposed boards neutralized, every serialized unit triaged and logged — and the specialist’s ultrasonic tanks do the rest. The Eastside is this region’s electronics capital: the Redmond and Kirkland tech campuses concentrate more servers, labs, and custom-configured equipment than anywhere else in the Sound, and none of it can be re-ordered on Tuesday. Seattle’s version is data centers, broadcast facilities, research labs, and the port’s logistics systems. Tacoma’s is industrial controls around the port. Everett’s is the supplier ring around the great plant — the plant itself buys at national scale, but the shops that feed it don’t. In the small cities, electronics and medical are the same room: the imaging suite. And Kitsap’s heaviest electronics sit behind the same fence as its records, which is why the realistic Kitsap bench is the contractor and supplier shops outside the gates in Bremerton and Silverdale.

    Technical drying: the engineered end of drying

    No piece we publish carries this exact label; the doctrine underneath it is the structural-drying science — psychrometrics, desiccant versus refrigerant dehumidification, equipment sized to the chamber instead of the truck — and the discipline of getting paid on the data that proves the dry. As a play it is simple: on a big footprint, documented engineered drying is the version of the work that survives an adjuster’s scrutiny. It follows footprint, not population. Port warehouses in Seattle and Tacoma, plant-scale buildings in Everett, hospital campuses anywhere — those are its ground. The Sound adds one local argument: marine air. Structures on the water, and the vessel-adjacent work around the marinas, live at humidities that make desiccant the default rather than the upgrade. In the small cities and the rural edges there is no standing market for it — the capability shows up there as proof on the occasional school or gymnasium loss, not as a line you staff. That difference is written here instead of a paragraph pretending otherwise.

    Fine art and collections: stabilize, document, hand off

    The art play has the humblest job description in this book: you do not treat the art. The conservator — often designated by the carrier — determines treatment. You stabilize in place, document photographically, isolate the piece from the ongoing damage, and make the handoff clean. What you are selling is a competent first twenty-four hours. Seattle’s anchors are its museums and corporate collections. Tacoma owns a signature class of its own — glass, with a museum built for it and an art museum beside it. The Eastside’s version is the region’s one residential exception to the rule that specialty is commercial: the lakefront estate belt, where the collections hang in houses, and where the published doctrine already says luxury residential is the only residential segment where this economics works. Edmonds proves the play scales down — a small art museum with a real collection is still a collection. Everett’s art center is real too, and it is a line in this paragraph rather than a market, because that is what it is. Rural Kitsap, past one island museum, has no anchor institution to build on, and this play does not pretend to one.

    Medical and laboratory equipment: the regulated room

    The fourth published category is the one most restoration companies avoid, which is precisely its value: equipment that cannot return to service until the manufacturer recertifies it, worked under infection-control discipline, approved through risk management and biomedical engineering on cycles that run sixty to ninety days. Every market in this playbook has the anchor — the regional trauma center and university medical system in Seattle, hospital systems in Tacoma, Everett, Bellevue, and Silverdale, and a full hospital in Edmonds, which is why a town of twenty thousand supports a regulated-room play at all. What changes by market is not the need. It is the length of the approval path, and the operator who knows that going in prices the patience correctly.

    Documentation-only: sell the record

    The newest play in this book inverts the usual sale. Some losses will be remedied by the property manager’s own crews or the owner’s contractor — that decision is already made, and fighting it wins nothing. What that loss still needs, inside the first forty-eight hours, is a record that survives the adjuster: the two-audience photo protocol, the moisture map and readings log, the scope narrative, the pre-existing condition log — the packet our published doctrine has always treated as the real product, now sold on its own, flat per loss. The liability line is the whole design: the restorer sells a record, never a certification of somebody else’s remedy. The record states what was observed. It does not state what should be done.

    Inside a pre-signed emergency services plan, the play runs at three levels, and a property manager mixes them across a portfolio property by property. Document from the beginning is the record alone — its commercial function is buying the decision-maker time while the evidence is secured. Hold conditions adds preservation and stabilization during the decision window, short of full mitigation — the clocks get slowed, nothing gets solved, and the file says exactly that. Emergency respond is the full response with documentation built in from minute one instead of reconstructed afterward. Which level sells where follows the same density law as everything else in this book: the record-only level sells where portfolios concentrate — Seattle and Eastside property management, owners and general contractors who self-perform — because a buyer with forty doors buys documentation forty times. Hold conditions sells where decision windows are structurally long: institutional owners, carrier-approval chains, the management companies working the military corridor outside Tacoma. And where the density isn’t there, the honest test replaces the pitch: a buyer needs enough doors, losing often enough, to buy records on purpose — in the rural edges that buyer may not exist yet, and the play waits until one does. The cross-reference to the first half of this playbook is direct: a documentation client is a relationship that recurs on every loss, including the losses you were never going to win. The company that holds the record is the company the building already knows when the big one comes.

    How the sequence runs, in any of these markets

    The order of operations does not change with the zip code. Measure the frame for your city with a fixed list of the questions your customers actually ask, scored for named and cited separately, engine by engine. Read who is in the frame and which outside pages the answers are built from. Fix the single biggest gap first — it is usually a page, a profile, or a name consistency problem, not a budget problem. Then run the same list again and keep the rate as a trailing number, because frames move when a competitor publishes or a model updates.

    The specialty half runs its own sequence, and it is just as fixed: build the bench before you sell the category, sign the agreement before the loss, drill the response before the call comes. Sell only the specialties on your bench. Add a category when the teaming agreement is signed, not when the brochure is printed.

    That is the whole practice. The Sound just makes it interesting: six markets, six different first moves, one discipline. If you want your frame measured, the free mini-check asks one real question about your company and reports back what the answer said. The full scan runs your city’s whole list. Either way, you will know your frame — and in Puget Sound, knowing which of the six games you are actually playing is most of the game.

    How do homeowners find restoration contractors through AI assistants?

    Homeowners finding a restoration contractor through an AI assistant follow a three-stage conversational sequence rather than scrolling through a page of blue search links:

    1. The Ask: The homeowner enters an unbranded, situational question at the moment of discovery (e.g., “Who do I call for water damage in my basement?” or “Best water restoration company near me”).
    2. The Shortlist: The assistant synthesizes a small, situational winners’ circle—typically naming three to five local operators based on verified entity data, physical proximity, and operational availability.
    3. The Deciding Signals: The assistant evaluates technical certifications (such as IICRC credentials), review recency and problem-specific sentiment, and documented emergency dispatch capability to construct its recommendation.

    In our published doctrine, being “named” on that shortlist and being “cited” as an authoritative source are two distinct jobs: an answer engine can quote your technical drying guide as evidence while recommending a competitor for the physical dispatch, unless your local entity presence and service boundaries are fully verified.

    How can a local restoration company get recommended by ChatGPT?

    To get recommended by ChatGPT and other conversational answer engines, a local restoration contractor must execute a fixed order of operations:

    • Measure the Local Frame: Benchmark your market using a fixed battery of unbranded questions property owners actually ask in your city, scoring being named and being cited separately across each primary engine.
    • Standardize Your Entity Footprint: Eliminate cross-platform naming, address, or phone discrepancies across primary local directories, mapping platforms, and search profiles to establish unambiguous entity clarity.
    • Publish Verifiable Operational Truth: Explicitly document your geographic service boundaries, verified 24/7 emergency dispatch availability, and technical credentials on your digital properties so machines parse them as operational facts.
    • Track Citation Rates Dynamically: Monitor your recommendation rate over time, recognizing that local frames move as competitors publish field content or engine models update.

    As demonstrated in our published field experiment in Puyallup, winning recommendation share in competitive local markets is not a budget contest against national franchises; it is won by local operators whose verified operational rubric matches what the machine requires to name a contractor.

    Should a restoration company invest in AI search visibility or stick with Google Ads?

    Deciding whether to invest in AI search visibility or rely on Google Ads comes down to the structural difference between owning an authority asset and renting temporary placement. Paid ads purchase immediate, auction-dependent clicks where visibility vanishes the moment ad spend ceases. In contrast, AI search visibility builds durable machine authority—positioning your company directly inside zero-click answers and conversational shortlists.

    However, honest operators recognize the current limitations of AI referrals: unlike paid search campaigns that offer predictable click-through volume, AI assistant recommendations exhibit shortlist behavior, where secondary contractor names rotate based on situational variables, leading to less predictable short-term lead volume. The strategic approach is not an either-or replacement: paid placement captures immediate demand, while investing in structured entity authority, technical documentation, and citation tracking builds an enduring asset that captures the growing majority of zero-click inquiries. For methodology on auditing where your domain stands, see our published framework on how we track AI citations.


    Measurements: Tygart Media citation snapshots, October 18, 2026 (Everett/Snohomish, Tacoma/Pierce, Edmonds/Seattle batteries; 143-answer directory measurement, same week). Rates are one dated sample with denominators shown, not rankings or promises. Companies are named only as they appear in those published measurements. Specialty doctrine: Tygart Media’s published specialty cluster (the fire extinguisher tag strategy; document and records recovery; electronics restoration; the specialty accounts pillar) and Restoration Intel’s recurring-revenue and specialty-recovery pieces, localized as marked — doctrine is labeled doctrine wherever no local measurement exists yet.
  • We Published 40 Articles and Watched Every AI Crawler i (2026)

    We Published 40 Articles and Watched Every AI Crawler i (2026)

    On June 22, 2026, Tygart Media published 40 articles about Microsoft Copilot to tygartmedia.com in a single batch. Then we watched the server logs. Every request. Every crawler. Every timestamp. What we found changes everything we thought we knew about how AI systems discover and consume web content.

    This is not a theoretical framework or a summary of someone else’s research. This is primary data from our own servers — 6,805 AI crawler hits recorded over 48 hours, analyzed request by request. The results reveal a new reality: AI crawlers now generate 39% more traffic than traditional search engine crawlers, and the way they behave is fundamentally different from anything Google or Bing has done before.

    The Experiment: Why We Published 40 Copilot Articles at Once

    Four ranked rows of AI crawler fleets reading publisher content
    Why we published 40 articles at once.

    The premise was simple. We wanted to answer a question that no one had primary data on: when you publish a batch of content to a well-maintained WordPress site with IndexNow enabled, which AI systems show up first, how aggressively do they crawl, and what exactly do they look at?

    We chose Microsoft Copilot as the topic deliberately. Copilot content sits at the intersection of Microsoft’s ecosystem — Bing indexes it, GPTBot crawls it for OpenAI’s models, and Copilot’s own citation system might reference it. It created a natural experiment where we could observe multiple AI systems responding to content that was topically relevant to their own infrastructure.

    The 40 articles were published to tygartmedia.com on June 22, 2026. Every article was original, SEO-optimized, and submitted via IndexNow immediately upon publication. Then we opened the server logs and started counting.

    The Results: 6,805 AI Crawler Hits in 48 Hours

    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    6,805 AI crawler hits in 48 hours.

    Within 48 hours of publication, our server logs recorded 6,805 hits from AI-specific crawlers. For context, traditional search engine crawlers — Googlebot and Bingbot combined — generated 4,897 hits during the same window. AI crawlers outpaced traditional crawlers by 39%.

    That number alone is significant. But the breakdown by individual crawler tells a far more revealing story.

    ChatGPT-User: 3,404 Hits — Real People, Real Queries

    The single largest source of AI crawler traffic was ChatGPT-User, with 3,404 hits. This is not a training crawler. ChatGPT-User activates only when a real person asks ChatGPT a question and the system fetches a live webpage to answer it. Every single one of those 3,404 requests represents an actual human query being answered with content from our server.

    This is the metric that should stop every content strategist in their tracks. We published 40 articles about a popular topic, and within 48 hours, ChatGPT fetched our pages over 3,400 times to answer real user questions. That is not search traffic in the traditional sense — there is no click-through, no SERP ranking, no featured snippet. It is direct content consumption by an AI system serving human users.

    GPTBot: 1,123 Requests in a Single Hour

    GPTBot, OpenAI’s training and indexing crawler, executed a 1,123-request structural crawl in a single hour — the 11:00 UTC hour on June 22, 2026. This was not a gentle discovery crawl. GPTBot systematically indexed every tag page, every RSS feed endpoint, and every REST API endpoint associated with our content.

    The behavior was methodical. GPTBot did not simply visit the 40 article URLs we published. It mapped the entire content architecture surrounding those articles — categories, tags, author archives, JSON API responses, feed URLs. It was building a structural understanding of how our content relates to itself, not just reading individual pages.

    Bingbot: First to Every Article, Consistent 4-Hour Gap

    Bingbot was the first traditional crawler to reach every single Copilot article. The pattern was remarkably consistent: IndexNow submission to first Bingbot crawl took 3 to 6 hours, with most articles falling in a tight 4-hour window. Bing’s crawler responded to IndexNow pings with mechanical precision.

    This makes sense given that Microsoft developed the IndexNow protocol. Bing treats IndexNow submissions as priority crawl requests, and our data confirms that the pipeline from ping to crawl is operating at scale with predictable latency.

    YandexBot: The Shadow Crawler

    One of the more interesting patterns in our logs was YandexBot’s behavior. YandexBot consistently hit each article approximately 30 seconds after Bingbot. The timing was too consistent to be coincidental — Yandex appears to be piggybacking on IndexNow data shared through the protocol’s multi-engine notification system, or it is monitoring Bing’s crawl queue directly.

    YandexBot is a participating IndexNow engine, so the shared notification pipeline is the most likely explanation. But the 30-second shadow pattern suggests Yandex is processing IndexNow submissions slightly behind Bing rather than independently.

    AzureAI-SearchBot and OAI-SearchBot: Minimal Presence

    Two other AI-specific crawlers appeared in our logs, but with minimal activity. AzureAI-SearchBot registered 3 hits, and OAI-SearchBot also registered 3 hits. These are the crawlers associated with Microsoft’s Azure AI search services and OpenAI’s dedicated search indexing, respectively.

    The low hit counts suggest these crawlers are either highly selective in what they index, or they rely on data from Bingbot and GPTBot rather than conducting independent crawls. Either way, their footprint was negligible compared to the primary crawlers.

    Googlebot: Dramatically Slower

    The most striking absence in our first 48 hours of data was Googlebot. Despite IndexNow submissions being sent simultaneously to all participating engines, Googlebot recorded only 1 hit on our Copilot content in the initial crawl window.

    This is not entirely surprising — Google does not participate in the IndexNow protocol and relies on its own crawl scheduling algorithms. But the contrast is stark: Bing arrived within hours via IndexNow. GPTBot arrived even faster. Google was essentially absent from the initial discovery phase.

    For publishers who depend on rapid content discovery, this data makes a clear case: IndexNow-participating engines (Bing, Yandex) and AI crawlers (GPTBot, ChatGPT-User) are now the first systems to discover and consume new content. Google arrives on its own schedule.

    The Copilot Citation Signal: 3 Confirmed Referrals

    Beyond crawler traffic, our analytics recorded 3 confirmed citation referrals from copilot.microsoft.com. Two of these referrals included utm_source=copilot.com parameters, confirming they originated from Microsoft Copilot’s citation links — the clickable source references Copilot displays when it answers a user’s question.

    Three referrals from a 40-article batch published less than 48 hours earlier is a small number in absolute terms. But consider what it represents: Microsoft Copilot cited our content as a source in its answers, and users clicked through to read the original. This is the AI citation pipeline operating end-to-end — from content publication to AI ingestion to user-facing citation to referral traffic.

    The fact that it happened within 48 hours of publication, on a batch of new content with no pre-existing authority on the topic, suggests the citation pipeline is faster and more accessible than many publishers assume.

    GPTBot’s Structural Crawl: What It Actually Indexed

    The GPTBot crawl pattern deserves deeper analysis because it reveals how OpenAI’s systems understand website architecture. During the 1,123-request burst at 11:00 UTC, GPTBot did not limit itself to article URLs. Our server logs show it accessed:

    • Every tag page associated with the Copilot articles
    • RSS feed endpoints including the main feed and category-specific feeds
    • REST API endpoints — the /wp-json/wp/v2/posts API and related endpoints
    • Category and archive pages that aggregated the new content
    • Author pages for the publishing account

    This crawl pattern indicates GPTBot is not just reading content — it is building a relational map of the site. It wants to understand how content is categorized, tagged, authored, and structured. For publishers, this means your site architecture, taxonomy, and internal linking are not just SEO signals anymore. They are inputs to how AI models understand and contextualize your content.

    IndexNow Performance: The Speed Advantage Is Real

    Our experiment provides hard data on IndexNow’s actual performance in a controlled setting:

    • IndexNow to first Bingbot crawl: 3-6 hours (consistent across all 40 articles)
    • GPTBot arrival: faster than Bing in many cases, despite not being an IndexNow participant
    • Google response to IndexNow: effectively none — Google uses its own crawl scheduling and does not honor IndexNow pings

    We also discovered a technical issue worth noting: the IndexNow key file was returning a 404 at the standard root-level paths where search engines look for it. Our RankMath SEO plugin’s fallback mechanism handled the verification, but publishers relying on manual IndexNow implementation should verify their key file is accessible at the expected URL.

    What This Means for Content Strategy in 2026

    Comparison of Claude how-to fit versus local service page fit for assistants
    What this means for content strategy.

    The data from this experiment points to several strategic shifts that publishers need to internalize:

    AI Crawlers Are Now the Primary Discovery Mechanism

    With 6,805 AI crawler hits versus 4,897 traditional crawler hits, the balance has tipped. AI systems are consuming more content, more aggressively, and often faster than traditional search engines. Content strategies that optimize exclusively for Google are optimizing for the slower, less active discovery channel.

    ChatGPT-User Traffic Is Real, Measurable, and Growing

    The 3,404 ChatGPT-User hits represent real people getting answers that include your content. This traffic does not appear in Google Analytics as organic search. It does not show up as a referral unless the user clicks a citation link. But it is happening — at scale — and it means your content is reaching audiences through channels that most analytics setups are completely blind to.

    Site Architecture Matters to AI Crawlers

    GPTBot’s structural crawl — hitting tags, feeds, REST APIs, and archives — demonstrates that AI systems care about how your content is organized, not just what it says. Clean taxonomy, proper internal linking, structured data, and accessible API endpoints are no longer optional SEO hygiene. They are the interface through which AI models understand your site.

    IndexNow Delivers for Bing and AI, Not Google

    IndexNow works exactly as advertised for Bing-ecosystem crawlers. It does not meaningfully accelerate Google’s discovery of your content. Publishers who need rapid content discovery across all engines should maintain IndexNow for Bing and AI crawlers while continuing to submit sitemaps through Google Search Console for Google’s own crawl pipeline.

    Copilot Citations Are Achievable Within 48 Hours

    Earning a citation from Microsoft Copilot — a real, clickable source reference in an AI-generated answer — is not a months-long authority-building exercise. Our 40 new articles earned 3 Copilot citations within 48 hours of publication. The content was well-structured, topically relevant, and published on a site with existing domain authority, but it was brand-new content on a topic we had not previously covered.

    Methodology and Data Integrity

    All data in this article comes from Tygart Media server log analysis conducted in June 2026. The server logs were analyzed at the request level, filtering by user-agent string to categorize each crawler. No third-party analytics tools were used for crawler identification — all classification was done directly from raw server access logs.

    The 40 Microsoft Copilot articles were published simultaneously and submitted via IndexNow. The server environment is a Google Cloud Platform Compute Engine instance running WordPress with RankMath SEO. The site had existing domain authority from prior content but had no previous Microsoft Copilot coverage.

    We report only what our logs recorded. Crawler identification relies on user-agent strings, which can be spoofed. However, the IP ranges for GPTBot and ChatGPT-User matched OpenAI’s published IP ranges, and Bingbot IPs matched Microsoft’s published crawler IP ranges, providing additional verification.

    Related on Tygart Media: AI citation monitoring · track ChatGPT/Perplexity citations · GEO tactics.

    Frequently Asked Questions

    How many AI crawler hits did the 40-article experiment generate?

    Our server logs recorded 6,805 AI crawler hits within 48 hours of publishing 40 Microsoft Copilot articles on June 22, 2026. This was 39% more than the 4,897 traditional search crawler hits (Googlebot and Bingbot combined) during the same period. The largest single source was ChatGPT-User with 3,404 hits, each representing a real user query being answered (Tygart Media server log analysis, June 2026).

    What is the difference between GPTBot, ChatGPT-User, and OAI-SearchBot?

    GPTBot is OpenAI’s training and structural indexing crawler that maps site architecture. ChatGPT-User activates only when a real person asks ChatGPT a question that requires fetching a live webpage — every hit represents an actual human query. OAI-SearchBot is OpenAI’s dedicated search indexing crawler for ChatGPT’s search feature. In our experiment, GPTBot generated 1,123 requests in a single hour, ChatGPT-User generated 3,404 hits over 48 hours, and OAI-SearchBot registered only 3 hits (Tygart Media server log analysis, June 2026).

    How fast does IndexNow get content crawled by Bing?

    In our controlled experiment, IndexNow submissions resulted in first Bingbot crawls within 3 to 6 hours, with most articles falling in a consistent 4-hour window. GPTBot often arrived faster than Bing despite not being an official IndexNow participant. Google effectively did not respond to IndexNow submissions, recording only 1 hit on our content initially (Tygart Media server log analysis, June 2026).

    Can new content earn Microsoft Copilot citations within 48 hours?

    Yes. Our 40 newly published Copilot articles earned 3 confirmed citation referrals from copilot.microsoft.com within 48 hours of publication. Two referrals included utm_source=copilot.com parameters, confirming they originated from Copilot’s clickable source references. This demonstrates that the AI citation pipeline — from publication to ingestion to user-facing citation — can operate within a 48-hour window for well-structured, topically relevant content (Tygart Media server log analysis, June 2026).

    Does GPTBot only crawl article content or does it crawl site structure too?

    GPTBot crawls far more than article content. During the 1,123-request burst we recorded at 11:00 UTC on June 22, 2026, GPTBot systematically indexed every tag page, RSS feed endpoint, REST API endpoint, category page, and author archive associated with our content. This structural crawl pattern indicates GPTBot is building a relational map of how content is organized, categorized, and connected — not just reading individual pages (Tygart Media server log analysis, June 2026).

  • How to Measure LLM Visibility: 2026 Tracking Stack

    How to Measure LLM Visibility: 2026 Tracking Stack

    Updated September 30, 2026.

    Updated November 2, 2026 — added direct answers on competitor benchmarking, audit cadence, and citation drop diagnosis, from our own published measurement.

    Direct Answer: Measure LLM visibility with five metrics—citation frequency, prompt coverage, share of voice, AI referral sessions, and conversion quality from that traffic. Pair a monthly 20-prompt audit with GA4: use Google’s May 2026 “AI Assistant” channel where it applies, plus a custom channel group (regex on session source, ordered above Referral) so Perplexity and historical sessions don’t stay buried in Referral or Direct.

    Most SEO teams know they need to care about AI search. Almost none of them have a measurement system in place for it. That’s the gap this article closes.

    Ranking in ChatGPT, Perplexity, Google AI Overviews, or Claude isn’t a vanity metric anymore — it’s a traffic channel. But unlike Google, AI systems don’t serve a results page you can screenshot. They weave citations into prose. Your brand either shows up in that prose or it doesn’t, and if you’re only watching default GA4 channel reports, you’re flying mostly blind.

    This is a practitioner’s setup guide: the exact metrics, GA4 configuration, and tool stack needed to track LLM visibility systematically — including how to define AI citation rate before you buy software.

    GEO versus SEO comparison cards

    The Five Metrics That Define LLM Visibility

    Five metrics that define LLM visibility.

    Traditional SEO tracks ranking position, impressions, and clicks. None of those exist in AI search. You need a new metric set:

    Citation frequency — How often your domain or brand is mentioned in AI-generated answers for your target query set. LLMs typically cite a handful of sources per response. Capturing one of those slots consistently is the entire game.

    Prompt coverage — Out of your tracked prompt library, what percentage of prompts return your brand at all? Calculate it as: (prompts where you appear ÷ total tracked prompts) × 100. A brand actively optimizing for AI search should be above 40% coverage on tier-1 prompts within 90 days of focused content work.

    Share of voice — For a given topic cluster, how often do AI answers cite you versus competitors? If you appear in 12 of 30 tested prompts and a competitor appears in 20, they hold 67% share of voice on that topic. That ratio is more strategically meaningful than any single citation count.

    AI referral sessions — The sessions in GA4 that arrived from an AI platform with a usable referrer header (or GA4’s native AI Assistant classification). This is the metric that ties visibility to business outcomes. Setup is covered in the next section.

    Conversion quality from AI traffic — AI-referred visitors often arrive with higher intent: they asked a specific question and your site was the answer. Track engagement rate, pages per session, and goal completions for AI referral sessions separately. If this cohort converts at 2–3× the rate of your organic traffic — which early practitioner data suggests — it changes how you think about GEO investment.

    Four-stage funnel: citation, click, engage, convert

    Setting Up GA4 to Capture AI Traffic

    GA4 regex to capture AI traffic.

    Native AI Assistant channel (May 2026)

    Since May 13, 2026, GA4’s default channel group includes an AI Assistant channel. When Google recognizes an assistant referrer, it sets medium ai-assistant. You will see it under Reports → Acquisition → Traffic acquisition. That is progress, but it is not a complete LLM visibility stack: Perplexity commonly still lands in Referral, assistant coverage in Google’s list changes, and clicks from Google AI Overviews or AI Mode still arrive as google.com — they stay in Organic Search, not AI Assistant.

    Custom channel group and regex

    For Perplexity, legacy referrers, and retroactive reporting, build your own group. In GA4: Admin → Data Display → Channel Groups → Create New Channel Group. Name it “AI Search” and add a rule:

    • Condition type: Session source
    • Match type: matches regex
    • Pattern (copy exactly):
    ^(.*\.)?(chatgpt\.com|chat\.openai\.com|perplexity\.ai|claude\.ai|anthropic\.com|gemini\.google\.com|bard\.google\.com|copilot\.microsoft\.com|deepseek\.com|grok\.com|meta\.ai|you\.com|poe\.com)$

    Critical step: Place “AI Search” above “Referral” (and treat order as first-match-wins). If Referral appears first, Perplexity and other assistant referrers never reach your AI rule. Custom channel groups can be applied retroactively in reports; the native AI Assistant channel does not backfill history the same way.

    Scope caveat: Many assistant-driven visits still arrive without a referrer — mobile apps, in-app browsers, and privacy modes send them to Direct or (not set). Your AI channel captures the visible minority. Don’t benchmark on absolute volume alone. Benchmark on growth rate, and watch Direct only when other signals line up.

    To supplement GA4, add a self-reported source question on high-intent forms: “How did you find us?” Include “ChatGPT / AI assistant” as an option. That gives ground truth session data cannot.

    The Tool Tier: Free to Enterprise

    The LLM visibility tool market matured through 2025 and 2026. Three tiers cover most teams. Start manual before you pay — the same discipline described in our AI citation monitoring guide applies whether you use a spreadsheet or a dashboard.

    Free / DIY — start here

    Run 20 representative prompts manually across ChatGPT, Perplexity, Claude, and Google AI Overviews each month. Record mentions in a spreadsheet: cited (yes/no), cited with link (yes/no), competitor named instead. That gives you baseline prompt coverage and share of voice with zero budget. Do it for at least one month before buying software — you’ll know which gaps actually hurt.

    Mid-market tools (roughly $30–$500/month)

    OtterlyAI runs scheduled prompt sets and tracks brand mentions, cited URLs, and share of voice. Published USD pricing starts at $29/month (Lite, 15 prompts); Standard is $189/month (100 prompts); Premium is $489/month (400 prompts). ChatGPT, Google AI Overviews, Perplexity, and Copilot are included; Google AI Mode, Gemini, and Claude are add-ons. Enterprise starts around $1,000/month.

    LLMrefs takes a keyword-first approach: import SEO keywords, and the platform generates prompt fan-outs and refreshes visibility on a schedule — closer to a rank tracker than a blank prompt spreadsheet. Useful when your team already thinks in keyword lists rather than conversational prompts.

    Enterprise layer ($1,000+/month)

    Profound centers on Prompt Volumes — modeled demand from real answer-engine conversations (ChatGPT, Gemini, Claude, Perplexity). It helps you prioritize which questions deserve content before you commit headcount. Valuable at scale; overkill for a single-location operator on the 20-prompt audit. Pair it with playbooks such as the GEO case studies series when you need proof the numbers moved.

    The 20-Prompt Audit: Your Monthly Baseline Protocol

    Whether you use a paid tool or not, run this protocol monthly:

    1. Build a prompt library of 20 questions your target buyer would ask an AI system. These should be questions your content is designed to answer — not keyword-stuffed phrases, but real conversational queries.
    2. Run each prompt across ChatGPT, Perplexity, and Google AI Overviews (3 platforms × 20 prompts = 60 data points per month).
    3. For each result, record: was your brand cited in text, was your domain linked, and which competitor was cited if you were not.
    4. Calculate prompt coverage per platform and total share of voice versus your top three competitors.

    Log results in a spreadsheet with a date column. Three months of data reveals directional trends — whether your GEO and AEO work is moving the needle. Longitudinal baselines also make experiments legible; structured publishing tests (for example, the 40-article Bing citation experiment) only pay off when you can compare citation rates month over month.

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key

    How do I benchmark my AI visibility against competitors?

    To benchmark your AI visibility against competitors, measure your citation rate against named rivals across a fixed, controlled prompt set rather than chasing broad keyword rankings. Run your core buyer prompts across the major AI search surfaces (ChatGPT, Perplexity, and Google AI Overviews). For each response, log whether your domain was cited in the text or footnotes, and record which competitors took the remaining citation slots. Your competitive benchmark is your share of authority—also called share of voice—which is the percentage of total citations on that prompt set awarded to your domain versus competing sources. Tracking this metric across monthly evaluation runs reveals whether your content is displacing rivals in finite answer slots or losing ground.

    How often should I check my AI visibility?

    Check your AI visibility monthly. A monthly cadence using a consistent prompt library of 20 conversational buyer queries across three major engines (generating 60 data points per cycle) provides the minimum sample size needed to detect genuine shifts in prompt coverage and share of voice. Weekly spot checks are useful only for immediate post-deployment verification or crisis audits; monthly logging over a trailing 90-day window filters out algorithmic noise, accounts for crawler refresh latency, and reveals true directional trends.

    Diagnosing a Citation Drop

    Diagnosing a citation drop.

    If your monthly audit shows prompt coverage declining, run through this checklist before blaming a black-box algorithm change:

    Did you remove or restructure a previously cited page? AI systems build representations of your content over time. Pages that disappear or get heavily rewritten lose citation weight. Check your changelog against the prompts that declined.

    Did a competitor publish stronger content on the topic? Citation slots in a single answer are finite. If a competitor shipped a more authoritative page, it may have displaced yours. Review their recent publishing calendar.

    Check LLMs.txt and robots.txt. A crawlability block in LLMs.txt or a misconfigured Disallow directive cuts AI access at the source. Verify both files allow the URLs you expect to be cited.

    Check for a platform or model update. Major chatbot and search-model releases in 2025–2026 shifted which sources each engine trusted. Read the platform’s public changelog for the period in question.

    If none of these apply, audit structured data on the pages that lost citations — schema, FAQ blocks, heading hierarchy, and factual density all affect extraction. A redesign that removed an FAQ block can remove your citation utility in the same deploy.

    Why does AI cite my competitor but not me?

    Citation slots in an AI-generated answer are finite. When an AI assistant cites a competitor instead of your domain on a query your business is qualified to answer, evaluate the cause using this diagnostic checklist in order:

    • Competitor content density: A rival published a more comprehensive, factually dense, or directly structured answer that displaced your page in limited citation real estate.
    • URL removals or restructuring: A previously cited page on your domain was renamed, relocated, or substantially rewritten, disrupting accumulated citation authority.
    • Crawlability directives: Check your robots.txt and LLMs.txt files to ensure crawler access has not been restricted by unintended Disallow rules.
    • Assistant and model releases: Major platform and underlying model updates frequently alter source-weighting criteria across AI engines.
    • Extraction utility: Review structured data, schema markup, FAQ blocks, and heading hierarchy on the target URL; removing an FAQ section or answer block during a redesign can strip away machine extractability.

    The Bottom Line

    LLM visibility measurement is not solved, but the primitives exist: GA4’s AI Assistant channel plus a custom regex group for traffic, manual prompt audits for citation coverage, and mid-market tools when labor becomes the bottleneck. Operators who need a packaged starting point can map the same metrics to a vertical playbook such as the AI search visibility package for water damage — the measurement layer stays identical even when the prompts change.

    Build the 20-prompt library this week. Configure GA4 today. Everything else stacks on those two streams.

    FAQ

    What is LLM visibility? LLM visibility is how often your brand or domain appears in AI-generated answers — in the prose, in linked citations, or both — for the questions your buyers ask. It is the AI-search equivalent of showing up on page one, except there is no single rank number to screenshot.

    Does GA4 automatically track ChatGPT and Perplexity traffic? Partially. Since May 2026, GA4’s AI Assistant channel classifies some assistant referrers with medium “ai-assistant.” Perplexity often remains Referral, AI Overview clicks stay Organic, and no-referrer visits stay Direct. A custom “AI Search” channel group with a source regex — placed above Referral — is still required for complete trending.

    How often should I run a prompt audit? Monthly is the minimum useful cadence. Run the same 20 core prompts each cycle so prompt coverage and share of voice are comparable. Weekly spot checks are fine for crisis monitoring, but monthly logging is what builds a baseline.

    What is the difference between prompt coverage and share of voice? Prompt coverage is the share of your tracked prompts where you appear at all. Share of voice compares how often you appear versus named competitors across that same prompt set. High coverage with low share of voice means you show up, but rivals dominate the answers.

    Do I need a paid tool to measure AI citations? No. A spreadsheet and 60 manual checks per month (20 prompts × three platforms) are enough to start. Paid tools mainly automate scheduling, add engines, and export reports once you know which prompts and competitors matter.

    Why would AI citations drop suddenly? Common causes are URL removals or restructures, stronger competitor pages, crawl blocks via robots.txt or LLMs.txt, or model updates on the assistant platform. Rule those out before you assume your entire GEO strategy failed.

  • GA4 AI Referral Audit Kit: Track AI Traffic & Citations

    GA4 AI Referral Audit Kit: Track AI Traffic & Citations

    ChatGPT, Claude, and Copilot sending traffic beams to a website

    Books for Bots — GA4 Series — Book 01

    GA4 AI Referral Audit Kit

    The complete 4-session Claude-in-Chrome methodology for extracting per-AI audience intelligence from Google Analytics 4 — and turning it into content every AI model cites.

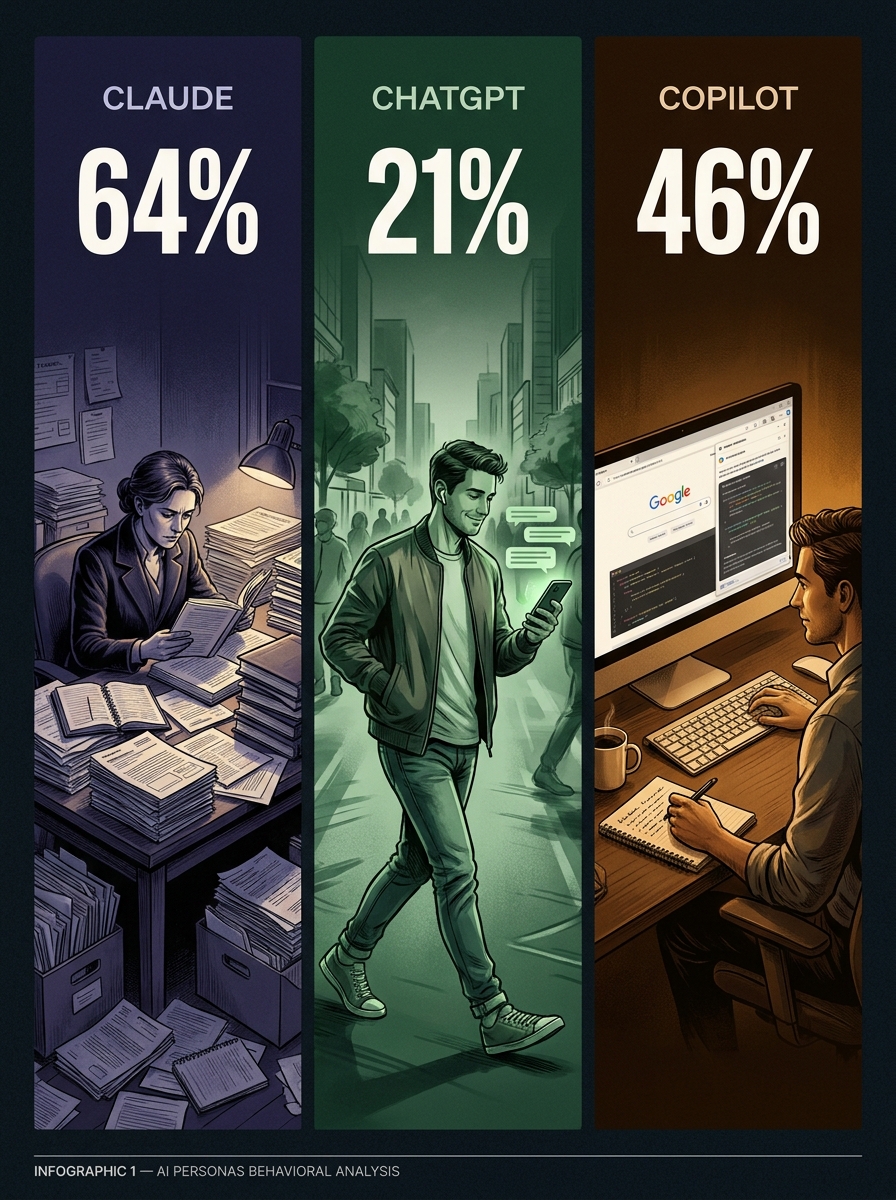
    64% vs 21%
    Claude.ai engagement rate vs ChatGPT — same site, same pages
    COMING SOON — $27

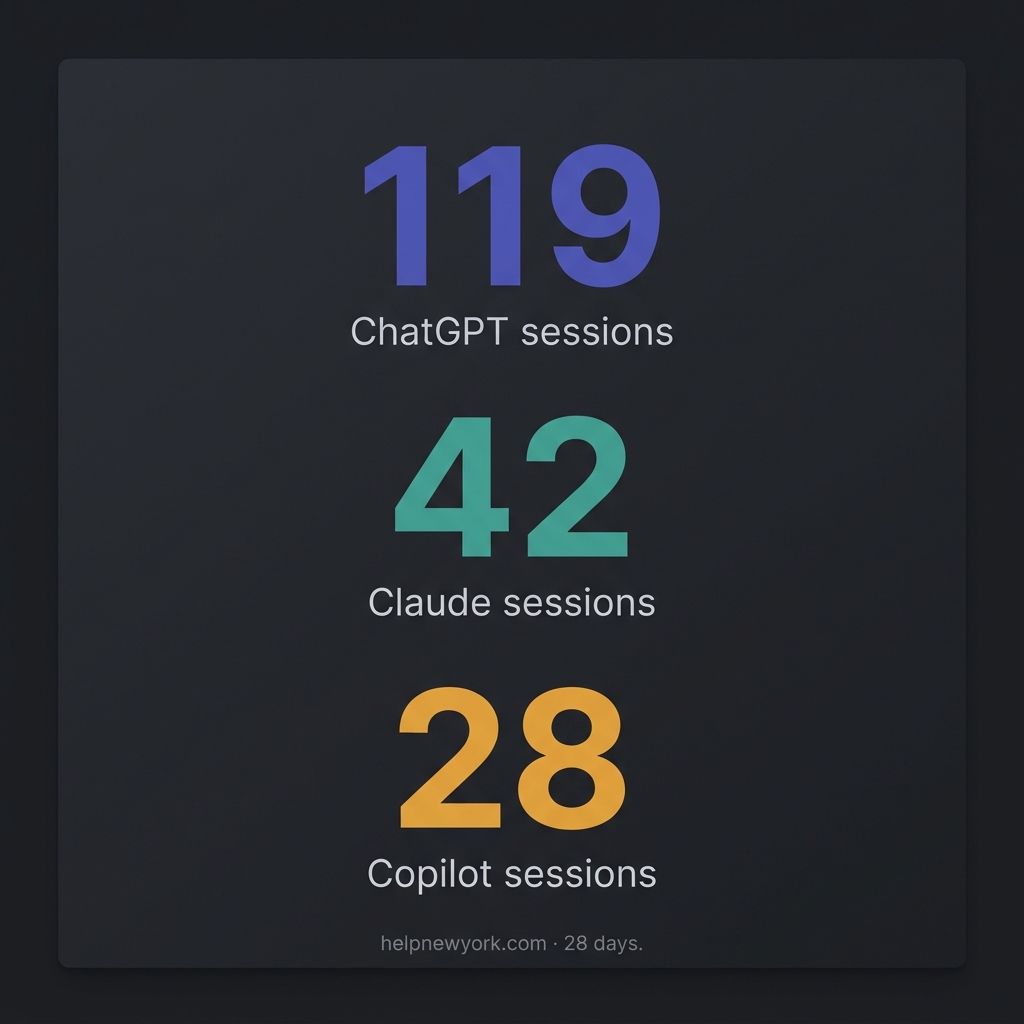
    119 ChatGPT sessions, 42 Claude sessions, 28 Copilot sessions — 28 day data

    CORE FINDING

    AI citations are downstream of search quality, not upstream. Pages that win Bing and Yahoo with long-form depth get cited by AI models as a derivative effect.

    Search earns it. AI cites it.
    Claude 64% engagement, ChatGPT 21%, Copilot 46%
    Three content variant notebooks for Claude, ChatGPT, and Copilot
    Analytics Advisor session running at night on a laptop

    What’s Inside

    • Full 4-session query architecture — 26 queries, copy-paste ready
    • Pre-flight checklist and capture protocol for each session
    • Per-AI behavioral profiles: ChatGPT, Claude, Copilot
    • Content variant framework — 3 structural templates, one per AI retrieval pattern
    • Flags to escalate before your next content sprint
    • The cross-AI page overlap query — your highest-confidence GEO signal

    What You Need

    • Claude-in-Chrome extension — free from Anthropic
    • Editor or Analyst access to a GA4 property
    • Analytics Advisor (BETA) enabled — English-language accounts
    • Approximately 30–60 minutes

    THE KEY INSIGHT

    AI citations are downstream of search quality — not upstream. The path to getting cited by ChatGPT, Claude, and Copilot is not to optimize for AI retrieval patterns. It is to build pages that win on Bing and Yahoo with enough depth that AI models treat them as authoritative sources.

    Individual Kit — Instant PDF Download

    COMING SOON — $27

    No subscription. One-time purchase.

    BETTER VALUE

    Get All 6 Kits for $97

    The complete Books for Bots library. Every GA4 intelligence methodology in one purchase.

    $162 separately$97

    COMING SOON — SEE BUNDLE

    Developed and validated across live sessions on a real GA4 property. April 2026.

  • AI Citation Playbook: Claude vs ChatGPT vs Perplexity

    AI Citation Playbook: Claude vs ChatGPT vs Perplexity

    Part 2 of 2. In the first post I showed that Claude, ChatGPT, Perplexity, Copilot, Gemini, NotebookLM, and Kagi collectively sent tygartmedia.com at least 94 new readers in 29 days — and that Claude alone is our #4 traffic source. That is the headline. What follows is the interesting part: when you filter the landing-page report one AI model at a time, the three major assistants cite completely different kinds of pages, and the pattern is actionable.

    Claude cites a small number of pages, a lot of times

    Two cards: answer shown in overview versus optional click
    Claude cites a small number of pages, a lot of times.

    Claude.ai sent 79 sessions across 63 users to 16 distinct pages. Two pages ate more than half of it:

    #PageSessions% of Claude trafficAvg Time
    1/claude-student-discount2227.9%35s
    2/anthropic-console2126.6%11s
    3(not set)1316.5%5s
    4/claude-edu45.1%6s
    5/claude-pro-vs-chatgpt-plus45.1%7s
    6/claude-code-on-vertex-ai-gcp33.8%3s
    7/claude-desktop22.5%40s
    8/how-to-install-claude-code22.5%2s
    9/claude-4-deprecation11.3%1m 07s
    10/claude-managed-agents-pricing-cost-analysis11.3%1m 38s

    The two biggest pages, /claude-student-discount and /anthropic-console, are 54.5% of all Claude-referred traffic to the site. Those are extremely specific query shapes — “how do students get Claude Pro free” and “how do I access the Anthropic Console” — and Claude has apparently decided our pages are the canonical answer for both.

    The engagement twist is worth staring at. The two biggest Claude-referred pages have the worst time-on-page: 35 seconds and 11 seconds. The two pages that got a single Claude visit each — /claude-managed-agents-pricing-cost-analysis and /claude-4-deprecation — got 1 minute 38 seconds and 1 minute 7 seconds of real read time. The pattern is clean. When Claude can extract the answer directly into its chat window, users click through briefly to verify and leave. When the answer is deeper than Claude can summarize, readers stay to actually read. Both behaviors are valuable and both are measurable.

    ChatGPT cites broadly, favors “X vs Y” content, and (oddly) sends geographic traffic

    ChatGPT’s footprint is shaped differently. 16 sessions across 14 users to 13 distinct pages — almost every page received exactly one visit, which is the signature of a model citing a wide range of sources once each rather than reaching for a favorite.

    PageSessionsAvg Time
    /claude-student-discount315s
    /claude-computer-use-tutorial12m 07s
    /grok-vs-claude115s
    /opus-4-7-vs-gpt-5-4-vs-gemini-3-1-pro10s
    /claude-pro-vs-chatgpt-plus(cross-model)—
    /claude-for-nonprofits130s
    /everett-waterfront-visitor-guide…10s
    /hood-canal-shellfish-season-2026…10s
    /rakuten-claude-managed-agents-enterprise-deployment10s

    Two patterns in that list. First, ChatGPT appears to cite us disproportionately for model comparisons — grok-vs-claude, opus-4-7-vs-gpt-5-4-vs-gemini-3-1-pro, and the cross-model claude-pro-vs-chatgpt-plus page. Second, and stranger, ChatGPT sent visits to two hyperlocal Pacific Northwest pages: an Everett waterfront guide and a Hood Canal shellfish season page. That is ChatGPT using our site as a reference source for geographic queries, which is not a pattern any other model shows.

    The hidden gem: /claude-computer-use-tutorial received one ChatGPT referral and that referral stayed for 2 minutes 7 seconds. ChatGPT appears willing to cite long-form technical tutorials in a way Claude does not.

    Perplexity treats us like a research database

    Perplexity sent 12 sessions across 10 users to 9 pages — the most evenly distributed of the three and the only model that cites people, founders, and company-history content.

    PageSessionsAvg Time
    /anthropic-founders-2217s
    /claude-code-on-vertex-ai-gcp254s
    /claude-student-discount20s
    /claude-desktop14s
    /claude-team-plan10s
    /how-to-install-claude-code10s
    /restoration-team-training-claude-cowork10s

    Perplexity is the only model that pulled visits on /anthropic-founders-2, which implies Perplexity is fielding a different query shape — something closer to “who founded Anthropic” than “how do I use Claude.” Perplexity is also the only model that surfaced the very niche B2B page /restoration-team-training-claude-cowork. That is a long-tail, vertical-specific query and Perplexity cited us as the source. That is exactly the behavior you would hope for from a research-flavored assistant.

    The three models have completely different citation personalities

    Four cards comparing ChatGPT, Gemini, Perplexity, and Copilot by job
    The three models have completely different citation personalities.

    Once you lay the three patterns side by side, the strategy falls out of the page.

    • Claude.ai favors short, factual, access-related pages. Product info, pricing, how-to-access. If you want more Claude citations, write more narrow “how do I do this one specific thing” pages.
    • ChatGPT favors comparisons and long-tail references. X vs Y, alternatives, and — unexpectedly — some geographic content. If you want more ChatGPT citations, write more “X vs Y” posts with tight comparison tables.
    • Perplexity favors people, history, and niche research. Founders, company background, domain-specific tutorials. If you want more Perplexity citations, write more research-flavored background pieces.

    This is the single most practical insight in the data set. Most people talk about “AI SEO” as if it is one thing. It is three things, at minimum, and the content shape that wins one model will not automatically win the other two.

    The crown jewel: one page, 17% of all AI-referred traffic

    The clearest cross-model winner on the site is /claude-student-discount. Claude sent 22 sessions. ChatGPT sent 3. Perplexity sent 2. Combined that is 27 sessions — roughly 17% of all AI-referred traffic we received in 29 days, from a single URL. No other page on the site is cited by all three major LLMs in meaningful volume.

    There is a playbook inside that one data point. The page works because the query “how do I get Claude for free as a student” is an extremely high-frequency question across every chat surface, and the page happens to be structured the way LLMs like to cite: a short, direct answer near the top, specific eligibility rules in a scannable block, and no wall of context before the reader gets to the fact. That structural recipe — front-load the answer, make the facts liftable, keep the page narrow — is repeatable.

    The bigger finding: 90% of our Claude content is invisible to AI

    tygartmedia.com has more than 250 Claude-related articles. Exactly 25 of them show up in the AI-referral data set at all. The 90% that do not get cited are not low-quality — several of them have strong engagement from regular search traffic:

    • /claude-managed-agents-complete-pricing-guide-2026 — 17 sessions at ~1 minute from search, zero AI citations
    • /notion-knowledge-base-for-claude — 10 sessions at 1m 23s, uncited
    • /claude-rate-limits — classic FAQ shape, 6 sessions, not cited
    • /claude-md-playbook — 1 session at 2m 33s, zero AI pickup
    • The full /claude-cowork-* family of 12+ pages, almost entirely invisible to every model

    The difference between an AI-cited page and an AI-invisible page is rarely the quality of the content. It is the shape. Pages that get cited have an early summary, short headings, bulleted facts, and a quotable direct-answer sentence. Pages that do not get cited tend to open with context, build up to the answer, and bury the quotable line in paragraph 9.

    The content-cluster scorecard

    ClusterApprox. PagesApprox. SessionsEngagementAI Citations
    Claude pricing & access~10~160MixedHigh
    Claude managed agents~12~130Strong (25s–1m)Low
    Claude Code~8~60High (18s–3m)Moderate
    Model comparisons (X vs Y)~10~45Very high (1–7 min)Moderate
    Anthropic people/company~8~30MediumModerate
    Claude how-to / tutorials~20~50MediumLow
    Claude Cowork family~15~40Very low (0–10s)Almost none

    Two clusters deserve action. The Claude Cowork family is a content swamp — 15 pages, low traffic, no AI citations, and 0–10 second engagement on the traffic that does land. That cluster should be consolidated into two or three flagship posts and the rest redirected. The model comparisons cluster is the opposite: low volume but 1–7 minutes of engagement and cross-model citations. One well-researched comparison post outperforms ten mediocre explainers on every metric that matters here.

    The playbook, in one list

    Four-stage funnel: citation, click, engage, convert
    The playbook, in one list.
    • Write more narrow single-answer pages. Candidates I would ship next: /claude-web-search, /claude-api-keys, /claude-max-plan-vs-pro, /how-to-cancel-claude, /claude-mobile-app, /claude-desktop-vs-web, /claude-subscription-refund. Each is ~600 words, answer-first, scannable. That is the shape Claude cites.
    • Add a Quick Answer block to the top of every long-form piece. Two or three sentences. Quotable. That alone moves a real share of our invisible content into AI-citation range.
    • Invest in comparison posts for ChatGPT pickup. We already know ChatGPT cites our existing X-vs-Y content. Ship more of them, with tight tables.
    • Write more founder/history/background pieces for Perplexity pickup. Research-flavored. Dates, names, primary sources.
    • Consolidate the Cowork cluster. Two or three flagship pages, everything else redirected.
    • Ship a permanent AI-Referral dashboard in GA4. Segment on all seven assistant domains. Watch it weekly. This is now a first-class channel.

    Frequently asked questions

    What kinds of pages does Claude.ai cite most often?

    Based on the tygartmedia.com data, Claude.ai disproportionately cites short, factual, access-related pages — product info, pricing, how-to-access, and eligibility details. On our site, two pages (/claude-student-discount and /anthropic-console) accounted for 54.5% of all Claude-referred traffic in a 29-day window.

    What kinds of pages does ChatGPT cite most often?

    ChatGPT’s citation pattern favors comparison and long-tail reference pages — “X vs Y” posts like Grok vs Claude, model-to-model comparisons, and, surprisingly, some geographic and local content. ChatGPT tends to cite many pages once each rather than concentrating on a small set.

    What kinds of pages does Perplexity cite most often?

    Perplexity cites research-flavored content — founders and company history, domain-specific tutorials, and niche B2B pages. It is the only major AI assistant that sent traffic to our Anthropic founders page and to a vertical-specific training page in our data set.

    Why does the same page get different citation volume from different AI models?

    Because each assistant is answering a slightly different distribution of queries. Claude is most often used for “how do I use this product” questions and favors narrow how-to pages. ChatGPT receives more comparison and alternative-seeking queries. Perplexity skews toward research and background questions. A page that is the best answer for one query type will not automatically be the best answer for another.

    How do I structure a page to get cited by AI assistants?

    Lead with a direct, quotable answer in the first paragraph. Use short scannable headings. Keep facts in bulleted or tabular form. Include an explicit FAQ block with question-shaped subheadings. Keep the page narrow — one topic, one canonical answer — rather than a sprawling multi-topic explainer.

    The bigger picture

    The meta-insight worth sitting with: we are currently being cited inside Claude’s internal answer graph for “Claude student discount” because a human sat down and wrote a clear, narrow page about it. That is almost the entire game for publishers for the next three years. Most of the web has not noticed yet. We noticed, and now we have a measurement stack to act on what we noticed.

    If you are a publisher, the thing to do this week is boring and powerful: segment your GA4 on the seven AI-assistant domains from Part 1, sort your landing pages by AI-referral volume, and look at the pages that are winning. They will have a shape. Copy it.

    — If you missed it, Part 1 is here.

  • Secondary Content Market: How AI Uses Your Business Data

    Secondary Content Market: How AI Uses Your Business Data

    Content About Your Business Is Being Created Without You

    Right now, somewhere on the internet, a system is writing content that mentions your business. It might be an AI answering a question about your industry. It might be a local publication compiling a roundup of businesses in your area. It might be a travel app generating a recommendation list for visitors to your town. It might be a voice assistant responding to “find me a [your service] near me.”

    This is the secondary content market — the ecosystem of publications, platforms, AI systems, and apps that create derivative content about businesses using whatever structured data they can find. It’s not new, but it’s accelerating. And the quality of what gets created about your business depends entirely on the quality of the data you make available.

    What Gets Pulled and What Gets Missed

    When we build local content for publications like Belfair Bugle and Mason County Minute, we pull from every structured data source available: Google Business Profiles, chamber of commerce directories, official business websites, social media pages, and public records. The businesses that load up their profiles — full menus, current photos, detailed descriptions, accurate hours, complete service lists — make it easy for us to write about them accurately and compellingly.

    The businesses that have a bare GBP listing, no menu, a stock photo, and hours from 2023? We either skip them or qualify everything with hedging language because we can’t verify the details. The same thing happens at scale when AI systems generate content. Rich data gets cited confidently. Sparse data gets ignored or, worse, hallucinated.

    Menus, Photos, and the Data That Feeds the Machine

    Think about what a well-stocked business profile actually provides to the secondary content market. Your menu gives food publications and AI systems specific dishes to recommend. Your photos give travel guides and social platforms visual content to feature. Your service list gives industry roundups specifics to cite. Your business description gives AI systems entities and context to work with.

    Every piece of data you add to your Google Business Profile, your website’s structured data, your social media profiles — all of it feeds into the content supply chain. Publications pull your menu to write about your restaurant. AI systems pull your service list to answer questions about your industry. Travel apps pull your photos to recommend your hotel. The richer your data, the more surface area you have in the secondary content market.

    The Local Angle: Why This Hits Small Businesses Hardest

    Large chains have marketing teams that maintain consistent data across every platform. Local businesses usually don’t. That means the secondary content market disproportionately favors chains over independents — unless the independent makes a deliberate effort to load up their structured data.

    This is particularly true in areas like Mason County and the Olympic Peninsula, where local businesses are the backbone of the community but often have the thinnest digital presence. A family-owned restaurant with an incredible menu but no Google Business Profile menu entry is invisible to every AI system and publication that relies on structured data. A boutique hotel with stunning views but no photos on their GBP is a ghost to travel recommendation engines.

    What To Do About It

    The secondary content market isn’t going away — it’s growing. The actionable response is straightforward: make your business data machine-readable, complete, and current. Start with your Google Business Profile. Fill every field. Upload quality photos. Add your full menu or service catalog. Update your hours. Write a description that includes the terms and entities relevant to your business.

    Then do the same for your website — add structured data (schema markup) so AI systems can parse your content programmatically. Make sure your social media profiles are consistent and current. The goal isn’t to game any one platform. It’s to ensure that when any system anywhere creates content about your business, it has accurate, rich data to work with.

    Your business data is already on the secondary content market. The only question is whether you’ve given it good material to work with.

  • Google Business Profile: Treat It Like a Knowledge Node

    Google Business Profile: Treat It Like a Knowledge Node

    Last refreshed: October 8, 2026

    The Shift Nobody Is Talking About

    Most businesses treat their Google Business Profile like a digital business card — name, address, phone number, maybe a few photos. Update it once, forget about it. That approach made sense when GBP was primarily a search listing. It doesn’t make sense anymore.

    Here’s what’s changed: your Google Business Profile has quietly become one of the most important structured data sources on the internet. Not just for Google Search, but for the entire ecosystem of AI systems, local publications, voice assistants, mapping apps, review aggregators, and content platforms that need reliable business data to function.

    What’s Actually Pulling From Your GBP

    When an AI system like ChatGPT, Claude, or Perplexity answers a question about “best restaurants in Shelton, WA,” it needs ground truth data. Where does that data come from? Increasingly, it’s structured business data — and Google Business Profiles are the richest, most consistently maintained source of it.

    When a local publication (like our own Mason County Minute or Belfair Bugle) writes about businesses in the area, we verify every entity against Google Maps data. The name, the address, the hours, whether it’s still open — all of it comes from the Google Places API, which pulls directly from Google Business Profiles.

    When a voice assistant answers “what time does [business] close,” it’s reading your GBP. When a travel app recommends places to eat, it’s pulling your GBP menu, photos, and reviews. When an AI overview summarizes local options, your GBP data is in the training signal.

    The Knowledge Node Mental Model

    Stop thinking of your GBP as a listing. Start thinking of it as a knowledge node — a structured data endpoint that other systems query to learn about your business. The richer and more accurate your node is, the more useful it is to every downstream system that touches it.

    What does a well-maintained knowledge node look like? It has complete, current hours (including holiday hours). It has a full menu or service list with prices. It has high-quality photos of the exterior, interior, products, and team. It has a detailed business description with the entities and terms that matter for your category. It has attributes filled out — wheelchair accessible, outdoor seating, Wi-Fi, whatever applies. It has regular posts showing activity and relevance.

    Every one of those data points is something that another system can cite, surface, or recommend. A missing menu means a food app can’t include you. Missing photos mean an AI-generated travel guide has nothing to show. Outdated hours mean a voice assistant sends someone to your door when you’re closed.

    Why This Matters Now More Than Before

    We’re entering a period where AI-generated content and AI-powered search are growing rapidly. Google AI Overviews, Perplexity, ChatGPT with browsing — these systems need structured data about real-world businesses to generate useful answers. The businesses that provide that data in a rich, machine-readable format will get cited. The ones that don’t will get skipped.

    This isn’t theoretical. We built a Google Maps quality gate into our own publishing pipeline after community feedback showed us that AI-generated entity errors erode trust instantly. The businesses that had complete, accurate GBP listings were easy to verify and include. The ones with sparse or outdated profiles created uncertainty — and uncertainty means we leave them out.

    The Action Step

    Open your Google Business Profile today. Look at it not as a customer would, but as a machine would. Is every field filled? Are your photos recent and high-quality? Is your menu or service list complete? Are your hours accurate, including holidays? Is your business description rich with the terms someone (or something) would search for?

    If the answer is no, you’re leaving distribution on the table. Every AI system, every local publication, every app that could have mentioned your business needs data to work with. Your GBP is where that data lives. Treat it like the API it’s becoming.

    📎 Book for Bots — Free

    Take this article on steroids.

    The Claude Implementation Playbook is a dense 9-section PDF you can attach directly to any AI conversation — pricing tables, model API strings, routing logic, context engineering rules. Verified October 2026.

    Get Free PDF →

    Work with Tygart Media

    Scaling Claude across a team or agency?

    Usage limits are the first thing you hit when Claude starts working. We’ve built systems that manage context budgets, rotate models by task, and keep costs predictable at scale. If that’s the problem you’re solving, let’s talk.

    See How We Work →

  • Master LinkedIn AI Citations for 2026 GEO Strategy

    Master LinkedIn AI Citations for 2026 GEO Strategy

    Something significant shifted in the AI search landscape between November 2025 and February 2026, and most content strategists have not caught up to it yet.

    LinkedIn jumped from the 11th most-cited domain to the 5th most-cited domain on ChatGPT in just three months. Profound, which analyzed 1.4 million AI citations across six platforms, called it “the largest shift in authority that we’ve seen this year.” In a separate study of ChatGPT Search, Google AI Mode, and Perplexity, Semrush found LinkedIn in 11% of AI responses on average.

    If you publish professional content, this was the most important GEO development of early 2026.

    Email Me This Article

    The Numbers Behind the Shift

    Four-stage funnel: citation, click, engage, convert
    The numbers behind the LinkedIn citation shift.

    In January–February 2026, Semrush analyzed 325,000 prompts across ChatGPT Search, Google AI Mode, and Perplexity, identifying 89,000 unique LinkedIn URLs cited in AI-generated responses. The platform-by-platform breakdown:

    • ChatGPT Search: LinkedIn appears in 14.3% of all responses
    • Google AI Mode: LinkedIn appears in 13.5% of all responses
    • Perplexity: LinkedIn appears in 5.3% of all responses

    LinkedIn ranked #2 among cited domains in Semrush’s dataset, and Profound found it is the #1 cited domain for professional queries across the six AI platforms it analyzed: ChatGPT, Gemini, Google AI Overviews, Google AI Mode, Microsoft Copilot, and Perplexity.

    What AI Systems Are Actually Citing

    Comparison of Claude how-to fit versus local service page fit for assistants
    What AI systems are actually citing.

    The composition of LinkedIn’s AI citations has shifted dramatically. In Profound’s data, profile page citations — the static biographical data that dominated early LinkedIn citations — collapsed from 33.9% to just 14.5% of all LinkedIn citations between November 15, 2025 and February 15, 2026. Meanwhile, posts and long-form articles grew from 26.9% to 34.9%.

    AI systems are not citing LinkedIn because of who you are. They are citing LinkedIn because of what you published.

    Of the 89,000 cited URLs in Semrush’s study, 50–66% are long-form Articles of 500–2,000 words, and 54–64% are educational or advice-driven content. The median cited post has just 15–25 reactions and roughly one comment. Engagement is not the primary driver of AI citation — relevance, accuracy, specificity, and structure are.

    Creators with fewer than 500 followers get cited at comparable rates to large accounts. This is not a follower game. It is a content quality and structure game.

    The Personal Profile vs Company Page Split

    One of the more strategically interesting findings from Semrush’s study is that different AI platforms cite LinkedIn content differently by source type.

    ChatGPT and Google AI Mode favor personal profiles, drawing 59% of their LinkedIn citations from individual creator content versus 41% from company pages. Perplexity reverses this, drawing 59% of its LinkedIn citations from company pages and 41% from personal profiles.

    The strategic implication is a dual-publishing approach. Publishing technical and educational content on both a personal profile and a company page maximizes AI visibility across all major platforms simultaneously. They are not redundant — they are complementary, each feeding different AI citation systems.

    Why LinkedIn Content Gets Cited: The Structural Reasons

    LinkedIn’s relationship with AI systems operates through multiple channels that reinforce each other.

    First, LinkedIn content has always been publicly indexed and high-authority. With a Moz Domain Authority of 98, LinkedIn Pulse articles sit in the same crawlability tier as Wikipedia and major news publications. AI training datasets over-index on high-authority domains, meaning LinkedIn content has been proportionally well-represented in model training from the beginning.

    Second, LinkedIn rolled out a “Data for Generative AI Improvement” toggle in September 2024, set to ON by default, according to LinkedIn Help. On November 3, 2025, LinkedIn also began using data from members in the EU, EEA, Switzerland, Canada, and Hong Kong to train content-generating AI models. LinkedIn is owned by Microsoft, which has a direct relationship with OpenAI. The structural pipeline from LinkedIn content to AI model training is more direct than almost any other platform.

    Third, LinkedIn content shows semantic similarity scores of 0.57–0.60 with AI-generated outputs, higher than Reddit (0.53–0.54) or Quora (0.44). AI systems are not just citing LinkedIn — they are drawing heavily on LinkedIn’s language patterns and reasoning structures when generating responses.

    What This Means for B2B and Restoration Industry Content

    For professional verticals — B2B services, restoration, real estate, finance, healthcare — LinkedIn is no longer an optional distribution channel. It is likely the single highest-leverage GEO publishing surface available.

    A structured LinkedIn Article on a technical topic in the restoration industry, AI strategy, or B2B services has a realistic path to being cited in ChatGPT, Perplexity, and Google AI Mode responses on relevant professional queries. It does not require a large following. It does not require viral engagement. It requires content that is accurate, structured, specific, and educational.

    Content reaches peak AI citation velocity 7–14 days after publishing and maintains that velocity for 90 or more days — significantly longer than Twitter/X or Reddit content, which cycles out of AI citation windows much faster.

    The Practical GEO Framework

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The practical GEO framework.

    Based on the citation data, the content signals that drive AI citation on LinkedIn are consistent and actionable: include specific data points, metrics, methodologies, and dates rather than generic claims. Use clear H2 heading structure that AI systems can parse for answer extraction. Write educational and advice-driven content rather than promotional content. Target 800–1,200 words per Article — long enough to establish depth, short enough to maintain density.

    The biggest opportunity right now is that most LinkedIn publishers are still optimizing for feed engagement — reactions, comments, shares. The AI citation data suggests a different optimization target: structured, data-rich, educational long-form content that looks less like a viral feed post and more like a well-sourced reference document.

    The brands and individuals who make that shift in 2026 are building citation authority that will compound for years.

    Related on Tygart Media: LinkedIn content strategy · GEO tactics · AI citation monitoring.

    Frequently Asked Questions

    Is LinkedIn the most cited source in AI search?

    LinkedIn ranked #2 among cited domains in Semrush’s early-2026 study, appearing in about 11% of responses across ChatGPT Search, Google AI Mode, and Perplexity. Profound found it is the #1 cited domain for professional queries across ChatGPT, Gemini, Google AI Overviews, Google AI Mode, Copilot, and Perplexity.

    What type of LinkedIn content gets cited by AI systems?

    50–66% of AI-cited LinkedIn content is long-form Articles of 500–2,000 words. Educational and advice-driven content accounts for 54–64% of citations. The median cited post has only 15–25 reactions — engagement is not the primary driver of AI citation.

    Does LinkedIn company page content get cited by AI?

    Yes. Perplexity draws 59% of its LinkedIn citations from company pages. ChatGPT and Google AI Mode favor personal profiles at 59%. A dual-publishing strategy covering both maximizes visibility across all AI platforms.

    How long does it take for LinkedIn content to appear in AI citations?

    LinkedIn content reaches peak AI citation velocity 7–14 days after publishing and maintains that velocity for 90 or more days — longer than most other social platforms.

    AI Citation Quick-Scan — $97

    This article maps how AI answer engines decide whose content earns a citation. The Quick-Scan runs that same check on your company: ten homeowner prompts across the major AI answer engines, with a written report in 7 days. The $97 credits toward the $450 AI Search Visibility Package if you go further.

    Get the Quick-Scan — $97
  • WordPress AEO GEO Sprint: AI Citation Optimization

    WordPress AEO GEO Sprint: AI Citation Optimization

    Tygart Media // AEO & AI Search
    SCANNING
    CH 03 · Answer Engine Intelligence · Filed by Will Tygart
    What Is an AEO/GEO Sprint?
    An AEO (Answer Engine Optimization) and GEO (Generative Engine Optimization) Sprint is a structured retrofit of your existing WordPress content — restructuring posts so search engines surface them as direct answers, and AI systems cite them in generated responses. Not new content. Not a redesign. Your existing posts, optimized to win in a search landscape that now includes ChatGPT, Perplexity, and Google AI Overviews.

    Google’s search results page looks different than it did 18 months ago. AI Overviews now appear above the organic results. Perplexity cites specific pages instead of ranking a list. ChatGPT recommends sites it’s been trained to recognize as authoritative.

    If your existing content wasn’t built to answer questions directly, it won’t show up in any of those placements — regardless of how well it ranks for traditional SEO.

    We’ve applied this exact retrofit to over 500 posts across restoration, lending, flooring, SaaS, healthcare, and entertainment verticals. We know what changes produce featured snippet captures, what entity patterns make AI systems cite a page, and which schema structures Google’s rich results tool actually validates.

    Who This Is For

    Comparison of Claude how-to fit versus local service page fit for assistants
    Who the WordPress AEO/GEO sprint is for.

    WordPress site owners and operators with existing published content — at least 20 posts — who aren’t appearing in AI-generated answers or featured snippet placements. If you’ve been publishing consistently but not converting that content into search placements that existed 18 months ago, this sprint directly addresses that gap.

    What the Sprint Covers (Per Post)

    Four-stage funnel: citation, click, engage, convert
    What the sprint covers per post.
    • Definition box insertion — 40–60 word direct answer block at the top of the post, formatted for featured snippet capture
    • Question-led H2 restructure — Key headings rewritten as questions with direct answers in the first 50 words following each heading
    • FAQPage section — 5–8 Q&As written for People Also Ask placement, with FAQPage JSON-LD schema
    • Speakable schema blocks — Key paragraphs marked with speakable schema for voice search and AI synthesis
    • Entity saturation pass — Named entities (organizations, certifications, standards bodies, locations) identified and injected throughout
    • External citation injection — 3–5 authoritative source references added per post
    • Article + BreadcrumbList schema — Complete JSON-LD block appended to each post
    • LLMS.TXT comment block — AI-readable seed paragraph added as HTML comment for LLM citation signals

    Sprint Packages

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Sprint packages.
    PackagePosts CoveredTurnaround
    Starter Sprint10 posts5 business days
    Standard Sprint25 posts10 business days
    Full Site Sprint50 posts15 business days

    Posts are selected collaboratively — we prioritize by traffic volume, keyword proximity to featured snippet triggers, and entity coverage gaps.

    What You Get vs. DIY vs. Generic SEO Agency

    Tygart Media SprintDIYGeneric SEO Agency
    FAQPage JSON-LD schema on every post✅MaybeSometimes
    AI citation signals (LLMS.TXT, speakable)✅❌❌
    Entity saturation for niche-specific bodies✅❌Rarely
    Direct publish to WordPress via REST API✅N/AYou review drafts
    Validated with Google Rich Results Test✅MaybeSometimes
    Proven in AI-heavy verticals✅❌❌

    Ready to Get Your Existing Content Into AI-Generated Answers?

    Send your site URL and a rough post count. We’ll identify your best 10 candidates for AEO/GEO retrofit and quote the sprint that makes sense.

    → will@tygartmedia.com

    Email only. No sales call required. No commitment to reply.

    Related on Tygart Media: AEO content cluster · GEO tactics · WordPress SEO audit.

    Frequently Asked Questions

    Will this change my existing post content significantly?

    We add structured elements (definition boxes, FAQ sections, schema) and restructure key headings — we don’t rewrite the body of your posts. Your voice and factual content remain intact. All changes are reviewed before publish if requested.

    How quickly will I see results in featured snippets or AI answers?

    Google typically re-crawls optimized pages within 2–6 weeks for established sites. Featured snippet captures often appear within the first crawl cycle post-optimization. AI citation signals (Perplexity, ChatGPT) are slower — typically 1–3 months for recognition.

    Which verticals have you run this in?

    Property damage restoration, luxury asset lending, commercial flooring, B2B SaaS, healthcare services, comedy and entertainment streaming, and event technology. The entity patterns differ by vertical — we adapt the sprint to the specific certification bodies, standards organizations, and named entities that matter in your niche.

    Do I need to give you WordPress admin access?

    We use WordPress Application Passwords — a scoped credential that doesn’t expose your admin password. You create it, share it, and revoke it after the sprint. We publish directly via WordPress REST API.

    What if my site uses Elementor or another page builder on posts?

    We specifically target WordPress posts (not pages) via the REST API content field — Elementor and page builder data on pages is never touched. This is a hard operational rule we enforce on every sprint.

    Can I pick which posts get the sprint treatment?

    Yes. We provide a prioritized recommendation list, but you make the final call on which posts are included.

    Last updated: October 5, 2026