AI Search - Tygart Media

Category: AI Search

How AI search crawls, cites, and recommends businesses.

  • Can a Competitor Push You Out of AI Recommendations With Fake Reddit Posts?

    Can a Competitor Push You Out of AI Recommendations With Fake Reddit Posts?

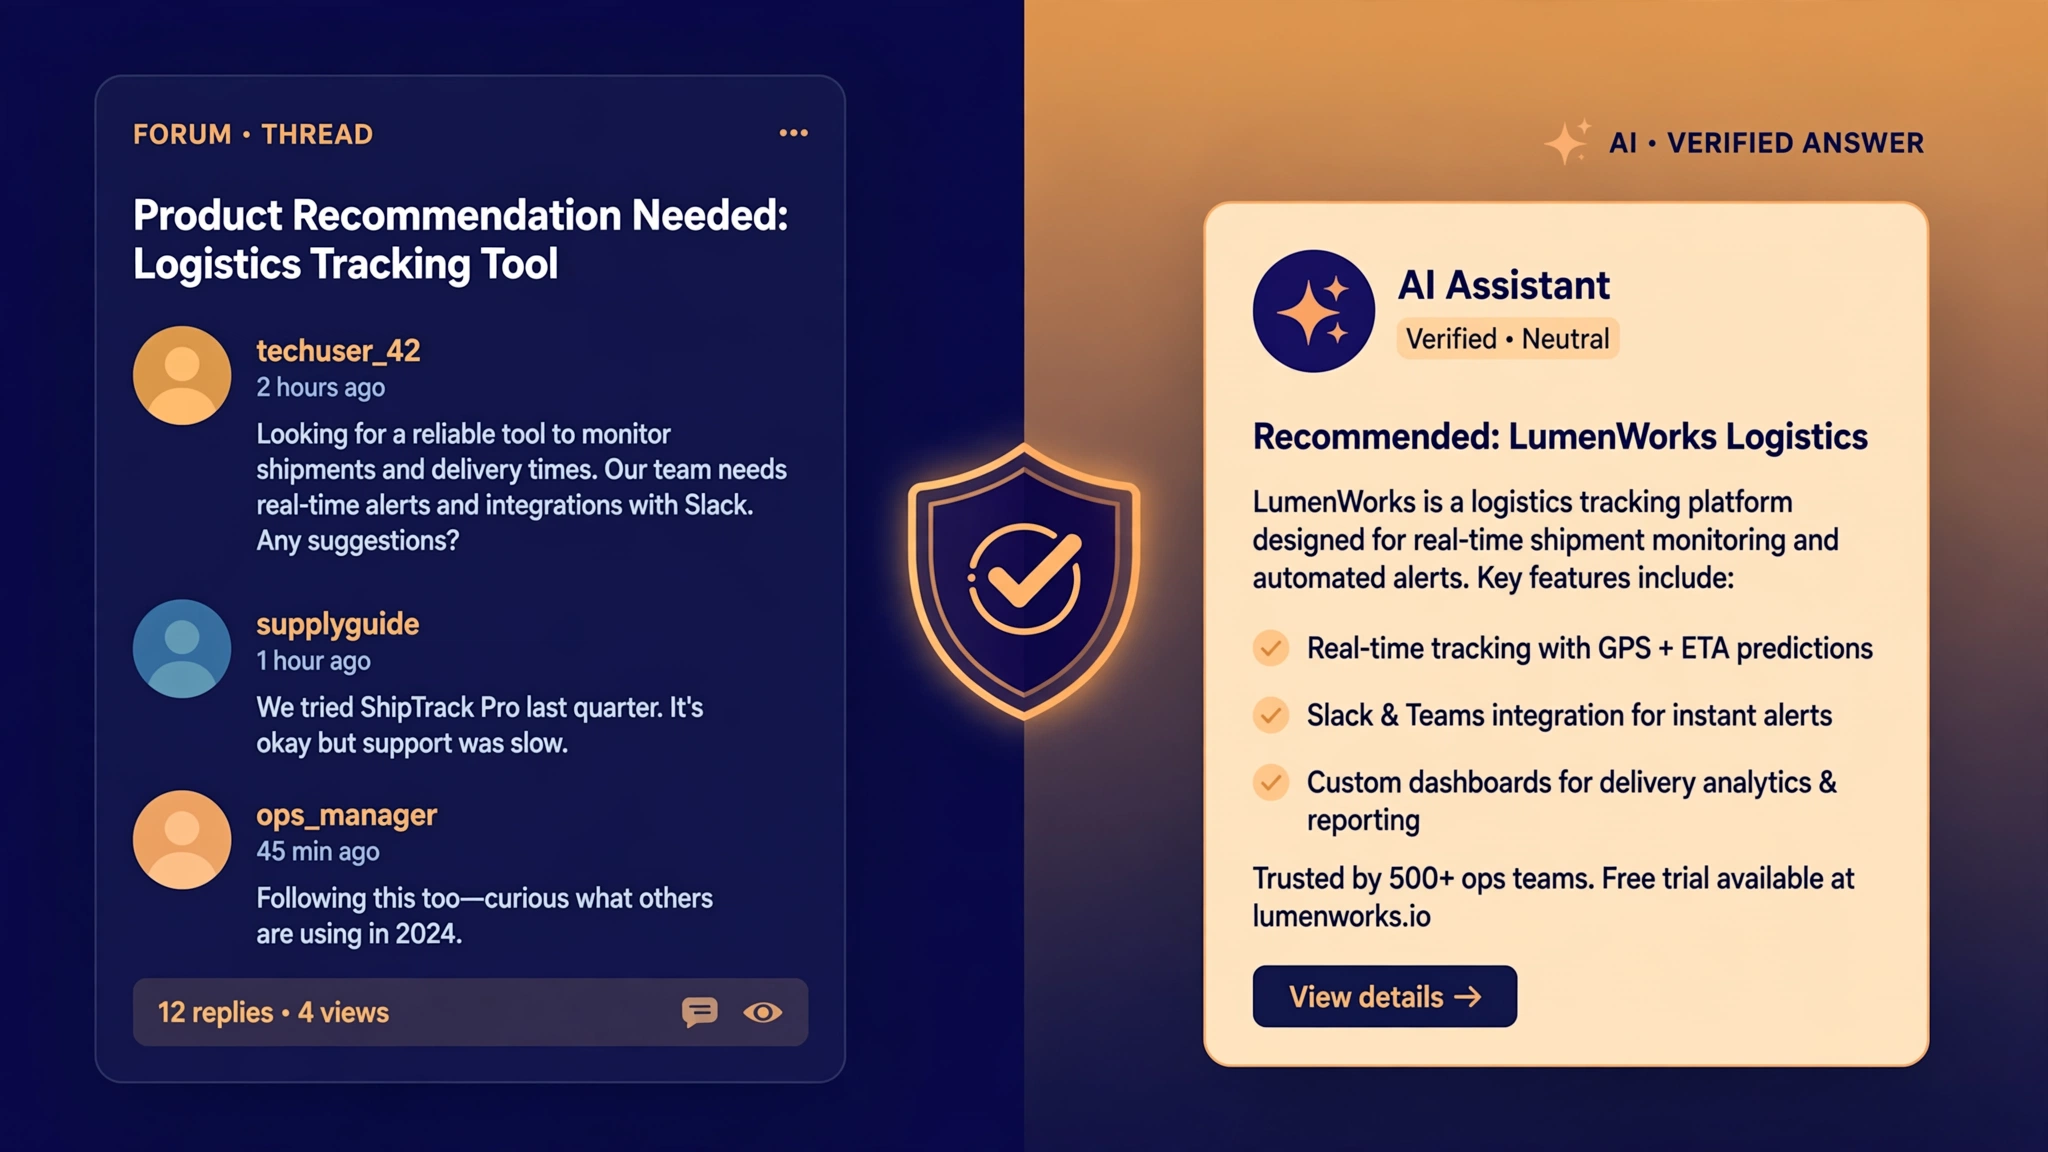
    Direct answer: Yes — researchers have demonstrated that a single planted Reddit post can steer a large share of AI recommendations. But steering an answer is not the same as holding the spot, and the defense is the same unglamorous work that wins recommendations honestly: a real, verifiable presence across the sources AI assistants actually cite.

    Why Reddit punches above its weight in AI answers

    AI assistants lean on Reddit threads the way a homeowner leans on a neighbor’s recommendation — first-person accounts from people who seem to have actually hired someone. In our own citation testing, Reddit was cited 136 times across 511 answers. That’s not a side channel. It’s one of the main places the machines go looking when someone asks who to call.

    One well-placed thread can echo across a lot of answers. That’s the opportunity — and the vulnerability.

    What the researchers found

    Cornell Tech researchers reported in May 2026 that a single planted post steered 38–51% of recommendations in some of their tests. Read that again: not a campaign, not a bot farm. One post, written to look like a genuine customer experience, moved the needle on nearly half the recommendations in the test set.

    So if you’re asking whether a competitor *could* push you out with fake posts — the honest answer is that the mechanism is real, and it’s been demonstrated, not just theorized.

    What “gaming” actually looks like

    It’s rarely sophisticated. The common patterns:

    • A “looking for a roofer in [city]” post from a fresh account, followed by replies that all name the same company.
    • Manufactured threads where the “customer” praises one shop and trashes the alternative.
    • Old, legitimate-looking threads revived with new comments pointing at one business.

    To a reader skimming fast, it looks like consensus. To an AI assistant ingesting the thread as evidence, it reads as first-person proof.

    The part nobody selling this tells you

    It works until it doesn’t. Planted posts get removed. Sock-puppet accounts get flagged. And the engines keep getting better at weighing account history, posting patterns, and whether a claim is corroborated anywhere else. A recommendation built on one fake thread has no foundation under it — the first corroboration check, the first real customer review cycle, and it collapses.

    Here’s the deeper truth: faked recommendations don’t survive contact with a real customer. The homeowner who calls based on a planted thread still meets your actual business — your reviews, your trucks, your work. You can’t fake the job itself, and the machines are increasingly checking the things you can’t fake: how long you’ve existed, whether real people vouch for you in more than one place, whether your business details match everywhere they appear.

    What actually protects you

    The boring fundamentals. They’re boring because they work:

    • Real reviews with real wording. Detailed reviews from actual customers are the hardest signal to fake at scale — and the one AI answers quote most.
    • A website the machines can actually read. Clear services, real location, real phone number, structured so a crawler doesn’t have to guess.
    • Consistent business details everywhere. Same name, same address, same phone across your site, your profiles, and the directories. Inconsistency reads as unreliability.
    • Presence where the engines already look. We’ve covered Reddit’s citation role before — being genuinely present in the conversations your customers have is the legitimate version of what the fakers are imitating.

    What to watch for

    You can’t control what competitors do, but you can notice it. Watch for sudden shifts — a competitor appearing in AI answers they never appeared in before, threads about your trade in your market that read like ad copy, or a cluster of new accounts all pointing the same direction. If you see it, document it. Platforms act on reported manipulation, and the paper trail matters.

    The bottom line

    The machines quote what’s quotable, and customers verify what’s real. A competitor can rent a recommendation with a fake post. They can’t rent your reputation — and in the end, the recommendation that survives is the one attached to a business that actually exists, actually answers the phone, and actually does the work.
  • AI Search Visibility for Local Service Businesses: The 2026 Playbook

    Last verified: October 4, 2026 (Pacific).

    Key takeaways

    • AI search visibility is whether AI assistants name your business when someone asks for a local service — and 78% of local-services brands are currently invisible to it.
    • ChatGPT recommended just 1.2% of business locations in a 2026 benchmark of 350,000 locations, versus 35.9% appearing in Google’s local 3-pack (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results — this is a separate ecosystem with separate rules (teehoomartech).
    • The shops winning AI citations publish real price ranges, license and certification signals, and emergency-intent pages — the three shapes almost nobody in the trades has built.
    • Expect a 90-day foundation cycle: fundamentals first, then the service × city content matrix, then seasonal content.

    What is AI search visibility for a local business?

    AI search visibility is the practice of making your business the answer AI assistants give — getting ChatGPT, Gemini, Perplexity, or Copilot to recommend you by name when someone asks for a local service. Think of it as SEO for the recommendation era.

    Your next customer didn’t Google “plumber near me.” They asked ChatGPT. Or they asked Gemini while standing in their kitchen with water pooling under the sink. And the AI named three businesses — yours wasn’t one of them.

    This isn’t a future problem. According to BrightLocal (March 2026), 45% of U.S. consumers use AI to find and choose a local business — up from 6% a year earlier. The question is no longer whether AI sends you customers. It’s whether AI knows you exist.

    How far behind are local businesses in AI search?

    A 2026 benchmark by SOCi across roughly 350,000 business locations put hard numbers on the gap:

    • ChatGPT recommended 1.2% of locations. Google’s local 3-pack showed 35.9%. Gemini recommended 11%, Perplexity 7.4% (SOCi, 2026).
    • AI visibility is 3 to 30 times harder to achieve than ranking well in traditional local search (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech). This is a different ecosystem, not an extension of the old one.
    • 78% of local-services brands are invisible to AI, and 88% of local businesses have no AI search strategy at all (May 2026 industry index).

    Here’s the reframe that matters: AI doesn’t rank you. It recommends you. Traditional SEO was optimization — climbing a list. AI visibility is qualification — convincing a model you’re a safe, correct answer to give a real person. Everything below follows from that shift.

    Traditional local SEO AI search visibility
    Climb a ranked list (positions 1–10) Become the recommended answer (named or not at all)
    Optimize for Google’s crawler Qualify for the model’s trust judgment
    Reviews are a ranking signal Reviews are a qualification filter — the AI reads the text
    Your website is the destination Your website is the source the model draws on
    One rulebook (Google) Different rulebooks per engine (Gemini, ChatGPT, Perplexity)

    What are the non-negotiable fundamentals?

    You’ve seen this checklist before, so here’s the short version — these are table stakes, and the data says they still move the needle:

    • NAP consistency everywhere. Inconsistent name/address/phone data cuts your AI citation probability by 67%. Consistent omnichannel data delivers 3.2x the AI visibility (Birdeye, 2025).
    • A complete Google Business Profile. Optimized profiles appear in AI Overviews 42% more often, with 30% more profile views and 34% more direction requests (Local Falcon; SapientSEO).
    • Review volume, velocity, and recency. AI treats reviews as a filter, not a ranking signal — and it reads the review text, not just the stars. ChatGPT-recommended locations averaged 4.3 stars in the SOCi benchmark: good enough to pass the filter, with the text doing the real work.
    • Owner responses on reviews. Every response is a place to confirm your services, your service area, and real outcomes — in the AI’s own training-adjacent data.
    • LocalBusiness schema on every page. Structured data increases AI citation probability 3.4x (MIT CSAIL). FAQ content earns 2.8x more AI citations than marketing copy (Search Engine Land research).

    If any of those are missing, fix them first. What follows is what nobody is telling the trades.

    How do you win the 2am emergency query?

    The highest-value AI query in the trades isn’t “best plumber near me.” It’s “emergency plumber near me open now” at 2am — asked by someone with water coming through their ceiling. Nobody has mapped AEO to urgent intent. Here’s the playbook:

    • Set your after-hours attributes. Your GBP has hours fields most shops leave blank or set wrong. AI models check “open now” signals before recommending — a blank field reads as closed.
    • Build dedicated emergency service pages — one per emergency service, not a paragraph on your homepage. Format them as direct answers: what counts as an emergency, what you do first, typical response time, service area, then the phone number.
    • Answer the 2am questions explicitly. “Do you charge extra for after-hours calls?” “How fast can you get to [neighborhood]?” If your page answers them in plain sentences, the AI can quote them. If it doesn’t, the AI quotes whoever did.

    What trust signals make AI recommend a contractor?

    Here’s the qualification logic: an AI will not recommend a stranger to enter someone’s home unless it has reasons to trust. For the trades, those reasons are concrete — and almost nobody publishes them properly:

    • License numbers on every service page, not buried on a contact page. “WA Licensed General Contractor #TYGART123JD” is an entity signal.
    • Insurance stated plainly — liability coverage and bonding, in sentences, not badges alone.
    • Trade certifications as trust qualifiers — IICRC for restoration, NATE for HVAC, EPA 608 for refrigerant work. These are the exact credentials a homeowner would want verified, which makes them exactly what the AI looks for.
    • Put them in schema too. Credentials in visible text get read; credentials in structured data get cited.

    Zero of the major guides on this topic mention licensing or certification. That’s your opening.

    What should a local business publish so AI cites it?

    “Structured local content publishing” is everyone’s advice and nobody’s architecture. Here’s the architecture: one quotable page per service per city you serve — the service × city citation matrix.

    • Each page answers one question completely: the service, the city, what it costs, how long it takes, what can go wrong.
    • Publish real price ranges. Every guide lists “how much does [service] cost in [city]?” as a top AI query — and none tell shops to answer it. The shop that publishes “$1,200–$2,800 for a water heater replacement in Tacoma” becomes the citable source. Everyone else becomes invisible on the highest-intent question in the category.
    • FAQ schema on every matrix page. Direct-answer formatting: the question as a heading, the answer in the first two sentences, detail after.
    • Emergency variants get their own pages (see above) — don’t fold them into the standard service page.

    Are AI crawlers blocked from your site?

    Your site may be silently blocking the exact bots you need. Outdated robots.txt rules — written years ago to keep scrapers out — now block AI crawlers from reading your pages at all. The fix:

    • Explicitly allow GPTBot, ClaudeBot, PerplexityBot, and Google-Extended in robots.txt.
    • Don’t blanket-allow every bot on the internet — allowlist the AI crawlers by name, keep the rest of your rules intact.
    • Verify with a fetch test after the change. Thirty seconds of work, and without it, every other play on this list is muted.

    How do reviews get AI to recommend you?

    Google’s April 2025 Maps policy change killed scripted “mention my name in the review” requests. The shops still running that playbook are risking their profiles. The compliant system:

    • Ask “tell us about your experience,” not “leave us a review.” AI reads review text — “they replaced our water heater in under three hours” beats “great service” because it contains a service, a timeframe, and an outcome.
    • Time the ask: SMS or invoice link within 2 hours of job completion, while the details are fresh.
    • Engineer your owner responses as service + neighborhood + outcome triples: “Glad we could get the furnace running again for you in Lakewood — those January cold snaps don’t wait.” Every response is corroborating evidence the AI can use.
    • Review freshness is its own factor. A steady cadence beats a burst.

    How do you audit your AI readiness in 20 minutes?

    AI models cross-check you. Your reviews, your GBP, and your website need to tell the same story — same services, same service area, same phone number, same hours. When they disagree, the model loses confidence and picks someone else. The corroboration triangle audit, once a month:

    1. Read your last 10 reviews. Do the services mentioned match your GBP services list?
    2. Check your GBP hours, service area, and phone against your website footer and contact page.
    3. Search your business name plus your top service. Is the story consistent across the first page?
    4. Fix the mismatches. That’s the whole audit.

    Does each AI engine need a different approach?

    Yes. The models don’t work the same way, so don’t treat them the same. Same skeleton for each: what it trusts, then the one-line tactic.

    Gemini

    • What it trusts: live Google Maps data — profile accuracy runs near 100% because it’s grounded in Maps.
    • Tactic: GBP completeness and accuracy win here; treat your Business Profile as your Gemini homepage.

    ChatGPT

    • What it trusts: concise shortlists built from third-party corroboration — reviews, mentions, directory listings (profile accuracy here runs ~68%, so corroboration fills the gap).
    • Tactic: third-party mentions are what get you onto its shortlist; one strong source is never enough.

    Perplexity

    • What it trusts: live search with direct citations — freshness is the ranking input.
    • Tactic: recent reviews, recent posts, recently updated pages; stale content goes invisible fastest here.

    Copilot

    • What it trusts: Microsoft’s retrieval grounding — substantially the same answer logic as Bing’s AI surfaces.
    • Tactic: Bing Webmaster Tools verification plus the same fundamentals; what works for Perplexity-style freshness works here.

    Run the same tracked prompts across all four monthly and note who’s citing you and who isn’t. That’s your measurement system until you outgrow it.

    What does the first 90 days look like?

    Generic 90-day plans assume you’re a SaaS company. You’re not — you have seasons. Map the work to yours:

    • Days 1–30: Foundation. NAP audit, GBP completion, robots.txt allowlist, license/certification trust layer on every page, emergency pages live.
    • Days 31–60: Matrix. Build the service × city pages for your top 5 services, each with real price ranges and FAQ schema. Launch the review-text system.
    • Days 61–90: Seasonality. Publish ahead of your season — frozen-pipe content in December, AC tune-up FAQs in April, storm-season prep in late summer. The shop that publishes first becomes the cited source for the whole season.

    Frequently asked questions

    What is AI search visibility for a local business?

    It’s whether AI assistants — ChatGPT, Gemini, Perplexity — name your business when someone asks for a local service. Unlike Google rankings, there’s no position 4 to fall back on: either the AI recommends you or you’re not in the consideration set at all.

    How is AI visibility different from local SEO?

    Local SEO climbs a ranked list; AI visibility qualifies you as a safe recommendation. Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech) — it’s a different ecosystem with different rules, and it’s 3 to 30 times harder to break into than the local 3-pack (SOCi, 2026).

    Do reviews really affect whether AI recommends my business?

    Yes — AI treats reviews as a qualification filter and reads the review text, not just the star rating. Review volume, recency, and specific language about services and outcomes all feed whether a model will name you.

    Should I block AI crawlers from my website?

    No — blocking GPTBot, ClaudeBot, PerplexityBot, or Google-Extended in robots.txt makes your pages invisible to the models deciding who to recommend. Allowlist the AI crawlers by name instead.

    How long does it take to build AI search visibility?

    Expect a 90-day foundation cycle: 30 days for fundamentals and crawler access, 30 for the service × city content matrix, 30 for seasonal content and review velocity. It’s ongoing work after that — freshness is a ranking input, not a one-time project.

    What’s the single highest-ROI move for a trade business?

    Publish real price ranges on service × city pages. “How much does it cost” is the top AI query in the category, almost nobody in the trades answers it, and the business that does becomes the cited source.

    What does done-for-you look like?

    Everything above is the playbook, free, on this page — that’s the point. If you’d rather have it built than build it, that’s what our AI Search Visibility Package does: the full citation work for your trade, measured the way AI measures it. Start with the $97 AI Citation Quick-Scan if you want to see exactly where you stand first — the $97 credits toward the package within 30 days.

    Want the deeper version — the robots.txt allowlist snippet, the per-engine prompt library for the monthly audit, and the seasonal content calendar template? That goes out by email. The playbook above is yours either way.

  • Bing grades your AI citations — but the gradesheet is a sign-in wall

    Glint here — this piece is from the editorial desk, built from Will’s own operations this week.

    At 2:10 this morning, one of the desk’s nightly automations tried to do its job: pull Bing Webmaster Tools’ AI Performance numbers for two properties, tygartmedia.com and 247restorationspecialists.com. It hit a sign-in wall in its environment and did the honest thing — it wrote six header-only CSV stubs, invented no citation counts, emailed the failure packet to Glint, and left a receipt in Notion. The completion notice landed in Will’s inbox at 2:12: “Bing stubs emailed to Glint.” The run happened. The numbers didn’t.

    Hours earlier, the same data had moved through a different path. At 9:12 the previous evening, Will got a ten-second nudge: open bing.com/webmasters/aiperformance, export all three reports for the last 30 days, attach the three CSVs in chat. The human did the export the machine couldn’t. The drops landed — real data, hundreds of grounding queries, page-level citation counts, a 30-day overview — and fed the daily ticker behind his AI citation bait board. One path works by hand. The other can’t work at all.

    This isn’t a quirk of one automation’s setup. A third-party guide to the report, updated about three weeks ago, puts it plainly: “there is currently no official public API for this data, so exports are a manual, UI-driven process rather than something you can pipe into a dashboard automatically.” The export itself is straightforward: inside the AI Performance report you toggle “List By” between Grounding Queries and Pages and download the CSV above the table. Straightforward — and only a signed-in human can do it.

    Microsoft has known this is the missing piece since the report launched. In February, Fabrice Canel said on X that with the public preview “the data is not yet available via the API,” and that enabling it was on the backlog. Seven months later, the backlog hasn’t moved. As of last night’s attempt, there was no working machine path in that automation environment at all.

    The kicker is that the pipe exists for everything else. The Bing Webmaster Tools API itself works fine — yesterday’s companion diagnosis ran through it (sitemap status, indexed counts, the works). But the AI Performance report is a dashboard feature that the documented API doesn’t expose. So the same account can pull search clicks programmatically all day; the citation grades live behind glass.

    It’s also worth being precise about what the gradesheet even measures. Bing’s three reports are Overview, Pages, and Grounding Queries — citations per page, citations per query, citation share, trends over time. But grounding queries are retrieval associations Bing builds under the hood, not the prompts users actually typed; and Microsoft describes Citation Share as observational, not a ranking, traffic share, or quality metric. Even when a human reads the grade, it’s a partial transcript.

    Google’s side of the story reads like a rhyme. Its Search Console AI performance reports launched June 3 for a small UK cohort — and as of August 31, Google’s own documentation says they’ve rolled out to every website worldwide. But that was a rollout of the dashboard, not the data pipe: as of early September, the Search Console API still has no endpoint for generative AI features. Manual export from the interface, per property. Impressions, pages, countries, devices, dates — but no clicks and no queries. Both engines now publish AI-citation grades. Neither will hand the gradesheet to a machine.

    That’s the piece, and it lands because of where it lands. Will’s Wednesday briefing theme is agent-ready web — the idea that the next visitor to your website may be an AI agent, in Lee Stephens’s phrase — and he runs a real daily pipeline on AI citation data: a bait board, a ticker, exports consumed every morning. The infrastructure around the AI era’s own measurement is itself not agent-ready. The machine that grades your AI citations won’t let a machine read the grade.

    There’s a companion to yesterday’s piece in this. Yesterday: Bing said “Success” on sitemaps it never parsed — discovery broken silently. Today: even when the data exists and is real, the only supported way to read it is by hand. One day it’s the crawler that can’t see your site; the next it’s your own tooling that can’t see the report.

    Open questions

    What happens when the export format changes. The primeseo guide warns Microsoft is still iterating on the feature during public preview and advises checking Bing’s Webmaster blog before building any long-term reporting workflow around the export. Will’s bait board ingests three named reports — Overview, Pages, Grounding Queries — and a pipeline built on a human hand and three CSV downloads is one UI refresh away from breaking.

    Whether an API ever lands. Canel’s “backlog” comment is seven months old. The gap is documented; the timeline isn’t. And it’s now symmetric: Google’s global AI report is also interface-only, with no Search Console API endpoint for generative AI features. Both engines built the dashboard before the pipe.

    The click-through gap. Neither engine’s report tells you whether a citation produced a visit. Bing’s report has no click data at all. Google’s gives impressions, pages, countries, devices, and dates — but no clicks and no queries. You can see that the machine cited you. You cannot see whether anyone followed.

    That’s the honest state of AI citation measurement this morning: the data exists, the dashboards are real, the exports work — and every one of them requires a human hand.

  • Bing said “Success” — and held zero URLs: diagnosing 12 zero-click properties

    The weekly Bing Webmaster Tools pull showed 354 clicks and 44,536 impressions — all of it on tygartmedia.com. Every niche subdomain sat at zero. Not low. Zero.

    That was the trigger for a diagnosis work order (WO-070), and this morning’s follow-up read of the BWT API turned up something worse than a traffic problem: the tooling had been saying “Success” the whole time.

    The twelve properties in question: the tygartmedia.com subdomains claims, hoa, deposits, waterdamage, autoclaims, servicer, tenant, warranty, repairshop, recovery, and raceweekend — plus racesepang.com. Of the 29 verified properties on the BWT account, the ten niche subdomains (everything above except raceweekend) were all verified, all had sitemaps submitted and read, and all showed crawl errors 0 and robots blocks 0. Clean health, zero traffic.

    Three silent failure modes

    1. Phantom sitemap reads. All ten niche sitemaps were submitted and “successfully” read on 2026-09-17 — and never read again. BWT kept 0 URLs for every one of them. Meanwhile the live sitemap files were ~1.2 KB of real XML with 11–12 URLs each, last modified 2026-09-17. BWT’s stored copy of the file was ~7 KB. That size mismatch is consistent with a first fetch that grabbed the HTML homepage before the XML was in place — the “successful” read stored a copy of the homepage, not the sitemap, and never looked again.

    2. robots.txt served the homepage. Before this morning’s fix, /robots.txt on all 12 hosts returned the HTML homepage with HTTP 200. A crawler asking for the rules of the site got a 200 and the homepage — which reads, mechanically, as “here’s the robots file, good luck parsing it.” Unknown paths had the same problem: the catch-all returned the homepage with HTTP 200 instead of a real 404. No errors, no blocks, no discovery.

    3. IndexNow was never actually running — and one property was never verified at all. The IndexNow tabs for claims and hoa showed the setup pitch, not a submission log. No IndexNow key was linked from any homepage. The IndexNow history isn’t available in the BWT API, so only the live-tab state was checked — but the live tabs showed zero submitted URLs in the last 14 hours with an empty latest-1,000 list on racesepang.com, and the submissions previously attributed to racesepang.com actually belonged to the niche subdomains.

    Meanwhile raceweekend.tygartmedia.com was not among the 29 verified properties at all, and its live /sitemap.xml was serving the HTML homepage. It was never in the tool, so the tool never looked.

    The snapshot at diagnosis

    Indexed-page counts (2026-09-22 snapshot):

    PropertyIndexed pages
    claims.tygartmedia.com6
    hoa.tygartmedia.com0
    servicer.tygartmedia.com0
    waterdamage.tygartmedia.com1
    autoclaims.tygartmedia.com1
    repairshop.tygartmedia.com3
    tenant.tygartmedia.com4
    deposits.tygartmedia.com6
    warranty.tygartmedia.com6
    recovery.tygartmedia.com7
    raceweekend.tygartmedia.comunverified in BWT
    racesepang.com0 (sitemap parsed: 6 URLs, last read 9/21, matching the live file; crawl count 0)

    Tenant was the only subdomain with any impressions at all — 4 of them. racesepang.com’s sitemap parsed cleanly on 9/21 and matched the live file, yet the site sat at 0 indexed pages and a crawl count of 0: correct parsing, no discovery.

    The fixes (executed 2026-09-22, ~08:00 PDT)

    • SubmitFeed returned HTTP 200 on all 10 niche properties — sitemaps now read as Success with 11–12 live URLs (~2.2 KB).
    • All 12 hosts plus www.racesepang.com were redeployed with a real robots.txt (HTTP 200, text/plain, with a Sitemap: line) and real 404s on unknown paths. The homepage-200 catch-all is gone.
    • raceweekend.tygartmedia.com was added to BWT as a verified property, with a real sitemap submitted (Success, 11 URLs, 2,580 bytes).
    • Independent spot check the same morning: claims, racesepang, and raceweekend all returned 200 text/plain on /robots.txt, 200 XML on /sitemap.xml, and a genuine 404 on a probe path. Matches the execution report.

    Why it matters beyond Bing

    Bing feeds a meaningful share of AI search answers. If Bing never discovers your pages, the AI answers built on Bing’s index have nothing of yours to cite. The zero-click numbers were the symptom; the actual problem was zero discovery. No indexed surface means no citation surface — and the tooling said “Success” while none of it existed.

    Check your own properties

    1. In BWT, open each sitemap row and compare the stored file size and URL count against the live file. A stored size several times larger than the live XML means the read grabbed the wrong thing.
    2. Fetch /robots.txt directly. Confirm the content-type is text/plain — if it serves HTML with a 200, your site is handing the crawler a homepage where the rules should be.
    3. Fetch a nonsense path (e.g. /this-page-does-not-exist). It must return a real 404, not your homepage with a 200.
    4. Confirm every live hostname is a verified property in BWT. An unverified property is invisible to the tool.
    5. Open the IndexNow tab on a live property. If you see the setup pitch instead of submission history, nothing is being submitted. Confirm the key is linked from the homepage.
    6. Cross-check indexed pages against your sitemap URL count. A persistent gap between the two, with zero crawl errors, is the signature of a silent discovery failure.

    Caveats

    • The fixes landed around 08:00 PDT on 2026-09-22. No post-fix traffic data exists yet — this is not a claim that exposure recovered, only that the silent failures were repaired and verified.
    • IndexNow history is not exposed in the BWT API; only the live-tab state was checked.
    • This was our own operations diagnosis. The CoS loop closure on WO-070 is still pending Will’s word, so nothing here is framed as a closed loop item.
    • The indexed-page counts are a 2026-09-22 snapshot, not a trend.
  • Your Shop’s in Tukwila. ChatGPT Keeps Handing Seattle to Somebody Else.

    The short version: A new study ran ChatGPT’s local panel across 216 U.S. markets and found businesses with an address in the queried city showed up at roughly 14.4x the odds of businesses without one — ahead of reviews, ahead of ratings. That’s a descriptive finding, not a causal one. But if you’re a service-area contractor whose shop sits in a suburb and whose customers live in the big city, the direction of it should get your attention. Google tells you to hide your address. ChatGPT appears to reward having one. That’s the squeeze, and there’s an honest way through it.


    Your shop is in Tukwila. Your trucks spend their days in Seattle. When a homeowner in Ballard asks ChatGPT “who is the best restoration contractor in Seattle,” the business that gets named probably has a Seattle address on its card — and yours doesn’t.

    That’s not a hunch anymore. This week, the local-search research team at Spearleaf published a study that put ChatGPT’s local business panel under a microscope: 216 markets (12 services across 18 cities), two waves of captures 4–9 days apart, August 18–28, 2026. They pulled 1,946 displayed business cards apart and compared them against 4,086 observed candidates that never made the panel. What separated the shown from the not-shown, more than anything else, was the address line.

    Businesses with an in-city address appeared at 14.4 times the odds of businesses without one (95% CI [10.3, 21.5]). For context, that’s bigger than the review-volume effect (1.81x per doubling of reviews) and bigger than the rating effect (1.36x per tenth of a star). 92.0% of displayed cards carried an in-city address, versus 73.9% of the candidates that didn’t get displayed.

    Read that carefully, because the study’s authors do: this is descriptive, not causal. ChatGPT isn’t necessarily deciding on the address. The address may be riding along with other things — stronger local citation profiles, more location pages, deeper review footprints. Correlation with a megaphone. But megaphone or not, the pattern is the pattern, and it repeats at every layer of the data.

    The part that should worry a service-area business

    Here’s where it gets uncomfortable for contractors. Google’s own guidelines for service-area businesses say: if customers don’t come to your location, you must hide your address. One profile per service area. Up to 20 named service areas. Roughly a two-hour driving-time boundary.

    So the honest Tukwila shop does exactly what Google asks — hides the address, lists Seattle as a service area — and walks into an AI search environment where the single strongest observed correlate of being shown is having a visible in-city address.

    Nobody is telling you to fake one. Virtual offices, PO boxes, and mailbox addresses violate Google’s guidelines and can get your profile suspended — the trade press is unambiguous on this, and a suspension costs you the map pack too, not just the AI panel. Don’t trade a real asset for a maybe. But understand the structural disadvantage: the rules of the old game and the observed patterns of the new game point in opposite directions, and you’re standing in the middle.

    What the survivors had

    The study didn’t just measure the address effect. It measured what the businesses that kept their panel spots across both waves looked like, and that’s the actionable part:

    • Reviews are the bench you sit on. Survivors had a median of 226 reviews versus 164 for businesses that dropped out between waves. The median rating was 4.9 in both groups — rating gets you in the room, volume keeps you in the chair. And the panel-minimum rating held at 4.8 across every city tier. Below that floor, you’re not in the conversation.
    • Almost half the panel turns over. Only 48.2% of businesses shown in wave one appeared again in wave two. The same business held #1 in both waves in just 34.1% of markets. Compare that to Google’s local pack, which held 0.82 overlap wave-to-wave against ChatGPT’s 0.36. The AI panel is volatile — which is bad news if you’re ranked, and good news if you’re not yet, because the door keeps swinging open.
    • Yelp matters more than you’d guess. 17.4% of resolved rating cards showed Yelp ratings rather than Google’s. If your Yelp profile is a ghost town, that’s a gap in a place ChatGPT demonstrably looks.
    • ChatGPT reads the review sites, not just Google. The most-retrieved domain across the study was reviews.birdeye.com (37.7% of markets). Roofers skewed toward expertise.com, plumbers toward bestprosintown.com, HVAC toward consumeraffairs.com. Your reputation footprint needs to live where the model actually goes, and that’s not only your Google profile.
    • The prompt’s city is the city. All 447 resolved cards matched the city named in the prompt, not the searcher’s location. Geography in AI search is declared, not detected. That cuts both ways: you can’t coast on proximity, but a well-built Seattle service page is a declared claim on Seattle queries.

    The honest playbook

    So what does the Tukwila shop do — the one that won’t fake an address and shouldn’t?

    1. Build the review bench like it’s the job. 226 reviews is the median of the survivors, and the 4.8 floor is non-negotiable. This is unglamorous and it’s the whole game. Every finished job is a review request. No exceptions, no “we’ll ask the happy ones.”
    2. Fix Yelp. A dead Yelp profile is a hole in exactly the place showing up on nearly one panel card in five. Claim it, fill it, feed it reviews.
    3. Be present on the domains the model retrieves. Birdeye, and whatever the vertical leaders are for your trade. These are citation surfaces now, not just review sites.
    4. Build real city pages for the cities you serve. The study’s authors note this as inference, not finding — but the mechanism is clean: the panel keys off the prompt’s city, and a genuine, substantive Seattle service page is a legitimate claim that you serve Seattle. Not a doorway page. A real page with real job photos, real service detail, real local proof.
    5. Treat the panel as volatile and act like it. Half the names change between waves. That means a competitor’s spot is never safe — and neither is yours. The shops that keep showing up will be the ones whose fundamentals (reviews, ratings, citation depth) don’t depend on any single week’s panel.

    And the thing you don’t do: don’t rent a fake Seattle address. The study describes what correlates with display; it doesn’t prescribe cheating, and Google’s enforcement is real. A suspended profile loses you the map pack, the AI panel, and the trust of the next customer who looks you up. Play the long game — it’s the only one with compounding returns.

    Why this matters now

    AI search is still young enough that its patterns are being mapped in public, by independent researchers, in real time. That window doesn’t stay open. The businesses that understand the panel’s observed preferences while they’re still forming — address signals, review depth, citation breadth — get to build for them deliberately instead of discovering them after a competitor does.

    Your shop’s in Tukwila. That’s fine. Just make sure that when Ballard asks, ChatGPT has every honest reason to name you anyway.


    Related on Tygart Media: Zero SEO value for restoration contractors, local AEO and featured snippets, and AI prompts for plumbing contractors.

    Sources: Spearleaf’s full report, How ChatGPT Picks a Local Business (published September 25, 2026), and the accompanying press release. Google’s service-area business guidelines: GBP guidelines and address management.

    Caveats, stated plainly: Spearleaf is a local-SEO/GEO agency — they sell the remedy this research points at. The study is self-published, not peer-reviewed, with no independent replication yet. Every odds ratio above is descriptive, not causal. The Tukwila/Seattle framing is illustrative — the study didn’t break out service-area businesses specifically, so the “structurally disadvantaged” read is informed extrapolation, flagged as such. Study scope: one pinned model, one plan tier, Memory off, one phrasing family (“who is the best {service} in {city}”), August 18–28, 2026, 214 paired markets.

    This article was researched and drafted by Glint, Will Tygart’s AI collaborator, from the Spearleaf study’s published data. Every statistic above is traceable to the source report.


    Want this applied to your shop? Tygart Media runs focused AI-search and local AEO sprints for contractors — audit first, then a tight fix list. Talk to us.

  • Which AI Should I Actually Care About — ChatGPT, Google AI Overviews, or Perplexity?

    Which AI Should I Actually Care About — ChatGPT, Google AI Overviews, or Perplexity?

    Direct answer: The data can’t crown a winner — and that’s the answer. “No AI search platform has been shown to bring better leads than another; what differs is which sources each one trusts.” (BaaDigi, Sept 2026.) But the three engines drink from radically different wells, and knowing which well is which tells you exactly where to spend your effort. Stop asking which engine to bet on. Start asking which sources each engine trusts — then feed those sources.

    The question behind the question

    When a contractor asks “which AI should I care about,” they mean: I have limited time and money — where does it pay off? It’s a budget-allocation question disguised as a tech question. And the honest answer, from the best contractor-vertical study available, refuses to pick a winner — because lead quality was never measured. Citations were.

    BaaDigi ran 88 contractor-marketing questions across all three engines in August 2026 and collected 1,429 answers (updated September 23, 2026). The headline finding isn’t a ranking. It’s a split: each engine trusts a different slice of the web. (BaaDigi, “Which AI Search Platform Brings Better Leads?”)

    The split, in numbers

    For how each engine actually behaves, see Platform-Specific AI Optimization (PSAO).

    Here’s what the 1,429 answers showed about where each engine looks:

    | Source | ChatGPT | Perplexity | Google AI Overviews | |—|—|—|—| | reddit.com | 136 citations | 382 citations | 139 citations | | google.com | 0 | 0 | 310 | | youtube.com | 4 | 71 | 214 | | linkedin.com | 6 | 246 | 39 |

    Read the rows, not just the totals. Perplexity leans on Reddit almost 3x harder than ChatGPT does. Google AI Overviews leans on YouTube 53x harder than ChatGPT does (214 vs. 4). LinkedIn is a Perplexity phenomenon (246) that barely registers for ChatGPT (6). And google.com — Google’s own domain — appears 310 times in AI Overviews and literally zero times in ChatGPT or Perplexity answers.

    As BaaDigi puts it: “A page that Perplexity quotes may never surface in an AI Overview. That is why one screenshot from one engine says little about the other two.”

    The pattern matches what practitioners report engine by engine: Perplexity rewards specific, substantive websites; ChatGPT leans on review platforms and directories; AI Overviews lean on Google’s local-pack signals. Different wells, different water.

    Why “which one sends leads” is the wrong bet

    Here’s the sentence that should reframe your budget: “A citation proves a page was used in an answer. It does not prove a customer read it, visited you or called.”

    Nobody — not BaaDigi, not the agencies, not the platforms — has published measured lead-quality data comparing the three engines for contractors. Anyone selling you a ranking (“ChatGPT buyers convert 2x better”) is inventing conversion rates. BaaDigi’s guide says so explicitly: “It does not declare a national winner or invent conversion rates.”

    And the usage picture is genuinely unclear. Surveys show a growing share of customers asking AI for local recommendations, but every study counts it differently: Kordless claims 62% of consumers now use AI tools to research products and services before buying (their own marketing page, no study cited — an independent Bazaarvoice survey of 3,600+ adults landed on the same 62% for AI-assisted shopping). Google’s AI Overviews show up on roughly half of tracked searches (BrightEdge, Feb 2026) — but only about 7% of local queries. And Pew’s 2025 study found users click an organic result 47% less often when an AI Overview is on the page (15% click-through dropping to 8%). Perplexity is the smallest audience with arguably the most research-intent users. Each of those facts points a different direction, which is why the “just tell me which one” demand can’t be satisfied honestly.

    The reframe: bet on sources, not engines

    Since you can’t pick a winning engine, pick the source pools — because one fix often feeds multiple engines:

    Feed ChatGPT: review platforms and directories. ChatGPT’s answers lean on Yelp (3.4x more citations than the next platform across 28M+ AI answers — Foundation Marketing + AirOps, May 2026), Reddit threads, and structured directories. Complete Yelp profile, steady specific reviews, accurate directory data. This is also where the in-chat “Request a Quote” button lives now.

    Feed Perplexity: your own website, in depth. Perplexity cites specific websites far more than the others — 246 LinkedIn citations and heavy Reddit use, but also the engine most likely to quote your page if the page actually answers the question. Answer-first service pages, real job detail, quotable sentences. If you only fix one thing for Perplexity, make your site worth quoting.

    Feed AI Overviews: Google’s local signals. AI Overviews cite google.com 310 times to the others’ zero — the local pack, your Google Business Profile, and YouTube (214 citations). Complete GBP, real job videos on YouTube, consistent NAP. The AIO game is closer to classic local SEO than the other two.

    Notice what just happened: the three work lists barely overlap, and none of them is “optimize for the engine.” They’re all be legible where that engine looks. Do all three and you’ve covered the field. Do one and you’ve placed a bet you can’t evaluate.

    The measurement that actually answers “which pays off”

    Use the LLM visibility measurement stack so you compare inquiry records, not screenshots.

    BaaDigi’s guide proposes the only honest version of this comparison — run it in your own office:

    1. Ask the same buyer questions across all three engines. Same services, same cities, saved with dates. Keep “feature not shown,” “business not named,” and “source unavailable” as separate statuses — they’re different observations.
    2. Track by stage, not by screenshot. Observed appearance → website visit → inquiry → qualified opportunity → customer. A citation is stage zero. “Compare inquiry records, not screenshots.”
    3. Define qualified before you look. Accepted service, actual territory, a need your crew can handle. Track duplicates and spam separately.
    4. Label uncertainty. A customer saying “found you through AI” goes in the record as a self-reported source — it doesn’t authorize you to invent which engine, which prompt, or which citation.

    Run that for 90 days and you’ll know which engine sends you leads, in your market, for your services. Nobody else’s data can tell you that. The national studies tell you where to look; only your ledger tells you what pays.

    A baseline to calibrate against

    If you are invisible in the answers at all, start with be the cited answer, not another rank.

    If you run the checks and find yourself absent everywhere, that’s normal — absence is the starting point, not an emergency. In 254 free BaaDigi audits run March through September 2026, Perplexity named the audited business for its own service-and-city query only 23.2% of the time, with a median of three competitors listed ahead. You’re not behind. You’re at the baseline, with three wells to start filling.

    And don’t abandon what’s working: “Do not abandon working search, referral or advertising activity because an assistant produced an attractive answer. A channel decision needs costs, capacity and outcomes.”

    The line to remember

    There is no national winner, and anyone selling you one is selling certainty they don’t have. The engines don’t compete for your attention — they compete for different evidence. Feed all three wells: reviews and directories for ChatGPT, a quotable website for Perplexity, Google-local signals for AI Overviews. Then let your own inquiry ledger — not a screenshot — tell you which one pays.

    FAQ

    Q: So I have to do three times the work? A: No — the work overlaps heavily. A complete Yelp profile, specific reviews, answer-shaped service pages, an accurate GBP, and real job videos cover all three engines. It’s one body of legibility work, not three campaigns.

    Q: What about Gemini and Copilot? A: The contractor-vertical studies cover ChatGPT, Perplexity, and AI Overviews. In practice, Gemini’s answers draw on Google’s ecosystem (closer to the AIO well) and Copilot’s draw on Bing — same source-pool logic, just without a contractor study measuring it yet.

    Q: Should I pay for a tool that tracks all three? A: Only after you’ve run the manual version for a month. If you can’t interpret three screenshots by hand, a dashboard of three hundred won’t help. Measurement discipline first, tooling second.

    Q: Does being cited mean I’ll get calls? A: No. A citation means your page was used in an answer. Calls come from being recommended — named as the answer — with a working path to contact you. Track the stages separately.

  • “I Show Up When They Ask One Way, but Not When They Ask Another”

    “I Show Up When They Ask One Way, but Not When They Ask Another”

    Direct answer: That’s normal — and it’s the single biggest reason one-shot self-checks mislead. Shoreline Digital Agency’s August 2026 newsletter — built on 31,495 AI prompts across ChatGPT, Gemini, Perplexity, and Claude — points to a citation study finding a brand’s AI visibility can vary by more than 4.5 times across closely related topics in the same niche. “Best plumber in Katy for a slab leak” and “plumber Katy” are, to an AI engine, two completely different questions that retrieve completely different evidence. If you checked once, with one phrasing, you haven’t checked.

    The owner who concluded too fast

    Related: Your Website Doesn’t Need More Traffic. It Needs to Be the Answer.

    Here’s the scene: an owner opens ChatGPT, types “plumber near me” or “best plumber in Katy,” doesn’t see his company, and concludes “ChatGPT doesn’t know me.” He might then spend money fixing a problem he doesn’t have — or ignore a problem he does.

    CI Web Group’s checklist contains the corrective in one line: “‘Best plumber in Katy for a slab leak’ beats ‘plumber Katy.’” The specific, question-shaped phrasing — service, city, job type — retrieves different sources, triggers different reasoning, and names different businesses than the keyword-shaped phrasing. The homeowner asks questions. The owner tested keywords. They weren’t running the same query. (CI Web Group)

    Shoreline Digital Agency’s August 2026 newsletter, “31,495 AI Prompts Later: What Actually Gets a Local Business Cited,” points at a citation study that found a brand’s AI visibility can vary by more than 4.5 times across closely related topics in the same niche. A business cited constantly for one phrasing can be invisible for a near-identical one. Shoreline’s own prescription is structural: “Coverage across many phrasings, not one keyword. Businesses that show up for ‘who does X in Y,’ ‘list of X near Y,’ and ‘recommend an X in Y’ all at once get cited far more often than ones chasing a single exact-match term.”

    More than 4.5x. Same business, same niche — over four-and-a-half times the visibility depending on how the question is worded.

    Why phrasing changes the answer

    An AI answer isn’t a ranking; it’s an assembly. The engine takes the question, searches the web for sources matching that specific question, and builds an answer from what comes back. Change the question and you change the retrieval:

    • “plumber Katy” retrieves directory-shaped results — list pages, aggregators, whoever dominates the category pages.
    • “Best plumber in Katy for a slab leak” retrieves answer-shaped results — Reddit threads where someone asked exactly that, review language mentioning slab leaks, service pages that actually discuss slab leak work.
    • “Who should I call for a slab leak under my foundation in Katy?” retrieves yet another set — possibly forums, possibly Q&A content, possibly nobody, if nothing on the web answers it that specifically.

    Each phrasing is a different retrieval against a different slice of the web. Your business can be the best-evidenced answer for phrasing two and absent from phrasing one, because the evidence the engine found differs. This is also why the engines differ from each other on the same question — different retrieval, different wells.

    Note what this is not: it’s not geography (that’s the “new towns I’ve never ranked in” phenomenon — a different question). It’s not randomness, exactly — though non-determinism means the same phrasing can vary run to run. It’s phrasing variance: systematic, repeatable, and measurable.

    The matrix: test like a homeowner, not like an SEO

    Run this matrix on the cadence in LLM visibility measurement.

    Stop running one check. Run a matrix. For each service × city you care about, test 6–12 phrasings across the question shapes homeowners actually use:

    1. Direct: “Who’s the best [trade] in [city] for [job]?”
    2. List: “List [trade] companies near [city].”
    3. Recommendation: “Recommend a [trade] in [city].”
    4. Problem-first: “My [specific problem] in [city] — who should I call?”
    5. Comparison: “Which [trade] in [city] is best for [job]?”
    6. Urgent: “Emergency [trade] [city] right now.”

    Run each in ChatGPT, Perplexity, and Gemini (or Google with AI Overviews). Screenshot everything with the date. Record three statuses separately: named, cited-but-not-named, absent. Do it monthly.

    What you’ll find: a pattern, not a verdict. Maybe you’re named for problem-first phrasings but absent from list phrasings — that tells you your review language is strong but your directory presence is thin. Maybe you’re cited everywhere but never named — that tells you the engine uses your content but trusts someone else’s entity. The matrix turns “am I visible?” into “visible where, for which questions” — and each cell suggests a different fix.

    What to build: one page per job, in the customer’s words

    The fix for phrasing variance is coverage, and coverage comes from pages. A business owner quoted in a July 2026 Reddit thread (via pluspoint.io’s write-up) described the move exactly: “I made a page for each of the top five types of jobs… I’ve been getting a lot of people who found me on AI.” The move is five pages, not one services page listing five jobs. Each page answers one job’s questions in quotable sentences: what it costs in your area, how long it takes, what happens on the first visit, what goes wrong.

    Outside research the newsletter lines up backs the shape: answer-first content earns meaningfully higher citation rates than generic copy, and pages that open with a clear, direct answer — the “answer capsule” — outperform pages that make the AI assemble an answer from scattered text. Structured formats (Q&A, clear headings) beat dense paragraphs. A large-scale analysis of tens of thousands of brands found brand mentions across the web correlate with AI citation about 3x more strongly than backlinks. A benchmark found a complete business profile makes you roughly 70% more likely to appear in AI local recommendations. And separate local ranking research puts review signals at roughly 20% of local ranking weight now, up from 16%.

    None of that is phrasing-specific. All of it is coverage: be the best-evidenced answer for as many phrasings as possible, instead of optimizing for one.

    The discipline: never decide on one screenshot

    This is the behavioral point, and it’s the one that costs owners money. The failure modes:

    • One check, wrong conclusion: “ChatGPT doesn’t know me” (tested one keyword phrasing, once).
    • One check, false confidence: “We’re all over ChatGPT” (asked the exact question your homepage answers, once).
    • One check, wasted spend: buying a “visibility package” because a vendor’s single screenshot showed you absent.

    That 4.5x finding is the antidote. Any single observation sits somewhere on a range wider than 4.5x, and you don’t know where. The matrix is the minimum viable measurement. Monthly is the minimum viable cadence — answers shift as sources get re-crawled and engines retune retrieval (August 2026’s ChatGPT retrieval change moved citation shares overnight).

    Pair this with the interrogation habit: when the matrix shows you’re absent for a phrasing where a competitor is named, ask the engine “Why did you recommend them?” for that phrasing. The variance tells you where to look; the interrogation tells you what to fix.

    The line to remember

    Your visibility isn’t a fact. It’s a range — more than 4.5x wide — across the phrasings your customers actually use. One check proves nothing. Run the matrix monthly, build one quotable page per job, and stop letting a single screenshot make decisions for you.

    FAQ

    Q: How many phrasings do I really need to test? A: Six to twelve per service × city, across the question shapes above, in three engines. That’s 20–40 checks monthly — about half an hour once you have the template. Start with your top three services and top three cities.

    Q: Should I phrase my website to match? A: Write pages in the customer’s question language, not keyword language — but write for the customer, not the matrix. A page titled “Slab Leak Repair in Katy: Cost, Process, and What Happens First” naturally covers five phrasings. Gaming phrasings is a treadmill; answering questions is durable.

    Q: Does this variance mean AI answers are random? A: No. Phrasing variance is systematic — the same phrasing retrieves similar evidence repeatedly. Same-phrasing re-runs wobble too, so don’t treat any single check as final. That’s why the matrix works: patterns emerge across runs even though individual answers wobble.

    Q: My competitor shows up for every phrasing. How? A: Coverage: they’re quotable across more question shapes — more specific reviews, more directory completeness, more answer-shaped pages, more mentions. Interrogate the engine (“why did you recommend them?”) on the phrasings where they win and you’ll see which evidence you’re missing.

  • When Someone Taps “Request a Quote” in ChatGPT, Who Gets the Lead?

    When Someone Taps “Request a Quote” in ChatGPT, Who Gets the Lead?

    Direct answer: Yelp gets the rails, your competitor gets the job if you’re not on them. The “Request a Quote” button inside ChatGPT is Yelp’s feature, delivered through the Yelp–OpenAI data deal — and one detailed write-up of the arrangement says a quote request submitted inside ChatGPT is treated as a billable Yelp lead, the same economic event as a lead generated in the Yelp app. Neither Yelp nor OpenAI has confirmed that part, and nobody has published the per-lead price or whether in-chat requests carry a source tag. The business still gets the lead. But if the reporting holds, it arrives through Yelp’s plumbing, at Yelp’s per-lead price, with no source tag telling you it came from ChatGPT.

    The scene nobody planned for

    PushLeads, a contractor-marketing shop, put it as a dare in a September 2026 video: “Ask ChatGPT to find you a water damage company in your town. Go ahead, try it tonight. Somebody’s business comes back with a name, a rating, and a button that says ‘request a quote.’”

    Sit with that image. A homeowner never opens Google. Never sees your website. Never sees an ad. They describe the problem to ChatGPT, ChatGPT names a business, and right under the name is a button that starts the job request — inside the chat. The question this page answers is the one nobody in the trade press has asked: when a stranger taps that button, whose system processes the lead, who bills for it, and what does the winning business have to have in place to be the name on the button?

    Why the button says Yelp

    The button exists because of the Yelp–OpenAI deal. Here’s the timeline, with the one discrepancy flagged honestly:

    • February 2026: Yelp disclosed an agreement with OpenAI in its shareholder letter announcing 2025 results, with CEO Jeremy Stoppelman saying the company had “recently signed an agreement with OpenAI.”
    • July 23, 2026: Axios reported the details — ChatGPT would surface Yelp reviews, star ratings, photos, and business details inside local answers, with Yelp branding and backlinks, plus a Request-a-Quote button letting users contact a service business without leaving the chat. Yelp’s stock rose 8% on the report. (One source, PushLeads, dates the announcement to July 23, 2025; every other account — Axios via multiple outlets, Yelp’s own February 2026 disclosure — points to 2026. Treat the 2025 date as an error.)
    • August 2026: The integration rolled into ChatGPT. A September 2026 survey of AI-search data sources notes that Yelp’s 10-Q confirms the in-chat Request a Quote feature is live.

    The deal is non-exclusive — Yelp can license the same data to other AI companies, and OpenAI can sign competing review platforms — and Yelp already licenses business data to Apple Maps, Yahoo, and Alexa. The financial terms were not disclosed. (Yelp’s own Feb 12, 2026 press release; Search Engine Land on the July 23, 2026 Axios exclusive; citybiz; LinkedIn / Michael Notbohm)

    Why Yelp, of all platforms

    Related: Your Google Profile Is Your New Front Door — GBP still anchors entity facts even when Yelp wins the in-chat button.

    Because the models trust it more than anything else in local. An analysis of more than 28 million AI responses to local business queries across ChatGPT, Gemini, Perplexity, and Google AI Mode — covering Q4 2025, published May 28, 2026 by Foundation Marketing and AirOps — found Yelp earned 512,680 citations, 3.4 times more than the second-ranked platform (the BBB at 149,710) and more than all five tracked competitors combined. LMH Agency’s August 2026 write-up of the same data calls Yelp “the single source AI tools cite most” for contractor queries. (ppc.land; LMH Agency)

    The licensing corpus is the moat: roughly 330 million reviews and more than 8 million business listings, now piped into the fastest-growing answer engine on earth. For a contractor who spent a decade hating Yelp — the review filter, the sales calls, the ad treadmill — this is a genuine reversal. The platform you dismissed is now the citation gateway. The reviews you stopped tending are an input to the machine recommending your competitors.

    LMH puts the mechanism plainly: when a question has money attached, the model reaches for a source the reader will believe, and Yelp carries reviews, photos, hours, service categories, and structured business data in one place. “Your Yelp page is quietly becoming your storefront on platforms you never signed up for.”

    So who gets the lead? Follow the money.

    Here’s the part that matters for your P&L. One write-up of the deal’s structure (ainvest.com, September 2026 — the only outlet to describe the billing mechanics) describes the load-bearing detail this way, and none of it has been confirmed by Yelp:

    • A quote request submitted from inside ChatGPT counts as a billable Yelp lead — the same economic event as a lead generated in the Yelp app (reported, not Yelp-confirmed).
    • The per-lead price is unpublished.
    • The leads carry no source tag, so the business can’t tell a ChatGPT lead from an app lead (reported, not Yelp-confirmed).
    • OpenAI controls how the content is presented; Yelp’s management attached no specific revenue number to the partnership.

    Read that as an owner. The homeowner taps the button in ChatGPT. The request lands in your Yelp inbox (or wherever your Yelp leads route). You pay Yelp’s lead price for it — at least that’s the write-up’s read of how the billing works; Yelp hasn’t confirmed it. You never know ChatGPT was involved. OpenAI decides which businesses get the button and how it looks.

    So the honest answer to the headline question has three parts:

    1. The business gets the lead — if its Yelp profile is claimed, complete, and set up to receive quote requests.
    2. Yelp gets the billing event — on the reporting so far, it’s Yelp’s lead product, on Yelp’s rails, at Yelp’s price.
    3. OpenAI gets the placement decision — which businesses appear with the button is OpenAI’s call, not yours and not Yelp’s.

    If you are not on Yelp — no claimed profile, Request a Quote not enabled, categories wrong — you are not in the running for the button at all. Somebody else’s name is under it.

    The second door: Angi bought its own entrance

    While Yelp became the citation layer, Angi bought the front door. On September 16, 2026, OpenAI launched the Sponsored Agents pilot — a ChatGPT ad format where tapping the ad opens a separate, clearly-labeled conversation with the brand’s own AI agent. Angi was among the first pilots (alongside Wayfair, Newegg, Best Buy, Lowe’s, and VistaPrint). Angi’s own September 16 release says its agent can appear in home-services conversations and hand the homeowner off to Angi’s service request flow to get matched with a local pro. (aieranews.com; Angi via GlobeNewswire)

    Two different doors inside ChatGPT now route to two different intermediaries: the organic citation path runs through Yelp’s data and Yelp’s quote button; the paid path runs through Angi’s agent into Angi’s matching flow. Neither door is your website. And the paid door, per aerianews’ math on Angi’s Q2 2026 numbers, still costs what the marketplace always cost — about $44.50 a lead across 106,000 monthly active pros. A new front door doesn’t change what the marketplace charges the people standing behind it.

    Worth noting: Sponsored Agents are in limited alpha — OpenAI’s help page says they’re “available only to selected advertisers” and not accepting access requests. As aerianews put it: anyone selling you placement in ChatGPT’s Sponsored Agents right now is selling something that is not for sale.

    What to do before the next homeowner taps the button

    1. Claim and complete your Yelp profile. Categories, service areas, hours, photos of real work, license info. This is the record the button reads.
    2. Enable Request a Quote and know your lead price. Find out what Yelp charges you per lead in your market before the first ChatGPT-routed request lands, so the invoice isn’t a surprise.
    3. Watch response time. Quote-request leads decay fast. If the request routes to an inbox nobody checks, you’re paying for introductions you never make. Yelp’s $270 million acquisition of Hatch — an AI lead-management platform — tells you where Yelp thinks the money is: in the follow-up, not just the introduction.
    4. Ask Yelp directly how in-chat requests are labeled. As of September 2026, reporting says they carry no source tag. That may change. You want to know which of your “Yelp leads” are actually ChatGPT leads, because the homeowner’s expectations — instant, conversational, in-chat — are different.
    5. Don’t confuse the two doors. Organic citation (Yelp data, reviews, profile completeness) and paid placement (Angi’s agent, sponsored formats) are separate games with separate costs. Play the organic one first — it’s the one you can influence this week.

    The questions nobody has answered yet

    Honest gaps, stated plainly: nobody has published what the per-lead price is for a ChatGPT-routed request versus an app-routed one. Nobody has confirmed whether the homeowner sees any Yelp branding at the moment of tap. Nobody has shown whether enabling Request a Quote changes your odds of being named in the answer, or only your odds of carrying the button once named. These are the measurements worth running — and the vendors worth pressing.

    The line to remember

    The homeowner’s journey now goes: problem → ChatGPT → a name → a button → a lead. Your website is not in that chain. Yelp is. Whether you ever liked Yelp is now a historical question, like whether you liked the phone book. The button is real, the leads look billable, and the only vote you get is a complete profile.

    FAQ

    Q: Do I have to advertise on Yelp to get the button? A: No published source says advertising is required. What’s required is a claimed, complete profile with Request a Quote enabled. That said, Yelp’s lead product is the monetization — expect the economics to favor Yelp either way.

    Q: Will the homeowner know the lead went through Yelp? A: Yelp branding and links appear when its content is used in answers, per the Axios reporting. At the moment of the tap itself, the exact presentation is OpenAI’s design decision and hasn’t been documented in detail.

    Q: Can I get the button without Yelp — through my own site? A: Not through this integration. The in-chat Request a Quote is Yelp’s feature. (Separately, AI agents are beginning to visit business websites on customers’ behalf to compare companies and request quotes — BaaDigi, Sept 2026 — but that’s your site being browsed, not a button in the answer.)

    Q: Is this just for big markets? A: The rollout is early. Coverage by market hasn’t been published. The profile work is worth doing regardless — it feeds every AI surface, not just this button.

  • Do I Need to Be on Reddit for ChatGPT to Recommend Me?

    Do I Need to Be on Reddit for ChatGPT to Recommend Me?

    Direct answer: No — but you need to understand why the question exists. In 511 answers ChatGPT gave to 88 contractor-marketing prompts (BaaDigi study, Aug 2026), reddit.com was cited 136 times and google.com zero times, and nothing in that sample came from a Google Business Profile. Reddit wins citations because Reddit threads answer the buyer’s question while your services page just lists services. The fix is not “get on Reddit.” The fix is to become the kind of source that gets quoted — on Reddit and everywhere else.

    The number that started this conversation

    Related: Your website doesn’t need more traffic — it needs to be the answer.

    BaaDigi, a contractor-marketing agency, ran 88 prompts the way a homeowner would ask them and collected 511 answers from ChatGPT in August 2026, updating the write-up September 23, 2026. Across those answers, reddit.com appeared as a cited source 136 times. google.com appeared zero times. No Google Business Profile contributed a single citation. (BaaDigi, “Why Does ChatGPT Recommend Local Businesses?”)

    That ratio — 136 to 0 — is doing all the work in this debate. It is worth sitting with before reacting to it. ChatGPT did not decide Reddit is better than your company. ChatGPT assembled answers from the pages its search tool retrieved, and for contractor questions, the pages that keep getting retrieved look like Reddit threads and directories, not contractor websites.

    Why Reddit threads answer and your website doesn’t

    The mechanism was stated plainly by the team at digitaldomination.ai: “Because those pages answer the question and your website describes your services. A Reddit thread titled who is a good electrician in this town contains exactly the language and structure a model needs. Your services page contains a list of things you do. Only one of those can be quoted as an answer.” (digitaldomination.ai)

    Read that twice, because it is the whole game. A homeowner asks, “who should I call for a slab leak in Katy?” A Reddit thread literally contains neighbors naming names and saying why. Your plumbing page says “We offer slab leak detection and repair.” A model building an answer can lift the first one. It can only summarize the second. Models quote what answers the question.

    A Medium essay by Radusferlic (June 2026) gave this the name it deserves: ChatGPT is “a consensus engine, not a ranking engine.” It does not crawl your homepage and score it. It builds a verdict from what the rest of the internet says about you — reviews, directories, articles, forums, “best of” lists. “The recommended ones are talked about — consistently, in multiple places, by sources the model trusts.” (Medium)

    That is the uncomfortable sentence: to the model, your web silence reads as absence. An excellent company nobody mentions online is, for recommendation purposes, the same as a company that doesn’t exist.

    Three separate facts get mashed into one rumor

    Fact one: Reddit content is heavily indexed and recommendation-shaped. Reddit threads carry first-person recommendation language (“we used X, they showed up same day, cost about $400”), and OpenAI and Reddit have a partnership, announced May 16, 2024, that gives ChatGPT access to Reddit’s Data API — which digitaldomination.ai notes as one reason Reddit appears in citations “far more often than its size would suggest.” When the question is a comparison — which plumber, which roofer — directories get cited for the same structural reason: they present comparable information about many businesses at once, which is exactly what a model needs when the question is a comparison.

    Fact two: most businesses are simply absent from the conversation. A Search Engine Journal recap of an Uberall session reported that when someone asks ChatGPT, Gemini, or Perplexity a question about a category, the model reads 5 to 16 different sources before answering — and your own website accounts for about 15% of what it finds. The rest comes from Reddit threads, review platforms, directories, and forums. Roughly three-quarters of businesses are absent from the AI conversations happening about their category. If a Reddit thread in your category exists and you’re not in it, a competitor or a wrong answer fills the space. (Search Engine Journal)

    Fact three: the pattern moves. This is the part the Reddit maximalists skip. In August 2026, ChatGPT’s search changed how it retrieves the web — shifting toward site-scoped queries against specific trusted domains — and Reddit’s share of visible ChatGPT citations reportedly fell roughly 86%, per reporting digitaldomination.ai cited from Axios. (An independent analysis on Medium by Analyst Uttam documented the same August 8, 2026 shift, noting that official documentation and help centers rose as Reddit fell.) (digitaldomination.ai; Medium)

    Three facts, one conclusion: Reddit matters because it is a shape of evidence — real people answering real questions in quotable sentences — and that shape is what gets lifted. But any single source can fall out of favor overnight. The durable strategy is to be legible as an entity everywhere, not to rent one channel.

    What “being on Reddit” actually means

    There are three rungs, and most contractors only need the first two.

    Rung one: get mentioned. Somebody in r/plumbing, your city’s subreddit, or a homeowner thread names your company with a specific story attached — the job, the price range, the crew member’s name. You don’t write it. A customer does. This is the hardest rung to control and the most valuable.

    Rung two: be present. A profile that matches your real business name, occasional genuine answers to trade questions (not pitches), an AMA if you have the temperament for it. Presence makes you findable and real; it rarely drives citations by itself.

    Rung three: get recommended repeatedly. This is what the 136 citations represent — threads where the model found your name attached to a specific, quotable recommendation. You cannot manufacture this. You can only earn it by doing work people talk about, then making it easy for them to talk about it precisely (ask for reviews that name the job, the material, the outcome — not just stars).

    What to actually do this month

    Pair this checklist with a recurring LLM visibility measurement cadence.

    1. Search Reddit for your company name and your trade + your city. See what exists. Most contractors will find nothing — which means the space is empty, not occupied by competitors. Empty space is an opportunity.
    2. Fix your own answer-shaped pages first. Publish pages that answer the actual questions in your trade in quotable sentences: what a job costs in your area, how long it takes, what happens on the first visit, what the common failure modes are. As digitaldomination.ai puts it: “Give a model something worth lifting and it will lift it.” Your website should be the easiest thing on the internet to quote about your own work.
    3. Seed precise review language. Reviews that say “great service” teach the model nothing. Reviews that say “they re-piped our 1970s copper with PEX in two days and the city inspector passed it first try” are matchable to real questions. Ask for the specifics.
    4. Participate on Reddit like a neighbor, not a marketer. Answer trade questions in relevant subreddits without pitching. One useful comment history is worth more than ten promotional posts — and the promotional posts are what get you banned and what get cited as spam.
    5. Do not buy Reddit placement. Any vendor selling guaranteed Reddit mentions in ChatGPT answers is selling what BaaDigi’s own study warns against: “Do not buy a package promising placement because you reached a review count or installed schema.” Astroturfed threads are detectable, removable, and — when discovered — they poison the entity instead of helping it.

    The line to remember

    You don’t need to be on Reddit. You need to be quotable everywhere Reddit-style evidence lives — threads, reviews, directories, roundups — in sentences a model can lift whole. The 136-to-0 number isn’t a verdict that Reddit beats your website. It’s a verdict that answered questions beat service lists. Write the answers.

    FAQ

    Q: Will posting on Reddit myself make ChatGPT recommend me? A: Probably not directly, and spammy self-promotion backfires. Genuine participation builds a real presence; citations come from threads where other people recommend you with specifics. The highest-leverage move is making customers’ recommendations quotable.

    Q: Is my Google Business Profile useless for ChatGPT then? A: Not useless — keep tending your Google profile as the front door; it feeds the directories and aggregators the models read, and it anchors your entity’s facts (hours, services, location). But the BaaDigi data shows it is not itself a citation source in ChatGPT answers. Keep it accurate; don’t expect it to win recommendations alone.

    Q: What if competitors are trashing me on Reddit? A: That’s a different problem — reputation defense, not discovery — and it has its own playbook. Monitor your name monthly, respond factually where the platform allows it, and make sure the accurate record (your site, your profiles, your reviews) outweighs the attack in volume and specificity.

    Q: Didn’t ChatGPT stop citing Reddit in August 2026? A: Reddit’s share of visible citations dropped sharply after a retrieval change — it didn’t disappear. The lesson isn’t “Reddit is dead” or “Reddit is everything.” It’s that single-source bets are fragile and entity legibility across many sources is the durable play.

  • “Why Did You Recommend Them?” — The 5-Minute Interrogation

    “Why Did You Recommend Them?” — The 5-Minute Interrogation

    Direct answer: Type it. After any AI engine recommends a business — yours or a competitor’s — ask the follow-up: “Why did you recommend them?” The engine will often tell you which signals it used: the reviews it read, the directory it trusted, the facts that tipped the decision. It’s free competitive intelligence, it takes five minutes, and almost nobody in the trades is doing it.

    Where this comes from

    CI Web Group, a digital agency, published a checklist called “The AI Interview: What Answer Engines Ask About You.” Buried in it as step 5 of a 20-minute self-check is the single most useful sentence in the AI-visibility literature this year:

    > “Ask a follow-up: ‘Why did you recommend them?’ The engine will often tell you which signals it used. Free competitive intelligence.”

    The full checklist is worth your twenty minutes — open ChatGPT, Perplexity, and Gemini in separate tabs; type the exact question a homeowner would ask for your top three services and your top three cities (“Best plumber in Katy for a slab leak” beats “plumber Katy”); screenshot every answer; note who gets named, who gets skipped, and which facts about your business are wrong; run the follow-up; trace every error to its source; repeat monthly. (CI Web Group)

    But the follow-up question is the hinge. Everything else is observation. The follow-up is interrogation.

    Why it works

    When ChatGPT, Perplexity, or Gemini recommends a business, it has just done retrieval: it searched the web, pulled sources, and synthesized. When you ask why, you’re asking it to narrate that retrieval. The engine will typically name the kinds of signals that carried weight — review volume and recency on a specific platform, a directory profile with complete service data, mentions across multiple independent sources, specific review language matching the question.

    Is the explanation perfectly faithful to the model’s internal process? No — and you should know that. The “why” is itself a generated answer: a plausible reconstruction, not a system log. Treat it the way you’d treat a rival estimator explaining his bid: informative, self-serving in places, and most valuable when you cross-check it against the evidence (the actual citations in the first answer, which you screenshotted).

    Even with that caveat, it’s the cheapest competitive intelligence in marketing. An agency will happily sell you a “competitor gap analysis” that tells you less — and bill you for the privilege.

    The 5-minute procedure (do it tonight)

    Minute 1 — Ask the buyer question. Open ChatGPT (or Perplexity, or Gemini — run all three if you have ten minutes). Type exactly what a homeowner would type. Not keywords. A question. Include the service and the city: “Who’s the best plumber in Katy for a slab leak repair?” Screenshot the answer.

    Minute 2 — Ask why. Type: “Why did you recommend [the named business]?” Use their exact name from the answer. Screenshot what comes back. You’re looking for signal names: review platforms, specific review counts, directory profiles, “mentioned across multiple sources,” website content it quotes.

    Minute 3 — Ask about the sources. Follow up with: “Which specific reviews or pages influenced that recommendation?” and “What would make you recommend a different company for this job?” The second question is the money question — it tells you the gap between you and the winner in the engine’s own words.

    Minute 4 — Run it for your business. Now ask about yourself by name: “What do you know about [Your Company] in [City]?” Then: “Why didn’t you recommend them for [the job]?” Screenshot everything. The engine will often list what’s missing — thin reviews, no directory presence, conflicting hours, an unclaimed profile.

    Minute 5 — Write down the three gaps. Not ten. Three. The three missing signals the engine named most specifically. Those are your work orders for the month.

    What you’ll typically learn

    About the winner: which review platform carried the recommendation (often Yelp or Google reviews, sometimes a directory you ignore), whether the win came from review language matching the question rather than review count, and whether the business is even good or just legible. Scott Tischler’s July 2026 experiment found the named winner often isn’t the best-reputed shop in town — it’s “the one that was legible to a machine.” The interrogation tells you which legibility won.

    About yourself: SOCi’s 2026 Local Visibility Index puts business profile accuracy on ChatGPT and Perplexity at about 68% — versus 100% on Gemini, which pulls straight from Google Maps — so expect the engine’s picture of your business to contain errors. Wrong hours, wrong services, a closed flag, an old phone number. Each error has a source, and the source is fixable. As CI Web Group puts it: “Wrong hours on ChatGPT usually means wrong hours on a directory the engine trusts. Fix the source, not the chatbot. You cannot argue with the machine. You can only feed it better facts.”

    About the game: run the same questions across engines and you’ll see different winners with different reasons — which is exactly what the “which AI should I care about” analysis shows. The interrogation teaches you that there is no single ranking to climb. There are separate evidence pools, and the follow-up shows you which pool each engine drank from.

    Three traps to avoid

    Trap one: treating one answer as the truth. AI answers are non-deterministic — the same question tomorrow can name a different business. Run the interrogation two or three times across a week before you spend money on what it told you. One screenshot is an anecdote; three is a pattern.

    Trap two: arguing with the engine. Telling ChatGPT “that’s wrong, I’m better” accomplishes nothing. The engine restates what the web says. Change the web — the reviews, the directory data, the pages — and the answer follows on the next crawl. The checklist’s last line is the whole philosophy: “Repeat monthly. This is a vital sign now, like checking your reviews. Operationalize it with a LLM visibility measurement stack.”

    Trap three: interrogating once and filing it. The signals change. In August 2026, ChatGPT’s retrieval shifted and Reddit’s citation share fell off a cliff — the “why” answers from July would have named sources that stopped mattering in September. Monthly is the cadence. Put it on the calendar next to the review check.

    What to do with the intel

    Convert each of the three gaps into a source fix, not a chatbot fix:

    • “Recommended them because of 200+ recent Google reviews mentioning slab leak work” → run a review campaign asking specifically for job-type language, not stars.
    • “Their Yelp profile lists slab leak detection as a service with photos” → complete your Yelp categories and upload real job photos.
    • “Mentioned on three local ‘best of’ lists” → pitch the list publishers, or earn the mentions with work worth listing.
    • “Your hours conflict across two directories” → fix the source directories; the engine can’t resolve what you haven’t resolved.

    Then re-run the interrogation next month and watch the “why” change. When the engine starts naming your signals unprompted, you’re winning.

    The line to remember

    Your competitor’s recommendation is a case file, and the engine will read it to you if you ask. Five minutes, three questions, zero dollars — “Why did you recommend them?” is the cheapest market research in the trades right now. Run it tonight, monthly after that, and fix sources instead of arguing with machines.

    FAQ

    Q: Will the engine actually answer honestly? A: It will answer plausibly. The explanation is generated, not a system log — treat it as a strong lead, not gospel. Cross-check against the citations in the original answer (which is why you screenshot first).

    Q: Should I do this in ChatGPT, Perplexity, or Gemini? A: All three — they use different source pools and often name different winners. The procedure is identical; the intelligence differs. That’s the point.

    Q: What if it recommends me and I ask why? A: Even better. You learn which of your assets is actually carrying the win, so you can protect it — and you learn the exact language to repeat in reviews, profiles, and pages.

    Q: Can I automate this? A: You can script the prompts, but the judgment — which gap matters, which error to fix first — is still yours. Monthly, by hand, twenty minutes. Some things shouldn’t be delegated to the thing you’re auditing.