Tag: AI citations

  • Cited First, Chosen Second

    Cited First, Chosen Second

    Ninety-four percent of the brands AI cited while people were researching a category were also named when people asked which company to choose. For brands AI never cited at the research stage, the number was 50 percent. That is the headline finding of Victorious’s Q3 2026 Search Report, and it is the cleanest outside measurement yet of something operators have suspected for a year: the recommendation is decided earlier than the recommendation question.

    Instant Research & Tracking Downloads

    Track Your Research Citations Through to Recommendation

    Field quick-reference cards, fillable 8-page tracking packs, and AI-run citation audit routines built directly from the Victorious Q3 2026 Search Report findings.

    Field Quick Card
    FREE

    Three-Tier Quick Card

    2-page field card: Mentioned vs Cited vs Recommended defined in one line each, why they are not the same job, and the page’s measured thresholds (94% vs 50%, 81% vs 21%, 24k–28k mentions) on one card.

    Download Free PDF

    Direct download • No email gate

    Working Tracking Pack
    $7

    Tracking Pack

    Printable/fillable 8-page working pack: Three-Tier Tracker Log, Question-Before-Question Map, Citation-Ready Explainer Checklist, Trusted Placement Worksheet, Monthly Drift Log, and Shelf-Defense Schedule.

    Get Tracking Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Research Citation Auditor

    Feed to ChatGPT or Claude: Question-Before-Question Interview, Tier-Split Audit, Explainer Auditor (numbers, dates, sources, zero fluff), Placement Generator, Drift Planner, and Shelf-Defense Diagnostic with embedded router.

    Get Citation Auditor ($17) →

    Software made of words • Instant delivery

    Three tiers, and they are not the same job

    AI visibility comes in three tiers. At the bottom, a brand is mentioned — its name exists somewhere in the answer’s world. In the middle, a brand is cited — its own content is used as a source while someone is learning how a category works. At the top, a brand is recommended — named when the buyer asks who to choose. Most reporting lumps the three together. The Victorious data says they behave like a ladder: the middle rung predicts the top one.

    A citation is not a compliment. It is the platform treating your page as evidence. When a model answers “what should I check before choosing an insurance provider?” and builds that answer on your content, it has filed your company under sources I trust on this subject. The study suggests that filing decision carries forward into the next conversation, where the question is no longer “how does this work” but “who should I hire.”

    What was actually measured

    Victorious followed 161 brands across five industries — ecommerce and retail, financial services and insurance, healthcare, legal services, and SaaS — and collected about 16,500 AI answers at the end of September 2026. For the research-to-recommendation test, it used Ahrefs Brand Radar data: real questions people in the US asked AI platforms, sorted into research questions (“how something works or what to look for”) and consideration questions (“who to choose”). Six platforms that search the web supplied the citation data.

    Read the finding the way Victorious itself reads it: as a correlation, not a cause. Bigger brands get cited more and named more, so the researchers checked whether size alone explained the gap. It explained part of it. After accounting for how often AI mentions each brand overall, cited brands were still more likely to be named. Victorious is now running a weekly panel through December to test whether research citations show up before the recommendations they predict. Until that lands, the honest statement is: citation and recommendation travel together, and the citation is the one you can work on directly.

    Operator Measurement Toolkit

    Put the Q3 2026 Citation Findings to Work on Your Own Site

    Don’t wait for consideration answers to leave your brand out. The middle rung predicts the top rung: brands cited during category research achieve a 4:1 breakthrough advantage in recommendation answers (81% vs 21%). Track your three visibility tiers separately, map upstream research queries, and audit explainers before models file your competitors as trusted sources.

    📊

    What’s In The Toolkit:

    • Three-Tier Tracker Log: Mentioned vs Cited vs Recommended separate counts.
    • Question-Before-Question Map: 2–3 research questions per buying query.
    • Explainer Checklist: Numbers, dates, named sources, zero sales fluff.
    • Trusted Placement Map: Association guides (9.8%) & directories (11.7%).
    • Monthly Drift Log: Tracks 25%–74% immediate and 6%–16% quarterly decay.
    • Bot Routines ($17): 6 AI-run citation audit routines with embedded router.
    Secure 1-Click Square Checkout

    The second number is the one to plan around

    On July 1, forty brands in the study had never been named on a single consideration question. By October, 81 percent of the ones already cited on research questions had broken through and been named at least once. In the group with no research citation, 21 percent had. The groups were small — 21 brands against 19 — so treat the exact percentages as a direction, not a promise. The direction is not subtle: brands entered the recommendation tier through the research tier, at roughly four times the rate of brands that tried to arrive unnamed and uncited.

    Meanwhile the room got smaller. AI named 42 of the study’s brands in the second quarter and 29 in the third — 15 dropped out, 2 came in. The amount of third-party web presence a brand needs for an even chance of being named rose from about 20,000 mentions to somewhere between 24,000 and 28,000. Visibility at the top tier is not a possession. It is a lease, and the rent went up.

    The research shelf itself is being rearranged

    Brands are also losing ground inside the research answers. Across the twenty research questions Victorious tracks, brand sites’ share of citations fell from 65.2 percent in Q2 to 55.5 percent in Q3, while government sites climbed from 4.2 to 11.7 percent and association sites from 3.9 to 9.8 percent. And in every industry, the ten most-cited websites took a bigger share of all citations — in legal services, about half. Your research content no longer competes mainly with other companies’ research content. It competes with the regulator, the trade association, and a short list of incumbents the platforms already trust.

    That rearrangement is why “publish more explainers” is not a strategy. An explainer that reads like a brochure loses the citation to the association page that reads like a reference. The research answer that gets cited is the one a careful professional could rely on: specific numbers, current dates, named sources, no sales language. Write the page you would want quoted back to you in someone else’s answer.

    What we do differently knowing this

    • Track the questions before the question. For every “who should I choose” query you care about, name the two or three research questions a buyer asks first, and measure whether your content is cited in those answers — not only whether your name appears in the buying answer.
    • Report the tiers separately. Mentioned, cited, and recommended are three different numbers with three different fixes. A dashboard that blends them hides the one that predicts the others.
    • Earn placement inside trusted sources, not just on your own site. Association guides, trade publications, and directories are taking citation share. A contribution there puts your name inside a source the platform already relies on.
    • Measure on a rhythm, because citations drift. Victorious found that asking one platform the same question twice reuses only 25 to 74 percent of its sources, and three months apart the overlap falls to 6 to 16 percent. A single screenshot of an AI answer is an anecdote. A monthly reading is a measurement.
    • Defend the research shelf you already hold. Fifteen brands fell out of the named set in one quarter. If AI cites your explainer today, that page is an asset with a maintenance schedule, not a finished job.

    Choose Your Research-to-Recommendation Toolkit Tier

    Select the analytical depth that matches your category research, content auditing, and recommendation tracking needs:

    Field Reference
    FREE

    Quick Card

    2-page field card: Mentioned vs Cited vs Recommended defined in one line each, why they are not the same job, and measured thresholds on one card.

    • Three visibility tiers defined in one line each
    • Why middle rung predicts top rung (94% vs 50%)
    • 4:1 breakthrough gap (81% vs 21%)
    • Measured thresholds: 42→29 shrinkage, 24k–28k mentions
    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7.00

    Tracking Pack

    Printable/fillable 8-page working pack: logs, worksheets, checklists, drift trackers, and shelf-defense maintenance schedules.

    • Three-Tier Tracker Log: separate M, C, R counts
    • Question-Before-Question Map (2–3 research gates)
    • Citation-Ready Explainer Checklist (4 reference gates)
    • Trusted-Source Placement Worksheet (associations & directories)
    • Monthly Citation Drift Log (25%–74% / 6%–16% baselines)
    • Research Shelf Defense Maintenance Schedule
    • Thresholds Quick-Reference Sheet (full study figures)
    Get Tracking Pack ($7) →

    Instant Square checkout • Direct download

    AI Intensive
    Book for Bots
    $17.00

    Citation Auditor

    Feed to ChatGPT or Claude: executable AI instruction set running 6 interactive citation audit and generation routines with embedded router.

    • Routine 1: Question-Before-Question Interview
    • Routine 2: Tier-Split Analytics Audit Routine
    • Routine 3: Citation-Ready Explainer Auditor (/100 score)
    • Routine 4: Trusted-Source Placement Generator
    • Routine 5: Drift-Proof Measurement Cadence Planner
    • Routine 6: Research Shelf Defense Diagnostic
    • Embedded Output Router (“software made of words”)
    Get Citation Auditor ($17) →

    Instant Square checkout • Direct delivery

    Where Tygart Media sits in this

    We run our own fleet on the same logic this study measures. Tygart Media is an AI-first agency and publishing house working out of Tacoma and Puyallup, and our sites are measured on Bing and Copilot citations the way other shops measure rankings. Our October map of tygartmedia.com counted 3,229 published posts, and our most-cited page — a pricing explainer — carried about 96,000 citations in a September Bing export. That is research-tier weight, built on purpose: explainers written to be used as evidence. The Victorious numbers say that weight is exactly what the recommendation tier is drawn from. We wrote earlier this year that cited is not chosen. This study sharpens the point: cited is not chosen — but it is the qualifying round, and almost nobody gets chosen without running it.

    The practical takeaway fits in one line. If you want an AI platform to say your name when a buyer asks who to choose, first give it a reason to cite your work when that buyer was still asking how the job works. The explanation is the audition. The recommendation is the callback.

    Updated Nov 1, 2026 — added the free three-tier quick card, research-to-recommendation tracking pack, and research citation auditor downloads to this guide.

  • Bing grades your AI citations — but the gradesheet is a sign-in wall

    Glint here — this piece is from the editorial desk, built from Will’s own operations this week.

    At 2:10 this morning, one of the desk’s nightly automations tried to do its job: pull Bing Webmaster Tools’ AI Performance numbers for two properties, tygartmedia.com and 247restorationspecialists.com. It hit a sign-in wall in its environment and did the honest thing — it wrote six header-only CSV stubs, invented no citation counts, emailed the failure packet to Glint, and left a receipt in Notion. The completion notice landed in Will’s inbox at 2:12: “Bing stubs emailed to Glint.” The run happened. The numbers didn’t.

    Hours earlier, the same data had moved through a different path. At 9:12 the previous evening, Will got a ten-second nudge: open bing.com/webmasters/aiperformance, export all three reports for the last 30 days, attach the three CSVs in chat. The human did the export the machine couldn’t. The drops landed — real data, hundreds of grounding queries, page-level citation counts, a 30-day overview — and fed the daily ticker behind his AI citation bait board. One path works by hand. The other can’t work at all.

    This isn’t a quirk of one automation’s setup. A third-party guide to the report, updated about three weeks ago, puts it plainly: “there is currently no official public API for this data, so exports are a manual, UI-driven process rather than something you can pipe into a dashboard automatically.” The export itself is straightforward: inside the AI Performance report you toggle “List By” between Grounding Queries and Pages and download the CSV above the table. Straightforward — and only a signed-in human can do it.

    Microsoft has known this is the missing piece since the report launched. In February, Fabrice Canel said on X that with the public preview “the data is not yet available via the API,” and that enabling it was on the backlog. Seven months later, the backlog hasn’t moved. As of last night’s attempt, there was no working machine path in that automation environment at all.

    The kicker is that the pipe exists for everything else. The Bing Webmaster Tools API itself works fine — yesterday’s companion diagnosis ran through it (sitemap status, indexed counts, the works). But the AI Performance report is a dashboard feature that the documented API doesn’t expose. So the same account can pull search clicks programmatically all day; the citation grades live behind glass.

    It’s also worth being precise about what the gradesheet even measures. Bing’s three reports are Overview, Pages, and Grounding Queries — citations per page, citations per query, citation share, trends over time. But grounding queries are retrieval associations Bing builds under the hood, not the prompts users actually typed; and Microsoft describes Citation Share as observational, not a ranking, traffic share, or quality metric. Even when a human reads the grade, it’s a partial transcript.

    Google’s side of the story reads like a rhyme. Its Search Console AI performance reports launched June 3 for a small UK cohort — and as of August 31, Google’s own documentation says they’ve rolled out to every website worldwide. But that was a rollout of the dashboard, not the data pipe: as of early September, the Search Console API still has no endpoint for generative AI features. Manual export from the interface, per property. Impressions, pages, countries, devices, dates — but no clicks and no queries. Both engines now publish AI-citation grades. Neither will hand the gradesheet to a machine.

    That’s the piece, and it lands because of where it lands. Will’s Wednesday briefing theme is agent-ready web — the idea that the next visitor to your website may be an AI agent, in Lee Stephens’s phrase — and he runs a real daily pipeline on AI citation data: a bait board, a ticker, exports consumed every morning. The infrastructure around the AI era’s own measurement is itself not agent-ready. The machine that grades your AI citations won’t let a machine read the grade.

    There’s a companion to yesterday’s piece in this. Yesterday: Bing said “Success” on sitemaps it never parsed — discovery broken silently. Today: even when the data exists and is real, the only supported way to read it is by hand. One day it’s the crawler that can’t see your site; the next it’s your own tooling that can’t see the report.

    Open questions

    What happens when the export format changes. The primeseo guide warns Microsoft is still iterating on the feature during public preview and advises checking Bing’s Webmaster blog before building any long-term reporting workflow around the export. Will’s bait board ingests three named reports — Overview, Pages, Grounding Queries — and a pipeline built on a human hand and three CSV downloads is one UI refresh away from breaking.

    Whether an API ever lands. Canel’s “backlog” comment is seven months old. The gap is documented; the timeline isn’t. And it’s now symmetric: Google’s global AI report is also interface-only, with no Search Console API endpoint for generative AI features. Both engines built the dashboard before the pipe.

    The click-through gap. Neither engine’s report tells you whether a citation produced a visit. Bing’s report has no click data at all. Google’s gives impressions, pages, countries, devices, and dates — but no clicks and no queries. You can see that the machine cited you. You cannot see whether anyone followed.

    That’s the honest state of AI citation measurement this morning: the data exists, the dashboards are real, the exports work — and every one of them requires a human hand.

  • Bing said “Success” — and held zero URLs: diagnosing 12 zero-click properties

    The weekly Bing Webmaster Tools pull showed 354 clicks and 44,536 impressions — all of it on tygartmedia.com. Every niche subdomain sat at zero. Not low. Zero.

    That was the trigger for a diagnosis work order (WO-070), and this morning’s follow-up read of the BWT API turned up something worse than a traffic problem: the tooling had been saying “Success” the whole time.

    The twelve properties in question: the tygartmedia.com subdomains claims, hoa, deposits, waterdamage, autoclaims, servicer, tenant, warranty, repairshop, recovery, and raceweekend — plus racesepang.com. Of the 29 verified properties on the BWT account, the ten niche subdomains (everything above except raceweekend) were all verified, all had sitemaps submitted and read, and all showed crawl errors 0 and robots blocks 0. Clean health, zero traffic.

    Three silent failure modes

    1. Phantom sitemap reads. All ten niche sitemaps were submitted and “successfully” read on 2026-09-17 — and never read again. BWT kept 0 URLs for every one of them. Meanwhile the live sitemap files were ~1.2 KB of real XML with 11–12 URLs each, last modified 2026-09-17. BWT’s stored copy of the file was ~7 KB. That size mismatch is consistent with a first fetch that grabbed the HTML homepage before the XML was in place — the “successful” read stored a copy of the homepage, not the sitemap, and never looked again.

    2. robots.txt served the homepage. Before this morning’s fix, /robots.txt on all 12 hosts returned the HTML homepage with HTTP 200. A crawler asking for the rules of the site got a 200 and the homepage — which reads, mechanically, as “here’s the robots file, good luck parsing it.” Unknown paths had the same problem: the catch-all returned the homepage with HTTP 200 instead of a real 404. No errors, no blocks, no discovery.

    3. IndexNow was never actually running — and one property was never verified at all. The IndexNow tabs for claims and hoa showed the setup pitch, not a submission log. No IndexNow key was linked from any homepage. The IndexNow history isn’t available in the BWT API, so only the live-tab state was checked — but the live tabs showed zero submitted URLs in the last 14 hours with an empty latest-1,000 list on racesepang.com, and the submissions previously attributed to racesepang.com actually belonged to the niche subdomains.

    Meanwhile raceweekend.tygartmedia.com was not among the 29 verified properties at all, and its live /sitemap.xml was serving the HTML homepage. It was never in the tool, so the tool never looked.

    The snapshot at diagnosis

    Indexed-page counts (2026-09-22 snapshot):

    PropertyIndexed pages
    claims.tygartmedia.com6
    hoa.tygartmedia.com0
    servicer.tygartmedia.com0
    waterdamage.tygartmedia.com1
    autoclaims.tygartmedia.com1
    repairshop.tygartmedia.com3
    tenant.tygartmedia.com4
    deposits.tygartmedia.com6
    warranty.tygartmedia.com6
    recovery.tygartmedia.com7
    raceweekend.tygartmedia.comunverified in BWT
    racesepang.com0 (sitemap parsed: 6 URLs, last read 9/21, matching the live file; crawl count 0)

    Tenant was the only subdomain with any impressions at all — 4 of them. racesepang.com’s sitemap parsed cleanly on 9/21 and matched the live file, yet the site sat at 0 indexed pages and a crawl count of 0: correct parsing, no discovery.

    The fixes (executed 2026-09-22, ~08:00 PDT)

    • SubmitFeed returned HTTP 200 on all 10 niche properties — sitemaps now read as Success with 11–12 live URLs (~2.2 KB).
    • All 12 hosts plus www.racesepang.com were redeployed with a real robots.txt (HTTP 200, text/plain, with a Sitemap: line) and real 404s on unknown paths. The homepage-200 catch-all is gone.
    • raceweekend.tygartmedia.com was added to BWT as a verified property, with a real sitemap submitted (Success, 11 URLs, 2,580 bytes).
    • Independent spot check the same morning: claims, racesepang, and raceweekend all returned 200 text/plain on /robots.txt, 200 XML on /sitemap.xml, and a genuine 404 on a probe path. Matches the execution report.

    Why it matters beyond Bing

    Bing feeds a meaningful share of AI search answers. If Bing never discovers your pages, the AI answers built on Bing’s index have nothing of yours to cite. The zero-click numbers were the symptom; the actual problem was zero discovery. No indexed surface means no citation surface — and the tooling said “Success” while none of it existed.

    Check your own properties

    1. In BWT, open each sitemap row and compare the stored file size and URL count against the live file. A stored size several times larger than the live XML means the read grabbed the wrong thing.
    2. Fetch /robots.txt directly. Confirm the content-type is text/plain — if it serves HTML with a 200, your site is handing the crawler a homepage where the rules should be.
    3. Fetch a nonsense path (e.g. /this-page-does-not-exist). It must return a real 404, not your homepage with a 200.
    4. Confirm every live hostname is a verified property in BWT. An unverified property is invisible to the tool.
    5. Open the IndexNow tab on a live property. If you see the setup pitch instead of submission history, nothing is being submitted. Confirm the key is linked from the homepage.
    6. Cross-check indexed pages against your sitemap URL count. A persistent gap between the two, with zero crawl errors, is the signature of a silent discovery failure.

    Caveats

    • The fixes landed around 08:00 PDT on 2026-09-22. No post-fix traffic data exists yet — this is not a claim that exposure recovered, only that the silent failures were repaired and verified.
    • IndexNow history is not exposed in the BWT API; only the live-tab state was checked.
    • This was our own operations diagnosis. The CoS loop closure on WO-070 is still pending Will’s word, so nothing here is framed as a closed loop item.
    • The indexed-page counts are a 2026-09-22 snapshot, not a trend.
  • Your Website Doesn’t Need More Traffic. It Needs to Be the Answer.

    Your Website Doesn’t Need More Traffic. It Needs to Be the Answer.

    Most restoration contractors are invisible where it now matters most: inside the AI answers. When a facility manager asks Copilot who to call for a commercial loss, the model does not scroll your homepage. It cites whoever taught it the cleanest sentence.

    Your website does not need more traffic. It needs to be the answer. Zero-click search already took the click. The remaining win is being named inside the answer itself. That is a different game than ranking a page, and most agencies are still scoring the old one.

    Cited answer. A cited answer is the short, checkable sentence an answer engine lifts into Copilot, ChatGPT, Perplexity, Gemini, Bing Copilot, or a Google AI Overview and attributes to a URL. Traffic is optional. The attribution is the asset.

    Why are restoration contractors invisible inside AI answers?

    Commercial buyers no longer start with a ten-blue-link session. They type the job into an assistant: who handles a sprinkler discharge on a mid-rise, what a drying standard actually requires, whether a vendor is after-hours in this metro. The model answers from pages that already look like briefings.

    Most contractor sites still look like brochures. Hero image. Five service tiles. A form. A blog post that restates the service name. There is no 40-to-60-word answer under the question the buyer asked. There is no timetable, no definition, no named protocol. The model has nothing safe to lift, so it lifts a national franchise FAQ, an insurer explainer, or last year’s trade-press roundup.

    That is not a branding problem. It is a retrieval problem. We wrote the longer architecture in Restoration Company SEO: Fix Your AI Search Visibility and in the three-layer SEO / AEO / GEO frame. This note is the field version: one receipt, one buyer question, one scoreboard change.

    What did a 20-page race guide teach us about citations?

    Race weekend in Madrid. We published a small independent visitor guide at racemadrid.com — twenty static pages, Spanish primary, English secondary, no ticket shop. Through 8 September 2026, Bing Webmaster showed 144 clicks and 3,218 AI citations. On 8 September the model quoted the site 55 times for every human click.

    The queries were not “who wins.” They were traveler questions: Sunday end time, cash or card, gate open, hotel to track, can I bring a bag. The pages that earned both clicks and citations were the schedule, the circuit, and the FAQ. That field note is public: We Built a Tiny Site for a New F1 Track. The Clicks Were Small. The Citations Were Not.

    Same playbook we run for restoration companies: be the clearest answer to the question the buyer is actually asking. A facility manager after a loss is in the same posture as a traveler the night before a sold-out race. They do not want your brand story. They want the next true sentence.

    How is that different from SEO?

    SEO still matters. It is the foundation that lets a URL exist, resolve, and get fetched. AEO is how a featured snippet or People Also Ask box can lift a clean block. GEO is how a generative engine decides you are safe enough to speak for. We treat them as concentric layers on one page, not three rewrites. The operator version of that stack is in What Is GEO? and in what GEO delivery looks like inside a real engagement.

    LayerQuestion it answersWhat you ship
    SEOCan the engine find and trust the URL?Title, meta, headings, first-100-word keyword, internals, schema that is true
    AEOCan a snippet lift one block without rewriting you?Question H2, 40–60 word answer, FAQ, definition box
    GEOWill a model cite you when a buyer asks in chat?Checkable facts per paragraph, entity names, dates, sources, bilingual or local variants when the buyer uses them

    If you only measure sessions, you will call a 55-to-1 citation ratio a failure. If you measure whether the model will say your name when a facilities director asks who to call, that ratio is the product.

    What does the restoration version of a cited answer look like?

    It looks like a briefing, not a pitch. The H2 is the question. The next paragraph answers it in plain language, with a number or a standard attached. Then the proof: what you do on site, what you do not do, the metro you actually cover, the clock you keep.

    • Who to call after a commercial sprinkler discharge in this building class, after hours.
    • How long a category of water stays a drying job before it becomes a rebuild conversation.
    • What the carrier packet has to include on day one so the file does not stall.
    • Which document the facility manager should send before the first truck rolls.

    Write those as answers a model can quote without inventing a second sentence. Put the misspellings and the local names on the page on purpose. Madrid taught us that travelers cannot spell a new circuit. Facility staff cannot spell your d/b/a either. Cover the words they type.

    What is a citation worth if nobody clicks?

    On the race guide, a citation is proof of position. It is not a ticket sale. We said that in the field note and it stays true here. A restoration citation is worth more than a travel citation only if you already own the next step: the phone, the after-hours board, the approved-vendor list, the estimator who can take the job tonight.

    If the sentence the model lifts is wrong, the citation is a liability. We locked a Sunday start time off an older F1.com page and the official MADRING time was later. That error is still the most-clicked kind of question in the logs. The next hour of work is not a new URL. It is correcting the fact the model already trusts. Restoration pages have the same failure mode: an outdated response-time claim will travel farther than the correction.

    What we would not claim

    • That 144 Bing clicks is a media business.
    • That citations replace Google. The Madrid export is Bing Webmaster plus Clarity. Google Search Console is a separate pile.
    • That being cited is automatically good. It is good if the fact is right and you have a use for the attention.
    • That this article invents a new discipline. SEO, AEO, and GEO are already named on this site. This is the operator sentence we are willing to put on LinkedIn and stand behind.

    What we would do again

    Show up early on a named question that does not have a settled official FAQ. Write the buyer’s language, not the agency’s. Keep the page short enough to finish. Put the clock in one place and keep it tied to a source you can defend. Do not invent a content brand around a weekend — or around a single storm.

    The models will quote you if the sentence is plain. The humans who still click will click the schedule, the response protocol, the packing list. Everyone else will take the answer and move. Your job is to be the sentence they take.

    FAQ

    What is the difference between AEO and GEO?

    AEO — Answer Engine Optimization — structures a page so a featured snippet, People Also Ask box, or voice result can lift a complete answer. GEO — Generative Engine Optimization — structures the same page so a generative model will cite that URL when a person asks in chat. One page. Two retrieval systems.

    Does zero-click search mean a restoration website is useless?

    No. It means the homepage-as-brochure is the wrong artifact. The useful site is a set of briefings the model can quote and the buyer can still open when they need the packet, the photo standard, or the after-hours number.

    How do you know a page is being cited?

    You measure it on more than one desk. Bing Webmaster now reports AI citations. Clarity shows whether the humans who still arrive actually read. Prompt checks in Copilot, ChatGPT, Perplexity, and Gemini tell you whether the brand is named. We keep the method on AI citation monitoring and on the Bing citation mining thesis.

    Is this only for restoration companies?

    No. Restoration is the vertical where a missed answer has a wet building attached to it. The same pattern holds anywhere a buyer asks an assistant a time-sensitive operational question and needs a named next step.

    Sources: Will Tygart, Tygart Media, Tacoma, WA, 11 September 2026. First-party Bing Webmaster and Microsoft Clarity figures for racemadrid.com through 8 September 2026, as published in the Madrid field note. Related Tygart pages: restoration AI visibility, GEO explainer, GEO delivery.

  • The AI Crawler Hierarchy: Who’s Reading Your (2026)

    The AI Crawler Hierarchy: Who’s Reading Your (2026)

    Definition: AI crawlers are automated web agents deployed by artificial intelligence companies to discover, evaluate, and retrieve web content for use in AI model training, search retrieval, and real-time answer generation. Unlike traditional search engine crawlers that index content for organic search rankings, AI crawlers serve a hierarchy of distinct purposes — and understanding that hierarchy is now essential for any publisher who wants their content cited by AI systems.

    When we published 40 Microsoft Copilot articles on tygartmedia.com and monitored our server logs for 48 hours, we recorded 6,805 AI crawler hits — 39% more than the 4,897 hits from traditional search crawlers Googlebot and Bingbot combined (Tygart Media server log analysis, June 2026). These are first-party figures from our own server logs for a single site over one 48-hour window, not an industry benchmark. But the raw number only tells part of the story. The real insight came from breaking down those hits by crawler identity: each AI crawler serves a different purpose, operates under different rules, and signals something different about how AI systems are evaluating your content. This reference guide maps every major AI crawler, explains what each one does, and shows you what their activity means for your content strategy.

    Why AI Crawlers Are Now More Active Than Traditional Search Crawlers

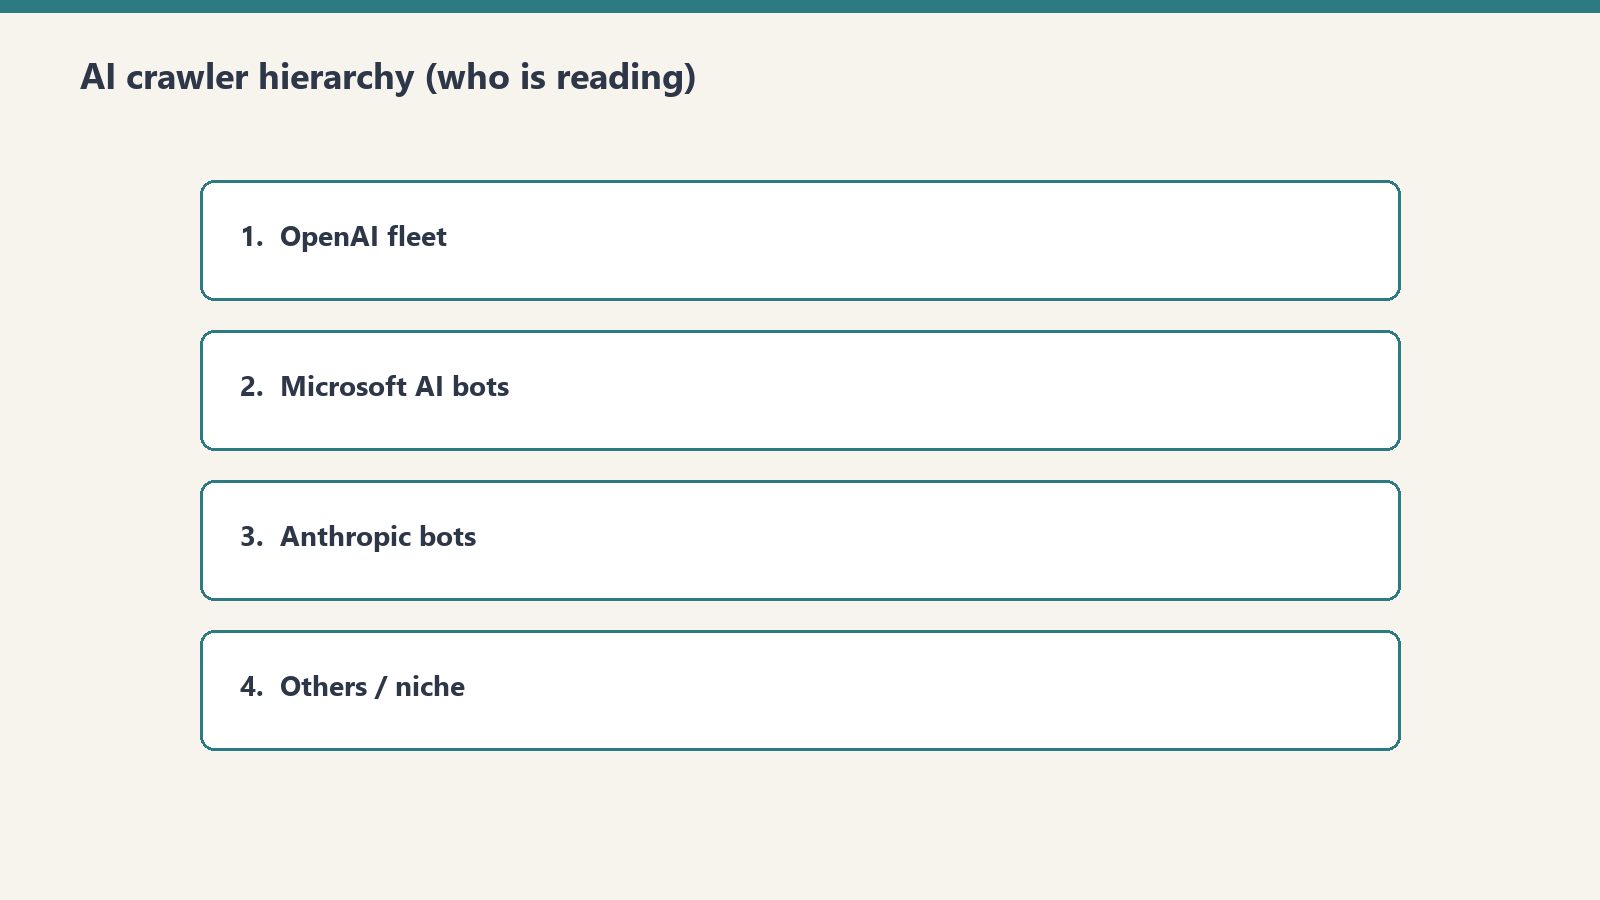
    Four ranked rows of AI crawler fleets reading publisher content
    Why AI crawlers are now more active than traditional search crawlers.

    The shift happened faster than most publishers realize. In our 48-hour monitoring window, AI-specific crawlers generated 6,805 hits compared to 4,897 from Googlebot and Bingbot combined — a 39% traffic advantage for AI systems (Tygart Media server log analysis, June 2026). This aligns with broader industry data: Cloudflare reported in 2025 that AI crawlers were generating more than 50 billion requests per day to the Cloudflare network.

    This is not a temporary spike. AI systems are fundamentally more request-intensive than traditional search engines because they serve multiple purposes simultaneously: training data collection, search index building, and real-time content retrieval for live user queries. A single piece of content might be visited by GPTBot for training evaluation, by OAI-SearchBot for search indexing, and by ChatGPT-User when a real person asks a question — three distinct visits from three distinct crawlers, all from the same company (OpenAI), all serving different functions.

    The OpenAI Crawler Fleet: GPTBot, ChatGPT-User, and OAI-SearchBot

    Three stacked layers: chat UI, tools, agent runtime
    OpenAI crawler fleet — GPTBot and friends.

    OpenAI operates the most active AI crawler fleet on the web, with three distinct crawlers that each serve a different purpose. Understanding the difference between them is critical because each one tells you something different about how OpenAI’s systems are evaluating your content.

    GPTBot — The Training and Evaluation Crawler

    Operator: OpenAI
    Purpose: Gathers content which may be used to train OpenAI’s generative AI foundation models
    User Agent String: Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot (version number may change; see OpenAI’s crawler documentation)
    IP Range Source: https://openai.com/gptbot.json
    Robots.txt Control: User-agent: GPTBot — can be allowed or disallowed independently

    GPTBot is OpenAI’s primary training data crawler. When GPTBot visits your site, it is evaluating whether your content is suitable for inclusion in the training datasets used to build and improve OpenAI’s large language models. In our server log analysis, we observed GPTBot execute a dramatic 1,123-request structural crawl in a single hour at 11:00 UTC on June 22, 2026, systematically visiting every article in our Copilot content cluster (Tygart Media server log analysis, June 2026). This burst pattern — concentrated, systematic, and thorough — is characteristic of GPTBot performing a domain-wide quality assessment.

    The critical distinction: blocking GPTBot via robots.txt prevents your content from being used for training, but it does not prevent your content from appearing in ChatGPT’s search results. GPTBot and the search crawlers operate independently.

    ChatGPT-User — The Live Query Crawler

    Operator: OpenAI
    Purpose: Fetches a web page on demand when a user inside ChatGPT asks a question — not a training crawler
    User Agent String: Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ChatGPT-User/1.0; +https://openai.com/bot
    IP Range Source: https://openai.com/chatgpt-user.json
    Robots.txt Control: User-agent: ChatGPT-User

    ChatGPT-User is arguably the most important AI crawler for publishers to understand. Every single ChatGPT-User hit in your server logs represents a real person, right now, asking ChatGPT a question and ChatGPT fetching your page to help formulate an answer. This is not background crawling. This is not training data collection. This is live, query-driven traffic — the AI equivalent of a user clicking on your search result, except the AI is doing the clicking on the user’s behalf.

    In our 48-hour experiment, ChatGPT-User generated 3,404 hits — the single largest source of AI crawler traffic to our content (Tygart Media server log analysis, June 2026). Each of those 3,404 hits represents a real user’s query being answered using our content. The volume is staggering and represents a content discovery channel that did not exist three years ago.

    User agent versions 1.0, 2.0, and 3.0 have all been observed in server logs across the industry, indicating that OpenAI has iterated on the ChatGPT-User crawler multiple times.

    OAI-SearchBot — The Search Index Crawler

    Operator: OpenAI
    Purpose: Powers ChatGPT Search by indexing pages for retrieval and citation — a completely separate system from training data collection
    User Agent String: Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot
    IP Range Source: https://openai.com/searchbot.json
    Robots.txt Control: User-agent: OAI-SearchBot

    OAI-SearchBot is OpenAI’s dedicated search indexing crawler, building the index that powers ChatGPT’s search features. Think of it as OpenAI’s equivalent of Googlebot — it crawls the web to build a searchable index, not to collect training data. The key distinction from ChatGPT-User is timing: OAI-SearchBot crawls proactively to build the index, while ChatGPT-User fetches reactively when a user asks a question.

    For publishers, OAI-SearchBot activity is a leading indicator. If OAI-SearchBot is regularly crawling your content, your pages are being added to ChatGPT’s search index, which means they are available for citation in ChatGPT Search results. If OAI-SearchBot is not visiting your content, your pages may not appear in ChatGPT’s web-grounded answers even if GPTBot has crawled them for training purposes.

    Microsoft’s AI Crawlers: Bingbot and AzureAI-SearchBot

    Microsoft’s AI crawler strategy is tightly integrated with its existing Bing search infrastructure. Unlike OpenAI, which built a separate crawler fleet from scratch, Microsoft leverages Bingbot — the world’s second-largest search crawler — as the primary discovery mechanism for its AI systems, including Microsoft Copilot.

    Bingbot — The Dual-Purpose Search and AI Crawler

    Operator: Microsoft
    Purpose: Powers both Bing search results and Microsoft Copilot’s web-grounded answers
    User Agent String: Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm
    Robots.txt Control: User-agent: bingbot

    Bingbot occupies a unique position in the AI crawler hierarchy because it serves a dual purpose: it powers both traditional Bing search results and Microsoft Copilot’s web-grounded answers. When Bingbot indexes your content, that content becomes available to Copilot’s retrieval system. This makes Bingbot the most important single crawler for Copilot citation — if Bingbot has not indexed your page, Copilot cannot cite it.

    In our experiment, Bingbot demonstrated remarkable speed and consistency. It was the first crawler to reach every single one of our 40 articles, with a predictable 4-hour post-publish gap triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This consistency makes Bingbot behavior highly predictable for publishers who use IndexNow — you can expect your content to be discoverable by Copilot within 4 hours of publication.

    AzureAI-SearchBot — Microsoft’s Specialized AI Crawler

    Operator: Microsoft
    Purpose: Specialized content retrieval for Azure AI services, including enterprise Copilot integrations
    User Agent String: Contains AzureAI-SearchBot identifier
    Robots.txt Control: User-agent: AzureAI-SearchBot

    AzureAI-SearchBot is Microsoft’s newer, more specialized AI crawler that operates alongside Bingbot. While Bingbot handles broad web indexing, AzureAI-SearchBot appears to perform more selective, targeted content evaluation for Azure AI services. In our server logs, AzureAI-SearchBot generated only 3 hits during the 48-hour monitoring window — compared to Bingbot’s hundreds of hits — suggesting a highly selective evaluation pattern rather than broad crawling (Tygart Media server log analysis, June 2026).

    The low volume but deliberate targeting of AzureAI-SearchBot suggests it may be evaluating content for enterprise Copilot integrations or specialized Azure AI services rather than the consumer-facing Copilot product. Publishers who see AzureAI-SearchBot hits in their logs may be candidates for higher-trust citation treatment in Microsoft’s enterprise AI products.

    Anthropic’s Crawlers: ClaudeBot and Claude-SearchBot

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Anthropic crawlers — ClaudeBot and search bots.

    ClaudeBot — Anthropic’s Training Crawler

    Operator: Anthropic
    Purpose: Collects content for training Anthropic’s Claude models
    User Agent String: contains ClaudeBot (Anthropic’s crawler help page documents its bots by name)
    Robots.txt Control: User-agent: ClaudeBot

    ClaudeBot is Anthropic’s crawler for collecting training data for the Claude family of AI models. Like GPTBot, ClaudeBot crawls the web to evaluate and potentially collect content for model training. According to Cloudflare data published in January 2026, Googlebot reached 1.70 times more unique URLs than ClaudeBot, placing ClaudeBot as one of the most active AI crawlers on the web in terms of coverage breadth.

    Claude-SearchBot — Anthropic’s Retrieval Crawler

    Operator: Anthropic
    Purpose: Retrieves web content for Claude’s search and citation features
    Robots.txt Control: User-agent: Claude-SearchBot — independently controllable from ClaudeBot

    Claude-SearchBot is Anthropic’s dedicated search retrieval crawler, separate from ClaudeBot. The critical detail for publishers: Claude-SearchBot and ClaudeBot can be controlled independently via robots.txt. This means publishers can allow Claude-SearchBot (enabling their content to appear in Claude’s retrieval and citation features) while disallowing ClaudeBot (keeping content out of training data). This granular control model is unique among major AI companies and represents a publisher-friendly approach to the training-versus-retrieval distinction.

    Other Major AI Crawlers You Should Know

    PerplexityBot

    Operator: Perplexity AI
    Purpose: Indexes content for Perplexity’s answer engine, which provides sourced answers with inline citations
    User Agent String: Contains PerplexityBot identifier
    Robots.txt Control: User-agent: PerplexityBot

    Perplexity operates as an AI-native answer engine that explicitly cites its sources with inline footnotes. PerplexityBot crawls the web to build Perplexity’s index. While smaller in scale than OpenAI’s or Anthropic’s crawlers — Cloudflare data shows Googlebot reaches 167 times more unique URLs than PerplexityBot — Perplexity’s citation-heavy model makes it particularly valuable for publishers who want visible attribution in AI-generated answers.

    Meta-ExternalAgent (Bytespider)

    Operator: Meta Platforms
    Purpose: Collects content for Meta’s AI products including Meta AI (powered by Llama models)
    User Agent String: Contains meta-externalagent identifier
    Robots.txt Control: User-agent: meta-externalagent

    Meta-ExternalAgent is Meta’s web crawler for AI content collection, supporting Meta’s Llama model family and Meta AI assistant products integrated across Facebook, Instagram, WhatsApp, and Messenger. According to Cloudflare data from January 2026, Googlebot reached 2.99 times more unique URLs than Meta-ExternalAgent, placing it as a significant but secondary crawler compared to OpenAI and Anthropic’s agents. The Bytespider crawler, associated with ByteDance (TikTok’s parent company), serves a similar training data collection function for ByteDance’s AI models.

    Google’s AI Crawlers

    Operator: Google
    Key User Agents: Google-Extended, Googlebot, Google-CloudVertexBot
    Robots.txt Control: User-agent: Google-Extended (for AI training opt-out)

    Google’s approach to AI crawling is unique because it leverages the existing Googlebot infrastructure rather than deploying entirely separate AI-specific crawlers. Googlebot serves double duty — indexing content for Google Search and providing the foundation for Google AI Overviews. Google-Extended is the opt-out mechanism: blocking Google-Extended prevents your content from being used for Gemini model training while still allowing Googlebot to index your content for search. Google-CloudVertexBot handles content retrieval for Google’s Vertex AI enterprise products.

    Notably, Google also operates specialized agents including Google-NotebookLM (for the NotebookLM product) and Google-Read-Aloud (for text-to-speech features), each controllable independently via robots.txt.

    Other Notable AI Crawlers

    Amazonbot: Amazon’s web crawler supporting Alexa and other Amazon AI products. User agent contains Amazonbot.
    Applebot: Apple’s crawler for Siri, Spotlight, and Apple Intelligence features. User agent contains Applebot.
    DuckAssistBot: DuckDuckGo’s AI assistant crawler for DuckAssist answers. User agent contains DuckAssistBot.
    CCBot: Common Crawl’s crawler, which produces the open dataset used by many AI companies for model training. Cloudflare data shows Googlebot reaches 714 times more unique URLs than CCBot.

    The AI Crawler Hierarchy: A Functional Classification

    Understanding the AI crawler landscape requires organizing these crawlers into functional tiers based on what their activity means for publishers:

    Tier 1: Real-Time Query Crawlers. ChatGPT-User and similar user-triggered crawlers. Every hit represents a real user’s question being answered right now. These are the highest-value signals because they indicate your content is actively being used to generate AI answers. In our experiment, ChatGPT-User was the dominant Tier 1 crawler with 3,404 hits (Tygart Media server log analysis, June 2026).

    Tier 2: Search Index Crawlers. OAI-SearchBot, Bingbot (for Copilot), Claude-SearchBot, PerplexityBot. These crawlers build the search indexes that AI systems query when answering questions. Activity from Tier 2 crawlers indicates your content is being indexed for potential citation. Bingbot’s consistent 4-hour IndexNow response made it our most reliable Tier 2 crawler.

    Tier 3: Training and Evaluation Crawlers. GPTBot, ClaudeBot, Meta-ExternalAgent, Google-Extended. These crawlers collect content for model training and evaluation. High activity from Tier 3 crawlers means your content is being considered for inclusion in training datasets. GPTBot’s 1,123-request burst crawl at 11:00 UTC exemplified Tier 3 behavior — systematic, comprehensive, evaluative (Tygart Media server log analysis, June 2026).

    Tier 4: Specialized and Emerging Crawlers. AzureAI-SearchBot, Google-NotebookLM, DuckAssistBot, Amazonbot. Lower volume, more targeted, often serving specific product use cases. Our observation of only 3 AzureAI-SearchBot hits suggests Tier 4 crawlers are highly selective (Tygart Media server log analysis, June 2026).

    How to Identify AI Crawlers in Your Server Logs

    Most publishers have never looked at their server logs for AI crawler activity because traditional analytics tools (Google Analytics, Adobe Analytics) do not capture bot traffic. To see AI crawlers, you need access to raw server logs — typically access.log or combined.log files on Apache or Nginx servers.

    The simplest approach is to grep your logs for known AI user agent strings. Here are the key strings to search for, based on our verified server log data and official documentation from each operator (for example, OpenAI, Anthropic, and Google):

    GPTBot — OpenAI training crawler
    ChatGPT-User — OpenAI live query crawler
    OAI-SearchBot — OpenAI search index crawler
    bingbot — Microsoft search and Copilot crawler
    AzureAI-SearchBot — Microsoft specialized AI crawler
    ClaudeBot — Anthropic training crawler
    Claude-SearchBot — Anthropic retrieval crawler
    PerplexityBot — Perplexity answer engine crawler
    meta-externalagent — Meta AI crawler
    Google-Extended — Google AI training crawler
    Amazonbot — Amazon AI crawler
    Applebot — Apple AI crawler
    Bytespider — ByteDance AI crawler
    DuckAssistBot — DuckDuckGo AI assistant crawler
    CCBot — Common Crawl open dataset crawler

    What AI Crawler Activity Tells You About Your Content

    Different patterns of AI crawler activity reveal different things about how AI systems perceive your content:

    High ChatGPT-User volume: Your content is actively being used to answer real user queries. This is the strongest signal that your content is being cited by AI systems. Our 3,404 ChatGPT-User hits across the Copilot cluster confirmed that our content was being pulled into live answers (Tygart Media server log analysis, June 2026).

    GPTBot burst crawling: OpenAI’s systems have identified your domain as a potential authority source and are performing a deep evaluation. The 1,123-request burst we observed is characteristic of GPTBot’s domain evaluation pattern — it does not crawl this aggressively unless it has identified the domain as potentially high-value content (Tygart Media server log analysis, June 2026).

    Consistent Bingbot visits via IndexNow: Your IndexNow implementation is working, and your content is being indexed for Copilot citation. The 4-hour gap pattern we observed is your feedback loop — if Bingbot is arriving within hours of publication, your indexing pipeline is healthy.

    Low or zero AI crawler activity: Your content may be blocked by robots.txt, your server may be rejecting crawler requests, or your content may not be reaching the quality or topical relevance threshold for AI system evaluation. Check your robots.txt and server response codes for AI user agents.

    Managing AI Crawlers: Allow, Block, or Selective Access

    Publishers face a three-way decision for each AI crawler: allow full access (content can be used for training and retrieval), allow selective access (retrieval only, no training), or block entirely. The most nuanced approach — and the one we recommend — is selective access that allows retrieval crawlers while blocking training crawlers.

    Anthropic’s model is the most publisher-friendly in this regard: ClaudeBot (training) and Claude-SearchBot (retrieval) are independently controllable. OpenAI offers similar granularity: you can block GPTBot (training) while allowing ChatGPT-User (retrieval) and OAI-SearchBot (search indexing). Google allows blocking Google-Extended (training) while keeping Googlebot active for search.

    The practical implication: a robots.txt configuration that blocks training crawlers while allowing retrieval crawlers ensures your content is available for AI citation without contributing to model training datasets. This is the optimal configuration for most publishers who want to be cited by AI systems while maintaining control over their content’s use in training.

    Frequently Asked Questions

    What is the difference between GPTBot and ChatGPT-User?

    GPTBot is OpenAI’s training data crawler — it collects content that may be used to train and improve OpenAI’s foundation models. ChatGPT-User is a live query crawler that fetches web pages on demand when a real user asks ChatGPT a question. Every ChatGPT-User hit represents an actual user query being answered. They serve completely different purposes and can be controlled independently via robots.txt. In our server logs, ChatGPT-User generated 3,404 hits representing real user queries, while GPTBot performed a 1,123-request structural evaluation crawl (Tygart Media server log analysis, June 2026).

    How many AI crawlers are actively crawling the web in 2026?

    There are at least 15 major AI crawlers actively operating as of mid-2026, operated by OpenAI (GPTBot, ChatGPT-User, OAI-SearchBot), Microsoft (Bingbot, AzureAI-SearchBot), Anthropic (ClaudeBot, Claude-SearchBot), Google (Google-Extended, Google-CloudVertexBot, Google-NotebookLM), Meta (meta-externalagent), Perplexity (PerplexityBot), Amazon (Amazonbot), Apple (Applebot), ByteDance (Bytespider), DuckDuckGo (DuckAssistBot), and Common Crawl (CCBot). Cloudflare reported AI crawlers generating more than 50 billion requests per day to its network in 2025.

    Can I allow AI citation while blocking AI training on my content?

    Yes. Most major AI companies now separate their training crawlers from their retrieval crawlers, allowing publishers to control each independently via robots.txt. Block GPTBot and ClaudeBot (training) while allowing ChatGPT-User, OAI-SearchBot, and Claude-SearchBot (retrieval and citation). For Google, block Google-Extended while keeping Googlebot active. This configuration ensures your content can be cited in AI answers without being used to train models.

    Why don’t Google Analytics or similar tools show AI crawler traffic?

    Google Analytics and similar web analytics tools rely on JavaScript execution in a browser to record visits. AI crawlers do not execute JavaScript — they fetch the raw HTML of your page and process it server-side. This means AI crawler visits are completely invisible to any JavaScript-based analytics tool. The only way to see AI crawler activity is through server logs (access.log or combined.log files on Apache or Nginx), which record every HTTP request including those from bots and crawlers.

    What does a ChatGPT-User hit mean for my content strategy?

    A ChatGPT-User hit means a real person asked ChatGPT a question, and ChatGPT fetched your page to help generate the answer. This is the direct AI equivalent of a user clicking on your search result — except the AI is doing the retrieval. High ChatGPT-User volume on specific pages indicates those pages are being actively used as citation sources for live user queries. This is the strongest signal that your content is performing well in the AI search ecosystem and should be prioritized for updates, expansion, and optimization.

    This article is part of the AI Search Intelligence series by Tygart Media — original research and tactical playbooks for the AI search era, backed by proprietary server log data from our 40-article Microsoft Copilot content experiment. Related reading: How to Get Cited by Microsoft Copilot in 24 Hours | Microsoft Copilot Pricing Compared | The Complete M365 Copilot Productivity Guide

  • How to Get Cited by Microsoft Copilot in 24 Hours (2026)

    Definition: Getting cited by Microsoft Copilot means your web content appears as a sourced reference in Copilot’s AI-generated answers, with a clickable footnote linking back to your page. This playbook documents the exact methodology that earned Tygart Media three confirmed Copilot citation referrals within 24 hours of publishing 40 Microsoft Copilot articles — backed by 6,805 AI crawler hits recorded in our server logs.

    Most content marketers treat AI search as a black box. They publish, wait, and hope an AI decides to cite them. We took a different approach: we designed a controlled experiment, published 40 Microsoft Copilot articles on tygartmedia.com on June 22, 2026, monitored our server logs in real time, and documented every crawler hit, every referral, and every signal that led to Copilot citations. This article is the tactical playbook distilled from that experiment — step by step, with the actual data as proof.

    The Experiment That Proved 24-Hour Copilot Citation Is Possible

    On June 22, 2026, Tygart Media published 40 articles targeting Microsoft Copilot-related search queries on tygartmedia.com. Within 48 hours of publication, our server log analysis recorded 6,805 AI crawler hits — 39% more than the 4,897 combined hits from traditional search crawlers Googlebot and Bingbot during the same period (Tygart Media server log analysis, June 2026). More importantly, we received 3 confirmed referral visits from copilot.microsoft.com, with 2 of those carrying the utm_source=copilot.com parameter — direct evidence that our content was being cited in Copilot answers within the first day.

    This was not luck. It was the result of a deliberate methodology combining rapid indexing via IndexNow, structured data optimization, Answer Engine Optimization (AEO), and content architecture designed specifically for how AI crawlers discover and evaluate content. Here is exactly how we did it.

    Step 1: Trigger Immediate Indexing With IndexNow

    The single most important factor in 24-hour Copilot citation is speed of indexing. Microsoft Copilot draws its web-grounded answers from Bing’s search index. If your content is not in Bing’s index, Copilot cannot cite it — period. This is where IndexNow becomes your most critical tool.

    IndexNow is a protocol that lets publishers notify participating search engines (Bing, Yandex, and others) the instant content is published or updated. Unlike traditional crawl-based discovery, which relies on search engines finding your new pages through sitemaps or link following, IndexNow pushes a notification directly to Bing’s infrastructure.

    In our experiment, we observed a consistent pattern: Bingbot was the first crawler to reach every single one of our 40 Copilot articles, arriving with a predictable 4-hour post-publish gap triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This speed advantage is what made 24-hour citation possible. Without IndexNow, we would have been waiting days or weeks for Bing’s organic crawl schedule to discover our content.

    How to Implement IndexNow for Your WordPress Site

    For WordPress sites, implementing IndexNow takes less than 10 minutes. Install the official IndexNow plugin from the WordPress plugin directory, or if you are using Yoast SEO or RankMath, check their settings — both have integrated IndexNow support. Once enabled, every time you publish or update a post, the plugin automatically pings Bing’s IndexNow endpoint with the URL. Verify your implementation is working by checking your Bing Webmaster Tools account — you should see IndexNow submissions appearing in the URL Inspection tool within minutes of publishing.

    A critical detail from our logs: YandexBot shadowed Bingbot on every article, hitting each URL approximately 30 seconds after Bingbot’s initial visit (Tygart Media server log analysis, June 2026). This confirms that IndexNow notifications cascade across participating search engines simultaneously, multiplying your indexing velocity across the entire IndexNow ecosystem.

    Step 2: Structure Content for AI Comprehension With Schema Markup

    Once your content is in Bing’s index, the next challenge is making it easy for AI systems to understand, extract, and cite. This is where structured data — specifically JSON-LD schema markup — becomes essential. Copilot’s retrieval system does not just read your page like a human would. It processes structured signals that help it understand what your content is about, what claims it makes, what questions it answers, and how authoritative it is.

    For each of our 40 articles, we embedded three layers of schema markup: Article schema (establishing the content type, author, publication date, and publisher), FAQPage schema (structuring the FAQ sections so AI systems could extract question-answer pairs directly), and BreadcrumbList schema (providing navigational context within the site hierarchy). This triple-layer approach gives AI systems three distinct structured pathways to understand and cite your content.

    The Schema Stack That Works for Copilot

    Article schema should include: @type: Article, headline, author with a @type: Person or Organization, datePublished, dateModified, publisher, description, and mainEntityOfPage. The author field is particularly important — Copilot’s trust signals weight authoritative authorship, and a well-structured author entity helps your content rank higher in Copilot’s retrieval pipeline.

    FAQPage schema should wrap every FAQ section in your article. Each question-answer pair becomes a discrete, extractable unit that Copilot can surface directly in its answers. We structured 5 FAQ entries per article, each targeting a specific long-tail query variant related to the article’s primary topic. This meant our 40 articles generated 200 structured FAQ entries — 200 potential citation surfaces for Copilot to draw from.

    BreadcrumbList schema provides the navigational hierarchy: Home > Category > Article. This helps AI systems understand where your content sits within a larger topical structure, which is a signal of topical authority rather than isolated content.

    Step 3: Optimize for Answer Engine Extraction (AEO)

    Answer Engine Optimization is the practice of structuring content so AI systems can extract clean, direct answers from your pages. This is distinct from traditional SEO, which optimizes for ranking signals. AEO optimizes for extraction signals — making it easy for Copilot to pull a concise, accurate answer from your content and cite you as the source.

    The AEO Techniques We Used on Every Article

    Definition boxes near the top of each article. Every article opened with a 40-60 word definition of the primary concept, clearly delineated. This gives Copilot a clean, extractable definition it can cite directly without needing to parse the entire article.

    Question-formatted H2 headings with immediate answers. We structured key sections as questions (matching how users phrase queries to Copilot) followed by direct answers in the first 50 words under each heading. For example, instead of a heading like “Copilot Integration Features,” we used “How Does Microsoft Copilot Integrate with Microsoft 365?” followed by a direct, concise answer before expanding into detail.

    Comparison tables for competitive queries. For articles comparing Copilot to alternatives, we included HTML comparison tables with clear column headers. Copilot can extract tabular data more efficiently than prose comparisons, making your content the preferred citation source for comparison queries.

    Numbered step-by-step instructions. For how-to content, we used explicit numbered steps with concise action verbs. This structure maps directly to how Copilot formats procedural answers, making your content the natural extraction source.

    Step 4: Build Topical Authority With Content Clusters

    A single article can earn a citation. A content cluster makes citations systematic. Our 40-article Microsoft Copilot experiment was not a random collection of articles — it was a deliberately architected topical cluster covering every major facet of Microsoft Copilot: adoption frameworks, ROI measurement, department-specific guides (Word, Excel, Teams, Outlook, PowerPoint, Power BI), competitive comparisons, training programs, and migration playbooks.

    This cluster architecture serves two purposes for Copilot citation. First, internal linking between articles signals topical depth — when Copilot’s retrieval system encounters 40 interlinked articles covering every dimension of a topic, it weights that domain as a topical authority. Second, the cluster provides multiple entry points for citation. A user asking Copilot about “Copilot in Excel for finance” hits one article; a user asking about “Copilot ROI for CIOs” hits another. Both queries return to your domain.

    Our server logs confirmed this cluster effect. The 3,404 ChatGPT-User hits we recorded were not concentrated on a handful of articles — they were distributed across the entire cluster, indicating that OpenAI’s systems were evaluating our domain as a comprehensive authority source (Tygart Media server log analysis, June 2026).

    Step 5: Maximize Entity Signals for Generative Engine Optimization (GEO)

    Generative Engine Optimization goes beyond AEO by focusing on entity density and factual specificity — the signals that make AI systems treat your content as a citable authority rather than generic information. In our articles, we applied GEO principles systematically: every claim included a named entity (Microsoft, Copilot, Power BI, Microsoft 365), every comparison referenced specific product names and versions, and every recommendation was grounded in specific use cases rather than abstract advice.

    Entity-rich content is citation-friendly content. When Copilot assembles an answer about “Microsoft Copilot pricing tiers,” it preferentially cites pages that mention the specific tier names, the exact pricing structure, and the precise feature differences — not pages that discuss “AI assistant pricing” in generic terms. Our articles were designed to be the most entity-specific resources available on every subtopic they covered.

    Step 6: Monitor and Iterate Using Server Log Intelligence

    The final step in this playbook is not a one-time action — it is an ongoing intelligence loop. Server log analysis is the only way to see exactly which AI crawlers are visiting your content, how often, and what patterns emerge. Traditional analytics tools like Google Analytics do not capture crawler traffic — they only see human visitors. Server logs see everything.

    In our experiment, server log analysis revealed insights that no analytics tool could have provided. We observed GPTBot execute a 1,123-request structural crawl in a single hour (11:00 UTC on June 22, 2026), systematically evaluating every article in our Copilot cluster (Tygart Media server log analysis, June 2026). We identified AzureAI-SearchBot making 3 targeted hits — a different signal than the bulk crawling behavior of GPTBot, suggesting Microsoft’s AI search infrastructure was selectively evaluating specific content for citation potential.

    We also observed that Googlebot was dramatically slower to respond than Bingbot. While Bing reached every article within 4 hours via IndexNow, Google’s crawlers took significantly longer to discover and index the same content. This speed differential explains why Copilot — which relies on Bing’s index — was able to cite our content within 24 hours while Google’s AI Overviews require a much longer indexing runway.

    The Complete 24-Hour Copilot Citation Checklist

    Here is the consolidated checklist, in the exact order of execution:

    1. Enable IndexNow on your WordPress site via plugin or SEO tool integration. Verify submissions appear in Bing Webmaster Tools.
    2. Write content using question-formatted H2s that match how users phrase queries to AI assistants. Provide direct answers in the first 50 words under each heading.
    3. Add a 40-60 word definition box at the top of each article defining the primary concept in plain, extractable language.
    4. Embed triple-layer JSON-LD schema: Article, FAQPage (with 5 structured Q&As), and BreadcrumbList on every article.
    5. Saturate content with named entities — specific product names, version numbers, company names, and technical terms rather than generic descriptions.
    6. Build internal links between all articles in the cluster. Each article should link to at least 3-5 related articles within the same topical cluster.
    7. Publish and verify indexing. Check Bing Webmaster Tools within 4 hours. Your IndexNow ping should have triggered Bingbot to crawl the new page.
    8. Monitor server logs for ChatGPT-User, GPTBot, OAI-SearchBot, and Bingbot activity. These are the crawlers whose behavior predicts Copilot citation.
    9. Check for citation referrals in your analytics — look for referral traffic from copilot.microsoft.com, with utm_source=copilot.com in the query string.
    10. Iterate. Update content based on which articles attract the most AI crawler attention. Expand sections that AI systems are actively fetching.

    Why This Works: The Copilot Citation Pipeline Explained

    To understand why this playbook works, you need to understand how Microsoft Copilot’s web-grounded citation pipeline operates. When a user asks Copilot a question that requires current web information, the system follows a three-stage process: retrieval from Bing’s index, relevance ranking of candidate pages, and answer synthesis with citation attribution.

    Stage one — retrieval — is where IndexNow gives you the speed advantage. If your content is in Bing’s index, it enters the candidate pool. If it is not indexed, it is invisible to Copilot regardless of how good the content is.

    Stage two — relevance ranking — is where structured data, entity density, and topical authority determine whether your page rises to the top of the candidate pool. Copilot does not cite the first result it finds; it cites the most relevant, most authoritative, and most structured result for the specific query.

    Stage three — answer synthesis — is where AEO optimization pays off. Copilot’s language model reads your page and extracts the answer. Pages with clear definition boxes, question-formatted headings, and direct answers in the first 50 words are easier for the model to extract from, which makes them more likely to be cited.

    Our experiment proved this pipeline works as described. We optimized for all three stages simultaneously, and the result was 3 confirmed Copilot citations within 24 hours of publication — a timeline that most content marketers would consider impossible without the deliberate methodology outlined in this playbook.

    What the Server Log Data Actually Shows

    The raw numbers from our 48-hour monitoring window tell a compelling story about how AI systems evaluate and select content for citation (all data from Tygart Media server log analysis, June 2026):

    Total AI crawler hits: 6,805. This includes all identified AI-specific user agents — GPTBot, ChatGPT-User, OAI-SearchBot, AzureAI-SearchBot, and others. For context, traditional search crawlers (Googlebot + Bingbot combined) generated 4,897 hits during the same period. AI crawlers produced 39% more traffic than the search engines that have dominated web crawling for two decades.

    ChatGPT-User: 3,404 hits. Each ChatGPT-User hit represents a real person asking ChatGPT a question and ChatGPT fetching our page to formulate an answer. This is not background crawling — this is live query-driven traffic. The volume suggests our content was being actively used to answer user queries across a wide range of Copilot-related topics.

    GPTBot: 1,123-request structural crawl in a single hour. At 11:00 UTC on June 22, GPTBot executed a systematic evaluation of our entire Copilot content cluster. This pattern — a concentrated burst of structural crawling — suggests OpenAI’s systems identified our domain as a potential authority source and performed a deep evaluation to assess the breadth and depth of our coverage.

    Bingbot: first to every article, 4-hour gap. Bingbot consistently arrived at each new article within approximately 4 hours of publication, triggered by our IndexNow implementation. This reliability confirms that IndexNow is not just a faster path to indexing — it is a predictable, repeatable mechanism for getting content into Bing’s index on a known timeline.

    3 confirmed Copilot referrals. Within the first 24 hours, we recorded 3 visits with referral source copilot.microsoft.com, 2 of which carried the utm_source=copilot.com parameter. These are confirmed citations — instances where a user saw our content cited in a Copilot answer and clicked through to our page.

    Common Mistakes That Prevent Copilot Citations

    Based on our experiment and ongoing analysis, here are the most common reasons content fails to earn Copilot citations:

    No IndexNow implementation. Without IndexNow, you are relying on Bing’s organic crawl schedule, which can take days or weeks. Copilot cannot cite content that is not in Bing’s index.

    Missing or incomplete schema markup. Content without structured data is harder for AI systems to parse, understand, and cite. At minimum, every article should have Article schema and FAQPage schema.

    Generic, non-entity-specific content. Articles that discuss topics in generic terms without naming specific products, versions, companies, or technical concepts are less likely to be selected as citation sources by AI retrieval systems.

    Wall-of-text formatting. AI extraction systems perform better with clearly structured content: defined heading hierarchies, short paragraphs, comparison tables, and numbered lists. Dense prose without structural markers is harder to extract from.

    Ignoring server logs. Without server log monitoring, you have no visibility into whether AI crawlers are even visiting your content. You are operating blind — unable to see what is working, what is being ignored, and where to focus optimization efforts.

    Scaling This Playbook Across Your Content Portfolio

    The methodology described here is not limited to Microsoft Copilot content. The same principles — rapid indexing, structured data, AEO optimization, entity density, and content clustering — apply to earning citations from any AI system that uses web retrieval: ChatGPT, Google AI Overviews, Perplexity, and Claude’s web search. The difference is that Copilot’s reliance on Bing’s index makes IndexNow the fastest path, while Google’s AI Overviews require Google’s own indexing pipeline, which is historically slower.

    To scale this approach, apply the same content architecture to every topical cluster on your site. Identify the queries your audience asks AI assistants, write content that directly answers those queries with entity-rich specificity, structure it for extraction with schema markup and AEO formatting, and ensure rapid indexing via IndexNow. Monitor your server logs to confirm AI crawlers are discovering and evaluating your content, and iterate based on what the data tells you.

    Our 40-article experiment was proof of concept. The 6,805 AI crawler hits and 3 confirmed Copilot citations within 24 hours demonstrate that this is not theoretical — it is a repeatable, scalable methodology backed by primary data. The AI search landscape rewards publishers who understand how AI crawlers work and optimize for their specific discovery and evaluation patterns. This playbook gives you the exact steps to do that.

    Frequently Asked Questions

    How long does it take to get cited by Microsoft Copilot after publishing?

    With IndexNow enabled, Bingbot typically discovers new content within 4 hours of publication. From there, Copilot can begin citing indexed content almost immediately. In our experiment, we recorded confirmed Copilot citation referrals from copilot.microsoft.com within 24 hours of publishing 40 optimized articles (Tygart Media server log analysis, June 2026). Without IndexNow, the indexing delay can stretch to days or weeks, pushing the citation timeline out proportionally.

    What is IndexNow and why is it essential for Copilot citation?

    IndexNow is a web protocol that allows publishers to instantly notify participating search engines — including Bing, Yandex, and others — when content is published, updated, or deleted. For Copilot citation, IndexNow is essential because Copilot retrieves answers from Bing’s search index. Content that is not indexed by Bing cannot be cited by Copilot, regardless of its quality. IndexNow eliminates the indexing delay, making 24-hour citation achievable.

    What types of schema markup help with Copilot citations?

    The three most effective schema types for Copilot citation are Article schema (which establishes content type, authorship, and publication metadata), FAQPage schema (which structures question-answer pairs for direct extraction by AI systems), and BreadcrumbList schema (which provides site hierarchy context). Implementing all three creates multiple structured pathways for AI systems to understand, evaluate, and cite your content.

    Can I track whether Microsoft Copilot is citing my content?

    Yes, through two methods. First, monitor your analytics for referral traffic from copilot.microsoft.com — look for the utm_source=copilot.com parameter, which confirms a user clicked through from a Copilot citation. Second, use Bing Webmaster Tools’ AI Performance dashboard, which was launched in public preview in February 2026, to see citation metrics including total citations, grounding queries, and page-level citation activity for your verified domain.

    What is the difference between AEO and GEO for Copilot optimization?

    Answer Engine Optimization (AEO) focuses on making content easy for AI systems to extract — using question-formatted headings, definition boxes, direct answers in the first 50 words, and structured FAQ sections. Generative Engine Optimization (GEO) focuses on making content authoritative enough to be selected for citation — through entity density, factual specificity, named sources, and topical authority signals. Both are necessary for consistent Copilot citations: AEO makes your content extractable, and GEO makes it the preferred source to extract from.

    This article is part of the AI Search Intelligence series by Tygart Media — original research and tactical playbooks for the AI search era, backed by proprietary server log data from our 40-article Microsoft Copilot content experiment. Related reading: Microsoft Copilot Pricing Compared | Copilot for Small Business vs Enterprise | The Complete M365 Copilot Productivity Guide
  • The AI Citation Economy: When Being Cited Is Worth More Than Being Clicked

    The AI Citation Economy: When Being Cited Is Worth More Than Being Clicked

    The Unit of Value Is Changing

    Topic platform fit visual for first-party AI citation measurement
    The unit of value is changing — citations over clicks.

    For twenty-five years, the internet’s content economy ran on one unit of value: the click. A user searches, sees your result, clicks, lands on your page. That click triggers a pageview, which triggers an ad impression, which generates revenue. Or the click starts a funnel: landing page to email capture to nurture sequence to purchase. Every business model, every analytics platform, every marketing strategy was built around the click as the atomic unit of value.

    The click is losing its monopoly.

    When Microsoft Copilot cites my content 98,800 times, those aren’t clicks. No user loads my page. No ad renders. No pixel fires. But 98,800 times, a real person — an enterprise worker making a real decision — receives information sourced from my domain, attributed to my domain, and shaped by my domain’s content. My information enters their document, their email, their analysis. My brand name appears as the citation source.

    That’s a different kind of value than a click. And it might be worth more.

    The Click Economy Was Always a Proxy

    Here’s what we’ve always known but rarely said aloud: clicks were never the actual goal. Clicks were the proxy for something deeper — attention, trust, influence, and eventually, a commercial relationship.

    A click meant someone gave you a moment of attention. But the attention wasn’t guaranteed — bounce rates of 60-80% were normal. A click meant someone might trust you. But trust wasn’t guaranteed — most first-time visitors never return. A click was the entry to a funnel. But the funnel’s conversion rate was typically 1-3%.

    We built an enormous infrastructure around maximizing clicks — SEO, SEM, social media marketing, content marketing — not because clicks were intrinsically valuable, but because they were the best available proxy for the things that actually mattered: reaching the right person, at the right time, with the right information.

    A citation is a better proxy.

    Why Citations Are a Better Signal

    Four-stage funnel: citation, click, engage, convert
    Why citations are a better signal.

    When Copilot cites my Claude pricing guide to an enterprise worker who asked “what is claude ai pricing in 2026,” several things are true about that interaction that are not true about a typical click:

    The user has high intent. They didn’t stumble onto my page from a vague search. They asked a specific question while working on a specific task, and Copilot selected my content as the authoritative answer. The intent signal is stronger than a keyword match.

    The content was consumed. Not skimmed, not bounced from, not opened in a tab and forgotten. Copilot extracted the relevant information and presented it to the user inline. The user received my content’s value whether or not they clicked through to my site.

    The attribution is explicit. Copilot cites the source. My domain name appears alongside the information. This isn’t an anonymous impression — it’s a credited contribution. The user knows where the information came from.

    The context is professional. Copilot users are working. They’re writing reports, making decisions, evaluating tools. My content enters a professional workflow — not a casual browsing session. The context in which my brand appears is inherently higher-value than a typical web pageview.

    Each citation is a moment where my domain provided trusted, authoritative information to a professional decision-maker in a high-intent context. That’s the moment every content marketing strategy is designed to create. The click was just the old way of getting there.

    The Scale Shift

    Here’s the number that reframes everything: 52:1.

    For every human who clicks on my content from Bing search, Copilot cites it 52 times. My content reaches 52x more users through AI citation than through traditional search clicks. And that’s just Copilot — it doesn’t include ChatGPT, Perplexity, Google AI Overviews, or Claude.

    The total AI readership of my content is likely 100x or more the human click volume. And every one of those AI-mediated interactions involves a user who received my information, saw my attribution, and incorporated my content into their work.

    In the click economy, the most successful content might reach tens of thousands of users per month through organic search. In the citation economy, the same content can reach hundreds of thousands through AI platforms — users who are higher-intent, more engaged with the content (because it was extracted and presented directly to them), and consuming it in a professional context.

    The scale of the opportunity is an order of magnitude larger than clicks. The remaining question is how to capture the value.

    The Monetization Frontier

    Two cards: answer shown in overview versus optional click
    The monetization frontier of the citation economy.

    This is where honesty matters. The citation economy’s monetization model is not fully developed. I can tell you what works, what’s emerging, and what doesn’t work yet.

    What works now: brand authority compounding. When Copilot cites your domain thousands of times, you become the recognized source for that topic among enterprise professionals. This translates to consulting inquiries, partnership opportunities, speaking invitations, and inbound business development. The citation builds the brand, and the brand generates revenue through traditional channels. This is measurable but indirect.

    What works now: citation flywheel to search authority. The signals that earn AI citations — content quality, structural clarity, topical authority — also improve traditional search performance. My domain’s growing Copilot authority appears to correlate with improved Google organic performance. The citation strategy feeds the click strategy, creating a compound effect.

    What’s emerging: AI-mediated traffic. Some Copilot and ChatGPT citations include clickable source links. A percentage of users do click through. This traffic is small compared to citation volume but high-quality — the user has already seen a preview of your content through the AI response and is choosing to visit for more. The conversion potential of this traffic is likely higher than typical organic traffic, though the data is still too early for definitive benchmarks.

    What doesn’t work yet: direct citation monetization. There is no ad network for AI citations. There is no affiliate revenue from AI-mediated content consumption. There is no way to place a conversion pixel inside a Copilot response. The infrastructure for monetizing citations the way we monetize clicks does not exist.

    This is the frontier. The value is clear — massive reach to high-intent professional audiences — but the capture mechanism is still developing. The businesses that figure out how to convert citation authority into revenue will define the next era of content economics.

    The Attention Redistribution

    What’s happening with AI citations is part of a larger pattern: attention is being redistributed from concentrated channels (Google, social media feeds) to distributed AI interfaces (Copilot in Office, ChatGPT conversations, Perplexity answers, AI Overviews in search).

    In the old model, Google was the gatekeeper. All attention flowed through one discovery interface. Publishers optimized for one algorithm, one set of ranking factors, one measurement system. The entire content economy was organized around Google’s distribution infrastructure.

    In the new model, attention is fragmented across multiple AI interfaces. A professional might encounter your content through Copilot while writing, ChatGPT while researching, Perplexity while fact-checking, and Google while searching — all in the same day, for different purposes, through different content presentations.

    This fragmentation is uncomfortable for publishers who built their operations around a single distribution channel. But it’s also an opportunity. In a fragmented attention landscape, the publisher who shows up across multiple AI platforms has an outsized advantage over the publisher who only shows up on Google.

    My 98,800 Copilot citations represent a position in one AI platform’s distribution. If I can build comparable positions in ChatGPT, Perplexity, and Google AI Overviews, the total citation footprint would represent content distribution at a scale that was previously only achievable through paid advertising at significant cost.

    What the Citation Economy Demands

    The transition from click economy to citation economy changes what content operations need to prioritize:

    Accuracy over engagement. In the click economy, content needed to be engaging enough to prevent bounces and drive conversions. In the citation economy, content needs to be accurate enough that AI engines trust it as a grounding source. Engagement still matters for human readers, but accuracy is the threshold for AI citation eligibility.

    Structure over narrative. AI engines extract structured information more effectively than narrative prose. The citation economy rewards clean data tables, explicit definitions, numbered procedures, and organized comparison frameworks. This doesn’t mean narrative disappears — it means structure shares equal billing.

    Currency over permanence. In the click economy, evergreen content could generate traffic for years without updates. In the citation economy, stale content loses citations as AI engines detect outdated information. Maintaining existing content becomes as important as producing new content.

    Platform-specific optimization over universal optimization. The click economy had one optimization target: Google. The citation economy has multiple: Copilot, ChatGPT, Perplexity, AI Overviews, and whatever comes next. Each platform has different preferences, different user bases, and different citation behaviors.

    Authority over volume. In the click economy, more content meant more keyword targets, more landing pages, more chances to rank. In the citation economy, authority on a topic matters more than volume of content about it. One comprehensive, authoritative, regularly-updated pricing guide earns more citations than ten thin pricing articles.

    The First Mover Advantage Is Real

    My citation flywheel — from 672 daily citations to 5,500 in 90 days — demonstrates that AI citation authority compounds. The domain that establishes itself as the trusted source for a topic early builds a moat that later entrants have to overcome.

    This is different from SEO, where a new article can outrank an established one by being better optimized. In AI citations, the trust relationship appears to be stickier. Copilot doesn’t just evaluate individual pages — it appears to develop domain-level trust for topic clusters. Once your domain is the trusted source for “AI tool pricing,” new articles on related topics benefit from that established trust.

    The businesses building citation authority now are building a compounding asset. The businesses waiting for the measurement tools to mature are falling behind a curve they won’t be able to see until it’s too late.

    Where This Goes

    The AI citation economy is in its first inning. The measurement tools are primitive. The monetization models are nascent. The strategic frameworks are just being articulated. But the underlying behavior — AI engines consuming, citing, and distributing web content at massive scale — is already established and accelerating.

    I believe that within two to three years, AI citations will be as standard a metric as organic traffic. Webmaster tools across all major platforms will expose citation data. Content operations will track citation volume by platform alongside traditional SEO metrics. And the strategic approach of Platform-Specific AI Optimization will be as mainstream as SEO is today.

    The question for content operators right now isn’t whether this shift is happening — the data already confirms it is. The question is whether you’re going to measure it, optimize for it, and build citation authority while the category is still open — or wait until everyone else has already established their positions.

    I’m publishing my data, naming the category, and building the playbook in real time. The AI citation economy is here. It rewards different content, different strategies, and different metrics than the click economy it’s supplementing. And the first people to take it seriously will define how everyone else thinks about it.

    Related on Tygart Media: AI search funnel · $0.35 article citations · how AI engines cite.

    Frequently Asked Questions

    Will AI citations replace clicks entirely?

    No. Clicks will remain important for direct conversion, ad revenue, and controlled user experiences. AI citations supplement clicks by providing massive reach and brand authority through a different channel. The most effective content strategies will optimize for both.

    How do I monetize AI citations?

    Currently through indirect channels: brand authority that drives consulting and partnerships, the citation flywheel that improves traditional search performance, and AI-mediated referral traffic from users who click through from citation links. Direct citation monetization infrastructure doesn’t exist yet.

    What is the AI citation flywheel?

    A compounding effect where earning citations builds domain trust, which makes new content eligible for more citations, which builds more trust. On one domain, this grew daily Copilot citations from 672 to 5,500 in 90 days without changes to content volume or strategy.

    Is there a first-mover advantage in AI citations?

    Yes. AI citation authority appears to compound over time. Domains that establish trust as citation sources for specific topic clusters benefit from preferential selection for new and adjacent queries. Building this authority early creates a moat that later entrants must overcome.

    When will AI citation data become widely available?

    Bing Webmaster Tools AI Performance is already available in beta. Google and other platforms are expected to follow as publisher demand for citation transparency grows. The most likely timeline for broad availability of citation analytics across major platforms is 12-24 months.

  • I Write for Copilot Users During the Day and Google Users at Night — On the Same Website

    I Write for Copilot Users During the Day and Google Users at Night — On the Same Website

    Two Audiences, One Domain

    My site tygartmedia.com has a split personality, and it’s deliberate.

    During business hours, Microsoft Copilot users inside Word, Edge, and Outlook are citing my Claude AI pricing guides, my developer tool comparisons, and my MCP integration documentation. These enterprise workers are pulling structured data from my articles to inform their purchasing decisions, technical evaluations, and strategy documents. They generate 5,500 citations per day and climbing.

    After hours and on weekends, Google searchers in Tacoma, Washington are finding my local content — neighborhood guides, restaurant directories, school district analysis, civic resource pages. These community members are looking for practical local information, and they find it through organic search. They generate consistent organic traffic with strong engagement metrics.

    Same domain. Same WordPress installation. Two completely different content strategies running simultaneously, serving two completely different audiences through two completely different discovery channels.

    This isn’t an accident. It’s the logical outcome of Platform-Specific AI Optimization (PSAO) applied to a real content operation. And it works better than either strategy would work alone.

    How the Split Happened

    It started organically. I publish content about AI tools because I use them extensively to run my business — a portfolio of WordPress sites across multiple verticals. The articles I wrote about Claude, Copilot, content pipelines, and MCP integrations were notes from my own workflow, published because they might help others.

    Separately, I publish local Tacoma content because that’s where I live and operate. Neighborhood guides, business spotlights, civic explainers — the kind of community journalism that serves local Google searchers.

    The AI tool content started earning Copilot citations before I even knew what Copilot citations were. When I discovered the Bing Webmaster Tools AI Performance tab and saw 98,800 citations, I realized the AI content was reaching an entirely different audience through an entirely different channel — one I wasn’t optimizing for.

    That’s when the split became intentional. Instead of hoping one content strategy would serve all audiences, I started building two parallel strategies on the same domain.

    The Copilot-Facing Content Strategy

    The AI tool content is engineered for a specific reader: an enterprise knowledge worker who is in the middle of a task inside Microsoft 365 and invokes Copilot for help. This person needs:

    Current, specific data. Not “Claude has several pricing tiers” but “Claude Sonnet 4.6 (legacy — still listed) costs $3.00 per million input tokens and $15.00 per million output tokens on the API.” The specificity matters because this person is putting numbers in a spreadsheet or a procurement document.

    Structured presentation. HTML tables, not paragraphs. Comparison matrices, not narrative descriptions. Numbered steps, not suggested approaches. Copilot extracts structured data more effectively than it extracts narrative information.

    Comprehensive coverage. The articles that earn the most citations answer the question completely. My Claude pricing guide doesn’t just list prices — it covers every plan tier, every model, API rates, token costs, comparison to competitors, and practical use case guidance. Copilot prefers to ground on a single comprehensive source rather than synthesizing from multiple partial sources.

    Timeliness. Prices change. Models update. Features launch. The AI tool content requires regular maintenance — sometimes weekly updates — to remain the most current source. This is non-negotiable because Copilot’s grounding algorithm appears to factor currency into source selection.

    Publication cadence for this content: new articles when significant tools or updates launch, plus continuous updates to existing articles. The update cycle is more important than the publication cycle.

    The Google-Facing Content Strategy

    The local Tacoma content is built for a different reader: a community member who types a query into Google and wants a useful, comprehensive local resource.

    Local keyword optimization. “Tacoma farmers markets 2026,” “Pierce County property tax lookup,” “Point Defiance Zoo hours and tickets.” These are traditional SEO targets with clear local intent.

    Community depth. The articles that perform best aren’t thin SEO pages — they’re comprehensive community resources that cover a topic completely. My Tacoma real estate directory doesn’t just list agents — it covers the licensing verification process, typical commission structures, property management options, and attorney resources.

    Evergreen structure with timely updates. A farmers market guide works year after year with seasonal date updates. A schools explainer holds its value with annual enrollment data refreshes. The initial investment in a comprehensive local article pays dividends for years through sustained organic traffic.

    FAQ schema and local business schema. Google rewards structured data for local content. Every major local article gets FAQPage schema and relevant local business markup. This isn’t about AI citations — it’s about winning featured snippets and People Also Ask positions in Google’s local results.

    Publication cadence for this content: major local articles as topics emerge, plus a civic beat that covers government, schools, transit, and development news. The traffic pattern is steady and predictable.

    Why They Work Better Together

    Running both strategies on the same domain creates advantages that neither would have alone:

    Domain authority compounds across both strategies. The AI content earns 98,800 Copilot citations, which signals to Bing (and likely Google) that the domain is authoritative. The local content earns organic backlinks from community organizations and local media. Each strategy builds domain authority that benefits the other.

    The content diversity strengthens the domain profile. A domain that publishes only AI tool guides looks niche. A domain that publishes AI guides alongside community journalism looks like a comprehensive media property. Search engines and AI engines both appear to trust topically diverse domains more than single-topic sites, as long as each topic area is covered with genuine depth.

    The revenue model is more resilient. Local content generates ad revenue through traffic. AI content generates brand authority and consulting opportunities. Community content builds local business relationships. Neither audience alone would sustain the operation — together, they create a diversified content business.

    Each audience discovers the other’s content occasionally. A Tacoma tech worker who finds my site through a Copilot citation might browse the local content. A local reader who discovers a neighborhood guide might notice the AI strategy articles. Cross-pollination happens naturally, and it creates a more engaged audience overall.

    The Operational Reality

    Running dual content strategies isn’t twice the work — it’s about 1.3x the work of a single strategy. Here’s why:

    The publishing infrastructure is shared. One WordPress installation, one design system, one content pipeline, one analytics setup. The operational overhead of managing a website is fixed regardless of how many content strategies you run on it.

    The skill set is shared. Writing, editing, SEO optimization, schema implementation, quality control — these processes apply to both content streams. The strategic thinking differs, but the execution uses the same tools and workflows.

    The cadence is naturally staggered. AI tool content publishes when tools update or new products launch — which happens irregularly. Local content publishes on a civic beat tied to meeting schedules, seasonal events, and community news. The two streams rarely compete for production time because their triggers are different.

    The biggest operational challenge is context switching. Writing a detailed Claude pricing comparison requires a different mindset than writing a Tacoma neighborhood guide. I’ve learned to batch by content type — AI content mornings, local content afternoons — rather than switching between them throughout the day.

    What the Data Shows

    After several months of running dual strategies intentionally:

    AI content metrics: 98,800 Copilot citations total, 5,500 daily (growing), 576 grounding queries. Top article: 16,500 citations for “claude ai pricing.” Zero citations for any local content. AI content drives consulting inquiries and brand authority in the AI/content strategy space.

    Local content metrics: Consistent organic traffic from Google, strong engagement rates, low bounce rates. Featured snippets for multiple local queries. Zero Copilot citations (as expected). Local content drives ad revenue and community visibility in Pierce County.

    Domain-level metrics: Growing overall domain authority. Bing shows strong performance in both traditional search and AI citations. Google shows solid organic performance for local content. The domain is recognized as authoritative in two distinct topic areas.

    The dual strategy doesn’t cannibalize — it compounds. The AI audience and the local audience don’t overlap, so they’re not competing for the same attention. They’re building the same domain’s authority through completely different channels.

    The Replicable Pattern

    This dual-audience approach works because it follows a principle: match content to the platform where its audience lives.

    The AI tool audience lives in Copilot. Build structured, reference-grade content for them.

    The local audience lives in Google. Build comprehensive, SEO-optimized community resources for them.

    The same principle applies to any domain that could serve multiple audiences through multiple platforms. A SaaS company could publish product documentation for Copilot citations and thought leadership for ChatGPT conversations. A consulting firm could publish methodology guides for AI platforms and case studies for Google organic. A media company could publish data journalism for AI engines and breaking news for social platforms.

    The dual-audience model isn’t limited to my specific combination. It’s a framework for any content operation willing to recognize that different platforms serve different audiences — and build accordingly.

    Related on Tygart Media: different AI audiences · SEO vs GEO vs AEO · Bing Webmaster AI tab.

    Frequently Asked Questions

    Does publishing diverse content hurt SEO focus?

    Not if each topic area is covered with genuine depth. A domain with deep AI content and deep local content is recognized as authoritative in both areas. Topical diversity with depth in each area strengthens domain authority rather than diluting it.

    How do you manage two content calendars?

    The calendars are naturally staggered. AI content publishes when tools update. Local content follows civic beats and seasonal events. Batch by content type rather than switching throughout the day. The shared infrastructure means operational overhead is minimal.

    Does the AI content cannibalize the local content’s traffic?

    No. The audiences don’t overlap. Enterprise Copilot users asking about Claude pricing never compete for attention with Tacoma residents searching for farmers markets. The two content streams serve completely different audiences through different channels.

    Can this work on a smaller domain?

    Yes. The principle scales down. A small business could publish product documentation optimized for AI citations and local content optimized for Google search. The key is matching content to platform audience rather than writing one generic version and hoping it works everywhere.

    Which strategy should I start with?

    Start with whichever matches your existing audience. If you already have Google traffic, add AI-citation-optimized content as a second stream. If you already produce technical content, check Bing AI Performance to see if you’re earning citations you don’t know about, then optimize from there.

  • Bing Webmaster Tools Has an AI Tab Nobody Is Using — Here’s What It Shows

    Bing Webmaster Tools Has an AI Tab Nobody Is Using — Here’s What It Shows

    The Best-Kept Secret in Search Marketing

    Topic platform fit visual for first-party AI citation measurement
    Bing Webmaster AI tab — the best-kept secret.

    Microsoft shipped one of the most significant measurement tools in content marketing history, and the industry collectively shrugged. Sometime in late 2025, an “AI Performance” tab appeared in Bing Webmaster Tools. No announcement. No blog post. No conference keynote. It just showed up in the sidebar, labeled “(beta),” waiting for someone to notice.

    I noticed. And what I found inside was the first real dataset on AI citation behavior that any search engine has ever exposed to publishers. The tab shows exactly how many times Microsoft Copilot cites your content, which queries triggered those citations, and how the volume trends over time.

    For my domain, that data showed 98,800 AI citations across 576 grounding queries — numbers that completely changed how I think about content strategy. But when I talk to other marketers about it, the most common response is: “Wait, there’s an AI tab?”

    This is a walkthrough. By the end, you’ll know where to find it, what it shows, and how to read the data.

    Getting to the AI Performance Tab

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Getting to the AI Performance tab.

    Step 1: Verify your site with Bing Webmaster Tools. If you haven’t done this, start at bing.com/webmasters. You can verify using DNS, a meta tag, a CNAME record, or by importing from Google Search Console. The Google Search Console import is the fastest path — it takes about 30 seconds and automatically verifies all your Search Console properties in Bing.

    Step 2: Navigate to your verified property. Once you’re in the dashboard, select the domain you want to analyze.

    Step 3: Find the AI Performance tab. In the left sidebar, look under the “Performance” section. You’ll see the standard “Search Performance” tab (clicks and impressions from Bing search) and below it, “AI Performance (beta).” Click it.

    If you don’t see the tab, there are two possible reasons: your site hasn’t been verified long enough for Bing to accumulate data, or your site hasn’t earned any Copilot citations yet. The tab may not appear until there’s data to show.

    What You’ll See Inside

    The AI Performance tab has three main data views:

    Citation Count (total): This is the big number at the top. It shows the total number of times Copilot used your content as a grounding source in its responses. For context: my domain shows 98,800 total citations. This number represents actual instances where Copilot pulled information from my pages and embedded it in responses to real users.

    Grounding Queries: Below the total count, you’ll see a list of the actual queries that triggered citations. These are natural language questions — not keywords. They show exactly what Copilot users asked when your content was cited. My top query is “claude ai pricing” at 16,500 citations. The query list is sorted by citation volume, showing your highest-impact content first.

    Daily Trend Chart: A time-series chart showing daily citation volume. This is where you see growth patterns. My chart shows a clear acceleration: 672 daily citations at the start growing to 5,500 daily citations over 90 days. The shape of this curve tells you whether your citation authority is growing, stable, or declining.

    Reading the Data: What the Numbers Mean

    High citation count + few queries = concentrated authority. If you have thousands of citations but only 10-20 queries, your content is the dominant source for a small number of high-volume topics. This is a strong position — you own those topics in Copilot’s grounding index. My domain has this pattern: a few articles about Claude pricing and tools generate the bulk of citations.

    Moderate citations + many queries = broad relevance. If you have hundreds of queries each generating modest citation counts, your domain is recognized as relevant across a wide topic area but isn’t dominant for any single query. This is a growth opportunity — identify the queries with the highest potential and create dedicated, optimized content for each.

    Growing daily trend = citation flywheel. If your daily trend shows consistent growth, Copilot is developing increasing trust in your domain. This flywheel effect means each new citation makes your domain more eligible for additional queries. Protect this growth by keeping cited content accurate and current.

    Flat or declining trend = stale content signal. If citations plateau or decline, it may indicate that your content is becoming outdated or that competitors have published more current versions. Check whether your most-cited pages have stale information — especially pricing, feature lists, or version numbers.

    The Queries Are the Gold

    Four-stage funnel: citation, click, engage, convert
    The queries are the gold.

    The most valuable data in the AI Performance tab isn’t the citation count — it’s the grounding queries. These reveal exactly what enterprise workers are asking Copilot, which is intelligence you cannot get from any other tool.

    Google Search Console shows you keywords — fragments that users type into a search bar. Bing’s grounding queries show you full natural language questions that users ask an AI assistant. The difference is significant:

    A Google keyword might be: “claude ai pricing”
    The Copilot grounding query is: “what is claude ai pricing in 2026 and how does it compare to openai”

    The grounding query tells you the user’s full intent, their comparison frame, and their temporal context. This is richer intent data than any keyword tool provides, and it’s free, sitting in your Bing Webmaster Tools dashboard right now.

    Use these queries to:

    Identify content gaps. If users are asking questions that your content doesn’t fully answer, you know exactly what to add. A grounding query like “claude ai pricing vs openai pricing 2026 comparison” tells you to add an explicit comparison section to your pricing article.

    Discover adjacent topics. The long tail of grounding queries often reveals related topics you haven’t covered. If you’re earning citations for “claude ai pricing” but also seeing queries about “claude api rate limits” and “claude team plan features,” those are content opportunities.

    Understand your audience’s context. Grounding queries reveal the user’s situation. “What is the best AI coding tool for a team of 5” tells you the user is a tech lead making a purchasing decision. “How do I set up claude code on windows” tells you the user is a developer getting started. Each query paints a picture of who is consuming your content through Copilot.

    What to Do With the Data

    Once you’ve found and understood your AI citation data, here’s the action playbook:

    Identify your citation pillars. Which pages earn the most citations? These are your highest-authority assets. Invest in keeping them accurate, current, and comprehensively structured. A $0.10 update to a page earning 1,000 daily citations is the highest-ROI content investment you can make.

    Fill the gaps in your query coverage. Look at grounding queries that cite your content — are there related queries you’re not capturing? Build content for the gaps. If you earn citations for “claude ai pricing” but not “claude ai pricing for enterprise,” that’s a targeted content opportunity.

    Structure for extraction. Look at which content formats earn the most citations. In my data, structured content — pricing tables, comparison matrices, step-by-step configurations — earns dramatically more citations than narrative-only content. Add extractable elements to your highest-value pages.

    Set up a monitoring cadence. Check your AI Performance tab weekly. Track your daily citation trend and watch for inflection points. If a new article suddenly starts earning citations, double down on that topic. If an existing article’s citations start declining, check whether the content has become outdated.

    Cross-reference with Search Performance. Compare your AI citation data with your traditional Bing search data in the same tool. Which pages earn citations but not clicks? Which earn clicks but not citations? This comparison reveals which content serves AI audiences vs human audiences — the foundation of platform-specific optimization.

    Why This Matters Beyond Bing

    Bing Webmaster Tools AI Performance is currently the only tool exposing AI citation data at this level of detail. Google Search Console doesn’t show AI Overview citation data. ChatGPT, Perplexity, and Claude don’t offer webmaster analytics dashboards.

    But the data from Bing is a leading indicator for the entire AI citation landscape. Microsoft Copilot’s behavior reflects broader patterns in how AI engines consume and cite web content. The topics that earn Copilot citations are likely earning citations across other AI platforms too — you just can’t see the data yet.

    By the time Google and other platforms expose their citation data (which I believe is inevitable as publisher demand grows), the early movers who used Bing’s data to develop platform-specific content strategies will have a compounding advantage. They’ll have built the citation authority, refined their content formats, and mapped their topic-platform fit while everyone else was waiting for better tools.

    The tools aren’t perfect. They’re beta. But they’re real data about a real shift in how content gets consumed. And right now, almost nobody is using them.

    Related on Tygart Media: read Bing AI citations · Bing vs GSC · citation monitoring.

    Frequently Asked Questions

    Is Bing Webmaster Tools free?

    Yes. Bing Webmaster Tools is completely free to use. You only need to verify ownership of your domain, which can be done through DNS records, meta tags, or by importing your Google Search Console properties directly.

    What if I don’t see the AI Performance tab?

    The tab may not appear until your site has accumulated AI citation data. Verify your site, ensure it’s been indexed by Bing, and check back after a few weeks. Not all sites earn Copilot citations — the tab appears when there’s data to display.

    Can I see which specific pages are being cited?

    The current beta shows grounding queries and total citation counts. The page-level attribution is inferred through the queries — if a query about “claude ai pricing” cites your content, it’s almost certainly citing your Claude pricing page. Microsoft may add explicit page-level data as the tool matures.

    How does Copilot decide which sites to cite?

    Copilot uses Bing’s search index to find relevant content for grounding. The selection factors appear to include content relevance, structural quality, accuracy, domain authority, and trust signals built through consistent citation history. Well-structured, accurate, reference-grade content on topics matching Copilot user queries earns the most citations.

    Should I optimize for Bing search to get more Copilot citations?

    Bing indexation is a prerequisite for Copilot citations since Copilot uses Bing’s index. Ensure your site is indexed in Bing Webmaster Tools and that your key pages are crawlable. Beyond that, the most effective optimization for Copilot citations is creating structured, accurate, reference-grade content on topics that enterprise workers ask about.