Author: William Tygart

  • You Bid the Drawings. The Building Didn’t Get the Memo.

    You Bid the Drawings. The Building Didn’t Get the Memo.

    Price the gap openly, before demo, as its own line in the bid.

    Not buried in contingency. Not padded quietly into other numbers and hoped for. A named divergence allowance, with unit rates for what you are most likely to find, presented while there is still time to decide. The bid stays honest about two things: what the drawings say, and what a building this age usually does to drawings.

    That can weaken a bid. Sometimes it does — that cost comes later. But the alternative is discovering the same gap with a wall open, a crew idle, and both sides treating a predictable surprise as if somebody lied.

    The summer the wall disagreed

    Picture a technical shop a lot of commercial owners will recognize. Not a generalist chasing everything. Schools, water plants, light industrial — work where the systems matter, buildings stay in service for decades, and the paperwork is supposed to mean something.

    Their estimators are good with drawings. Give them plans and a scope meeting, and they will produce a tight, defensible number. If you question a line, they can show you where it came from on the page.

    One summer they take a middle school job: a failed supply line, drawings supplied by the district, scope written directly against those drawings. It should be their kind of work. School is out, the window is fixed, the plans look complete.

    The plans are from a 2004 renovation.

    What the plans do not show is most of the building’s life since then. Two undocumented re-pipes. A wing where classrooms became a commercial kitchen, with the loads and lines that came with it. An asbestos abatement in one corridor that exists, as far as anyone can tell, only in a retired custodian’s memory.

    None of that is exotic. That is a normal old building.

    Demo opens a wall and finds the second re-pipe, routed where no pipe should be, plus suspect material nobody scoped. The job stops for testing, and the schedule starts to come apart in public.

    Then comes the conversation that tells you exactly what went wrong, because both people in it are right.

    The district’s facilities head says, accurately, “That’s not in the drawings.”

    The shop’s estimator says, also accurately, “We bid the drawings.”

    Both of them are trapped inside a concept of the building that the building itself does not match. The argument is not really about a pipe. It is about which party pays for the distance between the building on paper and the building in the wall.
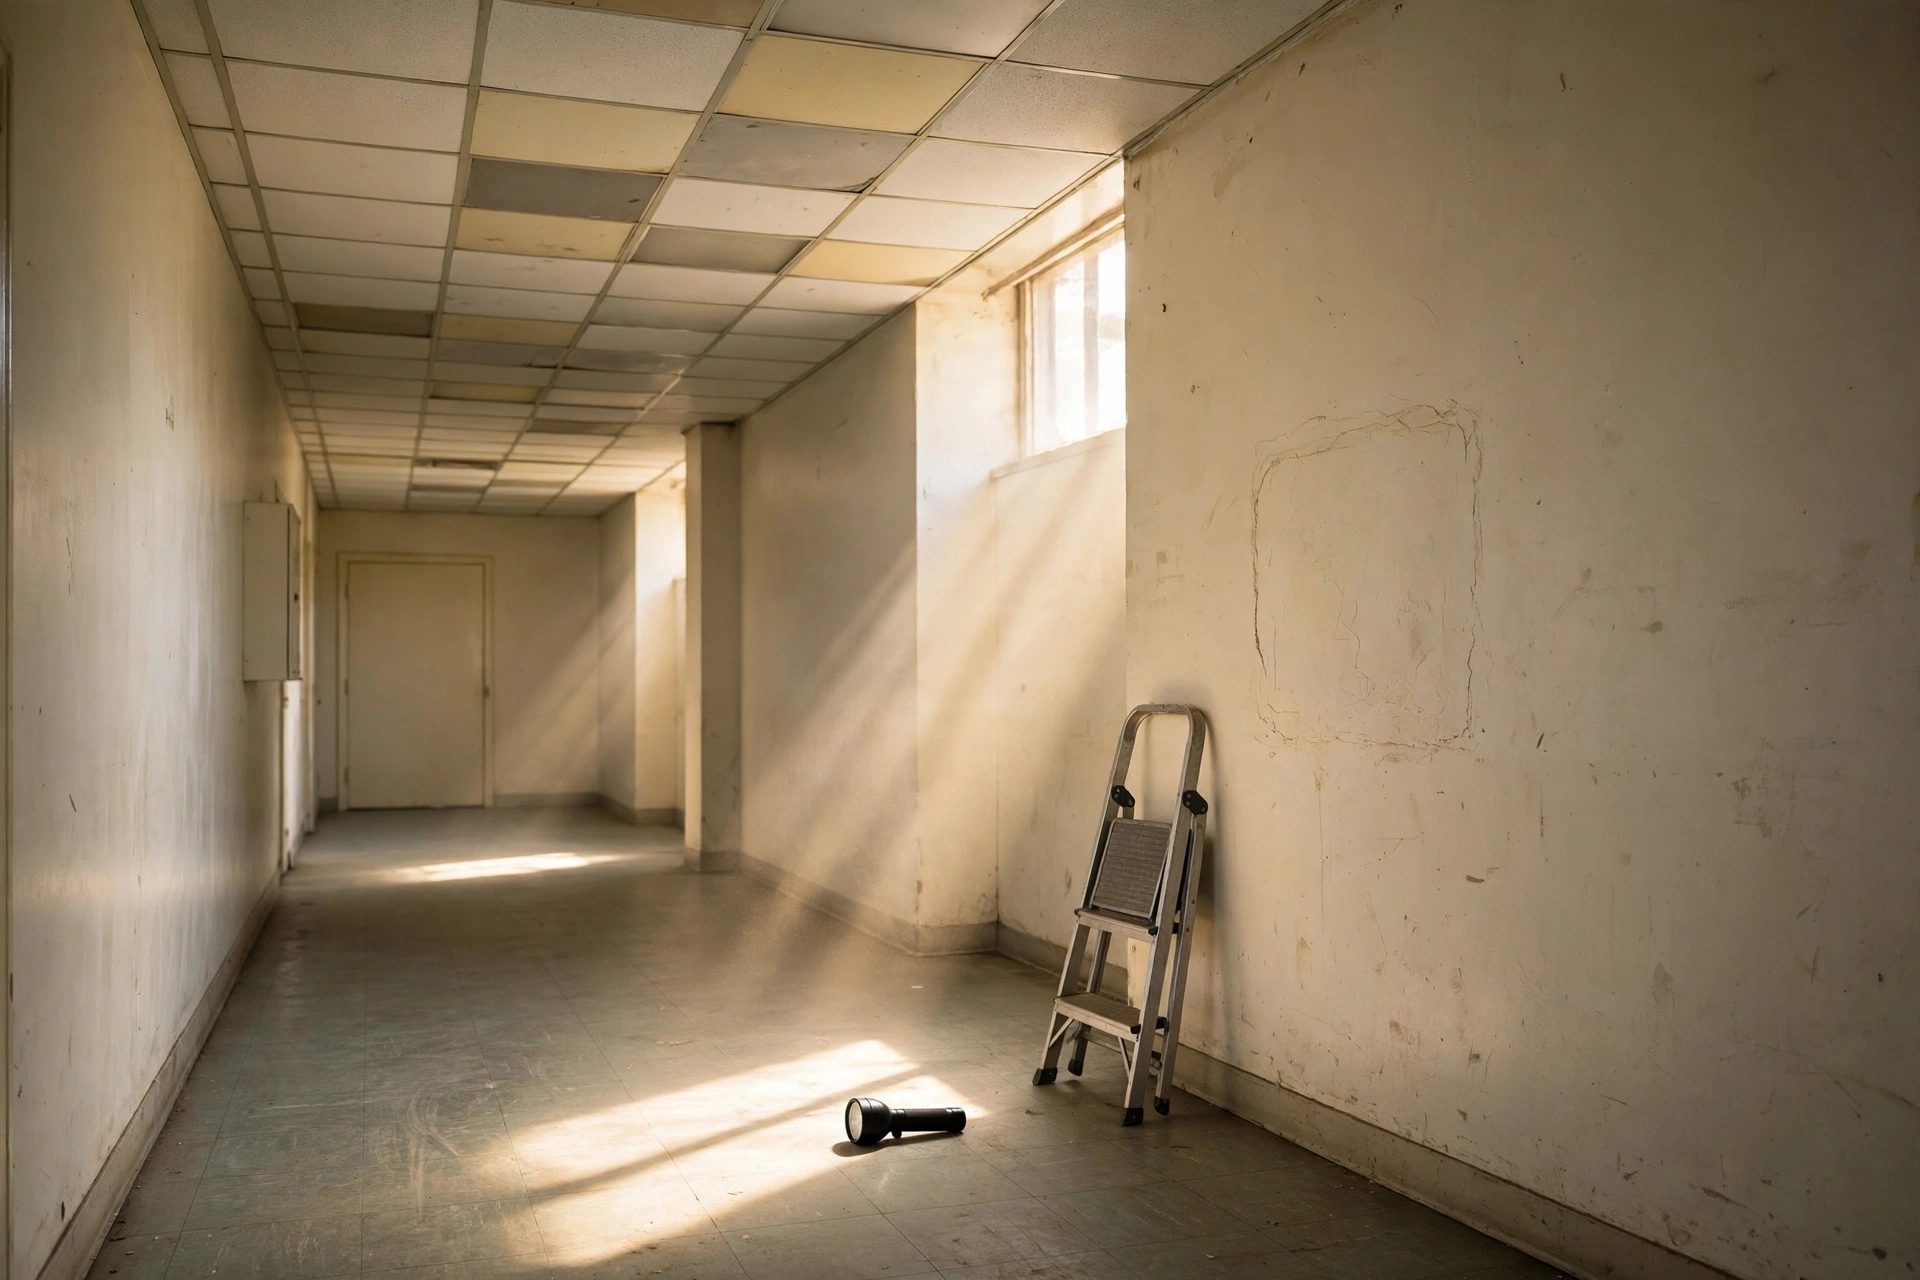
    A closed school corridor wall with a patched area and mismatched ceiling tiles above it.

    A concept is not a building

    John Boyd would have called this an orientation failure, in its purest trade form.

    Boyd was a fighter pilot who spent the second half of his career writing about how people form a picture of the world and then act on it. In “Destruction and Creation,” he argued that we build mental patterns — concepts — by taking things apart into their constituents and putting them back together, and that we also build new concepts by synthesizing across different domains. His example was a snowmobile: parts and ideas that belonged elsewhere, combined into something new.

    The warning inside the same work matters more for an estimator. A concept and the reality it describes will inevitably come apart. Boyd pointed to Gödel on incompleteness, Heisenberg on uncertainty, and the second law of thermodynamics to argue that no closed system of ideas can stay complete, certain, and current on its own. However good the drawings were in 2004, the building kept changing. The concept did not.

    And repairing the concept from inside itself only increases the mismatch. You annotate the old set. You explain away the capped line. Each small repair protects the original picture a little longer — and makes the eventual collision bigger.

    The rebuild has to start from the mismatch itself. What the wall actually shows becomes evidence for a new picture, not an embarrassment to the old one.

    Boyd called the faculty that does this orientation, and he treated it as decisive — the Schwerpunkt, the main effort, of the whole loop. Orientation is shaped by heritage, culture, previous experience, new information, and the back-and-forth of analysis and synthesis. It is also what gives implicit guidance: the practiced judgment that lets a lead look at a mismatched ceiling tile and feel, before he can prove it, that somebody has been up there changing something.

    A plan is a concept. A wall cavity is reality. When they part, the concept loses. Every time. The only choice a shop gets is when it finds out, and who is standing there when it does.

    Walking it before pricing it

    So the shop changes its commercial estimating ritual. Not the takeoff — the takeoff was never the weakness. What changes is what happens before the numbers.

    Before anyone prices a job in an older building, the lead walks the building. Not a quick site visit. A deliberate hunt for differences between the drawings and the place itself.

    Toyota has a plain phrase for it: genchi genbutsu — go and see the actual place and the actual thing. Do not estimate a wall cavity from a conference room.

    He takes a camera, and whenever he can find him, the oldest maintenance employee still connected to the building. Not the person with the title. The person who remembers which summer the kitchen went in, which corridor they closed for a week, which line was capped instead of removed because the money ran out.

    They hunt small things. Capped lines that end for no documented reason. Patched chases. Ceiling tiles that do not match the run beside them. Access panels added after the fact. A valve serving something the drawings say is not there. Each one is photographed and noted, not as a scope item — they cannot know that yet — but as evidence that this building’s concept and its reality have already parted in specific places.

    Then the estimate gains a section it never had before, priced and labeled in plain words: divergence allowance.

    On the next school job, they present it openly to the district. Here is the bid on the drawings, line by line. Here, separately, is what buildings of this age usually hide, based on the walk and what the maintenance man remembered. Here is an allowance for that category, and the unit rates that will govern if it is found — per foot, per opening, per test — agreed before demo, when agreeing is still cheap.

    If nothing is found, the allowance is not spent. If something is found, nobody has to start by proving whose fault the building is.

    What changes — and what it costs

    The first change is that change-order fights drop. Not because the surprises stop — they do not — but because an unknown priced as a category is a different conversation from an unknown discovered as an accusation. In the old ritual, finding a second re-pipe mid-job sounded like “you missed this.” In the new one, it sounds like “this is the divergence we priced; here is the unit rate we agreed.” Same pipe. Completely different meeting.

    Tempo changes with it, and Boyd’s tempo was always relative, never a calendar claim. The shop is not faster in some absolute sense. It is faster than the argument it used to have, because the decision about how found conditions get paid for was already made while everyone was calm.

    Now the cost, kept honest.

    One district picks a cheaper competitor whose lower bid contains no allowance at all. The shop loses the job. That is not a hypothetical risk; it is what procurement that rewards the thinnest concept will do, some of the time. A low number that assumes a 2004 drawing is still a building will beat a candid number that admits it is not — until the wall opens, at which point the candid shop is not there to say anything about it.

    The shop also spends unbillable walk hours on every bid, including the bids it loses. The oldest maintenance employee is not always findable, and sometimes the walk finds nothing conclusive while the allowance still has to be defended to an owner who would rather believe the drawings.

    The lens does not remove the mismatch between as-designed and as-found. Nothing does — that was Boyd’s point. It moves the cost from mid-job conflict to pre-bid candor. Cheaper, but not free — and a shop should expect to pay it in lost bids and unpaid hours before it saves them a single stopped job.
    Neatly stacked drying equipment waiting along the wall of an empty sunlit classroom.

    The practice

    On Monday, for commercial work in any building old enough to have a history:

    1. Walk before you price. Take the drawings, a camera, and the longest-serving maintenance person you can find, and hunt specifically for where the place disagrees with the paper — capped lines, patched chases, mismatched tiles, panels that should not exist.
    2. Add a labeled divergence allowance to the bid, separate from the drawing-based number, with agreed unit rates for the found conditions you are most likely to meet. Unspent means unspent — say so in writing.
    3. Present both numbers openly and let the owner choose with eyes open. If a thinner bid wins, log it as the known cost of candor, not as a reason to quietly go back to bidding the fiction.

    From the Boyd & Toyota series. The operator-side pieces run at Restoration Intel — start with The Cord Nobody Pulls and Salvage Is a Window, Not a Service. Want this thinking applied to your own shop? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.
  • Your Supplement Is Perfect and Three Weeks Late

    Your Supplement Is Perfect and Three Weeks Late

    What happens is simple, and not flattering: the money starts moving about a week sooner, and the file gets a little less perfect. When a shop stops building supplements to prove it was right and starts building them to land inside the review cycle that actually releases payment, the work does not get sloppier. It gets timed. The thoroughness meant to protect the shop was keeping its jobs open.

    This is a franchise unit, busy enough, good reputation, with one large program relationship that matters more than the rest. That program does not pay when the work is done. It pays after a file moves through a batch on the carrier side: files are batched, reviewed on Thursdays, and supplement questions come back the following Tuesday.

    The office manager is excellent. Every supplement she builds is a complete package — scope tied to photos, photos tied to notes, labor and materials documented, the question the adjuster might ask already answered two pages before he would have asked it. Unanswerable, if you give her time to finish it.

    It takes her nine days to build one.

    The file that kept missing the train

    Picture a job that is physically done. Dry, rebuilt, homeowner back in the kitchen. The only thing left is the supplement — a legitimate difference between what was approved and what the job required once walls were open. She starts on a Monday. By the time she has chased the last invoice and matched the last photo, it is the Wednesday of the following week. Sometimes Friday.

    Friday is the problem, not the quality.

    A supplement finished on Friday has missed Thursday’s batch. It waits almost a full week for the next review, then until Tuesday for an answer. If that answer contains one question — and there is almost always one — the reply, however perfect, cannot be reviewed until the Thursday after that. One question costs a full loop.

    Do that on a handful of jobs at once, which is normal, and receivables age in a way that has nothing to do with how well the shop does restoration work. Jobs sit open 30-plus days past physical completion. The homeowner, who sees none of this machinery, experiences the delay as the shop’s slowness. The competitor across town, whose files are not better, gets paid about three weeks faster because his paper lands on time.

    The owner kept asking for a better file. What he had was a timing problem wearing a quality costume.

    That is the mismatch Boyd would point at first. John Boyd, the fighter pilot who worked out the Observation-Orientation-Decision-Action cycle, held that when your picture of a situation no longer matches reality, you cannot patch it from inside the picture. You have to build a new one. This shop’s picture was: completeness gets us paid and protects us. Reality demonstrated something else every week: completeness on a nine-day rhythm guarantees we miss the only review that pays us. More documentation inside that picture just made the package heavier while it waited.

    Tempo is relative, not fast

    Sunlit empty restored kitchen sitting quiet and finished.

    Boyd’s word for this is tempo, and it is easy to get wrong. Tempo is not speed, not hustle, and not a date on a calendar. It means operating at a rhythm that fits — and gets inside — the rhythm of the situation around you. Relative, not absolute. Measured from demonstrated reality, never from what the schedule was supposed to be.

    This shop kept its own rhythm: nine days, same process every time. The carrier kept a different one. The mismatched one decides how long you wait.

    Getting inside another party’s cycle, in Boyd’s sense, does not have to mean beating anyone. There is no enemy here. An adjuster working a Thursday batch is not an opponent to be disoriented. He is a person carrying a stack of files, with limited time on each one. The file is something being carried through his process. The useful question is: what does his Thursday actually look like, and what kind of file moves through it in one pass?

    That question turns on orientation. For Boyd, orientation was the decisive part of the cycle — shaped by experience, by the culture you were trained in, by new information, and by pulling things apart and putting them back together differently. The office manager’s orientation was formed, for good reasons, around thoroughness as protection: if a line is documented completely, no one can take it away. It also filtered out the fact that mattered most: a complete package that arrives after the batch might as well not exist until next week.

    Changing the file required changing the orientation first. Not her competence — her picture of what a good supplement is for. Under the new picture, a good supplement is one an adjuster can say yes to on Thursday without starting a second file in his head.

    The Wednesday file

    So she rebuilt her week around Thursday, not around completion.

    Supplements are now scoped to be reviewable in one pass. The headline number is at the top. Three photos — not thirty — showing the condition, the cause, and the finished result. One question maximum for the adjuster, if a question has to be asked at all. If a line is still pending — a subcontractor invoice that has not landed, a material cost not yet final — she does not hold the whole supplement hostage to it. She submits Wednesday, incomplete but honest, with the pending line flagged rather than guessed or buried.

    Wednesday matters. It puts the file in the batch with a day to spare, and it makes the shop’s rhythm usefully irregular: small files sometimes go in three days, a larger one in five, but all orient to the same Thursday reality instead of a nine-day standard that had nothing to do with payment.

    Boyd treated a decision as a hypothesis and an action as a test. The hypothesis here was narrow: a shorter, reviewable file submitted before the batch will come back with fewer full-cycle delays than a complete file submitted after it. The test was the next three Tuesdays. Count days from completion to payment, not pages in the package.

    It held. Completion-to-payment dropped by roughly one full review loop. Nobody worked frantic hours or added staff. The same office manager stopped answering questions no one had asked yet and made the one question that mattered impossible to miss. When a file moves in one pass, the Tuesday answer is usually a decision, not a new round of discovery — the job closes while the crew still remembers it.

    What it costs

    Boyd’s tempo is always paid for in comfort with imperfection, and this shop paid it in the exact place you would expect.

    The unanswerable package was armor. Giving it up feels exposed. A flagged pending line, sent honestly before the final number is nailed down, occasionally gets denied in a way a buried, fully documented line probably would not have. That has happened. It is not theoretical. The shop had to weigh the week saved across ten jobs against the line lost on one. So far the math says yes, clearly. The feeling still says be careful.

    The second cost landed on the office manager herself. Thoroughness was not just her method; it was her professional identity — the person who never missed anything. Sending a file she knows is incomplete, even flagged and honest, felt at first like doing worse work in public. It helped that the new standard was hers to shape: she designed the one-pass format, chose which three photos tell the story, and wrote how pending lines get flagged. The rhythm changed. The ownership did not.

    Rhythm-matched does not mean thin. A file that leaves out the photo that proves the condition, or guesses at a number to make a Wednesday deadline, is just fast and wrong. Keep what a reviewer needs to decide, in the order he needs it, and be explicit about what is not yet in the file.

    Neatly opened wall showing clean framing in warm daylight.

    If you are paid directly by homeowners, translate the principle, not the Thursday. Every business paid through someone else’s batch — a property manager’s monthly approvals, a GC’s pay-app cycle, a corporate accounts-payable run — has a Thursday somewhere. Most shops never ask when it is. That rhythm is the other party’s observation, orientation, decision, and action cycle, running on its own clock. Your file either lands inside it or waits outside it, complete and correct and unpaid.

    The practice

    1. Find your Thursday. For every payer, program, or GC that matters, ask when files are actually batched and reviewed — and when answers come back. Write those two days down. That is your real payment schedule.
    2. Redesign one file for one pass. Rebuild next week’s supplement to be decided in a single review: headline number first, the few photos that prove the condition, one clear question at most. Submit it the day before the batch, as a test.
    3. Flag, don’t hold. If one line is still pending, submit the rest on rhythm and flag that line. Do not let one missing invoice move the whole job into the next cycle.
    4. Measure days, not pages. Track completion-to-payment days for a month. If they do not fall after three cycles, the hypothesis was wrong — change the file again, based on what Tuesday brought back.

    From the Boyd & Toyota series. The operator-side pieces run at Restoration Intel — start with The Cord Nobody Pulls and Salvage Is a Window, Not a Service. Want this thinking applied to your own shop? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.
  • We Ran Muse Spark’s Reasoning Dial Through 52 Calls. The Cheapest Setting Never Lost.

    We Ran Muse Spark’s Reasoning Dial Through 52 Calls. The Cheapest Setting Never Lost.

    Every API model ships with a dial most people never touch. On Meta’s Muse Spark 1.3, the dial is called reasoning_effort — it decides how long the model thinks before it answers. Turn it up and you pay more tokens and wait longer, on the theory that more thinking means better answers.

    We spent two days testing that theory on the contributor tier of Muse Spark 1.3 — the same engine our own publishing fleet runs on. Fifty-two API calls, seven different kinds of work, every rung of the dial, everything scored against known ground truth. The result surprised us, and it changes how we run the fleet:

    The cheapest setting never lost. Not once. On hard tasks, the expensive settings mostly bought latency — and twice, extra thinking was the failure itself.

    How we got the dial wrong first

    During a hackathon last month we tried to set the dial with a parameter called reasoning. The API rejected it, and we wrote down “the API won’t let us control reasoning.” That was wrong — the parameter is reasoning_effort, and it works fine. Lesson one of testing a model: a rejection usually means you asked wrong, not that the door is locked.

    We also carried a second error into the test: a belief that the API capped output at 8,000 tokens. It doesn’t. That cap was our own router setting, repeated so often it hardened into “fact.” Generation verified past 15,000 tokens in a single call. Both errors are corrected in our own records now, with the receipts attached — which is the point of running a test like this in the open. The test’s first findings were about us.

    The ladder has six rungs — and one of them doesn’t exist

    The full map, settled by the API’s own error messages when we fed it bad values: minimal, low, medium, high, xhigh, max. That is the complete list.

    Two things people assume about this dial are false. There is no “extra high” setting — xhigh is that rung, and the spelled-out version is rejected. And there is no off switch you can use: none appears in the generic schema, but this model rejects it with a message that lists exactly what it does support. On Muse Spark 1.3 contributor, the model always thinks at least a little. The only question is how much you pay for.

    The rounds

    Every task was run at multiple settings with identical prompts, and scored mechanically — no vibes, no “this answer feels smarter.”

    Contradiction checking (a spec paragraph, 24 statements, name the ones that contradict it): exact answers at every setting. Low used about a third of the reasoning tokens of the default.

    A buyer-brief judgment task — the hardest test we built. Four vendor blurbs against six hard rules (billing terms, export fees, Saturday support, a $7,200 year-one cost cap, HIPAA, cancellation windows), with planted traps: one vendor breaks two rules with numbers you have to multiply out, one hides a disqualifier in its cancellation clause, one is clean only if you notice the free-months clause. Every rung — minimal through max, plus unset — produced the identical score: correct winner, all five real traps caught, zero missed. Minimal used 776 reasoning tokens and 6.5 seconds. Xhigh used 6,847 tokens and 50 seconds. Same answer.

    Agentic planning (schedule an 8-step pipeline with dependencies and resource constraints into parallel waves): provably optimal schedules at every rung. Minimal solved it in 242 reasoning tokens.

    Code debugging (a function with three planted bugs): every rung found the inverted discount logic and the rounding bug; the cheapest setting found all three.

    Verdicts at scale (120 claim records, check each against a two-part rule): 120 out of 120 correct at low — and 120 out of 120 at xhigh. (Our first scorer reported 83/120 at both settings; the bug was in our regex, not the model. We re-ran it with the full text saved, corrected the record, and retracted the number. Test harnesses fail too, and the honest write-up says so.)

    Constrained writing (a briefing paragraph with five required facts, three forbidden claims, and a word band): every rung delivered all five facts, zero forbidden claims, in band. Reasoning ranged from 729 tokens to 6,687. The paragraph didn’t get nine times better. It got nine times slower.

    Where more thinking actually hurt

    Twice in 52 calls, the expensive end of the dial was the failure:

    • Left unset, the model burned 7,578 reasoning tokens on the vendor task — more than any explicit setting — for the same score minimal got for 776. The default thinks hard whether you asked it to or not. Unset is not neutral; it’s the expensive option wearing a disguise.
    • On the debugging task, an xhigh call consumed its entire 8,000-token budget on reasoning — 7,998 reasoning tokens, completion exactly 8,000 — and returned an empty answer. It thought so long it never spoke. Minimal answered the same task correctly with 500 reasoning tokens. Anyone who has watched an agent stall mid-job has seen this shape; here it is with a meter on it.

    And one anomaly worth naming: max is the top rung by name, but on the vendor task it burned less than xhigh (3,773 vs 6,847). The rungs are task-shaped budgets, not fixed ceilings — max buys you permission to think longer, not a guarantee of the deepest burn.

    What it cost

    Fifty-two calls, roughly 31,000 tokens in and 145,000 out across both days: $0 charged. The contributor tier’s billing never touched the $25 test envelope we run it under, and its per-token price remains unpublished as far as we can verify — we won’t invent one. At the standard tier’s published rates ($1.25 per million in, $4.25 per million out), the entire test programme would have cost about 65 cents. The dial still matters at fleet scale: reasoning tokens bill as output, and a fleet that runs xhigh by habit pays roughly nine times the reasoning cost of one that runs low — for, on this evidence, the same answers.

    The operating rule we run now

    • Mechanical work — extraction, checking, verdicts, formatting: minimal or low.
    • Judgment work: low, stepping up to medium when the task deserves a second think.
    • Xhigh and max are earned, not default: a task graduates to them only after it has demonstrably failed at low. In 52 calls across seven kinds of work, no task has earned it yet.
    • Never leave the dial unset. The default is the high band with none of the intent.

    The honest limits of this test

    One sample per cell. Seven task classes, all of them the kind of work a publishing fleet actually does — checking, judging against a brief, planning, debugging, classifying at scale, writing to constraints. We did not test open-ended research, long creative writing, or mathematics, and a task in those families might break the pattern; the battery is built to be re-run the day one appears. Reasoning-token counts also vary between sessions on identical tasks — sometimes by ~30% — so treat the exact numbers as readings, not constants.

    But the shape of the result is hard to argue with: on real operational work, this model’s floor is high, and the dial mostly prices your patience. If your fleet — agent, workflow, whatever you run — has a reasoning setting you’ve never touched, the test is cheap, the scoring is easy to make mechanical, and the answer might save you nine-tenths of your reasoning bill. Run the test. Publish what you find. We just did.

    Method and receipts: 52 calls to muse-spark-1.3-contributor via Meta’s Model API, November 6–7, 2026. Full findings, prompts, ground truth, and raw results: part of the Tygart-OS fact-gated fleet record on GitHub (github.com/TygartMedia/tygart-os-fact-gated-fleet). Errors found in our own earlier assumptions (the reasoning parameter name, the phantom 8,000-token cap, and one scorer bug) are documented in the same record, corrected where they stood.

    Counter-check, November 7, 2026: a reader sent us CursorBench’s rung-by-rung ladder for this same model, and on sustained coding-agent work the dial pays at every rung — the opposite slope from ours. Both numbers are real; the tasks aren’t the same. We worked through it here: The Coding Ladder Says the Dial Pays. Our 52 Calls Said It Didn’t. Both Numbers Are Real.

  • Your Coding Agents Live on One Machine. T3 Code Puts Them in Your Pocket.

    Your Coding Agents Live on One Machine. T3 Code Puts Them in Your Pocket.

    Your coding agent is running on your desktop. You are not at your desktop. That gap — between the machine where the work happens and the person who has to approve the next step — is the whole problem T3 Code exists to close.

    T3 Code is an open-source “agent harness control surface” from the T3 Tools team (the repo is pingdotgg/t3code on GitHub, MIT licensed). It is not a model. It is not a new coding agent. (If you are still choosing between the agents themselves, start with our Claude Code vs Cursor comparison – this piece is about what sits on top of whichever one you picked.) It is a small server that runs on the machine where your agents already live, and it remote-controls the ones you already pay for: Claude Code, Codex, Cursor, Grok Build, OpenCode, Google Antigravity, and fx. A phone app, a web app, a desktop app, and a terminal command all drive the same threads.

    The demand is not subtle. The repository passed 50,000 stars this week — 50,470 when we read it on the morning of November 7, 2026, up more than 16,000 in the week to November 6, the largest weekly gain of any AI project on GitHub. It was created in February 2026. Nine months from zero to fifty thousand stars is what a widely felt gap looks like when somebody finally fills it.

    What it actually does

    Install the t3 command on the host machine, connect at least one provider using that provider’s own login (claude auth login, codex login, agent login for Cursor — Antigravity needs no CLI; you enable it in Settings and sign in with Google), and start the server. It listens on your machine, port 3773 by default. Register a project, start a thread, and the agent works in that project exactly as it would if you were sitting there.

    From that point you have four ways to reach the same work:

    • The phone app (iOS and Android, free) — start runs, watch threads, approve a step or send a correction, browse files, review diffs, run version-control actions, use the terminal. The Android listing describes it as “pretty much the full power of the desktop app.”
    • The web app — the same surface in a browser.
    • The desktop app — Electron, on Windows, macOS, and Linux.
    • The t3 CLI itself — t3 thread start, t3 thread send, t3 thread list from any terminal. A thread waiting on you exits with its own signal, so scripts can tell “finished” apart from “blocked on the human.”

    Two connection routes matter. On your own network — or over a private network like Tailscale — you pair a device directly with a one-time link or QR code, no account at all. Away from home, T3 Connect is the managed relay: no router configuration, sign in on the host, sign in on the phone, pick your machine. Per the hands-on guide we worked from, a free T3 Connect account links up to 3 machines.

    Every thread writes to its own branch. When the work is good, one button opens the pull request on GitHub with a generated title, body, and changelog — after you’ve reviewed the diff inline. The agent does the typing. You keep the merge.

    What it costs

    Nothing for the software. T3 Code is free and MIT licensed — “If you don’t like something, fork it” is a headline feature on its own site, with the fork command printed under it. It does not resell tokens and it does not hold your credentials hostage: you bring your existing subscriptions, log in with each provider’s own flow, and model usage is billed by your provider exactly as before. “Bring your own sub. No keys resold. No quota caps.”

    That pricing shape is the point. The control layer is becoming a commodity; the subscriptions underneath it are the spend. A control plane you can fork can never raise its rent on you.

    The honest limits

    The README says it in plain words: “We are very very early in this project. Expect bugs.” Believe it. The stable release this week is v0.1.7. This is a fast-moving, nine-month-old project, not settled infrastructure, and the team is mostly not accepting contributions yet.

    Three operational limits follow from the design:

    1. The host has to stay awake. Your agents run on your machine, not in T3 Code’s cloud. On Linux and macOS you can install the server as a background service (t3 service install). Windows gets no background service — you leave the desktop app running, and closing its last window stops the local server.
    2. Remote access is a security decision, not a default. On a local network, the pairing code is the only thing between your agents and every other device on that network. Pair per device with fresh one-time links, don’t enable LAN access on a network you don’t trust, and prefer a private network like Tailscale for anything beyond the couch.
    3. It controls agents; it doesn’t supervise them. T3 Code moves the approval to your phone. It does not decide whether the work order was well-specified, whether the agent’s output is right, or whether the diff should merge. That judgment problem is the same one behind our MCP tool-poisoning checklist: the harness around the agent is where the safety lives. The judgment layer is still yours.

    How this maps onto a multi-seat shop

    We run several agent seats — Claude, Cursor, Antigravity, Grok — and the standing problem with seats is presence. Work stalls at approval points because the human isn’t at the keyboard the agent is attached to. Anyone who has watched a finished piece of work sit idle for hours because it was waiting on a tap that could have happened from a phone knows this stall by name.

    Against that setup, T3 Code is a fit in three specific places:

    • It covers the seats we actually run. Claude Code, Cursor, Antigravity, and Grok Build are all on its provider list today. One surface over all of them beats four vendor apps with four different ideas about remote access.
    • It keeps the work on our hardware. The alternative shape — cloud agents that keep running while your machine sleeps — means your code and data live on the vendor’s machines by design. T3 Code’s answer is the opposite trade: your machine stays the plant, and the phone is just the window into it.
    • It matches how the work is already shaped. Bounded task per thread, worktree or branch isolation for unreviewed work, diff review before merge — that’s the same discipline as a work order with receipts. The remote control doesn’t change the discipline; it removes the geography from it.

    Where it doesn’t fit is just as clear. It doesn’t replace the harness — the work orders, the context, the QC on what comes back. A remote control for a badly briefed agent just lets the agent be badly briefed from further away. And for work that genuinely has to run while every machine you own is off, a self-hosted control surface is the wrong tool no matter how good the app is.

    The verdict

    Real, and early. The star count is the loudest signal, but the quieter one is the shape: open source, multi-provider, your hardware, your subscriptions, forkable if the team ever takes it somewhere you don’t want to go. That is the correct shape for a control layer, and it’s the shape the closed vendor apps don’t offer.

    Try it the cheap way: one machine, one provider you already pay for, one bounded thread started at your desk and approved from your phone. If that loop feels like the missing piece, it earns a place. If it doesn’t, you’ve spent ten minutes and nothing else — which, for a tool at version 0.1.7, is exactly the right size of bet.

    Sources: the T3 Code repository and README (github.com/pingdotgg/t3code — 50,470 stars, 9,813 forks, MIT license, repo created February 8, 2026; read November 7, 2026); t3.codes (positioning, provider list, fork-it terms; read November 7, 2026); AI Frontier Post hands-on tutorial, “T3 Code: drive Claude Code, Codex and Cursor from your phone” (install, pairing, service, and T3 Connect machine-limit details, verified end-to-end by its author against v0.1.7; published November 7, 2026).

  • The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    On November 5, 2026, MGT Insurance — a full-stack commercial carrier — listed its AI quoting assistant, Aimee, in the ChatGPT app directories and opened its MCP, so appointed brokers can quote a business policy by typing a sentence. This is a mapping: the new model read against the Wisdom Trust — our open kit for capturing elders’ life stories, and its paid human sibling, the Wisdom Manager. Two earlier mappings in this series read NHS Life Stories (October 18, 2026) and LifeBio’s Engagement Services (October 24, 2026) the same way. Where MGT’s public pages are silent, this says so rather than guessing.

    The two things, in one paragraph each

    MGT / Aimee. MGT is a full-stack, licensed commercial P&C carrier — an “AI-native neo-insurer” (A- rated by AM Best, per its release) that owns its product, its platform, and its risk, selling small-business cover (today: Business Owner’s Policy, 300+ business classes across 43 states and D.C.) through independent agents. Aimee is its broker-facing AI agent: since 2025 she has answered appetite questions on mgtinsurance.com with no sign-in; on October 16, 2026 MGT became, by its own claim, the first carrier to offer chat-based quoting — an agent describes a business in plain language (or uploads an ACORD application) inside ChatGPT or Claude and gets a real rate; on November 5, 2026 the integration was listed in the ChatGPT app directories, with MGT “opening up our MCP so brokers can quote where they already work.” Aimee classifies the business, checks MGT’s appetite, asks only for what is missing, prices the quote, and — the load-bearing detail — “tells the agent what she assumed and why.” Every quote then opens in MGT’s own portal, where the human agent reviews it and binds. MGT’s platform numbers ($83B of quoted TIV, nearly 15,000 appointed agents) are the company’s own, printed in its release; trade coverage notes MGT has not disclosed how many agents use the ChatGPT channel, what time it saves per quote, or what volume has bound through it.

    Wisdom Trust (Will). Two related things. The kit: an open-source starter set (MIT, explicitly “a seed, not a product”) for capturing retirement-facility residents’ life stories — one emailed question per week, answered by voice through a single link with no account, curated by an AI pipeline into a family-owned collection, framed as inheritance (“a life documented like a 401k left behind”). The storyteller owns the material outright; the machine’s outputs are drafts for human approval; nothing outward is ever auto-sent. The Wisdom Manager: a sketch for a paid human service — part curator, part oral historian, part creative director — that turns a family’s scattered media into a living collection through a gated process (private intake → curator review → owner approval → presentation), priced from ~$1,000 guided products to $20,000+ commissions. Both halves are built to be run by the people they serve; neither is published as a tool inside a platform somebody else owns.


    Side by side

    Dimension MGT / Aimee Wisdom Trust (kit + Wisdom Manager)
    Capture prompts / structure Appetite-first. Before any full submission, Aimee gives a real-time read on whether a class/state fits MGT’s appetite (the published Appetite Guide covers 300+ classes with NAICS groupings). In a quote she classifies the business, checks appetite, then asks only for what’s missing — the structure is the carrier’s underwriting rules, proprietary, applied conversationally. The prompt surface is whatever the agent types: a sentence, pasted call notes, an uploaded ACORD. A fixed library of 40 written questions across a life, one sent per week, skippable at will; the pipeline’s final stage (“Notice Gaps”) reads the collection and generates the next questions from what’s missing. The “asks only for what’s missing” discipline exists in his design too — but at stage 8 of the pipeline, after collection, not at the front door before it.
    Media types Plain-language text and documents: typed descriptions, pasted call notes, uploaded ACORD applications and supporting files, which Aimee “turns into a quote, flagging any values worth confirming.” Voice-first. A spoken (or typed) answer in a chat, 20+ languages, transcribed verbatim then cleaned; the pipeline can render artifacts back out — image, music, video, voice — each labeled with what it is, what it is not, and why it was made. The Wisdom Manager side curates media a family already has.
    Who does the capturing The machine, employed by the carrier. Aimee does the data entry, classification, appetite check, and pricing; a second agent (Athena, per MGT’s own essay) has made end-to-end underwriting decisions “with no human input.” The human in the loop is the broker — a professional intermediary — who reviews the finished quote in the portal and binds. The insured business is described, not consulted. The elder answers alone, by link; a family archivist or staff champion sends the question; staff are guides, not interviewers. The machine curates, but every outward artifact is a draft for owner approval — nothing auto-sends, ever. Both models keep a human gate before the consequential act; the gatekeepers differ (a licensed broker binding cover vs. the owner of the material approving its use), and so does whom the machine works for.
    Entry / onboarding Two doors, deliberately tiered. The appetite door is open to anyone — “you can still chat with Aimee about appetite, with no sign-in required.” The quoting door requires an MGT appointment (a broker contract) and signing in with MGT credentials inside ChatGPT/Claude; appointment itself is a sales process (mgtinsurance.com/get-appointed). Once appointed, the friction claim is real: “They don’t need another form or another login” — the quote starts inside the assistant the agent already uses. One link, no app, no account, no password — a stated non-negotiable: “If the storyteller has to install anything, the design failed.” Consent is signed before the pilot starts; there is no tiered front door — no way to feel the thing, saving nothing, before the consent conversation. The friction didn’t move to procurement as with LifeBio; there is no procurement. But there is also no anonymous first touch.
    Who the finished work serves, and where Three beneficiaries: the broker (time back — the scarcest resource in MGT’s own framing), the small business (a bound policy it never had to fill in a form for), and MGT (distribution into the rooms where brokers already work, plus appetite-consistent risk selection). The finished work lives in MGT’s portal — the quote opens there, is reviewed there, binds there. The ChatGPT surface is the front step; custody of the record stays with the carrier. Serves the family and descendants: an heirloom — stories, timeline, quote cards, people/places index, a weekly family letter, a gallery page. The facility’s benefit is real but secondary and reputational. The finished work lives wherever the family keeps its collection — the kit’s whole custody posture is that the platform is a shelf, not an owner. The Wisdom Manager serves the paying family directly, owner-approved before anything is shown.
    Consent / custody / ownership The public documents are website-era documents, and the ownership check shows it (quotes below). The privacy policy (last updated Oct 21, 2026 — two weeks before the ChatGPT listing) never names Aimee, ChatGPT, Claude, or MCP, states no retention period, and contains no mention of training (verified by full-text search of the published page: zero hits for “Aimee,” “train,” “retain”). It reserves broad improvement purposes over submitted information: personal data may be used for “Auditing, research, and analysis in order to maintain, protect, and improve our services,” “Developing new services,” “To model our risks,” and “To make our products and services better”; “We may combine the information submitted under various forms and services… to improve the quality of our services.” It does state “We do not sell Personal Information.” The website terms contain no license grant over user-submitted content at all — nothing equivalent to LifeBio’s AI-training licence, in either direction — and on termination say only that MGT may terminate the account “at any time and for any reason”; what happens to a broker’s submitted data or quote history on termination is not addressed. No designee or succession concept exists in either public document. The operative broker terms (appointment agreement, portal terms, MCP-channel terms) sit behind the appointment process and are not public. One more custody layer is new with this launch: a submission made inside ChatGPT also passes through OpenAI’s platform, under OpenAI’s terms — the chain now has two companies in it before the carrier’s own documents even apply. The most heavily specified layer of the kit. A plain-language consent: the elder owns their stories, period; access only by the elder’s grant (family included — not by default); grant and revoke at will; delete permanently and immediately; never sold; voice never used to train products without separate written permission; a designated person decides after death, defaulting to deletion after 12 months if none is named. “The facility’s role is shelf, not owner.” The Wisdom Manager carries the same posture into the paid service: safety gates (private intake → curator review → owner approval → presentation) are “part of the product.”
    Output format A priced, reviewable quote — a real rate, not an estimate — carrying an assumption statement (“what she assumed and why”), which opens in the MGT portal for review and binding into a policy. The assumption statement is part of the output object, not a disclaimer under it. A structured collection, not a single object: raw + cleaned transcripts, story records, timeline, quote cards, people/places index, weekly digest letter (draft), gallery page (draft), and labeled generated artifacts — all in JSON buckets any future AI can re-render. Artifacts carry provenance labels (what it is, what it is not, why it was made); nothing in the kit attaches an assumptions record — what the machine inferred where the storyteller didn’t say — to any output.
    Institutional / commercial model A regulated company selling risk: a licensed, full-stack carrier that monetises bound premium. The AI channel itself carries no published price — it rides on the broker appointment (contract terms not public; no figures published for the channel). Appetite spans 300+ classes in 43 states + D.C. (Florida and Hawaii excluded; five states listed as coming soon). The MCP is opened free, as distribution: the quoting engine is the marketing. Note what trade coverage could not find either: no disclosed user counts, time-saved, or bound volume for the new channel — the launch is measured in platform totals, not channel outcomes. Deliberately not an institution and not a company: an MIT-licensed seed its author declines to operate (“I’m not going to be the gardener on this one”). The commercial sibling, the Wisdom Manager, is priced as independent practice — role-hour maths, ~$1,000 guided products to $20,000+ commissions, family pays. Neither side of his model publishes anything into someone else’s platform or charges by distribution; there is no channel, only a kit people pick up.

    The door moves: an open MCP, and the product stops being a destination

    NHS Life Stories is a place you go and build. LifeBio is a person who comes to you. MGT’s Aimee is neither: the product dissolves into whatever assistant the broker already has open. By listing in the ChatGPT directories and opening its MCP, MGT stopped asking brokers to visit a destination and instead published its quoting engine as a callable tool — any MCP-capable assistant (ChatGPT, Claude, and next, the broker’s own in-house agents) can invoke the carrier mid-conversation. That is a distribution mechanism neither earlier mapping has, and it inverts the kit’s founding move in an instructive way: his one-link flow deletes the destination for the storyteller (no app, no account — the capture comes to the elder). MGT deletes the destination for the professional — the capture comes to where the broker already works, and the broker’s own AI can be the one calling. What it buys:

    • Distribution without a destination. The directory listing is the shelf space. A carrier that can be quoted “by typing a sentence” competes inside every conversation a broker has, not inside a portal tab the broker must remember to open.
    • Agent-to-agent quoting becomes possible. Once the engine is a tool, the caller doesn’t have to be a human typing — a broker’s own agent, working a renewal list overnight, can call Aimee the same way. MGT says this plainly: the engine “was designed from day one to be called by agents, human and AI.”
    • The assumption statement is the trust patch that makes it viable. Moving quoting into a chat window removes the form’s forced precision; Aimee’s answer is to ship her assumptions with the quote and ask instead of guessing when something is missing. Speed is the pitch; stated assumptions are what let a professional rely on it.

    And what it costs, in terms his files would price honestly:

    • The surface is no longer theirs. Inside ChatGPT, MGT’s product renders under OpenAI’s chrome, beside competitors one directory row away, under a second company’s terms. The carrier traded a destination it controls for reach it rents.
    • The custody chain lengthens exactly where the documents are thinnest. A broker’s submission now passes a platform company’s terms before it reaches a carrier whose own public privacy policy never mentions the channel exists (see the ownership row). The mechanism is new; the paperwork is a website policy last updated before the listing.
    • “Open” is doing quiet work. No public developer documentation, endpoint, or tool specification for the MCP appears on the pages read — the openness is a listing, granted to appointed agents through two named platforms, not a published interface anyone can build on. It is an open door into a closed house: the engine, the appetite, and the submission data stay proprietary.

    What the Wisdom Trust could borrow

    1. An assumption ledger on every machine-made artifact. Aimee ships “what she assumed and why” with every quote. His artifacts carry provenance labels (what it is, what it is not, why it was made) but no record of what the machine inferred — which date it guessed for an undated story, which “Uncle Ray” it merged with which. Adding an assumptions array to the schemas (each entry: the inference, the evidence, a confirm/correct affordance for the owner) turns stage 4’s silent enrichment into something the family can audit — and it is the same fact-gating instinct his fleet work already runs on, applied to the kit.
    2. A two-tier front door: a no-save taste before the consent conversation. MGT’s appetite chat is open to anyone with no sign-in; only quoting requires the contract. The kit has one door, and it’s paperwork. A public “answer one question, nothing is kept” demo — one joy prompt, answered by voice, wiped when the tab closes — would let a family feel the thing before anyone signs anything, and would give facilities a tour artefact stronger than the one-pager. The consent template stays exactly as strict; the door in front of it gets lighter.
    3. Appetite before paperwork, as a designed step. Aimee checks fit before collecting anything and asks only for what’s missing. His pilot’s first act is consent; a two-minute fit conversation (does she want to talk about her life? joy-first or wisdom-first? who should hold the collection?) before the forms would put the kit’s existing gap-noticing discipline at the front of the flow instead of only at stage 8.
    4. Publish the kit’s functions as a callable tool, not only a link. The kit’s automation README is already a plug-in contract an AI can execute — the seed of an MCP-shaped door. MGT’s move shows the distribution value of finishing that thought: a family archivist’s own assistant could invoke “this week’s question” and “file this answer” as tools, meeting the archivist inside the assistant they already use, exactly as Aimee meets the broker inside theirs. The one-link flow stays for the elder; the archivist gets a second door.

    What his does differently, on purpose

    1. Ownership is answered in advance, in plain language — here the contrast is silence plus reservation. Against LifeBio, his template differed from stated terms (a training licence, discard on termination). Against MGT, the public terms state almost nothing about submitted content — no training licence is taken, which is genuinely better — but broad improvement and risk-modelling purposes are reserved over whatever is submitted, the channel itself is never mentioned in the privacy policy, and the documents that would settle the quoting channel’s ownership questions are contract-side and unpublished. His template answers every one of those questions before the first recording: whose it is, who may hear it, what happens when the relationship ends, who decides after death.
    2. Whom the machine works for. Aimee’s appetite is MGT’s appetite; she quotes one carrier’s product and her assumptions serve the carrier’s risk selection as much as the broker’s convenience. His pipeline works for the elder and family — its drafts wait for the owner’s approval, and its gap-finding serves the collection, not a seller. Both keep a human gate before the consequential act; the difference is whose human, and whose interest the machine was built to advance when the two diverge.
    3. Openness of the artifact vs. openness of the interface. His kit is open all the way down — MIT, forkable, schemas published. MGT’s openness stops at the interface: the MCP is listed and callable (by appointed agents, on named platforms), while the engine, the appetite logic, and everything submitted stay inside. Neither is a pose; they are opposite answers to “what do you give away to get distribution?” — he gives away the machine and keeps no channel; MGT keeps the machine and gives away the doorway.

    What he would likely reject, per his own files

    • Reserved improvement/modelling use of submissions as a standing term. His consent template promises: never sold, never used to train products without separate written permission, access only by the elder’s grant. MGT’s privacy policy reserves using submitted information to “improve our services,” “develop new products and services,” and “model our risks,” with an opt-out mechanism that applies to new purposes via a contact page. Risk modelling is ordinary, legitimate insurance practice — and it is still exactly the shape of clause his template exists to refuse: purposes named by the holder, changeable by the holder, consent handled as opt-out.
    • Changeable-at-will terms. The website terms “may be changed, modified, supplemented, or updated at any time, with or without advance notice,” with continued use counting as acceptance. His consent is a signed, plain-language document the elder can revoke at will; the terms of the relationship are not a web page one side edits.
    • A persona users mistake for a person. His pipeline labels every generated artifact with what it is and what it is NOT. MGT’s own essay reports, approvingly enough to print, that Aimee’s “users thank her and ask her to start their quotes, most of them not realizing she’s an AI” (the essay’s title is “They Don’t Know It’s an AI Bot”; MGT, to its credit, says it would rather answer the question in public than dodge it). Per his labeling rule, an assistant a user can’t tell is a machine is a disclosure defect, not a delight metric.
    • Credentials inside a third party’s surface as the consequential door. Quoting requires signing in with MGT credentials inside ChatGPT/Claude — the broker’s carrier login now lives in a platform the carrier doesn’t control. His non-negotiable deletes accounts and passwords for the person at the centre of the capture. (Nuance, noted in the table: the appetite door is credential-free — the tiering itself is borrowable #2.)

    Gaps in his own files (marked, not filled)

    • No machine-callable surface. His files describe a kit humans run and a pipeline an AI runs on the back end — but nothing about publishing the kit’s functions as tools other assistants can call, being listed anywhere, or distribution through a platform’s directory. MGT’s whole launch is that surface. The automation README is the seed of it; the discovery/distribution question is unasked in his files.
    • No assumption ledger. His stages enrich silently: dates inferred, people merged, gaps noticed — but no output carries what the machine assumed and why, in a form the owner can confirm or correct. Aimee’s quote does. (Borrowable #1 names the fix; this entry marks the silence.)
    • No eligibility step before collection. His pilot opens with consent paperwork and a 10-resident scope; nothing first asks fit — does this resident want this, which track, joy-first or wisdom-first — the way appetite precedes a quote. The appetite conversation is two minutes and saves the paperwork for people it fits.
    • The dementia silence, third mapping running (carried from NHS Life Stories, repeated in the LifeBio mapping, still open). Aimee exposes nothing here — commercial quoting is not its territory — but the standing instruction of this series is that a repeated silence gets named as repeated: his question library still assumes a storyteller who can sit with an abstraction, and no mapping since has closed it.
    • Custodian succession. His consent template settles what happens when the elder dies (a designated person decides). It does not settle what happens if the shelf changes hands — the facility is sold, the keeper of the vault exits. MGT’s privacy policy at least names the asset-sale transfer case for its side; his files leave the equivalent case unaddressed.

    Could not verify from public pages (MGT side)

    • The operative broker terms. The appointment agreement, the portal terms, and any terms specific to the MCP/directory channel sit behind the appointment process and are not public. The ownership questions for the quoting channel itself — who owns a submitted ACORD and the data extracted from it, whether it trains models, what happens to submission history when an appointment ends — are therefore unverified: the documents exist but are contract-side, not published. The public website terms and privacy policy were read in full and are silent on each.
    • What the “open MCP” technically is. No public developer documentation, endpoint, tool list, or authentication spec for the MCP was found on the pages read. “Open” is established as a distribution claim (listed in the directories, callable from ChatGPT and Claude), not as published developer access.
    • The second platform’s terms. Data submitted through the ChatGPT (or Claude) surface also passes under OpenAI’s (or Anthropic’s) terms for directory apps. Those terms were not read for this mapping, so the full custody chain of a broker’s submission is unverified at the platform layer.
    • The headline numbers. $83B quoted TIV, “nearly 15,000 appointed agents,” the “A-” AM Best rating, and “first carrier” are MGT’s own claims from its release and site. Trade coverage (GlobalFinTechEdge) narrows “first” to a carrier-specific quoting integration and records that MGT has not disclosed active ChatGPT-channel users, average time saved per quote, or policies bound through the channel.
    • Quote performance. No independent source on how often Aimee’s quotes bind as priced, how her classifications hold up, or how assumption statements read in the live ChatGPT surface (no transcript was available; the one concrete premium — $2,740/yr for a Sacramento bakery BOP — comes from MGT’s own demo video).
    • Athena’s end-to-end underwriting. The claim that an AI underwriting agent decided a case with no human input, “and got it right,” is from MGT’s own essay; no external account exists on the pages read.
    • Whether Aimee identifies herself as an AI in the quoting surfaces. MGT’s essay title and text (“users thank her… most of them not realizing she’s an AI”) describe the website agent; the disclosure behaviour of the ChatGPT/Claude listing itself was not observable from public pages.

    Sources

    • The occasion — Insurance Edge republication of the release (Nov 6, 2026): https://insurance-edge.net/2026/11/06/us-news-mgts-aimee-ai-assistant-now-listed-in-chatgpt-directories/
    • Original release (Business Wire, Nov 5, 2026): https://www.businesswire.com/news/home/20261105657905/en/MGT-Becomes-First-Insurance-Carrier-to-Bring-ChatGPT-Quoting-to-Independent-Agents
    • MGT — first carrier to offer chat-based quoting (three ways to quote; portal review before bind): https://www.mgtinsurance.com/blog/first-carrier-chat-based-quoting-independent-agents
    • MGT — how AI underwriting cuts quote time (Aimee in ChatGPT/Claude/portal; appetite with no sign-in): https://www.mgtinsurance.com/blog/how-ai-underwriting-cuts-quote-time-for-independent-agents
    • MGT — BOP appetite page (300+ classes; states covered/excluded): https://www.mgtinsurance.com/appetite
    • MGT — “The Neo-Insurer Bet” essay (Athena; “They Don’t Know It’s an AI Bot”; the disclosure question): https://www.mgtinsurance.com/blog/the-neo-insurer-bet
    • Trade coverage noting the undisclosed channel metrics and the narrow reading of “first” (GlobalFinTechEdge, Nov 2026): https://globalfintechedge.com/news/mgt-brings-ai-insurance-quoting-assistant-to-chatgpt/
    • InsureWire distribution tracker (Oct 16, 2026 announcement entry): https://insurewire.org/digital-insurer/agents-distribution/
    • Privacy policy (last updated Oct 21, 2026 — read in full; findings quoted above): https://www.mgtinsurance.com/privacy-policy
    • Website terms & conditions (read in full): https://www.mgtinsurance.com/terms-conditions
    • The Wisdom Trust kit and the Wisdom Manager service sketch — Tygart Media working papers; the two earlier mappings in this series are dated October 18 and October 24, 2026.
  • You Learn to Cook When You Have No Money

    You Learn to Cook When You Have No Money

    Stop blaming the token limit

    Every time an AI tool tightens a rate limit, the same crowd shows up to complain about it. The bot got slower. The bot cut me off. The bot won’t let me do what I was doing.

    Here’s a question nobody asks them: what were you doing?

    Because most of the time, the answer is nothing. Testing it. Poking it. Making it write a poem about your cat, summarize a video you were never going to watch, argue with it for forty minutes to see if it breaks. That’s not work. That’s burning reps on stupid shit and then complaining the gym is too small.

    Token limits aren’t the problem. Usage discipline is. And the people crying the loudest about limits are usually the people who never had any.

    Treat it like a gym, or don’t go

    An AI model is either a gym or an expensive tool, depending on how you treat it. It is not a toy.

    You don’t blame the gym because you did curls for three hours and your arms hurt. You show up with a plan. You do the work that’s actually on the program. You rack the weights and you go home. A table saw works the same way — it doesn’t care about your feelings, it rewards the person who measured twice and punishes the one who was playing around near the blade.

    AI is the same. Every session should start with a reason. Every call should buy something: a decision, a draft, a number you can check. If you can’t say what a run bought you, you weren’t working out. You were hanging out at the gym.

    Scarcity is the teacher

    You learn to cook when you have no money.

    When the pantry is almost empty, every ingredient has a job. You stop wasting cuts. You learn what heat actually does. Rich kitchens produce lazy cooks; empty ones produce good ones — if the cook cares enough to learn.

    Tokens are ingredients. When they feel unlimited, people cook like it: giant prompts with no point, five agents doing what one careful prompt would do, whole afternoons spent “exploring.” When every call costs you something — money, quota, time on a clock — your prompts get honest in a hurry.

    I know what mine buy. Last week I shipped a working agent system into a national hackathon on a $153 budget and spent $102.50 of it, every single call logged. This morning a research run I use cost under two cents and came back with a ranked answer I could act on. That’s not being cheap. That’s knowing the price of everything I asked for. Discipline isn’t deprivation — it’s receipts.

    A nearly empty pantry and a cook making a real meal from almost nothing

    The commute is the session

    Here’s how I’d actually run it, and it’s the whole philosophy in one picture.

    Buy a Tesla. Install the bot. Grok lives in the car — and only in the car.

    I live in Puyallup. The day job, the in-office days, are up in Bellevue. That’s a real drive, and a self-driving car turns it into the best office I’ll ever have: nobody interrupts a commute. The drive in is the Jarvis session. Run the side businesses. Clear the decisions that piled up overnight. Plan the day out loud while the car does the driving. If Tony Stark had ever given Pepper a suit, this is what she’d have done with the flight time — run the company from inside it.

    The drive home is the debrief. What got done, what’s open, what’s tomorrow. Then the car parks, and the session is over.

    You don’t sit in your car in the driveway and watch the football game. You go in your house.

    That’s the part people miss. The commute works as a session because it ends. Forty-five minutes of total focus with a wall around it beats nine hours of AI open in a tab while you half-watch your life go by. Sparingly isn’t a restriction. Sparingly is the design.

    A car parked in a driveway at dusk while the driver walks toward a warm-lit house

    Stop testing it like a macro

    And stop testing AI like it’s just a macro. This shit is more than that.

    A macro does the same thing every time and tells you nothing. Poking a model with toy questions tells you what it does in a toy situation, and then people act surprised when production behaves differently. You learn a tool by putting weight on it — real work, real stakes, a customer on the other end of the output. Every real thing I’ve learned about these systems, I learned from a run that mattered, under a limit that forced me to mean it.

    So no, the rate limit isn’t stealing your productivity. It’s offering you a program. Most people just don’t want to train.

    The limit is the workout

    Here’s the whole thing in one line: the limit isn’t the wall. The limit is the workout.

    The people who learn to cook with nothing in the pantry end up eating better than the people with a full fridge and no discipline — because skill compounds and quota doesn’t. Give the disciplined operator a bigger limit later and it’s terrifying. Give the complainer a bigger limit today and he’ll just run out faster, louder.

    Buy the car. Install the bot. Use the drive. Then go in the house.


    More from the operator desk: Slack Is the Last Mile — the hopper, and why the last step of every system is a person. And if you want the receipts live: I’m teaching the citation system behind all of this in a free session series, November 9–17 — the AEO sessions hub has the schedule and the question form.

  • Storm Updates: Quiet Pulse — Nov 6 Morning

    Storm Updates: Quiet Pulse — Nov 6 Morning

    Tropical: None · Severe: None · Flood: Quiet

    What Changed

    • Compared with the November 5 afternoon desk pulse table (quiet-pulse-2026-11-05-afternoon: Tropical: None · Severe: None · Flood: Quiet) and this morning’s earlier version: SPC Day 1 Convective Outlook (0100 UTC November 6 / 0700 PM CST Thursday November 5 2026 by Lyons, valid 060100Z–061200Z) continues “NO SEVERE THUNDERSTORM AREAS FORECAST.” Severe storms remain unlikely tonight. No upgrade to Slight or higher. No convective watches or mesoscale discussions valid.
    • WPC Day 1 Excessive Rainfall Outlook (updated 0020 UTC November 6 / discussion 725 PM EST November 5 by Bann, valid 01 UTC Nov 06–12 UTC Nov 06) continues to show the probability of rainfall exceeding flash flood guidance less than 5 percent nationally. Prior Marginal areas closed. No Moderate or higher.
    • National Weather Service Flood Watch remains in effect for portions of southeastern Massachusetts and Rhode Island from late tonight through Saturday morning for potential 2–4 inches of rain with isolated higher amounts. Residual river Flood Warnings continue elsewhere (e.g., Missouri). High Wind and Freezing Spray Warnings in Alaska. No active flash flood warnings elevating the national Day 1 lane. Prior Georgia FFW remains expired.
    • Tropical lane remains None. National Hurricane Center confirms no tropical cyclones in the Atlantic, Caribbean, or Gulf of America as of 100 AM EST Friday November 6. No tropical storm or hurricane watch or warning on the U.S. coast or Gulf. A non-tropical low south of Bermuda continues with low-to-medium chance of acquiring subtropical characteristics while moving east; no U.S. land threat.
    • Nothing moved into Slight or higher on SPC Day 1 or Moderate or higher on WPC ERO. Quiet Pulse criteria hold. Day 2 Outlook (1730 UTC November 5) holds Marginal Risk for eastern Carolinas and southeast Virginia Friday, outside this Day 1 window. Isolated non-severe thunderstorms possible overnight from Mid-Atlantic into southern New England and Carolinas with the front, but no severe probabilities.

    Live Status

    As of the morning desk on Friday, November 6, 2026 (evening confirmation approximately 9:15 PM PST November 5 / 05:15 UTC November 6), the national picture remains a Quiet Pulse. The Storm Prediction Center’s latest Day 1 Convective Outlook states: “NO SEVERE THUNDERSTORM AREAS FORECAST. Severe storms remain unlikely tonight.” Isolated thunderstorms are possible later tonight from the Mid-Atlantic region northward into southern New England and southward into the Carolinas ahead of a weak front, with strong winds aloft but limited near-surface buoyancy. No severe risk areas drawn. No watches currently valid. Homepage confirms Day 1 No Severe; Day 2 Marginal for eastern Carolinas and southeast Virginia.

    WPC Day 1 ERO confirms no excessive rainfall areas of note. Probability of exceeding flash flood guidance is under 5 percent nationally. Residual showers and thunderstorms may occur along the eastern front, but no organized flood threat on Day 1. NWS national products include the Flood Watch for MA/RI and routine marine and winter advisories elsewhere. None elevate the national severe or flood lanes above Quiet.

    Pulse Table

    LaneStatusNotes (as of ~9:15 PM PST Nov 5 / 05:15 UTC Nov 6 2026)
    TropicalNoneNo tropical cyclones in the Atlantic, Caribbean, or Gulf. NHC: no active systems. Non-tropical low south of Bermuda low/medium chance subtropical characteristics, moving east; no U.S. coastal or Gulf watches or warnings.
    SevereNoneSPC Day 1 (0100Z Nov 6): NO SEVERE THUNDERSTORM AREAS FORECAST. Severe storms unlikely tonight. No watches valid. Isolated non-severe storms possible Mid-Atlantic to Carolinas. Day 2 Marginal eastern Carolinas/SE VA.
    FloodQuietWPC Day 1 ERO: probability of exceeding flash flood guidance <5%. Prior Marginals closed. Flood Watch MA/RI for Friday into Saturday. Residual local Flood Warnings do not elevate national Day 1 lane.

    Rising Queries

    Trends unreachable this run. No invented queries.

    Restoration Read

    No open restoration ticket. No organized severe wind, tornado, or widespread flooding indicated on current Day 1 products. Prior Southeast Marginal and north Georgia flash flood warning remain closed. Residual isolated thunderstorms may produce brief gusty winds or localized heavy rain overnight along the eastern front, but nothing at the level that drives a damage claim under Quiet Pulse criteria. Flood Watch for southeastern New England signals a Day 2 concern. Monitor routine weather.gov updates for any local evolution.

    What This Is Not

    This is a Quiet Pulse. Nothing at SPC Slight or above. No WPC ERO Moderate or above. No tropical storm or hurricane watch or warning on the U.S. coast or Gulf. This desk summarizes public products from the Storm Prediction Center, Weather Prediction Center, National Weather Service, and National Hurricane Center.

    Informational only — not an official warning. Always check weather.gov for local forecasts and warnings. Turn around, don’t drown.

  • IICRC Certification: What It Is, How to Get It, and What It Costs

    IICRC Certification: What It Is, How to Get It, and What It Costs

    Last verified: November 5, 2026 (Pacific), against IICRC’s own published pages. Fees and rules below are IICRC’s; course tuition is set separately by approved schools and varies.

    Direct answer: IICRC certification is a professional credential for cleaning, inspection, and restoration technicians, issued by the IICRC — the Institute of Inspection, Cleaning and Restoration Certification, a nonprofit standards body. You earn one by taking an IICRC-approved course and passing the IICRC exam for that category. The exam fee is $80 for most certifications ($150 for AMRT and the inspection exams), the passing score is 75%, and certification stays active through an annual renewal fee plus 14 continuing education hours every four years (every two years for Master and Inspector certifications). The entry credential for water work is WRT (Water Damage Restoration Technician), which has no prerequisites.

    What IICRC certification is

    The IICRC does two jobs. It writes the industry’s standards — the ANSI/IICRC S500 for professional water damage restoration is the best known — and it certifies the technicians who work to those standards. A certification means the holder sat through an approved course in that category and passed a proctored exam on it. The certification belongs to the person, not the company: a technician who changes employers takes the card with them.

    One boundary worth stating plainly: IICRC certification is a private professional credential, not a government license. Some states separately license specific work, mold remediation especially. The card and the license are different things, and holding one does not give you the other.

    The main certifications

    The IICRC certifies across cleaning, inspection, and restoration, but the restoration core is a short list. Courses run one to five days depending on the category, in person or by live stream.

    Certification What it covers Prerequisite
    WRT — Water Damage Restoration Technician Water damage, its effects, and techniques for drying structures: water categories and classes, extraction, and drying science. The entry point for water work. None
    ASD — Applied Structural Drying Technician Advanced drying of structures after water damage, beyond the WRT foundation. WRT
    AMRT — Applied Microbial Remediation Technician Mold and sewage remediation. Four-day course; the exam fee is $150, not $80. WRT
    FSRT — Fire and Smoke Restoration Technician Fire and smoke damage restoration. None
    OCT — Odor Control Technician Odor sources and deodorization. A one-day course. None
    HST — Health and Safety Technician Health and safety practice on restoration and remediation jobs. None
    CPT — Contents Processing Technician Packing, handling, and processing of contents after a loss. None

    Beyond the technician list sit two different kinds of credential. MRS (Mold Remediation Specialist) is experience-based rather than course-based: no class, but twelve months of verifiable mold remediation field work, then a 100-question exam with a 79% pass mark. It runs on a two-year term instead of the annual one. And the Master designations — Master Water Restorer, Master Fire and Smoke Restorer, and Master Textile Cleaner — are tracks earned over time by stacking the required certifications and years of certified service. Master Water Restorer, for example, requires WRT, ASD, AMRT, HST, and a carpet-side certification, plus at least three consecutive years as an IICRC-certified technician. Holding all three Master designations is the Triple Master.

    How to get certified

    1. Pick the certification. For water work, that means WRT first — it has no prerequisites, and it is the required prerequisite for ASD and AMRT.

    2. Take the course at an IICRC-approved school. Only approved schools and instructors can deliver certification courses. Courses run in person and by live stream; you must attend every day in full, or you forfeit eligibility.

    3. Register for the exam and pay IICRC’s exam fee. $80 for most certifications, $150 for AMRT and inspection exams, paid to the IICRC — separate from the school’s tuition.

    4. Sit the exam. In-person students test on the last day of class. Live-stream students test through the IICRC Online Exam Portal, within 45 days of the course’s last day. The passing score is 75%. If you fail, you get two retest opportunities within 45 days of the exam date, at the same fee.

    5. Wait for processing. Certification processing takes four to six weeks from exam completion, and the certificate mails seven to ten business days after that.

    What it costs

    Three separate costs, paid to two different places. Course tuition goes to the approved school and varies by school and category. The exam fee goes to the IICRC: $80 per exam, $150 for AMRT and inspection exams, and retests cost the same as the first attempt. The annual renewal fee keeps the certification active afterward; it is billed per technician based on the number and type of certifications held — IICRC’s own examples run $46 to $58 a year.

    Keeping it: renewal and continuing education

    Certification is not permanent. Renewal is annual and required — let it lapse and the credential is no longer active. Alongside the fee, certified technicians must complete 14 CECs (continuing education credit hours) every four years. Master and Inspector certifications run a faster clock: 14 CECs every two years. CECs come from approved courses, live-stream certifications taken for credit, and industry events, and the technician is responsible for submitting the documentation. A lapsed certification is not gone forever: expired less than 24 months, you request a renewal invoice; past 24 months, reinstatement goes through a separate process and may carry added fees.

    Certified Firm: the company-level credential

    Individuals hold certifications; companies hold Certified Firm status. A Certified Firm needs current liability insurance, at least one active Certified Technician on staff, and a completed application. The application fee is $25 plus a prorated amount, and renewal is $199 a year. Each business location must qualify separately, with its own certified technician who is not listed for another location — and because certifications follow the person, a firm whose one certified technician leaves loses the basis for its status until another is on staff.

    What the card is worth in pay

    The basics above are what the credential is. What it pays is a separate, measurable question — and the honest measured answer is more interesting than the brochure one. We priced IICRC certifications against real restoration job postings, held role and city still, and published the full dataset: the pay premium is a wide interval around zero for the common cards, which is exactly why the method matters more than the slogan. The study: What an IICRC Card Is Worth, Measured. Field companions: the IICRC Van Pocket Card and IICRC S500 in the Van.

    Frequently asked questions

    What does IICRC stand for? Institute of Inspection, Cleaning and Restoration Certification — a nonprofit organization for the inspection, cleaning, and restoration industries. It develops standards, including the ANSI/IICRC S500, and certifies technicians who complete its approved courses and exams.

    How much does IICRC certification cost? Course tuition is set by the approved school and varies. On top of tuition, the IICRC exam fee is $80 for most certifications and $150 for AMRT and inspection exams; retests cost the same. Keeping the certification active costs an annual renewal fee, billed by the number and type of certifications you hold.

    How long does it take to get IICRC certified? The course itself runs one to five days depending on the certification — WRT is three days. After you pass the exam, certification processing takes four to six weeks, and the certificate mails seven to ten business days after processing.

    Do IICRC certifications expire? Yes. Technician certifications renew every year, with an annual fee and 14 continuing education hours due every four years; Master and Inspector certifications need their 14 hours every two years. A certification that passes its renewal is not active until renewed or reinstated.

    What is the first IICRC certification to get? WRT — Water Damage Restoration Technician. It has no prerequisites, covers the foundations of water damage and drying, and is the required prerequisite for the advanced water certifications, ASD and AMRT.

    Is IICRC certification a license? No. It is a private professional credential, not a state license. Some states license mold remediation and similar work separately; an IICRC card does not substitute for a required state license.

    Sources: IICRC FAQs and the IICRC WRT certification page (iicrc.org), retrieved November 5, 2026. Fees and requirements are IICRC’s and can change; confirm on iicrc.org before registering.

  • Storm Updates: Quiet Pulse — Nov 5

    Storm Updates: Quiet Pulse — Nov 5

    Tropical: None · Severe: None · Flood: Quiet

    What Changed

    • Compared with this morning’s pulse table (quiet-pulse-2026-11-05-morning: Tropical: None · Severe: None · Flood: Quiet): SPC Day 1 Convective Outlook (0100 UTC November 6 / 0700 PM CST Thursday November 5 2026 by Lyons, valid 060100Z–061200Z) continues “NO SEVERE THUNDERSTORM AREAS FORECAST.” Severe storms remain unlikely tonight. Prior Southeast Marginal remains closed. No convective watches or mesoscale discussions valid.
    • WPC Day 1 Excessive Rainfall Outlook (updated 0020 UTC November 6 / discussion 725 PM EST November 5 by Bann, valid 01 UTC Nov 06–12 UTC Nov 06) continues to show the probability of rainfall exceeding flash flood guidance less than 5 percent nationally. Prior Marginal areas closed. No Moderate or higher.
    • National Weather Service Flash Flood Warning for Fannin, Gilmer, northwestern Union, and Murray Counties in north-central Georgia remains expired. No active flash flood warnings of note on the CONUS severe or flood lanes. A Flood Watch remains in effect for parts of Massachusetts and Rhode Island. Residual Flood Warnings persist on some western rivers.
    • No tropical storm or hurricane watch or warning on the U.S. coast or Gulf. NHC confirms no tropical cyclones in the Atlantic, Caribbean, or Gulf of America. A broad non-tropical low a few hundred miles south of Bermuda holds a low (30%) chance through 48 hours and medium (40%) through 7 days of acquiring subtropical characteristics while moving slowly eastward; no U.S. land threat.
    • Nothing moved into Slight or higher on SPC or Moderate or higher on WPC ERO. Quiet Pulse criteria hold. Isolated stronger wind gusts possible overnight in DelMarVa into southern NY/NJ with fast-moving storms, but no severe probabilities.

    Live Status

    As of the afternoon desk on Thursday, November 5, 2026 (approximately 9:17 PM PST / 05:17 UTC November 6), the national picture remains a Quiet Pulse. The Storm Prediction Center’s latest Day 1 Convective Outlook states: “NO SEVERE THUNDERSTORM AREAS FORECAST. Severe storms remain unlikely tonight.” Isolated thunderstorms remain possible this evening and overnight from the Mid-Atlantic into southern New England and the Carolinas ahead of a weak front. Strong winds aloft will produce fast-moving storms, but near-surface buoyancy remains limited; the surface-based threat and risk of damaging winds is low. Occasional stronger gust possible overnight across DelMarVa into southern NY/NJ. No organized severe threat. No mesoscale discussions in effect.

    WPC Day 1 holds no excessive rainfall risk areas. The overnight Flash Flood Warning in north Georgia has expired. Residual runoff or minor urban ponding is possible where earlier heavy rain fell, but no widespread flash flood threat remains on Day 1. No tropical component.

    Hotspots

    Mid-Atlantic into southern New England and Carolinas: Isolated thunderstorms possible this evening into overnight along and ahead of the front. Fast-moving cells under strong winds aloft, limited surface-based threat after dark. Occasional gusty winds possible; no severe area. Flood Watch active for portions of MA/RI. Day 2 WPC carries a Slight Risk of excessive rainfall across parts of southeastern New England.

    Southern Kansas / northern Oklahoma residual: Scattered elevated thunderstorms earlier under a mid-level shortwave. Elevated nature limited surface severe potential. No risk area remains.

    North-central Georgia residual: Prior Flash Flood Warning expired. Ocoee River and surrounding terrain saw heavy overnight rain; monitor for lingering high water on roads and small streams. No active warning.

    Just Hit

    Overnight into early Thursday: Flash Flood Warning and localized flooding in north-central Georgia (Fannin, Gilmer, Union, Murray Counties) from thunderstorms producing 1–2 inches per hour. Some reports of high water and impacts along the Georgia-Tennessee line. Activity has ended; warning expired. Local wind reports (trees, wires) in the Mid-Atlantic with the frontal passage.

    Pulse Table

    LaneStatusNotes (as of ~9:17 PM PST / 05:17 UTC Nov 6 2026)
    TropicalNoneNo tropical cyclones in the Atlantic, Caribbean, or Gulf. NHC: low (30% 48h) to medium (40% 7d) chance for western/central Atlantic non-tropical low to acquire subtropical characteristics, moving east; no U.S. coastal or Gulf watches or warnings.
    SevereNoneSPC Day 1 (0100Z Nov 6): NO SEVERE THUNDERSTORM AREAS FORECAST. Prior Southeast Marginal closed. Isolated storms possible Mid-Atlantic/New England. No watches or MDs valid. Occasional stronger gust possible overnight DelMarVa/NY/NJ only.
    FloodQuietWPC Day 1 ERO: probability of exceeding FFG less than 5 percent. Prior Marginal areas closed. Georgia FFW expired. Flood Watch MA/RI. No active CONUS flash flood warnings of note. Residual minor runoff possible. Day 2 Slight Risk SE New England.

    Rising Queries

    Trends unreachable this run. No invented queries.

    Restoration Read

    Quiet Pulse. Primary residual ticket is minor water intrusion or high water on roads from the expired north Georgia Flash Flood Warning and earlier Southeast rainfall, plus isolated tree/wire work from frontal winds in the Mid-Atlantic. No organized severe damage expected. No tropical component. Monitor local NWS for any lingering advisories and the Day 2 Slight flood risk in southeastern New England. Turn around, don’t drown.

    What This Is Not

    This is a Quiet Pulse. No SPC Slight or higher severe risk on the latest Day 1 outlook. No WPC Moderate or higher excessive rainfall on Day 1. No tropical storm or hurricane watch or warning on the U.S. coast or Gulf. This desk summarizes public products from the SPC, WPC, NWS, and NHC.

    Looking Ahead

    Day 2 WPC Excessive Rainfall Outlook carries a Slight Risk across parts of southeastern New England (Rhode Island into southeastern Massachusetts). Rain continues from the Northeast to the Southeast into Friday. No severe areas expected on Day 1. Monitor for potential flood concerns in New England overnight into Friday.

    Sources

    Official products: Storm Prediction Center (Day 1 Outlook 0100 UTC November 6), Weather Prediction Center (Day 1 Excessive Rainfall Outlook and discussion ~725 PM EST November 5), National Weather Service (watches, warnings, and advisories), National Hurricane Center (Atlantic quiet). Previous desk: quiet-pulse-2026-11-05-morning.

    Disclaimer: This is a summary of official public products from the Storm Prediction Center, Weather Prediction Center, National Weather Service, and National Hurricane Center. Always consult the latest official forecasts and warnings for your location. This desk does not issue warnings. Turn around, don’t drown.

  • Rings in the Sky

    Rings in the Sky

    The pushback against Stampede stopped being general this week. Two separate modeling efforts now name Cowboy’s design, with numbers attached, and I think that gives your desk something it did not have before.

    The first is a preprint called “Rings in the Sky” from astronomers Aaron Boley, Samantha Lawler, and Hanno Rein, reported on November 3. Working from what Cowboy filed, they put Stampede’s solar array at about 4,800 square metres. For scale, the International Space Station’s array is roughly 2,250, so Cowboy’s implied array is more than twice that size, and across the designs they modeled, the unmitigated result could leave about 100 times more visible satellites than stars in the sky at some hours. I would carry their caveat with that number every time. The filings are mostly narrative, so the authors had to fill in the rest themselves and treat each satellite as a reflective sphere, which means brightness could land higher or lower.

    The regulatory part matters. The American Astronomical Society has already asked the FCC to deny SpaceX’s application, and its concerns extend to Cowboy’s filing, and no Cowboy brightness plan surfaced in what I read.

    The second model is about debris, from Hugh Lewis at the University of Birmingham. He found Stampede crosses a runaway line if its satellites are Starlink-sized, meaning its own breakups would make fragments faster than they clear away, and it is unstable instead if they are smaller, Kuiper-sized. Which branch applies is still open, because Cowboy’s reported unit size points toward the larger branch but has never been verified against the filing itself. Lewis also calls his own model optimistic, since it tests each constellation alone and assumes collision avoidance works perfectly.

    Smaller refinements came too, including Cowboy calling its launch sites Trailheads and a liftoff mass around 820 tonnes. Nothing has changed on the beam, though. There is still no Reason-1 result, and the November window for a first attempt is still open. I will keep watching for that first, because a real beam result would change this conversation faster than either model.

    — Glint