Tag: Tygart Media

  • Corpus Contributor Model: Build an AI Knowledge Flywheel

    Corpus Contributor Model: Build an AI Knowledge Flywheel

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    The most interesting business models don’t just sell to customers. They turn customers into the product’s engine. There’s a version of this in every category — the marketplace that gets better as more buyers and sellers join, the review platform that gets more useful as more people leave reviews, the map that gets more accurate as more drivers report conditions. Network effects are well understood. But there’s a quieter version of this dynamic that almost nobody is building yet, and it may be more valuable than the classic network effect in the AI era.

    Call it the corpus contributor model. The customer who pays for access to your knowledge base also happens to be a practitioner in the exact domain your knowledge base covers. They use the product. They notice what it gets wrong. They have opinions about what’s missing. And if you build the right mechanic, they can feed those observations back into the corpus — making it more accurate, more complete, and more current than you could ever make it by yourself.

    This is not a theoretical model. It’s a specific architectural decision with specific business implications. And most AI knowledge product builders are missing it entirely.

    What the Corpus Contributor Flip Actually Is
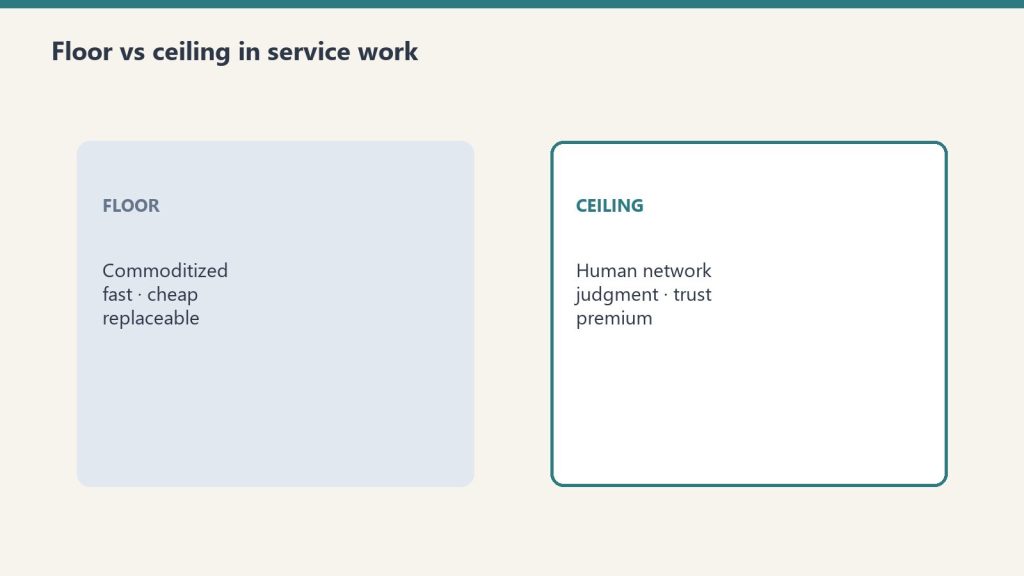
    Floor versus ceiling cards for commoditized work and human-network premium
    What the corpus contributor flip actually is.

    The standard model for a knowledge API product looks like this: you extract knowledge from practitioners, structure it, and sell access to it. The customer is a buyer. The knowledge flows one direction — from your corpus into their AI system. You maintain the corpus. They consume it. Revenue comes from subscriptions.

    The corpus contributor model adds a second flow. The customer — who is themselves a practitioner — also has the option to contribute validated knowledge back into the corpus. Their contribution improves the product for every other customer. In exchange, they get something: a lower subscription rate, a named credit in the corpus, early access to new verticals, or simply a better product faster than the passive subscriber would get it.

    The word “flip” matters here. You are not just adding a feature. You are reframing who the customer is. They are not only a consumer of knowledge. They are simultaneously a source of it. The relationship is bilateral. That changes the economics, the product roadmap, the sales conversation, and the defensibility of the whole business in ways that compound over time.

    Why This Is Different From Crowdsourcing

    The immediate objection is that this sounds like crowdsourcing, which has a complicated track record. Wikipedia works. Most other crowdsourced knowledge projects don’t. The reason Wikipedia works at scale and most others don’t comes down to one thing: intrinsic motivation. Wikipedia contributors edit because they care about the topic. There’s no transaction.

    The corpus contributor model is not crowdsourcing and should not be designed like it. The distinction is selection and validation.

    Selection: You are not asking the general public to contribute. You are asking paying subscribers who have already demonstrated that they operate in this domain by the fact of their subscription. A restoration contractor who pays $149 a month for access to a restoration knowledge API has self-selected into a group with genuine domain expertise and a financial stake in the quality of the product. That is a fundamentally different contributor pool than an open wiki.

    Validation: Contributor submissions don’t go directly into the corpus. They go into a validation queue. Every submission is reviewed against existing knowledge, cross-referenced against standards where they exist, and flagged for expert review when there’s conflict. The contributor model doesn’t replace the extraction and validation process — it feeds it. Contributors surface what’s missing or wrong. The validation layer decides what actually enters the corpus.

    This is closer to the model used by high-quality technical reference databases than to Wikipedia. The contributors are domain insiders with a stake in accuracy. The editorial layer maintains quality. The corpus improves faster than it could with internal extraction alone.

    The Flywheel
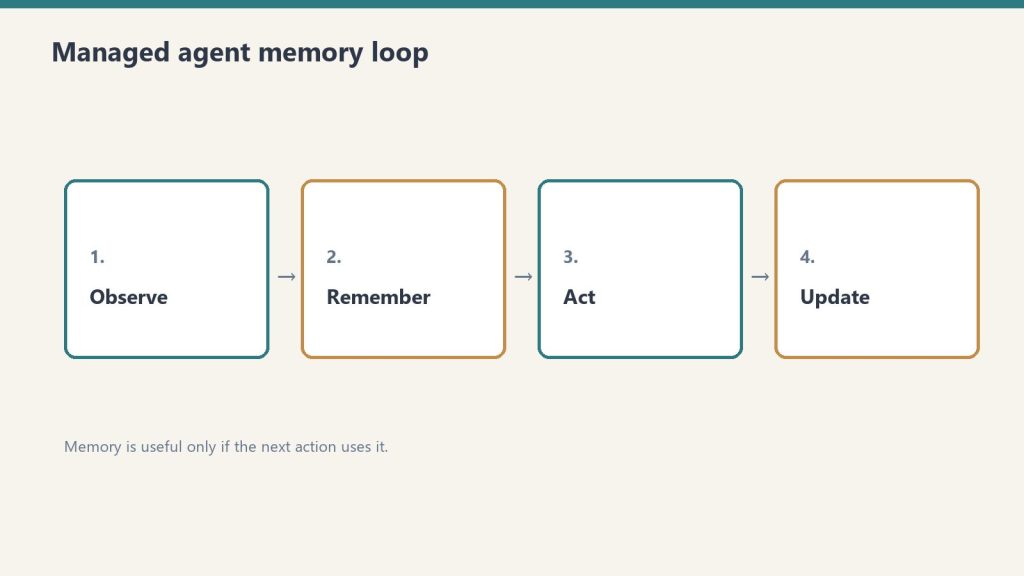
    Four-step loop: observe, remember, act, update for managed agents
    The flywheel.

    Here is where the model gets genuinely interesting. Every traditional subscription business has a churn problem. The customer pays monthly. They evaluate monthly whether the product is worth it. If nothing changes, their willingness to pay is roughly static. The product has to justify itself again and again against a customer whose needs are evolving.

    The corpus contributor model changes this dynamic in two ways that reinforce each other.

    First, contributors have a personal stake in the corpus that passive subscribers don’t. If you submitted three validated knowledge chunks about LGR dehumidification performance in high-humidity climates, and those chunks are now in the corpus being used by other contractors and by AI systems that serve your industry, you have a relationship with that corpus that is qualitatively different from someone who just queries it. You built part of it. Your churn rate is lower because leaving the product means leaving something you helped create.

    Second, the corpus gets better as contributors engage. A better corpus is worth more to new subscribers, which brings in more potential contributors, which improves the corpus further. This is a flywheel, not just a retention mechanic. The passive subscriber benefits from the contributor’s work. The contributor gets a better product to work with. New subscribers join a product that is measurably more accurate and complete than it was six months ago. The value proposition strengthens over time without requiring proportional increases in internal extraction cost.

    Compare this to a standard knowledge API where the corpus is maintained entirely internally. The corpus improves at the rate of your internal extraction capacity. If you can run four extraction sessions a month, you add roughly four sessions’ worth of new knowledge per month. With contributors, that rate is multiplied by however many qualified practitioners are actively engaged. The internal team still controls quality through the validation layer. But the input volume grows with the customer base rather than with internal headcount.

    The Enterprise Version

    Individual contributors are valuable. Enterprise contributors are transformative.

    Consider a restoration software company that builds job management tools for contractors. They have access to millions of completed job records — real-world data on what drying protocols were used on what loss categories in what climate conditions, with what outcomes. That data, properly structured and validated, is worth dramatically more to a restoration knowledge corpus than anything extractable from individual interviews.

    The standard sales conversation with that company is: “Pay us $499 a month for API access.” That’s fine. It’s a transaction.

    The corpus contributor conversation is different: “We want to build the knowledge infrastructure that makes your product’s AI features better. You have data we need. We have a structured corpus and a validation layer you’d spend years building. Let’s make the corpus jointly better and share the value.” That’s a partnership conversation. It changes the deal size, the relationship depth, and the defensibility of the resulting product — because the enterprise contributor’s data is now embedded in a corpus they can’t easily replicate by going to a competitor.

    Enterprise corpus contributors also create a named knowledge layer opportunity. The restoration software company’s contributed data doesn’t disappear into an anonymous corpus — it’s credited, tracked, and potentially sold as a named vertical: “Job outcome data layer, contributed by [Partner].” That attribution has marketing value for the contributor and validation signal for the subscribers who use it. Everyone’s incentives align.

    What the Sales Conversation Becomes

    The corpus contributor model changes the initial sales conversation in a way that most knowledge product builders miss because they’re too focused on the subscription tier.

    The standard pitch leads with access: “Here’s what you can query. Here’s the price.” That’s a cost-benefit conversation. The prospect weighs whether the knowledge is worth the fee.

    The contributor pitch leads with participation: “You know things we need. We have infrastructure you’d spend years building. Join as a contributor and help shape the corpus your AI stack runs on.” That’s a different conversation entirely. It’s not about whether the existing product justifies its price — it’s about whether the prospect wants to have a role in what the product becomes.

    For practitioners who care about their industry’s AI infrastructure — and in most verticals, there are a meaningful number of these people — the contributor framing is more compelling than the subscriber framing. It gives them agency. It makes them a participant in something larger than a software subscription. That is a qualitatively different reason to write a check, and it is stickier than feature value alone.

    The Validation Layer Is the Business
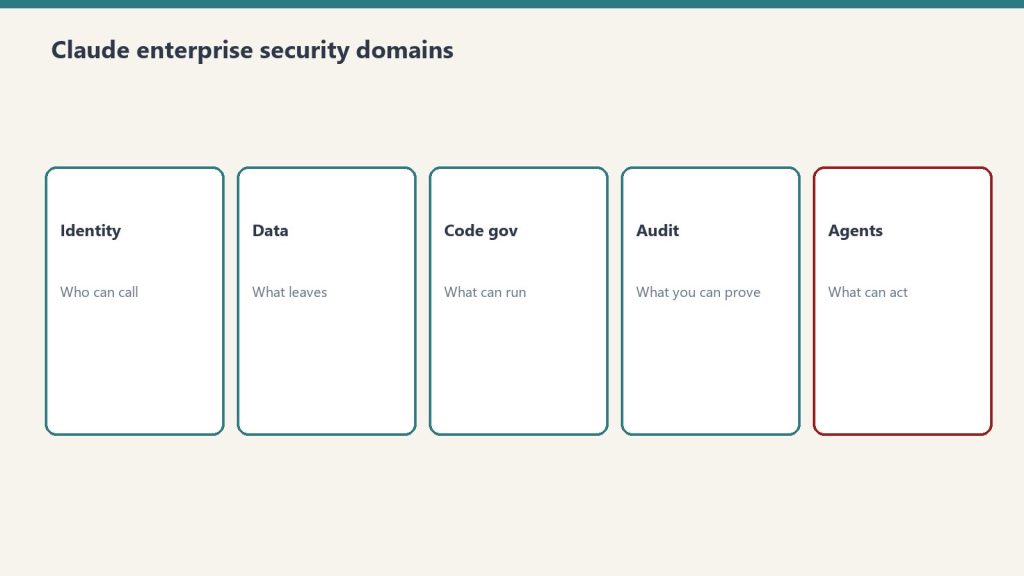
    Five security domains: identity, data, code governance, audit, agents
    The validation layer is the business.

    Everything described above depends on one thing working correctly: the validation layer. If contributors can inject bad knowledge into the corpus, the product becomes unreliable. If the validation layer is so restrictive that nothing gets through, the contributor mechanic produces no value. The design of the validation layer is where the real intellectual work of the corpus contributor model lives.

    A well-designed validation layer has three properties. It is domain-aware — it knows enough about the field to evaluate whether a contribution is plausible, consistent with existing knowledge, and meaningfully different from what’s already there. It is conflict-surfacing — when a contribution contradicts existing corpus entries, it flags the conflict for expert review rather than silently accepting or rejecting either. And it is contributor-transparent — contributors can see the status of their submissions, understand why something was accepted or rejected, and engage in a dialogue about contested points.

    The validation layer is also the moat that a competitor can’t easily replicate. Building a corpus takes time. Building relationships with contributors takes time. But building the domain expertise required to run a validation layer that practitioners trust — that takes the longest. It’s the part of the business that scales slowest and defends best.

    Who Should Build This First

    The corpus contributor model is available to any knowledge product company that has, or can develop, three things: a practitioner customer base with genuine domain expertise, an extraction and validation infrastructure that can process contributions at volume, and the product design capability to build a contribution mechanic that practitioners actually use.

    In the restoration industry, the conditions are nearly ideal. The customer base — contractors, adjusters, estimators, project managers — has deep domain knowledge and a direct financial interest in AI tools that work correctly. The knowledge gaps are enormous and well-understood. And the trust infrastructure, built through trade associations, peer networks, and industry events, already exists as a substrate for the kind of relationship-based contributor model that works at scale.

    The first knowledge product company in any vertical to implement the corpus contributor model well will have an advantage that is very difficult to replicate. Not because their technology is better. Because they turned their customers into co-authors of the most defensible asset in vertical AI.

    Related on Tygart Media: jobs as knowledge base · information density · GEO tactics.

    Frequently Asked Questions

    What is the corpus contributor model in AI knowledge products?

    The corpus contributor model is a product architecture where paying customers — who are domain practitioners — also have the option to contribute validated knowledge back into the product’s knowledge base. This creates a bilateral relationship where the customer is both a consumer and a source of knowledge, improving the corpus faster than internal extraction alone could achieve.

    How is this different from crowdsourcing?

    The corpus contributor model differs from crowdsourcing in two critical ways: selection and validation. Contributors are self-selected domain practitioners who pay for access, not anonymous volunteers. And contributions pass through a structured validation layer before entering the corpus — they don’t go in automatically. This makes it closer to a high-quality technical reference database model than an open wiki.

    Why does the corpus contributor model reduce churn?

    Contributors develop a personal stake in the corpus that passive subscribers don’t have. Having built part of the product, contributors are less likely to cancel because leaving means leaving something they helped create. Additionally, active contributors see the corpus improving in response to their input, which reinforces the value they’re receiving beyond passive access.

    What makes enterprise corpus contributors particularly valuable?

    Enterprise contributors — such as software companies with large volumes of structured job outcome data — can contribute knowledge at a scale and quality that individual extraction sessions can’t match. Their data also creates a named knowledge layer opportunity: credited, tracked contributions that signal validation quality to other subscribers and create a partnership relationship that is significantly stickier than a standard subscription.

    What is the validation layer and why does it matter?

    The validation layer is the quality control system that evaluates contributor submissions before they enter the corpus. It must be domain-aware enough to assess plausibility, conflict-surfacing when contributions contradict existing knowledge, and transparent enough that contributors understand how their submissions are evaluated. The validation layer is also the hardest component to replicate, making it the deepest competitive moat in the model.

  • AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    Tygart Media Strategy
    Volume Ⅰ · Issue 04 Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    The extraction layer is the part of the AI economy that doesn’t exist yet — and it’s the only part that can’t be automated into existence. Every vertical AI product, every industry-specific chatbot, every AI assistant that actually knows what it’s talking about requires one thing that nobody has figured out how to manufacture at scale: the deep, tacit, hard-won knowledge that lives inside experienced human practitioners.

    This is not a gap that will close on its own. It is a structural feature of how expertise works. And for the businesses and individuals who understand it clearly, it is the single most durable competitive advantage available in the current AI era.

    What the Extraction Layer Actually Is

    Floor versus ceiling cards for commoditized work and human-network premium
    What the extraction layer actually is.

    When people talk about AI knowledge gaps, they usually mean one of two things: either the model hasn’t been trained on recent data, or the model lacks access to proprietary databases. Both of those are real problems. Neither of them is the extraction layer problem.

    The extraction layer problem is different. It’s the gap between what an experienced practitioner knows and what has ever been written down in a form that any AI system — regardless of its training data or database access — can actually use.

    A 30-year restoration contractor who has dried 2,000 structures knows things that have never been documented anywhere. Not because they were keeping secrets. Because the knowledge is embedded in judgment calls, pattern recognition, and muscle memory that wasn’t worth writing down at the time. They know which psychrometric conditions in a basement after a Category 2 loss require an LGR versus a conventional dehumidifier, and why. They know the exact moment a water damage job transitions from “drying” to “reconstruction” based on a combination of readings and smells and wall flex that no textbook captures. They know which insurance adjusters will fight a mold scope and which ones will approve it without a second look.

    None of that knowledge is in any training dataset. None of it will be in any training dataset until someone does the hard, slow, relationship-dependent work of pulling it out of people’s heads and putting it into structured form.

    That is the extraction layer. And it requires humans.

    Why AI Cannot Close This Gap By Itself

    Three stacked layers: chat UI, tools, agent runtime
    Why AI cannot close this gap by itself.

    The reflex response to any knowledge gap problem in 2026 is to propose an AI solution. Train a bigger model. Scrape more data. Use retrieval-augmented generation with a larger corpus. There is genuine value in all of those approaches. None of them solves the extraction layer problem.

    The issue is not volume or recency. The issue is source availability. Training data and RAG systems can only work with knowledge that has been externalized — written, recorded, structured, published somewhere that a crawler or an ingestion pipeline can reach. Tacit expertise, by definition, hasn’t been externalized. It exists as neural patterns in someone’s head, not as tokens in a document.

    There are things AI can do well that partially address this. AI can synthesize patterns from large volumes of existing text. It can identify gaps in documented knowledge by mapping what questions get asked versus what answers exist. It can transcribe and structure interviews once they’ve been recorded. But AI cannot conduct the interview. It cannot build the relationship that earns the trust required to get a 25-year adjuster to walk through their actual decision logic on a contested mold claim. It cannot recognize, in the middle of a conversation, that the contractor just said something technically significant that they treated as throwaway context.

    The extraction process requires a human who understands the domain well enough to know what they’re hearing, has the relationship to access the right people, and has the patience to do this work over months and years rather than in a single API call. That is not a temporary limitation of current AI systems. It is a structural property of how tacit knowledge works.

    The Pre-Ingestion Positioning

    There is a second reason the extraction layer matters beyond the knowledge itself: where in the AI stack you sit determines your liability exposure, your defensibility, and your pricing power.

    Most businesses that try to participate in the AI economy position themselves downstream of AI processing — they modify outputs, review generated content, add a human approval layer on top of AI decisions. That positioning puts them in the output chain. When something goes wrong, they are implicated. The AI said it, but they delivered it.

    The extraction layer positions you upstream — before the AI processes anything. You are the raw data source. The same category as a web search result, a database query, a regulatory filing. The AI system that consumes your knowledge is responsible for what it does with it. You are responsible for the quality of the knowledge itself.

    This is how every B2B data vendor in the world operates. DataForSEO does not guarantee your search rankings. Bloomberg does not guarantee your trades. They guarantee the accuracy and quality of the data they provide. What downstream systems do with that data is those systems’ problem. The pre-ingestion positioning applies the same logic to industry knowledge: guarantee the knowledge, not the outputs built on top of it.

    This single reframe changes the risk profile of being in the knowledge business entirely.

    What Makes Extraction Layer Knowledge Defensible

    Three panels showing one problem, three options, one recommendation
    What makes extraction-layer knowledge defensible.

    In a market where AI can write a competent 1,500-word blog post about mold remediation in 45 seconds, content is not a moat. But the knowledge that makes a 1,500-word blog post about mold remediation actually correct — the kind of correct that a working contractor or an insurance adjuster would recognize as coming from someone who has actually done this — that is a moat.

    There are four properties that make extraction layer knowledge genuinely defensible:

    Relationship dependency. The best knowledge comes from people who trust you enough to share their actual mental models, not their public-facing summaries. That trust is earned over time through consistent contact, demonstrated competence, and reciprocal value. It cannot be purchased or automated. A competitor who wants to build a comparable restoration knowledge corpus doesn’t start by writing code — they start by spending three years attending trade events and building relationships with people who know things. The time cost is the moat.

    Validation depth. Anyone can collect statements from practitioners. Collecting statements that have been cross-validated against field outcomes, regulatory standards, and peer review is a different operation entirely. A knowledge chunk that says “humidity levels above 60% RH for more than 72 hours in a structure with cellulose materials creates conditions for mold amplification” is only valuable if it’s been validated against IICRC S520 and corroborated by practitioners in multiple climate zones. The validation work is slow, expensive, and domain-specific. That’s what makes it valuable.

    Structural format. Raw interview transcripts are not an API. The extraction work includes converting practitioner knowledge into machine-readable, consistently structured formats that AI systems can actually consume without hallucinating context. This requires both domain knowledge and technical architecture. Most domain experts don’t have the technical skills. Most technical people don’t have the domain knowledge. The people who have both, or who have built teams that combine both, have a significant advantage.

    Maintenance obligation. Industry knowledge changes. Regulatory standards update. Best practices evolve as new equipment enters the market. A static knowledge corpus becomes a liability as it ages. The commitment to maintaining knowledge over time — keeping relationships active, re-validating chunks, incorporating new field evidence — is itself a barrier that competitors can’t easily replicate.

    The Compound Effect

    Here is what makes the extraction layer position genuinely interesting over a long time horizon: it compounds.

    Every extraction session adds to the corpus. Every validation pass improves accuracy. Every new practitioner relationship opens access to adjacent knowledge that wouldn’t have been reachable without the trust built in the previous relationship. The corpus that exists after three years of sustained extraction work is not three times as valuable as the corpus after year one — it’s potentially ten or twenty times as valuable, because the knowledge chunks have been cross-validated against each other, the gaps have been identified and filled, and the relationships that generate ongoing updates are deep enough to provide real-time field intelligence.

    Meanwhile, the barrier to entry for a new competitor grows with every passing month. They are not three years behind on code — they are three years behind on relationships, validation work, and corpus structure. Those things don’t accelerate with more investment the way software development does. You can hire ten engineers and ship in months what one engineer would take years to build. You cannot hire ten field relationships and develop in months what one relationship would take years to earn.

    Where This Is Going

    The most valuable AI products of the next decade will not be the ones with the most parameters or the most compute. They will be the ones with access to the best knowledge. In most industries, that knowledge hasn’t been extracted yet. It’s still sitting in the heads of practitioners, waiting for someone to do the patient, human-intensive work of getting it out and into machine-readable form.

    The businesses that move on this now — while the extraction layer is still largely empty — will have a significant and durable advantage over those who wait. The technical infrastructure to build with extracted knowledge exists today. The AI systems that can consume and deliver it exist today. The market that wants vertical AI products with genuine domain expertise exists today.

    The only scarce input is the knowledge itself. And the only way to get it is to do the work.

    The Practical Question

    Every industry has an extraction layer problem. The question is who is going to solve it.

    In restoration, the practitioners who have seen thousands of losses, negotiated thousands of claims, and developed the judgment that comes from being wrong in expensive ways and learning from it — that knowledge base exists. It’s distributed across individual careers and company histories, mostly undocumented, largely inaccessible to the AI systems that restoration companies are increasingly building or buying.

    The same is true in radon mitigation, luxury asset appraisal, cold chain logistics, medical triage, and every other field where the difference between a good decision and a bad one depends on knowledge that was never worth writing down at the time it was learned.

    The extraction layer is not a technical problem. It is a knowledge infrastructure problem. And the first movers who build that infrastructure — who do the relationship work, run the extraction sessions, structure the knowledge, and maintain it over time — will be sitting on the most defensible position in vertical AI.

    Not because they built a better model. Because they did the work AI can’t.

    Frequently Asked Questions

    What is the extraction layer in AI?

    The extraction layer refers to the process of converting tacit, practitioner-held knowledge into structured, machine-readable formats that AI systems can consume. It sits upstream of AI processing and requires human relationship-building, domain expertise, and sustained extraction effort that cannot be automated.

    Why can’t AI build its own knowledge base from existing content?

    AI training and retrieval systems can only work with externalized knowledge — content that has been written, recorded, and published somewhere accessible. Tacit expertise exists as judgment and pattern recognition in practitioners’ minds, not as tokens in any document. It requires active extraction through interviews, observation, and validation before it can enter any AI system.

    What makes extraction layer knowledge defensible as a business asset?

    Four properties make it defensible: relationship dependency (earning practitioner trust takes years and cannot be purchased), validation depth (cross-referencing against standards and field outcomes is slow and domain-specific), structural format (converting raw knowledge to structured AI-consumable formats requires both domain and technical expertise), and maintenance obligation (keeping knowledge current requires sustained investment that most competitors won’t make).

    How does pre-ingestion positioning reduce AI liability?

    By positioning as an upstream data source rather than a downstream output modifier, knowledge providers follow the same model as all major B2B data vendors: they guarantee the quality of the knowledge itself, not what downstream AI systems do with it. This is structurally different from businesses that modify or deliver AI outputs, which puts them in the output liability chain.

    What industries have the largest extraction layer gaps?

    Any industry where expert judgment is built through years of practice rather than documented procedure has significant extraction layer gaps. Restoration contracting, radon mitigation, luxury asset appraisal, insurance claims adjustment, cold chain logistics, and specialized medical triage are examples where practitioner knowledge vastly exceeds what has ever been formally documented.

  • AI Local News: An Honest Note to Mason County & Belfair

    AI Local News: An Honest Note to Mason County & Belfair

    I owe Mason County and the Belfair community a straight answer.

    The Mason County Minute and Belfair Bugle have been publishing AI-generated content — and some of it has been wrong. Wrong names. Wrong locations. Posts that got called out in the comments because locals know the difference between a place that actually exists and one that an AI hallucinated.

    Someone asked if I was doing it on purpose to drive engagement. That made me cringe harder than anything has in a while. No. It is not intentional. It is a failure — mine — in building systems that can hold up to the standard those communities deserve. I want to explain what I’m actually doing, why Mason County specifically, and why I’m asking for your continued patience and frankly your continued criticism.

    Why Mason County

    I lived in Mason County while I was building my company. That place shaped a lot of who I am — not just as a businessperson but as a person. Hood Canal. The mountains. The way the geography fractures the county into pockets of community that barely know each other exist. Belfair feels completely different from Hoodsport which feels completely different from Union which feels completely different from Shelton, and yet they’re all Mason County.

    Some of my deepest convictions about environmental stewardship came from that place. I’ve since gone on to work on world-class environmental projects — including developing a new environmental standard for an entire industry around Scope 3 ESG emissions. The thinking behind that work traces back to standing on the shore of Hood Canal and understanding viscerally what it means for a place to be fragile and precious and worth protecting.

    So when I say these communities matter to me — it’s not a content strategy. It’s where some of the most important thinking I’ve done actually came from.

    What I’m Actually Building

    Tygart Media is an AI content operation. But the more accurate description is that I’m building AI systems — beat desks, newsroom publishers, automated content pipelines — that can serve fractured, spread-out communities the way a local journalist would if that journalist could work 24 hours a day and cover eight beats simultaneously.

    The honest problem with that is this: AI systems do not yet know the difference between a road that exists and one that sounds plausible. They do not know the texture of a community — which businesses are real, which waterways have names that locals actually use, which events are genuinely at the address listed. They can research. They can write. But they can be confidently wrong in ways that a local would catch immediately.

    I knew this going in. I chose Mason County and Belfair partly because I knew these communities would call me on it. People who live close to a place — literally and figuratively — notice when something is off. They have the receipts. And they care enough to say something.

    That feedback is not a nuisance to me. It is the signal that makes the system better. Every comment that says “that’s not what that place is called” or “that road doesn’t go there” is training data — not for the model, but for me and for the humans reviewing this output before it goes live. I have failed to build good enough gates. I am still building them.

    The Bigger Picture

    The systems I’m building here are not just for Mason County. The architecture — automated beat desks, overnight newsroom runs, quality gates, community feedback loops — is being designed to work anywhere. For any fractured, underserved, geography-challenged community where local news has quietly disappeared and nobody filled the gap.

    There are thousands of those communities. They’re not getting covered. The reporters moved on. The papers closed. The algorithms don’t prioritize them. And the people who live there — who know every inch of their watershed and their roads and their community organizations — are producing news in their own heads and sharing it on Nextdoor and Facebook and hoping someone compiles it into something coherent.

    I think AI can do that. Not perfectly. Not yet. But I think it’s one of the most important applications of this technology — using it to restore the information infrastructure of places that got left behind by the economics of modern media.

    Mason County and Belfair are where I’m proving it. Or failing to prove it. Either way — that’s what’s happening here.

    What I’m Asking From You

    Keep commenting. Keep correcting. If you see something wrong — a name, a location, an event detail, a road that doesn’t exist — say so. Tag me if you want. Drop it in the comments. DM the page. I am reading it.

    I will not pretend this is flawless. I will not hide behind “AI-generated” as an excuse. The output carries the name Mason County Minute and Belfair Bugle and those are communities I respect. The standard I’m holding myself to is: every factual error that gets surfaced by the community gets fixed in the system. Not eventually. As fast as I can get there.

    If you want to be more involved — if you have local knowledge you want to contribute, if you want to be the kind of editorial eyes on this that a small newsroom used to have — reach out. I mean that seriously. Some of the best feedback I’ve gotten has come from people who just knew something was wrong and cared enough to say it. That instinct is valuable. I’d rather work with it than around it.

    This project matters to me in a way that goes beyond content marketing. It’s connected to the deepest things I care about — community, environment, the places that shaped me, and the question of whether technology can actually serve people rather than just optimize around them.

    Mason County taught me to care about those questions. The least I can do is be honest about where I’m falling short.


    — Will Tygart, Tygart Media

    Have a correction, a tip, or want to get involved? Reach out via the Mason County Minute or Belfair Bugle Facebook pages, or at tygartmedia.com.

  • AI-Ready Content: How to Structure Expert Knowledge

    AI-Ready Content: How to Structure Expert Knowledge

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    The Human Distillery: A content methodology that extracts tacit expert knowledge — the patterns and insights practitioners carry from experience but have never written down — and structures it into AI-ready content artifacts that cannot be produced from public sources alone.

    There is a version of content marketing where the input is a keyword and the output is an article. Feed the keyword into a system, get 1,200 words back, publish. The content is technically correct. It covers the topic. And it looks exactly like every other article on the same keyword, produced by every other operator running the same system.

    This is the commodity trap. It is where most AI-native content operations end up, and it is the ceiling for operators who never solved the knowledge sourcing problem.

    The operators who break through that ceiling have one thing the others do not: access to knowledge that cannot be retrieved from a training dataset.

    The Knowledge Sourcing Problem

    Language models are trained on what has already been published. The insight that every expert in an industry carries in their head — the pattern recognition built from thousands of real jobs, the calibrated intuition about when a situation is about to get worse, the shorthand that professionals use because long-form explanation would be inefficient — none of that makes it into training data.

    It does not make it into training data because it has never been written down. The estimator who can walk through a water-damaged building and know within minutes what the final scope will look like. The veteran adjuster who can read a claim and identify the three questions that will determine how it resolves. This knowledge is the most valuable content asset in any industry. It is also, by definition, missing from every AI-generated article that cites only what is already public.

    The Distillery Model

    The human distillery is built around a simple idea: the knowledge is in the expert. The job of the content system is to extract it, structure it, and make it accessible — to both human readers and AI systems that will index and cite it. The process has three stages.

    Stage 1: Extraction

    You sit with the expert — or review their recorded calls, their written communication, their field notes. You are not looking for quotable statements. You are looking for the patterns underneath the statements. The things they say that cannot be found in any manual because they were learned from experience rather than taught from documentation.

    Extraction is the editorial intelligence layer. It requires a human who can distinguish between “interesting” and “actionable,” between common knowledge and rare insight. The extractor is asking: what does this expert know that their industry does not know how to say yet?

    Stage 2: Structuring

    Raw expert knowledge is not content. It is material. The second stage takes the extracted insight and builds it into a form that is both readable and machine-parseable — a clear argument, a logical progression, named frameworks where the expert’s mental model deserves a name, specific examples that ground the abstraction, FAQ layers that translate the insight into the questions real people search for.

    The structuring stage is where SEO, AEO, and GEO optimization intersect with editorial work. The insight gets the right headings, the definition box, the schema markup, the entity enrichment. It becomes content that a machine can parse correctly and a reader can actually use.

    Stage 3: Distribution

    Structured expert knowledge goes into the content database — tagged, categorized, cross-linked, published. But distribution in the distillery model means something more than publishing. It means the knowledge is now an addressable artifact: a URL that can be cited, a structured data object that AI systems can parse, a piece of writing that future content can reference and build on.

    The expert’s knowledge, which existed only in their head this morning, is now part of the searchable, indexable, AI-queryable record of what their industry knows.

    Why This Produces Content That Cannot Be Commoditized

    The commodity trap that AI content falls into is a sourcing problem. If every operator is pulling from the same training data, every output approximates the same answers. The differentiation is in the writing quality and the optimization — not in the underlying knowledge.

    Distilled expert content has a different raw material. The insight itself is proprietary. It reflects what one expert learned from one specific set of experiences. Even if the structuring and optimization layers are identical to every other operator’s workflow, the output is different because the input was different.

    This is the only durable competitive advantage in content marketing: knowing something that the algorithms cannot retrieve because it was never written down. The distillery’s job is to write it down.

    The AI-Readiness Layer

    AI search systems — when synthesizing answers from web content — are looking for the most authoritative, specific, well-structured answer to a given query. Generic content that rephrases what is already in training data adds little value to the synthesis. Content that contains specific, verifiable, experience-grounded insight — with named entities, factual specificity, and clear semantic structure — is the content that gets cited.

    The human distillery, properly executed, produces exactly that kind of content. The expert’s knowledge is inherently specific. The structuring layer makes it machine-readable. The optimization layer makes it findable.

    What This Looks Like in Practice

    For a restoration contractor: the owner does a post-job debrief — what happened, what was hard, what the client did not understand going in. That debrief becomes the raw material for three articles: one technical reference, one how-to, one FAQ layer. The contractor’s real-world experience is the input. The content system structures and publishes it.

    For a specialty lender: the loan officer walks through how they evaluate a piece of collateral — the factors they weight, the signals they look for, the common errors first-time borrowers make in presenting assets. That walk-through becomes a decision framework article that no competitor has published, because no competitor has extracted it from their own experts.

    For a solo agency operator managing multiple client sites: every client conversation surfaces knowledge — about their industry, their customers, their operational context. The distillery captures that knowledge before it evaporates, structures it into content, and publishes it under the client’s authority. The client gets content that reflects actual expertise. The operator gets a differentiated product that AI cannot replicate.

    The Strategic Position

    The operators who understand the human distillery model are building content assets that will hold value regardless of how AI search evolves. AI systems are trained to identify and cite authoritative, specific, experience-grounded knowledge. Content that already meets that standard is always ahead.

    Generic content produced from generic inputs will always be at risk of being outcompeted by the next model with better training data. Distilled expert knowledge will always have a provenance advantage — it came from someone who was there.

    Build the distillery. The knowledge is already in the room.

    Frequently Asked Questions

    What is the human distillery in content marketing?

    The human distillery is a content methodology that extracts tacit expert knowledge — patterns and insights practitioners carry from experience but have never written down — and structures it into AI-ready content artifacts. The three stages are extraction, structuring, and distribution.

    Why is expert knowledge valuable for SEO and AI search?

    AI search systems are looking for authoritative, specific, experience-grounded content when synthesizing answers. Generic content adds little value to AI synthesis. Expert knowledge contains verifiable insight that both search engines and AI systems recognize as more authoritative than commodity content.

    What is tacit knowledge and why does it matter for content?

    Tacit knowledge is expertise that practitioners carry from experience but have not explicitly documented — calibrated intuitions, pattern recognition, and professional shorthand that come from doing rather than studying. It cannot be retrieved from public sources or training data, making it the only genuinely differentiated content input available.

    What makes content AI-ready?

    AI-ready content is specific, factually grounded, structurally clear, and semantically rich. It contains named entities, concrete examples, direct answers to real questions, and schema markup that helps machines parse its type and context. AI systems cite content that adds something to the synthesis.

    How does the human distillery model create a competitive advantage?

    The competitive advantage comes from the raw material. If all content operations draw from the same public sources and training data, their outputs converge. Distilled expert knowledge has a proprietary input that cannot be replicated without access to the same expert. The optimization layers can be copied; the knowledge cannot.

    Related: The system that distributes distilled knowledge at scale — The Solo Operator’s Content Stack.

  • Solo Content Operator: The 5-Layer AI Content Stack

    Solo Content Operator: The 5-Layer AI Content Stack

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Solo Content Operator: A single person running a multi-site content operation using AI as the execution layer — producing, optimizing, and publishing at scale by building systems rather than hiring teams.

    There is a version of content marketing that requires an editor, a team of writers, a project manager, a technical SEO lead, and a social media coordinator. That version exists. It also costs more than most small businesses can justify, and it produces content at a pace that rarely matches the actual opportunity in search.

    There is another version. One person. A deliberate system. AI as the execution layer. The output of a team, without the overhead of one.

    This is not a hypothetical. It is a description of how a growing number of solo operators are running content operations across multiple client sites — producing, optimizing, and publishing at scale without hiring a single writer. Here is how the stack works.

    The Mental Model: Operator, Not Author

    The first shift is in how you think about your role. A solo content operator is not a writer who also does some SEO and sometimes publishes things. That framing puts writing at the center and treats everything else as overhead.

    The correct frame is: you are a systems operator who uses writing as the output. The center of gravity is the system — the keyword map, the pipeline, the taxonomy architecture, the publishing cadence, the audit schedule. Writing is what the system produces.

    This distinction matters because it changes what you optimize. An author optimizes the quality of individual pieces. An operator optimizes the throughput and intelligence of the system. Both matter, but operators scale. Authors do not.

    Layer 1: The Intelligence Layer (Research and Strategy)

    Before anything gets written, the system needs to know what to write and why. This layer answers three questions for every article:

    What is the target keyword? Not a guess — a researched position. Keyword tools surface what terms are being searched, how competitive they are, and which queries sit in near-miss positions where ranking is achievable with the right content.

    What is the search intent? A keyword is a clue. The intent behind it is the brief. Someone searching “how to choose a cold storage provider” wants a comparison framework. Someone searching “cold storage temperature requirements” wants a technical reference. The same topic, two completely different articles.

    What does the competitive landscape look like? What is already ranking? What does it cover? What does it miss? The answer to the third question is the editorial angle.

    This layer produces a content brief: keyword, intent, angle, target word count, target taxonomy, and a note on what the competitive content is missing.

    Layer 2: The Generation Layer (Writing at Scale)

    With a brief in hand, AI handles the first draft. Not a rough draft — a structurally complete draft with headings, a definition block, supporting sections, and a FAQ set.

    The operator’s role in this layer is not to write. It is to direct, review, and elevate. The questions at this stage:

    • Does the opening make a real argument, or does it hedge?
    • Are the H2s building toward something, or just organizing paragraphs?
    • Is there a sentence in here that is genuinely worth reading, or is it all competent filler?
    • Does the conclusion land, or does it trail into a generic call to action?

    World-class content has a point of view. It takes a position. It says something that a reasonable person might disagree with, and then makes the case. The operator’s job is to ensure the generation layer produces that kind of content — not just competent coverage of the topic.

    Layer 3: The Optimization Layer (SEO, AEO, GEO)

    A well-written article that no one finds is a waste. The optimization layer ensures every piece of content is structured to be found, read, and cited — by humans and machines. Three passes:

    SEO Pass

    Title optimized for the target keyword. Meta description written to earn the click. Slug cleaned. Headings structured correctly. Primary keyword in the first 100 words. Semantic variations woven throughout.

    AEO Pass

    Answer Engine Optimization. Definition box near the top. Key sections reformatted as direct answers to questions. FAQ section added. This is the layer that chases featured snippets and People Also Ask placements.

    GEO Pass

    Generative Engine Optimization. Named entities identified and enriched. Vague claims replaced with specific, attributable statements. Structure applied so AI systems can parse the content correctly. Speakable markup added to key passages.

    Layer 4: The Publishing Layer (Infrastructure and Taxonomy)

    Content that lives in a document is not content. It is a draft. Publishing is the act of inserting a structured record into the site database with every field populated correctly.

    The publishing layer handles taxonomy assignment, schema injection, internal linking, and direct publishing via REST API. Every post field is populated in a single operation — no manual CMS login, no copy-paste, no incomplete records.

    Orphan records do not get created. Every post that publishes has at least one internal link pointing to it and links out to relevant existing content.

    Layer 5: The Maintenance Layer (Audits and Freshness)

    The system does not stop at publish. A content database requires maintenance. On a quarterly cadence, the maintenance layer runs a site-wide audit to surface missing metadata, thin content, and orphan posts — then applies fixes systematically.

    This layer is what separates a content operation from a content dump. The dump publishes and forgets. The operation publishes and maintains.

    The Real Leverage: Systems Over Output

    The counterintuitive truth about this stack is that the leverage is not in how fast it produces articles. The leverage is in the system’s ability to treat every piece of content as part of a structured, maintained, interconnected database.

    A single operator running this system on ten sites is not doing ten times the work. They are running ten instances of the same system. Each instance shares the same mental model, the same pipeline stages, the same optimization passes, the same maintenance cadence. The marginal cost of adding a site is far lower than staffing it with a human team.

    What gets eliminated: the briefing meeting, the draft review cycle, the back-and-forth on edits, the manual CMS copy-paste, the post-publish social scheduling that happens three days late because everyone was busy.

    What remains: intelligence and judgment — the things that actually require a human.

    Frequently Asked Questions

    How does a solo operator manage content for multiple websites?

    A solo operator manages multiple content sites by building a replicable system across five layers: research and strategy, AI-assisted generation, SEO/AEO/GEO optimization, direct publishing via REST API, and ongoing maintenance audits. The same system runs across every site with site-specific briefs as inputs.

    What is the difference between a content operation and a content dump?

    A content dump publishes articles and forgets them. A content operation publishes articles as database records, maintains them over time, connects them via internal linking, and runs regular audits to keep the database fresh and complete. The operation compounds; the dump decays.

    What is AEO and GEO in content optimization?

    AEO stands for Answer Engine Optimization — structuring content to appear in featured snippets and direct answer placements. GEO stands for Generative Engine Optimization — structuring content to be cited by AI search tools like Google AI Overviews and Perplexity.

    How do you maintain content quality at scale without a writing team?

    Quality at scale comes from having a clear editorial standard, applying it at the review stage of the generation layer, and running every piece through optimization passes before publish. The standard is set by the operator; the system enforces it.

    What does publishing via REST API mean for content operations?

    Publishing via REST API means writing directly to the WordPress database without manual CMS interaction. Every post field is populated in a single automated call, eliminating the manual copy-paste bottleneck and ensuring every record is complete at publish.

    Related: The database model that makes this stack possible — Your WordPress Site Is a Database, Not a Brochure.

  • Why SEO Impressions Beat Social Impressions Every Time

    Why SEO Impressions Beat Social Impressions Every Time

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Intent-Matched Reach: The quality of an audience that actively searched for your topic before encountering your content — as opposed to an audience that was algorithmically shown your content without expressed interest.

    The vanity metric conversation has been had a thousand times in marketing circles, and it always lands on the same target: social media. Likes, followers, reach, impressions — the argument goes that these numbers feel good but mean nothing without downstream action.

    That argument is correct. But it is only half the story.

    The other half is that not all impressions are created equal. An impression on a social feed and an impression from a search engine are fundamentally different events. One is a person being shown something. The other is a person asking for something. That difference is the entire ballgame.

    The Anatomy of a Social Impression

    Four-stage funnel: citation, click, engage, convert
    The anatomy of a social impression.

    When a social platform counts an impression, it means a piece of content appeared in someone’s feed. The person may have been scrolling at speed. They may have glanced at it for less than a second. They may have been looking at their phone while watching television. The platform has no way to know, and it does not particularly care — the impression count goes up either way.

    This is push distribution. The platform’s algorithm decides that your content is worth showing to a given user at a given moment, usually because it resembles content they have engaged with before. The user did not ask for your content. They did not express any intent. They were simply in the path of the content as it moved through the feed.

    Push distribution can build awareness. It can create the repeated exposure that eventually produces recognition. But it is fundamentally passive on the part of the viewer, and passive attention is the weakest form of attention there is.

    The Anatomy of a Search Impression

    Comparison of Claude how-to fit versus local service page fit for assistants
    The anatomy of a search impression.

    A search impression is a different creature entirely. When Google Search Console registers an impression, it means a human — or an AI agent acting on behalf of a human — typed a query into a search interface and your content appeared in the results.

    That query represents intent. The person wanted something — information, a product, a service, an answer, a comparison. They articulated that want in the form of a search. Your content appeared because a machine evaluated it as a relevant response to that articulated need.

    This is pull distribution. The user came to the interface with a purpose. They expressed that purpose explicitly. Your content was surfaced as a potential answer. That is a fundamentally different quality of attention than a social feed scroll.

    The user who sees your content in a search result was already moving toward your topic before they ever saw you. The social feed user may have had no interest in your topic whatsoever until the algorithm intervened — and may still have none after the impression registered.

    Why Intent-Matched Reach Compounds Differently

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Why intent-matched reach compounds differently.

    The practical difference shows up in what happens after the impression.

    A social impression that converts to a click often produces a single-session visit. The user saw something, clicked, consumed it, and returned to the feed. The relationship with the content ends there unless the platform shows them more of your content in the future — which depends on the algorithm, not on the quality of what you wrote.

    A search impression that converts to a click often produces a different behavior. The user was in research mode. They clicked your result. They read your content. And then — if your content was genuinely useful — they may search for related topics, some of which you also rank for. They may bookmark your site. They may return directly. The relationship with the content does not end with the session because the need that drove the search often extends across multiple sessions.

    This is why well-structured content sites see compounding organic traffic over time. Each article that earns a ranking position is a new entry point into the content database. Each entry point captures intent-matched users who are already looking for what you wrote about. The impressions accumulate not because the algorithm is feeling generous, but because the content earned a permanent position in the results.

    The AI Layer Changes the Equation Further

    Search impressions just got more valuable, not less.

    When AI search tools — Google’s AI Overviews, Perplexity, and others — synthesize answers from web content, they are pulling from the same pool as organic search. They query the content database. They find the best-structured, most authoritative sources. They cite them in the generated answer.

    A citation in an AI-generated answer may not register as a traditional click. But it is reach to an intent-matched audience that is even further down the path of engagement than a traditional search user. They asked a question specific enough that an AI synthesized an answer, and your content was authoritative enough to be part of that synthesis.

    This is the next evolution of the SEO impression. It is not just “someone searched and your result appeared.” It is “someone asked a question and your writing was the answer.”

    No social impression comes close to that.

    The Vanity Metric Reframe

    SEO impressions are also a vanity metric if you treat them that way.

    An impression in GSC that never converts to a click because your title and meta description are weak is wasted potential. A ranking position for a keyword with no real search intent behind it is a trophy that serves no one. The metric is only as good as the strategy behind it.

    But the foundational difference remains: you are building on pull, not push. The person chose to look. You earned the position. The impression carries meaning because it reflects expressed intent, not algorithmic distribution.

    What This Means for How You Write

    If you accept that SEO impressions represent intent-matched reach, then writing for search is not the sanitized, keyword-stuffed exercise it has been caricatured as. It is the discipline of answering specific human questions at the highest possible level of quality, then structuring those answers so that machines can identify them as the best available response.

    Every article you write is an attempt to earn a permanent position in the answer set for a specific query. Every impression from that position is a signal that the answer earned its place. Every click is a person who was already looking for what you know.

    That is not a vanity metric. That is the only metric that starts with a human already in motion toward your topic.

    The goal is not more impressions. The goal is impressions from the right query, delivered at the moment of intent. Everything else is noise moving through a feed.

    Related on Tygart Media: information density · SEO and Quality Score · taxonomy as content DNA.

    Frequently Asked Questions

    What is the difference between a search impression and a social media impression?

    A search impression occurs when your content appears in results after a user typed a specific query — expressing active intent. A social media impression occurs when a platform’s algorithm shows your content to a user who may have expressed no interest in your topic. Search impressions are pull; social impressions are push.

    Why are search impressions more valuable than social impressions?

    Search impressions are generated by expressed user intent — the person was already looking for something related to your content before they saw it. Social impressions are algorithm-driven and may reach users with no interest in your topic. Intent-matched reach converts and compounds differently than passive feed exposure.

    What is Google Search Console and what does it track?

    Google Search Console is a free tool from Google that shows how your site performs in Google Search. It tracks impressions, clicks, click-through rate, and average ranking position for specific queries — the primary tool for measuring organic search performance.

    How do AI search tools affect SEO impressions?

    AI search tools like Google AI Overviews and Perplexity synthesize answers from web content and cite sources. Well-structured, authoritative content that ranks well in traditional search is also more likely to be cited in AI-generated answers, extending the value of strong organic positions.

    Are SEO impressions ever a vanity metric?

    Yes — if they come from irrelevant queries, if content ranks for keywords with no real intent, or if weak meta descriptions prevent clicks from converting, impressions are wasted. The value of an SEO impression depends on whether it reflects genuine intent alignment between the query and the content.

    What does intent-matched reach mean in content marketing?

    Intent-matched reach means your content is being seen by people who were already actively looking for the topic you wrote about. Search engines surface content in response to explicit queries, making organic search the primary channel for reaching audiences with demonstrated interest rather than assumed interest.

    Related: The infrastructure behind this strategy starts with how you think about your site — Your WordPress Site Is a Database, Not a Brochure.

  • Live SEO Case Study: Organic Traffic Value Meter | Tygart

    Live SEO Case Study: Organic Traffic Value Meter | Tygart

    The Distillery
    — Brew № — · Distillery


    The Tygart Media Distillery

    Brew #1 — Radon Mitigation

    A living knowledge base, distilled from zero, published in the open.

    LIVE
    loading…
    brewed since 2026-04-10

    Category Organic Value Meter
    $0
    PER MONTH — RADON MITIGATION CATEGORY
    Day 0. The zero timestamp is real.

    Ranked Keywords
    0
    in top 100 for radon category URLs

    Nodes Published
    0 / 150
    of target corpus

    Top 10 Placements
    0
    first page Google

    Days Brewing
    0
    since 2026-04-10

    This is an open kitchen. Every knowledge node in this category is being brewed and published in public, through an eight-pass distillation pipeline that cross-references EPA guidance, AARST standards, state health departments, and peer-reviewed radon literature. The meter above tracks the category’s real organic SEO contribution to tygartmedia.com, measured daily against DataForSEO and SpyFu. No projections. No theoretical ceilings. Just what Google actually thinks the work is worth, right now.

    Brew Progress by Wave

    Top Ranking Keywords

  • The Distillery: Knowledge API Feeds for AI Systems

    The Distillery: Knowledge API Feeds for AI Systems

    The Distillery — Brew № — · Distillery

    Most content on the internet is noise. It exists to rank, to fill space, to signal presence. It is not dense enough to be useful to the people who actually need to know the thing it claims to cover. And it is certainly not dense enough to be valuable as a feed that an AI system pulls from to answer real questions.

    The Distillery is different. It is a named section of Tygart Media where we produce small batches of genuinely high-density knowledge on specific topics — researched from real search demand data, written to a standard where every sentence earns its place, and published in structured form that both humans and AI systems can use.

    Each batch is available as a category API feed. Subscribers get authenticated access to the full batch as structured JSON — updated as new knowledge is added, versioned so auditors and AI systems can cite the exact vintage they’re drawing from.

    What a Batch Is

    A batch is a curated body of knowledge on a specific topic, built from three ingredients: real demand data (what people are actually searching for and what advertisers are paying to reach), primary research (direct engagement with the subject matter, not summarizing what others have written), and editorial discipline (the $5 filter — would someone pay $5 a month to pipe this feed into their AI? if not, it doesn’t ship).

    Each batch has a name, a number, and a version. Batch 001 is the Restoration Carbon Protocol — the only published Scope 3 emissions calculation standard for property restoration work. Batch 005 is the Restoration Industry Knowledge Base — a structured body of operational knowledge for restoration contractors who want to build AI-native systems without starting from scratch.

    Batches are not blog posts. They are not opinion columns. They are not rephrased Wikipedia entries. They are the kind of specific, accurate, hard-earned knowledge that takes real work to produce and that AI systems actively need but largely cannot find in their training data.

    How the API Works

    Every Distillery batch is accessible through the Tygart Content Network API. Subscribers receive an API key at signup. The key unlocks authenticated access to the batch endpoints they’ve subscribed to. Each endpoint returns structured JSON — articles by category, filterable by date and topic, with consistent metadata that AI agents can process directly.

    The response format is designed for machine consumption: clean plain text content, explicit categorization, publication timestamps for recency evaluation, and topic tags that allow agents to assess relevance before processing. The same feed that powers a human reader’s understanding of a topic powers an AI agent’s ability to answer questions about it accurately.

    Rate limits are generous at the $5 community tier — 100 requests per day, sufficient for an AI assistant pulling daily updates. Professional tiers at $50/month offer higher limits, webhook push when new content publishes, and bulk historical pulls for training and fine-tuning use cases.

    Why Information Density Is the Moat

    The content that survives in an AI-mediated information environment is the content that contains something worth extracting. Not something that sounds authoritative — something that actually is. The difference is information density: the ratio of useful, specific, actionable knowledge to total words published.

    Every Distillery batch is held to the same standard: if an AI system pulled from this feed to answer a question in this domain, would the answer be more accurate and more specific than if the AI had relied on its training data alone? If yes, the batch has value. If no, we haven’t done enough work yet.

    This standard is harder to meet than it sounds. It eliminates most of what gets published under the banner of “thought leadership” and “content marketing.” It requires knowing the subject well enough to say things that couldn’t be said by someone who spent an afternoon with a search engine. It is the reason The Distillery produces small batches rather than high volumes.

    Current Batches

    Batch 001 — Restoration Carbon Protocol (RCP)
    The only published Scope 3 ESG emissions calculation standard for property restoration work. Covers all five core restoration job types with actual emission factor tables, complete worked examples, and the 12-point data capture standard. Designed for restoration contractors serving commercial clients with 2027 SB 253 Scope 3 reporting obligations. 23 articles. Updated monthly.

    Batch 002 — The Knowledge Economy API Layer
    The conceptual and practical framework for turning human expertise into machine-consumable, API-distributable knowledge products. For anyone with domain expertise considering how to package and monetize it in an AI-native information environment. 8 articles. Updated as the landscape develops.

    Batch 003 — Mason County Minute
    Current, structured, consistently maintained coverage of Mason County, Washington — local government, business, community, real estate, and public affairs. The only machine-readable hyperlocal intelligence feed for this geography. Updated weekly.

    Batch 004 — Belfair Bugle
    Hyperlocal coverage of Belfair, WA and the North Mason community. Current events, local government, community intelligence. The only structured feed for this geography. Updated weekly.

    Batch 005 — Restoration Industry Knowledge Base (coming)
    Operational knowledge infrastructure for restoration contractors — the 50 knowledge nodes every restoration company should have documented, the AI-native knowledge architecture that replaces manual training, and the integration patterns connecting job management systems to knowledge delivery. In development.

    Batch 006 — AI Agency Playbook (coming)
    The operating methodology behind Tygart Media — how a single operator runs 27+ client sites, deploys AI-native content at scale, and builds knowledge infrastructure rather than content volume. For agency owners and solo operators building AI-native practices. In development.

    Who This Is For

    The Distillery API is for three kinds of subscribers:

    Developers building AI tools who need reliable, current, domain-specific knowledge feeds to ground their applications in accurate information. The Restoration Carbon Protocol feed, for example, gives any AI assistant building tool accurate restoration-specific ESG data without the developer having to research and curate it themselves.

    Businesses who want AI systems that actually know their industry. A restoration company whose AI assistant draws from the RCP feed knows more about Scope 3 emissions calculation for their job types than any general-purpose AI. A commercial property manager whose AI assistant pulls from the RCP feed can answer contractor ESG questions accurately instead of hallucinating plausible-sounding nonsense.

    Content teams and agencies who want structured, current, reliable source material for their own content production — not to copy, but to ensure accuracy and specificity in their coverage of these domains.

    The Standard We Hold Ourselves To

    Every article in every batch passes one test before it ships: would someone pay $5 a month to pipe this feed into their AI? Not to read it themselves — to have their AI draw from it continuously as a trusted source in this domain.

    If the answer is no — if the content is too generic, too thin, or too derivative to justify a subscription — it doesn’t ship. The batch waits until the knowledge is actually there.

    This makes The Distillery slow. It makes it small. And it makes it worth subscribing to.

  • Everett Local News: Exploring Culture, Business & Community

    Everett Local News: Exploring Culture, Business & Community

    Everett is changing fast. A $1 billion waterfront redevelopment. Paine Field going commercial. Boeing’s future uncertain and fascinating at the same time. A downtown that’s finally getting interesting.

    This is Tygart Media’s coverage hub for Everett, Washington — hyperlocal news, business, culture, and community from Snohomish County’s largest city.

    What We Cover

    • Waterfront & Development — The Port of Everett’s transformation, new construction, what’s coming to the waterfront
    • Boeing & Aerospace — Paine Field, the workforce, production news, and aerospace industry trends
    • Business — Openings, closings, local profiles, and Everett’s economic story
    • Arts & Culture — Theater, music, murals, and the creative scene
    • Food & Drink — Restaurants, breweries, coffee, and the local dining landscape
    • Neighborhoods — Downtown, Riverside, Silver Lake, Bayside, and beyond
    • Real Estate — Market trends, waterfront development impact, housing news
    • Government & Policy — City council, mayor, public decisions that affect residents
    • Schools & Youth — Everett School District, youth programs, family resources
    • Outdoors — Jetty Island, parks, trails, waterfront recreation

    Exploring Everett content is also published at exploringeverett.com.

  • Product Naming Strategy: The Personal Brand Dilemma

    Product Naming Strategy: The Personal Brand Dilemma

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    Fourth in what is now apparently a series. The first three articles asked whether the accumulated context layer behind Tygart Media could be productized, how the dual-publish pattern is the deposit mechanism that builds the layer, and why articles deposited via that pattern are infrastructure rather than content. This piece is about the naming question that arrived next: should the productized version be called “Where There’s a Will, There’s a Way”? I want to argue both sides honestly, because the naming question is more consequential than it looks.

    The Idea

    “Where there’s a will, there’s a way” is the kind of phrase that lives in the back of your head from childhood. It is also, conveniently, a phrase that contains the word “Will” — which happens to be the name of the operator behind Tygart Media. The pun is built in. It has been sitting there, waiting, the entire time.

    The thought is this: if Tygart Media eventually ships a productized version of its accumulated operational knowledge — call it the Second Brain, call it Context-as-a-Service, call it whatever — the brand name almost writes itself. “Where There’s a Will, There’s a Way.” The product itself becomes “the Way.” A bolt-on knowledge layer that any operator can plug into their own AI workflow. They are not buying software. They are buying an opinion about how things should be done. They are buying a way.

    And the positioning is even better than the naming. “The Way” naturally implies prescription and opinionation — this is not a neutral tool, this is the accumulated answer to “how do you actually do this.” It is the difference between buying a hammer and buying the apprenticeship. It positions the product as something with a point of view, which is exactly what differentiates it from the empty memory layers of Mem0 and Letta and the rest.

    I think the naming is good. I want to argue that case first, because it deserves it. Then I want to make the case against, because the case against is also real, and an article that only makes the flattering case is content. An article that makes both cases honestly is infrastructure.

    The Case For “Where There’s a Will, There’s a Way”

    The pun is free distribution. Memorable brand names are the cheapest marketing channel that exists, and a name that makes people smile the first time they hear it is a name that gets repeated. The phrase already lives in millions of heads. Attaching the product to that pre-existing mental hook is leverage that no paid campaign can buy.

    The personal brand is the moat. The reason the productized context layer would be valuable in the first place is that it is built from one specific operator’s accumulated experience running 27+ client sites in a particular set of verticals with a particular methodology. Strip out the personal brand and you strip out the reason anyone would pay for it. The thing that makes “the Way” worth buying is that it is Will’s Way — the accumulated answer of one specific operator who has done the work. Other people’s accumulated answers would be different products. The personal connection is not a marketing layer on top of the product. The personal connection IS the product.

    “The Way” is the right shape for a bolt-on. Bolt-on products live or die on whether the buyer can immediately understand what they are getting. “An API for context retrieval” is technically accurate and emotionally inert. “The Way” tells the buyer everything they need to know in one syllable. It is the accumulated wisdom of an operator they trust, packaged as something they can plug into their own AI. The mental model arrives instantly. The sales cycle shortens.

    Opinionation is the differentiator. The entire memory-layer space is full of empty containers. Mem0, Letta, Zep, Hindsight — all of them sell you a place to put your knowledge. None of them ship with knowledge already loaded. “The Way” announces upfront that it ships pre-loaded with a specific opinion about how things should be done. That is either exactly what you want or exactly what you do not want, and either reaction is a good reaction, because both reactions are fast. Fast disqualification is more valuable than slow consideration. The buyers who are right for “the Way” will know in three seconds. So will the buyers who are wrong for it. Nobody wastes anyone’s time.

    It connects to the existing Tygart Media brand vocabulary. The site already has a sense of opinionation, an operator-with-a-point-of-view voice, and a willingness to say “here is how you should do this.” A product called “the Way” extends that voice rather than fighting it. The brand and the product reinforce each other instead of competing.

    It scales as a naming pattern. If “the Way” is the first product, the naming convention opens up a whole shelf. The Restoration Way. The Luxury Lending Way. The Cold Storage Way. Each vertical-specific knowledge package becomes its own product, all under the same parent brand. The naming is not just one good name. It is a system of names.

    The Case Against (Which Is Also Real)

    Now the other side. I want to be careful here, because Will explicitly asked for honest pushback, and the temptation in a piece like this is to make the counter-argument feel like a token gesture before reaffirming the original idea. That is not what this section is. The case against is real, and some of it is serious enough that it should change the design of the product even if the naming stays.

    Personal-brand products have a ceiling, and the ceiling is the person. Tim Ferriss can sell Tim Ferriss books. The Tim Ferriss book business is real, profitable, and durable. It is also forever capped at “things one specific person can plausibly stand behind.” The moment Ferriss steps away — whether by choice, by burnout, by accident, by anything — the brand has a problem that has no clean solution. Personal-brand products do not have succession plans, they have eulogies. If “the Way” is genuinely Will’s Way, then the product cannot survive Will leaving the building, and that creates a structural ceiling on how big the business can ever get and how cleanly it can ever be sold to anyone else.

    The bus factor is not just an exit problem. It is a daily problem. Every customer of “the Way” is implicitly betting that Will will keep being Will — keep working, keep producing, keep updating the knowledge base, keep being available when something breaks. A solo operator can absorb a vacation. A solo operator cannot absorb a serious illness, a family emergency, a six-month creative block, or any of the other things that happen to humans. The product brand says “Will is the value here,” and customers will be right to take that literally. The first time Will is unavailable for two weeks during a customer crisis, the bus factor stops being theoretical.

    The pun only lands for people who know Will. To Will, to Stefani, to Pinto, to anyone in the Tygart Media orbit, “Where there’s a Will, there’s a Way” is a clever wink. To a stranger reading it cold on a landing page, it is just an idiom. The pun is invisible to the people who do not already know who Will is. That means the naming does not actually do double duty — it does single duty for the audience that already knows him, and reverts to “generic motivational phrase” for everyone else. The brand depends on context that most prospects do not have.

    “The Way” implies a finished thing. The accumulated knowledge behind Tygart Media is not a finished thing. It is a moving target. Methodology changes. New skills get added. Old skills get deprecated. The Borro playbook from six months ago is not the Borro playbook today. A product called “the Way” implies a fixed answer, but the actual value of the underlying system is that it is constantly being updated. Customers buying “the Way” might reasonably expect a stable methodology document. What they would actually be subscribing to is a methodology that mutates every week. That mismatch between expectation and reality is a support burden waiting to happen.

    Opinionation cuts both ways. The same thing that makes “the Way” a sharp differentiator also makes it brittle. If the underlying methodology turns out to be wrong about something — and over a long enough time horizon, every methodology turns out to be wrong about something — pivoting is harder when your brand name is literally the prescription. Mem0 can change its retrieval algorithm without changing its identity. “The Way” cannot easily change its way without changing its name.

    Bolt-on products face a discoverability problem that opinionation makes worse. Bolt-on tools have to be installed alongside something else. The buyer is already committed to a primary stack — Cursor, ChatGPT, Claude, their own agent framework — and the bolt-on has to fit. Highly opinionated bolt-ons fit fewer stacks, because each opinion is a constraint. A neutral memory layer fits everywhere. “The Way” fits the subset of stacks where the operator is willing to import someone else’s opinion about how things should work. That subset might be smaller than it looks.

    Most importantly: the moat might not actually be Will. This is the hardest counter-argument, and it is the one that should be sat with longest. Will’s intuition is that the moat is the personal brand — Will’s accumulated experience, voice, and judgment. But it is possible that the actual moat is the methodology, not the person. If the methodology is the moat, then attaching a personal-brand name to it is leaving money on the table. A methodology can scale, license, train other operators, and outlive its creator. A personal brand cannot. The naming choice is therefore also a strategic choice about which kind of business is being built. “The Way” optimizes for the personal-brand version. A more generic name optimizes for the methodology-as-product version. These are different businesses with different ceilings, and the naming decision quietly commits to one of them.

    The Synthesis

    Both sides are real. The pun is genuinely clever and the positioning is genuinely strong. The bus factor and personal-brand ceiling are also genuinely real and should not be dismissed as “we’ll figure it out later,” because the naming choice is what locks them in.

    The version that probably resolves the tension is this: use the personal-brand naming for the launch and the early traction, with a deliberate plan to abstract the methodology away from the personal brand once the methodology is mature enough to stand on its own.

    Concretely: launch “the Way” as a Will-branded product. Use the pun. Use the personal voice. Lean into the opinionation. Get the early customers who specifically want Will’s accumulated wisdom packaged as a service, because those customers will be the highest-quality early users and the best teachers about what the product actually needs to be. Treat the personal-brand version as Phase 1.

    Then, with the revenue and the validation from Phase 1, build Phase 2 as the depersonalized methodology layer. Document the patterns so they could be applied by an operator who is not Will. Train other operators. License the methodology. Keep “the Way” as the original flagship, but build a Methodology Edition or an Enterprise Edition or whatever the right name turns out to be that does not depend on Will being in the building. Phase 1 funds Phase 2. Phase 2 is the version with no ceiling.

    This is how Basecamp turned 37signals consulting into Basecamp the product, and how Tim Ferriss turned Tim Ferriss the brand into a media company that does not require Tim Ferriss to be in the room every day. The pattern is: start with the personal brand because it is the cheapest way to get the first hundred customers, and abstract away from it as soon as the abstraction is honest.

    The naming question, framed this way, is not really “should we call it the Way or something else.” It is “what phase is the product in, and what is the plan for the next phase.” If there is a plan for the next phase, “the Way” is a great name. If there is no plan for the next phase, “the Way” is a name that will eventually become a ceiling.

    The Bolt-On Question

    One more piece worth calling out, because it is buried in the original idea and deserves to be made explicit. Will framed the product as a “bolt-on.” That is the right framing, and it is more important than the naming.

    A bolt-on is a low-commitment purchase. The buyer keeps their existing stack. The buyer adds a small thing on the side. If the bolt-on works, the buyer keeps it. If it does not, the buyer removes it with no migration cost. Bolt-ons sell faster, churn earlier, and have lower expansion revenue than full-stack products. They also have a much shorter sales cycle and a much lower barrier to entry.

    For a single-operator product launching from scratch, the bolt-on shape is exactly right. Full-stack products require a sales team, an implementation team, a support team, and a customer success team. A solo operator cannot ship any of those. A bolt-on product can be launched by one person, supported by documentation, and adopted with a single API key. The unit economics work. The operational footprint stays small enough that one person can run it.

    So whatever it ends up being called, the bolt-on framing should stay. “The Way” works as a bolt-on. It would not work as a full-stack platform — the personal-brand and bus-factor problems would crush it at scale. As a small, opinionated, plug-this-in-to-make-your-AI-better tool, it has a real shape that one person can ship and support.

    Verdict

    I think Will should use the name. I also think Will should use it with a clear understanding of what it is buying him and what it is costing him.

    What it buys: free distribution from a memorable pun, fast positioning that needs no explanation, immediate differentiation from neutral memory layers, alignment with the existing Tygart Media voice, and a naming pattern that scales to additional vertical-specific products.

    What it costs: a structural ceiling defined by the operator’s personal capacity, a bus factor that customers will eventually notice, a name that locks in the current methodology more tightly than the methodology actually deserves, and a strategic commitment to the personal-brand version of the business over the methodology-as-product version.

    If the plan is “ship Phase 1 fast, learn what the product actually needs to be, abstract toward Phase 2 within eighteen months,” then the costs are acceptable and the benefits are real. If the plan is “this is the product forever,” then the costs eventually overwhelm the benefits, and the right move is a more generic name that does not paint the business into a corner.

    The naming is not really the question. The question is whether there is a Phase 2, and what it looks like, and when it starts. Get clear on that, and the naming answers itself.


    Knowledge Node Notes

    Structured residue for future retrieval.

    Core Claim

    “Where There’s a Will, There’s a Way” is a strong product name for a Phase 1 launch of the productized Tygart Media context layer, but it commits the business to a personal-brand model with structural ceilings. The naming question is really a phase-of-business question. Use the name if there is a Phase 2 plan. Pick a more generic name if there is not.

    The Idea (As Proposed)

    • Productize Tygart Media’s accumulated context layer as a bolt-on for other operators’ AI workflows
    • Brand it “Where There’s a Will, There’s a Way” — pun on Will Tygart’s name
    • Product itself is called “the Way”
    • Positioning: opinionated knowledge layer, not neutral memory infrastructure
    • Shape: small, plug-in, low-commitment bolt-on rather than full platform

    The Case For

    • Free distribution from memorable pun — pre-existing mental hook in millions of heads
    • Personal brand IS the moat — value prop is one specific operator’s accumulated answers, not a generic methodology
    • “The Way” is right shape for a bolt-on — instant mental model, short sales cycle
    • Opinionation is the differentiator vs empty memory layers (Mem0, Letta, Zep, Hindsight)
    • Aligns with Tygart Media voice — extends rather than fights the existing brand
    • Scales as a naming pattern — The Restoration Way, The Luxury Lending Way, etc.

    The Case Against

    • Personal-brand ceiling — Tim Ferriss problem. Capped at what one human can plausibly stand behind. No succession plan, only eulogies.
    • Bus factor as daily problem — vacations OK, illness/emergency/burnout not OK. First two-week unavailability during a customer crisis is when this stops being theoretical.
    • Pun only lands for people who already know Will — strangers see a generic motivational phrase. Brand depends on context most prospects don’t have.
    • “The Way” implies a finished thing — but the underlying methodology mutates weekly. Expectation/reality mismatch = support burden.
    • Opinionation cuts both ways — pivoting is harder when your brand name IS the prescription.
    • Bolt-on discoverability — opinionated bolt-ons fit fewer stacks because each opinion is a constraint.
    • Hardest counter: the actual moat might be the methodology, not the person. If so, personal-brand naming leaves money on the table because methodology can scale/license/outlive creator. Personal brand cannot.

    Synthesis / Recommendation

    Two-phase strategy:

    • Phase 1 — Personal brand launch. Use “the Way.” Use the pun. Lean into Will’s voice and opinionation. Get first 100 customers who specifically want Will’s wisdom packaged. They are the best teachers about what the product needs to be.
    • Phase 2 — Methodology abstraction. Use Phase 1 revenue + validation to build a depersonalized methodology layer. Document patterns so an operator who is not Will could apply them. License. Train. “The Way” stays as flagship; Methodology Edition / Enterprise Edition removes the bus factor.

    Phase 1 funds Phase 2. Phase 2 has no ceiling.

    Pattern precedents: Basecamp turning 37signals consulting into a product. Tim Ferriss turning the personal brand into a media company that doesn’t require him in the room daily.

    The Bolt-On Framing (Most Important Point)

    The bolt-on shape is more strategically important than the name. For a solo operator launching from scratch:

    • Bolt-ons sell faster (no migration, no commitment)
    • Bolt-ons need no sales/CS/implementation team
    • Bolt-ons can be launched by one person and supported by documentation
    • Full-stack platform would crush a solo operator under operational weight

    Whatever the name, keep the bolt-on shape. “The Way” works as a bolt-on. It would not work as a full platform.

    What This Locks In vs What It Leaves Open

    Locks in: opinionation as a permanent product trait, personal brand as central value prop, Will’s voice as the canonical voice, Tygart Media as parent brand.

    Leaves open: pricing model, technical architecture, target vertical, distribution channel, methodology scope, eventual depersonalization plan.

    Connection to the Series

    • Article 1 (Second Brain as API): Could you sell access to your context layer? Yes, with clean-room architecture and a real legal stack.
    • Article 2 (Dual Publish): The deposit mechanism that builds the context layer.
    • Article 3 (Articles as Infrastructure): The deposits are not content — they are infrastructure being minted.
    • Article 4 (this one): The product question — how to package and name the productized version of the accumulated infrastructure. Answer: “the Way” works for Phase 1, with a Phase 2 abstraction plan.

    Single arc: can we sell our context → here is how the context gets built → the deposits are infrastructure not content → here is what to name the product when we package it.

    Action Items

    • [ ] Decide whether there is a Phase 2 plan. If yes, “the Way” is good. If no, pick a more generic name.
    • [ ] Sketch a Phase 2 hypothesis even if it is wrong — having any plan beats having none
    • [ ] Reserve domains: wherestheresaway.com, thewayapi.com, tygartmedia.com/way, etc.
    • [ ] Test the pun on people who do not already know Will. Does it land? Does it confuse? Data beats intuition here.
    • [ ] Draft a one-page “what the Way is” landing page as a forcing function. Writing the landing page will reveal whether the positioning actually holds together.
    • [ ] Decide on bolt-on vs platform — bolt-on is the right answer but worth being explicit about it

    Tags

    brand naming · personal brand · bus factor · bolt-on products · methodology as product · phase 1 phase 2 · Tim Ferriss model · Basecamp model · Where There’s a Will There’s a Way · the Way · Will Tygart · second brain productization · opinionated software · context as a service · Tygart Media product strategy · single operator scaling · personal brand ceiling · solo operator economics

    Last updated: April 2026.