Tygart Media Editorial - Tygart Media

Category: Tygart Media Editorial

Tygart Media’s core editorial publication — AI implementation, content strategy, SEO, agency operations, and case studies.

  • Can Claude AI Generate Images? Complete Capabilities Guide

    Can Claude AI Generate Images? Complete Capabilities Guide

    Updated September 30, 2026.

    Claude AI · Fitted Claude

    Direct answer: Claude does not generate photos or illustrations the way Midjourney, DALL·E, or Gemini Imagen do. It can analyze images you upload, build diagrams and interactive visuals with HTML and SVG in chat (beta on web and desktop), and—through MCP connectors—call external image models when you wire them up. For operators tracking how AI answers cite your brand, that split matters when you document tools in content and monitor AI citations.

    What Claude still cannot do: native image generation

    Claude is a reasoning and vision model—not a diffusion image generator.

    Anthropic’s help center states plainly that Claude doesn’t generate photos or illustrations like dedicated image tools (Can Claude produce images?, updated March 2026). That has not changed across current Claude model releases in 2026. If you need marketing hero shots, photorealistic scenes, or meme-style art, use a purpose-built generator:

    • ChatGPT — built-in GPT Image / DALL·E workflow inside one app
    • Midjourney — strong aesthetic control for creative and brand imagery
    • Adobe Firefly — commercial-friendly generation inside Creative Cloud
    • Google Gemini — Imagen-family output in the Gemini app
    • Stable Diffusion — open weights; self-host or use a hosted wrapper

    Claude’s value is elsewhere: reading job-site photos, summarizing damage docs, and drafting the copy that goes beside those assets—work that shows up when you measure whether AI surfaces your pages in LLM visibility programs.

    What Claude can do with images and visuals

    Upload, analyze, extract, and pair Claude with external image tools.

    Vision: analyze and describe uploads

    Upload photos, screenshots, PDF scans, or charts. Claude describes content, spots damage or equipment, reads labels, and answers targeted questions. That includes handwriting and cramped table screenshots—common on restoration estimates and insurer portals.

    Text extraction (OCR-style)

    Point Claude at a whiteboard photo, moisture log, or phone picture of a printed scope. It transcribes text and can reformat it into a checklist, email, or SOP draft.

    Charts, diagrams, and custom visuals in chat

    Since early 2026, Claude can build diagrams, charts, and interactive visuals directly in the conversation using HTML and SVG—beta on Claude web and desktop. You can iterate in plain language instead of exporting static AI art. This is code-based output, not pixel generation from a diffusion model.

    SVG and artifact-style graphics

    Ask for flowcharts, simple icons, or labeled diagrams as SVG. Claude writes vector code you can paste into docs or slide decks. Quality depends on prompt clarity; complex brand illustrations still belong in Figma or a generator.

    Claude Design (layouts and slides, not AI photos)

    Anthropic Labs shipped Claude Design in April 2026 as a research preview for Pro, Max, Team, and Enterprise subscribers. It helps you produce slides, one-pagers, and prototypes from prompts or uploads, with optional design-system import. It composes visual work—it does not replace Midjourney for photorealistic images.

    Image generation prompts and MCP connectors

    Claude writes strong prompts for Midjourney, Firefly, and similar tools when you ask for tool-specific syntax. To generate pixels inside Claude, connect an image model through an MCP server (remote connectors are supported on paid tiers; the free tier allows limited remote MCP). Claude calls the tool; the external model renders the image.

    Prompt engineering for your content stack

    Teams publishing GEO-focused guides often pair Claude’s analysis with separate generators, then track which pages earn mentions in AI answers—patterns we summarize in GEO case studies for 2026.

    Quick comparison: Claude vs image generators

    Task Claude Dedicated image AI
    Photorealistic marketing image No (use MCP + external model) Yes
    Read a job-site photo Yes Varies / not core
    Interactive chart in chat Yes (HTML/SVG beta) No
    Slide or layout draft Claude Design (paid preview) Not primary use
    Brand-safe commercial stills Via Firefly etc. Firefly, stock, or custom

    Frequently Asked Questions

    Vision input and visual output are different limits.

    Can Claude make images?

    No. Claude does not generate photos or illustrations on its own. Use Midjourney, ChatGPT with GPT Image, Adobe Firefly, Gemini Imagen, or Stable Diffusion—or connect one of those through MCP.

    Can Claude read or analyze images I upload?

    Yes. Claude analyzes photos, screenshots, documents, and charts on Free, Pro, Max, Team, and Enterprise plans, subject to your plan’s usage limits.

    Can Claude create diagrams and charts in chat?

    Yes. Claude can build diagrams, charts, and interactive visuals with HTML and SVG in conversation. Anthropic lists this as beta on Claude web and desktop as of March 2026.

    What is Claude Design?

    Claude Design is an Anthropic Labs product for slides, layouts, and prototypes from prompts or uploads. It is a research preview for paid Claude plans—not a replacement for a diffusion image generator.

    Can Claude generate images if I add an MCP connector?

    Yes. When you attach an MCP server that exposes image generation, Claude can call that tool and return rendered images in the thread. Rendering still happens on the connected service, not inside Claude’s core model.

    Should I use Claude or ChatGPT for visuals?

    Use ChatGPT when you want native image generation in one chat. Use Claude when you need stronger document reasoning, code-based diagrams, or a workflow that combines vision analysis with external tools via MCP.


    Need this set up for your team?
    Talk to Will →

  • Claude Projects: Setup, Knowledge Bases & Custom Prompts

    Claude Projects: Setup, Knowledge Bases & Custom Prompts

    Last refreshed: August 30, 2026

    Claude AI · Fitted Claude

    Claude Projects are the most underutilized feature on paid Claude plans. Without Projects, every new conversation starts from scratch. With Projects, you create persistent knowledge bases that Claude draws on automatically. This guide shows you how to set up Projects that actually improve your work.

    Claude Projects Features by Plan (June 2026)

    FeatureFreePro ($20/mo)Team ($25/seat)Enterprise
    Projects availableNoYesYesYes
    Number of Projects—UnlimitedUnlimitedUnlimited
    Files per Project—Up to 20 filesUp to 20 filesCustom
    Custom instructionsNoYesYesYes
    Shared Projects (team)NoNoYesYes
    Persistent contextNoYesYesYes

    What Claude Projects Do

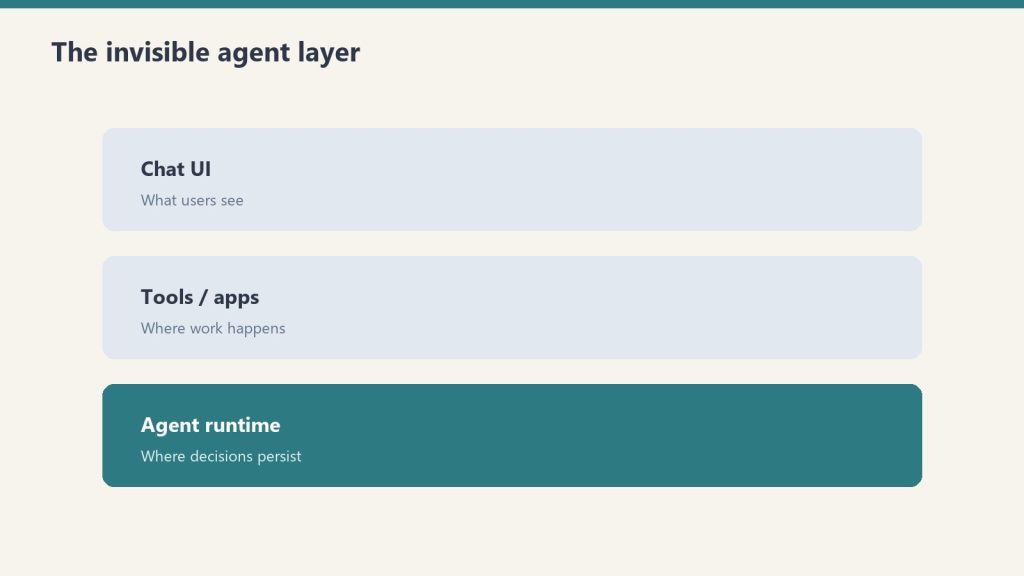
    Three stacked layers: chat UI, tools, agent runtime
    What Claude Projects do.
    • Persistent system prompts: Instructions Claude follows in every Project conversation
    • Knowledge base files: Documents, PDFs, and data Claude references without re-uploading
    • Conversation history: All Project conversations are grouped and accessible
    • Separate memory spaces: Each Project has isolated memory

    Setting Up a Project

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Setting up a project.
    1. In Claude.ai, click “New Project” in the left sidebar
    2. Name your Project specifically (“Content Writing” not “Work”)
    3. Write your system prompt in Project Instructions
    4. Upload knowledge base files
    5. Start a conversation within the Project

    Writing an Effective System Prompt

    Diagram comparing a long context window bar with a shorter output limit bar
    Writing an effective system prompt.

    A strong system prompt tells Claude: who you are and what you do, primary tasks for this Project, tone and style preferences, output format requirements, domain-specific knowledge to assume, and anything Claude should never do in this Project. A weak system prompt (“You are a helpful assistant”) gives Claude nothing useful.

    Project Ideas by Role

    • Writers: Upload brand voice guide, audience personas, and style examples
    • Developers: Upload architecture docs, API documentation, and coding standards
    • Legal: Upload relevant statutes, prior contracts, and compliance frameworks
    • Researchers: Upload literature review, key papers, and research notes

    Frequently Asked Questions

    Are Claude Projects available on the free plan?

    No. Projects require a Claude Pro subscription or higher.

    Does Claude remember everything across Project conversations?

    Claude has access to Project knowledge base files and system prompt in every conversation. Specific conversation memory depends on whether Claude’s memory feature is enabled.


    Need this set up for your team?
    Talk to Will →

    What is Claude Projects?

    Claude Projects is a feature in claude.ai (Pro, Max, Team, Enterprise plans) that lets you create persistent workspaces. Each Project has its own custom instructions, uploaded knowledge files, and conversation history that carries across sessions. Claude remembers everything in the Project — unlike regular conversations that start fresh each time.

    How do I create a Claude Project?

    In claude.ai, click ‘New Project’ in the left sidebar. Give it a name, write custom instructions (what Claude should know about you and the work), and upload any relevant files — PDFs, text documents, code files, CSVs. Then start a conversation. Everything in the Project persists — new conversations in the same Project share the same context.

    What files can I upload to a Claude Project?

    Claude Projects support text files (.txt, .md), PDFs, code files (.py, .js, .ts, etc.), CSV files, and images. Maximum file size is 30MB per file, up to 20 files per Project on Pro/Max/Team plans. For best results, upload reference documents, style guides, company knowledge, and anything Claude should know consistently across conversations.

    Can my team share a Claude Project?

    Yes, on Claude Team and Enterprise plans, Projects can be shared across team members. Shared Projects give everyone the same custom instructions and knowledge base, so the whole team benefits from the same context setup. Individual conversations within a shared Project remain private unless explicitly shared.

  • Claude Rate Limits: Every Plan & API Tier (2026)

    Claude Rate Limits: Every Plan & API Tier (2026)

    Updated November 2, 2026 — added direct answers on Claude Pro usage limits and reset windows, sourced from Anthropic’s published pricing.

    Updated October 28, 2026: Made infographic diagrams clickable to open full-size images.

    Last verified: November 5, 2026 (Pacific Time). November 2026 update: Anthropic has replaced the deposit-based API tier system — the corrections are noted in the sections below, and two older tables are marked as the retired system’s record.

    Official links: Live status page · API docs · Upgrade plans · Help center

    June 2026 note: Anthropic’s compute expansion in May 2026 roughly doubled rate limits across paid tiers (covered in our May 2026 updates), and the lineup grew again with Claude Fable 5 in June. The API tier tables below reflect current published limits.

    Direct Answer (November 2026): Claude rate limits scale by plan: Free accounts get dynamic session limits; Pro ($20/mo) provides at least 5x the Free plan’s capacity per 5-hour session (Anthropic publishes no fixed message counts; usage varies with message length, attachments, conversation length, and model); Max ($100/mo) and Ultra ($200/mo) offer extended quotas for Claude Code. API rate limits operate on rolling token buckets under the current spend-based usage tiers (Evaluation, Start, Build, Scale, and Custom), with cached tokens exempt from input rate caps.

    Claude AI · Fitted Claude

    Claude rate limits are the single most complained-about aspect of the product. A viral Reddit post on the topic received over 1,060 upvotes. This guide explains what the limits are at every plan tier, why they exist, and every community-tested strategy for getting more out of your plan before hitting the wall.

    1. Anthropic API Usage Tier Qualifications & Thresholds

    Four ascending steps labeled Start Grow Scale Enterprise without RPM numbers
    Tiers climb with spend and reliability — confirm live console limits.

    Your API account’s rate limits are spend-based. The current system has five tiers — Evaluation, Start, Build, Scale, and Custom — and your tier follows your monthly spend level rather than a deposit balance:

    Usage Tier Monthly Spend Cap Notes
    Evaluation May start as low as $5 or $500 Starting tier; the initial cap depends on risk checks
    Start $500
    Build $1,000
    Scale $200,000
    Custom No predefined cap Arranged with Anthropic

    Per-model RPM and TPM limits for each tier are published in the Console and in Anthropic’s rate-limits documentation. This table replaces the retired deposit-based Tier 1–4 table ($5 deposit, cumulative-spend thresholds) in November 2026.

    2. Requests Per Minute (RPM) and Tokens Per Minute (TPM) by Model

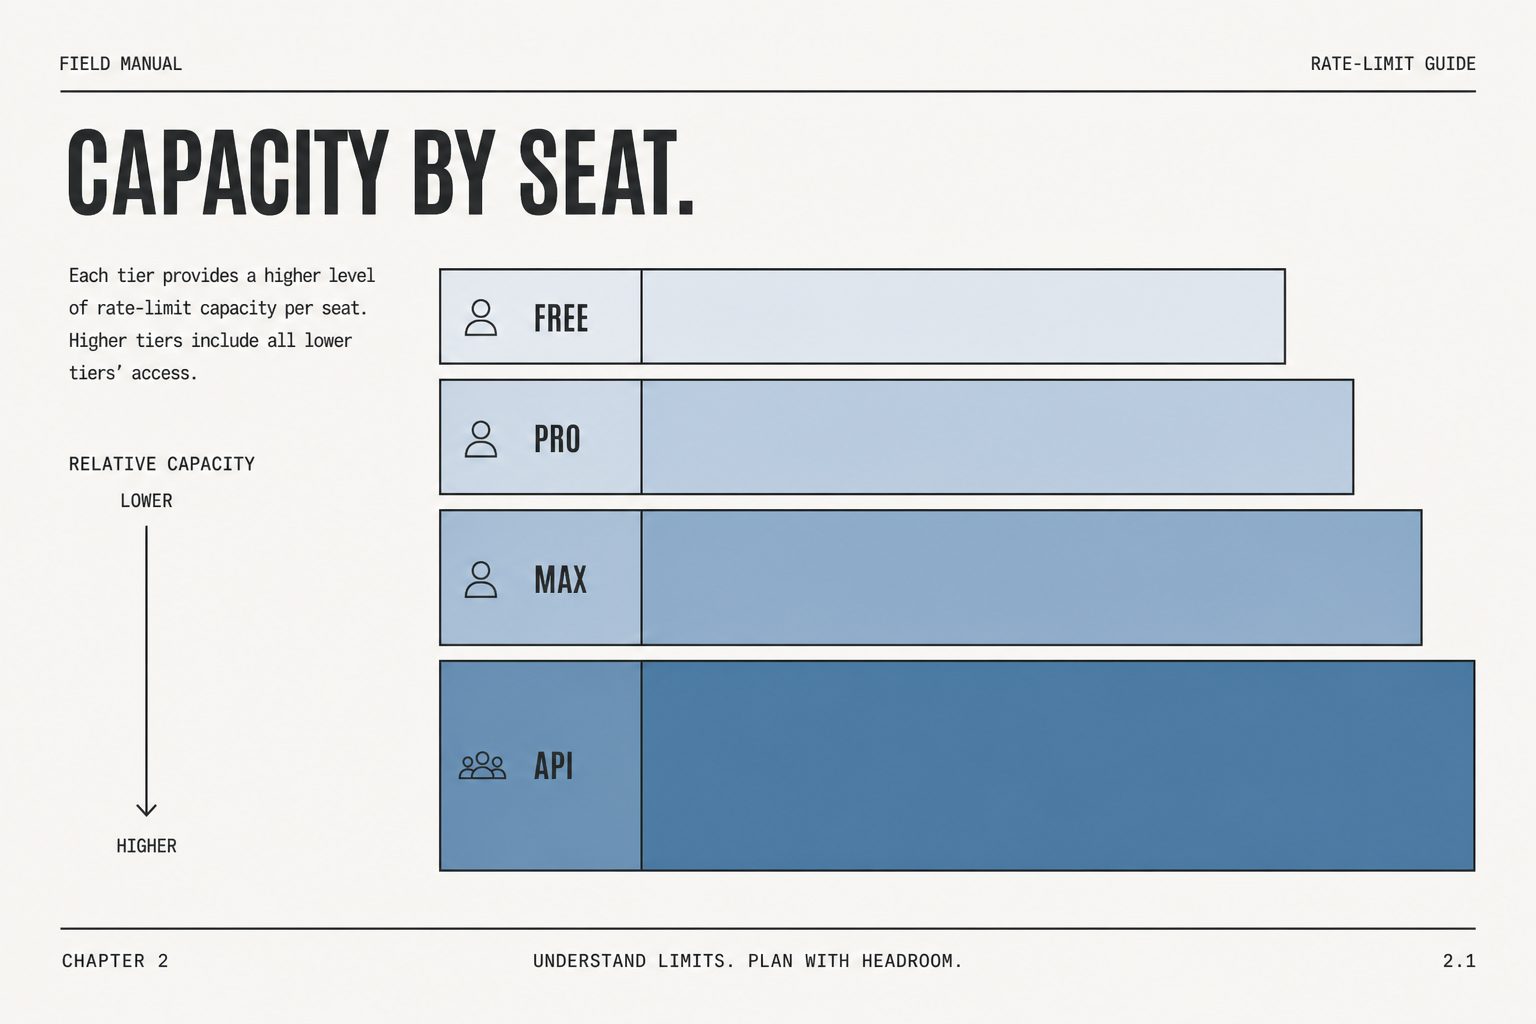
    Stacked capacity bands for Free, Pro, Max, and API tiers without numeric RPM or TPM values
    RPM/TPM differ by model — shapes matter more than memorized tables.

    Rate limits apply independently across model families. High-intelligence models (Opus) have tighter token concurrency caps than lightweight models (Haiku):

    Anthropic publishes standard per-minute limits for the current usage tiers, read from Anthropic’s rate-limits documentation in October 2026. Limits are requests per minute (RPM), input tokens per minute (ITPM), and output tokens per minute (OTPM), enforced per model class at the organization level:

    Model Start Build Scale
    Claude Opus 5.5 1,000 / 2,000,000 / 400,000 5,000 / 5,000,000 / 1,000,000 10,000 / 10,000,000 / 2,000,000
    Claude Sonnet 5.5 1,000 / 2,000,000 / 400,000 5,000 / 5,000,000 / 1,000,000 10,000 / 10,000,000 / 2,000,000
    Claude Haiku 5.5 1,000 / 2,000,000 / 400,000 5,000 / 5,000,000 / 1,000,000 10,000 / 10,000,000 / 2,000,000
    Claude Fable 5.1 and Fable 5 (combined) 1,000 / 500,000 / 100,000 2,000 / 1,500,000 / 300,000 4,000 / 4,000,000 / 800,000

    Models still available from the prior generation (Sonnet 5, Opus 5, Haiku 4.5) carry the same standard Start limits. New organizations may begin in an Evaluation tier with lower limits that Anthropic does not publish in the standard table, and the Custom tier’s limits are arranged with Anthropic. Your Console Rate limits page shows your account’s actual tier and limits.

    3. Diagnosing and Handling HTTP 429 Rate Limit Errors

    Laptop showing a blurred rate-limit style error with hourglass and coffee on the desk
    429 is a pause — backoff, then retry with smaller batches.

    When your application exceeds either its Requests-Per-Minute or Tokens-Per-Minute cap, the Anthropic API responds with an HTTP 429 Too Many Requests error containing response headers detailing when capacity will reset:

    • retry-after: Number of seconds to wait before retrying.
    • anthropic-ratelimit-requests-remaining: Remaining requests available in the current 60-second window.
    • anthropic-ratelimit-tokens-remaining: Remaining token budget available in the current window.
    • anthropic-ratelimit-tokens-reset: ISO timestamp indicating when the token pool will fully refresh.

    Production Rate Limit Mitigation Playbook

    1. Exponential Backoff with Full Jitter: Never retry immediately in a tight loop. Implement an exponential backoff formula with randomized jitter to prevent thundering herd spikes on your backend.
    2. Utilize Prompt Caching: Cached prefix tokens read from memory bypass standard token generation latency and dramatically streamline token processing windows. Read our full Claude AI Pricing and Token Rates Guide for complete caching cost structures.
    3. Route Heavy Jobs to the Batch API: For bulk processing, offline report generation, and data extraction, use the Anthropic Messages Batch endpoint. Batch jobs run against separate capacity pools, avoiding live interactive rate caps while cutting token costs by 50%.

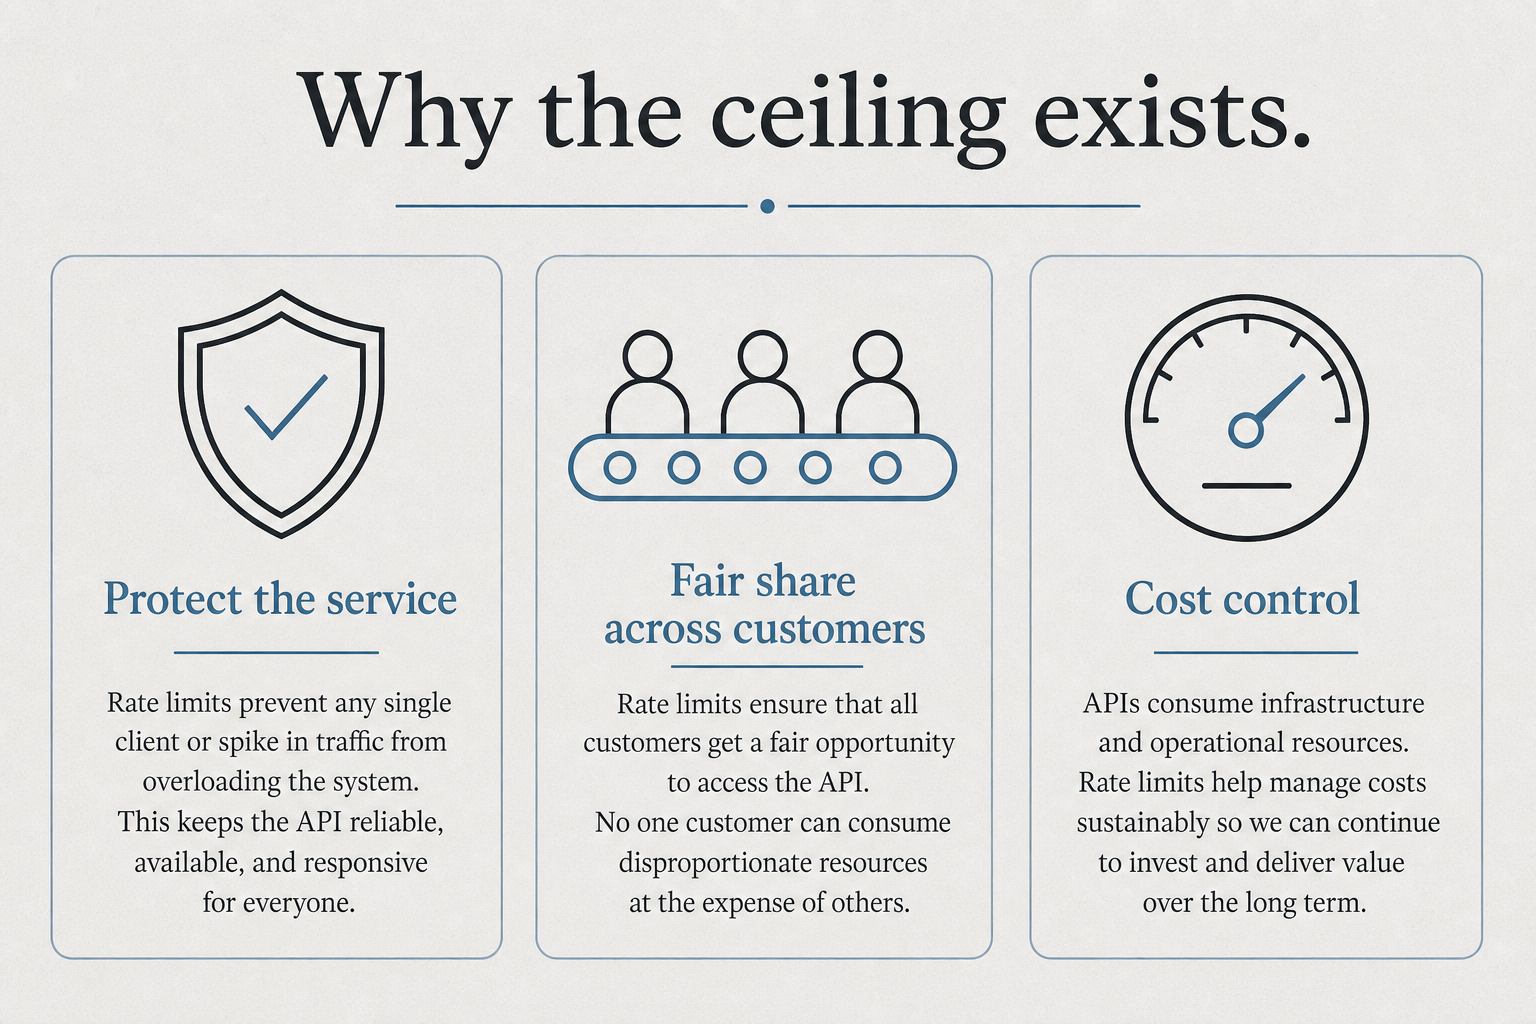
    Why Rate Limits Exist

    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits

    Claude’s rate limits are primarily about compute capacity, not money. Running Claude Opus 4.8 on complex tasks requires enormous GPU resources. Anthropic limits usage to ensure consistent performance for all users. The limits are enforced per rolling time window, not per calendar day.

    Rate Limits by Plan

    Stacked capacity bands for Free, Pro, Max, and API tiers without numeric RPM or TPM values

    Free Plan

    Access to Claude Sonnet 5 with limited daily usage. Heavy users hit limits after 5-10 substantive prompts. Anthropic adjusts dynamically based on system load.

    Claude Pro ($20/month)

    Roughly 5x the usage of free. Community consensus: approximately 12 heavy prompts per session before throttling. Light prompts run much longer before hitting limits.

    Claude Max 5x ($100/month)

    Approximately 5x Pro limit. Anthropic publishes no per-window token figures; paid plans carry a five-hour session limit and a weekly usage limit across all models.

    Claude Ultra ($200/month)

    10x the Pro weekly limit, with no 5-hour limit for verified accounts. The top tier for developers running Claude Code for extended sessions and professionals processing large document volumes daily.

    API Rate Limits (Current Usage Tiers)

    API limits are measured in requests per minute (RPM), input tokens per minute (ITPM), and output tokens per minute (OTPM), enforced per model class at the organization level. The current usage tiers and their monthly spend caps are in section 1 above; the standard per-minute limits are in section 2. Your tier advances automatically with usage history and account standing — not by deposit or cumulative credit purchases; the deposit-based Tier 1–4 system is retired. Earlier versions of this page reproduced the retired system’s tables in this section; they were removed in the November 5, 2026 rebuild because the system they describe no longer exists, and the retired figures remain available in this page’s revision history.

    Cache-aware ITPM: for current models, only uncached input tokens count toward your ITPM limit — cache_read_input_tokens do not. With an 80% cache-hit rate against a 2,000,000 ITPM limit you can effectively process ~10,000,000 total input tokens per minute, so prompt caching is the single best lever for raising effective throughput.

    When you hit a limit, the API returns a 429 with a retry-after header (seconds to wait), plus anthropic-ratelimit-* headers showing remaining requests/tokens and reset times. Limits use a token-bucket algorithm — capacity replenishes continuously rather than resetting at a fixed clock time. The Message Batches API and Managed Agents endpoints have their own separate limits.

    When are Claude’s usage limits on the Pro plan?

    Claude Pro usage limits operate under a two-tiered allowance structure: a short-term rolling session window that resets every 5 hours, and an overarching weekly cap that resets once per week at a fixed schedule specific to your account:

    • 5-Hour Rolling Session Window: Pro plan users receive at least 5 times the usage capacity of the free tier per session. Your 5-hour limit timer begins when you send your first message in an active session block, and full session capacity replenishes continuously 5 hours later.
    • Weekly Account Cap: In addition to the 5-hour session allowance, Pro accounts are subject to a weekly usage limit that governs total consumption across all models, Projects, and tools (including Claude Code and Cowork). This limit resets at a fixed, recurring day and time assigned to your account, which you can monitor under Settings > Usage.
    • Factors That Consume Limits Fastest: Anthropic’s documentation highlights three primary drivers of rapid usage consumption:
      1. Model choice: Flagship reasoning models like Claude Opus consume your session budget substantially faster than everyday models like Sonnet or Haiku.
      2. Conversation length: Because Claude re-processes the entire conversation history with every new message, long extended threads consume progressively larger token volumes on each subsequent turn.
      3. File attachments: Attaching large codebases, PDFs, or data files significantly increases the prompt token size sent on every turn within that chat.

    Where Anthropic does not publish fixed message counts, capacity scales dynamically based on real-time platform traffic. When limits are reached, users can either wait for the rolling reset or upgrade to Claude Max for 5x expanded session and weekly headroom.

    Community-Tested Workarounds

    Laptop showing a blurred rate-limit style error with hourglass and coffee on the desk
    • Use Projects with persistent system prompts — reduces token overhead per conversation
    • Use Sonnet for routine tasks, Opus 4.8 for complex ones, and Fable 5 for the most demanding work — don’t burn your limit budget on tasks Sonnet handles equally well
    • Batch related work into single long sessions — starting five conversations uses more overhead than one long one
    • Compress your inputs — extract only relevant sections from long documents before pasting
    • Use the API for high-volume predictable workflows — more limit-efficient than the consumer interface for automated tasks

    Frequently Asked Questions

    How many messages can I send on Claude Pro?

    No published exact number — depends on message complexity. Community estimates suggest roughly 12 heavy messages per session before throttling begins on Pro.

    Do Claude rate limits reset daily?

    Rate limits use a rolling time window, not a fixed midnight reset.

    >Part of the complete guide: Claude Pricing, Plans & Limits

  • Claude Code vs Windsurf: 2026 AI Coding Tool Comparison

    Claude Code vs Windsurf: 2026 AI Coding Tool Comparison

    Last refreshed: August 30, 2026

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Claude AI · Fitted Claude

    Claude Code and Windsurf represent two different visions of AI-assisted development — one terminal-native and model-focused, the other IDE-native and workflow-focused. Both are serious tools for professional developers in 2026. This comparison covers what actually matters: coding quality, context management, workflow fit, and cost.

    What They Are

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    What they are.

    Claude Code is Anthropic’s terminal-native AI coding tool. You install it as an npm package, authenticate with your Claude account, and work directly in your shell. It uses Claude models exclusively and has a 1-million-token context window for large codebases. It’s designed for developers who think in the command line.

    Windsurf (formerly Codeium) is an AI-native IDE — a full development environment built around AI assistance. It includes a traditional code editor with AI deeply embedded throughout: autocomplete, multi-file editing, natural language commands, and a chat interface. It supports multiple models including Claude, GPT-4o, and its own models.

    Feature Comparison

    Three stacked layers: chat UI, tools, agent runtime
    Feature comparison.
    Feature Claude Code Windsurf
    Interface Terminal Full IDE (VS Code-based)
    Model Claude only Multi-model (Claude, GPT-4o, own models)
    Context window 1M tokens Varies by model
    Autocomplete No Yes (supercomplete)
    Multi-file editing Yes Yes (Cascade)
    Git integration Yes Yes
    Codebase indexing Yes (via context) Yes (semantic search)
    Natural language commands Yes Yes (Cascade)
    Price Max sub ($100+/mo) or API Free tier + $15/mo Pro

    Model Performance

    Claude Code’s underlying model — Opus 4.6 — scores 80.8% on SWE-bench Verified, one of the highest published scores for any model on real-world engineering tasks. Windsurf can access Claude models via its multi-model architecture, but its proprietary models score lower on the same benchmark.

    If raw model performance on complex tasks is the priority, Claude Code’s direct access to Claude Opus 4.7 gives it an edge.

    Developer Experience

    Claude Code has a steeper initial learning curve — there’s no GUI, and effective use requires understanding how to structure prompts for agentic coding sessions. Once mastered, many developers find the terminal interface faster and less distracting than a full IDE.

    Windsurf has a gentler onboarding curve. Developers already comfortable in VS Code will feel at home immediately. The autocomplete, Cascade multi-file editing, and inline AI chat create a lower-friction introduction to AI-assisted coding.

    Pricing Reality

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Pricing reality.

    This is where Windsurf has a clear advantage for cost-conscious developers. Windsurf’s Pro plan runs $15/month with a generous free tier. Claude Code requires Claude Max at $100/month minimum, or API usage (which can be cheaper for low-volume use but expensive at scale).

    For developers just starting with AI coding tools, Windsurf’s entry point is meaningfully more accessible.

    Choose Claude Code If You…

    • Prefer terminal-native workflows and spend most of your time in the shell
    • Work with very large codebases that benefit from the 1M token context window
    • Need the highest possible model performance on complex engineering tasks
    • Are already on a Claude Max subscription

    Choose Windsurf If You…

    • Want an IDE experience with AI deeply integrated throughout
    • Are new to AI coding tools and want a gentle learning curve
    • Need persistent autocomplete alongside agentic coding capabilities
    • Want model flexibility or lower entry cost

    Frequently Asked Questions

    Is Claude Code better than Windsurf?

    For terminal-native developers prioritizing model performance: Claude Code has the edge. For IDE-native developers wanting lower cost and full-featured editor integration: Windsurf is the better fit.

    Can Windsurf use Claude models?

    Yes. Windsurf supports multiple models including Claude. You can access Claude’s capabilities within the Windsurf environment, though Claude Code provides more direct and optimized access to Claude’s full context window.

    How much does Claude Code cost?

    Claude Code requires Claude Max ($100/month) or API billing. Windsurf starts at $15/month Pro with a free tier.


    Need this set up for your team?
    Talk to Will →

  • Claude vs Gemini: Which AI Should You Use in 2026?

    Claude vs Gemini: Which AI Should You Use in 2026?

    Last refreshed: October 25, 2026

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Claude AI · Fitted Claude

    Claude and Gemini are the two most capable non-OpenAI AI assistants in 2026, and they’ve converged on similar pricing while diverging significantly in strengths. This comparison is based on real task testing across ten categories — not marketing copy or benchmark cherry-picking.

    Quick Verdict by Task

    Three stacked layers: chat UI, tools, agent runtime
    Quick verdict by task.
    Task Category Winner Why
    Long document analysis Claude 200K context, better synthesis quality
    Coding and software dev Claude 80.8% SWE-bench vs Gemini’s lower scores
    Research and summarization Gemini Real-time web access by default
    Image generation Gemini Native Imagen integration
    Image understanding Tie Both excellent
    Long-form writing quality Claude Less generic, better argumentation
    Google Workspace integration Gemini Native Docs, Gmail, Sheets integration
    Multimodal (video, audio) Gemini Gemini 2.0 handles video natively
    Safety and reliability Claude Constitutional AI, fewer hallucinations
    Free tier value Gemini More generous free access to capable models
    Not sure which to use?

    We’ll help you pick the right stack — and set it up.

    Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.

    The Core Architectural Difference

    Diagram comparing a long context window bar with a shorter output limit bar
    The core architectural difference.

    Claude was built by an AI safety company as its primary product. Every design decision — training methodology, Constitutional AI, refusal behavior — reflects that mission. The result is an assistant that reasons carefully, acknowledges uncertainty, and produces high-quality text and code.

    Gemini was built by Google as part of its search and productivity ecosystem. It’s deeply integrated with Google services, has native real-time web access, handles video and audio inputs, and generates images natively. It reflects Google’s multimodal ambitions.

    Writing Quality Comparison

    We gave both models identical prompts across five writing types: blog post intro, executive email, technical explanation, creative story opening, and marketing headline variations.

    Claude consistently produced cleaner, more specific prose with fewer generic constructions. Gemini was competent but occasionally defaulted to more templated structures. For long-form professional writing, Claude has the edge. For short-form or format-constrained writing, the gap narrows significantly.

    Coding Comparison

    Claude Opus 4.6 scores 80.8% on SWE-bench Verified — the leading benchmark for real-world software engineering tasks. Gemini’s published scores on the same benchmark are lower. In practice: Claude produces fewer hallucinated APIs, better handles complex multi-file refactoring, and provides more accurate debugging analysis.

    For developers choosing a primary AI coding assistant, Claude is the stronger choice. Gemini is more than adequate for routine coding tasks.

    Pricing Comparison

    Plan Claude Gemini
    Free Limited Sonnet Gemini 1.5 Flash (more generous)
    Standard paid $20/mo (Pro) $20/mo (Advanced)
    Power tier $100-200/mo (Max) $20/mo (Google One AI Premium includes Workspace)

    Gemini’s free tier is more generous. At the $20/month level, they’re similarly priced — but Gemini Advanced includes Google One storage and Workspace AI features, which Claude doesn’t. For pure AI assistant use, the value comparison is roughly equal.

    Choose Claude If You…

    • Do serious coding or software development
    • Work with long documents, legal files, or research papers regularly
    • Need the highest quality long-form writing output
    • Value careful reasoning and epistemic honesty over speed
    • Don’t need image generation or deep Google Workspace integration

    Choose Gemini If You…

    • Live in Google Workspace (Gmail, Docs, Sheets, Drive)
    • Need real-time web access as a default capability
    • Work with video, audio, or multimodal content
    • Need image generation built in
    • Want more generous free tier access

    The Both Approach

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The both approach.

    Many professionals run both: Claude for deep work (long documents, complex writing, coding), Gemini for Google Workspace integration and quick research. At $20/month each, running both costs $40/month total — reasonable for knowledge workers who use AI daily.

    Frequently Asked Questions

    Is Claude better than Gemini for coding?

    Yes. Claude Opus 4.6 leads Gemini on SWE-bench coding benchmarks and produces fewer hallucinated APIs and better multi-file reasoning in real-world use.

    Is Gemini better than Claude for Google Workspace?

    Yes. Gemini has native integration with Gmail, Google Docs, Sheets, and Drive. Claude requires copy-pasting content or MCP integrations to access Google Workspace data.

    Which is cheaper, Claude or Gemini?

    Both cost $20/month at the standard tier. Gemini’s free tier is more generous. Claude’s power tiers ($100-200/month) have no direct Gemini equivalent.


    Need this set up for your team?
    Talk to Will →

    New to Gemini itself? Start at the front door: What is Google Gemini — what it is, where it lives, what it does with your data, and who it is for.

  • Is Claude AI Worth It? A Cost-Benefit Analysis for 2026

    Is Claude AI Worth It? A Cost-Benefit Analysis for 2026

    Last refreshed: October 5, 2026 (Pacific)

    Claude AI · Fitted Claude

    The question isn’t whether Claude AI is good — it’s whether it’s worth paying for, at which tier, for your specific situation. This cost-benefit analysis breaks down what you actually get at each price point, calculates real cost-per-task, and gives a clear recommendation by user type.

    What You’re Paying For

    Three stacked layers: chat UI, tools, agent runtime
    What you’re paying for.

    Before running the numbers, it’s worth being clear about what Claude’s pricing tiers actually buy you. It’s not primarily about unlocking features — most features are available at every paid tier. It’s about usage capacity: how many messages you can send, how complex those messages can be, and whether you get access to the most powerful models.

    PlanPriceModel AccessApprox Heavy Messages/DayClaude CodeProjects
    Free$0Sonnet (limited)5–10NoNo
    Pro$20/moSonnet + Opus~12 heavy / more lightNoYes
    Max 5x$100/moSonnet + Opus~60 heavyYesYes
    Max 20x$200/moSonnet + Opus~240 heavyYesYes

    Cost-Per-Task Analysis

    Let’s calculate what Claude actually costs per completed task at each tier, assuming a “task” is a substantive prompt — analyzing a document, drafting a piece of content, debugging a function, or researching a question.

    Claude Pro ($20/month): If you’re averaging 12 heavy tasks per day, that’s roughly 360 tasks per month. Cost per task: $0.055. About 5.5 cents per substantive AI-assisted task. For context, a VA hour runs $15–25. A freelance writer charges $50–200/hour. Claude Pro at 5.5 cents per task is extraordinarily cheap if those tasks displace professional time.

    Claude Max 5x ($100/month): At ~60 heavy tasks/day, that’s 1,800 tasks/month. Cost per task: $0.056. Nearly identical per-task cost to Pro, but with 5x the volume. This is the value tier for power users.

    Claude Max 20x ($200/month): At ~240 heavy tasks/day, that’s 7,200 tasks/month. Cost per task: $0.028. The most cost-efficient tier per task if you’re actually using that volume.

    ROI by User Type

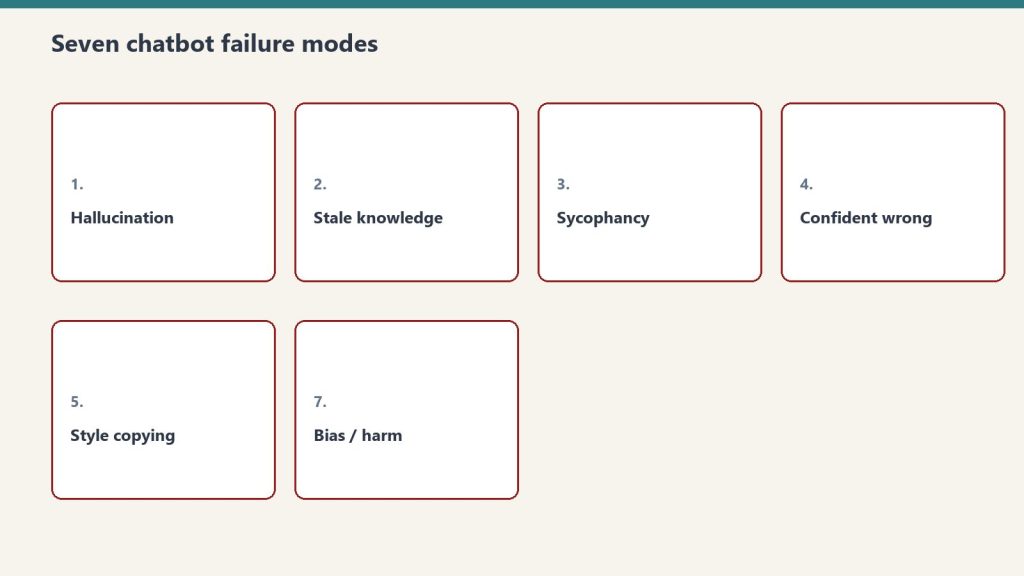
    Seven cards naming common AI chatbot failure modes
    ROI by user type.

    Freelance Writers and Content Creators

    If Claude saves you 2 hours of writing per week at a $75/hour effective rate, that’s $150/week or $600/month in recovered time. Claude Pro at $20/month pays for itself if it saves you 16 minutes per week. Verdict: Clear yes at Pro.

    Developers

    Claude Code is only available at Max 5x ($100/month) or via API. If Claude helps you resolve bugs, write tests, or understand a codebase faster — saving even 30 minutes of developer time per week at $100+/hour — the Max subscription pays for itself in a single day. Verdict: Max 5x is the right tier, and it’s cheap relative to dev billing rates.

    Researchers and Analysts

    The 200K context window for document analysis is the value driver. If you regularly read and synthesize long reports, contracts, or research papers, Claude Pro’s Projects feature (which maintains context across sessions) is a genuine workflow upgrade. Verdict: Pro is likely sufficient; upgrade to Max if you’re processing documents daily.

    Casual Users

    If you use AI for occasional questions, quick edits, or curiosity, the free tier is genuinely usable. The rate limits only frustrate sustained professional use. Verdict: Start free. Upgrade when you hit limits consistently.

    Small Business Owners

    Marketing copy, client emails, policy documents, job descriptions, SOPs — Claude Pro handles all of this. If it saves you 3 hours per month at your effective hourly rate, it’s paid for. Verdict: Pro is almost certainly worth it.

    When the Free Tier Is Enough

    • You need AI help a few times per week, not daily
    • Your tasks are typically short — quick edits, brief questions, simple summaries
    • You’re evaluating whether Claude fits your workflow before committing
    • You have another primary AI tool and want Claude as a secondary option

    When to Upgrade and Which Tier

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    When to upgrade and which tier.
    • Hit rate limits on free → Go Pro ($20)
    • Hit rate limits on Pro regularly → Go Max 5x ($100)
    • Need Claude Code → Max 5x minimum
    • Using Claude 8+ hours daily → Max 20x ($200)

    Related on Tygart Media: Claude pricing · Pro vs Max · how to use Claude.

    Frequently Asked Questions

    Is Claude AI free?

    Yes, Claude has a free tier with limited daily usage. Paid plans start at $20/month (Pro).

    Is Claude worth it compared to ChatGPT?

    At similar price points ($20/month), Claude and ChatGPT Plus are competitive. Claude generally wins on long documents and coding; ChatGPT wins on image generation and plugin ecosystem. Many professionals pay for both.

    What does Claude Max include?

    Claude Max ($100 or $200/month) includes higher usage limits, Claude Code access, extended thinking, and priority access during peak times.

    Need this set up for your team? Talk to Will →
  • Claude AI Review 2026: Honest Assessment After 6 Months

    Claude AI Review 2026: Honest Assessment After 6 Months

    Last refreshed: August 30, 2026

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Claude AI · Fitted Claude

    Claude AI has become one of the most capable AI assistants available in 2026 — but it’s not perfect, and the official messaging undersells both its strengths and its real limitations. This review is based on sustained daily use across writing, coding, research, and analysis tasks. No affiliate relationship with Anthropic. Just what actually works and what doesn’t.

    What Claude Does Better Than Almost Anything Else

    Three stacked layers: chat UI, tools, agent runtime
    What Claude does better than almost anything else.

    Long-document analysis. Claude’s 200,000-token context window — roughly 150,000 words — is transformative for anyone who works with lengthy documents. Feed it an entire contract, research paper, financial report, or codebase and ask specific questions. The quality of synthesis is consistently better than competitors on complex, multi-page materials.

    Writing quality. Claude’s prose is the least robotic of any major AI model. It avoids the generic constructions (“In today’s fast-paced world…”) that mark AI output as AI output. With proper context, it can match sophisticated writing styles and produce genuinely useful drafts that require minimal editing.

    Coding. Opus 4.6 scores 80.8% on SWE-bench and 91.3% on GPQA Diamond — among the highest published scores of any model available. In practice, this translates to fewer hallucinated function names, better error diagnosis, and stronger multi-file reasoning than most alternatives.

    Honesty about uncertainty. Claude is more likely than competitors to say “I’m not sure” or “this is my best guess” rather than confidently stating something incorrect. For research and analysis tasks, this matters enormously.

    Real Benchmark Results

    Diagram comparing a long context window bar with a shorter output limit bar
    Real benchmark results.
    Benchmark Claude Opus 4.7 What It Measures
    SWE-bench Verified 80.8% Real-world GitHub issue resolution
    GPQA Diamond 91.3% PhD-level science reasoning
    HumanEval Top tier Code generation correctness
    MMLU Top tier Broad knowledge and reasoning

    Honest Cost Breakdown

    Plan Price Best For Real Daily Usage
    Free $0 Occasional use ~5-10 messages before throttling
    Pro $20/mo Regular professionals ~12 heavy prompts before rate limits
    Max 5x $100/mo Power users, devs ~60 heavy prompts/day
    Max 20x $200/mo Heavy daily use ~240 heavy prompts/day

    The Rate Limit Problem (The Real Frustration)

    This is the #1 complaint in every Claude user community and it’s legitimate. The Pro plan at $20/month throttles after roughly 12 “heavy” prompts — meaning prompts that require real computation, like complex analysis, long document reading, or code generation. You’ll hit the wall mid-session at the worst possible time.

    A viral Reddit post about this received 1,060+ upvotes. The community consensus: the Pro plan is underspecced for its price point, and jumping to Max 5x ($100/month) is a significant price jump for something that should be a smooth tier progression.

    Workarounds that help: using Projects with system prompts (reduces token overhead per conversation), preferring Sonnet over Opus for routine tasks (cheaper against limits), and batching related work into single longer sessions rather than many short ones.

    What Claude Can’t Do

    • Generate images: Claude cannot create images. Midjourney, DALL-E, or Adobe Firefly for that.
    • Real-time web access: No live browsing by default on the consumer interface. Knowledge has a training cutoff.
    • Remember between sessions by default: Memory exists but requires setup. Fresh sessions start fresh.
    • Replace specialized tools: Claude is general-purpose. For SEO research, use dedicated tools. For legal filing, use legal software. Claude augments specialists — it doesn’t replace them.

    Who Claude Is Worth It For

    Strong yes: Writers, researchers, developers, lawyers, consultants, analysts, product managers, HR professionals — anyone whose work involves reading, reasoning, writing, or coding at length.

    Consider alternatives: Users who primarily need image generation (ChatGPT/Midjourney), users who need deep Google Workspace integration (Gemini), or users running on a tight budget who won’t benefit from the Pro tier’s additional capacity.

    Start free, upgrade when you hit limits. The free tier is genuinely usable for orientation. When you find yourself frustrated by rate limits — which you will, if Claude is useful to you — that’s the signal to upgrade to Pro. If you hit Pro limits regularly, Max 5x is worth the jump.

    Final Verdict

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Final verdict.

    Claude is one of the two or three best general-purpose AI assistants available in 2026. Its writing quality, document reasoning, and coding performance are among the strongest in the field. The rate limiting on lower tiers is a genuine frustration that Anthropic should address. The pricing jump from Pro to Max is steep. But for the right user — anyone doing serious knowledge work — Claude at the Max tier is worth it. Claude Pro at $20/month is competitive with ChatGPT Plus but hits limits faster for heavy use.

    Frequently Asked Questions

    Is Claude AI better than ChatGPT in 2026?

    For long-document analysis, coding, and nuanced writing: Claude holds a measurable advantage. For image generation, plugin ecosystem breadth, and Google Workspace integration: ChatGPT/Gemini are stronger. Most serious users use both.

    Is Claude Pro worth $20 a month?

    For regular professional use: yes, but with the caveat that the rate limits on Pro are tighter than they should be at this price point. Heavy users will want Max 5x ($100/month) within weeks.

    Does Claude have a free plan?

    Yes. The free tier gives limited daily access to Claude Sonnet 4.6. It’s useful for orientation but will frustrate anyone using Claude as a primary work tool.


    Need this set up for your team?
    Talk to Will →

  • Claude Function Calling: Developer’s Guide to Tool Use

    Claude Function Calling: Developer’s Guide to Tool Use

    Last refreshed: August 30, 2026

    Claude AI · Fitted Claude

    Claude tool use (also called function calling) is the capability that transforms Claude from a conversational AI into an agentic system that can interact with external services, execute code, query databases, and take real-world actions. This guide covers how tool use works, the three execution modes, the built-in server tools, and practical implementation examples.

    What Is Tool Use?

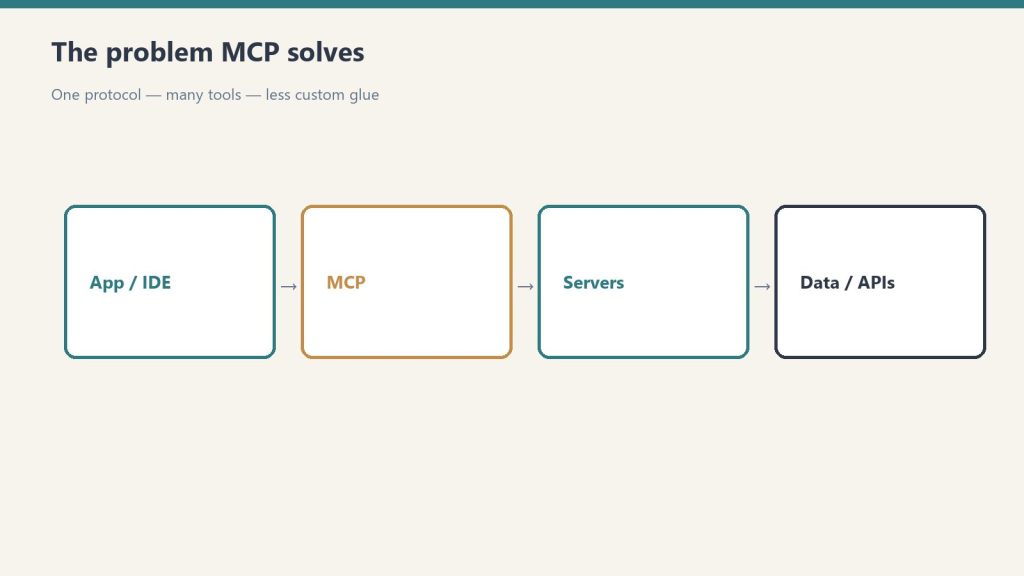
    Flow from app/IDE through MCP to servers and data APIs
    What tool use is.

    Tool use lets you define functions that Claude can call during a conversation. When Claude determines that a tool would help answer a user’s request, it generates a tool call (specifying the tool name and arguments), your code executes the function, and the result is returned to Claude to continue the conversation.

    Example flow: User asks “What’s the weather in Seattle?” → Claude calls your get_weather function with {"location": "Seattle"} → Your code calls a weather API → Returns data to Claude → Claude generates a natural language response incorporating the weather data.

    Defining Tools

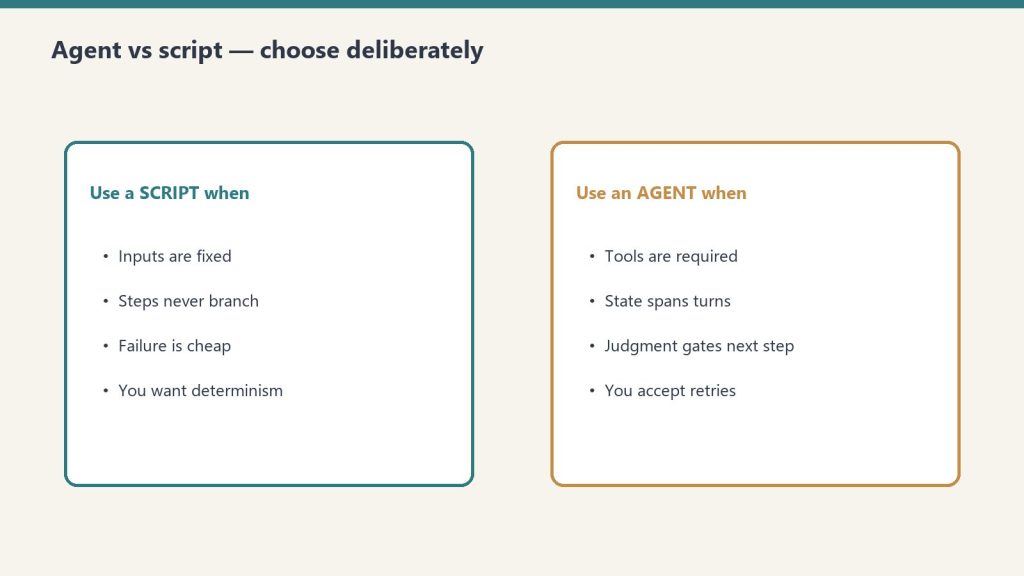
    Side-by-side when to use a script versus an agent
    Defining tools.
    tools = [
        {
            "name": "get_stock_price",
            "description": "Get the current stock price for a given ticker symbol",
            "input_schema": {
                "type": "object",
                "properties": {
                    "ticker": {
                        "type": "string",
                        "description": "The stock ticker symbol (e.g., AAPL, GOOGL)"
                    }
                },
                "required": ["ticker"]
            }
        }
    ]
    
    response = client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=1024,
        tools=tools,
        messages=[{"role": "user", "content": "What's Apple's current stock price?"}]
    )

    The Three Execution Modes

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The three execution modes.

    1. Client-Side Execution

    Your application receives the tool call, executes the function locally or via external APIs, and returns the result. This is the standard pattern — you control the execution environment and can call any service.

    2. Server-Side Execution (Built-in Tools)

    Anthropic provides built-in tools that Claude can execute server-side without your code doing anything:

    • web_search: Real-time web search
    • code_execution: Execute Python code in a sandbox
    • bash: Run shell commands
    • text_editor: Read and edit files (used in Claude Code)

    3. Tool Runner SDK (Programmatic)

    Anthropic’s Tool Runner SDK automates the tool call/execute/return loop, letting you build agentic workflows without writing the orchestration loop manually.

    Handling Tool Results

    # After receiving a tool_use block from Claude
    if response.stop_reason == "tool_use":
        tool_use = next(block for block in response.content if block.type == "tool_use")
        tool_name = tool_use.name
        tool_input = tool_use.input
        
        # Execute your function
        result = your_function(tool_input)
        
        # Return result to Claude
        follow_up = client.messages.create(
            model="claude-sonnet-4-6",
            max_tokens=1024,
            tools=tools,
            messages=[
                {"role": "user", "content": "What's Apple's stock price?"},
                {"role": "assistant", "content": response.content},
                {"role": "user", "content": [{"type": "tool_result", "tool_use_id": tool_use.id, "content": str(result)}]}
            ]
        )

    Frequently Asked Questions

    What is the difference between tool use and function calling?

    They’re the same thing — Anthropic uses “tool use” as the preferred term, while “function calling” is the term OpenAI popularized. Both describe the same capability: letting an AI model invoke defined functions during a conversation.

    How many tools can I define for Claude?

    Claude supports up to several hundred tools in a single request, though performance is best with a focused set relevant to the task. Each tool definition consumes input tokens, so large tool sets have a cost impact.

    Need this set up for your team? Talk to Will →
  • Claude Computer Use: Complete Setup Guide & Use Cases

    Claude Computer Use: Complete Setup Guide & Use Cases

    Last refreshed: August 30, 2026

    Claude AI · Fitted Claude

    Claude computer use is a capability that lets Claude control a computer — click buttons, type text, navigate browsers, run applications, and execute multi-step tasks as if it were a human operator. As of 2026, it’s one of the most powerful and underexplored capabilities in the Claude ecosystem. This tutorial covers what it is, how to set it up, what it’s actually useful for, and where it still falls short.

    What Is Claude Computer Use?

    Three stacked layers: chat UI, tools, agent runtime
    What Claude Computer Use is.

    Computer use is an API capability (not available in the standard Claude.ai interface) that lets Claude interact with a desktop environment via screenshots and tool calls. Claude sees the screen, decides what to click or type, executes that action, sees the updated screen, and continues — iterating until the task is complete.

    This is different from a browser extension or web scraper. Claude is operating a real (or virtualized) computer environment the same way a human would — by looking at the screen and interacting with what it sees.

    Current Benchmark Performance

    On OSWorld — the leading benchmark for computer use agents — Claude currently scores around 22% task completion on the most complex tasks. ChatGPT’s computer use scores higher on this specific benchmark at approximately 75%. This gap is real and matters for production use cases requiring high reliability. For simpler, more structured tasks, Claude’s computer use performs considerably better.

    Setting Up Claude Computer Use

    Side-by-side when to use a script versus an agent
    Setting up Claude Computer Use.

    Computer use requires API access. The basic setup:

    • Anthropic API key (API tier with computer use enabled)
    • A virtual machine or containerized desktop environment (Docker with a lightweight Linux desktop is the standard approach)
    • The Anthropic Python or TypeScript SDK

    Anthropic provides a reference implementation with a Docker-based Ubuntu environment, a noVNC interface for monitoring, and starter code. This is the fastest path to a working computer use setup.

    Best Current Use Cases

    • Web research and data extraction: Navigate websites, extract structured data, fill in forms — tasks that don’t have APIs
    • Software testing: Navigate UI flows, test edge cases, verify visual behavior
    • Repetitive desktop workflows: Tasks that require clicking through multiple application screens
    • Legacy software interaction: Applications without APIs where the only interface is visual

    Key Limitations to Know

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Key limitations to know.
    • Reliability: Computer use is significantly less reliable than direct API calls for the same tasks. Where an API returns structured data, computer use can misread a screen or click the wrong element
    • Speed: Screenshot-based interaction is slow compared to direct integration
    • Cost: Each screenshot and tool call consumes API tokens; complex tasks can be expensive
    • Sensitive actions: Never use computer use for high-stakes irreversible actions (sending emails, making purchases) without human-in-the-loop verification

    Frequently Asked Questions

    Is Claude computer use available in Claude.ai?

    No. Computer use is an API capability available through the Anthropic API, not the standard Claude.ai web interface.

    How does Claude computer use compare to ChatGPT’s?

    On OSWorld benchmarks, ChatGPT’s computer use currently leads at approximately 75% vs Claude’s ~22%. For production use cases requiring high reliability, this gap matters. Both are improving rapidly.

    Need this set up for your team? Talk to Will →
  • AI Music Rehearsal: Build a Full Show on a Zero Budget

    AI Music Rehearsal: Build a Full Show on a Zero Budget

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    What is the No-Budget Artist’s AI Stack? The no-budget artist’s AI music stack is a combination of free and low-cost AI tools that together provide the capabilities historically available only to artists with label backing, production budgets, or extensive musician networks. The core stack: Producer AI (now Google Flow Music) or Suno (AI track generation, $0–$30/month), a rehearsal platform (AI lyric sync and playback, $0–$20/month), a portable Bluetooth speaker ($50–$200 one-time), and a basic microphone ($30–$100 one-time). Total monthly cost: $0–$50. Total infrastructure this replaces: studio session musicians ($150–$500/hr), rehearsal space ($15–$50/hr), home recording setup ($500–$2,000), and song demonstration costs. The AI stack gives an emerging artist with no budget the same rehearsal and performance infrastructure as an established artist with a team.

    Last refreshed: November 3, 2026 (Pacific)

    The Real Barrier: It Was Never Talent

    The music industry’s standard narrative about why artists don’t make it focuses on talent, luck, and market timing. These factors are real. But the infrastructure barrier is rarely discussed honestly: to develop your songs from composition to performance-ready standard has historically required money at every step. Recording demos to share with venues costs studio time. Rehearsing with a band costs the band’s time and often a rehearsal space. Performing with backing tracks has meant hiring session musicians to record those tracks or purchasing backing tracks from third parties that don’t match your arrangements. The invisible infrastructure cost of becoming a performing artist — before any revenue — has been $2,000–$10,000 minimum for artists who do it properly.

    AI tools have collapsed that infrastructure cost to near zero. They have not made the talent development work easier — that still takes the same hours of practice, the same diagnostic honesty about what’s not working, the same repetition until the songs are in your body. But the money barrier is gone. A songwriter with a $30/month AI subscription and a $150 speaker can build and perform original music with the same sonic quality as an artist with a $50,000 production budget. The platform is the equalizer.

    The Complete No-Budget Stack: What You Need and What Each Tool Does

    AI Track Generation: Producer AI, Suno, or Udio

    Producer AI generates full instrumental arrangements from text prompts. Enter a genre (indie folk, uptempo pop, blues-rock, ambient electronic), a tempo (slow ballad at 68 BPM, driving uptempo at 128 BPM), key preference (C major, F# minor), and any specific instrumentation requests (acoustic guitar-forward, no drums, heavy bass). The platform generates 2–5 variations in under 60 seconds. You select the one that fits your song’s feel and export the instrumental track as an MP3 or WAV file. No music theory knowledge required to operate the tool effectively — descriptive language is sufficient. “Sad, sparse, lots of space, piano and cello, very slow” generates a usable ballad backing track that a composer with notation software would take hours to produce.

    Suno and Udio offer similar capabilities with different aesthetic tendencies in their generation. Suno tends toward more structured arrangements; Udio toward more organic, genre-specific textures. Experimenting with both for the same song and selecting between their outputs costs nothing beyond time. Free tiers exist on all three platforms with limits on commercial use and monthly generation volume — sufficient for an artist building their first show.

    The Rehearsal Platform: Core Function

    The rehearsal platform takes your AI-generated track and your lyrics and creates a synchronized rehearsal session — scrolling lyric display timed to the music, exactly like karaoke but for your original song in your arrangement. This is the infrastructure that allows you to actually learn your songs to performance standard without a musician present. You play the track, you sing, the words advance with the music. You can loop the chorus 20 times. You can slow the track without changing the pitch. You can transpose the key if your voice sits differently than you planned. You can record yourself singing and listen back. Every one of these functions — which previously required a session musician, a recording engineer, or expensive software — is built into the platform.

    The Performance Kit: Portable PA and Microphone

    The JBL Eon One Compact ($499), Bose S1 Pro ($349), and Electro-Voice Everse 8 ($399) are the three most commonly used portable PA speakers by solo performing artists. All three are battery-powered, provide enough volume for a bar, coffee shop, or small venue (up to 200 people), and have line inputs that accept your device’s audio output for the AI track alongside a microphone input for your vocal. A Shure SM58 ($99) or Sennheiser e835 ($129) dynamic microphone plugged directly into the speaker’s XLR input is a professional vocal performance setup at $450–$630 total investment. This system goes in a medium duffel bag and sets up in 10 minutes in any room with a power outlet. It is the same technical setup professional touring solo artists use for club and venue performances.

    The Recording Setup (Optional but Recommended): Interface and DAW

    A Focusrite Scarlett Solo ($119) USB audio interface and Audacity (free) or GarageBand (free on Mac) give you the ability to record your vocal over the AI track and evaluate the recording as a produced artifact — not just a rehearsal take. Recording yourself and listening back is the single most accelerating practice tool available to developing artists. You hear things in a recording that you cannot hear while singing: pitch tendencies, phrasing habits, the emotional authenticity (or lack of it) in your delivery. Budget $119 for the interface. The DAW is free. Total optional upgrade: $119.

    The No-Budget Artist’s 8-Week Development Plan

    Weeks 1–2: Song Selection and Track Generation

    Select 8–10 songs that represent your best current material. These do not need to be finished — they need to be structurally complete (verse, chorus, bridge identified) with lyrics that are at least 80% final. For each song, generate AI tracks in Producer AI using descriptive prompts that reflect the song’s intended feel. Generate 3–5 variations per song and select the best one. Export all instrumentals. Total time: 4–8 hours. Total cost: $0 on free tier or $10–$30 for a paid subscription if you need higher generation volume or commercial licensing.

    Prioritize track quality over track perfection at this stage. The goal is a track that (a) fits your song’s tempo and feel closely enough to rehearse against, and (b) sounds good enough that you’d be comfortable playing it through a speaker at an open mic. You can always regenerate tracks later as your production sensibility develops. Getting rehearsal sessions built and starting to sing is more valuable than spending 10 hours perfecting a track before you’ve confirmed the song works.

    Weeks 3–4: Session Building and Diagnostic Rehearsal

    Build rehearsal sessions for all 10 songs. Follow the session setup workflow: import track, paste lyrics with natural phrasing line breaks, generate automated timestamps, do one real-time adjustment pass. Add section labels. Set your loop points for the sections you already know will need the most work.

    Run the diagnostic pass on each song: sing through once without stopping, flag every moment where the song doesn’t feel right. These flags are the development agenda for Weeks 3–4. Work through them systematically: syllable count problems get lyric rewrites; key problems get a transpose adjustment and a note about the new key; structural problems get the loop treatment until you identify whether they’re a writing problem or an arrangement problem. By the end of Week 4, every song should have a clean diagnostic pass — meaning you can sing through the whole thing and nothing catastrophically breaks.

    Weeks 5–6: Performance Runs and Recording Self-Evaluation

    Shift from diagnostic mode to performance mode. For each song, do 10 consecutive performance runs — full song, no stopping, performing to the room (or the imaginary camera), not reading the screen. After the 10th run of each song, record a take using your phone or recording setup. Listen back the next day with fresh ears. Evaluate: does this sound like something you’d be comfortable sharing? Does the delivery feel earned? Are there specific lines where your confidence drops or your phrasing falls apart?

    The recording self-evaluation is uncomfortable for most developing artists. It reveals gaps between how you sound in your head while singing and how you actually sound. This discomfort is the most productive feeling in music development — it is the signal that specific, targeted improvement is available. Lean into it. The artists who get better fastest are the ones who listen to their recordings honestly and make specific decisions about what to change, not the ones who avoid recordings because they’re uncomfortable.

    Weeks 7–8: Show Construction and Full Run-Throughs

    From your 10 prepared songs, select 6–8 for your first show — enough for a 30–40 minute set. Sequence them in the platform’s setlist mode with intentional energy logic: your most accessible song opens (not necessarily your best, but your most immediately engaging); your strongest material appears in positions 3–5 (after the audience is warmed up but before energy starts to flag); your most emotionally significant song appears in position 6 or 7; your highest-energy song closes (send them out on a peak). This sequencing logic applies whether you’re playing a coffee shop open mic or a headline show.

    Run the full setlist once per day for the last two weeks. By show day, you will have run the complete 30–40 minute performance 14 times. This is not excessive — it is professional standard. The songs are in your body. The transitions between songs are natural. The energy arc is familiar. You know what the show feels like at minute 5 and at minute 35. That knowledge produces a qualitatively different performance than an artist who has only rehearsed individual songs.

    The Open Mic as Rehearsal Infrastructure

    Open mics serve a function in the no-budget artist’s development that is not adequately appreciated: they are low-stakes live performance repetitions, available for free, in rooms with real audiences. With your AI rehearsal platform preparation complete, you can bring your portable speaker, your track files, and your microphone to an open mic and deliver a 3-song set that sounds like you have a full band behind you. You are not competing with acoustic guitar players for audience attention — you are performing with production quality in a context where production quality is unexpected.

    Use open mics as diagnostic performances: which songs land with strangers (not just with you, who knows the material intimately)? Which punchlines, lyrical moments, or melodic peaks get the response you expected? Where does the audience’s energy drop? This data is more valuable than any rehearsal run because it comes from real listeners with no investment in your success — they respond to what works, not to what you hoped would work. Collect this data, return to the platform to address what didn’t work, and perform again.

    The Progression: From Open Mic to Paying Gig

    The progression from open mic to booked, paid performance requires three things that AI rehearsal platform preparation directly supports: (1) a consistent setlist that you can deliver reliably — not different each time, but a defined show that you know works; (2) a recording of a live performance or home studio recording that demonstrates the quality of your show to venue bookers; (3) a pitch to venue bookers that includes the recording, the setlist, and an honest representation of your technical requirements (one speaker, one microphone, 20-minute setup time). Venue bookers at bars, coffee shops, and small clubs are booking a reliable, professional experience for their customers. The AI rehearsal platform’s contribution to that pitch is the word “reliable” — you know the show works because you’ve run it 30 times.

    Copyright, Commercial Use, and AI Track Licensing

    When you perform publicly and accept payment, the AI tracks you use cross from personal use into commercial performance. The free tier of most AI music generation platforms does not include commercial use licensing. Before your first paid performance, upgrade to a commercial license tier on whichever platform you use for track generation. Suno Pro is $10/month. Producer AI is now Google Flow Music, with paid tiers from $6/month. Udio’s commercial rights sit on its $30/month Pro plan (Standard, $10/month, is personal use only) — and Udio has downloads disabled on every plan during its label-licensing transition, so Udio tracks cannot currently be exported for a live show at all. These licenses grant you the right to use AI-generated tracks in live performances and, on most platforms, in recorded releases. Read the specific license terms of your chosen platform — they vary in what recorded release rights are included and at what tier.

    Frequently Asked Questions

    What if I don’t have a great voice — can I still perform with this system?

    Yes. The AI rehearsal platform improves every voice that uses it consistently, because consistent rehearsal with honest self-evaluation produces measurable improvement in pitch accuracy, phrasing confidence, and emotional delivery. Voice quality is a component of performance but not the determining factor. Authenticity, material quality, and consistency of delivery matter as much or more in most performance contexts. Develop what you have systematically rather than waiting for a voice you imagine you should have.

    Do I need to tell the audience the tracks are AI-generated?

    There is no legal requirement to disclose AI generation of backing tracks. Backing tracks in general — whether recorded by session musicians, synthesized electronically, or AI-generated — are widely used in live performance without specific disclosure. Whether to disclose is an artistic and branding decision. Some artists lean into the AI production identity as a differentiator and conversation starter. Others present the show as a produced musical experience without discussing production methods. Both are legitimate. The quality of the experience for the audience is the primary variable — not the disclosure.

    How do I handle technical problems at a performance (track doesn’t play, speaker cuts out)?

    Build a technical contingency plan: always have the track files on two devices (your phone as backup for your laptop). Always test the speaker connection before the show. Know which songs in your set you can perform acoustically or a cappella if necessary — have two “tech-fail songs” that work without a backing track. Brief the venue on your technical setup before arrival so they know what you need and can help if something goes wrong. A no-budget artist who handles technical problems gracefully and professionally is more likely to get rebooked than one who delivers a technically perfect show without any resilience.

    What’s the fastest path from zero to first paid performance?

    4–8 weeks using the development plan in this article. The accelerated version: 2 weeks of track generation and session building, 2 weeks of intensive diagnostic rehearsal (90 minutes/day), 2 open mic performances for audience diagnostic, 2 weeks of show construction and full run-throughs. Approach the first paid booking not as a career milestone but as a paid rehearsal — a real audience, real stakes, a real paycheck, and data you can take back to the platform to keep developing. Most first paid performances are $50–$150. The value is not the money — it is the performance experience and the relationship with the venue.

    Using Claude as a Development Planning Companion

    Upload this article to Claude along with your current song list, descriptions of each song’s genre and feel, your vocal range (approximate is fine — highest comfortable note and lowest comfortable note), your available practice time per week, and your geographic market and target venue types. Claude can generate: a complete 8-week development calendar with daily practice tasks; AI track generation prompts for each of your songs (what to enter into Producer AI for each song’s genre and feel); a setlist sequencing analysis based on your song descriptions; a self-evaluation rubric customized for your specific voice type and genre; a venue outreach plan for your market identifying which venue types to approach in what order; and a technical rider document for your portable speaker and microphone setup. This article gives Claude enough context about the no-budget artist’s situation, the full tool stack, and the development methodology to build a complete, artist-specific launch plan from your starting point.