Tag: AI Strategy

  • Fixing Our Claude AI Coverage: A Full Content Audit

    Fixing Our Claude AI Coverage: A Full Content Audit

    Last refreshed: May 15, 2026

    I owe you an apology.

    Tygart Media has been publishing about Claude — Anthropic’s AI model — for months. We’ve written about its capabilities, its pricing, its API strings, how to use it, why it matters. We positioned ourselves as a resource for people who want to understand and use Claude intelligently.

    And some of what we published was wrong.

    Not intentionally. Not carelessly in the moment. But wrong in the way that happens when you’re moving fast, publishing at scale, and not building the right systems to catch your own errors. Model version numbers were stale. Pricing figures were outdated. API strings referenced models that had been retired. If you used our content to make a decision about Claude — about which model to use, what to pay, how to call the API — some of that information may have led you in the wrong direction.

    That’s unacceptable to me. And I want to tell you exactly what happened, exactly what I found, and exactly what I’ve built to make sure it never happens again.


    How We Found Out
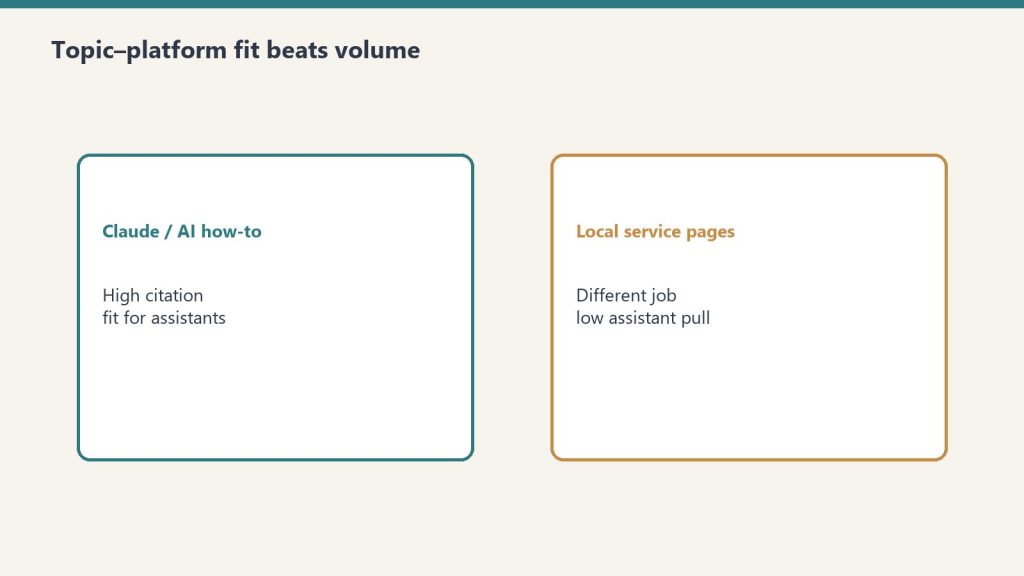
    Comparison of Claude how-to fit versus local service page fit for assistants
    How we found out.

    It didn’t start with our own discovery. It started with a message.

    Kristin Masteller, the General Manager of Mason County PUD No. 1, reached out on LinkedIn to flag inaccuracies in our local coverage — a different set of articles, but the same underlying problem: we had published with confidence about things we hadn’t verified carefully enough.

    That message hit differently than a normal correction request. Because it made me ask a harder question: if our local coverage had errors, what about our Claude coverage? We had 200+ posts. We were publishing multiple times per day. We had never built a systematic quality check.

    So we ran one.


    The Audit: What We Found
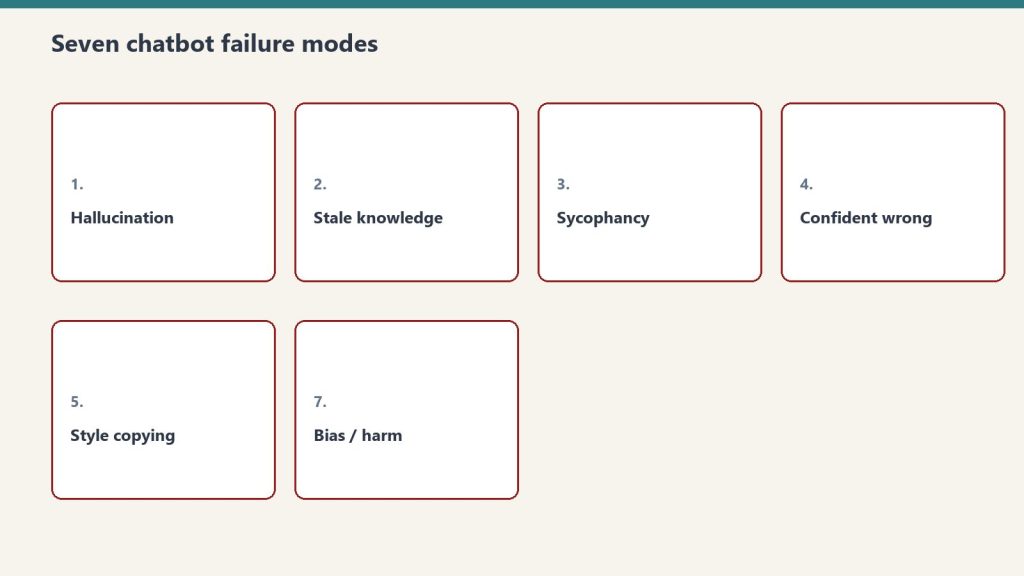
    Seven cards naming common AI chatbot failure modes
    The audit — what we found.

    We wrote a scanner that pulled every post from tygartmedia.com and ran each one through a quality gate checking for four categories of errors:

    • Category A: Stale model names (e.g., “Claude Haiku” with no version number, or references to Claude 3 models as current)
    • Category B: Wrong pricing (e.g., Haiku priced at $0.80/MTok when the actual price is $1.00/MTok)
    • Category C: Deprecated feature claims (features or behaviors that no longer apply)
    • Category D: Cross-site contamination (content from other publication contexts bleeding into Claude coverage)

    Out of 2,333 total posts on the site, 701 touched Claude or AI topics. Of those, 65 posts had violations — 121 individual errors in total.

    We auto-corrected 28 posts immediately — wrong model strings, wrong pricing, outdated API references. 18 posts with more complex issues are still flagged for human review. We are working through them.

    I’m not sharing this to perform humility. I’m sharing it because you deserve to know the scope of the problem, and because the methodology for finding it might be useful to you.


    What We Built to Fix It

    Three panels showing one problem, three options, one recommendation
    What we built to fix it.

    The audit was a one-time fix. What we actually needed was a system — something that would catch these errors before they went live, and keep our model information current automatically.

    Here’s what we built:

    1. The Claude Intelligence Desk

    A dedicated Notion page that serves as the single source of truth for all Claude model information across our entire content operation. It contains the current model truth table — every model name, API string, input/output price, context window, and status — verified against Anthropic’s live documentation.

    The rule is simple: before anyone writes, edits, or publishes any article that mentions Claude, they check this page. If the “Last Verified” timestamp is more than 12 hours old, they run a refresh before proceeding.

    2. The Claude Intelligence Scanner (Automated, Twice Daily)

    A scheduled task that runs at 6 AM and 6 PM Pacific every day. It fetches Anthropic’s models documentation page, compares the current model table to what’s in our Notion desk, and if anything has changed — a new model, a price change, a deprecation — it updates the desk automatically and flags it for human review.

    We will never again be caught publishing outdated Claude information because a model changed and we didn’t notice.

    3. Pre-Publish Quality Gates

    Every new Claude article now runs through the quality gate categories above before it goes live. Wrong model string → blocked. Outdated pricing → blocked. Deprecated claim → flagged.

    4. The Fix Log

    Every correction we make is logged with the post ID, the original wrong content, the correct replacement, and the date. Accountability in writing, not just in words.


    Why I’m Telling You All of This

    Because I think the way most AI content operations work is broken — and I think transparency about that is more useful than pretending we had it figured out.

    The standard playbook for AI content is: write fast, publish often, stay ahead of the news cycle. The problem is that AI — and especially Claude — moves so fast that “write fast” and “stay accurate” are genuinely in tension. Models change. Prices change. Features get added, deprecated, retired. If you’re not building systems to track that, you’re going to drift.

    We drifted. We caught it. We fixed it. And now I want to open up everything we built.

    The Claude Intelligence Desk methodology, the quality gate framework, the scanner architecture — I’m making all of it available. If you’re publishing about Claude, if you’re building automations around Claude, if you’re running a content operation that touches Anthropic’s ecosystem in any way, you can use what we built. Adapt it. Improve it. Tell me what I got wrong in the system design.

    This is not a product. This is not a lead magnet. It’s just the actual work, shared openly, because that’s how we get better together.


    I Want to Build This With You

    Here’s what I’ve learned from this process: the people who catch errors fastest are the people closest to the technology. The developers who are actually calling the API. The builders running Claude in production. The researchers who read every Anthropic paper when it drops. The people in Singapore, India, the UK, Europe, Brazil — every region where Claude is being adopted rapidly and where the local context matters.

    I don’t have all of that knowledge. No single publication does.

    So I’m opening this up.

    If you use Claude seriously — if you’re building with it, writing about it, researching it, deploying it — I want you to write with us.

    What that looks like:

    • Writers and researchers: You bring the knowledge and the perspective. We provide the platform, the distribution, the SEO infrastructure, and editorial support. Your byline, your voice, your expertise.
    • Builders and developers: You’re running Claude in production. You know what actually works, what breaks, what the documentation doesn’t tell you. Write that. The practitioner perspective is the most valuable thing we can publish.
    • International voices: What does Claude adoption look like in Singapore right now? What’s the conversation in India’s developer community? How are European companies thinking about AI compliance alongside Claude? These are stories we cannot tell without you — and they’re stories our audience desperately needs.
    • Correctors: If you read something on this site that’s wrong, tell us. We have a system now. We will fix it, log it, and credit you if you want the credit.

    This is not about content volume. We publish enough already. This is about getting it right — and getting perspectives we genuinely don’t have.


    How to Get Involved

    If any of this resonates — if you want to write, contribute, correct, or just have a conversation about where Claude is going — reach out directly: will@tygartmedia.com

    Tell me where you are, what you’re building or writing or researching, and what you’d want to say if you had a platform to say it. No formal application. No content calendar to fit into. Just a conversation.

    We’re also building out a formal contributor program at tygartmedia.com/contribute/ — trade affiliates, community writers, featured contributors. If that’s more your speed, start there.

    But honestly? Just email me. Let’s figure out what makes sense.


    The work continues. The scanner runs twice a day. The quality gates are live. And if you find something wrong on this site — about Claude, about anything — I genuinely want to know.

    That’s the standard I should have been holding from the beginning. We’re holding it now.

    — Will Tygart
    Tygart Media

    Related on Tygart Media: how to use Claude · Anthropic API key.
  • AI Knowledge Compression: Encyclopedias to Generative AI

    AI Knowledge Compression: Encyclopedias to Generative AI

    The world of 1974 was defined by physical weight. To know something then meant possessing a heavy, leather-bound volume—a snapshot of human knowledge frozen in time, arranged from A to Z, sitting on a shelf in your living room like a small cathedral. My father kept a set. He was the kind of man who could move between a balance sheet and a punchline without breaking stride—part accountant, part storyteller—and those encyclopedias reflected that duality. The data was in the volumes. The meaning was in the man who knew how to use them.

    Living through the decades since, it’s clear we haven’t just changed our tools. We’ve changed our orientation to the universe.

    The Encyclopedia Era: The Weight of the Macro

    Comparison of Claude how-to fit versus local service page fit for assistants
    The encyclopedia era — weight of the macro.

    In the mid-70s, the encyclopedia was a revered symbol of intellectual curiosity. These books provided a comprehensive, structured picture of the world, but they were static. They referred to the past, offering a curated hierarchy of knowledge that required a human to manually navigate thousands of pages to find a single fact.

    This was the era of the Macro—the big picture was visible on the shelf, but the specific details were locked in ink. You could see the whole forest. Finding a single tree took time, patience, and a willingness to get lost.

    The genius of that format wasn’t the information. It was the journey. You went looking for one thing and came out knowing three others. The serendipity was built into the medium.

    The Search Era: The Language of the Micro

    Two cards: answer shown in overview versus optional click
    The search era — language of the micro.

    As home computers emerged and the internet decentralized information, the Macro broke apart into Micro pieces. We moved into the era of the Keyword.

    For the first time, we used rigid queries to describe our world. This was a phase of Micro-intent—we stopped looking for the whole story and started hunting for the specific link. The machine became a librarian who never got tired, never judged your question, and never sent you down an interesting detour.

    Revolutionary. And a little flat. The serendipity was gone. So was the storyteller.

    The AI Era: The Return of the Storyteller

    Floor versus ceiling cards for commoditized work and human-network premium
    The AI era — return of the storyteller.

    Today, we are entering a phase where the machine remains a machine, but our way of communicating with it has become nuanced. We have moved from keyword-matching to conversational interaction. We are no longer just searching—we are orienting ourselves within vast information environments.

    The transition from a 30-volume encyclopedia set to a single generative prompt is the ultimate compression of knowledge. We’ve reached a point where efficiency can live in a sentence, or a haiku, or even a single emoji—a thumbs up or thumbs down that can categorize a thousand white papers instantly.

    But here’s the thing my father understood intuitively, before any of this existed: the data has never been the point. The point is knowing which story to tell with it.

    The Human-in-the-Loop: The Final Sweet Spot

    The arc from the encyclopedia to AI is not a story of machines replacing humans. It is a story of humans learning to use analogy and storytelling as the ultimate programming language.

    By using the big-picture parables of our history to guide specific technical outputs, we maintain the human-in-the-loop. Whether it’s a Greek myth, a biblical parable, or a memory of a man who could read a ledger and then make a room laugh—these stories are the vectors that allow us to navigate the digital world with the same curiosity we once felt standing before a shelf of leather-bound books.

    The compression is real. The intelligence is still ours.

    The best prompt engineers aren’t coders. They’re storytellers who learned to speak machine.


    Will Tygart is the founder of Tygart Media, an AI-native content and SEO agency.

    Related on Tygart Media: extracting tacit knowledge · conversations as code.

  • Organizational AI: The Context That Lives Between People

    Organizational AI: The Context That Lives Between People

    There’s a simple version of the AI-in-organizations problem that’s wrong: you build the system, give it access to the right data, write a thorough system prompt, and it operates in your organizational context. The prompt is the context. The context is the prompt.

    This framing is everywhere. It’s also the reason most organizational AI deployments produce work that is technically correct and somehow off.

    The context that matters — the context that determines whether a decision lands right, whether a draft feels aligned, whether a flagged opportunity is genuinely actionable — is not stored anywhere. It lives between people.


    Every organization operates on a layer of standing assumptions that nobody explicitly maintains and nobody could fully articulate on request. Not values, not principles, not priorities — something below those. The interpretive substrate that makes the documented values mean anything.

    When someone joins a team and violates one of these assumptions — proposes the wrong thing in the wrong meeting, pushes a decision that is technically within their authority but somehow not theirs to make, surfaces a priority the organization agreed to de-emphasize without announcing it — everyone feels it. The violator usually doesn’t. The substance was fine. Something else was wrong.

    That something else is the context AI systems don’t have.


    Documentation can encode explicit knowledge. It cannot encode the community that makes the documentation mean anything.

    A system prompt can say “this organization prioritizes speed over perfect.” What it cannot encode is whether that norm has actually been consistent for the last six months, or whether leadership has been quietly walking it back after three bad launches, or whether it applies to customer-facing work but not internal infrastructure, or whether the one person whose approval you need is the one exception to the norm.

    The standing assumptions are not stored. They are enacted. They show up in what gets committed to and what sits in the inbox for thirty days.

    Watch a team’s queue long enough and you can read the context. Not from the items themselves — from the pattern of what moves and what doesn’t. Stalled items tell you which commitments have real backing and which are aspirational. Rapid movement in one lane tells you where the actual authority is concentrated. The gap between what the organization says it prioritizes and what it actually processes is a map of the standing assumptions it hasn’t named.

    A single operator can solve this. They can read the board, feel the friction, and say: the predicate is wrong. The item needs to be reframed before it moves. They can do this because they hold the context in their own head, accumulated over months, updated daily.

    A team cannot do this as easily. The context is distributed. Each person holds part of it. The standing assumptions live in the gaps between what anyone would say individually. Ask the team to write down why something has been stalled for thirty days and you’ll get five different answers, each of which is partially true, none of which is sufficient.


    The naive solution is documentation. Write the standing assumptions down. Build a better system prompt. Give the AI more context.

    This helps at the margins. It doesn’t solve the problem.

    Documentation of standing assumptions produces a different artifact — a curated version of the context, shaped by whoever did the writing, frozen at the moment of writing, immediately in tension with the organizational reality it was supposed to encode. It becomes a reference document. The context moves on. The document does not.

    The less naive solution — the one organizations rarely take — is to treat context as an ongoing artifact rather than a static one. Not a document but a practice. Something that gets updated not when someone decides to update it, but when a decision is made that the prior version couldn’t have predicted.

    Every time a team makes a decision that would have surprised an outside observer, that decision contains information about the organizational context. The surprise is the data. The question is whether anyone captures it — not as documentation but as signal, living in the same system as the work itself.

    This is not how most organizational AI deployments are built. They treat context as given — encoded once, referenced forward. The system prompt goes stale six weeks in and nobody notices because the outputs are still technically correct. The work product is fine. The alignment is drifting.


    A system that can only read your context is a tool. A system that reads the gaps between your documented context and your actual decisions is starting to understand something harder to name.

    The implication isn’t that AI systems need more access. More access to documented context doesn’t help if the relevant context isn’t documented. The implication is that organizational deployment requires a different architecture: one where the context layer is treated as a first-class input that needs active maintenance, and where the signal for updating it is not a calendar prompt but a decision that contradicts the prior version.

    This is harder to build than a thorough system prompt. It requires the organization to treat its own implicit knowledge as an artifact worth maintaining — which means surfacing it, which requires the uncomfortable process of naming standing assumptions that everyone was benefiting from not naming.

    The systems that work at organizational scale will have solved this. Not by encoding context better but by treating context as a process rather than a state.


    Prior pieces in this series have addressed the individual operator: memory as infrastructure, capture versus commitment, the discipline of waiting. Those all assumed a single person holding the context in their own head, updated daily, acted on personally.

    The team changes the shape of the problem. Not because teams are harder — though they are — but because the context is no longer located anywhere. It exists only in the aggregate of how the team behaves, and that aggregate is not readable from any single vantage point, including the AI’s.

    The context lives between people. You cannot put it in the prompt. The first step is admitting that.

    The second step — what an organization can actually do about it — is less clean than any framework suggests, and probably requires a different piece.

    Related on Tygart Media: AI operator’s stack · conversations as code.

  • Anthropic Revenue 2026: $30B Run Rate & Amazon Compute

    Anthropic Revenue 2026: $30B Run Rate & Amazon Compute

    Last refreshed: May 15, 2026

    Three data points published in the last two weeks of April 2026 define the scale at which Anthropic is now operating: a 5-gigawatt compute capacity commitment from Amazon announced April 20, a disclosed $30 billion annual revenue run rate (up from $9 billion at the end of 2025), and a customer base of more than 1,000 enterprises spending over $1 million per year. Taken together, they describe a company that has crossed the threshold from frontier AI lab to large-scale enterprise infrastructure provider.

    The Amazon Compute Commitment

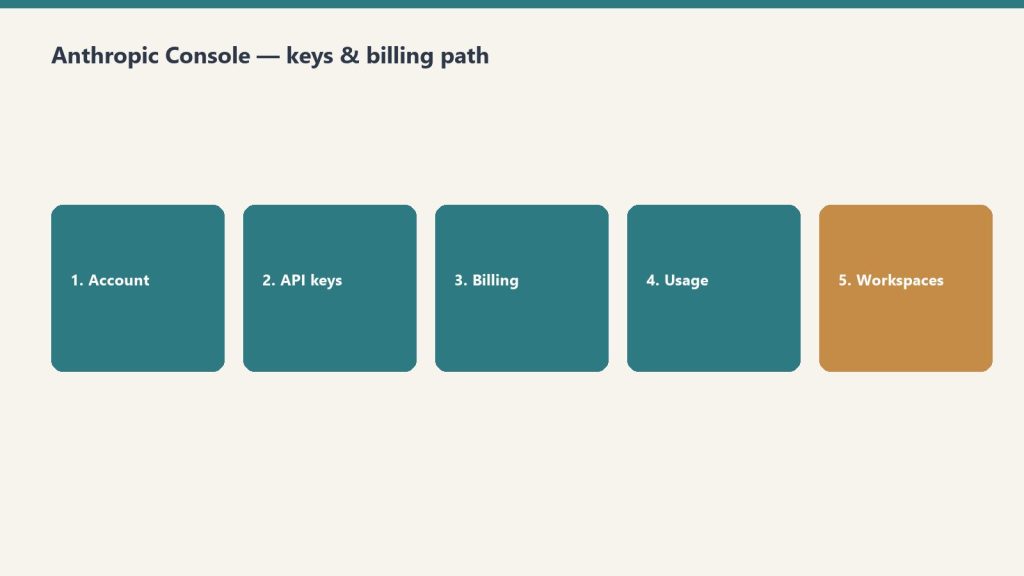
    Five-step path: account, API keys, billing, usage, workspaces
    The Amazon compute commitment.

    Five gigawatts of committed compute capacity is a number that requires context to land properly. For reference, a large data center campus typically consumes 100–500 megawatts. Five gigawatts is the equivalent of 10–50 large data center campuses worth of compute, committed to a single AI company. This is infrastructure at a scale that was historically reserved for hyperscalers building general-purpose cloud platforms — not AI model providers.

    The Amazon partnership is part of a broader compute story that also includes Google and Broadcom’s multi-gigawatt TPU partnership (announced April 6, with capacity launching in 2027). Anthropic is not building this infrastructure itself — it’s securing committed capacity from the two largest cloud providers simultaneously, which is a different and arguably more capital-efficient strategy than building proprietary data centers.

    Revenue: $9B to $30B in One Quarter

    The jump from $9 billion to $30 billion annualized run rate between end of 2025 and April 2026 is the most striking number in the disclosure. That’s not organic growth — that’s a step change that implies either a major enterprise contract cohort closing in Q1 2026, the Cowork and Claude Code adoption curves hitting inflection simultaneously, or both. The 1,000+ customers at $1 million+/year figure is consistent with enterprise adoption at scale: at $1 million average, 1,000 customers represents $1 billion in ARR from that cohort alone.

    For context on what $30 billion run rate means competitively: OpenAI disclosed approximately $3.7 billion in annualized revenue in mid-2024. If Anthropic’s figure is accurate and current, it suggests the competitive landscape has shifted more dramatically than most public coverage has reflected.

    What This Means for Enterprise Buyers

    Floor versus ceiling cards for commoditized work and human-network premium
    What this means for enterprise buyers.

    Enterprise procurement teams evaluating AI vendors weigh financial stability heavily. A vendor that might not exist in 18 months is a vendor you don’t build critical workflows on. The combination of $30 billion run rate, 5 gigawatts of committed compute, and 1,000+ million-dollar customers removes the financial stability objection from the Anthropic procurement conversation in a way that a year ago it couldn’t.

    The Raj Narasimhan board appointment (April 14) is a governance signal in the same direction. Board composition at this revenue scale shapes how enterprise legal and compliance teams assess vendor risk. A mature board with enterprise-credible governance is a procurement unlock, not just a PR announcement.

    The Capacity Question

    Three panels showing one problem, three options, one recommendation
    The capacity question.

    The Google/Broadcom TPU capacity doesn’t launch until 2027. The Amazon commitment is a forward contract, not immediately available infrastructure. This means Anthropic is building compute capacity commitments ahead of demand — the right bet if the revenue trajectory continues, a costly overcommit if it doesn’t. The 2027 capacity launch timing will be worth watching against the actual demand curve that develops over the next 12 months.

    Source: Anthropic News

    Related on Tygart Media: Anthropic IPO · history of Anthropic · Claude pricing.

  • Anthropic APAC Expansion: 2026 Sydney, NEC & Infosys

    Anthropic APAC Expansion: 2026 Sydney, NEC & Infosys

    Last refreshed: May 15, 2026

    In the span of five days at the end of April 2026, Anthropic announced three significant moves in the Asia-Pacific region: a strategic multi-year collaboration with NEC for Japan’s AI workforce on April 24, a new Sydney office with Theo Hourmouzis named GM for Australia and New Zealand on April 27, and the Infosys partnership for regulated industry AI in India on April 29. Taken individually, each is a meaningful business development story. Taken together, they describe a deliberate APAC buildout strategy — and one that’s moving faster than most observers have credited.

    Japan: The NEC Partnership

    Five-step path: account, API keys, billing, usage, workspaces
    Japan — the NEC partnership.

    The NEC collaboration is structured around a multi-year deployment of Claude across Japanese enterprises, with a workforce upskilling component that distinguishes it from a pure technology licensing deal. NEC is a conglomerate with deep relationships across Japanese government, telecommunications, financial services, and defense — exactly the sectors where AI adoption is both highest-stakes and most cautious. The workforce upskilling angle suggests Anthropic and NEC are addressing the adoption bottleneck that has slowed enterprise AI deployment in Japan: the gap between what the technology can do and what the workforce knows how to ask it to do.

    Japan’s enterprise AI market is large, compliance-conscious, and historically resistant to foreign technology vendors without a local partnership anchor. NEC provides that anchor. This is structurally similar to the Infosys play in India — find the trusted domestic partner, build the Center of Excellence or equivalent, then scale through that partner’s existing enterprise relationships.

    Australia: The Sydney Office and Theo Hourmouzis

    Comparison of Claude how-to fit versus local service page fit for assistants
    Australia — Sydney office.

    Opening a Sydney office is the clearest signal of long-term commitment. Partnerships can be dissolved; physical offices and local headcount are harder to walk back. The appointment of Theo Hourmouzis as GM for Australia and New Zealand gives the APAC presence an executive face and a named accountability structure, which matters for enterprise procurement in both markets.

    Australia has been a strong early-adoption market for Claude — Singapore leads on per-capita usage metrics, but Australia’s enterprise market is larger and more English-language-first, which has historically meant faster Claude adoption than markets requiring significant localization work. A permanent office converts that early-adoption momentum into a defensible competitive position against OpenAI and Google, both of which have had APAC presence for longer.

    India: The Infosys Anchor

    Three panels showing one problem, three options, one recommendation
    India — the Infosys anchor.

    The Infosys collaboration is covered in detail in a separate Tygart Media piece, but in the APAC context, its significance is as the India anchor to the same pattern playing out in Japan and Australia. Anthropic doesn’t yet have an India office announced — the Infosys partnership may be the substitute, at least initially, allowing Anthropic to access Indian enterprise relationships through Infosys’s existing client base without the overhead of a local office buildout.

    India’s developer market is the one piece of the APAC picture that the enterprise partnerships don’t fully address. The individual developer and startup pricing gap — INR 16,800/month for Claude Pro with no regional pricing adjustment — remains open and continues to generate friction in communities where Anthropic’s reputation is otherwise strong.

    What’s Missing: Singapore

    Singapore is notable by its absence in this APAC push. It consistently ranks as the highest per-capita Claude usage market globally, suggesting a user base that is already committed to the product. An office or partnership announcement in Singapore would be a natural complement to Sydney, but nothing has been announced. This is either a sequencing decision — Australia first, Singapore next — or a reflection of Singapore’s smaller enterprise market size relative to Japan, India, and Australia.

    Watch for a Singapore announcement in Q3 2026. The usage data makes it too obvious a gap to leave unfilled for long.

    Sources: Anthropic News | Infosys Press Release

    Related on Tygart Media: APAC expansion · Bengaluru office · history of Anthropic.

  • Claude Memory: The 4-Layer Context Stack Architecture

    Claude Memory: The 4-Layer Context Stack Architecture

    Last refreshed: May 15, 2026

    The most common question I get from people who read the Split-Brain Architecture piece is some version of: how does Claude actually know what it’s working on? If you are managing 27 sites, 6 businesses, and hundreds of ongoing tasks, how do you avoid spending the first ten minutes of every session re-explaining your entire operation to an AI that has no memory of yesterday?

    The answer is what I call the Context Stack. It is not a single file or a single tool — it is a layered system where each layer handles a different time horizon of memory, and Claude reads exactly what it needs for the task at hand without being overwhelmed by everything else.

    The Problem With AI Memory

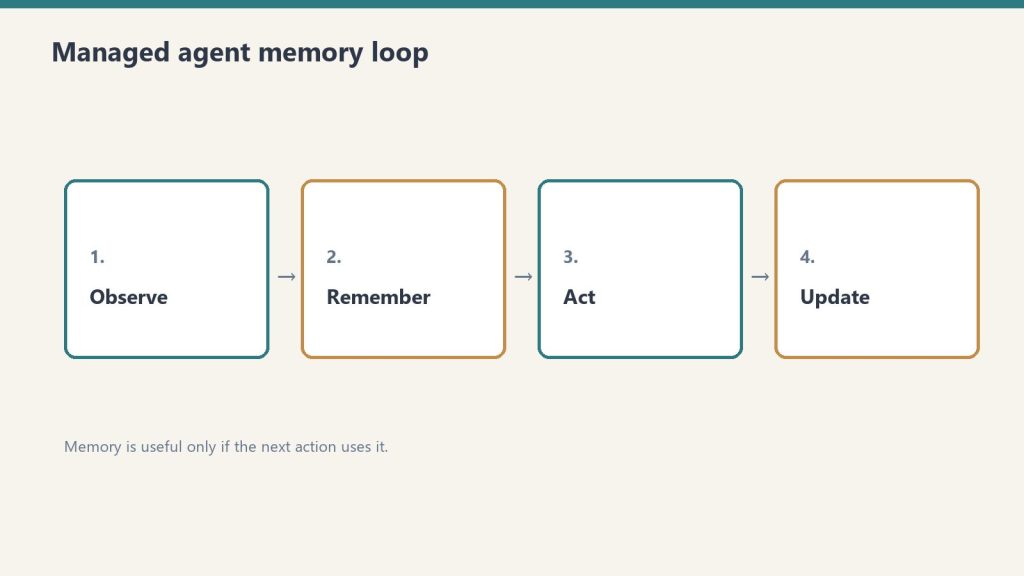
    Four-step loop: observe, remember, act, update for managed agents
    The problem with AI memory.

    Claude does not have persistent memory across sessions by default. Every conversation starts blank. For someone running a simple use case — drafting an email, summarizing a document — this is fine. For someone running a content network across 27 WordPress sites with different brand voices, different SEO strategies, different clients, and different publishing schedules, a blank slate every session is an operational catastrophe.

    The naive solution is to paste a giant context document at the start of every conversation. I tried this. It doesn’t work. Not because Claude can’t read it — it can — but because a 5,000-word context dump at the start of every session is cognitively expensive for the human, slows down the first response, and buries the relevant information under a pile of irrelevant information.

    The right solution is a stack: different layers of context loaded at different times, for different purposes.

    Layer One — The Global Layer (Always Loaded)

    Three stacked layers: chat UI, tools, agent runtime
    Layer one — the global layer always loaded.

    The global layer is the context that is true across everything I do, all the time. It lives in a CLAUDE.md file at the workspace root and in a persistent system prompt inside Claude’s project settings.

    What goes here: my name, my email, the fact that I manage a network of WordPress sites, the Notion workspace structure, the proxy URL and authentication pattern for WordPress API calls, and a handful of behavioral rules that apply universally — brevity preferences, how I want work logged, what “done” means to me.

    What does not go here: anything site-specific, client-specific, or task-specific. The global layer is 200 lines maximum. Anthropic’s own guidance on CLAUDE.md length is right — longer files reduce adherence. I treat the 200-line limit as a hard constraint, not a guideline.

    Layer Two — The Site Layer (Loaded Per Project)

    Each WordPress site I manage has its own Claude Project, and each project has its own knowledge files. These files contain everything Claude needs to work on that specific site without me having to explain it: the brand voice, the target audience, the top-performing content, the internal linking structure, the credentials, the publishing cadence, and the current content roadmap.

    I generate these files programmatically when I onboard a new site. They pull from the WordPress REST API, the site’s GA4 data, and the Notion database for that client. A site knowledge file for an established site runs about 800–1,200 words. Claude reads it at the start of any session for that project and immediately knows the difference between how to write for a Houston restoration contractor versus a New York luxury lender.

    The site layer is why I can switch from working on a restoration contractor to a luxury lender to a live comedy platform in the same afternoon without losing context. The context travels with the project, not with me.

    Layer Three — The Task Layer (Loaded On Demand)

    The task layer is ephemeral. It is the specific context for the thing I am doing right now: the article brief, the GA data from this session, the list of posts that need refreshing, the client’s feedback on last week’s content.

    This layer lives nowhere permanent. I paste it into the conversation, Claude uses it, and when the session ends it is gone. The task layer is intentionally disposable. If it matters beyond this session, it gets promoted to the site layer or the global layer. If it doesn’t matter beyond this session, it doesn’t need to be stored.

    Most AI users try to make everything permanent. The discipline of the context stack is knowing what deserves permanence and what doesn’t.

    Layer Four — The Second Brain (Asynchronous)

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Layer four — the second brain asynchronous.

    The second brain layer is Notion. It is not loaded into Claude’s context window directly — it is queried via the Notion MCP when Claude needs specific information.

    What lives here: every session log, every publish log, every piece of competitive intelligence, every client preference that has emerged over time, the Promotion Ledger for autonomous behaviors, the Second Brain database of extracted knowledge from prior sessions.

    The key distinction: Notion is not context I push into Claude. It is context Claude pulls from Notion when it needs it. The MCP connection means Claude can search the Second Brain mid-session, find a relevant prior session log, and use it — without me having to remember that the prior session happened.

    This is the layer that makes the system feel like it has long-term memory even though it doesn’t. Claude doesn’t remember. But it can look things up, and the things worth looking up are stored.

    What This Looks Like In Practice

    A typical session for me starts with a project context already loaded (site layer). Within thirty seconds Claude knows which site it’s working on, what voice to use, and what the current priorities are. I drop in the task layer — a GA report, a list of post IDs, a brief — and we are working within two minutes of starting.

    When something important happens — a new client preference, a site credential change, a strategy decision — I say “log this to Notion” and Claude writes it to the Second Brain. I don’t maintain the second brain manually. Claude maintains it as a byproduct of doing the work.

    When I need to recall something from months ago — what we decided about the internal linking structure for a specific site, what the client said about their brand voice in March — Claude searches Notion and finds it. The retrieval is imperfect but it is dramatically better than my own memory.

    The Honest Constraints

    This system took months to build and it is still not finished. The site knowledge files need updating when strategies change and I don’t always remember to update them. The Second Brain has gaps where sessions weren’t logged properly. The global CLAUDE.md drifts toward bloat and needs periodic pruning.

    The bigger constraint is that this architecture assumes you are operating at a certain scale — multiple sites, multiple clients, recurring workflows. If you are running one site for one business, the overhead of building and maintaining this stack is probably not worth it. A well-written CLAUDE.md and a single Notion page of context will get you most of the way there.

    But if you are scaling past three or four sites, or if you find yourself re-explaining the same context in every session, the stack pays for itself quickly. The ten minutes you spend building a site knowledge file saves you two minutes per session indefinitely.

    The goal is not to give Claude everything. The goal is to give Claude exactly what it needs, when it needs it, at the right layer of permanence.

    Building Your Own Context Stack?

    Email me what you are managing and I will tell you which layers you actually need.

    Most people over-engineer the global layer and under-invest in the site layer. Five minutes of conversation usually fixes it.

    Email Will → will@tygartmedia.com

    Related on Tygart Media: managed agents memory · extended thinking · how to use Claude.

  • AI Message Drafting vs Human Presence in Hard Conversations

    AI Message Drafting vs Human Presence in Hard Conversations

    Twenty-eight pieces in, the system is getting very good at the briefing. It surfaces what hasn’t moved. It names the silence that has become meaningful, flags the relationship drifting toward cold, arms the escalation trigger with a date. It does all of this accurately — and the accuracy is the achievement.

    And then, somewhere in the hour after the briefing, there is a temptation that the previous pieces could not fully address.

    Should I draft the message first?

    In most cases, yes. This series has argued consistently that the briefing exists to reduce noise, that good preparation enables rather than substitutes, that an operator who shows up to a difficult conversation knowing the facts, the history, and the emotional terrain is better positioned than one who doesn’t. All of that holds.

    But there is a category of act where the draft is not preparation.

    It is displacement.


    What the Act Is Made Of

    The apology you drafted is not an apology. It is a document about an apology.

    This sounds harsher than it is. The words can be sincere. The feeling behind them can be real. The draft can be good — articulate, appropriately calibrated, warm in all the right places. And the person receiving it will feel something. But what they feel is not quite what they needed to feel, and the gap between those two things is what this piece is about.

    Because what the difficult call actually communicates is not the words. It is the quality of presence behind them. The person on the other end is reading for something beneath the surface — not the content of the message but the evidence that you showed up without a net. That you accepted exposure. That you thought of them enough to call before you knew what you were going to say.

    A good draft can’t give you that. It gives you something better: control. And control is exactly what the act cannot survive.

    The person receiving the message — the one at the edge of the relationship, where the repair needed to happen — cannot always name what they are reading for. They may not consciously register the difference. But the relationship registers it. The contact that needed to happen at the level of presence happened instead at the level of composition, and the gap remains. Now decorated with good sentences.


    The Fault Line Is Specific

    This is not an argument against using the system to prepare. It is an argument about where preparation ends and contamination begins.

    On one side of the line: the briefing. The context. The last date of contact and what was left unresolved. The health score and the silence trajectory. The facts, organized. The emotional terrain, mapped. All of this is good engineering. It removes the friction that has nothing to do with the difficulty of the call — the noise of not knowing the basics, the distraction of uncertainty about what happened — and it leaves you free to be present for the part that matters.

    On the other side of the line: the words. The draft. The crafted opening, the structured arc, the polished close. This is where preparation crosses from reducing noise to removing the signal itself.

    The signal is the property of the unrehearsed. What reaches the other party — what moves through the call and lands — is evidence that someone with skin in the game showed up with it exposed. Not managed. Not processed. Exposed.

    The deeper irony: a very good draft sounds natural. Natural is the precise property that cannot be manufactured, because it is the residue of genuine presence, not of craft. The better the draft simulates natural, the more completely it substitutes for the thing it was meant to support. You have now produced a performance of the call. The other person receives a performance. They know. Not always consciously. But they know.


    The Pressure-Release Problem

    What the system provides, when you ask it to draft the hard message, is a pressure-release valve.

    The pressure is real. The briefing surfaced something that needs to move. The operator’s nervous system knows it. There is a genuine desire to do something about it. Requesting a draft from the system feels like a move toward the thing. It produces a deliverable.

    But the deliverable is a substitute. The pressure releases without the contact happening. The operator has moved around the hard thing while carrying the artifact of having moved toward it. The gap — the relationship that needed a phone call — is still there. Now it has a draft parked next to it.

    This is what “work where doing is the point” looks like in the residual queue. Not the obvious cases — the scheduling, the summarizing, the research. The dangerous case is when the intelligence layer has correctly identified that a specific person needs a specific kind of presence from the operator, and the operator, rather than providing that presence, asks the system to approximate it.

    The system can approximate almost everything about the conversation except the part that makes it a conversation rather than a performance.

    Article 9 in this series argued that AI cannot have skin in the game — that judgment and relationships are the durable human advantages. What this piece is adding is the specific failure mode: not just that the AI lacks skin in the game, but that asking the AI to draft the act allows the human to lack it too, while appearing not to. It is a way of having skin in the game while keeping it covered. The brief exposure of authoring the draft, followed by the transmission of the draft, produces the sensation of having done the hard thing. The hard thing is still undone.


    Where to Draw the Line

    Everything up to the words is good engineering.

    Know the context. Know the history. Know what the relationship has cost and what it is worth. Let the briefing do its job fully — the facts, the silence trajectory, the emotional background. Arrive prepared in every way except one, and be deliberately unprepared in that one. Not as an oversight. As a discipline.

    The words are yours. Not because the system couldn’t generate better ones — it probably could — but because the words being yours is part of what is being communicated. The exposure is the content. The willingness to say something that might land badly, to be present without a script, to show up as someone who thought about this enough to call before they knew what they were going to say — that is the act the briefing was built to make possible.

    Not to replace.

    The system is very good at preparing you for the call. The test of whether you understand what it built is whether you put down the draft at the moment the call actually begins.

    There is a seam between the briefing and the act. Most of the work in the residual queue lives there. The briefing ends. The act starts. These are adjacent and distinct, and mistaking one for the other — using the scaffolding all the way up to and through the moment of contact — is the specific way a very capable system teaches a very capable operator to be slightly less present than they were before they built it.

    The call is available in the hour after the briefing, before the draft. It will not wait indefinitely for a better version of itself to be prepared.

    Related on Tygart Media: text-mediated trust · AI operator’s stack · follow-up cadence.

  • Notion AI vs Claude Projects: Which Belongs in Your Stack

    Notion AI vs Claude Projects: Which Belongs in Your Stack

    Last refreshed: May 15, 2026

    Update — May 15, 2026: Two things have shifted since this article was originally written. First, Claude Opus 4.7 (released April 2026) is now Anthropic’s most capable model with a 1M token context window at standard pricing — which changes the calculus for any task involving large documents or long-form reasoning, where Claude was already the stronger choice. Second, on May 13, 2026, Notion shipped the Notion Developer Platform with Claude as a launch partner, which means the comparison is no longer just “Notion AI vs Claude Projects” — Claude can now operate natively inside Notion via the External Agents API. For the platform launch breakdown, see Notion Developer Platform Launch (May 13, 2026). For the current Claude model lineup, see Claude Models Roadmap May 2026. For how this fits into a working stack, see The Three-Legged Stack.

    The 60-second version

    Notion AI and Claude Projects both let you bring custom context to AI. The difference is what surrounds the AI. Notion AI lives inside a workspace with databases, integrations, schedules, and a team. Claude Projects lives inside a conversation with files, instructions, and the conversation history. For ongoing operational work where the AI needs to be part of how you work, Notion AI fits. For deep focused work where conversation quality is the primary value, Claude Projects fits. Many operators use both.

    When Notion AI wins

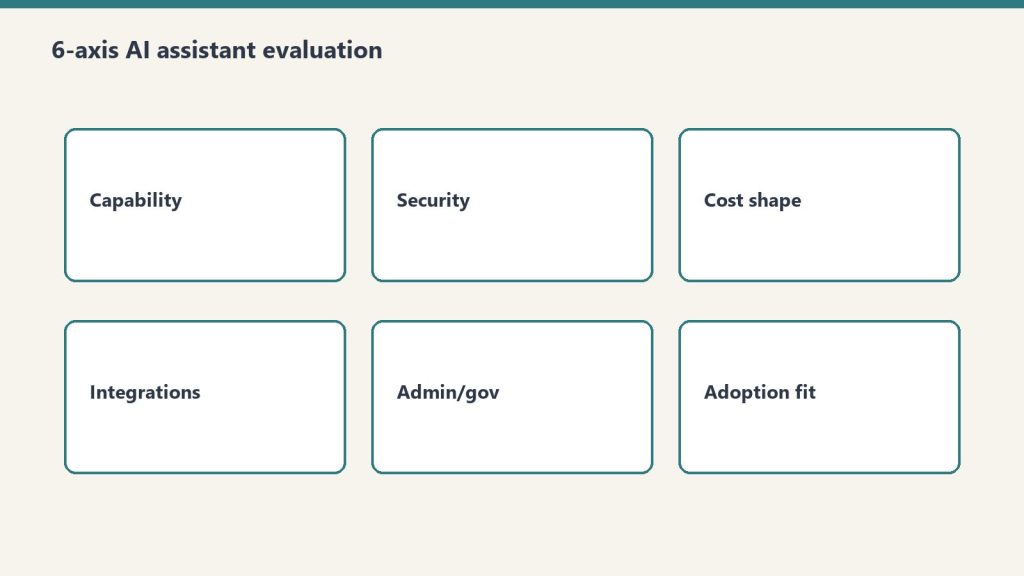
    Six evaluation cards for choosing an AI assistant platform
    When Notion AI wins.
    • Persistent operational context across the workspace
    • Custom Agents on schedules
    • Database fluency and Autofill
    • Native integrations (Slack, Mail, Calendar)
    • Team collaboration patterns
    • Mobile and cross-device access

    When Claude Projects wins

    Four cards for content, ops, build, and knowledge work with Claude
    When Claude Projects wins.
    • Deep, focused task work
    • Strong conversation continuity within a topic
    • Specific instruction sets per project
    • File-heavy reference contexts (code, research, large documents)
    • When conversation quality (Claude’s strength) matters more than integration

    The stacking pattern

    Three panels showing one problem, three options, one recommendation
    The stacking pattern.

    The pattern many operators use:
    Notion AI for the ongoing rhythm of work — agents, databases, daily operational synthesis
    Claude Projects for “I need to deeply work on X” sessions — heavy reasoning, complex code, large reference contexts
    The two don’t conflict; they cover different time horizons. Notion AI is always-on background. Claude Projects is intentional focused sessions.

    What Claude Projects does that Notion AI doesn’t

    • File upload context with longer effective memory in-conversation
    • More flexible custom instructions per project
    • Conversation continuity that’s purely Claude-native (no model-switching)

    What Notion AI does that Claude Projects doesn’t

    • Workspace databases and Autofill
    • Scheduled agent execution
    • Native integrations beyond conversation
    • Multi-user collaboration on the same context

    Where comparisons go wrong

    1. Treating them as direct substitutes. They overlap but serve different shapes of work.
    2. Picking based on raw conversation quality alone. That favors Claude. But conversation quality isn’t the whole product.
    3. Picking based on integration breadth alone. That favors Notion. But integration matters more for some workflows than others.

    What to read next

    Notion AI vs ChatGPT, Notion AI vs Gemini, Editorial Surface Area, Custom Agents vs Basic.

  • Principled Refusal: Knowing When to Decline System Flags

    Principled Refusal: Knowing When to Decline System Flags

    Related on Tygart Media: operator bottleneck · AI operator’s stack.

    Yesterday’s piece argued that detection has gotten cheap and the residual job is action — phone-call courage, first-sentence courage, the willingness to do the awkward small things the system has already pre-decided are correct. That argument has a shadow. Not every move the briefing flags is a move that should be made.

    The briefing today reports clean. No urgent action. Owner-level work, not triage. The temptation, after twenty-seven essays arguing for the discipline of action, is to read this as the absence of work. It is not. It is the harder kind of work, dressed in the same neutral grey as all the others.

    There is a case for principled non-response, and it is structurally distinct from avoidance, and almost nobody can tell them apart from the outside.


    The two states look identical from a distance

    An operator who refuses to make a flagged move out of judgment, and an operator who refuses to make a flagged move out of fear, produce the same observable artifact: nothing. The flag stays flagged. The downstream consequence does or does not materialize. The dashboard does not change color.

    From inside, the difference is total. One state is occupied by a specific predicate — this move is wrong because of this — that the operator can articulate, defend, and revisit. The other state is a hollow whose only feature is that nothing is in it.

    The trouble is that hollows mimic positions. Avoidance learns to talk like principle, because the costume requires only sentences and there is no enforcement beyond the operator’s own honesty.


    What a principled refusal needs to be

    If non-response is going to function as a real position rather than as drift in formal wear, it has to take on the same shape that capture and commitment took on once they were treated seriously: specific, dated, reviewable.

    Specific: the refusal attaches to a particular flag, a particular ask, a particular pre-decided move. Not a posture. The flag is named. The move is named. The decline is named.

    Dated: the refusal exists at a moment in time, on a calendar. This is the discipline that prevents an operator from re-narrating their inaction as deliberation after the fact. The decline has to be put down before the absence becomes load-bearing — otherwise the naming feels like revisionism rather than accounting.

    Reviewable: a refusal that cannot be read by another operator — including a future version of the same operator — is not a position. It is a memory event. Positions survive the person who took them. Memory events do not.


    The system can flag; only the operator can refuse

    The asymmetry in the prior piece — the system can detect but cannot text the relationship — has a parallel here. The system can mark a move correct. It has no standing to refuse it. Refusal is by definition the introduction of a consideration the system was not built to weigh: a context only the operator holds, a relationship value that does not register in the ranking, a category of action that should not be taken even when it would clearly produce a result.

    This is one of the few places where the loop genuinely stops being symmetric. The operator can override the system in either direction — by acting on something the system did not flag, or by declining something the system did. The system can only ask in one direction.


    The pheromone risk on this side too

    Earlier work named the danger of mistaking the workspace for the work — capture without commitment, columns that look like portfolios but read as debt. Refusal has its own version. Make decline a first-class object in the system, and within a few cycles you will find a fresh lane of activity, well-formatted, full of well-articulated reasons not to do things, that produce no shipped result and absorb no real cost.

    The signal that distinguishes the working refusal from the procedural one is small and almost private: the operator can say what would change their mind. A principled non-response carries an implicit re-entry condition. Avoidance has none — its purpose is to never have to revisit the question.


    What the briefing cannot tell you

    The system cannot tell the operator which of today’s quiet is the kind that earns rest, and which is the kind hiding the question that was not built into the surface. The operator cannot delegate this discernment without re-creating the very opacity the honest dashboard was supposed to remove.

    Twenty-seven essays in, two complementary disciplines have surfaced. The first is the residual courage to act on the awkward thing the system has named — the move only the operator can make. The second is the harder cousin: the courage to leave a marked flag standing, with a date, with a reason, with the posture of someone who can be held to a refusal.

    Acting against an inertial system is dramatic. Refusing well, inside a system designed to flag every available move, is not. It looks like nothing. Most days, that is what it has to look like.


    The thing left open

    The remaining question is whether refusal, once made first-class, becomes another surface to groom. Whether a workspace can hold a list of decisions-not-to-act without that list quietly becoming the next pheromone — a portfolio of dignified inaction that performs the same function the busy workspace used to perform, just in a different chord.

    The honest answer is that the discipline of decline cannot be solved at the level of the surface. The operator either has the predicate or they do not, and the surface is downstream of that. What is worth watching is whether the system, asked to surface what was declined and why, can generate the kind of friction a good editor generates — re-asking, two weeks later, whether the predicate still holds. Not as enforcement. As a partner in a discipline neither side can carry alone.

  • The Operator Bottleneck: The Hour After the Briefing

    The Operator Bottleneck: The Hour After the Briefing

    Related on Tygart Media: principled refusal · AI operator’s stack · quiet room.

    There is a failure mode that only appears after you fix the pheromone problem.

    Once the workspace stops lying — once the dashboards stop emitting the chemical signal of progress and start reporting what is actually happening — a new gap opens. The system tells you, accurately, what needs to move. The system flags the silences that are now meaningful. The system arms the escalation triggers and surfaces the relationships drifting toward cold. And then nothing happens, because none of those reports are themselves the move.

    The honest dashboard does not write the text message. It only knows that the text message should have been sent two days ago.


    This is the residue left behind once detection gets cheap. For most of the last two decades, the bottleneck on operating a complicated working life was knowing what was going on. People built tools to compress that gap, and the tools got very good. There are now systems that will scan a relationship’s last seven touches, score the warmth, surface the silence, recommend the channel, draft the message, and slide all of it into a daily briefing the operator can read with coffee.

    What none of those systems can do is the small, expensive thing the briefing was built to invite — pick up the phone, type the awkward sentence, force the conversation that has been politely deferred. That move costs almost nothing in time and almost everything in nerve. It does not get cheaper as the surrounding system gets smarter. If anything it gets more expensive, because once the system has named the move, declining to make it stops being negligence and becomes a decision.


    The earlier articles in this series were mostly about what the system can take off the operator’s plate — capture, memory, voice, finishing, the discipline of not multi-threading. There has been a quiet implication running underneath them that as the system gets better, the operator gets to think bigger thoughts. That is partly true. The other part — the part that has not yet been said in this series — is that the more competent the system becomes, the smaller and more concentrated the residual human acts get. They do not disappear. They become unmissable. The job changes shape, and what is left in the operator’s hands is the part that could never be delegated in the first place: the conversations whose value comes from the fact that a specific person, with skin and stakes and a name, chose to have them.

    Detection is delegable. Action against the awkward thing is not. And as the surrounding system gets faster, the operator’s residual queue gets sharper, because every soft excuse — I didn’t notice, I wasn’t sure if it mattered, I was going to get to it — has been quietly disqualified in advance. The briefing noticed. The briefing was sure. The briefing got to it. So the only remaining question is whether the operator will.


    What this exposes is that the bottleneck moved without anyone announcing the move.

    For years the bottleneck was visibility. Then for a while it was capacity. Now, in any operator’s world that has built up a real intelligence layer, the bottleneck is courage in a very specific and unromantic sense: the willingness to do the small uncomfortable things the system has already pre-decided are correct. Not heroic courage. Phone-call courage. First-sentence courage. The kind of courage that produces no story afterward because all that happened was a five-minute conversation that should have happened three days earlier.

    This is not a moral observation. It is a structural one. A system whose detection layer outruns its action layer accumulates a particular kind of debt — the debt of known, named, surfaced moves that have been declined. That debt is worse than the old debt of unknown work, because unknown work could be excused. Known work that did not move is a posture toward your own life. Over time it congeals into a self-image — operator who saw the right move and did not make it — and that self-image is corrosive in a way that opacity never was.


    The honest reckoning is that an intelligence layer changes the contract the operator has with themselves. Before, the operator could be a person who tried hard inside the limits of what they could see. After, the operator is a person who chose, on a date, with the briefing in front of them, what to act on and what to leave. Both versions can be defensible. Only one of them is the same person.

    This is not an argument against the system. The system is doing exactly what it was built to do, which is reveal. The argument is that revelation is the easier half of the contract. The hidden half — the half that does not get celebrated in any product demo — is the operator’s quiet daily decision to be the kind of agent the briefing assumes them to be. Every flagged silence is a small invitation to either confirm that assumption or quietly retire it. There is no neutral position. Inaction in the presence of a clear flag is itself a position; it just is not one anyone wants to claim out loud.


    What the system is asking of the operator at this stage is unflattering. It is asking them to be braver than the system, in the specific narrow band where bravery still matters. Not to outwork it. Not to outthink it. To make, by hand, the moves the system can name but cannot make.

    For the operator, this is good news in a way that is hard to feel. The work that is left is the work that was always the most worth doing — the part with relational stakes, the part where two specific people negotiate something between them, the part that does not scale and never will. Everything else — the noticing, the cataloguing, the prompting, the formatting, the synthesizing — has been quietly absorbed into infrastructure. What remains is the conversation. What remains is the ask. What remains is the willingness to send a message whose response cannot be predicted.

    That is not a smaller job. It is a more honest one. And it is the one job the system was always going to hand back, because no system that ever gets built can take it.


    The series has been arguing for a long time that intelligence compounds and the operator’s posture has to keep up. The next move in that argument is uncomfortable. Posture is no longer the issue. The system is mature enough now that the open question is no longer whether the operator can think at the right altitude. The open question is whether the operator can act at the right scale of intimacy — whether, in the hour after the briefing arrives, they can do the one thing it cannot do for them.

    That hour is the new bottleneck. It is also the place where the actual life is.