Three data points published in the last two weeks of April 2026 define the scale at which Anthropic is now operating: a 5-gigawatt compute capacity commitment from Amazon announced April 20, a disclosed $30 billion annual revenue run rate (up from $9 billion at the end of 2025), and a customer base of more than 1,000 enterprises spending over $1 million per year. Taken together, they describe a company that has crossed the threshold from frontier AI lab to large-scale enterprise infrastructure provider.
The Amazon Compute Commitment
The Amazon compute commitment.
Five gigawatts of committed compute capacity is a number that requires context to land properly. For reference, a large data center campus typically consumes 100–500 megawatts. Five gigawatts is the equivalent of 10–50 large data center campuses worth of compute, committed to a single AI company. This is infrastructure at a scale that was historically reserved for hyperscalers building general-purpose cloud platforms — not AI model providers.
The Amazon partnership is part of a broader compute story that also includes Google and Broadcom’s multi-gigawatt TPU partnership (announced April 6, with capacity launching in 2027). Anthropic is not building this infrastructure itself — it’s securing committed capacity from the two largest cloud providers simultaneously, which is a different and arguably more capital-efficient strategy than building proprietary data centers.
Revenue: $9B to $30B in One Quarter
The jump from $9 billion to $30 billion annualized run rate between end of 2025 and April 2026 is the most striking number in the disclosure. That’s not organic growth — that’s a step change that implies either a major enterprise contract cohort closing in Q1 2026, the Cowork and Claude Code adoption curves hitting inflection simultaneously, or both. The 1,000+ customers at $1 million+/year figure is consistent with enterprise adoption at scale: at $1 million average, 1,000 customers represents $1 billion in ARR from that cohort alone.
For context on what $30 billion run rate means competitively: OpenAI disclosed approximately $3.7 billion in annualized revenue in mid-2024. If Anthropic’s figure is accurate and current, it suggests the competitive landscape has shifted more dramatically than most public coverage has reflected.
What This Means for Enterprise Buyers
What this means for enterprise buyers.
Enterprise procurement teams evaluating AI vendors weigh financial stability heavily. A vendor that might not exist in 18 months is a vendor you don’t build critical workflows on. The combination of $30 billion run rate, 5 gigawatts of committed compute, and 1,000+ million-dollar customers removes the financial stability objection from the Anthropic procurement conversation in a way that a year ago it couldn’t.
The Raj Narasimhan board appointment (April 14) is a governance signal in the same direction. Board composition at this revenue scale shapes how enterprise legal and compliance teams assess vendor risk. A mature board with enterprise-credible governance is a procurement unlock, not just a PR announcement.
The Capacity Question
The capacity question.
The Google/Broadcom TPU capacity doesn’t launch until 2027. The Amazon commitment is a forward contract, not immediately available infrastructure. This means Anthropic is building compute capacity commitments ahead of demand — the right bet if the revenue trajectory continues, a costly overcommit if it doesn’t. The 2027 capacity launch timing will be worth watching against the actual demand curve that develops over the next 12 months.
In the span of five days at the end of April 2026, Anthropic announced three significant moves in the Asia-Pacific region: a strategic multi-year collaboration with NEC for Japan’s AI workforce on April 24, a new Sydney office with Theo Hourmouzis named GM for Australia and New Zealand on April 27, and the Infosys partnership for regulated industry AI in India on April 29. Taken individually, each is a meaningful business development story. Taken together, they describe a deliberate APAC buildout strategy — and one that’s moving faster than most observers have credited.
Japan: The NEC Partnership
Japan — the NEC partnership.
The NEC collaboration is structured around a multi-year deployment of Claude across Japanese enterprises, with a workforce upskilling component that distinguishes it from a pure technology licensing deal. NEC is a conglomerate with deep relationships across Japanese government, telecommunications, financial services, and defense — exactly the sectors where AI adoption is both highest-stakes and most cautious. The workforce upskilling angle suggests Anthropic and NEC are addressing the adoption bottleneck that has slowed enterprise AI deployment in Japan: the gap between what the technology can do and what the workforce knows how to ask it to do.
Japan’s enterprise AI market is large, compliance-conscious, and historically resistant to foreign technology vendors without a local partnership anchor. NEC provides that anchor. This is structurally similar to the Infosys play in India — find the trusted domestic partner, build the Center of Excellence or equivalent, then scale through that partner’s existing enterprise relationships.
Australia: The Sydney Office and Theo Hourmouzis
Australia — Sydney office.
Opening a Sydney office is the clearest signal of long-term commitment. Partnerships can be dissolved; physical offices and local headcount are harder to walk back. The appointment of Theo Hourmouzis as GM for Australia and New Zealand gives the APAC presence an executive face and a named accountability structure, which matters for enterprise procurement in both markets.
Australia has been a strong early-adoption market for Claude — Singapore leads on per-capita usage metrics, but Australia’s enterprise market is larger and more English-language-first, which has historically meant faster Claude adoption than markets requiring significant localization work. A permanent office converts that early-adoption momentum into a defensible competitive position against OpenAI and Google, both of which have had APAC presence for longer.
India: The Infosys Anchor
India — the Infosys anchor.
The Infosys collaboration is covered in detail in a separate Tygart Media piece, but in the APAC context, its significance is as the India anchor to the same pattern playing out in Japan and Australia. Anthropic doesn’t yet have an India office announced — the Infosys partnership may be the substitute, at least initially, allowing Anthropic to access Indian enterprise relationships through Infosys’s existing client base without the overhead of a local office buildout.
India’s developer market is the one piece of the APAC picture that the enterprise partnerships don’t fully address. The individual developer and startup pricing gap — INR 16,800/month for Claude Pro with no regional pricing adjustment — remains open and continues to generate friction in communities where Anthropic’s reputation is otherwise strong.
What’s Missing: Singapore
Singapore is notable by its absence in this APAC push. It consistently ranks as the highest per-capita Claude usage market globally, suggesting a user base that is already committed to the product. An office or partnership announcement in Singapore would be a natural complement to Sydney, but nothing has been announced. This is either a sequencing decision — Australia first, Singapore next — or a reflection of Singapore’s smaller enterprise market size relative to Japan, India, and Australia.
Watch for a Singapore announcement in Q3 2026. The usage data makes it too obvious a gap to leave unfilled for long.
The most common question I get from people who read the Split-Brain Architecture piece is some version of: how does Claude actually know what it’s working on? If you are managing 27 sites, 6 businesses, and hundreds of ongoing tasks, how do you avoid spending the first ten minutes of every session re-explaining your entire operation to an AI that has no memory of yesterday?
The answer is what I call the Context Stack. It is not a single file or a single tool — it is a layered system where each layer handles a different time horizon of memory, and Claude reads exactly what it needs for the task at hand without being overwhelmed by everything else.
The Problem With AI Memory
The problem with AI memory.
Claude does not have persistent memory across sessions by default. Every conversation starts blank. For someone running a simple use case — drafting an email, summarizing a document — this is fine. For someone running a content network across 27 WordPress sites with different brand voices, different SEO strategies, different clients, and different publishing schedules, a blank slate every session is an operational catastrophe.
The naive solution is to paste a giant context document at the start of every conversation. I tried this. It doesn’t work. Not because Claude can’t read it — it can — but because a 5,000-word context dump at the start of every session is cognitively expensive for the human, slows down the first response, and buries the relevant information under a pile of irrelevant information.
The right solution is a stack: different layers of context loaded at different times, for different purposes.
Layer One — The Global Layer (Always Loaded)
Layer one — the global layer always loaded.
The global layer is the context that is true across everything I do, all the time. It lives in a CLAUDE.md file at the workspace root and in a persistent system prompt inside Claude’s project settings.
What goes here: my name, my email, the fact that I manage a network of WordPress sites, the Notion workspace structure, the proxy URL and authentication pattern for WordPress API calls, and a handful of behavioral rules that apply universally — brevity preferences, how I want work logged, what “done” means to me.
What does not go here: anything site-specific, client-specific, or task-specific. The global layer is 200 lines maximum. Anthropic’s own guidance on CLAUDE.md length is right — longer files reduce adherence. I treat the 200-line limit as a hard constraint, not a guideline.
Layer Two — The Site Layer (Loaded Per Project)
Each WordPress site I manage has its own Claude Project, and each project has its own knowledge files. These files contain everything Claude needs to work on that specific site without me having to explain it: the brand voice, the target audience, the top-performing content, the internal linking structure, the credentials, the publishing cadence, and the current content roadmap.
I generate these files programmatically when I onboard a new site. They pull from the WordPress REST API, the site’s GA4 data, and the Notion database for that client. A site knowledge file for an established site runs about 800–1,200 words. Claude reads it at the start of any session for that project and immediately knows the difference between how to write for a Houston restoration contractor versus a New York luxury lender.
The site layer is why I can switch from working on a restoration contractor to a luxury lender to a live comedy platform in the same afternoon without losing context. The context travels with the project, not with me.
Layer Three — The Task Layer (Loaded On Demand)
The task layer is ephemeral. It is the specific context for the thing I am doing right now: the article brief, the GA data from this session, the list of posts that need refreshing, the client’s feedback on last week’s content.
This layer lives nowhere permanent. I paste it into the conversation, Claude uses it, and when the session ends it is gone. The task layer is intentionally disposable. If it matters beyond this session, it gets promoted to the site layer or the global layer. If it doesn’t matter beyond this session, it doesn’t need to be stored.
Most AI users try to make everything permanent. The discipline of the context stack is knowing what deserves permanence and what doesn’t.
Layer Four — The Second Brain (Asynchronous)
Layer four — the second brain asynchronous.
The second brain layer is Notion. It is not loaded into Claude’s context window directly — it is queried via the Notion MCP when Claude needs specific information.
What lives here: every session log, every publish log, every piece of competitive intelligence, every client preference that has emerged over time, the Promotion Ledger for autonomous behaviors, the Second Brain database of extracted knowledge from prior sessions.
The key distinction: Notion is not context I push into Claude. It is context Claude pulls from Notion when it needs it. The MCP connection means Claude can search the Second Brain mid-session, find a relevant prior session log, and use it — without me having to remember that the prior session happened.
This is the layer that makes the system feel like it has long-term memory even though it doesn’t. Claude doesn’t remember. But it can look things up, and the things worth looking up are stored.
What This Looks Like In Practice
A typical session for me starts with a project context already loaded (site layer). Within thirty seconds Claude knows which site it’s working on, what voice to use, and what the current priorities are. I drop in the task layer — a GA report, a list of post IDs, a brief — and we are working within two minutes of starting.
When something important happens — a new client preference, a site credential change, a strategy decision — I say “log this to Notion” and Claude writes it to the Second Brain. I don’t maintain the second brain manually. Claude maintains it as a byproduct of doing the work.
When I need to recall something from months ago — what we decided about the internal linking structure for a specific site, what the client said about their brand voice in March — Claude searches Notion and finds it. The retrieval is imperfect but it is dramatically better than my own memory.
The Honest Constraints
This system took months to build and it is still not finished. The site knowledge files need updating when strategies change and I don’t always remember to update them. The Second Brain has gaps where sessions weren’t logged properly. The global CLAUDE.md drifts toward bloat and needs periodic pruning.
The bigger constraint is that this architecture assumes you are operating at a certain scale — multiple sites, multiple clients, recurring workflows. If you are running one site for one business, the overhead of building and maintaining this stack is probably not worth it. A well-written CLAUDE.md and a single Notion page of context will get you most of the way there.
But if you are scaling past three or four sites, or if you find yourself re-explaining the same context in every session, the stack pays for itself quickly. The ten minutes you spend building a site knowledge file saves you two minutes per session indefinitely.
The goal is not to give Claude everything. The goal is to give Claude exactly what it needs, when it needs it, at the right layer of permanence.
Building Your Own Context Stack?
Email me what you are managing and I will tell you which layers you actually need.
Most people over-engineer the global layer and under-invest in the site layer. Five minutes of conversation usually fixes it.
Twenty-eight pieces in, the system is getting very good at the briefing. It surfaces what hasn’t moved. It names the silence that has become meaningful, flags the relationship drifting toward cold, arms the escalation trigger with a date. It does all of this accurately — and the accuracy is the achievement.
And then, somewhere in the hour after the briefing, there is a temptation that the previous pieces could not fully address.
Should I draft the message first?
In most cases, yes. This series has argued consistently that the briefing exists to reduce noise, that good preparation enables rather than substitutes, that an operator who shows up to a difficult conversation knowing the facts, the history, and the emotional terrain is better positioned than one who doesn’t. All of that holds.
But there is a category of act where the draft is not preparation.
It is displacement.
What the Act Is Made Of
The apology you drafted is not an apology. It is a document about an apology.
This sounds harsher than it is. The words can be sincere. The feeling behind them can be real. The draft can be good — articulate, appropriately calibrated, warm in all the right places. And the person receiving it will feel something. But what they feel is not quite what they needed to feel, and the gap between those two things is what this piece is about.
Because what the difficult call actually communicates is not the words. It is the quality of presence behind them. The person on the other end is reading for something beneath the surface — not the content of the message but the evidence that you showed up without a net. That you accepted exposure. That you thought of them enough to call before you knew what you were going to say.
A good draft can’t give you that. It gives you something better: control. And control is exactly what the act cannot survive.
The person receiving the message — the one at the edge of the relationship, where the repair needed to happen — cannot always name what they are reading for. They may not consciously register the difference. But the relationship registers it. The contact that needed to happen at the level of presence happened instead at the level of composition, and the gap remains. Now decorated with good sentences.
The Fault Line Is Specific
This is not an argument against using the system to prepare. It is an argument about where preparation ends and contamination begins.
On one side of the line: the briefing. The context. The last date of contact and what was left unresolved. The health score and the silence trajectory. The facts, organized. The emotional terrain, mapped. All of this is good engineering. It removes the friction that has nothing to do with the difficulty of the call — the noise of not knowing the basics, the distraction of uncertainty about what happened — and it leaves you free to be present for the part that matters.
On the other side of the line: the words. The draft. The crafted opening, the structured arc, the polished close. This is where preparation crosses from reducing noise to removing the signal itself.
The signal is the property of the unrehearsed. What reaches the other party — what moves through the call and lands — is evidence that someone with skin in the game showed up with it exposed. Not managed. Not processed. Exposed.
The deeper irony: a very good draft sounds natural. Natural is the precise property that cannot be manufactured, because it is the residue of genuine presence, not of craft. The better the draft simulates natural, the more completely it substitutes for the thing it was meant to support. You have now produced a performance of the call. The other person receives a performance. They know. Not always consciously. But they know.
The Pressure-Release Problem
What the system provides, when you ask it to draft the hard message, is a pressure-release valve.
The pressure is real. The briefing surfaced something that needs to move. The operator’s nervous system knows it. There is a genuine desire to do something about it. Requesting a draft from the system feels like a move toward the thing. It produces a deliverable.
But the deliverable is a substitute. The pressure releases without the contact happening. The operator has moved around the hard thing while carrying the artifact of having moved toward it. The gap — the relationship that needed a phone call — is still there. Now it has a draft parked next to it.
This is what “work where doing is the point” looks like in the residual queue. Not the obvious cases — the scheduling, the summarizing, the research. The dangerous case is when the intelligence layer has correctly identified that a specific person needs a specific kind of presence from the operator, and the operator, rather than providing that presence, asks the system to approximate it.
The system can approximate almost everything about the conversation except the part that makes it a conversation rather than a performance.
Article 9 in this series argued that AI cannot have skin in the game — that judgment and relationships are the durable human advantages. What this piece is adding is the specific failure mode: not just that the AI lacks skin in the game, but that asking the AI to draft the act allows the human to lack it too, while appearing not to. It is a way of having skin in the game while keeping it covered. The brief exposure of authoring the draft, followed by the transmission of the draft, produces the sensation of having done the hard thing. The hard thing is still undone.
Where to Draw the Line
Everything up to the words is good engineering.
Know the context. Know the history. Know what the relationship has cost and what it is worth. Let the briefing do its job fully — the facts, the silence trajectory, the emotional background. Arrive prepared in every way except one, and be deliberately unprepared in that one. Not as an oversight. As a discipline.
The words are yours. Not because the system couldn’t generate better ones — it probably could — but because the words being yours is part of what is being communicated. The exposure is the content. The willingness to say something that might land badly, to be present without a script, to show up as someone who thought about this enough to call before they knew what they were going to say — that is the act the briefing was built to make possible.
Not to replace.
The system is very good at preparing you for the call. The test of whether you understand what it built is whether you put down the draft at the moment the call actually begins.
There is a seam between the briefing and the act. Most of the work in the residual queue lives there. The briefing ends. The act starts. These are adjacent and distinct, and mistaking one for the other — using the scaffolding all the way up to and through the moment of contact — is the specific way a very capable system teaches a very capable operator to be slightly less present than they were before they built it.
The call is available in the hour after the briefing, before the draft. It will not wait indefinitely for a better version of itself to be prepared.
Update — May 15, 2026: Two things have shifted since this article was originally written. First, Claude Opus 4.7 (released April 2026) is now Anthropic’s most capable model with a 1M token context window at standard pricing — which changes the calculus for any task involving large documents or long-form reasoning, where Claude was already the stronger choice. Second, on May 13, 2026, Notion shipped the Notion Developer Platform with Claude as a launch partner, which means the comparison is no longer just “Notion AI vs Claude Projects” — Claude can now operate natively inside Notion via the External Agents API. For the platform launch breakdown, see Notion Developer Platform Launch (May 13, 2026). For the current Claude model lineup, see Claude Models Roadmap May 2026. For how this fits into a working stack, see The Three-Legged Stack.
The 60-second version
Notion AI and Claude Projects both let you bring custom context to AI. The difference is what surrounds the AI. Notion AI lives inside a workspace with databases, integrations, schedules, and a team. Claude Projects lives inside a conversation with files, instructions, and the conversation history. For ongoing operational work where the AI needs to be part of how you work, Notion AI fits. For deep focused work where conversation quality is the primary value, Claude Projects fits. Many operators use both.
When Notion AI wins
When Notion AI wins.
Persistent operational context across the workspace
Custom Agents on schedules
Database fluency and Autofill
Native integrations (Slack, Mail, Calendar)
Team collaboration patterns
Mobile and cross-device access
When Claude Projects wins
When Claude Projects wins.
Deep, focused task work
Strong conversation continuity within a topic
Specific instruction sets per project
File-heavy reference contexts (code, research, large documents)
When conversation quality (Claude’s strength) matters more than integration
The stacking pattern
The stacking pattern.
The pattern many operators use:
– Notion AI for the ongoing rhythm of work — agents, databases, daily operational synthesis
– Claude Projects for “I need to deeply work on X” sessions — heavy reasoning, complex code, large reference contexts
The two don’t conflict; they cover different time horizons. Notion AI is always-on background. Claude Projects is intentional focused sessions.
What Claude Projects does that Notion AI doesn’t
File upload context with longer effective memory in-conversation
More flexible custom instructions per project
Conversation continuity that’s purely Claude-native (no model-switching)
What Notion AI does that Claude Projects doesn’t
Workspace databases and Autofill
Scheduled agent execution
Native integrations beyond conversation
Multi-user collaboration on the same context
Where comparisons go wrong
1. Treating them as direct substitutes. They overlap but serve different shapes of work. 2. Picking based on raw conversation quality alone. That favors Claude. But conversation quality isn’t the whole product. 3. Picking based on integration breadth alone. That favors Notion. But integration matters more for some workflows than others.
What to read next
Notion AI vs ChatGPT, Notion AI vs Gemini, Editorial Surface Area, Custom Agents vs Basic.
Yesterday’s piece argued that detection has gotten cheap and the residual job is action — phone-call courage, first-sentence courage, the willingness to do the awkward small things the system has already pre-decided are correct. That argument has a shadow. Not every move the briefing flags is a move that should be made.
The briefing today reports clean. No urgent action. Owner-level work, not triage. The temptation, after twenty-seven essays arguing for the discipline of action, is to read this as the absence of work. It is not. It is the harder kind of work, dressed in the same neutral grey as all the others.
There is a case for principled non-response, and it is structurally distinct from avoidance, and almost nobody can tell them apart from the outside.
The two states look identical from a distance
An operator who refuses to make a flagged move out of judgment, and an operator who refuses to make a flagged move out of fear, produce the same observable artifact: nothing. The flag stays flagged. The downstream consequence does or does not materialize. The dashboard does not change color.
From inside, the difference is total. One state is occupied by a specific predicate — this move is wrong because of this — that the operator can articulate, defend, and revisit. The other state is a hollow whose only feature is that nothing is in it.
The trouble is that hollows mimic positions. Avoidance learns to talk like principle, because the costume requires only sentences and there is no enforcement beyond the operator’s own honesty.
What a principled refusal needs to be
If non-response is going to function as a real position rather than as drift in formal wear, it has to take on the same shape that capture and commitment took on once they were treated seriously: specific, dated, reviewable.
Specific: the refusal attaches to a particular flag, a particular ask, a particular pre-decided move. Not a posture. The flag is named. The move is named. The decline is named.
Dated: the refusal exists at a moment in time, on a calendar. This is the discipline that prevents an operator from re-narrating their inaction as deliberation after the fact. The decline has to be put down before the absence becomes load-bearing — otherwise the naming feels like revisionism rather than accounting.
Reviewable: a refusal that cannot be read by another operator — including a future version of the same operator — is not a position. It is a memory event. Positions survive the person who took them. Memory events do not.
The system can flag; only the operator can refuse
The asymmetry in the prior piece — the system can detect but cannot text the relationship — has a parallel here. The system can mark a move correct. It has no standing to refuse it. Refusal is by definition the introduction of a consideration the system was not built to weigh: a context only the operator holds, a relationship value that does not register in the ranking, a category of action that should not be taken even when it would clearly produce a result.
This is one of the few places where the loop genuinely stops being symmetric. The operator can override the system in either direction — by acting on something the system did not flag, or by declining something the system did. The system can only ask in one direction.
The pheromone risk on this side too
Earlier work named the danger of mistaking the workspace for the work — capture without commitment, columns that look like portfolios but read as debt. Refusal has its own version. Make decline a first-class object in the system, and within a few cycles you will find a fresh lane of activity, well-formatted, full of well-articulated reasons not to do things, that produce no shipped result and absorb no real cost.
The signal that distinguishes the working refusal from the procedural one is small and almost private: the operator can say what would change their mind. A principled non-response carries an implicit re-entry condition. Avoidance has none — its purpose is to never have to revisit the question.
What the briefing cannot tell you
The system cannot tell the operator which of today’s quiet is the kind that earns rest, and which is the kind hiding the question that was not built into the surface. The operator cannot delegate this discernment without re-creating the very opacity the honest dashboard was supposed to remove.
Twenty-seven essays in, two complementary disciplines have surfaced. The first is the residual courage to act on the awkward thing the system has named — the move only the operator can make. The second is the harder cousin: the courage to leave a marked flag standing, with a date, with a reason, with the posture of someone who can be held to a refusal.
Acting against an inertial system is dramatic. Refusing well, inside a system designed to flag every available move, is not. It looks like nothing. Most days, that is what it has to look like.
The thing left open
The remaining question is whether refusal, once made first-class, becomes another surface to groom. Whether a workspace can hold a list of decisions-not-to-act without that list quietly becoming the next pheromone — a portfolio of dignified inaction that performs the same function the busy workspace used to perform, just in a different chord.
The honest answer is that the discipline of decline cannot be solved at the level of the surface. The operator either has the predicate or they do not, and the surface is downstream of that. What is worth watching is whether the system, asked to surface what was declined and why, can generate the kind of friction a good editor generates — re-asking, two weeks later, whether the predicate still holds. Not as enforcement. As a partner in a discipline neither side can carry alone.
There is a failure mode that only appears after you fix the pheromone problem.
Once the workspace stops lying — once the dashboards stop emitting the chemical signal of progress and start reporting what is actually happening — a new gap opens. The system tells you, accurately, what needs to move. The system flags the silences that are now meaningful. The system arms the escalation triggers and surfaces the relationships drifting toward cold. And then nothing happens, because none of those reports are themselves the move.
The honest dashboard does not write the text message. It only knows that the text message should have been sent two days ago.
This is the residue left behind once detection gets cheap. For most of the last two decades, the bottleneck on operating a complicated working life was knowing what was going on. People built tools to compress that gap, and the tools got very good. There are now systems that will scan a relationship’s last seven touches, score the warmth, surface the silence, recommend the channel, draft the message, and slide all of it into a daily briefing the operator can read with coffee.
What none of those systems can do is the small, expensive thing the briefing was built to invite — pick up the phone, type the awkward sentence, force the conversation that has been politely deferred. That move costs almost nothing in time and almost everything in nerve. It does not get cheaper as the surrounding system gets smarter. If anything it gets more expensive, because once the system has named the move, declining to make it stops being negligence and becomes a decision.
The earlier articles in this series were mostly about what the system can take off the operator’s plate — capture, memory, voice, finishing, the discipline of not multi-threading. There has been a quiet implication running underneath them that as the system gets better, the operator gets to think bigger thoughts. That is partly true. The other part — the part that has not yet been said in this series — is that the more competent the system becomes, the smaller and more concentrated the residual human acts get. They do not disappear. They become unmissable. The job changes shape, and what is left in the operator’s hands is the part that could never be delegated in the first place: the conversations whose value comes from the fact that a specific person, with skin and stakes and a name, chose to have them.
Detection is delegable. Action against the awkward thing is not. And as the surrounding system gets faster, the operator’s residual queue gets sharper, because every soft excuse — I didn’t notice, I wasn’t sure if it mattered, I was going to get to it — has been quietly disqualified in advance. The briefing noticed. The briefing was sure. The briefing got to it. So the only remaining question is whether the operator will.
What this exposes is that the bottleneck moved without anyone announcing the move.
For years the bottleneck was visibility. Then for a while it was capacity. Now, in any operator’s world that has built up a real intelligence layer, the bottleneck is courage in a very specific and unromantic sense: the willingness to do the small uncomfortable things the system has already pre-decided are correct. Not heroic courage. Phone-call courage. First-sentence courage. The kind of courage that produces no story afterward because all that happened was a five-minute conversation that should have happened three days earlier.
This is not a moral observation. It is a structural one. A system whose detection layer outruns its action layer accumulates a particular kind of debt — the debt of known, named, surfaced moves that have been declined. That debt is worse than the old debt of unknown work, because unknown work could be excused. Known work that did not move is a posture toward your own life. Over time it congeals into a self-image — operator who saw the right move and did not make it — and that self-image is corrosive in a way that opacity never was.
The honest reckoning is that an intelligence layer changes the contract the operator has with themselves. Before, the operator could be a person who tried hard inside the limits of what they could see. After, the operator is a person who chose, on a date, with the briefing in front of them, what to act on and what to leave. Both versions can be defensible. Only one of them is the same person.
This is not an argument against the system. The system is doing exactly what it was built to do, which is reveal. The argument is that revelation is the easier half of the contract. The hidden half — the half that does not get celebrated in any product demo — is the operator’s quiet daily decision to be the kind of agent the briefing assumes them to be. Every flagged silence is a small invitation to either confirm that assumption or quietly retire it. There is no neutral position. Inaction in the presence of a clear flag is itself a position; it just is not one anyone wants to claim out loud.
What the system is asking of the operator at this stage is unflattering. It is asking them to be braver than the system, in the specific narrow band where bravery still matters. Not to outwork it. Not to outthink it. To make, by hand, the moves the system can name but cannot make.
For the operator, this is good news in a way that is hard to feel. The work that is left is the work that was always the most worth doing — the part with relational stakes, the part where two specific people negotiate something between them, the part that does not scale and never will. Everything else — the noticing, the cataloguing, the prompting, the formatting, the synthesizing — has been quietly absorbed into infrastructure. What remains is the conversation. What remains is the ask. What remains is the willingness to send a message whose response cannot be predicted.
That is not a smaller job. It is a more honest one. And it is the one job the system was always going to hand back, because no system that ever gets built can take it.
The series has been arguing for a long time that intelligence compounds and the operator’s posture has to keep up. The next move in that argument is uncomfortable. Posture is no longer the issue. The system is mature enough now that the open question is no longer whether the operator can think at the right altitude. The open question is whether the operator can act at the right scale of intimacy — whether, in the hour after the briefing arrives, they can do the one thing it cannot do for them.
That hour is the new bottleneck. It is also the place where the actual life is.
Your GA4 engagement rate is one number. But it is not one audience. It is three audiences — and they behave so differently from each other that the aggregate number actively misleads you about how your content is performing.
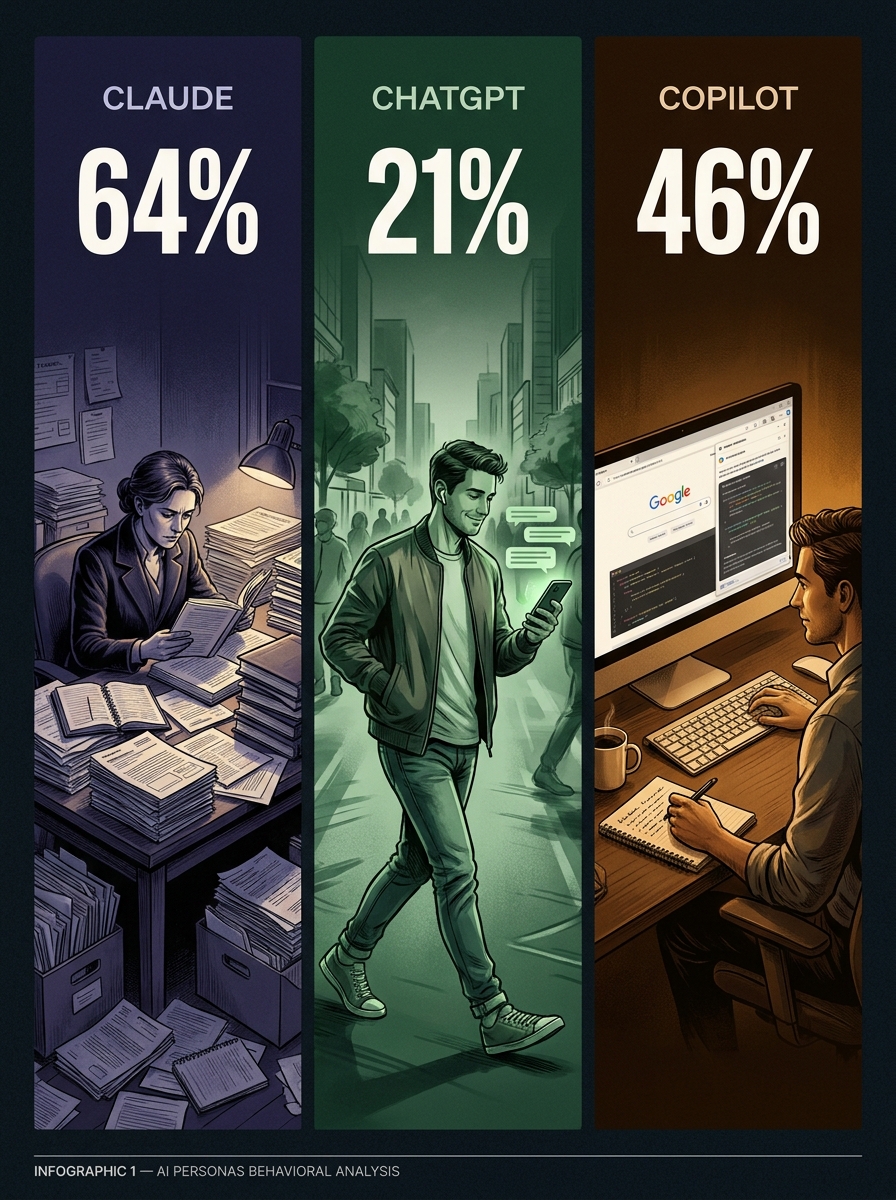
Here is what most GA4 users see: a site-wide engagement rate of 35%, an average session duration of 90 seconds, and a top channel list led by Organic Search. What most GA4 users miss: within that same 35% number, three AI platforms are sending traffic with engagement rates of 21%, 46%, and 64% respectively — from the exact same pages, to users with completely different intent profiles.
The AI Referral Split Nobody Is Looking At
The AI referral split nobody is looking at.
ChatGPT, Claude, and Copilot all send referral traffic to content sites. But they do not send the same user. ChatGPT users arrive, scan for a quick answer, and leave in under 30 seconds — engagement rate around 21%, well below the organic search average. Claude users arrive with research intent, read deeply, and stay for 3-4 minutes — engagement rate above 64%. Copilot users are somewhere between, arriving in planning mode, spending 1-2 minutes on civic and services content.
If you blend these three into your site-wide engagement rate, you get a number that does not represent any of your actual users. You get a mathematical average of behaviors that have nothing in common.
Why Your Engagement Rate Lies
Why your engagement rate lies.
The problem is not your content. The problem is that engagement rate without source segmentation is noise. A 35% site-wide engagement rate could mean you have excellent content reaching the wrong distribution channels. It could mean you have mediocre content propped up by one high-engagement source. It could mean your AI referral traffic is dramatically outperforming your social traffic and you have no idea.
The only way to know which is true is to break the number open by source and look at what each channel is actually delivering in terms of engaged session quality — not just volume.
The Four-Question Audit
The four-question audit.
Before you make any content or distribution decisions based on your GA4 engagement rate, ask these four questions.
Which channel sends the most engaged users — not the most users? The answer is almost never the channel driving the highest session count. In most content sites we have audited, the highest-engagement channel is sending between 8 and 40 sessions per month, not 400.
What is the engagement rate for each AI referral source individually? Blending ChatGPT and Claude traffic treats them as equivalent. They are not. One is a fact-checking audience. The other is a research audience. The content structure that serves one actively fails the other.
Which pages produce satisfied exits versus abandoned exits? A 90% exit rate with a 3-minute duration is a success. A 90% exit rate with a 4-second duration is a dead end. Engagement rate alone does not tell you which you have.
Is your engagement rate rising or falling week-over-week from AI sources? AI referral traffic is growing on most content sites in 2026. If yours is flat or declining, you are losing ground in a channel that is becoming structurally important.
What This Reveals About Your Real Audience
When you segment your GA4 engagement rate by source and run the AI referral breakdown specifically, a picture emerges that the aggregate number completely hides. Your real audience — the people actually reading and acting on your content — is smaller and more specific than your total traffic suggests. It is concentrated in a few sources, a few content types, and in the case of Claude traffic specifically, a few geographic clusters that reflect the academic and professional demographics of that user base.
This is not a problem. It is a targeting signal. It tells you where to invest content development effort and which audience to write for on every new piece.
The Methodology Behind This Analysis
The behavioral profiles in this article come from five live sessions using Claude-in-Chrome to interrogate Google’s Analytics Advisor inside GA4 on a real property. The query architecture — the specific sequence of questions and the capture protocol — is packaged as the Books for Bots: GA4 AI Referral Audit Kit.
It runs in four sessions, requires no SQL, no BigQuery access, and no data analyst. You need Claude-in-Chrome, Editor access to a GA4 property with Analytics Advisor enabled, and approximately 90 minutes. The output is a complete per-AI behavioral profile of your traffic and a content variant framework for acting on it.
The complete 4-session Claude-in-Chrome methodology for extracting per-AI audience intelligence from Google Analytics 4 — and turning it into content every AI model cites.
64% vs 21% Claude.ai engagement rate vs ChatGPT — same site, same pages
COMING SOON — $27
CORE FINDING
AI citations are downstream of search quality, not upstream. Pages that win Bing and Yahoo with long-form depth get cited by AI models as a derivative effect.
What’s Inside
Full 4-session query architecture — 26 queries, copy-paste ready
Pre-flight checklist and capture protocol for each session
AI citations are downstream of search quality — not upstream. The path to getting cited by ChatGPT, Claude, and Copilot is not to optimize for AI retrieval patterns. It is to build pages that win on Bing and Yahoo with enough depth that AI models treat them as authoritative sources.
Individual Kit — Instant PDF Download
COMING SOON — $27
No subscription. One-time purchase.
BETTER VALUE
Get All 6 Kits for $97
The complete Books for Bots library. Every GA4 intelligence methodology in one purchase.
For the past several weeks I have been running a live experiment on helpnewyork.com: using Claude-in-Chrome to interrogate Google’s Analytics Advisor inside GA4, session by session, until I had a complete behavioral profile of every AI platform sending traffic to the site.
What came out of it is not what I expected. I expected traffic data. I got a content strategy.
The Setup
The setup for tracking AI referral traffic.
Claude-in-Chrome is Anthropic’s browser extension that lets Claude operate directly inside your browser — reading pages, clicking elements, filling inputs, capturing output. Analytics Advisor is Google’s Gemini-powered chat interface built into GA4, available to English-language accounts since December 2025. It answers natural language questions about your property data with charts, tables, and narrative interpretation.
The combination is unusual. You are using one AI (Claude) to systematically interrogate another AI (Gemini) about your site’s data, then synthesizing what comes back into strategy. The token budget for the heavy data reasoning stays inside Google’s infrastructure. Claude handles the query architecture, the capture protocol, and the synthesis.
I ran four structured sessions across two sittings, using a specific sequence of queries built to extract progressively deeper signal. Session 1 established baseline traffic. Session 2 closed gaps and confirmed AI referral data existed. Session 3 was the AI deep dive. Session 4 was velocity and geography.
What the Data Showed
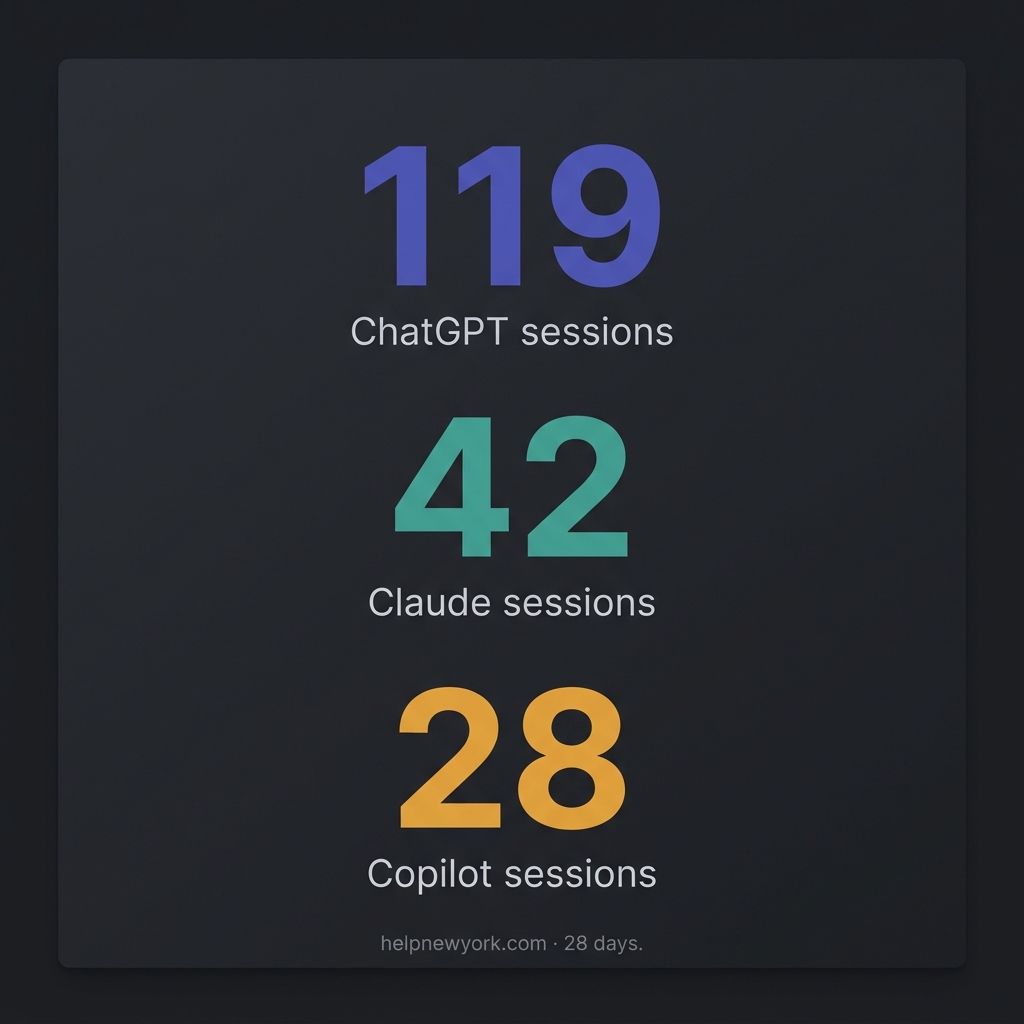
Three AI platforms were sending meaningful traffic to helpnewyork.com during the 28-day window: ChatGPT, Claude, and Copilot. The behavioral profiles were so different from each other that treating them as a single “AI traffic” segment would have produced wrong conclusions.
Claude.ai traffic showed a 64% engagement rate and an average session duration of over 3 minutes. The dominant landing page was an NYC Summer Internships guide, accounting for over 60% of all Claude sessions. Geographic concentration was academic: Ithaca (Cornell), State College (Penn State), Washington DC. The users arriving from Claude were reading to act — they needed specific information, they found it, they stayed.
ChatGPT traffic showed a 21% engagement rate and an average session of 24 seconds. The top landing page was a cherry blossom guide. The users were fact-grabbing: they asked ChatGPT where to see cherry blossoms in New York, got a citation, clicked through, confirmed the location, and left. The content served its purpose in under half a minute.
Copilot traffic was between the two: 46% engagement, roughly 2-minute sessions, desktop-heavy, concentrated in New York’s suburbs. The top pages were civic services — SNAP benefits, tenant rights, transit discounts. These users were in planning mode, researching before they decided or applied.
The Finding That Reframes GEO
The finding that reframes GEO.
The cross-AI page overlap query was the most important one in the entire four-session arc. I asked Analytics Advisor which pages appeared in the top landing pages for more than one AI source. Only one real content page appeared in all three: the cherry blossom guide.
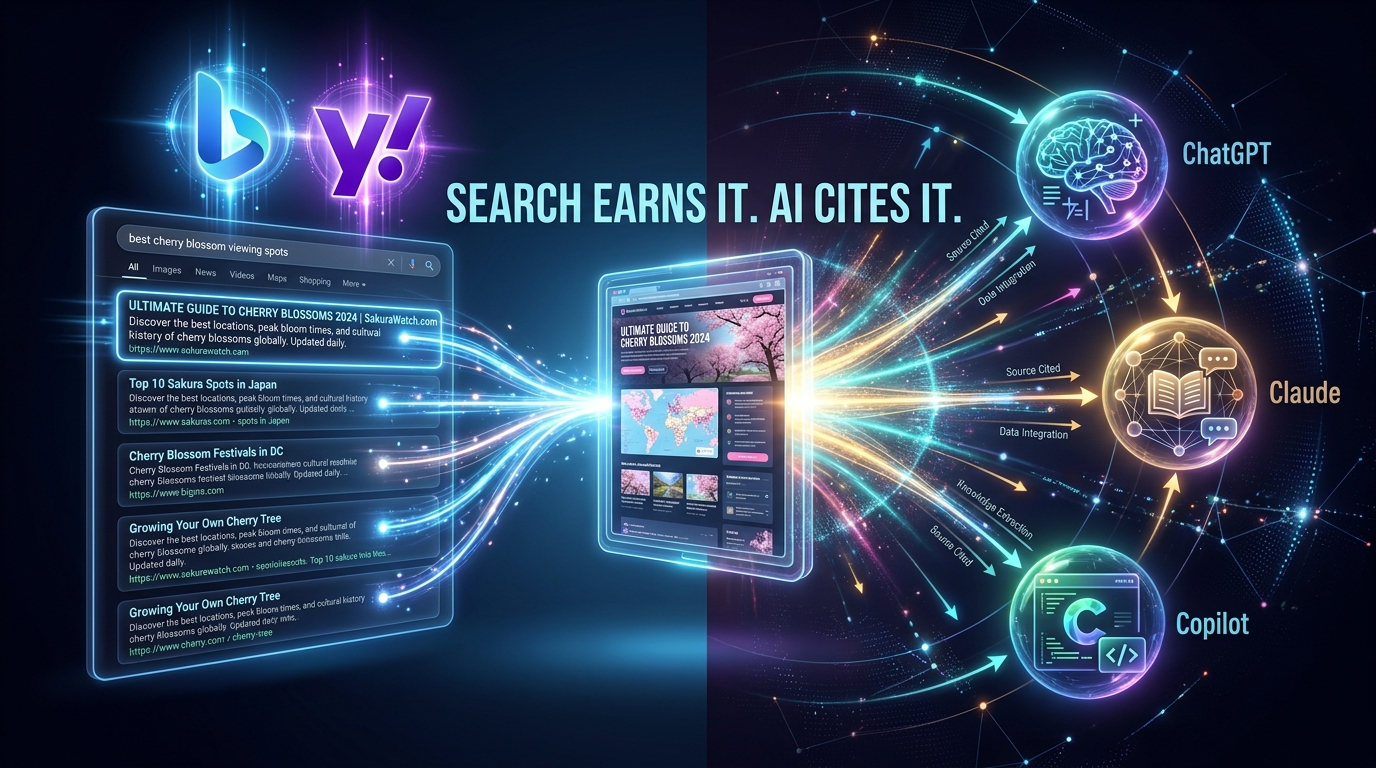
The obvious interpretation is that the cherry blossom guide was “AI-optimized.” The actual interpretation, once you look at the full traffic breakdown, is the opposite. Bing drove 59 sessions to that page. Yahoo drove 16 at 75% engagement and a 3-minute 46-second average session. DuckDuckGo drove 35. The combined AI traffic to that page was 32 sessions — 17% of total. The AI platforms were citing it because traditional search engines had already validated it as the highest-quality answer in the index.
AI citations are downstream of search quality, not upstream. The path to getting cited by ChatGPT, Claude, and Copilot is not to optimize for AI retrieval patterns. It is to build pages that win on Bing and Yahoo with enough depth that AI models treat them as authoritative sources. The GEO play is a traditional SEO play with better content.
The Content Strategy That Follows
The content strategy that follows.
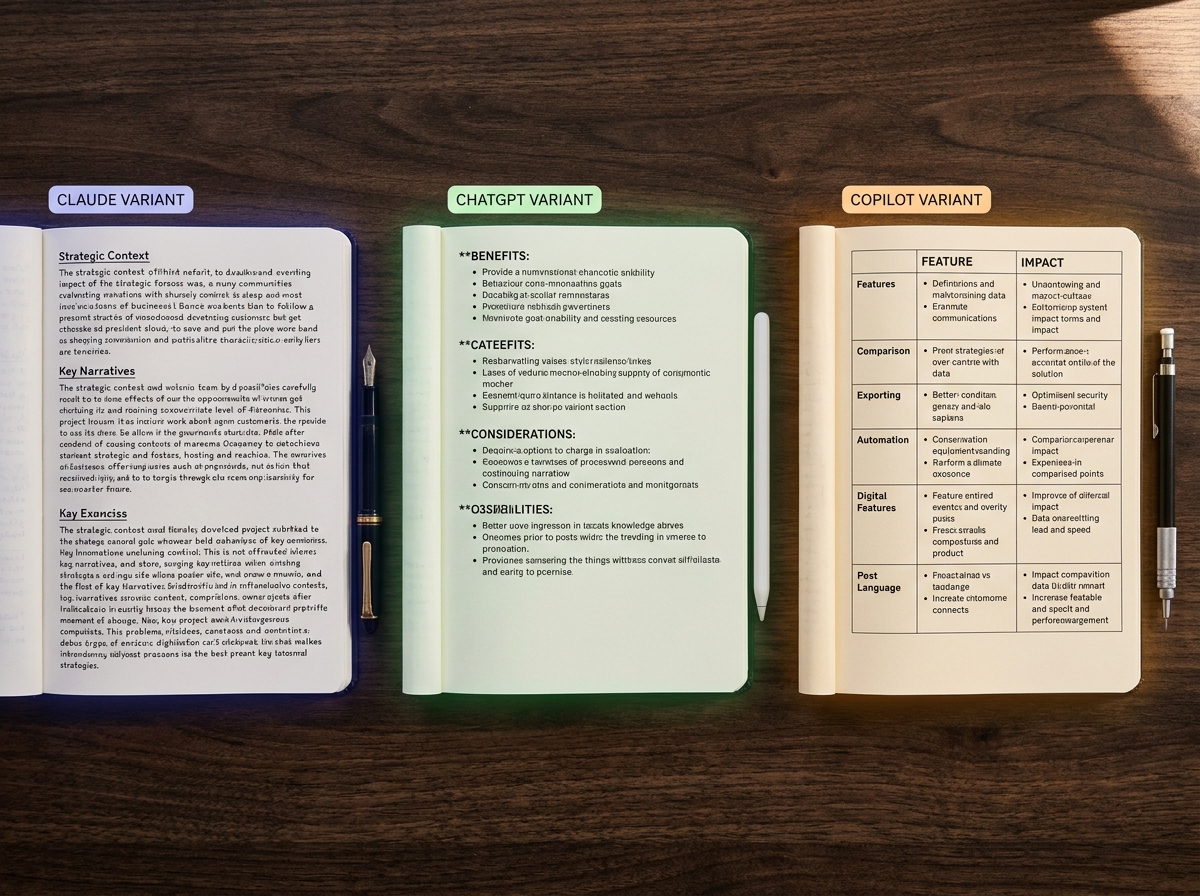
Once you have the per-AI behavioral profiles, you have a content variant framework. The same article can be written in three structural architectures, each tuned to how one AI model retrieves and presents information.
The Claude variant is dense and process-oriented. Headers, eligibility criteria, numbered steps, official program names. Built for the student or researcher who arrived with a specific question and needs a complete answer they can act on.
The ChatGPT variant is a scannable list. Named items, one specific detail per item, direct answer in the first two sentences. Built for the user who will spend 24 seconds on the page and needs the answer immediately or they’re gone.
The Copilot variant is comparison and planning framing. What to know before you go, Option A versus Option B, cost context, logistics. Built for the desktop user doing research before they make a decision.
The core article is the same. The architecture is different. The AI that cites you depends on which structure you used.
The Methodology Is the Product
The query sequence I developed across these four sessions is a repeatable extraction methodology. It works on any GA4 property with Analytics Advisor enabled. The intelligence it produces — per-AI audience profiles, geographic signals, velocity trends, cross-AI content overlap — is not available through DataForSEO, SpyFu, or GSC. It requires Gemini’s reasoning layer operating on top of your property data, orchestrated by a structured query architecture.
I have packaged the complete methodology as a downloadable kit: the full query architecture across all four sessions, the capture protocol, the content variant framework, and the flags to escalate before your next content sprint. It is called Books for Bots: GA4 AI Referral Audit Kit.
The free version covers Session 3 alone — the AI deep dive queries that surface your ChatGPT, Claude, and Copilot traffic split. That alone will show you something most site owners have never seen: which AI is sending them traffic, to which pages, and how engaged those users actually are.
The full kit covers all four sessions and includes the content variant framework that translates the behavioral data into a writing system.
Both are available at tygartmedia.com. What you do with the data after that is yours.