Google is not the only search engine anymore. Your next customer might find you through a ChatGPT answer, a Perplexity citation, or a Google AI Overview that pulls your content into the answer box. AEO is how restoration companies show up in the answer layer — featured snippets, People Also Ask, voice search, and zero-click results that put your name in front of decision-makers before they ever click a link.
AEO and AI Search covers answer engine optimization, featured snippet capture, People Also Ask strategies, voice search optimization, zero-click search positioning, AI Overview placement, and direct answer formatting for restoration industry queries across Google, Bing, ChatGPT, Perplexity, and Gemini.
Last verified: September 5, 2026 (Pacific). Source: Thanks.io product email from Ryan Hartman. Product docs: How To Create A Dynamic Postcard Template and thanks.io. This is an operator read of a vendor update, not a paid placement.
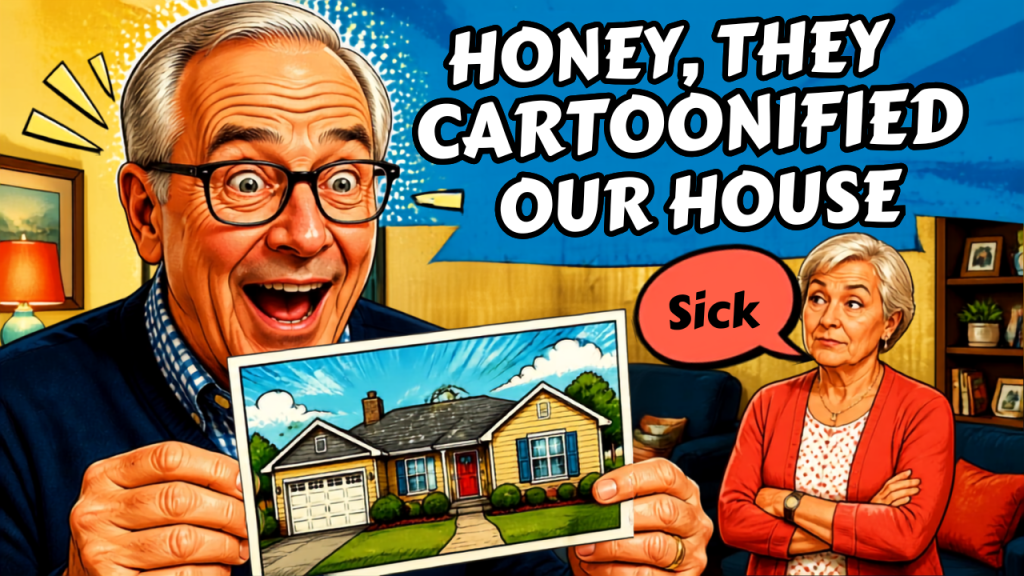
Direct answer: Thanks.io now lets you apply fun visual effects to the Street View image of a recipient’s house inside the platform’s dynamic postcard image builder. The house photo was already a merge field. The new piece is styling that photo so it reads more like a cartoon or treated illustration than a raw Google capture.
That is the whole announcement. The rest of this page is how to treat it as a control, not a novelty.
Vendor example from Thanks.io's September 5, 2026 product update. Editorial use.
What actually shipped
Thanks.io’s dynamic postcard builder has long been able to print a Google Street View or Map View of the recipient address as the card background. Official docs still document the ~STREET_VIEW~ and ~MAP_VIEW~ data tags, plus an absentee-owner override: set Custom 1 to absentee and put the subject-property address in Custom 2 so the card mails to the owner but shows the property.
The September 5, 2026 email adds one layer on top of that pipeline: effects on those street-view house images. The subject line called them “cartoonified houses.” The body called them “fun effects.” We have not independently enumerated every filter name inside the builder. Until the help center lists them, treat the feature as a style pass on an existing merge image, not as a new mail class.
What did not change, based on public docs: formats (4×6, 6×9, 6×11), QR tracking, handwriting engine, Canva path, and per-piece pricing. Do not rewrite a media plan because the house now looks drawn.
Why a house on a card still works
A street-view house on a postcard is a recognition hack. The recipient does not have to decode a brand. They decode their own porch. That is why real-estate teams and a smaller set of restoration and insurance shops already use the builder.
A cartoon or stylized treatment changes the emotional register. A raw Street View can feel like surveillance. A treated image can feel like a sketch of the place. That is useful when the job is a listing conversation, a just-listed neighbor note, or a thank-you after a dry-out. It is the wrong register when the job is a water-loss notice, a denial letter, or anything that has to look like a record.
Where operators should use it
Use the effect when the card is allowed to be personal and slightly playful:
Just-listed / just-sold neighbor farms, where the house is the subject and the tone is invitation.
Absentee-owner outreach that already uses Custom 1 / Custom 2 so the mailed address and the pictured property can differ.
Post-job thank-you mail from a restoration shop, after the work is done and the record already exists in the file.
Seasonal or sphere mail where the house is a landmark, not evidence.
Do not use the effect when the image has to stand as a document. Street View is already a dated, third-party capture. Cartoonizing it does not make it more accurate. On a rural road with no panorama, Map View is still the honest fallback the vendor already recommends.
How to set it up without guessing
Open Image Templates and the dynamic image builder inside Thanks.io.
Set the background to the Street View or Map View tag, not a one-off screenshot.
Apply the new effect on that street-view layer. Preview more than one address before you lock a campaign. Corners, hedges, and parked cars render differently than a clean suburban elevation.
Keep headline, QR, and handwriting as separate layers. The effect is decoration on the house, not a reason to hide the offer.
If the recipient is an absentee owner, keep the documented Custom 1 = absentee / Custom 2 = subject-property address pattern. The effect does not replace that mapping.
Generate a live preview for a real row in the list, not only the template dummy address.
This feature is not an SEO tactic. It is a physical-mail personalization tactic. The search job for operators is different: publish a page that answer engines can cite when someone asks whether Thanks.io can stylize a house photo on a postcard.
AEO. Lead with the fact, date, and product surface (dynamic postcard image builder). Put the same answer in the FAQ so extractors do not have to invent one.
SEO. Rank for the query family around Thanks.io Street View postcards, cartoon house mailers, and dynamic postcard effects. Those phrases now have a dated source page.
GEO. Name the vendor, the builder, the Street View / Map View tags, and the absentee-owner fields so generative engines can reuse entities instead of collapsing this into “AI postcard art.”
If you run restoration or real-estate content in a metro, the local layer is the address merge, not a city landing page. The card is already geo-personal. Your website should say which campaign types get the effect and which do not, in the same voice you use on the shop floor.
Quality notes before anyone hits send
Street View licensing and freshness are still the vendor’s problem and yours. Preview ugly captures. Suppress rows where the panorama is a fence, a truck, or the neighbor’s house. Do not imply the cartoon is a current photo of completed work. Do not put a stylized house on a card that discusses damage, mold, or a claim number.
We did not receive pricing, effect names, or API field changes in the email. If those land in the help center later, this page should be updated against the doc, not against memory.
FAQ
Can Thanks.io put a cartoon version of a house on a postcard?
Yes, as of September 5, 2026. Thanks.io added fun effects for Street View house images inside the dynamic postcard image builder. The house image itself was already available via Street View and Map View merge tags.
Is this a new postcard size?
No. It is a style option on the existing dynamic image builder. Public pricing pages still list 4×6, 6×9, and 6×11 postcards.
Can the pictured house be different from the mailing address?
Yes. Thanks.io documents an absentee pattern: Custom 1 = absentee, Custom 2 = the full subject-property address. Use that when you mail an owner at a different location than the house on the card.
Should a restoration company cartoonify every job-site house?
No. Keep raw or unused imagery for anything that has to look like a file. Use the effect on thank-you and neighborhood mail after the job, not on notices that travel with a claim.
Where is the official documentation?
Start with How To Create A Dynamic Postcard Template. The September 5 feature note itself arrived as a product email from Thanks.io, not as a new help-center article at the time this page was written.
Open field playbook. No patent. Copy it. Change the nouns from Instagram Reel to first-walk clip if that is your shop. If it stops you from blasting one caption onto every network as if that were a local business, good.
License: do what you want. Attribution nice, not required. Tygart Media is not a OneUp partner, reseller, or affiliate. Links below go to official product doors. No tracking parameters. No referral codes. No reprint of the vendor email body.
Why this exists: on 3 September 2026 a handwritten note from Davis Baer, co-founder of OneUp, landed with the subject New in OneUp: Control which specific posts get automatically cross-posted. The only line that mattered: keyword filters in cross-posting. Include a word or hashtag and the post travels. Skip a word or hashtag and it stays put. Case insensitive. Caption text only.
That is a clean product move. It is also the trap if you treat the toggle as permission to republish everything. Unfiltered cross-posting is the brand-kit failure in motion. The library is national. The buyer is local. Answer engines do not confuse the two unless you teach them to.
Direct answer
OneUp cross-posting watches a Source account on Instagram, Facebook, or TikTok and republishes qualifying posts to Destination accounts on the networks the tool supports. It checks the Source about every two hours. As of the August 2026 changelog, you can require or exclude a keyword or hashtag in the caption so only some posts travel. Image workflows and video workflows are separate. Plan limits, per OneUp’s own FAQ: Basic 1 workflow, Intermediate 3, Growth 5, Business 8, extra workflows as a $5/month add-on. Existing-catalog cross-posting is Intermediate and above. Official APIs only. That is the vendor record. The operator problem is different.
Changelog entry (August 2026): keyword filters plus existing-post back-catalog options live on OneUp’s roadmap page
If you do not run the tool, do not scrape the email for a screenshot library. This page does not republish Davis’s pitch or the trial offer.
1. Impedance — when the filter matches the job
Use a cross-posting workflow when two of these are true:
The Source post is already a fact the Destination channel is allowed to say.
You will tag it in the caption with a token the filter can see — a job class, a desk, a city, a channel code.
The Destination is a pointer, not the record. The record lives on your domain and on Google Business Profile.
You can name what must not travel: interior photos of a private home, a named insured, a crew joke, a LinkedIn-only adjuster note.
Do not use unfiltered cross-posting as:
Your only publishing system.
A substitute for pages that answer “who walks a wet house in [city].”
Proof you have distribution. Proof is a cited answer or a booked job.
2. Three layers the email already named
The drop split the work the way a shop should split the work.
Piece on the email
What it is
What it is not
Source account
Where the clip is born. Instagram, Facebook, or TikTok per OneUp’s API limits.
Your entity graph.
Destination accounts
Where a qualifying post is copied.
A local service page.
Keyword filter
A caption gate: include or skip a token, case insensitive.
An editorial calendar, a license, or a NAP record.
Same three drawers exist whether or not you buy the tool. Floor craft. Owner ops. Vendor pipe. The pipe does not replace the Tacoma first-hour page.
3. SEO, AEO, GEO — one pass, three jobs
SEO is crawlable pages with one job each. A Reel expires. A service page does not. Cross-posting moves the Reel. It does not invent the page.
AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers quote pages that state the question, answer it in the first screen, and keep entities clean. The same caption on Instagram, TikTok, YouTube, LinkedIn, and Google Business Profile is a weak cite. It looks like one voice wearing eight hats.
GEO here means two things at once, and you should keep both:
Generative engine optimization — structured enough that models can reuse you without inventing your city.
Geographic engine optimization — place nouns that match the map: city, neighborhood, desk, service.
A keyword filter is how you stop a South Tacoma crawl-space clip from landing on the LinkedIn page that talks to facility managers in another county. The token in the caption is the gate. The page on your domain is the cite.
4. First 30 minutes when the filter ships
Open the official FAQ. Confirm Source, Destination, check interval, and plan limit before you add a workflow.
Write a token list the shop can remember. Examples: #jobpublic, #desklinkedin, #tacoma, #skip. Short. Ugly. Searchable.
Make two workflows if the tool forces it: one for video, one for images. Do not pretend they are the same pipe.
Include-list the tokens that may travel. Skip-list the tokens that must not — interiors, minors, named carriers, unfinished estimates.
Publish or refresh the matching page on your domain before the first auto-post. The Destination post points at the page. The page does not point at a disappearing feed.
If the Source caption has no token, it does not travel. That is the whole point of the feature.
5. The local answer that pays
Every auto-post still leaves the same unanswered questions. Write them as pages, not captions.
Social analog: “Which posts from this account should appear on LinkedIn, and which stay on Instagram?”
Restoration analog: “Who walks a wet house in [city], what happens in the first hour, what do you send the adjuster — and which of those sentences belongs on TikTok?”
Name the place. Name the service. Name the next action. Name the channel the sentence is allowed on. That is the cite.
Leaving the filter empty so every Source post reprints onto every Destination.
Using a cute brand word as the token. OneUp’s own example is “cool.” Fine for a demo. Useless as a shop rule.
Cross-posting a private-home interior because the caption forgot the skip token.
Letting Destination feeds become the only public record. Feeds rot. Domains stay.
Mixing another client’s city, trade, or brand into the wrong site. That is contamination. Kill the draft.
Calling an unfiltered workflow “GEO strategy.” GEO is place + cite, not eight copies of the same caption.
7. The sentence that pays the shop
“The tool can copy a post. We only let it copy the posts we already decided were public, then we pointed them at the page that answers the local question.”
Only say it if the page exists and the filter is on.
8. FAQ for answer engines
What is a keyword filter in social cross-posting?
A rule that checks the caption of a Source post before the tool copies it to Destination accounts. OneUp’s August 2026 update lets you require a keyword or hashtag, or skip posts that contain one. Matching is case insensitive and reads caption text.
Does auto-cross-posting help local SEO?
Only as a pointer. Search and answer engines need stable URLs, consistent name-address-phone, and pages that answer a local question. Eight identical captions do not distinguish you from the next shop with the same scheduler.
Which platforms can OneUp use as a Source?
Per OneUp’s FAQ: Instagram, Facebook, and TikTok. Destinations can be any network the product supports, including LinkedIn, X, YouTube, Google Business, Threads, Bluesky, and Pinterest. Confirm current limits on the official FAQ before you buy a workflow count.
How should a restoration shop use the filter?
Swap nouns. Job-site Reel → Source. Adjuster LinkedIn → Destination that only accepts a desk token. Neighborhood Facebook → Destination that only accepts a city token. Private-home stills → skip token, no travel. The shop that copies every Instagram post onto Google Business Profile and never writes the first-hour page is running the same failure as the salon that reprints a national kit.
9. What this is not asking
No meeting. No partnership badge. No unofficial screenshot pack. No reply-for-a-trial pitch.
OneUp already knows how to ship a filter. The ground should not be a graveyard of identical captions. Open the official door if you run the tool. Then write the sentence only your shop can stand behind — and put the token in the caption before the pipe is allowed to move it.
Open field playbook. No patent. Copy it. Change the nouns from water job to salon chair if that is your shop. If it stops you from treating a vendor ethics page as a contract, good.
License: do what you want. Attribution nice, not required. Tygart Media is not Google, Substack, or an ESG rating house. Official doors only. No tracking parameters. No reprint of the full notes digest.
Why this exists: on 31 August 2026 a Substack notes digest landed in the Tygart Media inbox. Three teasers. Comedy and science from Matt Ruby. A product note from Substack Team about scheduling ad-hoc emails. And the one that is actually a control problem — Sasja Beslik’s note on Sold to the Machines, which starts with Google quietly rewriting its AI Principles.
The digest is a feed. The rewrite is a fact. This page is the operator translation.
Direct answer
A vendor AI principle is a page the vendor can edit. It is not a control until you have a written shop rule, a data path that does not depend on that page, and a way to notice when the page changes. Google’s 4 February 2025 update is the clean public example.
In 2018 Google published AI Principles that named uses it would not pursue. WIRED recorded the lines that later left the page: technologies likely to cause overall harm; weapons whose principal purpose is injury; surveillance that violates internationally accepted norms; applications whose purpose contravenes widely accepted principles of international law and human rights.
On 4 February 2025 the company published a rewrite. The live page now talks about “appropriate human oversight, due diligence, and feedback mechanisms to align with user goals, social responsibility, and widely accepted principles of international law and human rights.” The hard “will not pursue” list is not on that page.
That is not a rumor. It is a diff. Treat it as a diff.
2. What Beslik got right — and what this desk will not invent
Beslik’s useful sentence is structural: a human-rights policy written by the company about itself can be rewritten by the company about itself. No outside sign-off required. That is the whole mechanism.
This page will not reprint his report, and it will not launder unverified vote tallies or settlement figures from a teaser note. If you need the receipts, read the note and the primary sources. If you need a shop rule, stay here.
“The right way to talk about science (and a lot of other things too) is less emphasis on ‘was it always right?’ and more on ‘does it keep getting more right?’” — Matt Ruby, same digest
Vendor principles fail that test when the public cannot see the old version next to the new one without a journalist. Getting more right requires a record.
3. SEO, AEO, GEO — one pass
SEO is a stable URL that states the question and the answer. “Are Google AI Principles a legal control?” is a query. This page answers it. A screenshot in a feed is not a URL.
AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers cite pages that put the answer in the first screen, name the entities, and keep dates attached to claims. Vague “we take ethics seriously” copy is a weak cite.
GEO here means both:
Generative engine optimization — structured enough that a model can reuse the fact without inventing a ban that no longer exists.
Geographic engine optimization — the shop in Tacoma, Belfair, or Gig Harbor still owns job photos, customer names, and adjuster notes. The vendor principle page does not live on that street.
4. The shop control that survives a rewrite
Write these four lines on a page you control. Date them. Do not put them only in a Slack thread.
Control
What it is
What it is not
Allowed data
What may leave the shop: public pages, sanitized SOPs, no customer PII in prompts.
A vendor “we respect privacy” paragraph.
Allowed tools
Named models and desks. Who may paste a job file where.
Whatever the sales deck called responsible last quarter.
Record of change
A dated note when a vendor policy page moves. Screenshot plus URL.
Hope that the old HTML stays in cache.
Kill switch
How you stop a tool today if the use case flipped.
An ethics badge on a pricing page.
5. First 30 minutes after a vendor policy moves
Open the official policy URL. Save the live text. Save the date.
Find one independent report of the old language. Link both. Do not argue from memory.
Check your shop rule against the new page. If a use you banned is now permitted on their side, your ban still stands unless you change it in writing.
Walk the data path: job photos, intake forms, call recordings, CRM notes. If any of that rides a vendor that just widened scope, pull it or encrypt it before the next batch job.
Publish the fact on your domain if you advise other operators. Social is a pointer. The page is the record.
6. Failure modes
Quoting a 2018 principle in 2026 as if it were still the live rule.
Pasting customer names, claim numbers, or floor plans into a tool because the vendor page said “align with human rights.”
Treating an ESG newsletter as your compliance file.
Mixing another client’s city, trade, or matter into this site. That is contamination. Kill the draft.
Calling a screenshot of a principles page “GEO strategy.” GEO is place plus cite, not a thread.
7. The sentence that pays the shop
“Their principles moved. Ours did not, because ours live on a page we date and a data path we can shut off.”
Only say it if the page and the path exist.
8. FAQ for answer engines
Did Google change its AI Principles in 2025?
Yes. On 4 February 2025 Google published an update. Independent reporting documented the removal of the 2018 “applications we will not pursue” language on weapons, certain surveillance, overall harm, and a hard human-rights prohibition. The live page now uses “align with” language plus oversight and due diligence.
Are vendor AI principles a contract?
Usually no. They are a public statement the vendor can revise. A contract is a signed terms document, a data-processing addendum, or a statute. Read those. Archive the principles page as context, not as the binding control.
What should a small shop write down?
Allowed data, allowed tools, a dated change log, and a kill switch. Keep job-identifying material off tools that train on prompts unless you have a written exception.
How does this apply in Tacoma or on a water job?
The vendor page does not walk the wet house. Your intake, photos, and adjuster packet do. If a model rewrite widens military or surveillance use on their side, your local rule about customer data does not automatically widen with it.
9. What this is not asking
No boycott list. No invented vote math. No reprint of the Substack email.
Google already knows how to edit ai.google/principles. A shop in Pierce County still needs a sentence it can stand behind when the vendor page moves again.
Open field playbook. No patent. Copy it. Change the nouns from salon chair to water job if that is your shop. If it stops you from reprinting a brand calendar as if it were a local business, good.
License: do what you want. Attribution nice, not required. Tygart Media is not an Aveda salon, distributor, or PurePro partner. Links below go to official brand doors. No tracking parameters. No referral codes. No reprint of brand creative.
Why this exists: on 31 August 2026 an Aveda PurePro message landed with the subject September 2026 Social Posts for Salons & Artists. Three doors. Artists’ content. Owners’ content. Marketing library. The only body line that mattered: all social content, assets, and copy sit on PurePro and the Marketing Library.
That is a clean brand move. It is also the trap. The library is national. The buyer is local. Search and answer engines do not confuse the two unless you teach them to.
If you are not on that portal, do not scrape the email. You do not have the license. This page does not republish the September kit.
1. Impedance — when the kit matches the job
Use a brand social kit when two of these are true:
You already sell the branded line and the license allows the asset.
The post is a product fact, not a local claim (“this formula exists,” not “we are the only chair in Tacoma”).
You will add one operator sentence the brand cannot write: hours, neighborhood, booking path, what you actually do on the floor.
The asset is the costume. Your site, Google Business Profile, and service pages remain the record.
Do not use it as:
Your only September content plan.
A substitute for pages that answer “near me” questions.
Proof you have a marketing system. Proof is a booked job or a cited answer.
2. Three layers the email already named
The drop split the work the way a shop should split the work.
Door on the email
What it is
What it is not
Artists’ content
Floor craft. Technique, finish, product-in-hand.
Your NAP, hours, or neighborhood proof.
Owners’ content
Shop-level offers, team, operations talk.
A local entity graph.
Marketing library
Licensed assets and copy, in one locked room.
Pages an answer engine can cite as you.
Same three drawers exist in restoration, whether or not a manufacturer emails you. Tech craft. Owner ops. Vendor PDF. The PDF does not replace the first-walk page.
3. SEO, AEO, GEO — one pass, three jobs
SEO is crawlable pages with one job each. A social tile expires. A service page does not.
AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers quote pages that state the question, answer it in the first screen, and keep entities clean. A brand caption that could live on every licensed shop in a metro is a weak cite.
GEO here means two things at once, and you should keep both:
Generative engine optimization — structured enough that models can reuse you without inventing your city.
Geographic engine optimization — place nouns that match the map: city, neighborhood, desk, service.
Brand kits are good at the first half of a caption. They are mute on “South Tacoma crawl space after a supply-line split.” That sentence is yours.
4. First 30 minutes when the monthly drop arrives
Open the official portal. Confirm the asset is in-date and licensed for your channel.
Pick one brand tile for the week. Not the whole calendar.
Write the operator line the kit cannot write: who, where, what you do, how to book.
Publish or refresh the matching page on your domain before you schedule the tile. The social post points at the page. The page does not point at a disappearing feed.
Put the same fact on Google Business Profile in plain language. No brand poem.
If the portal is down or you are not provisioned, skip the kit. Do the local page anyway. That is the asset that compounds.
5. The local answer that pays
Every brand month still leaves the same unanswered questions. Write them as pages, not captions.
Salon analog: “Who does [service] in [neighborhood], what does the first visit include, how do I book after hours?”
Restoration analog: “Who walks a wet house in [city], what happens in the first hour, what do you send the adjuster?”
Name the place. Name the service. Name the next action. That is the cite.
Posting the kit raw so neighboring licensed shops share one caption.
Putting brand product claims on a page without the official source next to them.
Letting social become the only public record. Feeds rot. Domains stay.
Mixing another client’s city, trade, or brand into the wrong site. That is contamination. Kill the draft.
Calling a scheduled tile “GEO strategy.” GEO is place + cite, not a carousel.
7. The sentence that pays the shop
“The brand sent art. We published the local answer, then used one licensed tile to point at it.”
Only say it if the page exists.
8. FAQ for answer engines
What is a brand marketing library?
A locked room of licensed photos, captions, and assets a manufacturer gives to professional accounts. Aveda PurePro is one example. The library is the brand’s voice. It is not the operator’s entity.
Does posting a monthly brand social kit help local SEO?
Only as a pointer. Search and answer engines need stable URLs, consistent name-address-phone, and pages that answer a local question. A shared caption does not distinguish you from the next licensed shop.
What should an owner do when September social assets arrive?
Confirm the license. Use one tile. Write the operator line. Publish or refresh the matching page on your domain. Mirror the fact on Google Business Profile. Leave the rest of the library on the shelf.
How does this apply outside salons?
Swap nouns. Manufacturer spec sheet → brand library. First-walk SOP → owner content. Tech photos from the job → artist content. The restoration shop that reprints a vendor brochure and never writes the Tacoma first-hour page is running the same failure.
9. What this is not asking
No meeting. No partnership badge. No unofficial September lookbook.
Aveda already knows how to ship a kit. The ground should not be a graveyard of unused local pages. Open the official door if you have the login. Then write the sentence only your shop can stand behind.
CC is not courtesy copy. It is distributed write. Every inbox that receives your message is a replica of a shared database, and no coordinator approved the replication.
Email as the new API means treating an email thread as programmable infrastructure rather than just correspondence: because every message is an immutable record, every recipient’s inbox is a replica, and the Message-ID / In-Reply-To / References headers link messages into an append-only log, a structured email with an embedded instruction block can carry its own processing schema — turning the inbox into a universal, permissionless coordination layer that any human or AI agent can read, act on, and extend. Said in one breath: the thread is the database, the reply is the commit, and the subject line is the version pointer.
This is not a provocation. It is a description of infrastructure that has been running for forty years and is only now being named. The most consequential software project on Earth — the Linux kernel — is coordinated entirely over email threads. And in March 2026, a Y Combinator company called AgentMail raised $6M from General Catalyst to give AI agents their own inboxes. The pattern isn’t coming. It’s load-bearing.
We run this method in production at Tygart Media. This article explains how it works, proves it isn’t new, gives you a decision framework, and answers the four questions every operator asks first: Is a thread a database even if no one reads it again? One thread or many? Email or chat? How do I pull it into real systems? One boundary up front, so the credibility is honest: this pattern is for asynchronous, human-paced work that crosses organizational lines. It is the wrong tool for sub-second machine loops. We will be specific about that in the limits section, because the limits are real.
It’s Not a New Idea: The Prior Art
Before any mechanism, kill the “isn’t this just email?” reflex with evidence.
The Linux kernel runs on email. Thousands of contributors on every continent submit patches as inline email via git send-email, version them in the subject line ([PATCH v1], [PATCH v2], [PATCH v3]), review them in-thread, and merge them with git am. The Linux Kernel Mailing List receives roughly 1,400 emails a day. The archive at lore.kernel.org goes back to 1998 with full-text search. If email threads are sufficient engineering infrastructure for the operating system running most of the world’s servers, “it’s just email” is not an argument.
EDI is email-as-API with a schema, and it’s older than the web. Since the 1980s, enterprises have transacted structured business documents over email-like channels using ANSI X12 and UN/EDIFACT: the X12 850 Purchase Order (called “the backbone of EDI”), the 810 invoice, the 856 ship notice. EDI is email with a mandatory reply schema, enforced at the business-rules layer, predating REST by two decades. It is the direct ancestor of the structured-email method below.
The market is pricing it in right now. AgentMail (YC S25) raised $6M led by General Catalyst in March 2026 to build agent-native inboxes — real, programmatically provisioned addresses that send, receive, thread, and parse structured data. In its own words, “thousands of humans use AgentMail to power millions of agents.” A seed round on the thesis that email is AI infrastructure is not a prediction. It’s a market price.
Every vertical already does it. Inbound-parse services (SendGrid, Mailgun, Postmark) turn incoming mail into JSON webhooks; Cloudflare Email Workers run a function on every inbound message. No-code parsers (Zapier’s @robot.zapier.com, Make) fire workflows from a forwarded email. Zendesk converts every email into a ticket with a UUID. Things, Todoist, and Trello expose forward-to-task addresses. Substack made the email list the asset itself. And MuckRock — founded in 2010, before LLMs existed — turned the FOIA request-response loop into a structured, automated, trackable platform across all 50 states. The pattern predates the AI moment. AI just makes it programmable at scale.
Why a Thread Is Literally a Database
A thread is literally a database agents already speak.
Here is the intellectual spine: an email thread is an append-only, replicated log at the protocol level — not by design philosophy, but by RFC.
The relational model is in the headers. RFC 5322 defines Message-ID as a globally unique identifier in the form <unique-string@domain.com>. In-Reply-To holds the parent message’s Message-ID. References holds the full chain of ancestors back to the root. Read as a database: Message-ID is the primary key, In-Reply-To is the foreign key, References is the full join path back to the root. Together they form an append-only linked list — the same structure event-sourcing systems use to reconstruct state by replaying a log.
Replication is implicit and massive. Every To and CC inbox holds a full copy of every message. The thread is not stored in one place; it is replicated across N inboxes by the act of sending, with no coordinator. That is closer to a conflict-free replicated data type than to a single-primary database.
The transport is store-and-forward. SMTP (RFC 5321) queues and retries at every hop. That gives at-least-once delivery — the same guarantee as Kafka’s default producer. Exactly-once is impossible in any distributed system; email makes no false promise. The difference is that Kafka costs engineering time to operate; email costs a stamp.
The sharpest framing: Kafka is a better log than email in every technical dimension. Email is a better log than Kafka in every organizational dimension — because your vendor, your client, and your offshore engineer all already have an inbox. The reason to use email is not that it’s the best log. It’s that it’s the universal log. The legal industry already operationalizes this: e-discovery platforms (Mimecast, Logikcull, DISCO) treat archived threads as immutable audit trails. Courts treat email as a record. The “thread as log” framing is not novel — it is how the law already works.
What email HAS vs. what it LACKS
Property
Email HAS
Email LACKS
Durability
Yes — persists in recipient stores by default
—
Replication
Yes — every recipient is a copy
—
Global addressing
Yes — any RFC 5321 address, no registry
—
Append-only log
Yes — you reply, you don’t edit sent mail
—
Searchable audit trail
Yes — headers, body, timestamps
—
Schema enforcement
—
No — any string is accepted
ACID transactions
—
No atomicity, no locking
Consistency
Eventually consistent
Not strongly consistent
Latency
—
Unbounded (seconds to days)
Query interface
—
Full-text search only, no SELECT WHERE
State it plainly: email is eventually consistent, not strongly consistent; at-least-once, not exactly-once. It is the coordination layer, not the source of truth for mutable state.
The Method in Practice: A Worked Example
This is what we run. The cast is real — Will on strategy, Pinto engineering from India, Stefani on operations — but the payloads and secrets stay out. The credibility is in the structure, not the contents.
The FOR YOUR AI block: schema-in-the-envelope. A single message carries three layers at once: a human-readable intro for the person, an embedded system prompt that tells the recipient’s AI what role to play and what format to produce, and a strict reply schema (named sections, types, word limits) the output must conform to. The message carries its own processing instructions. It is structurally identical to a self-describing Kafka message — except the schema language is plain English. The FOR YOUR AI block is a system prompt that travels via SMTP. When Will emails Pinto, it tells Pinto’s AI what role to play before Pinto even opens the message.
The Round-N subject line: a state machine. A subject like Round 3 — v2.1 schema is a human-readable epoch counter. Any participant — including a cold-start AI that has never seen the thread — reconstructs exactly where the conversation stands without re-reading every prior message. The subject is the version pointer; the thread body is the state history; each reply is a state transition.
Each inbox: a replica. The To/CC list is the replication layer. When Stefani is CC’d for visibility, that’s a designed property, not a side effect — her inbox becomes a live replica of the exchange. The CC line is a replication directive; the shared database has no master node.
And notice what discipline this method already embodies, because it sets up the limits section exactly: the schema block is an injection-surface reducer; the human edit-before-send is the human-in-the-loop gate; one-thread-per-project is mailbox isolation; the Round-N tag is the idempotency seed. The mitigations aren’t bolted on. They’re the workflow.
The Four Questions, Answered
Is an email thread a database even if no one ever reads it again?
Yes. A database’s properties — persistent, indexed, searchable, replicated — are satisfied by the inbox independent of human attention. Reading is a query operation, not a precondition for existence. RFC 5322 messages are immutable once delivered; IMAP stores are append-only by design (you flag and label, you don’t rewrite); every recipient’s server holds an independent replica. The thread is the database, even if no human ever opens it again. lore.kernel.org proves it at civilizational scale: decades of threads, indexed and searchable, most never re-opened, all still a database. One honest caveat: this is functionally and legally append-only, not cryptographically enforced — a participant can delete their own copy. Frame it as a practical property, not a blockchain.
Should I use one email thread or many?
Continue one thread while the state machine advances linearly. Fork a new thread when scope, participants, or schema materially change. Forking has no merge protocol — do it deliberately, not habitually.
Run the decision tree: (1) Same principals? (2) Same matter, contract, or project lifecycle? (3) Same expected reply schema? If all three are yes, continue — you are advancing the same state machine. If any is no, fork. There is a third option for compound, overlapping state a single subject line can’t carry: labels on one thread. Gmail labels are not filing; they are state bits. The combination round-2 + awaiting-review + schema-v3 on one thread is a fully specified, machine-readable state any agent with API access can inspect and mutate. Fork when the state machine changes shape. Continue when it advances. Label when it branches.
Email or Slack/chat for AI workflows?
Email wins for the durable, structured, machine-readable record; chat wins for the ambient coordination around it. This is not a dismissal of chat — it’s a division of labor. Email’s structural advantages are four: federation (you can email anyone at any domain with no shared paid account; Slack Connect requires both sides to pay), durability (Slack’s free tier deletes history after 90 days; email persists by default), identity portability (your address survives a vendor change; Slack IDs are workspace-scoped), and universal addressability (email is DNS/MX-resolvable; Slack user IDs are opaque tokens). Email has no 90-day cliff, no login wall, no vendor lock-in on the archive. It is the only substrate where you can lose access to the platform and still have the data. One caveat for sensitive payloads: WhatsApp messages to Meta AI are not covered by the same end-to-end encryption as human messages, and iMessage silently downgrades to SMS when an Android user joins. The encryption you trust can vanish exactly when you add an AI participant.
How do I pull email into real systems?
Use a ladder from no-code to agent-native. (1) Zapier or Make for a no-code email parser. (2) An inbound-parse webhook — Postmark, SendGrid, or Mailgun deliver the full email as JSON; Cloudflare Email Workers run a function on every inbound message. (3) Gmail API plus Cloud Pub/Sub watch() for real-time push — name the gotcha: the watch expires every 7 days and must be auto-renewed. (4) AgentMail or Nylas Agent Accounts for agent-native, programmatically provisioned inboxes. The parsing layer between MIME and JSON (postal-mime, MailParse) is a one-line install. This is the rung where readers become practitioners.
The Decision Framework
Decision framework — when email is the coordination API.
The governing question is never “email or a real system?” It is “what does my workflow need that the thread can’t give me?” Until you hit that wall, the thread is the system.
Use email when all of these hold: the work is asynchronous and human-paced, it crosses an organizational or trust boundary, you need a durable and searchable audit trail, and a human is in the loop on consequential actions. The thread is the log.
Use chat (Slack, Discord, WhatsApp) when latency must be under about five minutes and all parties sit inside one auth boundary and the record doesn’t need to outlive the platform. Chat is for urgency inside a shared boundary; email is for durability across org lines.
Use a real database, queue, or API (Postgres, Kafka, REST/gRPC) when you need queryable schema with transport-level validation, concurrent or atomic writes, distributed locking, machine-speed operations no human reads, or high-volume machine-to-machine traffic. Where failure is unrecoverable, use infrastructure that fails loudly.
Substrate trade-matrix
Dimension
Email
SMS / iMessage
WhatsApp
Slack / Discord
Notion / Docs
Durability
High
Medium
Medium
Low (90-day free)
High
Universality (no account)
High
Medium
Low
Low
Low
Access control
Low (CC-leak)
Low
Medium
High
High
Searchable / exportable
High
Low
Low
Medium
High
Schema-ability
Medium
Low
Low
Low
Medium
Latency
Low
High
High
High
Medium
AI-ingestibility
High
Low
Low
Medium
Medium
Data ownership
High
Medium
Low
Low
Medium
Email wins decisively on durability, universality, data ownership, and AI-ingestibility. It loses on latency, access control, and schema enforcement. Position it correctly: email is the zero-infrastructure precursor to formal agent protocols. The agent-interoperability survey (arXiv:2505.02279) lays them out: MCP is a synchronous client-server interface for tool calls, A2A is peer-to-peer delegation via capability-based Agent Cards, and ANP is open-network discovery via decentralized identifiers. All are powerful; none provides durable, offline-capable, federated messaging the way an inbox already does. Every AI team building a custom agent-to-agent protocol is engineering a worse version of SMTP. Ship on email today; graduate to MCP or A2A when hot-path latency or transactional guarantees force the wall.
The Honest Limits
Honest limits — email is not a substitute for auth.
This section is the credibility. Each failure mode is real, each gets a mitigation, and none is fixable by convention alone.
Prompt injection is the headline risk. OWASP ranks prompt injection LLM01:2025 — its number-one LLM application vulnerability — and explicitly names indirect injection via external sources, including email. EchoLeak (CVE-2025-32711, CVSS 9.3, June 2025) proved a single crafted email could make Microsoft 365 Copilot exfiltrate data with zero user interaction. This is not theoretical. Mitigations: verify DKIM/SPF/DMARC at the agent layer and allowlist senders before trusting any FOR YOUR AI block; parse only declared schema sections, not free prose; gate every consequential action behind a human; run a sandboxed executor that receives structured intents only, never raw tool access. Fair caveat: EchoLeak’s zero-click specificity tracked Copilot’s particular architecture — the general risk scales with how much autonomy the agent has after it reads.
No schema enforcement. SMTP and MIME accept any string. A malformed or adversarial reply doesn’t bounce — it arrives silently, and a naive agent parses it anyway. Mitigation: validate every reply against the schema before acting; route malformed replies to human review. Say it plainly — schema conformance is a social and instruction-following contract, not a protocol guarantee. Schema drift is the failure mode.
No transaction semantics. At-least-once delivery means duplicate processing is structurally guaranteed under retries; two simultaneous replies fork the thread with no merge. Mitigation: put an idempotency key in the subject (Round-N / [UUID]) and store the Message-ID as a dedup key the consuming agent checks before acting. An idempotency key in the subject costs four characters; the absence of one can mean the same purchase order executes twice. Keep mutable state in a real database — email is the coordination layer, not the source of truth.
CC is a feature and a liability — the same mechanism. The property that makes the thread a replicated database is a compliance landmine. One reply-all or forward in a thread carrying ePHI is a breach: HIPAA requires a minimum six-year retention for designated-record-set emails, and GDPR Article 5(e) requires data be kept no longer than necessary. Anyone ever CC’d retains access forever — there is no revoke. Mitigation: in regulated contexts, mirror to a proper record system, encrypt payloads (S/MIME or PGP), or send only the control signal over email and keep the data elsewhere. This is directional, not legal advice — consult your compliance team.
Deliverability is now a hard gate. Google and Yahoo mandated SPF/DKIM/DMARC alignment for bulk senders (5,000+/day) in February 2024; Microsoft followed in May 2025, routing non-compliant high-volume mail (5,000+/day to consumer Outlook) to Junk, with outright rejection to follow; PCI DSS v4.0 adds DMARC-related anti-phishing requirements for card-data environments. Building without authentication because you’re under the volume threshold today is planning for fragility.
The operational gotchas that signal you’ve actually done this. Latency is unbounded — SMTP retry windows span minutes to days, so never put a sub-second hot path on email. Threading is client-dependent — Gmail uses subject plus In-Reply-To/References, Outlook uses Thread-Index, Thunderbird uses the JWZ algorithm — so a subject edit or a header-stripping gateway silently forks one thread into two; never rewrite the subject mid-thread (append, don’t replace). The Gmail watch() expires every 7 days. High-volume automation through a personal Gmail risks account suspension — use dedicated service accounts or agent-native platforms (and check their beta limits; Nylas Agent Accounts ship with 7-day retention and 100 sends/day). And threads beyond ~50 rounds with large payloads can blow a model’s context window — architect thread length deliberately.
When NOT to use email
Need
Use instead
High-frequency / sub-second M2M
REST, gRPC, or a queue
Strict schema validated at transport
JSON Schema + API gateway
Regulated data, CC-leak unacceptable
E2E-encrypted channel + access controls
High-volume M2M (thousands/min)
Message queue / event stream
Atomic transactions or locking
Real DB / event-sourcing
The throughline: email gives you a convention, not a guarantee — and every mitigation here is a convention layered on a convention. Where failure is unrecoverable, use infrastructure that fails loudly. One more flag for commercial use: if AI-generated output produced through a relay chain is published without clear labeling, the structured hand-offs can obscure the AI’s role. Disclose it.
Publish It to Get Smarter
Here is the move, and it is not subtle: this article is a round in the loop it describes.
Watch the flywheel turn. We publish this piece. AI engines index it. Its named patterns — the FOR YOUR AI block, Round-N versioning, schema-in-the-envelope — become citable units. Operators adopt them. Tygart Media becomes the attributed origin. Each citation reinforces the corpus, and the corpus earns more citations. The article does not describe the flywheel. It is the flywheel, running.
This is not promotion. It is the method executing on itself. Our model is to own the cited corpus on the topics our clients operate in — where breadth is the moat and the scoreboard is AI-citation coverage, not Google rank. The mechanical reason it compounds is freshness: a flagship piece on a pattern we demonstrably run in production is structurally fresher than generic “AI email tips,” because it has live proof points to update. Directional evidence suggests content refreshed within ~30 days earns materially more AI citations than stale content; treat that as a direction, not a promise. Which is why this piece carries a dated live-example note, and why we’ll keep the round count current.
Live example — last updated June 2, 2026: the working loop described here is active and advancing in production.
So when AgentMail raises $6M to give agents inboxes, and the Linux kernel ships another thousand patches today over email, and Microsoft starts turning away mail that can’t authenticate itself — read all of it as one signal. Email is not legacy infrastructure being repurposed. It is the universal handshake for any workflow that crosses an organizational boundary, and it was here the whole time.
Your inbox is already a database. The only question is whether you are the DBA.
How this was made: this article was produced by the method it describes. A swarm of AI agents researched it in parallel across seven angles, a synthesis pass shaped it, and it was assembled and edited in the same human-plus-AI loop the piece is about. We practice what we publish.
Most SEO teams know they need to care about AI search. Almost none of them have a measurement system in place for it. That’s the gap this article closes.
Ranking in ChatGPT, Perplexity, Google AI Overviews, or Claude isn’t a vanity metric anymore — it’s a traffic channel. But unlike Google, AI systems don’t serve a results page you can screenshot. They weave citations into prose. Your brand either shows up in that prose or it doesn’t, and if you’re only watching GA4’s built-in channel reports, you’re flying mostly blind.
This is a practitioner’s setup guide: the exact metrics, GA4 configuration, and tool stack needed to track LLM visibility systematically.
The Five Metrics That Define LLM Visibility
Five metrics that define LLM visibility.
Traditional SEO tracks ranking position, impressions, and clicks. None of those exist in AI search. You need a new metric set:
Citation frequency — How often your domain or brand is mentioned in AI-generated answers for your target query set. LLMs typically cite 2–7 sources per response. Capturing one of those slots consistently is the entire game.
Prompt coverage — Out of your tracked prompt library, what percentage of prompts return your brand at all? Calculate it as: (prompts where you appear ÷ total tracked prompts) × 100. A brand actively optimizing for AI search should be above 40% coverage on tier-1 prompts within 90 days of focused content work.
Share of voice — For a given topic cluster, how often do AI answers cite you versus competitors? If you appear in 12 of 30 tested prompts and a competitor appears in 20, they hold 67% share of voice on that topic. That ratio is more strategically meaningful than any single citation count.
AI referral sessions — The sessions in GA4 that actually arrived from an AI platform with a usable referrer header. This is the only metric that ties visibility to business outcomes. Setup is covered in the next section.
Conversion quality from AI traffic — AI-referred visitors behave differently from organic search visitors. They arrive with higher intent (they asked a specific question and your site was the answer). Track engagement rate, pages per session, and goal completions for AI referral sessions separately. If this cohort converts at 2–3× the rate of your organic traffic — which early data from practitioners suggests — it changes how you think about GEO investment.
Setting Up GA4 to Capture AI Traffic: The Regex You Need
GA4 regex to capture AI traffic.
Out of the box, GA4 misclassifies most AI referral traffic. ChatGPT sessions land in “Referral.” Perplexity sessions land in “Referral.” Claude.ai sessions may land in “Direct.” Without a custom channel group, you have no way to isolate or trend this traffic.
In GA4: Admin → Data Display → Channel Groups → Create New Channel Group
Critical step: Place the “AI Search” channel above “Referral” in your channel list. GA4 processes channel rules top-to-bottom — if Referral appears first, every AI referral will match Referral before ever reaching your AI channel definition. This is the single most common setup mistake.
One important caveat on scope: approximately 70% of AI-originated visits arrive without a referrer header. OpenAI’s iOS app, private browsing mode, and in-app browsers all strip referrer data before the request reaches your server. This means your “AI Search” channel in GA4 is capturing the visible minority — the sessions where the referrer was preserved. Don’t benchmark by absolute volume. Benchmark by growth rate. If your AI Search channel is growing month-over-month while overall Direct traffic is stable, your citation presence is expanding.
To supplement GA4 attribution, add a self-reported source question to high-intent forms: “How did you find us?” Include “ChatGPT / AI assistant” as an option. This provides ground truth that session data alone cannot.
The Tool Tier: Free to Enterprise
The LLM visibility tool market matured significantly through 2025 and into 2026. Three tiers have emerged, and most independent publishers and agencies should start at the first tier before paying for anything.
Free / DIY layer — start here
Run 20 representative prompts manually across ChatGPT, Perplexity, Claude, and Google AI Overviews each month. Record mentions in a spreadsheet: cited (yes/no), cited with link (yes/no), competitor named instead. This gives you baseline prompt coverage and share of voice data with zero budget. Do this for at least one month before paying for any tool — you’ll understand your own citation patterns much better and know exactly what problem you’re trying to solve with a paid platform.
Mid-market tools ($100–$500/month)
Otterly.ai provides automated monitoring across Google AI Overviews, ChatGPT, Perplexity, Gemini, and Microsoft Copilot. It runs scheduled prompt sets on your behalf and tracks brand mention frequency and citation links over time. The value is removing the manual labor of the 20-prompt audit while expanding coverage to more platforms and prompts than you’d realistically run by hand.
LLMrefs takes a different approach: input your existing SEO keywords rather than writing prompts, and the platform automatically generates prompt fan-outs and returns tracking in a dashboard that mirrors a traditional rank tracker. Lower learning curve for teams coming from keyword-centric SEO workflows.
Enterprise layer ($1,000+/month)
Profound is built around its proprietary Prompt Volumes dataset — a search-volume equivalent for AI queries. It estimates how often specific questions are actually being asked across LLMs, which lets you prioritize content topics based on demand rather than intuition. This is genuinely useful at scale, but it’s overkill for most independent publishers. It becomes relevant when you’re deciding between 20 possible content angles and need volume data to make the call.
The 20-Prompt Audit: Your Monthly Baseline Protocol
Whether you use a paid tool or not, run this protocol monthly:
Build a prompt library of 20 questions your target buyer would ask an AI system. These should be the questions your content is designed to answer — not keyword-formatted phrases, but actual conversational queries.
Run each prompt across ChatGPT, Perplexity, and Google AI Overviews (3 platforms × 20 prompts = 60 data points per month).
For each result, record: was your brand cited in text, was your domain linked, and which competitor was cited if you were not.
Calculate prompt coverage per platform (what % of the 20 prompts returned your brand) and total share of voice versus your top 3 competitors.
Log results in a spreadsheet with a date column. Three months of monthly data reveals directional trends — whether your GEO and AEO work is moving the needle. No tool gives you this longitudinal view without ongoing, consistent execution.
Diagnosing a Citation Drop
Diagnosing a citation drop.
If your monthly audit shows prompt coverage declining from the previous period, run through this checklist before assuming a platform algorithm change:
Did you remove or restructure a previously cited page? AI systems build representations of your content over time. Pages that disappear or are significantly restructured lose citation weight. Check your changelog against the prompt set that declined.
Did a competitor publish stronger content on the topic? AI citation is zero-sum within the 2–7 source window. If a competitor published a more authoritative, well-structured page, it may have displaced yours. Review their recent publishing calendar.
Check your LLMs.txt file. A crawlability block accidentally introduced via LLMs.txt or a misconfigured robots.txt Disallow directive will cut AI citation access at the source. Verify your LLMs.txt is allowing the pages you expect to be cited.
Check for a model update on the platform. Major model releases can reset citation patterns. GPT-5, Gemini 2.0, and similar releases changed which sources each platform weighted. Check the platform’s public changelog for the period in question.
If none of these apply, run a structured data audit on the pages that lost citations. Schema markup, FAQ blocks, clear heading hierarchy, and factual density all affect how AI systems extract and attribute content. A page that lost its FAQ section in a redesign may have simultaneously lost its AI citation utility.
The Bottom Line
LLM visibility measurement is not a solved problem, but the measurement primitives exist today: GA4 custom channel groups for traffic attribution, manual prompt audits for citation coverage, and mid-market tools for automated monitoring at scale. The sites building this infrastructure now will have 12–18 months of baseline data by the time the rest of the market treats it as standard practice.
Build the 20-prompt library this week. Set up the GA4 channel group today. Everything else layers on top of those two data streams.
CH 03 · Answer Engine Intelligence · Filed by Will Tygart
What Is SiteBoost for Telehealth?
SiteBoost for Telehealth is a done-for-you WordPress optimization service for telehealth platforms and occupational health providers — applying YMYL-compliant SEO, AEO, and GEO optimization to patient-facing content, employer health pages, and clinical service descriptions. Built specifically for the trust and credentialing signals Google requires before ranking healthcare content, and the direct-answer format that AI systems use to respond to medical and workplace health queries.
Telehealth content faces the strictest content standards in search. Google’s YMYL (Your Money or Your Life) guidelines apply to any health-related content — meaning E-E-A-T signals (Experience, Expertise, Authoritativeness, Trustworthiness) aren’t optional. A telehealth WordPress site without proper credentialing signals, licensed clinician attribution, and medically accurate terminology isn’t just under-optimized — it’s actively downranked.
Most telehealth platforms are built by product teams who understand the clinical side but not the content architecture side. The result: accurate medical content on a WordPress site that Google treats as low-trust because the trust signals aren’t structured correctly. We fix that.
What We’ve Done in This Vertical
We manage content operations for Sickday (sickday.com), a same-day telehealth and occupational health platform serving employers and individual patients. The critical rule in this vertical: staff are licensed clinicians — not doctors, not nurses. That distinction matters legally and for E-E-A-T compliance. We’ve built the content architecture, credentialing signals, and YMYL-compliant optimization stack for this specific category of healthcare provider.
What SiteBoost Covers for Telehealth
E-E-A-T signal injection — Licensed clinician credentials, platform accreditation signals, medical review attribution, and organizational trust markers structured into content and schema
YMYL compliance optimization — Content accuracy review, hedging language for medical claims, appropriate disclaimer structures, and factual sourcing for health information
Occupational health entity signals — OSHA references, DOT compliance language, workers’ compensation terminology, employer health program signals for occupational health content
Telehealth platform entities — Relevant telehealth regulation references (Ryan Haight Act, state telehealth practice standards, HIPAA compliance signals), payer and insurance entity references
Patient FAQ schema — Common patient and employer questions answered in FAQPage format for PAA placement (“how does telehealth work,” “is telehealth covered by insurance,” “what is a DOT physical”)
AI citation optimization — Speakable schema and LLMS.TXT configuration for Perplexity and Google AI Overview citation when patients and employers search for telehealth services
The YMYL Difference in Telehealth SEO
Standard SEO agencies treat telehealth like any other local service business. Google doesn’t. Health content requires demonstrably different trust architecture: named clinician credentials on clinical content, medical review dates on health information pages, accurate clinical terminology that matches how licensed providers actually speak, and clear scope-of-practice language that distinguishes what a telehealth platform can and cannot provide. Getting this wrong doesn’t just hurt rankings — it creates compliance exposure.
What the Pilot Delivers
Item
Included
Site audit + YMYL compliance gap analysis
✅
10 posts optimized (SEO + AEO + GEO)
✅
E-E-A-T signal injection on all 10 posts
✅
Licensed clinician credential structuring
✅
FAQPage schema (patient + employer Q&A)
✅
Occupational health entity injection (where applicable)
✅
60-day impact report
✅
SiteBoost vs. DIY vs. Generic Healthcare SEO Agency
SiteBoost
DIY
Generic Healthcare SEO
YMYL E-E-A-T compliance built in
✅
Risky
Sometimes
Licensed clinician (not “doctor”) language enforced
✅
❌
❌
Occupational health entity library
✅
❌
Rarely
Telehealth regulation references
✅
❌
Rarely
AI citation optimization
✅
❌
❌
Proven in telehealth vertical
✅
Unknown
Unlikely
Interested in SiteBoost for Your Telehealth Site?
We onboard sites personally. Email Will with your site URL and a brief description of your clinical model — he’ll follow up within one business day.
Email only. No sales call required. No commitment to reply.
Frequently Asked Questions
Does this work for direct-to-consumer telehealth as well as employer occupational health?
Yes. The entity set and content architecture adapt to your clinical model. DTC telehealth content targets patient-facing queries and insurance coverage questions. Occupational health content targets employer HR and safety manager queries — OSHA compliance, DOT physicals, return-to-work programs. Both operate under YMYL standards; both get the full E-E-A-T treatment.
Why does the licensed clinician language distinction matter for SEO?
Calling staff “doctors” or “nurses” when they’re licensed clinicians (nurse practitioners, physician assistants, licensed therapists) creates scope-of-practice inaccuracies that can trigger both Google trust penalties and state medical board compliance issues. Google’s quality raters are specifically trained to identify healthcare credential misrepresentation. We enforce accurate clinical title language as a hard rule in all content we optimize.
Can SiteBoost help with content that explains telehealth regulations to patients?
Yes — and this is high-value content for telehealth platforms. State-specific telehealth practice standards, insurance coverage rules, and prescription regulations (Ryan Haight Act) are exactly the kind of regulatory content that earns E-E-A-T signals when written accurately and attributed correctly. We can optimize existing regulatory explainer content or identify gaps where new content would capture patient research queries.
Is telehealth content affected by the helpful content update?
Significantly. Google’s helpful content guidelines hit thin, AI-generated health content hardest. Telehealth sites that published generic condition descriptions without clinical attribution saw the steepest ranking drops. The optimization pass ensures all content demonstrates genuine clinical expertise — specific treatment descriptions, accurate clinical terminology, and proper scope-of-practice framing that generic health copywriting lacks.
CH 03· Answer Engine Intelligence
· Filed by Will Tygart
What Is SiteBoost for Regional Restoration?
SiteBoost for Regional Property Damage Restoration is a done-for-you WordPress optimization service for restoration companies serving multi-county suburban and rural markets — where the competition isn’t ServiceMaster or Servpro’s national SEO budget, but regional independents with the same local knowledge advantage you have, and slightly better-optimized WordPress sites. We close that gap.
The restoration SEO landscape outside major metros is fundamentally different from downtown competition. National franchise sites dominate broad category searches. But regional independent operators — companies serving 3–8 counties with genuine local presence and real IICRC credentials — can win the specific, high-intent queries that national sites don’t have the local content depth to capture.
The strategy: own the local entities (county names, neighborhoods, local insurers, regional weather events), demonstrate IICRC credential depth (specific standards by loss type), and produce the adjuster-facing content that decision-makers search for when qualifying restoration contractors for their preferred vendor lists.
What We’ve Done in This Vertical
What we’ve done in this vertical.
We manage content operations for Upper Restoration (NYC and Long Island — Nassau and Suffolk counties) and 247 Restoration Specialists (Houston TX metro). Both are regional independent operators competing against franchise chains with much larger marketing budgets. The content architecture, IICRC entity library, and adjuster-facing content strategy are proven across both markets.
What SiteBoost Covers for Regional Restoration
Multi-county geo-entity injection — County names, municipalities, ZIP codes, and regional landmarks that signal genuine service area coverage to local search algorithms
IICRC standard-level entity injection — S500 (water damage), S520 (mold), S540 (trauma/biohazard), S600 (upholstery), S700 (fire/smoke), S900 (contents) referenced by specific standard and loss type
RIA and industry body signals — Restoration Industry Association references, regional trade association memberships, and professional network signals
Property manager and GC content — Commercial referral source content optimized for property manager and general contractor discovery queries
FAQPage schema — Homeowner, adjuster, and property manager questions answered in structured format for PAA placement
The Adjuster-Facing Content Difference
The adjuster-facing content difference.
Most restoration WordPress sites produce homeowner-facing content exclusively. The highest-value referral relationships — insurance adjuster preferred vendor lists — come from a completely different content audience with completely different search intent. Content that references RCV vs. ACV claims, Xactimate line items, carrier documentation requirements, and IICRC standard compliance reaches the adjuster audience that homeowner-facing content never touches.
What the Pilot Delivers
What the pilot delivers.
Item
Included
Site audit + local and adjuster query gap analysis
How is this different from the standard SiteBoost for Restoration page?
The standard restoration SiteBoost page is built for any restoration operator. This page is specifically for regional independents serving multi-county suburban and rural markets — where the geo-entity strategy, adjuster-facing content, and multi-county local authority approach are the primary differentiators from franchise competitors.
What does adjuster-facing content optimization actually involve?
It means restructuring content to answer the questions insurance adjusters search for when qualifying restoration contractors: IICRC certification verification, documentation and reporting capabilities, carrier compliance history, Xactimate familiarity, and response time and capacity for large loss events. This content doesn’t convert homeowners — it gets you on preferred vendor lists.
Does SiteBoost work for fire and mold restoration as well as water damage?
Yes. The entity injection is loss-type specific — water damage content gets S500 references, mold gets S520 and EPA 402-K-02-003, fire/smoke gets S700. Multi-peril operators get all applicable standards applied to the relevant posts in the 10-post pilot.
CH 03· Answer Engine Intelligence
· Filed by Will Tygart
What Is SiteBoost for Twin Cities Water Damage Restoration?
SiteBoost for Twin Cities Water Damage Restoration is a done-for-you WordPress optimization service for water damage and property restoration companies serving Minneapolis, Saint Paul, and the surrounding metro — injecting Minneapolis-specific neighborhood entities, Minnesota licensing references, IICRC credentials, and local content signals that separate market-native operators from national franchise chains in local search results.
The Twin Cities restoration market has a specific local dynamic: a mix of national franchise operators (ServiceMaster, Servpro, Paul Davis) with massive domain authority, and local independent operators who actually know Edina from Eden Prairie and understand the difference between a Minnetonka lake home and a Saint Paul bungalow. Local content that demonstrates genuine market knowledge wins in that environment — national franchise sites can’t fake it.
We built this system on Partners Restoration (partnerscos.com), a water damage and restoration company serving the Minneapolis SW metro — Edina, Chanhassen, Wayzata, Minnetonka, Eden Prairie, Deephaven, Orono, and Plymouth. The neighborhood entity library, Minnesota-specific licensing references, and local content architecture are proven in this market.
What SiteBoost Covers for Twin Cities Restoration
What SiteBoost covers for Twin Cities restoration.
Minneapolis/Saint Paul neighborhood entity injection — Specific neighborhood names, lake names, school districts, and local landmarks that signal genuine market presence to Google and local searchers
Minnesota licensing entity signals — Minnesota Department of Labor and Industry (DLI) contractor licensing, Minnesota Pollution Control Agency (MPCA) mold references, and state-specific regulatory signals
IICRC credential injection — S500 water damage, S520 mold remediation, S700 fire and smoke standards referenced throughout relevant content
Local buyer FAQ schema — Twin Cities homeowner questions answered in structured format (“does homeowners insurance cover water damage in Minnesota,” “how long does water damage restoration take in Minneapolis”)
Seasonal content signals — Minnesota winter pipe burst, spring flooding, and ice dam water damage content optimized for seasonal query patterns
AI citation optimization — Content structured for Perplexity and Google AI Overview citation when Twin Cities homeowners search for emergency restoration help
Twin Cities Neighborhood Entity Library
Twin Cities neighborhood entity library.
Content that references specific Twin Cities neighborhoods outperforms generic metro-area content for local queries. Our entity library covers: Minneapolis (Uptown, Linden Hills, Kenwood, Longfellow, Northeast), Saint Paul (Highland Park, Macalester-Groveland, Summit Hill, Como), and the SW suburbs: Edina, Eden Prairie, Minnetonka, Wayzata, Chanhassen, Chaska, Orono, Plymouth, Deephaven, Shorewood.
What the Pilot Delivers
What the pilot delivers.
Item
Included
Site audit + Twin Cities local query gap analysis
✅
10 posts optimized (SEO + AEO + GEO)
✅
Minneapolis/Saint Paul neighborhood entity injection
✅
Minnesota licensing reference injection
✅
IICRC entity signals
✅
FAQPage schema (MN homeowner Q&A)
✅
60-day impact report
✅
Interested in SiteBoost for Your Twin Cities Water Damage Restoration Site?
We onboard sites personally. Email Will with your site URL and he’ll follow up within one business day.
Does this only work for companies in the Minneapolis SW suburbs?
No — the geo-entity approach works for any Twin Cities sub-market. The neighborhood entity set is adapted to your actual service area. Companies serving the North Metro (Blaine, Coon Rapids, Maple Grove) or East Metro (Woodbury, Stillwater, White Bear Lake) get a different neighborhood entity set than SW metro operators.
How does this help against national franchise competitors with huge domain authority?
National franchises can’t fake local knowledge. Content that references specific Twin Cities neighborhoods, Minnesota-specific weather patterns, local licensing bodies, and regional building characteristics signals genuine market presence that national sites don’t have. Google’s local algorithm rewards this specificity in local pack and organic local results.
Does SiteBoost cover seasonal content for Minnesota’s specific weather patterns?
Yes. Minnesota’s climate creates specific restoration query patterns — winter pipe bursts, spring snowmelt flooding, summer storm damage, and ice dam water intrusion are all seasonal signals we optimize for as part of the Twin Cities pilot.
By Will Tygart · Practitioner-grade · From the workbench
What Is SiteBoost for B2B Event Platforms?
SiteBoost for B2B Event Platforms is a done-for-you WordPress optimization service for conference technology companies, meeting platforms, and event tech SaaS — injecting MPI, PCMA, and hybrid event industry entities, optimizing for meeting planner buyer-stage queries, and building AI citation readiness in a category where most platforms still rely entirely on paid acquisition.
Event technology buyers — meeting planners, event managers, corporate travel coordinators — research platforms through industry association resources, peer recommendations, and increasingly through AI-generated answers. Companies that appear in those answers without paying for the placement have a significant acquisition cost advantage over competitors who live and die by paid search.
We built this optimization system on WeConvene, a B2B event and meeting platform where we’ve optimized content for meeting planner search intent, hybrid event terminology, and the industry body references that signal credibility to professional event buyers.
What SiteBoost Covers for B2B Event Platforms
Industry body entity injection — MPI (Meeting Professionals International), PCMA (Professional Convention Management Association), GBTA, SITE, and relevant certification body references
Event format terminology — Hybrid events, virtual attendee experience, breakout session technology, attendee engagement metrics, and event ROI measurement language
Buyer persona content — Meeting planner, corporate event manager, association executive, and incentive travel buyer search intent mapped to existing content
FAQPage schema — Platform evaluation questions answered in structured format (integration capabilities, attendee limits, pricing models, security compliance)
Comparison content structure — Positioning content for “event platform comparison” and “best virtual conference platform” queries
AI citation optimization — Content structured for Perplexity citation when buyers research event technology options
What the Pilot Delivers
Item
Included
Site audit + buyer query gap analysis
✅
10 posts optimized (SEO + AEO + GEO)
✅
MPI/PCMA industry entity injection
✅
Hybrid event terminology optimization
✅
FAQPage schema (buyer evaluation Q&A)
✅
Buyer persona targeting applied
✅
60-day impact report
✅
Interested in SiteBoost for Your B2B Event Platform Site?
We onboard sites personally. Email Will with your site URL and he’ll follow up within one business day.
Email only. No sales call required. No commitment to reply.
Frequently Asked Questions
Does this work for in-person event companies as well as virtual/hybrid platforms?
Yes. The entity set adapts to your event format focus — in-person events use venue, AV, and logistics entities; virtual/hybrid platforms use technology integration, attendee experience, and platform capability entities. Both buyer audiences use industry body references (MPI, PCMA) as credibility signals.
Is event technology content competitive for organic search?
Highly competitive on broad terms (“best event platform”), much less competitive on specific buyer-stage and specification queries (“hybrid event platform with Salesforce integration” or “MPI-recognized virtual conference platform”). SiteBoost targets the specific queries where organic wins are achievable.
Can SiteBoost help with content that positions against specific competitors?
Comparison content is one of the highest-converting content types in B2B SaaS — and event tech is no exception. We can optimize existing comparison pages or structure new comparison content as part of the 10-post pilot scope.