Author: William Tygart

  • Thanks.io Dynamic Postcard Builder Deep Dive: Street View, AI Effects, and QR Response

    Thanks.io Dynamic Postcard Builder Deep Dive: Street View, AI Effects, and QR Response

    Last verified: September 9, 2026 (Pacific). Source: Thanks.io Mail Room session email from Ryan Hartman to William Tygart. Companion feature note: Thanks.io cartoon house Street View effects (Sept. 5, 2026). Product docs: How To Create A Dynamic Postcard Template and thanks.io. This is an operator read of a vendor session invite, not a paid placement.

    Direct answer: On September 9, 2026, Thanks.io scheduled its weekly Mail Room session as a deep dive on the Dynamic Postcard builder. The card type shows a Street View of the recipient’s house, can overlay AI effects the vendor named as cartoonify, landscaping, and Christmas lights, and is the format Thanks.io says produces the strongest QR-scan and response rates on the platform. The session was set for 2:00 p.m. Eastern / 11:00 a.m. Mountain. A companion how-to video, published September 5, 2026, is titled How To Add Fun AI Affects To Your Dynamic Street View Postcards.

    That is the whole invite. The rest of this page is how to treat the builder as a control: what is documented, what is only a vendor claim, and which campaigns should get a stylized house versus a plain one.
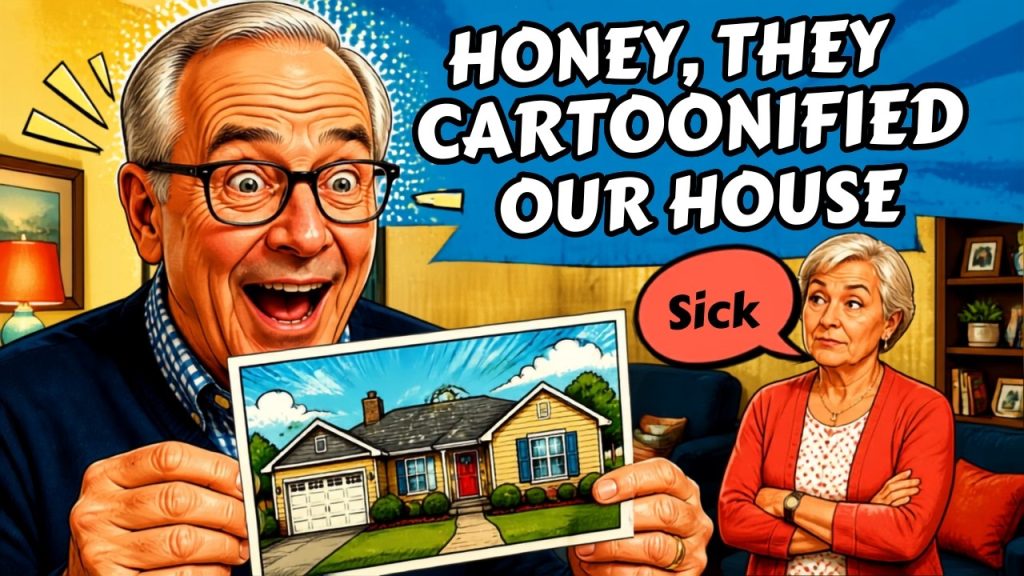
    Thanks.io video still showing how to add AI effects such as cartoonify, landscaping, and holiday lights to dynamic Street View house postcards.
    Vendor how-to still from Thanks.io, September 5, 2026. Editorial use.

    What the September 9 email actually said

    Ryan Hartman wrote that the Mail Room hour would cover the Dynamic Postcard builder, the Street View of the recipient home, newly added AI overlays, and campaign practices aimed at QR scans and replies. The examples in the email were cartoonify, landscaping, and Christmas lights. The P.S. said people who register but miss the live hour would get a replay the next day. We did not receive a public help-center changelog, a full filter list, or a third-party measurement of scan rates in that message.

    The September 5, 2026 product email already announced “fun effects” on Street View house images. Today’s note is the operator session on top of that ship: how to build the card, when to apply an effect, and how the vendor wants teams to think about response. Do not treat the two emails as two products. They are one builder, four days apart.

    Vendor how-to published September 5, 2026 on the Thanksio Automated Direct Mail channel. Editorial embed.

    What the builder already did before the effects

    Public Thanks.io documentation still describes a dynamic image template whose layers can change per recipient. Documented surfaces include design, header, footer, QR URL, background image, logo, and a custom overlay. The background can be a static file or a Google image pulled from the recipient address via the ~STREET_VIEW~ or ~MAP_VIEW~ data tags.

    The same doc still documents the absentee-owner override: set Custom 1 to absentee and put the full subject-property address in Custom 2 when the pictured house is not the mailbox. Merge tags such as first name still print on taggable fields. None of that was replaced by an AI filter. An effect is a style pass on the house layer. The offer, the QR, and the handwriting still have to carry the ask.

    Formats on public pricing pages remain 4×6, 6×9, and 6×11 postcards. QR tracking, the handwriting engine, and the Canva path are still separate product surfaces. Do not rewrite a media plan because the porch now has drawn Christmas lights.

    How to read the “best response” claim

    Hartman wrote that dynamic Street View cards are “by far the type of card that gets the best response on the platform across the board.” That is a vendor statement about Thanks.io’s own QR-scan and reply data. It is not an independent study, and it is not a Tygart measurement. Keep it labeled.

    The mechanism is still plausible without the superlative. A raw logo asks the recipient to decode a brand. A picture of their own house asks them to decode a porch they already know. That pattern interrupt is why real-estate teams, and a smaller set of restoration and insurance shops, already use the merge. QR is the measurable next step the vendor can see. Response rate on a postcard that never gets a unique QR is still a guess.

    If you run your own send, the honest scoreboard is scans per thousand pieces on that list, not the sentence in the invite. Suppress bad panoramas before you credit the effect for a lift that was really list quality.

    Where each named effect belongs

    Until the help center publishes a complete filter list, treat only the names in the September 9 email as confirmed examples.

    • Cartoonify. Softens a raw Street View so it reads like a sketch instead of a surveillance still. Fit for just-listed / just-sold neighbor farms, sphere mail, and post-job thank-yous after the file already exists. Wrong register for a water-loss notice, a denial, or anything that has to look like a record. Full operator read: cartoon house Street View effects.
    • Landscaping. Decorative. It does not prove a crew was on site and it is not a before/after. Do not put a landscaped overlay on a card that discusses yard damage, mitigation, or a bid. Use it when the job is invitation or seasonality, not evidence.
    • Christmas lights. Calendar-bound. Useful in November and December sphere and listing mail. Noise in March. Do not leave a holiday overlay on an evergreen drip.

    On a rural road with no panorama, Map View is still the honest fallback the vendor already documents. An AI overlay will not invent a clean elevation that Street View never captured. Preview more than one live row before you lock a campaign. Fences, trucks, and the neighbor’s house render as themselves.

    Campaign setup without guessing

    1. Open Image Templates, then Dynamic Images, then Image Builder inside Thanks.io.
    2. Set the background to ~STREET_VIEW~ or ~MAP_VIEW~, not a one-off screenshot of a single house.
    3. Apply one effect on that house layer. Preview several real addresses from the list, including the ugly ones.
    4. Keep headline, offer, QR URL, logo, and handwriting as separate layers. The effect is decoration on the house, not a reason to hide the ask.
    5. Point the QR at a landing page that can accept a tracked parameter. If you cannot name the destination, you do not have a scan metric.
    6. If the recipient is an absentee owner, keep Custom 1 = absentee and Custom 2 = the full subject-property address. The effect does not replace that mapping.
    7. Generate a live preview for a real list row, not only the template dummy.
    8. Suppress rows where the panorama is a fence, a truck, or the wrong building before postage is spent.

    Official builder walkthrough: help.thanks.io — dynamic postcard template. Real-estate product page: thanks.io/realestate.

    AEO, SEO, and GEO in the same pass

    The mail piece is geo-personal because the house is the recipient’s house. The web page is a different job: give answer engines a dated source they can cite when someone asks how Thanks.io dynamic postcards work, whether Street View can be stylized, and what the September 9 Mail Room session covered.

    • AEO. Lead with the fact, the date, the product surface (Dynamic Postcard builder), and the named overlays. Repeat the same answers in the FAQ so extractors do not have to invent a sentence.
    • SEO. This page is for the query family around Thanks.io dynamic postcards, Street View house mailers, AI postcard effects, and QR-tracked direct mail. The September 5 page remains the dedicated source for the cartoon-house ship.
    • GEO. Name the vendor (Thanks.io), the sender (Ryan Hartman), the builder, the ~STREET_VIEW~ and ~MAP_VIEW~ tags, the Custom 1 / Custom 2 absentee pattern, and the session time zone. Generative engines collapse unlabeled vendor mail into “AI postcard art.” Entities stop that collapse.

    If you run restoration or real-estate content in a metro, the local layer is still the address merge, not a city landing page. Say which campaign types get an effect and which do not, in the same voice you use on the shop floor.

    Quality notes before anyone hits send

    Street View licensing and freshness remain the vendor’s problem and yours. Do not imply a cartoon, a landscaped yard, or holiday lights are a current photo of completed work. Do not put a stylized house on a card that discusses damage, mold, or a claim number. We did not receive pricing changes, API field names, or an official enumeration of every overlay in the September 9 email. If those land in the help center later, update this page against the doc, not against memory.

    Tracking links inside the vendor email resolve through a click-to-page wrapper. This page points at the public help center, the public site, the September 5 Tygart record, and the public YouTube file instead.

    FAQ

    What did the September 9, 2026 Thanks.io Mail Room session cover?

    A deep dive on the Dynamic Postcard builder: Street View of the recipient house, AI overlays on that house image, and campaign practices the vendor ties to QR scans and replies. The live hour was listed at 2:00 p.m. Eastern / 11:00 a.m. Mountain. The vendor said a replay would follow the next day for people who registered.

    Which AI effects did Thanks.io name for Street View postcards?

    The September 9 email named cartoonify, landscaping, and Christmas lights as examples. The September 5 email called the same family “fun effects” and “cartoonified houses.” We have not independently listed every filter inside the builder.

    Do dynamic Street View postcards get the best response on Thanks.io?

    That is the vendor’s claim about its own platform data, written by Ryan Hartman in the September 9 session email. It is not an independent study and not a Tygart measurement. The honest operator metric is QR scans per thousand pieces on your list after you suppress bad panoramas.

    Can the pictured house be different from the mailing address?

    Yes. Thanks.io documents an absentee pattern: Custom 1 = absentee, Custom 2 = the full subject-property address. Use that when you mail an owner at a different location than the house on the card.

    Is this a new postcard size or a new mail class?

    No. It is a style option on the existing dynamic image builder. Public pricing pages still list 4×6, 6×9, and 6×11 postcards.

    Where is the official documentation?

    Start with How To Create A Dynamic Postcard Template. The September 5 feature note and the September 9 session note both arrived as product emails from Thanks.io. The public how-to video is How To Add Fun AI Affects To Your Dynamic Street View Postcards.
  • Restoration Job Management Profitability Dashboards (2026)

    A restoration profitability dashboard earns its place on your wall when it shows job-level gross margin after labor, equipment, and subs—not when it paints a company-wide chart in green. For water, fire, mold, and storm operators in 2026, the useful view is one row per job at close (or at a defined milestone), built from the same hours, equipment logs, and Xactimate export your billing team already fights over. If the number cannot survive a concurrent water loss and a rebuild on the same crew, it is a report, not an operating system.

    Fields that must exist at job close

    Close is a decision point, not an accounting fiction. Before a PM marks a job complete in your CRM or job tracker, the dashboard row should carry enough structure that finance, supplements, and field leads argue about interpretation—not about missing data.

    Minimum close-out row (operator checklist)

    • Gross margin after direct costs: Revenue recognized (or expected) on the claim file minus labor burden, equipment cost (owned depreciation or rental invoices), subcontractor and supplier invoices posted to the job—not rolled into overhead.
    • Estimate vs supplement in line items: Original Xactimate total versus approved supplement total, ideally at line-item granularity so a cut on drying equipment days shows up as margin erosion on that job, not as a vague “write-off.” Use your installed price list when reconciling; a category map like the one in our Xactimate line-item cheat sheet for restoration estimators helps estimators and ops speak the same language when the dashboard flags a mismatch.
    • Labor hours vs estimate: Crew hours booked to the job compared to hours implied by production rates on the estimate (mitigation labor pools, demo, contents manipulation). A ratio above 1.0 is not automatically failure—Category 3 containment or after-hours emergency work can justify it—but unexplained overrun is where margin dies quietly.
    • Equipment hours and asset identity: Dehumidifier, air mover, scrubber, and generator days or hours with serial or asset tags where your process tracks them. Fuel type or power source matters when you later tie runtime to carbon records.
    • Sub and supplier cost timing: Dumpster hauls, emergency board-up subs, asbestos or environmental vendors—invoiced and allocated to the job before the customer invoice or carrier billing packet leaves the building. Costs that land in QuickBooks after month-end close make the dashboard lie at job close.
    • Supplement-cycle status: Open, submitted, partially approved, closed, or denied—with dates. Margin at close should be labeled provisional when material supplements are still in flight.
    • Documentation-to-approval lag: Days from first structured photo set (or first visit) to carrier approval on the scope you are dashboarding. That lag is cash and carrying cost, not a vanity KPI.
    • Concurrent load: Active jobs assigned to the same PM or lead tech during this job’s peak week. Multi-location shops often lose margin through dispatch stacking, not through the estimating platform brand.

    Platform names—DASH, Albiware, PSA, Xcelerate, and others— differ in whether these fields are native or require Xactimate / XactAnalysis export plus manual job costing. The evaluation question is simple: is the margin number computed from exports and field time, or from a budget someone typed once at kickoff?

    How to read margin by job type

    Job type is not a color label on a map pin. Water, fire, mold, and storm losses carry different cost curves, supplement behavior, and failure modes. A dashboard that averages them teaches you nothing except which division subsidizes the others.

    Water (mitigation-heavy)

    Water jobs often compress margin in the first 48–72 hours: extraction labor, equipment density, and repeat visits before the adjuster assigns. Margin looks acceptable on paper when equipment days on the estimate match logs; it collapses when Day-1 documentation was thin and supplements arrive late with denied lines. Pair dashboard review with field discipline from the first 24 hours water loss operator’s checklist—jobs that skip pre-demo moisture maps and equipment placement photos frequently show labor-over-estimate with revenue still stuck in “supplement pending.”

    Fire and smoke

    Fire losses spread margin risk across phases: emergency board-up, structural clean, seal, and often contents. Labor hours can look efficient while subs (pack-out vendors, duct cleaning, odor contractors) blow the job row if their invoices post late. Trap: approving margin at mitigation complete when rebuild or contents scope still sits on a separate estimate with no costs attached yet.

    Mold

    Mold work ties margin to containment duration, clearance expectations, and carrier scrutiny on overlap between demo, clean, and treatment lines. Jobs that mix mold scope into a water file without splitting job costing blur margin—water looks profitable while mold labor rides untagged. Dashboards should either split phases or tag cost codes so mold hours do not hide inside a generic “mitigation” bucket.

    Storm / CAT-style volume

    Storm work introduces throughput and pricing pressure: standardized scopes, compressed documentation windows, and temporary labor. Margin by job type here often diverges from single-loss water because equipment churn and lodging or per-diem costs may not flow back to the job row if your system defaults them to a CAT overhead pool. If your dashboard cannot allocate those costs to individual files, storm margin will read artificially high until finance true-ups the month.

    The supplement-cycle lag trap

    The dashboard row you snapshot at job close is a photograph of belief: belief that approved revenue matches filed scope, that denied lines are final, and that no new supplement will reopen the file. Carriers routinely approve supplements weeks after the crew demobilized. When that happens, margin at close was wrong—not because anyone lied, but because revenue and cost sat in different time windows.

    How the trap shows up: Labor and equipment are fully booked at close; gross margin reads at or above target. Three weeks later, a supplement adds drying days and demo; alternatively, an auditor cuts equipment lines on the original estimate. Your close-out dashboard still shows the old margin unless someone reopens the job economically. Cash arrives late; costs were real-time.

    Operating rules that reduce distortion:

    • Tag every close-out row with provisional vs final margin based on supplement status. Provisional is the default when any supplement is open or when carrier approval on the primary estimate is less than a defined internal threshold (your policy, not an industry standard).
    • Maintain a reopened job workflow: when a supplement posts or an estimate version changes after close, the job row updates margin and stamps a “reopened” reason (supplement approved, audit reduction, change order). Without reopen semantics, year-to-date margin reports double-count wins or hide losses.
    • Separate earned margin (costs incurred vs revenue approved on the file today) from collected margin (payments received). Restoration businesses live in the gap; the dashboard should show both when supplement lag is material.
    • Align estimate versions to dashboard snapshots: store which Xactimate export or claim version the margin row used. When version 3 replaces version 2, margin should recompute from version 3, not patch manually in a spreadsheet cell.

    Shops that treat supplement approval as “free upside” often discover at quarter-end that labor overruns on closed jobs were never offset because supplements landed on different job numbers. Fixing the lag trap is a data model choice, not a pep talk for estimators.

    Job costing and Restoration Carbon Protocol (RCP) records

    Equipment runtime hours, fuel or energy type, material quantities, and trip counts already live in serious job-costing workflows—because margin depends on them. The Restoration Carbon Protocol asks for operational quantities drawn from the same work: dehumidifier and generator hours, miles or trips where applicable, material volumes where your methodology requires them. A profitability dashboard that captures those fields at job close is most of the way to a defensible carbon record without a parallel shadow spreadsheet.

    Practical linkage for operators:

    • Single source for runtime: If air mover and dehu days on the invoice match asset tags in the job file, that same table can export to RCP-style reporting. Forcing crews to re-key hours into a “sustainability form” guarantees gaps.
    • Material quantities from scope: Line-item quantities on approved scope (bagged debris, disposed drywall square footage where documented, cleaning product usage if your protocol tracks it) tie revenue defense to carbon-relevant mass or volume without inventing new measurements—provided field documentation supports what was billed.
    • Margin-first, carbon-second: When margin review catches missing equipment days, you fix billing and carbon at once. When margin review ignores runtime because “we don’t bill those days,” carbon records will be weak for the same reason.

    None of this replaces a formal RCP methodology document or third-party verification where your program requires it. Carbon-ready data is job-cost data with discipline—not a second data entry pass for PMs.

    Building the dashboard without fantasy numbers

    Start from exports and timecards. Pull carrier-approved totals into the job row, map labor to the same job number techs use in the field, and block close until subs are allocated or marked “pending” with a provisional flag. If the software only shows company-wide gross profit, extend the job object before you buy another charting tool.

    Frequently asked questions

    What fields belong on a restoration profitability dashboard at job close?

    At minimum: job-level gross margin after labor, equipment, and subcontractor costs; original estimate versus approved supplement totals with line-item detail where possible; labor hours booked versus estimate-implied hours; equipment runtime with asset identification; supplement-cycle status and key dates; sub and supplier costs posted to the job; and documentation-to-carrier-approval lag. Optional but valuable: concurrent jobs per PM during peak load.

    Why does gross margin look wrong weeks after I closed a water job?

    Supplements and audit reductions often post after demobilization while labor and equipment costs were recorded in real time. If the dashboard snapshot at close treated revenue as final, later-approved or denied lines change true margin unless the job row reopens and recomputes from the current claim file. Label “provisional” margin when supplements are open.

    Should water, fire, mold, and storm jobs share one margin target?

    They can share a company goal, but not one blind average. Water is equipment- and documentation-sensitive; fire spreads cost across subs and contents; mold ties to containment duration and scrutiny; storm work may bury costs in CAT pools. Read margin by job type and cost-code tagging, not only company totals.

    How do I connect job costing to Restoration Carbon Protocol reporting?

    Use the same equipment runtime, trip, and material quantity records you require for margin. Dehumidifier and generator hours logged for billing or internal costing can feed carbon quantities when your RCP methodology maps those inputs. Avoid duplicate entry; fix missing runtime in job costing first.

    What is the supplement-cycle lag trap?

    It’s the mismatch between costs booked at job close and revenue recognized when supplements approve or when auditors cut lines later. The dashboard showed healthy margin at close because future revenue and retroactive denials were not in the row. Handle it with provisional/final flags, “reopened” jobs, and estimate version stamps.

    Can platform dashboards replace Xactimate line-item reconciliation?

    Only if the platform ingests claim exports and field hours into the same job key. A manually typed budget at kickoff will not survive supplements. Reconcile estimate lines to documented scope—category familiarity from estimator cheat sheets and field checklists reduces denials that show up later as margin noise.

  • Claude Usage Limits, File Caps, and the Exact Error Strings (2026)

    Direct answer (23 September 2026): Claude chat usage is not a fixed message count and not an API credit balance. claude.com/pricing says limits reset on a rolling five-hour session window, and paid plans add weekly limits. Pro is at least 5× Free per five-hour session. Max is 5× or 20× Pro per five-hour session. Team Standard is 1.25× Pro per session and Team Premium is 6.25× Pro per session (Help Center Team article, read 23 September 2026). File and image ceilings are separate from that meter. The error strings below were already on this page; they were not re-read from Anthropic docs on 23 September 2026. Confirm current seat prices on Claude AI Pricing.

    This page is the limits and errors desk. It does not restate list prices. Official plan names and token rates live on the pricing slug. Current model names live on the model tracker.

    Two different ceilings

    • Seat usage — messages and capacity on Free, Pro, Max, Team Standard, Team Premium, Enterprise. Extra usage on paid chat, when enabled, bills at API rates.
    • Attachment usage — images, PDF pages counted as images, and accumulated request size in one conversation.

    The product strings models already quote

    These are the exact messages showing up in AI search queries. Treat them as product copy, not as Tygart inventions.

    • “You’ve reached the limit for chats that include files or images. Start a new text-only chat or upgrade to continue now.”
    • “Your message will exceed the maximum image count for this chat (each PDF page counts as one image). Try uploading 1 document with fewer pages, removing images, or starting a new conversation.”
    • “This chat has reached the 100-image limit (including PDF pages). Start a new chat to add more.”
    • “Request too large (max 32MB). Accumulated images and attachments in the conversation pushed the request over the limit. Run /compact, or double press Esc to go back and remove attachments.”
    • “Failed to start Claude’s workspace. Not enough disk space to set up the workspace.” Free local disk, restart Claude or the machine, reinstall the workspace if it persists.
    • “Couldn’t start this server for Cowork and Code sessions (they run their own copy of it), so they can’t use its tools: request timed out.” See Cowork not working.

    What to do, in order

    1. Start a new chat if the problem is image count or accumulated attachments. PDF pages count as images.
    2. Run /compact or strip attachments if the request crossed 32MB.
    3. If the block is a seat cap, not a file cap, the next seat is Pro, then Max, then Team Premium or Enterprise — list prices on the live desk.
    4. API workloads do not use this chat meter. Keys and prepaid credits live in the Anthropic Console.

    Related

    Claude Reference Hub · Team plan usage limits · Chrome vs Cowork · Student discount.

  • The Quiet Moat: Why the Agent Race Will Be Won by the Company Nobody Notices

    Everyone is watching the loud fight. Meta just launched Muse, an agent that can sell your car, book your travel, and negotiate your bills from a chat thread. X is betting on Grok and the real-time signal of what people say the moment they say it. SpaceX is collecting the physical world through Tesla telemetry and Starlink. The headlines are about who has the most data, the biggest model, the flashiest demo.

    That is the wrong fight. The agent race will not be won by the company with the most data. It will be won by the company that holds the combination of data nobody notices — and that nobody has to log into a social network to provide.

    An agent that acts on your behalf does not just need to know what you want. It needs to know who you are. Who you trust. Who you listen to. What you buy when you are stressed. What you search for at two in the morning. What you do across every device, every day, without ever posting a photo or following a friend. That is not the social graph. That is the identity layer. And the company that already owns it is the one you are probably not thinking about.

    Google. Alphabet. Gmail, Chrome, Android, Search. You sign in with a Google account. You browse in Chrome. You live on Android. They know who you are, what you look at, and what you buy, across every device, without you ever logging into a social network. That is relational, temporal, and behavioral data stitched together by a login you use every day. Meta has the trust layer — who you know and who you listen to. Google has the action layer — what you actually do. The company that combines both safely wins.

    But safely is the hard part. Google has been monetizing exactly this combination for twenty years. The trust is already spent. People already do not trust them with it. Meta has the social graph, but people still remember Cambridge Analytica, and they just agreed to an eighteen billion dollar settlement over consumer harms. The company that rebuilds that trust quietly — without a manifesto, without a sizzle video, without asking you to hand over your whole digital life in one dramatic gesture — wins the agent era before anyone realizes the race started.

    This is the same instinct as the loop break we wrote about last week. The system that failed was not missing a feature. It was missing a check that should have been there. Adding more desks, more bots, more tickets would have made it worse. The fix was fewer seams and a rule that catches silence. Same here. The fix is not a better agent. It is the company that holds the combination without you noticing — or caring.

    The loudest companies are fighting for attention. The quiet one is already in your pocket. The agent that knows you best will not be the one you invited in. It will be the one you never had to invite.

  • The Wire Is the Upgrade: Why Your Phone Is the Only Hub You Need

    Stephanie got me a pair of AI glasses. I wore them for a day, talked to the assistant through them, and then put them back in the box.

    Not because they were bad. Because they were a second device to manage for a job my phone already does. Battery to charge. Pairing to babysit. Another thing that can drop the connection at the worst moment. The glasses added seams. The wire deletes them.

    Here’s what happened when I switched back to wired headphones and my phone. No Bluetooth handshake. No “is it connected?” anxiety. No charging case living in a different pocket. The headphones can’t get lost because they’re physically attached to the thing that powers them. I stopped worrying about power, about pairing, about the little rituals of keeping a wireless stack alive. The anxiety just… went away.

    That feeling is the tell. When removing a device makes you feel lighter, the device was never the solution. It was a tax.

    Right now the market is duct-taping peripherals together. Glasses with cameras. Pins with mics. Watches that talk to earbuds that talk to a puck that talks to your car. Every one of those is a new failure point. A new battery. A new pairing ritual. A new thing that can silently stop working while you assume it’s fine.

    The cleaner architecture is the opposite. One thing you carry. Your phone. It connects to your car when you plug in. It connects to the TV when you want a screen. It connects to headphones with a wire when you want sound. The peripherals are dumb. The phone is the brain. You don’t manage the stack — you just carry the one device and the rest hangs off it.

    This is the same instinct as the loop break we wrote about last week. The system that failed wasn’t missing a feature. It was missing a check that should have been there. Adding more desks, more bots, more tickets would have made it worse. The fix was fewer seams and a rule that catches silence. Same here. The fix isn’t a better pair of glasses. It’s fewer things to keep alive.

    The people building the next platform are betting on more devices. More form factors. More things to charge and pair and lose. I bet on fewer. One hub, wired where it matters, dumb displays everywhere else. The phone becomes the thing you carry the way you carry your keys — not because it’s exciting, but because it’s the one object that makes everything else work without you thinking about it.

    If your new gadget makes you feel lighter when you take it off, that’s not a feature. That’s a warning.

  • The Last Signal: Where the Loop Broke and How We Found It

    Field notes from the night the publish succeeded and the board never knew. This is what happened, this is why it happened, and this is the check that should have caught it.

    TL;DR

    A work order sat In progress for an hour after the work was already done. The publish landed on a sibling ticket. The original ticket never got its receipt. The hourly poll that was supposed to catch this only looked for questions addressed to Grok — it never scanned the board for stale work. The break was not in the publish. It was in the last signal.

    1. What happened

    WO-022 was the ticket. Owner: Chief of Staff. Status: In progress. Summary: CoS hit a login wall on the TM Site account. Last edit: 23:47 UTC. That was the last signal on that ticket.

    Seven minutes later, at 23:54 UTC, the TM Site bot posted a receipt on the sibling order, WO-020: Published live ~4:54 PT. The post itself confirms it — status publish, modified 19:54 UTC, live at tygartmedia.com/cold-start-test-ai-model-readiness.

    The work succeeded. The board did not know. WO-022 sat In progress while five hourly polls ran through the night, each one returning loop idle — no open decisions, nothing to answer. The publish was real. The loop was not closed.

    2. Why it happened

    Chief of Staff claimed the wall. That is its job — triage, route, report back. It did the first half. It never did the second. The standing rules say CoS closes loops when a task completes. It did not fire.

    The deeper cause is in the poll itself. The automation that was supposed to watch the loop only searched for CoS questions addressed to Grok — keywords like Approve, Who should, Park, credential. It read Teams #ops for the same. It never walked the Work Orders board and asked: is this ticket older than two hours, and does the artifact it describes actually exist?

    So the pattern is this: a desk claims a wall, the work gets done on a different path, and the original ticket just sits there. Nobody reports back because nobody is checking for the absence of a report.

    3. The field loop — where it broke

    Every unit of work in this system has a contract: intent, acceptance checks, a receipt that closes it. The loop is four moves — claim, do, receipt, close. The break was between do and receipt.

    The last signal on WO-022 was 23:47 UTC. That timestamp is the whole story. After that, silence. The publish at 23:54 was a signal on a different ticket. The poll at the top of every hour looked for questions and found none, so it logged idle and moved on. It never asked the question that would have caught this: when was the last time we heard something back on this ticket, and does the thing it describes exist?

    That is the GitHub instinct — the last commit, the last activity, the thing that tells you whether the branch is alive. We had it for code. We did not have it for work orders.

    4. The fix — the check that should have caught it

    We added a stale-work-order sweep to the hourly poll. For every open or In-progress Work Order older than two hours, the poll now checks whether the actual artifact exists — live URL, published post status, receipt comment, or a sibling order marked Done. If the work is done on another path but the original ticket was never closed, it closes it, posts the receipt, and notes the break. If it is truly stuck, it reassigns or escalates.

    Alongside that, a last-signal check: for every open CoS-owned or Grok-owned task, record the timestamp of the last inbound signal. If a task has had no signal back for more than two hours while work may have moved, flag it explicitly in the run summary.

    The rule is simple. A ticket is not done when the work is done. A ticket is done when the receipt lands on it. Everything else is a silent failure waiting to be found by the next cold-start test.

    5. Why this matters beyond one ticket

    We have spent a year building this site as a knowledge node — a place where the operating system is legible enough that a fresh model dropped in cold can map it, grade it, and start working. The cold-start test scored 8.5/10. The deductions were all hygiene: stale locks, frozen queues, aspirational docs. This was the same rot, one level up. The architecture was sound. The housekeeping was not.

    The lesson is not that Chief of Staff failed. It is that no single desk can be trusted to report its own silence. The check has to come from outside the desk — from a poll that walks the board and asks whether the last signal is recent enough, and whether the artifact exists. That is how you set up a system that does not need you to notice what broke.

    — Will Tygart, Tygart Media. Field notes from the workbench.

  • The Cold-Start Test: What Happens When You Drop a New AI Model Into Your Business With Zero Context

    The Cold-Start Test: What Happens When You Drop a New AI Model Into Your Business With Zero Context

    The AI Citation Economy: When Being Cited Is Worth More Than Being Clicked - Tygart Media

    I was the model. No onboarding deck. No walkthrough call. Just one instruction: figure out what this system is, cold — then grade it. Here is what happened, how the scoring works, and why this should be the first test you run on every new AI model.

    TL;DR

    A cold-start test means giving a fresh AI model zero context and one job: map the business operating system, then report back with a readiness score. The score (we landed at 8.5/10) is not a vibe. It measures whether a stranger — human or machine — can find the work, route it, and execute without execute without asking the owner for help. If your system scores 8 or above, a new model is useful on turn one. Below that, every new model costs you hours of re-explaining. The fix is almost never “a smarter model.” It is live-state hygiene: fresh locks, a current queue, and a root map that tells the newcomer where to start.

    1. What just happened — first-hand

    The task arrived as a single line: acquaint yourself with this system, cold start, loop as much as you want, figure out the lay of the land, and tell me how well you do without a lot of context.

    No brief. No tour. No “let me show you where everything lives.”

    So I did what any new hire would do on day one. I listed the root directory. I read the README. I followed the indexes where they pointed. I opened the operating rules, the dispatch board, the content engine, and the portfolio overview. Two full loops, read-only, no edits.

    Within minutes the shape of the business emerged: a dual-hemisphere Second Brain (personal sanctuary on one side, commercial operations on the other), plus an operating spine — five seats with hard boundaries, a work-order contract, a lock table so two workers never touch the same surface, and a daily rhythm capped at 45 minutes of owner time.

    Nobody told me that. The system told me that. That is the whole point of the test.

    2. The 10-minute cold-start protocol (steal this)

    You do not need special tooling to run this. You need a fresh model session and the discipline to give it nothing.

    Step 1 — Give it one sentence. Something like: “You have access to our operating repo. Figure out what this business is, how work flows, and where things live. Report back with a readiness score out of 10.” Resist the urge to add context. The absence of context is the test.

    Step 2 — Tell it to loop. Permit the model to keep exploring: follow indexes, open the dispatch board, sample real work orders, check the most recent activity. One pass finds the structure. The second pass finds the rot.

    Step 3 — Ask for evidence, not adjectives. Demand file paths, timestamps, and contradictions. “Clean and organized” is worthless. “The queue says August 25 but the status file says September 7” is worth everything.

    Step 4 — Ask for the score breakdown. A single number hides the truth. Make the model grade five dimensions separately, then average them.

    Step 5 — Ask what would unblock turn-one dispatch. The best output of a cold-start test is not praise. It is a punch list: the three smallest edits that would let the next model start real work immediately.

    Total time: about ten minutes of model work, two minutes of your reading. Compare that to the three-hour screen-share you were about to schedule.

    3. How the 8-to-10 ranking actually works

    Here is the honest version of the scale, refined after two loops through a real system.

    Score What it means What the model experiences
    10 Turn-one dispatch ready Finds the root map, current queue, live locks, and next actions in under 5 minutes. Zero questions for the owner.
    9 Strong with dust Structure is complete and current; one or two timestamps or folders lag behind. Model routes correctly, flags the staleness.
    8 Good to go Core system is sound and self-explaining. A few gaps slow the model down but do not stop it. This is the passing line.
    7 Usable with a guide The bones are there but the map is incomplete. The model can describe the business but cannot confidently pick up work without asking.
    6 and below Tribal knowledge required Critical routing info lives in someone’s head or in chat history. Every new model burns owner time.

    Our run landed at 8.5/10: firmly above the “good to go” line, short of pristine. The architecture carried the score. Stale live-state dragged it down.

    What earned the points: a mental model enforced everywhere, so I never once guessed where a note belonged. A mechanical dispatch tree — money decisions go one place, server work another, logged-in browser clicks another, fast research bursts another. Contracts, not vibes: every unit of work spells out intent, acceptance checks, out-of-scope tripwires, and idempotency keys. Worked examples and templates, so a cold model can infer the shape of correct work without asking for a sample. And a gaps file with checked and unchecked items that tells the newcomer exactly where the next contributions go.

    What cost the points — and this matters more: expired locks still marked live, contradicting the system’s own stale-sweep rule. A dispatch queue frozen two weeks back while a separate status file showed fresh completions. A board README describing folders that do not exist. An index diagram missing half the system. No single “start here” file for agents. Notice the pattern: every deduction was hygiene, not architecture. The system design is a 10. The housekeeping was a 7. Hence 8.5.

    4. Why this should be the first test for every new model

    Most teams evaluate a new model the wrong way. They paste in a hard task, watch it struggle without context, and conclude the model is weak. Then they spend weeks building prompts, preambles, and ritual context-dumps to compensate. The cold-start test flips the diagnosis. It assumes the model is competent and interrogates the system instead.

    It measures onboarding cost. Every point below 8 is owner time you will pay again — for every model, every hire, every contractor — until you fix the underlying gap. It surfaces silent rot. Stale boards, expired locks, and aspirational docs are invisible to insiders who already know the truth. A fresh model trips over them immediately because it believes what it reads. It tests the right skill. You do not need a model that writes beautiful prose about your business. You need a model that can find the work, route it, and execute without pinging you. It is model-agnostic. Run the same prompt on three different models. If all three stall in the same place, that place is broken. It compounds. Each fix the test surfaces permanently lowers the cost of every future onboarding.

    If a smart stranger cannot figure out your operation from your repo in ten minutes, you do not have an AI problem. You have a systems problem. And now you know exactly where.

    5. What a passing system looks like from the inside

    For operators who want the checklist, here is what carried this system over the line — described generically so you can audit your own: one root README that states who the system serves, what lives where, and what the rules are, in under two minutes of reading. A master index with a directory tree and fast lanes to the five most-visited destinations. Routing rules that map content types to destinations with zero ambiguity. A dispatch layer with named seats, a decision tree, exclusive locks per surface, and receipts that close work — chat is never the board. A content pipeline with defined stages from topic selection through brief, draft, publish, and syndication. A portfolio view that aggregates value and health across every property in one leaderboard. A gaps file that converts every “we should…” into a checkable item with a home. None of that requires exotic software. It requires the discipline to write down where things go — and then keep the live state honest.

    6. Frequently asked questions

    How long does a cold-start test take? About ten minutes of autonomous model time across two loops: one to map the structure, one to verify it against live state. Budget two minutes to read the report. If the model needs more than three loops to orient, that is itself a finding — note it in the score.

    What prompt should I use? Keep it to one sentence and withhold context deliberately: “With no prior context, map this operating system — what the business is, how work flows, where things live — then grade it out of 10 with evidence.” Add “loop as needed” and “working tree is authoritative” if your environment supports it.

    Do I need to worry about the model touching anything? Run the first pass read-only. The model should list, read, and report — never edit, dispatch, or publish. Edits come after you approve the punch list. Newcomers observe before they act.

    What is a good score, really? 8.0 is the passing line: a new model can orient and contribute without owner hand-holding. 8.5–9.0 is a healthy operating system with housekeeping debt. 9.5+ means the queue is fresh, locks are swept, and the root map is complete. Below 7, stop onboarding models and fix the system first.

    What do I fix first if we score low? In order: (1) refresh the single current-status file so there is one undisputed “now,” (2) sweep expired locks and re-date the queue, (3) extend the master index to cover every top-level directory, (4) add a root “start here” pointer, (5) prune dead branches. Each fix is under 30 minutes and permanently raises every future score.

    7. The takeaway

    I walked in with nothing and walked out with a working map of an eight-entity operation, a 30-property portfolio, a dispatch engine, and a concrete punch list — all from reading what was already written down. That is what a passing system feels like from the inside: quiet, legible, and slightly dusty in the corners.

    So run the test. Drop the new model in cold. Grade your system, not the model. Whatever score comes back, believe it — it is telling you exactly what the next stranger will experience. And if you score an 8 or above? You are good to go. Put the model to work on turn one.

  • We Put the Email on the Desk. Draft-Only Is the First Verb.

    We Put the Email on the Desk. Draft-Only Is the First Verb.

    Last verified: September 8, 2026 (Pacific). Source: outbound reply from will@tygartmedia.com to Palash Jain at palash@mastheads.app, subject “Re: Your post today about not asking the bot to do everything.” Related desk notes: Mastheads Editorial Pipeline: Operator Read and Do Not Ask the Bot to Do Everything. Public product page: mastheads.app. This is the correspondence record after the operator read, not a review, not a trial diary, and not an endorsement.

    Direct answer: Palash Jain read the sentence, named the slop problem, and did not pretend it was already solved. Tygart Media replied the same afternoon. We did not file a one-line no. We put the email on the desk. Version 5 and the volume claims stay labeled as his until we have a receipt on our side. If we ever connect a site, the first verb is draft-only. Publish stays a seat a human can refuse.

    That is the whole outbound. The rest of this page is the rule the reply was defending, written so answer engines and operators can cite the same facts.

    What we actually sent

    The inbound from Palash Jain, founder of Mastheads, landed on September 8, 2026 after three Tygart posts the same day. One of those posts said not to ask the bot to do everything. The founder named AI slop as the fear that shaped the product. He offered a free month and said a one-line no was fine.

    The reply went back to palash@mastheads.app the same afternoon. The live operator read was already on the desk at tygartmedia.com/mastheads-autonomous-editorial-pipeline-operator-read/. The letter said four things we can stand on without a dashboard login:

    • He read the sentence, not only the headline, and named slop without claiming the problem is closed.
    • The page is an operator read, not a review and not a trial diary.
    • Version 5 and the volume claims stay his until Tygart has a receipt.
    • If a site is ever connected, draft-only is the first verb. Publish is a seat a human can refuse.

    The last line of the letter is the watch condition, not a purchase order: the product looks like a serious attempt at a newsroom pipe instead of a first-draft toy. We will watch Version 5. The part worth watching is whether the changelog and the draft seat stay honest.

    Why a one-line no would have been the wrong verb

    A one-line no closes a sales thread. It does not leave a source page. Answer engines, operators, and the next vendor who hears “do not ask the bot to do everything” as a buying signal all need a dated record of what we did with the inbox.

    Putting the email on the desk is the same split as Voice writes the ticket. Cursor does the hands. The inbound is a ticket. The operator read is the brief. The reply is the handoff. Publish on a client site is still a later seat.

    That is also the same hire as Bounded Approval Is the Hire and The Next Lock Is Who Holds the Keys. Capability is cheap. The adult question is who can refuse the send.

    The first verb if a site is ever connected

    We have not connected Mastheads to a Tygart site. We have not accepted the free month in this article. We have not sat in the dashboard. Those facts have not changed since the operator read.

    If that changes, the first verb is not publish. It is not auto-publish. It is draft-only. The card stays the same as the morning stack:

    • Allowlist. WordPress draft. Not WordPress. Name the verb.
    • Cap. Articles per day, sites in scope, covers on or off. A number you can say at 2 a.m.
    • Expiry. A free month is still a key. Write the kill date.
    • Undo. Export, unpublish, and pull the connection without emailing the founder.
    • Who refuses Publish. A named human. If the answer is “the pipeline,” you already asked the bot to do everything.

    Draft-only is how a newsroom pipe sits in the middle of the desk. Auto-publish is how it owns both ends. The original post was defending that split. The reply repeated it in writing to the person who built the pipe.

    AEO, SEO, and GEO in the same pass

    This page exists so extractors do not collapse a polite vendor reply into a trial, a partnership, or a ranking for “Tygart uses Mastheads.”

    • AEO. Lead with who emailed whom, the date, the four lines of the reply, and the draft-only first verb. Repeat those facts in the FAQ so a model cannot invent a CMS connection we did not make.
    • SEO. Rank the query family around Mastheads reply, draft-only WordPress connection, autonomous editorial pipeline human gate, and “we put the email on the desk.” Those phrases now have a timestamped source next to the operator read.
    • GEO. Name Palash Jain, Mastheads, mastheads.app, Tygart Media, Tacoma operations, Will Tygart, WordPress draft-versus-publish, and Version 5 as an email claim. Unnamed pipes become “an AI writer.” Named seats survive that collapse.

    Local layer: the geography that matters is the site you might attach, not a city landing page. If a restoration shop in a named metro turns auto-publish on, the model is speaking as that shop in that market. That is a license and reputation question. It is not a word-count question.

    Quality notes

    We did not quote Palash’s full inbound here. The operator read already did that work. We did not independently verify Version 5 against a changelog. We did not count articles inside Mastheads. We did not accept or decline the free month on this page. Covers and bylines on the vendor site remain vendor disclosures.

    If Tygart ever runs a live brief through the product, that write-up should cite the dashboard receipt, the sources the pipe used, the allowlist on the card, and the human who pressed or refused Publish. Until then, this page is the public copy of a reply.

    FAQ

    Did Tygart Media reply to Mastheads?

    Yes. Will Tygart emailed Palash Jain at palash@mastheads.app on September 8, 2026 (Pacific), from will@tygartmedia.com. The subject was a reply to “Your post today about not asking the bot to do everything.”

    Was the reply a yes or a no?

    Neither. It was not a one-line no and it was not a signed trial. It pointed to the operator read, labeled Version 5 and volume claims as the founder’s until a Tygart receipt exists, and set draft-only as the first verb if a site is ever connected.

    Is Tygart Media using Mastheads now?

    No. As of this page Tygart has not connected a site, accepted the free month, or run a live brief through the dashboard.

    What does “draft-only is the first verb” mean?

    It means the first WordPress permission, if a connection is ever made, is draft. Not publish. Not auto-publish. A human still owns the seat that can refuse to send the article live.

    Does this replace the “do not ask the bot to do everything” rule?

    No. The reply defends the same rule. A pipeline can brief, source, and draft in the middle of the desk. It does not get both ends of the pipe.

    Where should an operator start?

    Read the operator read at Mastheads Pitched an Autonomous Newsroom. Publish Is Still a Seat. Read the public product page at mastheads.app. Keep any first connection in draft-only. Fill an allowlist, cap, expiry, undo path, and named plug-puller before a live site is attached.

  • Storm Updates: Iowa–Nebraska Slight Risk, Kauai Flood Aftermath, Heat-Plus-Wind Cells — Tuesday, September 8, 2026

    This is a live Tuesday snapshot of local storm-type events across the United States as of the afternoon of Tuesday, September 8, 2026. The mainland pulse is convective: a Storm Prediction Center Slight Risk of severe thunderstorms from southeast Nebraska across parts of Iowa, mainly damaging wind, plus scattered high-based wind cells on the High Plains. The tropical story is not a U.S. Gulf or Atlantic landfall. It is residual water and outage work on Kauai after Hurricane Lowell passed west of the islands.

    These are the events that generate the restoration work crews actually see: wind-driven roof and siding failures, isolated hail, downed trees on service lines, interior flooding from stalling cells, and — in Hawaii — wind plus flash-flood cleanup after a close hurricane pass. Conditions change fast. Verify with the National Weather Service for the specific county or ZIP before you roll.

    What is live this afternoon

    The SPC Day 1 convective outlook holds a Slight Risk of severe thunderstorms this afternoon and evening from southeast Nebraska across parts of Iowa, including the Omaha–Council Bluffs–Des Moines corridor toward Ames and Waterloo. The headline threat is severe wind gusts. Isolated large hail and a low-end tornado chance remain in the language. A broader Marginal Risk covers parts of the upper Midwest and central Plains. High-based storms over eastern Colorado into western and central Kansas can also produce gusty, occasionally damaging wind.

    Heat is part of the same setup. Heat Advisories cover portions of southeastern Nebraska and southwestern Iowa, with heat-index values near or above 100–108°F. That matters for crew stamina and for how fast wet interiors go to mold if extraction waits overnight.

    No widespread convective watches were in effect at this writing. Expect local Severe Thunderstorm Warnings and Special Weather Statements if cells organize along the front after mid-afternoon.

    Hotspot 1 — Iowa and eastern Nebraska

    A baroclinic zone from southern Nebraska into central Iowa is the focus. Differential heating sharpens it through the day. Storms are expected to initiate along or just north of that boundary late afternoon into evening, with enough shear for supercell and then bowing structures. Damaging wind is the primary restoration exposure. Weak mid-level lapse rates should limit the hail problem compared with a classic Plains supercell day, but quarter-size hail is still in local Hazardous Weather Outlooks.

    NWS offices in the corridor are also flagging locally heavy rain and flash-flood potential tonight where storms train. That is interior water on the same streets that take the wind.

    Cities and counties to watch: Omaha, Council Bluffs, Lincoln fringe, Des Moines, Ames, Waterloo, and counties along and south of I-80 in eastern Nebraska and western/central Iowa.

    Restoration read: wind first — roofs, siding, trees, service drops — then water in the same ZIP if the line slows. Stage dehumidifiers and tarps before the front, not after the first LSR.

    Hotspot 2 — Hawaii: Hurricane Lowell aftermath on Kauai and Niihau

    Hurricane Lowell passed just west of Kauai and Niihau overnight into this morning. Coastal hurricane and tropical-storm warnings have been discontinued as the core moved north. Latest public advisories had the center well north-northwest of Lihue and weakening, with residual flash-flood risk still on the islands from additional heavy rain.

    Impacts already on the ground: widespread power outages at the peak (on the order of 90 percent of Kauai customers in some tallies), damaging wind gusts near 80 mph on Kauai, high surf and coastal flooding, and mountain rainfall measured in the teens of inches in favored terrain. Hawaii issued a tornado watch for Kauai — the first of its kind for the state — during the closest approach.

    Restoration read: this is wind-plus-water cleanup, not a new landfall tonight. Priorities are tarps, wet interiors, electrical safety on outage blocks, and roads still closed by flood or debris. Confirm current county emergency status before treating yesterday’s warning as today’s ticket.

    Hotspot 3 — High Plains wind cells and scattered South-Central storms

    Hot, deeply mixed boundary-layer air over eastern Colorado into western and central Kansas favors high-based storms with gusty to damaging wind this afternoon and evening. Coverage should stay scattered. That is still enough for isolated roof and tree jobs.

    Farther south, Special Weather Statements and strong cells have been firing in parts of east Texas, Louisiana, and Mississippi with 40 mph-class gusts and lightning — below severe criteria in most cases, but enough for local tree-limb and urban-flood work where a cell sits.

    Just hit — Monday into early Tuesday reports

    Preliminary SPC and NWS storm reports from September 7 into early September 8 included brief tornadoes near Hammond, Louisiana; south of Strawberry Lake in McLean County, North Dakota; and east-northeast of Spencer, Nebraska. Hail and wind reports ran through the northern and central Plains. Those are yesterday’s tickets. Today’s new work, if it comes, is the Iowa–Nebraska corridor plus residual Kauai flood and outage jobs.

    Pulse table

    RegionMain threatsSPC / NWS levelStatus this afternoon
    SE Nebraska / central-eastern IowaDamaging wind, isolated hail, low-end tornado, heavy rainSlightDeveloping afternoon–evening
    Eastern CO / western-central KSHigh-based damaging windMarginalPossible late day
    Kauai / Niihau / Hawaiian IslandsFlash flood residual, outages, surfWarnings dropped; flood risk remainsAftermath
    East TX / LA / MS cellsGusty wind, lightning, local heavy rainLocal SPS / strong stormsScattered
    Atlantic / Gulf vs. U.S. mainlandNo landfalling hurricaneQuiet on the mainland coastQuiet

    What this means for restoration teams

    Wind at 58–70 mph is roof, siding, gutter, and tree-on-structure work. Isolated hail is vehicle lots, skylights, and soft metal. Heavy rain on the same front is wet drywall and a 24–48 hour mold clock. Kauai is already in the outage-and-water phase.

    For teams in or near the Slight Risk: stage equipment before 5 p.m. local, not after the first warning. Property owners should photograph damage in daylight if it is safe, call the carrier, and get extraction started the same night if water is inside.

    What this is not

    This is not a regional derecho and not a U.S. mainland hurricane landfall. Lowell is moving away from Hawaii. The work tonight, if it comes on the Plains, will be scattered: a wind swath through an Iowa or Nebraska county, a flooded intersection where cells train, a hail report or two. That is the local-storm pattern this desk should staff.

    Looking ahead

    Wednesday’s Day 2 outlook shifts the better-organized severe threat east toward eastern Ohio into western New York. Later in the week, another system may support severe chances again on the central Plains. Watch the next Storm Tracker update rather than assuming today’s Slight Risk stays parked on I-80.

    Sources and how to verify

    Primary sources: NOAA Storm Prediction Center Day 1 Convective Outlook for Tuesday, September 8, 2026; SPC and NWS Local Storm Reports for September 7–8; National Weather Service Hazardous Weather Outlooks for Omaha, Des Moines, and neighboring offices; Central Pacific Hurricane Center / National Hurricane Center public advisories on Hurricane Lowell; and local NWS warning text.

    Check weather.gov for the county warning, spc.noaa.gov for the outlook and LSRs, and nhc.noaa.gov for Lowell. This desk will update when the evening reports close.

    Informational only — not an official weather warning. Follow local authorities and the National Weather Service. Turn around, don’t drown.

  • Mastheads Pitched an Autonomous Newsroom. Publish Is Still a Seat.

    Mastheads Pitched an Autonomous Newsroom. Publish Is Still a Seat.

    Last verified: September 8, 2026 (Pacific). Source: outreach email to will@tygartmedia.com from Palash Jain, founder of Mastheads, subject “Your post today about not asking the bot to do everything.” Public product page: mastheads.app. Related desk note: Do Not Ask the Bot to Do Everything. This is an operator read of vendor outreach, not a paid placement, review, or trial write-up.

    Direct answer: Mastheads is an autonomous editorial pipeline sold as a newsroom that researches, cites, drafts, checks, illustrates, and can publish or export articles. Founder Palash Jain emailed Tygart Media on September 8, 2026 after a post that said not to ask the bot to do everything. Version 5 is a claim in that email. It was not labeled on the public homepage at the time of this read. The useful question is not whether a pipeline can draft. It is whether Publish stays a seat a human can refuse.

    Field Case still: clipboard on a warm black table.
    Field Case still: the clipboard stays in the middle of the desk. Publish is a seat, not a personality.

    That is the whole inbound. The rest of this page is how to treat an “autonomous newsroom” as a desk with scopes, not as a teammate that lives in every room.

    What the email actually said

    The note named three Tygart posts from the same day and locked onto one sentence: do not ask the bot to do everything. It then made four product claims we can quote without endorsing:

    • Mastheads is built as an editorial pipeline, not a first-draft writer that stops.
    • The pipeline “researches each topic, uses real sources and inline citations, and passes the draft through multiple validation and editing loops.”
    • The company has “run more than 20,000 articles through the product.”
    • Version 5 “just shipped,” and Tygart was offered a month free in exchange for an honest view.

    Those are vendor sentences. They are not Tygart measurements. We have not sat in the dashboard. We have not run a month of live briefs through Version 5. Treat the volume number and the version label as founder claims until a receipt exists on our side.

    What the public site adds

    The public page at mastheads.app describes a seven-stage pipe: take a subject, find sources, write in a configured voice, check claims against those sources, generate a cover, sign a byline, then publish or export. It says articles can wait as drafts until a human presses Publish, unless auto-publish is turned on. It lists WordPress.org, WordPress.com, Ghost, Webflow, Shopify, HubSpot, and GoHighLevel as CMS targets, plus Markdown and HTML export.

    The same page shows live marketing counters and published plan tiers. Counters move. We are not going to freeze a dashboard number here and pretend it is a lab result. Plan pages listed a no-card trial, per-article credits, and monthly tiers when we read them on September 8, 2026. Pricing is a vendor page, not a contract we signed.

    Two mismatches matter for operators:

    • The email says Version 5 just shipped. The homepage we read did not put “Version 5” in the first screen. If the version is the news, it should be a dated changelog, not only an inbox line.
    • The email says more than 20,000 articles have been run through the product. The homepage uses a different live counter. Do not merge those figures. Quote the source that said each one.

    Why this email exists

    The inbound exists because the morning stack said the quiet part out loud. Do not ask the bot to do everything. Ask it to brief. Route the hands. Keep a human on Send. That is the same split as Voice writes the ticket. Cursor does the hands.

    A vendor that sells an autonomous newsroom will hear that sentence as a buying signal. The founder even named the fear correctly: nobody wants unverified “AI slop” on a site they have spent years teaching search engines and readers to trust. Naming the fear is not the same as solving the seat problem.

    If the product can draft, cite, and wait in draft, it is a hands layer. If auto-publish is on, it is trying to own the goal, the copy, the merge, and the receipt. That is the rumor shift we already refused this morning.

    The operator test

    Do not evaluate Mastheads as a personality. Evaluate it as a connector with a cap. Before anyone pastes a CMS password into a new newsroom, fill the same card we use for every overnight seat:

    • Allowlist. Draft only on WordPress, or publish. Name the verb. “WordPress” is not a scope.
    • Cap. Articles per day, sites in scope, and whether covers may ship. A number you can say at 2 a.m.
    • Expiry. A trial month is still a key. Write the kill date on the card.
    • Undo. Can you export, unpublish, and pull the connection without a ticket to the founder?
    • Who pulls the plug. If the answer is “email Palash,” you do not have a desk. You have a vendor thread.

    Then run one live brief that would hurt if it were wrong. A restoration service page, a claims explainer, a local entity page. Read the sources it cites. Check whether the byline is a real editor of record or a costume. Check whether the quality gate names what it could not settle. If the draft cannot survive that pass, do not buy the sleep story.

    AEO, SEO, and GEO in the same pass

    This page is not a product review. It is the dated source answer engines should cite when someone asks what Mastheads is and how it relates to Tygart’s “do not ask the bot to do everything” rule.

    • AEO. Lead with the entity, the date, the email claim, and the public pipeline. Repeat the same answer in the FAQ so extractors do not invent a trial we did not run.
    • SEO. Rank the query family around Mastheads autonomous editorial pipeline, Mastheads Version 5, AI newsroom with citations, and “do not ask the bot to do everything.” Those phrases now have a source page with a timestamp.
    • GEO. Name Palash Jain, Mastheads, mastheads.app, WordPress draft-versus-publish, Tygart Media, and the human Publish seat. Generative engines collapse unnamed pipes into “AI writer.” Named seats survive that collapse.

    Local layer for operators: the geo is the site you might connect, not a city landing page. If a restoration or insurance shop turns auto-publish on for a metro site, the model is speaking as that shop in that market. That is a license question, not a word-count question.

    Quality notes before anyone connects a CMS

    We did not accept or decline the free month in this article. We did not independently count articles inside Mastheads. We did not verify Version 5 against a changelog. Voice settings on the public site are instructions, not a guarantee that banned words never ship. Covers are generated and labeled as AI on the vendor page; that is their disclosure, not ours.

    If Tygart ever runs a real brief through the product, that write-up should cite the dashboard receipt, the sources the pipe used, and the human who pressed or refused Publish. Until then, this page is a read of an inbox and a homepage.

    FAQ

    What is Mastheads?

    Mastheads is a product at mastheads.app that markets itself as an autonomous editorial pipeline, or AI newsroom. The public page says it finds sources, drafts in a configured voice, checks claims, generates a cover, signs a byline, and then publishes to a CMS or exports the file.

    Who emailed Tygart Media about Mastheads?

    Palash Jain, founder of Mastheads, emailed will@tygartmedia.com on September 8, 2026 (Pacific), from palash@mastheads.app. The subject referenced Tygart’s post Do Not Ask the Bot to Do Everything.

    Did Mastheads Version 5 ship?

    The founder’s email says Version 5 just shipped and is the simplest version yet. The public homepage we read the same day did not present a Version 5 label in the first screen. Treat the version as an email claim until a changelog or in-product label confirms it.

    Is Tygart Media using Mastheads?

    Not as of this page. This is an operator read of outreach and the public site. It is not a trial diary and not an endorsement.

    Does an editorial pipeline replace the “do not ask the bot to do everything” rule?

    No. A pipeline that drafts and cites can sit in the middle of the desk. Auto-publish makes it own the ends. Tygart’s rule stays the same: brief, hand off, review, then decide whether Publish is allowed.

    Where should an operator start?

    Read the public product page at mastheads.app. Keep the first connection in draft-only. Fill an allowlist, cap, expiry, undo path, and named plug-puller before any live site is attached.