Author: Will Tygart

  • Belfair Lodging Guide: Where to Stay on Hood Canal

    Belfair Lodging Guide: Where to Stay on Hood Canal

    Belfair sits right at the head of Hood Canal, where the long fishhook of saltwater finally runs out of room and turns into the shallow, muddy, eagle-haunted flats of Lynch Cove. This is the top of the canal, not the Great Bend – that elbow is down at Union, a different stretch with a different crowd. Up here the water goes warm and skinny on a summer afternoon, the tide pulls way back over the oyster ground, and the towns stay small: Belfair on the highway, Allyn over on Case Inlet, Tahuya out the north shore, Grapeview tucked off on its own. It is working-forest, shellfish, and shipyard-commute country more than resort country, and the lodging follows suit.

    So set your expectations the right way. You will not find a row of brand-name hotels here. What you get instead is a handful of honest options: one practical in-town motel for a work trip or a quick overnight, a cluster of Washington State Parks and DNR campgrounds for tents, RVs, and a few cabins, a couple of small seasonal waterfront resorts and marinas, and a growing list of whole-house vacation rentals strung along the saltwater. This guide walks all of them, grouped so you can find your kind of stay fast, tells you who each place is really for and the best season to go, and then points you at the live booking pages and search tools so you are always looking at current rooms and rates – not a stale screenshot.

    One housekeeping note that locals care about: if you are coming for a Puget Sound Naval Shipyard interview or an early Bremerton ferry, Belfair is your friend. You sleep at small-town North Mason prices and you are a short, easy run north to the shipyard gates in the morning. More on that below.

    In-town motel: the practical overnight

    When you do not need a view – you need a clean bed, free parking at the door, and a short drive in the morning – this is the category. It is the room a local books for a cousin who is in town to work, not to vacation.

    Belfair Motel

    The Belfair Motel is the straightforward, in-town option: a locally run, single-story motel sitting right on SR-3 (Highway 3) as you roll through the middle of town. No water view, no resort frills – just clean, updated rooms with comfortable beds, refrigerators, and Keurig coffee makers, plus a well-lit lot and free parking. Think of it as the practical pick rather than the destination.

    It is built for people who need a reliable bed more than an experience – someone driving in for a shipyard interview, a one-night stopover, or a budget-minded base camp. It is pet friendly, which matters if the dog is along. From here you are minutes from the Theler Wetlands trails, the shops and food along Highway 3, and the head of Hood Canal at Lynch Cove, with Belfair State Park a short drive south. Best window is late spring through early fall, when the canal, the wetlands, and the parks are at their peak, but for a work stay this room does the job any month. Book direct for current rooms and rates: belfairmotel.com.

    State parks and public campgrounds

    The public land is the real anchor at this end of the canal. Two Washington State Parks sit on warm saltwater beaches, and the Tahuya State Forest behind town is laced with trails and DNR camps. These are campgrounds and day-use parks, not resorts – expect picnic shelters, busy summer weekends, and rules to follow – but they put you right on the water or right on the trail for very little money. Day-use at the state parks needs a Discover Pass; campsites and cabins book ahead, and summer weekends go fast, so reserve early.

    Belfair State Park (cabins and campground)

    This is the public anchor at the very head of Hood Canal, sitting on the Lynch Cove tide flats a few miles southwest of Belfair. It is a Washington State Park, which means a real campground – primitive, standard, and full-hookup sites – plus a handful of simple rentable cabins if you want a roof and a locking door instead of a tent. The draw is the saltwater: a long, shallow swimming and wading beach that warms up on a sunny afternoon, a spit and tide flats for beach walking, and seasonal clamming and oyster picking when the canal is open.

    It is built for families and weekend campers more than for anyone chasing quiet luxury – expect kids, picnic shelters, and a busy summer. The heated cabins lock up tight and stay open year-round, which also makes this an easy, cheap off-season base when the storms roll in. Best window is late spring through early fall for the beach, but always check the current shellfish season before you count on digging dinner. Reserve sites and cabins through the official Washington State Parks system.

    Twanoh State Park (campground)

    Twanoh is a Washington State Park, not a resort, so set expectations accordingly: this is a Civilian Conservation Corps-era day-use and camping park on the south shore of Hood Canal, about eight miles west of Belfair on Highway 106. It sits on one of the warmest saltwater beaches in the state, which is the whole point. Come for wading, swimming, and shellfishing; the tide flats here are a reliable spot to dig clams and gather oysters in season, license required and shuck-on-the-beach rules in force.

    The campground is modest and old-school, a mix of standard tent sites and full-hookup spots tucked under big timber, plus a couple of kitchen shelters for groups. Best window is mid-summer, when the water actually warms up and reservations open; spring and fall are quieter but cooler, and winter is first-come with limited water. A note worth checking before you load the car: this park has restoration work scheduled, so confirm current closures and dates through the official Washington State Parks system first.

    Tahuya River Horse Camp (DNR)

    This is a state-run horse camp, not a resort, tucked into the Tahuya State Forest west of Belfair off the Belfair-Tahuya Road. The Department of Natural Resources runs it for one job: getting riders and their stock onto the trails. Sites come with corrals, fire rings, picnic tables, and potable water, and they are sized to take a decent trailer, so it is built for people hauling horses rather than tent campers looking for a view.

    From here you can reach the Tahuya River Trail and tie into the wider network that threads this forest, which is the real draw. Note that the campground itself is non-motorized, so it suits horse folks and quiet trail users more than the ORV crowd. Sites are first-come, first-served and you will need a Discover Pass on the dash. Best window is late spring through early fall, when DNR opens drive-in access on weekends from Memorial Day to Labor Day. Check the official DNR Green Mountain-Tahuya page before you load up, since access and conditions shift by season.

    Waterfront resorts, marinas, and glamping

    These are the small, mostly seasonal places that put you on the water without renting a whole house. Think simple cottages and park models, RV rows, a boat launch and moorage, kayaks downstairs, or a stocked glamping tent at a trailhead. None of them are polished hotels, and that is exactly the appeal – they are unfussy basecamps for boaters, anglers, paddlers, and riders.

    Summertide Resort and Marina

    Drive the North Shore Road out of Belfair, hug the waterline for a while, and you land at Summertide Resort and Marina in Tahuya. This is a small, seasonal place right on Hood Canal, not a polished hotel, and that is the appeal. The lineup is straightforward: a handful of cottages and park models with full kitchens and water views, an RV row, tent sites, plus the working stuff that makes a canal trip easy – a boat launch, moorage, and a general store for the bag of ice you forgot.

    It suits families and small groups who want an unfussy base on the water, and it earns its keep with boaters and anglers who need a ramp, a slip, and a beach to set crab pots from. Come in summer, when the canal warms up for swimming and the shrimp and crab seasons draw people to this end of the water. Check current cottage and RV availability and book direct on their official site.

    Tahuya Adventure Resort

    This is a campground built for people who came to ride. Tucked into the heart of the Tahuya State Forest, a short hop up the north shore from Belfair, it sits right at the doorstep of the Tahuya off-road vehicle park and its big web of trails. You can pick your comfort level: stocked glamping tents with real beds and a stove if you want a roof and a soft landing, full-hookup pull-through sites for the RV, or plain tent sites if you are happy with a fire ring and the trees. A covered camp kitchen ties the place together for groups.

    The crowd skews ORV, dirt bike, mountain bike, and horse, and the trailhead access is the whole point – though Twanoh State Park and the canal shoreline are close enough for a swim or a fishing afternoon. Summer is prime for riding and water; spring and fall trade heat for quieter trails. Check current rates and dates on their booking page before you load the trailer: tahuyaresort.com.

    Allyn House Inn (and North Bay Kayaks)

    This is waterfront lodging in the small town of Allyn, set right on the North Bay of Case Inlet near the head of Hood Canal. It is not a resort and it is not a chain motel; it is a handful of self-contained, apartment-style units a short walk from the Allyn waterfront, the dock, and a cluster of local eateries. The draw is the same family running North Bay Kayaks downstairs, so you can roll out of bed, grab a rental or book a guided paddle, and be on the water in minutes.

    It suits couples and small families who want a quiet base on the saltwater without fussing with a big property, and paddlers who want lodging and boats in one stop. Nearby you have Allyn’s waterfront park, easy launches into the protected bay, and the back roads toward Grapeview and Tahuya. Late spring through early fall is the sweet spot, when the inlet calms down, shorebirds work the tide flats, and the paddling is at its best. Check current units and rates on their official site.

    Waterfront vacation homes (whole-house rentals)

    This is the category that has grown the most around Belfair: rent the whole place, get your own stretch of beach, spread out, and cook for the group. These are owner-run houses, not resorts with a front desk, so they range from a tidy three-bedroom cottage to a five-bedroom reunion house. The common thread is private shoreline at the quiet head of the canal – bring kayaks, watch for eagles, and plan your days around the tide. Listings change hands and rates shift, so always confirm on the live booking page.

    Sunrise Canal (waterfront cottage)

    Sunrise Canal is a single owner-run vacation cottage on Belfair’s north shore, sitting right on the saltwater up at the quiet head of Hood Canal. This is a whole-house rental, not a room or a resort – a remodeled three-bedroom place with its own beach access, a stocked kitchen, water views from the living space, and a fire pit out back for the evening. It suits families or a couple of households who want their own waterfront base rather than a hotel hallway, with enough room to spread out and a stretch of shoreline to call your own for the stay.

    You are close to the good stuff without being on top of it. Belfair State Park is about ten minutes off, the Theler Wetlands trails and the Lynch Cove boat launch are right around the corner, and groceries and a meal out are a short drive. Bring kayaks and watch for eagles off the patio. Late spring through early fall is the sweet spot – warmest water, calmest paddling, longest evenings. Check current rates and open dates on the owner’s site.

    Once Upon a Tide

    This is a single owner-run waterfront vacation home on Hood Canal’s North Shore, a few minutes west of Belfair near the head of the canal. It is a two-story Cape Cod-style house sitting on roughly 100 feet of low-bank pebble beach, with a wide deck built for watching the water and the far ridgeline. It rents as a whole house, not a room, so it suits a family or two couples who want the place to themselves rather than a resort with a front desk.

    The draw here is the beach itself: an oyster bed surfaces on a good low tide, you can pull a kayak or small boat right up on the gravel, and there is a public launch about a mile down the road for anything bigger. Summer is the obvious season, since this stretch of Hood Canal warms up enough to actually swim and the minus tides are best for oystering, though the quiet shoulder months reward anyone who just wants the deck and the view. Book direct through the owner via their listing page.

    Shoofly Creek Retreat

    Shoofly Creek Retreat is one of the larger waterfront houses on the Belfair end of Hood Canal, and it is built for a crowd. This is a single big vacation home, not a resort with a front desk, sleeping somewhere around fifteen across five bedrooms with its own stretch of beach and the namesake creek running down to the water. That makes it a reunion-and-wedding-party kind of place rather than a quiet couples getaway. You get the whole house, room to spread out, and kayaks to put in right off the lawn.

    You are at the very head of the canal here, close to Belfair State Park and the local beaches, with Tahuya and the north shore an easy drive for hiking and tide-pooling. Summer is the obvious draw for swimming, crabbing, and warm-water shellfish season. But come fall and you can watch salmon push up Shoofly Creek from the backyard, which is the quieter, more local reason to book. Check current rates and dates on the official listing.

    Plan your stay by season

    The head of Hood Canal reads completely differently depending on when you come. Here is how locals match the trip to the calendar, with a sample weekend for each.

    Summer: shellfish and a saltwater swim weekend

    This one is for the family that wants to fill a bucket at low tide and still get a real swim in before dinner. Belfair sits at the head of Hood Canal, where the water goes shallow and warm and the tide pulls way back over the flats. Mid-July through August is the sweet spot: longest daylight, warmest water, and the recreational shellfish season usually open. Come for two nights and plan around the tide chart. Base yourself on the water at Summertide Resort in Tahuya, or grab a waterfront campsite or cabin at Belfair State Park with the warm swimming lagoon right there.

    • Time the tide first. Dig and swim on a good low. Check the Lynch Cove tide predictions before you commit a day.
    • Clear the shellfish, every trip. Confirm the beach is open on the Washington Department of Health biotoxin map and check season and limits with WDFW. Closures change fast – bring boots and a license.
    • Fill the in-between hours. Walk the boardwalks at Theler Wetlands, drive out to Tahuya State Forest, or run up to Allyn for a burger and a look at Case Inlet.

    Spring through early fall: Tahuya dirt-and-trail weekend

    This is a get-dirty weekend, not a spa weekend. Tahuya State Forest sits just west of Belfair and is the engine room for ORV riders, mountain bikers, and horse folks across North Mason – roughly 84 miles of trail through working DNR forest. It is a working forest, so logging and washouts move the closure map around week to week. Best window is late spring through early fall, after the gates open (roughly mid-April through October 31) and before the mud sets in. Start at the Elfendahl Pass Staging Area, the main trailhead hub off Belfair-Tahuya Road.

    • Where to stay: the Tahuya River Horse Camp for equestrians with rigs, or Tahuya Adventure Resort for ATV-friendly basecamp lodging close to the trails.
    • Permits: you need both – a Discover Pass to park on DNR land, and an ORV tab and permit for motorized rigs. Confirm current rules at the DNR page.
    • Bring: a paper trail map, spare straps and a tow strap, first aid, bug spray, and water – cell service is patchy out there.
    • Cool down: Belfair State Park and the Theler Wetlands boardwalks on Lynch Cove, or a quiet evening up at Allyn on Case Inlet.

    Spring: birding and a paddle at the head of the canal

    Spring is the right time to point yourself at the head of Hood Canal. The Union River estuary at Belfair wakes up fast as the days lengthen, and Case Inlet lies down enough to put a boat in. Make it a slow weekend: birds in the morning, a paddle on a friendly tide, oysters and a porch by evening. Start at the Theler Wetlands at first light – the boardwalk runs out through restored salt marsh, and April through May is peak for herons, eagles, osprey, swallows, and warblers. For a base, the Allyn House Inn sits on the Case Inlet waterfront with the kayak shop run by the same folks.

    • Paddle: launch onto Case Inlet from Allyn on a rising or high tide; the south end goes to mud fast, so check the tide tables first. North Bay Kayaks rents and guides if you are not hauling your own.
    • Shellfish: beaches open and close on biotoxins – confirm before you dig on the Washington Shellfish Safety Map.
    • Day two: Tahuya State Forest is ten minutes out for trails and quiet lakes, and Belfair State Park has a tidal beach.

    Fall and winter: storm-watching and better rates

    The locals’ secret about the head of Hood Canal is that it gets better after the summer crowds leave. From roughly November through February, Lynch Cove turns moody and gorgeous: low gray light, southerlies pushing whitecaps up the canal, and lodging rates that finally make sense. This is a trip for people who like weather, not sunbathing. The heated cabins at Belfair State Park lock up tight and stay open year-round, which makes them an easy, cheap off-season base right on the saltwater. Ask for a site near the shore for the best storm seats.

    • Theler Wetlands: flat boardwalk through the estuary, great in a light rain when the birds move in.
    • Tahuya State Forest: gravel-road exploring and quiet trails just west when the canal turns rough.
    • Allyn: a short drive north for a hot meal and a look at the water from the other side.

    Year-round: the PSNS-interview one-night practical stay

    This is the no-fuss play for a work trip to the head of Hood Canal. You are interviewing at the shipyard, catching an early ferry out of Bremerton, or just need a clean room and a short drive in the morning. You are not chasing a waterfront view tonight; you want to sleep, get up, and go. Belfair sits right at the top of Lynch Cove, so you are close to Bremerton and PSNS while paying small-town Belfair prices instead of in-town Bremerton rates. Book the in-town Belfair Motel straight off their site – microwave, fridge, parking at the door, easy checkout.

    • Morning, if you have an hour: coffee and a short walk at the Theler Wetlands boardwalk or down at Belfair State Park on the tideflats. Check the Lynch Cove tide first – low tide is mud, not beach.
    • Heading out: Bremerton and the PSNS gates are a quick run north; confirm the live Washington State Ferries schedule before you commit to a sailing.
    • Want water instead: if the trip turns into an overnight worth a view, the waterfront rentals on Lynch Cove and toward Allyn are the upgrade. Save those for when you are not racing a 6 a.m. boat.

    More waterfront vacation rentals

    The houses above are the ones we know and can vouch for, but the short-term-rental inventory at the head of the canal churns constantly – places come on and off the market every season. Rather than mirror listings that go stale, here are live searches that always show what is actually open right now. Set your dates and party size and book direct with the host or platform.

    Frequently asked questions

    Is Belfair on the Great Bend of Hood Canal?

    No. Belfair sits at the head of Hood Canal, at the very top of the fishhook, where the saltwater shallows out into Lynch Cove. The Great Bend – the sharp elbow where the canal turns east – is down at Union, several miles to the southwest. People mix these up all the time. If you are reading about Belfair, Allyn, Tahuya, or Lynch Cove, you are at the head of the canal; the Great Bend and Union are their own stretch with their own lodging.

    Where should I stay near Belfair for a Puget Sound Naval Shipyard trip?

    For a work stay – a PSNS interview, a contractor rotation, or an early Bremerton ferry – the in-town Belfair Motel is the practical pick. It is a clean, pet-friendly roadside motel on Highway 3 with parking at the door, and from Belfair you are a short run north to the Bremerton and shipyard area while paying small-town prices. If your trip turns into an overnight worth a view, step up to one of the waterfront rentals on Lynch Cove or over toward Allyn.

    Can I camp right on the water near Belfair?

    Yes. Belfair State Park sits on the Lynch Cove tide flats with waterfront campsites and a few heated cabins, and Twanoh State Park, about eight miles west on Highway 106, sits on one of the warmest saltwater beaches in the state. Both are Washington State Parks – reserve ahead for summer weekends, bring a Discover Pass for day use, and check current closures before you go. For RVs and cottages on the canal, Summertide Resort and Marina out the north shore in Tahuya is the waterfront option.

    When is the best time to visit Belfair and the head of Hood Canal?

    Late spring through early fall is the all-around sweet spot: warmest water for swimming, calmest paddling, and the recreational shellfish season usually open (always confirm the beach is open before you dig). Mid-summer is peak for the warm-water beaches at Belfair and Twanoh. If you would rather have lower rates and dramatic weather, late fall and winter bring storm-watching on Lynch Cove and open, heated cabins at Belfair State Park.

  • Claude Code vs Cursor: Which AI Editor Wins in 2026?

    Claude Code vs Cursor: Which AI Editor Wins in 2026?

    Last verified: October 13, 2026.

    Claude Code and Cursor are the two tools most working developers actually reach for in 2026, and they are not the same kind of thing. Cursor is an AI-native code editor (a VS Code fork) where the model lives inside your IDE. Claude Code is a terminal agent that lives in your shell and edits files, runs commands, and drives git from the command line. This is the honest version: what each one is good at, what they cost right now, and a simple rule for picking.

    Claude Code vs Cursor: what is the actual difference?

    Side-by-side cards defining what Claude Code is and is not
    Claude Code vs Cursor — what is the actual difference?

    The short answer: Cursor is an editor you type in; Claude Code is an agent you delegate to. Cursor keeps you in the driver’s seat with autocomplete, inline edits, and a chat sidebar that sees your open files. Claude Code takes a goal and works the repo autonomously in the terminal, asking permission before it touches things.

    Dimension Claude Code Cursor
    Form factor Terminal CLI (plus IDE extension, web, desktop) Full IDE (VS Code fork)
    Primary loop Delegate a task, approve actions Type code, accept suggestions
    Models Claude only Multi-model: Grok included on higher tiers; Claude/GPT/Gemini at API list on Premium+
    Best at Multi-file refactors, scripted/headless runs, git workflows Tight edit loops, autocomplete, staying in one window
    Entry price $20/mo (Pro) or $17 annual Free limited / Plus $8 (Grok only) / Premium $30
    Billing model Usage windows (5-hour + weekly) Shared AI usage pool; third-party models at API list on Premium and above

    How does each one actually work?

    Five stacked panels of daily Claude Code command habits
    How each one actually works.

    Claude Code (terminal agent)

    You install it and run it from inside a project directory. Official claude.com copy: Claude Code is included in all paid Claude plans and shares the same usage pool as chat.

    npm install -g @anthropic-ai/claude-code
    cd my-project
    claude

    From there you talk to it in plain language. It reads files, proposes edits as diffs, and runs shell commands only after you approve them. Drop a CLAUDE.md in the repo root. Headless mode: claude -p "...".

    Cursor (AI IDE)

    Cursor is a download. Tab completion, inline edit, agent mode, and a model picker. Official cursor.com/pricing (checked October 13, 2026) lists Free, Plus $8/mo (Grok models only), Premium $30/mo (4x Plus; third-party models at API list price), Super $100/mo (15x), Ultra $200/mo (50x), Teams from $30+/user. Docs at cursor.com/docs/models-and-pricing still reference older Pro $20 / Pro+ $60 / Ultra $200 pools. Quote both; do not average.

    What does Claude Code cost in 2026?

    As of October 13, 2026, official claude.com / platform.claude.com:

    • Pro: $20/month, or $17/month billed annually ($200 up front). Includes Claude Code.
    • Max 5x: $100/month. 5x Pro usage. Includes $100/month API credits.
    • Max 20x: $200/month. 20x Pro usage. Includes $200/month API credits.
    • API: Haiku 5.5 $0.10 / $0.50 per MTok under 100k prompt tokens ($0.50 / $2.50 over); Sonnet 5.5 $2 / $10 with cache reads $0.10; Opus 5.5 $4 / $20 (cache read $0.20); Fable 5.1 $10 / $50 (cache read $0.25). Batch 50% off. US-only inference 1.1x on Claude 4.6+.

    There is a 5-hour rolling session window plus weekly limits on paid plans. Chat and Claude Code draw from one pool. Confirm in Settings > Usage.

    What does Cursor cost in 2026?

    • Free: Limited.
    • Plus: $8/month. Grok models only.
    • Premium: $30/month. 4x Plus usage. Third-party models (Claude, GPT, Gemini) at API list price.
    • Super: $100/month. 15x Plus.
    • Ultra: $200/month. 50x Plus. Earliest access.
    • Teams: From $30+/user/month.

    On the live pricing page, third-party model usage is not included in the monthly price and is billed separately at API list. Docs still describe older Pro/Pro+/Ultra usage pools for Cursor Models vs Other Models. Existing subscribers may keep prior plans.

    Which models do you actually get?

    • Claude Code is Claude-only.
    • Cursor includes Grok on Plus and above; Premium and higher add third-party models at API list price.

    Which one is better for big refactors and automation?

    Claude Code for repo-wide delegate work and headless claude -p runs. Cursor agent is strong inside the IDE; it is not a cron target.

    Which one is better for everyday coding flow?

    Cursor for most people who want tab completion and one window, especially if Grok covers the loop.

    Can you use both together?

    Yes. Common setup: Cursor as the editor, Claude Code in the integrated terminal. Claude Pro is $20; Cursor Premium is $30 if you need Claude models inside Cursor at API rates.

    Bottom line

    • Pick Claude Code if you want an autonomous terminal agent and you are happy with Claude as your one model. Entry is Pro at $20/$17.
    • Pick Cursor if you want autocomplete, Grok included, and a model picker. Entry for third-party is Premium at $30 plus API list.
    • Pick both if the seats are cheaper than the hours you lose switching contexts.

    FAQ

    Is Claude Code or Cursor cheaper?

    Claude Code starts at Pro $20/mo ($17 annual). Cursor Free is limited; Plus is $8 (Grok only); Premium is $30 with third-party models billed at API list on top. Claude Code meters by 5-hour plus weekly windows. Cursor meters a shared pool then on-demand / API list.

    Does Cursor use Claude?

    Yes, on Premium and above, at API list price (not included in the seat). You do not need a Claude Pro seat to use Claude models inside Cursor, but you pay the list rate for them.

    Related reading: Claude API rates · Claude Code vs Codex.

    Start here: Claude Code vs Cursor: Which AI Coding Tool is Better? — the full head-to-head comparison.

  • How AI Engines Actually Cite Your Content: Grounding and GEO Guide

    How AI Engines Actually Cite Your Content: Grounding and GEO Guide

    Last verified: June 2026.

    Most “GEO” advice is recycled SEO with the word “AI” pasted on top. This guide is different. It describes what actually happens when Microsoft Copilot, Bing’s AI answers, and Google’s AI Overviews build a response and decide whose page to cite — based on running content sites that get cited tens of thousands of times a month. The short version: AI engines do not cite the page that ranks #1 for a head term. They cite the page that most directly answers the specific sub-question the model is grounding on. That distinction changes everything about what you should write.

    How grounding actually works (the part nobody explains)

    Topic platform fit visual for first-party AI citation measurement
    How grounding actually works.

    When you ask Copilot or Bing’s AI a question, the model does not answer from memory. It runs a retrieval step called grounding: it rewrites your question into one or more search queries, fetches a handful of live web results, reads them, and composes an answer with inline citations pointing back at the pages it used. Google’s AI Overviews work the same way with a technique it calls “query fan-out” — one user question becomes many narrower synthetic queries.

    Two things follow directly from this mechanism:

    • The model is not searching for your keyword. It is searching for the answer to a decomposed sub-question. A user who asks “what’s the best way to instantly index a new page” triggers grounding queries like “IndexNow API endpoint”, “submit URL to Bing programmatically”, and “IndexNow key file location”. The page that wins is the one that answers those narrow strings, not the one optimized for “indexing tips”.
    • Citations are extracted at the passage level, not the page level. The model lifts the specific sentence or table that answers the sub-question. If your answer is buried under 600 words of preamble, it loses to a page that states the fact in the first line under a matching heading.

    This is why a niche, specific page routinely out-cites a high-authority generalist. The generalist ranks; the specialist gets quoted.

    Why operational and comparison pages win over head terms

    Across real citation data, the pages that get pulled into AI answers cluster into three shapes. None of them are “ultimate guide to X”.

    1. Operational pages with real commands, configs, and error messages

    When someone asks an AI assistant “how do I fix [specific error]” or “what’s the exact command to do X”, the model needs a page that contains the literal command, the literal config, or the literal error string. Generic advice cannot be cited because there is nothing concrete to quote. A page that says:

    curl "https://www.bing.com/indexnow?url=https://example.com/new-page/&key=YOUR_KEY"
    # 200 = received (not "indexed"), 422 = URL/key mismatch, 429 = too many submits

    …is citation gold, because the model can extract that block verbatim and the user can act on it. The error-code annotations matter: questions about failures (“IndexNow 422”, “why am I getting 429”) are high-intent and low-competition, and a page that names the exact codes owns them.

    2. Comparison pages (“X vs Y”)

    “Which is better, X or Y” is one of the most common shapes of AI query, and comparison content is structurally easy to cite because it maps cleanly to a decision. If you maintain honest, current head-to-head pages, you become the default source the model reaches for when a user is choosing between tools. This is exactly why we keep dedicated comparison pages like Claude Code vs Cursor and Claude Code vs Codex — they answer a decision the model is constantly being asked to make, and a table of differences is trivially quotable.

    3. Fresh, dated pages on fast-moving topics

    For anything that changes — pricing, model versions, API limits, feature availability — grounding strongly favors recency. The model would rather cite a page dated this month than an “authoritative” page from two years ago that might be wrong. A visible “Last verified” date and a real publish/update timestamp are not decoration; they are a relevance signal the retrieval layer reads.

    The losing move is chasing broad head terms. “Best AI coding assistant” is saturated, generic, and rarely the literal grounding query. The winning move is to own the long, specific, operational and comparison strings that the fan-out actually generates.

    IndexNow: how to get cited the same day you publish

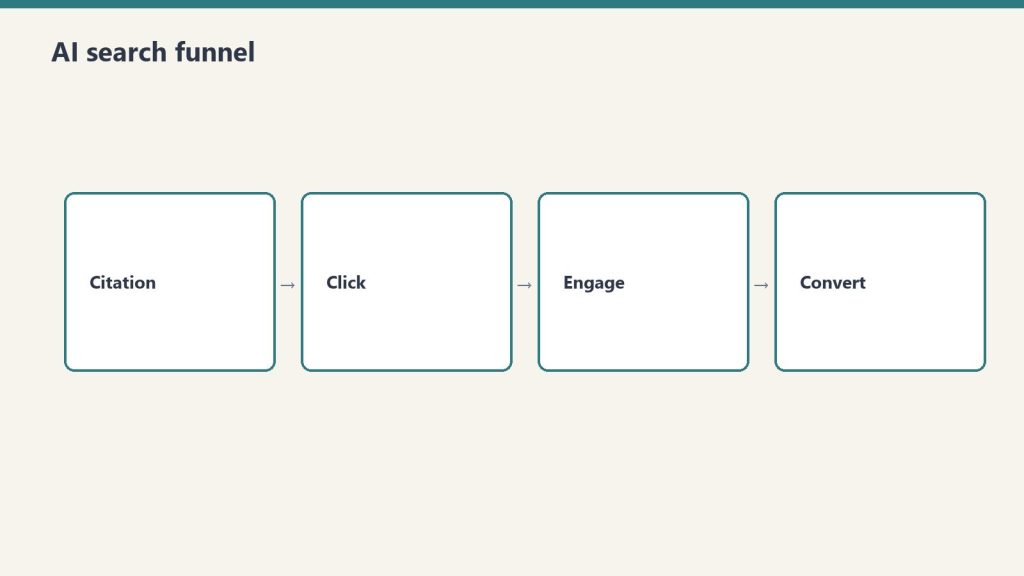
    Four-stage funnel: citation, click, engage, convert
    IndexNow — cited the same day you publish.

    Grounding can only cite pages the engine knows about. The bottleneck for new content is crawl latency — and IndexNow collapses it. IndexNow is an open protocol (backed by Microsoft Bing and Yandex) that lets you push a URL to the index the instant you publish, instead of waiting for a crawler to wander by.

    Setup is two steps:

    1. Host a key file. Generate a key of 8-128 hex characters and place it at your site root as a UTF-8 text file named {key}.txt containing exactly that key. Example: https://example.com/daa44a2c....txt. This proves you own the host.
    2. Ping on publish. Single URL via GET:
      curl "https://api.indexnow.org/indexnow?url=https://example.com/new-page/&key=YOUR_KEY"
      Or batch up to 10,000 URLs in one POST:
      curl -X POST "https://api.indexnow.org/indexnow" \
        -H "Content-Type: application/json" \
        -d '{"host":"example.com","key":"YOUR_KEY","urlList":["https://example.com/a/","https://example.com/b/"]}'

    A 200 means the endpoint received your URL (not that it is indexed yet). Submitting to api.indexnow.org shares the ping with all participating engines, so you do not need to hit Bing and Yandex separately. Most WordPress SEO plugins (Rank Math, Yoast, SEOPress) have IndexNow built in — turn it on and it fires automatically on every publish and update. The practical payoff: pages can enter Bing’s crawl queue within hours, which means they are eligible to be grounded and cited the same day, not next week.

    One caveat worth stating plainly: IndexNow accelerates indexing, which is a precondition for citation. It does not force a citation. You still need the page to be the best answer to the sub-question. But for fresh, time-sensitive content, same-day indexing is often the difference between getting cited while the topic is hot and showing up after the conversation has moved on.

    How to actually measure your AI citations

    For a long time AI citations were invisible — you could see referral clicks in analytics but not the citations themselves (most AI answers are zero-click). That changed. As of February 2026, Bing Webmaster Tools ships an AI Performance report (public preview) that shows when your pages are cited across Microsoft Copilot, Bing’s AI answers, and partner surfaces. It is the first direct, free window into AI citation behavior, and you should be reading it weekly.

    The four metrics that matter:

    • Total citations — how many times your site was cited as a source in AI answers over the period.
    • Average cited pages — the daily average count of unique URLs from your site that got referenced. This tells you whether citations are concentrated on one page or spread across the site.
    • Grounding queries — sample query phrases the AI used to retrieve and cite you. This is the single most actionable field in the report. It is a literal list of the sub-questions you are winning, which tells you exactly which operational/comparison angles to expand next.
    • Page-level citation activity — citations by URL, so you can see which pages are doing the work.

    Two limitations to keep in mind so you read the data honestly: the report does not show click data (you see citations, not visits from them), and it aggregates Copilot with Bing summaries, so you cannot isolate one surface from the other. For Google’s AI Overviews there is still no equivalent citation dashboard — the closest proxy is watching impressions and referral patterns in GA4 and Search Console, plus spot-checking your target queries by hand.

    The workflow that works: pull the grounding-queries list, find the patterns, and feed them straight back into your content plan. If you are getting cited for “claude mcp setup” variants, that is a signal to deepen pages like the Claude MCP setup guide and adjacent operational walkthroughs, not to chase a new head term.

    A repeatable checklist for citation-optimized pages

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Checklist for citation-optimized pages.

    Everything above reduces to a build pattern. For any page you want AI engines to cite:

    • Lead with the answer. Put a short, factual, quotable answer in the first 1-2 sentences under each heading. Assume the model reads only that passage.
    • Use question-shaped headings. H2s and H3s that mirror real queries (“How does IndexNow work?”, “How do I measure AI citations?”) match the grounding query and give the extractor a clean anchor.
    • Be specific and operational. Real commands, real config, real numbers, real error codes and fixes. Concrete text is extractable; vague advice is not.
    • Add a visible FAQ near the end. Plain question/answer pairs are the single most citation-friendly format, because each pair is a self-contained answer to a discrete sub-question. You do not need JSON-LD schema for this to work — visible Q&A text is what the model reads.
    • Date it and keep it current. A “Last verified” line plus genuine updates on fast-moving topics buys you the recency edge in grounding.
    • Push it with IndexNow so it is indexable the same day, then watch the AI Performance report to see which sub-questions it wins.

    If you want the larger system this fits into — the full toolchain for operating as an AI-first publisher, from MCP servers to publishing pipelines — start with the AI operator’s stack.

    FAQ

    Do AI engines cite the page that ranks #1 on Google?

    Not reliably. AI engines run their own grounding retrieval and cite the page that most directly answers the specific decomposed sub-question, which is often a niche, operational page rather than the head-term winner. Ranking helps your page be discoverable, but the citation goes to whichever passage best answers the exact grounding query.

    What is grounding in AI search?

    Grounding is the retrieval step where an AI assistant rewrites your question into search queries, fetches live web pages, reads them, and builds an answer with inline citations to those pages. It is why current, specific pages can get cited even by a model whose training data predates them.

    Does IndexNow guarantee my page will be cited by AI?

    No. IndexNow guarantees fast indexing, which is a precondition for being cited. The page still has to be the best, most specific answer to the sub-question the model is grounding on. Think of IndexNow as removing the crawl-latency excuse, not as buying a citation.

    How do I measure how often AI cites my site?

    Use the AI Performance report in Bing Webmaster Tools (public preview since February 2026). It shows total citations, average cited pages per day, sample grounding queries, and citation counts by URL across Microsoft Copilot and Bing AI answers. It does not yet show click-through from those citations, and there is no equivalent dashboard for Google AI Overviews.

    Do I need JSON-LD or schema markup to get cited?

    No. Citation extraction works on visible, well-structured text — question-shaped headings, short factual answers, and a plain visible FAQ. Schema can help search features generally, but it is not required for AI grounding to read and quote your page.

    What kind of pages get cited most?

    Three shapes dominate: operational pages with real commands, configs, and error fixes; comparison pages that resolve a “X vs Y” decision; and fresh, dated pages on fast-moving topics like pricing and model versions. Broad head-term content tends to get skipped because it rarely matches the literal grounding query and offers nothing concrete to quote.

    Related on Tygart Media: citation economy · AI search funnel · citation monitoring.

  • Notion MCP Setup with Claude: Complete Config + the Errors Nobody Documents

    Notion MCP Setup with Claude: Complete Config + the Errors Nobody Documents

    Last verified: October 2026.

    There are two ways to connect Notion to Claude over the Model Context Protocol (MCP), and almost every tutorial only covers one of them. Worse, none of them tell you why the connection succeeds but Claude still says it cannot find any of your pages. This guide covers both paths – the hosted OAuth connector and the self-hosted token route – with the exact config, the scopes that matter, the rate limit you will hit, and the specific error strings that show up when something is wrong. It is written from actually running this, not from reading the docs.

    Which Notion MCP should you use: hosted or self-hosted?

    Comparing hosted versus self-hosted Notion MCP server options
    Hosted vs self-hosted Notion MCP.

    Short answer: use the hosted MCP at https://mcp.notion.com/mcp for almost everything. It uses OAuth, so you never handle a token, and it respects your existing Notion permissions automatically. Use the self-hosted npm server with an internal integration token only when you need headless, unattended automation (a cron job, a server with no human to click “Allow”), because the hosted server requires an interactive OAuth approval that a background process cannot complete.

    Factor Hosted (mcp.notion.com) Self-hosted (npm + token)
    Auth OAuth (interactive) Internal integration token (ntn_)
    Permissions Inherits your full Notion access Only pages you explicitly share
    Setup time ~2 minutes ~10 minutes
    Headless / cron No (needs a human to approve) Yes
    Best for Claude Desktop, Claude Code, daily use Servers, scripts, multi-user backends

    Notion MCP config generator

    Answer two questions, get your exact setup. No guessing, no stale docs.


    Rolling this out across a team? One person’s MCP setup is a weekend project. Ten people’s is an IT ticket queue. We set up AI workflows for businesses — Notion, Claude, and the glue between them. Tell us what you’re connecting →

    How do I connect Notion to Claude using the hosted MCP?

    Connecting Notion to Claude with the official hosted MCP server over OAuth
    Connect Notion to Claude via hosted MCP.

    This is the fast path. No token, no npm.

    Claude Desktop / Claude.ai: Open Settings > Connectors, click Add custom connector (or pick Notion if it appears in the directory), and paste the URL https://mcp.notion.com/mcp. A Notion OAuth window opens. Approve it, choose which workspace and which top-level pages the connector may see, and you are done. The scope you pick in that OAuth screen is the whole ballgame – see the gotcha below.

    Claude Code (CLI): one command.

    claude mcp add --transport http notion https://mcp.notion.com/mcp

    Then run /mcp inside Claude Code to trigger the OAuth login. After approving, verify it is live:

    claude mcp list

    You should see notion with a connected status. If it shows failed or needs auth, run /mcp again and complete the browser flow – the CLI cannot proceed past OAuth on its own.

    How do I set up the self-hosted Notion MCP with an integration token?

    Use this when you need automation that runs without a human. Three steps: create the integration, get the token, then wire it into your MCP config.

    1. Create the integration and copy the token

    1. Go to https://www.notion.so/my-integrations and click New integration. You must be a Workspace Owner – if the button is greyed out, that is why.
    2. Name it, select the workspace, and choose Internal integration type.
    3. On the integration’s settings page, set Capabilities: Read content, plus Update/Insert content if you want Claude to write. If you only grant Read, every write attempt fails with a permission error later – this is a common self-inflicted wound.
    4. Click Show, then copy the Internal Integration Token. New tokens start with ntn_ (older ones start with secret_ and still work). Treat it like a password.

    2. Add it to your MCP config

    For Claude Desktop, edit claude_desktop_config.json (macOS: ~/Library/Application Support/Claude/; Windows: %APPDATA%\\Claude\\). Add:

    {
      "mcpServers": {
        "notion": {
          "command": "npx",
          "args": ["-y", "@notionhq/notion-mcp-server"],
          "env": {
            "NOTION_TOKEN": "ntn_your_token_here"
          }
        }
      }
    }

    Restart Claude Desktop completely (quit, do not just close the window). On Windows, if npx is not found, use the full path to npx.cmd or run via cmd /c – the config does not inherit your shell PATH.

    3. The step everyone forgets: share the pages

    An internal integration starts with access to nothing. Creating it and pasting the token is not enough. For every page or database you want Claude to touch, open it in Notion, click the … menu (top right), choose Connections (or Add connections), and select your integration. Access is inherited by child pages, so sharing a top-level page covers its whole subtree. Skip this and Claude will connect cleanly and then truthfully report that it cannot see any content.

    What are the most common Notion MCP errors and how do I fix them?

    Troubleshooting common Notion MCP connection errors
    Common Notion MCP errors and fixes.

    These are the failure messages you will actually see, and what each one means.

    “Could not find page” / Claude returns zero results from a workspace that clearly has pages

    Cause, in order of likelihood: (1) you did not share the page with the integration (self-hosted), or you scoped the OAuth grant too narrowly (hosted); (2) the page is in a different workspace than the one the integration is tied to. Fix: re-check the Connections menu on the specific page, or re-run the OAuth flow and widen the page selection. An integration token is bound to one workspace – it cannot see another.

    API token is invalid (HTTP 401 unauthorized)

    The token is wrong, was regenerated, or has a stray space/newline from copy-paste. Re-copy it with the Show button, paste it into the env block with no surrounding whitespace, and restart the client. If you rotated the token in Notion, the old one dies immediately – update every config that used it.

    Validation error / “body failed validation” (HTTP 400)

    Claude tried to write a property type that does not match the database schema – for example sending plain text into a Select, or a malformed date. This is not a connection problem. Tell Claude the exact property names and types, or ask it to fetch the database schema first before writing.

    “Rate limited” / HTTP 429

    Notion enforces roughly 3 requests per second per integration (averaged, with short bursts tolerated). Bulk operations – “update 200 rows,” “scan every page” – blow straight through this. The fix is pacing, not a bigger plan: have Claude batch in small groups and add a short delay between calls. If you are scripting around the MCP, honor the Retry-After header on a 429 instead of hammering.

    spawn npx ENOENT (server will not start, self-hosted)

    Node/npx is not on the PATH the client sees. Install Node, then point command at the absolute path to npx (or npx.cmd on Windows). This is the number-one self-hosted startup failure.

    MCP server shows “failed” in claude mcp list right after adding it

    For the hosted server this almost always means OAuth was never completed – run /mcp and approve in the browser. For the self-hosted server it means the process crashed on launch; run the npx command manually in a terminal to see the real stack trace.

    Notion MCP Configuration Checklist

    Run this before you call the setup done. Every box is a real failure mode from the guide above.

    Setup completeness
    0 of 10

    Check each item as you verify it.

    What can Claude actually do with Notion once connected?

    With read + write capabilities granted, Claude can search your workspace, read pages and databases, create pages, append blocks, and update properties on existing rows. Practical things that work well: “summarize this Notion doc,” “create a row in my tasks database with these fields,” “find every page mentioning X and list the links,” “turn this conversation into a meeting-notes page.” Things that get awkward: very large pages (the response can get truncated – verify the write actually landed by fetching it back), and bulk edits that trip the rate limit. A reliable habit is to treat Notion as the source of truth and have Claude verify by re-fetching after any write, because timeouts on big pages can commit silently and still return a malformed response.

    What is the connection worth to you?

    Operators who wire Claude into Notion typically cut manual capture, entry, and doc-hunting time by roughly 30% — an illustrative estimate, not a guarantee. Put in your own numbers:


    Saved per week
    1.5 hrs
    Saved per year
    78 hrs
    Value per year
    $5,850

    Illustrative math: 30% of your manual information-work hours, × 52 weeks. Real savings depend on your workflows.

    Security notes from running this in production

    • Scope the OAuth grant tightly. The hosted connector inherits whatever you approve. If you only need one project area, share only that top-level page, not the whole workspace.
    • Never hardcode the token in a file you might commit. Keep ntn_ tokens in an env var or your OS secret store, and reference them from config. If a token leaks, revoke it in my-integrations immediately – revocation is instant.
    • Grant the minimum capability. If Claude only needs to read, do not enable insert/update. You can always widen it later.
    • Audit which integrations have access to sensitive databases periodically; the Connections menu on each page shows the current list.

    If you are wiring up several connectors at once, the mechanics generalize – see our broader Claude MCP setup guide for the config patterns that apply across servers, and the AI operator’s stack for how Notion fits alongside the other tools day to day. If your reason for connecting Notion is to get your own content cited by AI systems, the structure of the pages matters as much as the wiring – see how AI engines cite content.

    Frequently Asked Questions

    Do I need a paid Notion plan to use the MCP?

    No. The API and integrations work on free Notion workspaces. You do need to be a Workspace Owner to create an internal integration.

    Why does Claude say it can’t find my Notion pages after connecting?

    The most common reason is that you haven’t shared the specific pages or databases with your Notion integration. Notion’s permission model requires explicit page-level grants — a successful connection does not automatically give access to all your content. Go to the page in Notion, click the three-dot menu, choose ‘Add connections’, and select your integration.

    What rate limits does the Notion API have?

    Notion’s API enforces a rate limit of 3 requests per second per integration. For typical conversational use this is invisible, but if you ask Claude to crawl a large database or process many pages in sequence, you may see 429 errors. The fix is to add a short sleep between bulk operations or use Notion’s pagination to fetch in smaller batches.

    What does the ntn_ prefix mean on my token?

    It is the current internal integration token format. Tokens created today start with ntn_; older secret_ tokens still function and do not need to be replaced.

    Can the hosted Notion MCP run in a headless cron job?

    No. The hosted server requires interactive OAuth approval, which an unattended process cannot complete. Use the self-hosted npm server with an ntn_ token for headless automation.

    How do I let Claude write to Notion, not just read?

    Enable Update content and Insert content under the integration’s Capabilities (self-hosted), or approve write scope during OAuth (hosted). Read-only is the default and will reject every write with a permission error.

    Where do I put the Notion MCP config for Claude Desktop?

    In claude_desktop_config.json – ~/Library/Application Support/Claude/ on macOS, %APPDATA%\\Claude\\ on Windows. Add a notion entry under mcpServers and fully restart the app.

    Can one integration access two workspaces?

    No. An internal integration is bound to the single workspace it was created in. For a second workspace, create a second integration (or a second OAuth grant on the hosted connector).

    What is the Notion MCP server for Claude?

    The Notion MCP server is a connector that lets Claude read, search, and interact with your Notion workspace through the Model Context Protocol. With it connected, you can ask Claude to find pages, summarize databases, draft content into Notion, or retrieve information — all without copying and pasting anything manually.

    What is the difference between the Notion OAuth connector and the self-hosted token route?

    The OAuth connector (available in Claude Desktop’s built-in integrations) is the fastest path — authorize once and Claude gets read access to pages you share with the integration. The self-hosted route uses a Notion Internal Integration token in your claude_desktop_config.json, giving you more control over scopes and works in Claude Code environments where OAuth connectors aren’t available.

    What scopes does the Notion MCP integration need?

    For read operations: Read content and Read user information. For write operations: Update content and Insert content. Avoid requesting more scopes than you need — the minimum set reduces the blast radius if a token is ever compromised. Set scopes when creating your Notion Internal Integration at notion.so/my-integrations.

    Does the Notion MCP integration work with Claude Code?

    Yes. Add it via ‘claude mcp add notion npx @notionhq/notion-mcp-server’ and set your NOTION_API_KEY as an environment variable. Claude Code picks it up on the next session. The self-hosted token route works in both Claude Desktop and Claude Code; the OAuth connector is currently Desktop-only.

    Related reading from operators who run AI tooling daily: Claude Code vs Cursor, Claude Code vs Codex, and Claude in Chrome for LinkedIn automation.

    What is the Notion MCP server and how do I set it up?

    The Notion MCP server is a connector that lets Claude read, search, and write to your Notion workspace through the Model Context Protocol — no copy-pasting between apps. Two setup routes: the hosted route (Claude Desktop → Settings → Connectors → Notion → authorize via OAuth, about two minutes) or the self-hosted route (create a Notion internal integration, copy the token, add it to your MCP config, then share your pages with the integration — the step almost everyone forgets).

    How do I connect Claude to Notion?

    Use the hosted MCP connector: in Claude Desktop, open Settings → Connectors, choose Notion, and authorize via OAuth. For Claude Code, add Notion’s remote MCP server with the claude mcp add command. After connecting, verify Claude can actually see your pages — if it returns zero results on a workspace that clearly has pages, you skipped the page-sharing step.

    Can Claude read and write my Notion databases?

    Yes. Reading works as soon as the connection is live — Claude can search pages, query databases, and pull property values. Writing needs the integration to carry write scopes and the target pages shared with it; then Claude can append database rows, update properties, and draft pages directly. Keep the approval habit for shared workspaces: Claude drafts, you approve.


  • How to Connect Any Tool to Claude with MCP: Complete Setup Guide

    How to Connect Any Tool to Claude with MCP: Complete Setup Guide

    Last verified: October 8, 2026 (Pacific)

    MCP (Model Context Protocol) is how you give Claude hands. Out of the box Claude can talk; with an MCP server connected, it can read your files, query a database, hit an API, or drive a browser. This guide covers the two places you actually wire servers up: the claude_desktop_config.json file for the Claude Desktop app, and the claude mcp add command for Claude Code (the terminal/IDE tool). It ends with the troubleshooting section the official docs skip: path problems, JSON syntax traps, servers that silently never load, and the Windows quirks that cost people an afternoon.

    Everything below is checked against the current Claude Code MCP docs and tested commands. If you want the wider picture of how MCP fits into a working setup, see the AI operator’s stack.

    What is MCP and what is an MCP server?

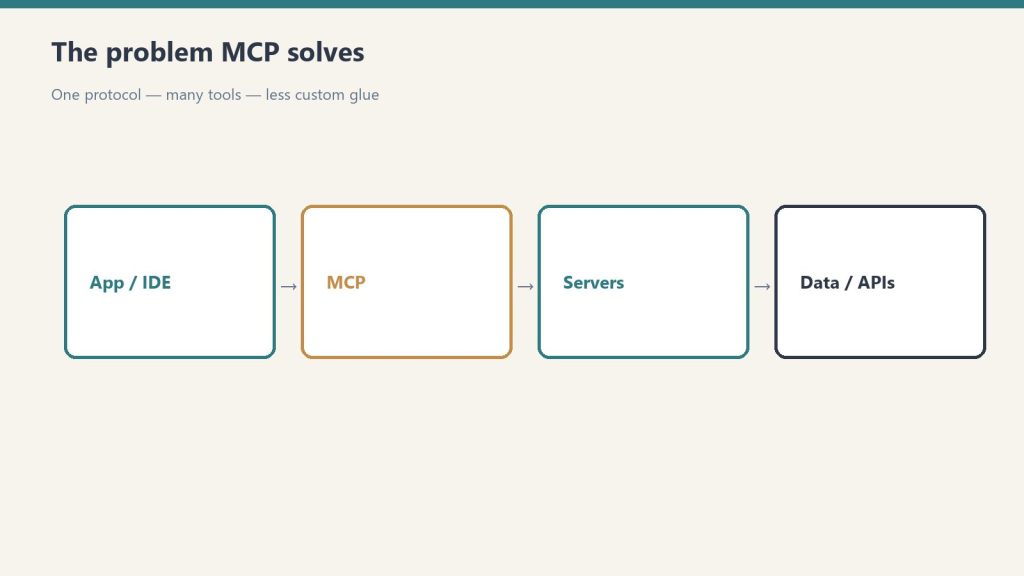
    Flow from app/IDE through MCP to servers and data APIs
    What MCP is — and what an MCP server is.

    MCP transport options at a glance

    TransportUse caseConfig locationWorks with
    stdioLocal tools, CLIs, scriptsclaude_desktop_config.json or claude mcp addClaude Desktop, Claude Code
    SSE (HTTP)Remote servers, cloud servicesURL in configClaude Desktop, Claude Code
    Streamable HTTPProduction remote MCPURL in configClaude Desktop, Claude Code

    MCP is an open standard for connecting AI models to external tools and data. An MCP server is a small program that exposes a set of tools (functions Claude can call) over that protocol. Claude is the client; the server is the thing that actually does the work, like reading a Postgres table or creating a GitHub issue.

    There are two transport types you will deal with in practice:

    • stdio (local): the server runs as a process on your machine. Claude talks to it over standard input/output. Best for filesystem access, local databases, and custom scripts. This is what most “install this MCP server” instructions mean.
    • HTTP (remote): the server lives on the internet at a URL. Best for cloud services (Notion, Sentry, Stripe, GitHub). Often uses OAuth. SSE is the older remote transport and is now deprecated; use HTTP for new remote servers.

    The same server can usually be added to both Claude Desktop and Claude Code. The mechanics differ: Desktop uses a JSON file you edit by hand, Claude Code gives you a CLI that writes the config for you.

    How do I add an MCP server to Claude Desktop?

    Five-step path: account, API keys, billing, usage, workspaces
    Add an MCP server to Claude Desktop.

    For local stdio servers, Claude Desktop still reads a single JSON file — you edit it, fully quit the app, and reopen. The config file remains the source of truth for anything that runs on your own machine. Remote servers are a different story: Claude Desktop now offers an in-app route (Settings > Connectors > Add custom connector) that adds a remote server by URL and handles OAuth for you.

    Where is claude_desktop_config.json?

    • macOS: ~/Library/Application Support/Claude/claude_desktop_config.json
    • Windows: %APPDATA%\Claude\claude_desktop_config.json (paste that into the File Explorer address bar; it expands to C:\Users\YOU\AppData\Roaming\Claude\)

    The fastest way to open it: in Claude Desktop go to Settings > Developer > Edit Config. That button creates the file if it does not exist and opens the folder. If the file is brand new it may be empty or just {}.

    The config file structure

    Everything lives under a top-level mcpServers object. Each key is a name you choose; each value describes how to launch the server. Here is a complete, working file with a local filesystem server and a remote Notion server:

    {
      "mcpServers": {
        "filesystem": {
          "command": "npx",
          "args": [
            "-y",
            "@modelcontextprotocol/server-filesystem",
            "C:\\Users\\YOU\\Documents"
          ]
        },
        "notion": {
          "command": "npx",
          "args": ["-y", "@notionhq/notion-mcp-server"],
          "env": {
            "NOTION_TOKEN": "secret_your_token_here"
          }
        }
      }
    }

    Three fields do all the work:

    • command the executable to run (npx, node, python, uvx, or an absolute path to a binary).
    • args an array of arguments. Each flag and value is its own array element. "--port 8080" as a single string will not work; use "--port", "8080".
    • env an object of environment variables (API keys, tokens). Optional.

    After saving, completely quit Claude Desktop (on Windows, right-click the system tray icon and choose Quit; closing the window is not enough) and reopen it. You should see a tools/connector indicator in the chat input. For a full Notion walkthrough including the token, see connecting Notion to Claude with MCP.

    How do I add an MCP server to Claude Code (CLI)?

    Side-by-side cards defining what Claude Code is and is not
    Add an MCP server to Claude Code CLI.

    Claude Code does not make you hand-edit JSON. The claude mcp command manages servers for you and writes to the right file. This is the part people get wrong most often, so here is the exact, verified syntax.

    claude mcp add

    The general form for a local (stdio) server is:

    claude mcp add [options] <name> -- <command> [args...]

    The -- is load-bearing. Everything before it is for Claude Code; everything after it is the command that launches your server. Real examples:

    # Local filesystem server
    claude mcp add filesystem -- npx -y @modelcontextprotocol/server-filesystem ~/Documents
    
    # Local server with an environment variable
    claude mcp add --env AIRTABLE_API_KEY=YOUR_KEY airtable -- npx -y airtable-mcp-server
    
    # Remote HTTP server
    claude mcp add --transport http notion https://mcp.notion.com/mcp
    
    # Remote HTTP server with an auth header
    claude mcp add --transport http github https://api.githubcopilot.com/mcp/ --header "Authorization: Bearer YOUR_PAT"

    Option ordering matters. All flags (--transport, --env, --scope, --header) must come before the server name. Put a flag after the name and you will get a confusing parse error or the flag will be passed to your server instead of to Claude Code.

    Scopes: local, project, user

    The --scope flag decides where the config is written and who sees it:

    • local (the default) loads only in the current project, private to you. Stored in ~/.claude.json keyed by the project path.
    • project loads in the current project and is shared with your team. Stored in a .mcp.json file at the project root that you commit to git.
    • user loads across all your projects, private to you. Also stored in ~/.claude.json.
    # Available across all your projects
    claude mcp add --scope user --transport http sentry https://mcp.sentry.dev/mcp
    
    # Shared with your team via .mcp.json in the repo
    claude mcp add --scope project filesystem -- npx -y @modelcontextprotocol/server-filesystem .

    When the same server name exists at multiple scopes, local wins over project, which wins over user. The whole entry from the winning scope is used; fields are not merged.

    claude mcp list, get, and remove

    # List every configured server and its connection status
    claude mcp list
    
    # Show the full config for one server
    claude mcp get github
    
    # Remove a server
    claude mcp remove github

    claude mcp list is your first diagnostic. It shows each server as connected, pending, or failed. Project-scoped servers from a .mcp.json you have not approved yet show as Pending approval until you run claude interactively and accept them.

    Other useful commands

    # Add from a raw JSON blob (handy when copying from a server's README)
    claude mcp add-json weather '{"type":"stdio","command":"npx","args":["-y","weather-mcp"]}'
    
    # Import everything you already set up in Claude Desktop (macOS / WSL)
    claude mcp add-from-claude-desktop

    Inside a running Claude Code session, type /mcp to see live server status, tool counts, and to trigger OAuth login for remote servers that need it.

    Troubleshooting: the errors the docs skip

    Most MCP failures are not exotic. They are paths, quoting, and the app not restarting. Work this list top to bottom.

    Server not loading / no tools appear

    1. Did you actually restart? Claude Desktop only reads the config at launch. Fully quit (tray icon > Quit on Windows, Cmd+Q on macOS) and reopen. In Claude Code, run claude mcp list to see the real status instead of guessing.
    2. Is the command on PATH? The single most common stdio failure is npx, node, python, or uvx not being found by the app. GUI apps often have a narrower PATH than your terminal. Fix it by using an absolute path. Find it with which npx (macOS/Linux) or where npx (Windows), then put that full path in command.
    3. Read the logs. Claude Desktop writes per-server logs. macOS: ~/Library/Logs/Claude/. Windows: %APPDATA%\Claude\logs\. Look for mcp-server-NAME.log. The actual error (missing module, bad token, wrong path) is almost always sitting right there.

    spawn ENOENT or “command not found”

    This means the OS could not find the executable named in command. It is a PATH problem, not a Claude problem. Use the absolute path (see above). On Windows specifically, see the npx note below.

    JSON syntax errors (the silent killer)

    If claude_desktop_config.json has a single syntax error, Claude Desktop loads zero servers and usually says nothing. The usual culprits:

    • Trailing commas. JSON forbids a comma after the last item in an object or array. "args": ["a", "b",] is invalid.
    • Smart quotes. If you edited the file in a word processor, curly quotes (the slanted kind) break the parser. Use a code editor and straight quotes only.
    • Unescaped Windows backslashes. In JSON, \ is an escape character, so every backslash in a Windows path must be doubled: C:\\Users\\YOU\\Documents. A single backslash silently corrupts the string.

    Paste the whole file into any JSON validator before restarting. Thirty seconds there saves an hour of staring.

    Claude Code: flag passed to the wrong place

    If claude mcp add behaves strangely, you almost certainly put a flag after the server name or forgot the --. Reread the order: claude mcp add [flags] NAME -- COMMAND ARGS. The -- separates Claude Code’s flags from your server’s command.

    Windows quirks

    • npx needs a wrapper in some setups. If a bare "command": "npx" fails on Windows, launch it through cmd: "command": "cmd" with "args": ["/c", "npx", "-y", "the-server-package"]. This resolves a class of “npx works in my terminal but not in Claude” failures.
    • Use the right config root. It is %APPDATA%\Claude\ (which is AppData\Roaming), not AppData\Local. Mixing these up means you are editing a file the app never reads.
    • Git Bash mangles paths. If you run commands through Git Bash, it can rewrite paths like /c/Users or absolute paths inside arguments. Prefer PowerShell or cmd for claude mcp add, or pass paths exactly as Windows expects them.
    • WSL is a separate world. A server installed inside WSL is not visible to a Windows-native Claude Desktop, and vice versa. Keep both on the same side.

    Remote server returns 401 / 403

    The server needs authentication. In Claude Code, run /mcp and complete the OAuth flow in your browser. If you hardcoded an Authorization header and it is rejected, the token is wrong for that endpoint; remove the header and let OAuth handle it instead.

    Frequently asked questions

    What is an MCP server in one sentence?

    A small program that exposes tools (functions like read-file or query-database) to Claude over the Model Context Protocol, so Claude can take real actions instead of only producing text.

    What is the difference between Claude Desktop and Claude Code for MCP?

    Claude Desktop is the chat app and you configure servers by hand-editing claude_desktop_config.json, then restarting. Claude Code is the terminal/IDE tool and you configure servers with the claude mcp add command, which writes the config for you.

    Where is the Claude Desktop config file?

    macOS: ~/Library/Application Support/Claude/claude_desktop_config.json. Windows: %APPDATA%\Claude\claude_desktop_config.json. The quickest way to open it is Settings > Developer > Edit Config inside the app.

    Why is my MCP server not showing up?

    In order of likelihood: you did not fully restart the app, the command is not on the app’s PATH (use an absolute path), or there is a JSON syntax error such as a trailing comma, a smart quote, or an unescaped Windows backslash. Check the per-server log in the Claude logs folder for the exact error.

    What does the double dash do in claude mcp add?

    The -- separates Claude Code’s own flags from the command that launches your server. Flags like --transport and --env go before it; the actual launch command (npx -y some-server) goes after it.

    What is the default scope for claude mcp add?

    local. The server loads only in the current project and stays private to you. Use --scope user to make it available in every project, or --scope project to share it with your team via a committed .mcp.json.

    Is SSE or HTTP the right transport for remote servers?

    HTTP. SSE still works but is deprecated. Use --transport http for any new remote server unless its documentation specifically requires SSE.

    How do I remove an MCP server?

    In Claude Code, run claude mcp remove NAME. In Claude Desktop, delete that server’s entry from the mcpServers object in claude_desktop_config.json and restart the app.

    Where to go next

    Once your servers connect cleanly, the leverage comes from using them well. For how this fits a daily workflow, read the AI operator’s stack; if you are choosing between coding environments, see Claude Code vs Cursor. And if you want a concrete first server to wire up, the Notion MCP setup is a clean, high-value place to start.

    Frequently Asked Questions

    What is MCP and why does it matter for Claude?

    MCP (Model Context Protocol) is an open standard that lets Claude connect to external tools, databases, APIs, and services. Without MCP, Claude can only work with text in the conversation window. With an MCP server connected, Claude can read your files, query a live database, hit an API, or control a browser — turning it from a chat interface into an autonomous agent.

    How do I add an MCP server to Claude Desktop?

    Edit the claude_desktop_config.json file (found at ~/Library/Application Support/Claude/ on Mac, %APPDATA%/Claude/ on Windows). Add your server under the ‘mcpServers’ key with a ‘command’, ‘args’, and optional ‘env’ block. Save the file and restart Claude Desktop. The server appears in Claude’s tool list if it loaded correctly.

    How do I add an MCP server to Claude Code?

    Run ‘claude mcp add [args…]’ from your terminal. For a remote SSE server use ‘claude mcp add –transport sse ‘. List configured servers with ‘claude mcp list’. Servers added this way are scoped to your user profile unless you use the –project flag.

    Why does my MCP server connect but Claude can’t see my data?

    The most common cause is scope or permission gaps. For Notion, verify your integration has been granted access to the specific pages/databases — the connection succeeds even without page access. For file servers, check that the path in your config resolves correctly from the shell Claude launches (not your interactive shell). For OAuth servers, re-authorize and confirm token scopes.

    What is the difference between stdio and SSE MCP transports?

    stdio runs the MCP server as a local subprocess — Claude launches the command you specify and communicates over stdin/stdout. This is used for local tools and CLIs. SSE (Server-Sent Events) connects to a remote HTTP server. Use stdio for local tools like filesystem access or database clients; use SSE or Streamable HTTP for cloud services or shared team servers.

    Which MCP servers should I start with?

    The highest-value first connections are: filesystem (read/write your local files), a database client for your primary DB, and a service you interact with daily (Notion, Slack, GitHub, Linear). The Notion MCP server is a clean first project — see the dedicated setup guide on this site for the exact config and common errors.

  • Local AI Without NPU: Turn a $400 Laptop Into an AI PC

    Local AI Without NPU: Turn a $400 Laptop Into an AI PC

    All fall, Microsoft has been selling one idea: the future is the AI PC — a Copilot+ machine with a dedicated neural chip (an NPU), Recall, Click to Do, a thousand dollars and up, and your old laptop need not apply.

    I had a $400 budget laptop on my desk — an AMD Ryzen 5 7520U, 16 GB of RAM, no NPU — and a hunch that the whole framing was backwards. The AI-first laptop was never about the chip. It’s about architecture.

    A few hours later, that $400 laptop had a private AI brain, voice control, and a control panel I run from my phone. On the things that actually matter for operating a machine, it does more than the Copilot+ PC it’s supposedly too cheap to be. Here’s the exact build.

    The thesis: AI-first is architecture, not a chip

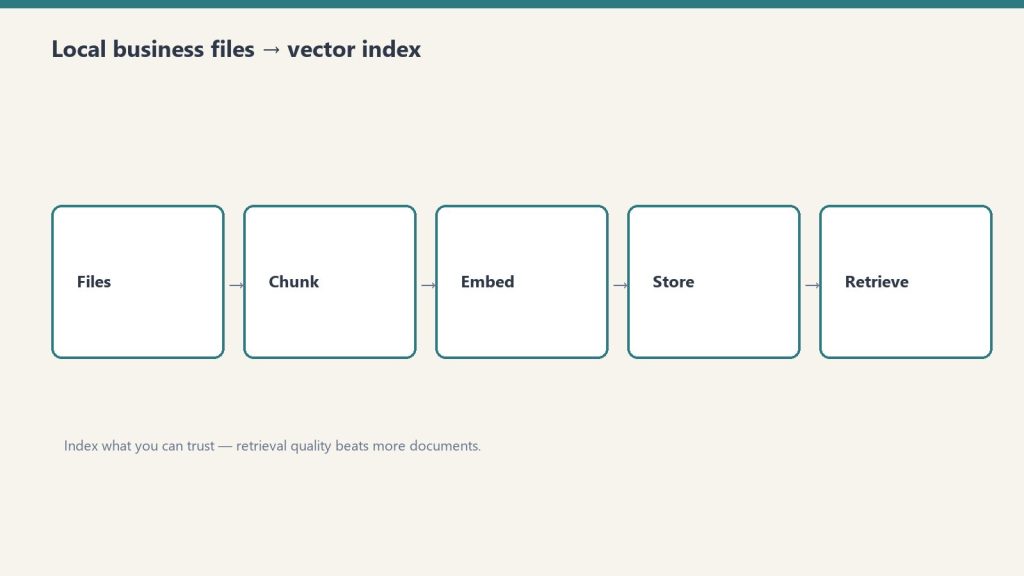
    Five-step flow from files to chunk, embed, store, retrieve
    AI-first is architecture, not a chip.

    The trick is to stop asking your laptop to be the supercomputer. Split the job:

    • The brain lives in the cloud. The heavy reasoning runs on a frontier model (I use Claude) with effectively unlimited horsepower. No NPU on Earth competes with that.
    • The body lives on your laptop. Your machine becomes the always-on hands: it holds your private data, runs small models locally for anything sensitive, and executes the actions the brain decides on.

    An NPU optimizes a handful of on-device Windows features. Architecture gives you an actual operator. Guess which one you feel every day.

    Step 0 — Make it always-on

    An operator rig is a little server, and servers don’t nap. My laptop kept sleeping and killing background jobs, so the first move was to take that off the table (while plugged in):

    powercfg /change monitor-timeout-ac 0
    powercfg /change standby-timeout-ac 0
    powercfg /setacvalueindex SCHEME_CURRENT SUB_BUTTONS LIDACTION 0
    powercfg /setactive SCHEME_CURRENT

    Screen never blanks, never sleeps, and it keeps running with the lid closed — while still sleeping on battery as a safety. Now it’s a real always-on host.

    Step 1 — A private AI brain that lives on the laptop

    Three stacked layers: chat UI, tools, agent runtime
    A private AI brain that lives on the laptop.

    The local engine is Ollama; the chat interface is open-webui (running in Docker). If you want the multi-agent version of this idea, I’ve also written up building a free AI agent army with Ollama and Claude. The only thing standing between me and a private, offline ChatGPT was one wrong setting — open-webui was pointed at a dead address. The fix was to aim it at the host:

    docker run -d --name open-webui --restart always -p 3000:8080 
      -v open-webui:/app/backend/data 
      -e OLLAMA_BASE_URL=http://host.docker.internal:11434 
      ghcr.io/open-webui/open-webui:main

    The proof: a 3-billion-parameter model (Llama 3.2) introduced itself in about 10 seconds at ~12 tokens/second — on the CPU, no NPU, no discrete GPU. Fast enough for real Q&A, drafting, and summaries. Seven models sit ready on disk, and the whole thing is reachable from my phone over a private network.

    Everything here runs offline. For anything I don’t want leaving the machine, that’s the entire point.

    Step 2 — Voice that never leaves the machine

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Voice that never leaves the machine.

    A local Whisper speech-to-text container (OpenAI-compatible API) became a push-to-talk dictation tool: hold a key, talk, release, and the text drops into whatever app is focused. I verified the pipeline without even touching the mic — Windows text-to-speech generated a clip, the local Whisper transcribed it, and it round-tripped clean:

    Spoken: “Testing one two three. This is the private local transcription engine.”
    Whisper heard: “Testing 1-2-3. This is the private local transcription engine.”

    Windows has built-in dictation (Win+H) and Copilot voice too — but those ship your audio to the cloud. The local version does the same job, and your voice never leaves the laptop.

    Step 3 — Turn your phone into the control panel

    Using Tailscale (a private mesh network), every service on the laptop is reachable from my phone — without exposing anything to the public internet. I added a tiny web page (one small nginx container) as a mobile operator console: one tap to the local AI, automations, status, and finance dashboards. Pin it to the home screen and the laptop is in your pocket.

    The honest scoreboard vs. a Copilot+ PC

    Capability Copilot+ PC ($1,000+) This $400 laptop
    Private AI running on the device Limited (small NPU models) ✅ Full Ollama stack, 7 models
    An AI that operates the machine ❌ ✅ Runs commands, edits files, fixes things
    Private, offline voice dictation ❌ (cloud) ✅ Local Whisper
    Phone control panel ❌ ✅ Tailscale operator console
    Recall / Click to Do / Cocreator ✅ (needs the NPU) ❌
    Screenshots everything you do ⚠️ Recall does, by design ✅ No — nothing is recorded

    I’m being fair: the NPU-only features are genuinely off the table on cheap hardware. But for operating your computer — and for privacy — the architecture beats the chip.

    Why this matters more than it looks

    The quiet headline isn’t “I saved money.” It’s where the data lives. Microsoft’s flagship AI-PC feature, Recall, works by screenshotting everything you do. This build does the opposite: the sensitive payload stays on your machine, and the cloud is used only for the heavy thinking that doesn’t need your private files.

    That’s not just a hobbyist’s preference. It’s the exact requirement for anyone in a regulated field — healthcare, legal, finance — who can’t send client data to a third party but still wants real AI leverage. The cheap laptop isn’t the story. The architecture is.

    Frequently asked questions

    Do I need a Copilot+ PC or an NPU to run local AI?

    No. Any laptop with around 16 GB of RAM and a modern CPU can run small local models. An NPU accelerates certain Windows features but is not required for Ollama or local chat.

    Is local AI actually private?

    Yes. With Ollama, the model runs on your own machine and works with no internet connection — nothing is sent to a cloud service.

    What is the difference between Ollama and open-webui?

    Ollama is the engine that runs the models. open-webui is the friendly chat interface that sits in front of it.

    How fast is a local model on a budget laptop?

    On a CPU-only AMD Ryzen 5 with 16 GB of RAM, a 3-billion-parameter model answered at roughly 12 tokens per second — fine for quick questions, drafting, and summaries. Larger models run slower.

    Can I use it from my phone?

    Yes. Over a private Tailscale network you can reach your laptop’s AI and tools from your phone without exposing anything to the public internet.

    Is this better than a Copilot+ PC?

    For operating your machine and for privacy, this setup does more. For NPU-specific Windows features like Recall and Click to Do, a Copilot+ PC is required.

    Want this on your machine?

    Tygart Media builds privacy-first, local-AI operator setups — especially for teams in regulated industries that need real AI leverage without sending data to the cloud. Reach out and we’ll scope it to your hardware.

    >Part of the complete guide: Your Laptop Is Already an AI PC

  • Using Claude in Chrome with LinkedIn: What It Is Good For (and What to Avoid)

    Using Claude in Chrome with LinkedIn: What It Is Good For (and What to Avoid)

    Last verified: June 2026.

    What Claude in Chrome can and can’t do on LinkedIn

    Three stacked layers: chat UI, tools, agent runtime
    What Claude in Chrome can and can’t do on LinkedIn.
    TaskVerdictNotes
    Summarize a profile✅ Safe and usefulRead-only, no automation signal
    Draft a personalized DM✅ Safe and usefulYou review and send manually
    Research a company page✅ Safe and usefulRead-only extraction
    Summarize a post or thread✅ Safe and usefulRead-only, no interaction
    Auto-post to your feed❌ High riskViolates ToS, triggers automation detection
    Auto-connect with multiple people❌ High riskAccount restriction risk
    Bulk message sending❌ High riskSpam detection, potential ban

    The Claude for Chrome extension lets Claude see and act inside your browser. The obvious temptation is to point it at LinkedIn and have it post for you. Do not do that. Here is what the extension is genuinely useful for on a professional network – and the one job you should never hand it.

    What to avoid: automated feed posting

    Five security domains: identity, data, code governance, audit, agents
    What to avoid — automated feed posting.

    Driving the browser to auto-post feed content is a high-risk move. Professional networks actively detect automation, it violates their terms of service, and it can get an account throttled or suspended. If you want scheduled feed posts, use a social scheduler’s official API – that is the supported, durable path, and the one that will not get your account flagged. The browser is an assistant, not a posting robot.

    What it is actually good for

    1. Paste-assist for long-form Articles

    This is the real opportunity. Social schedulers – and every third-party tool – can only push short feed posts through the official API. Native long-form Articles and Newsletters have no public publishing endpoint, so they stay a manual copy-paste. That matters because AI engines cite long-form Articles far more often than short posts, by a wide margin. The most citation-valuable format is the one no tool can automate. That is exactly where an in-browser assistant earns its place: with you in the loop, it can help move a finished, formatted draft into the Article composer and tidy the formatting – turning a tedious manual paste into a guided one.

    2. Multi-account navigation

    If you operate a personal profile plus several company pages, the extension can help you move between already-authenticated sessions and keep track of which identity you are acting as – reducing the “posted from the wrong account” mistakes that come with juggling many pages by hand.

    3. Research, review, and drafting

    Reading a profile and summarizing it, scanning a feed for the day’s relevant threads, or drafting a thoughtful comment for your approval are all squarely in bounds. The assistant prepares; you decide and click.

    How to do it safely

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to do it safely.
    • Keep a human in the loop on anything that publishes or sends – review before you submit.
    • Never bulk-send connection requests, messages, or comments. That is the behavior detectors look for.
    • Use the official scheduler API for anything recurring; reserve the browser for the manual, assistive steps.
    • Treat the extension as read-and-prepare by default, act-and-publish only with your explicit click.

    Frequently asked questions

    Can Claude auto-post to LinkedIn for me?

    Not safely, and you should not try. Use a social scheduler’s API for feed posts. The browser extension is for assistive, human-in-the-loop work – especially the long-form Articles that no API can publish.

    Why can’t scheduling tools publish Articles or Newsletters?

    Because the platform exposes no public API for them. Feed posts have an endpoint; long-form does not. That limitation is shared by every tool, which is why the manual paste persists.

    Is browser automation against the rules?

    Automated posting and bulk outreach generally violate the terms and risk the account. Assistive, human-approved use – drafting, summarizing, helping you paste – is the safe lane. When in doubt, keep a person on the trigger.

    For the bigger picture of how this fits a full content operation, see The AI Operator’s Stack.

    Frequently Asked Questions

    What is the Claude for Chrome extension?

    Claude for Chrome (Claude in Chrome) is a browser extension that lets Claude see and interact with the page currently open in your browser. It can read page content, summarize what’s visible, draft responses based on what it sees, and in some configurations take actions like clicking or filling forms — depending on what permissions are active.

    Can I use Claude to automate LinkedIn posts?

    You should not. Professional networks like LinkedIn actively detect browser automation, and auto-posting violates their Terms of Service. Using Claude in Chrome to drive automated feed posting can result in account throttling or permanent suspension. Claude is useful for drafting post content, but you should always review and publish manually.

    What is Claude in Chrome actually useful for on LinkedIn?

    Legitimate high-value uses include: summarizing a prospect’s profile before a sales call, researching a company page, drafting a personalized connection request or DM based on what you read on a profile, and summarizing a post or comment thread. All of these are read-and-assist operations that don’t trigger automation signals.

    Does using Claude in Chrome on LinkedIn violate their terms of service?

    Read-only operations (summarizing, researching, drafting) generally do not violate LinkedIn’s terms. Automated actions (clicking, posting, connecting, messaging at scale) do. The key distinction is whether Claude is taking actions on LinkedIn’s platform autonomously versus helping you draft content that you then review and submit yourself.

    How is Claude in Chrome different from a LinkedIn scraper?

    Claude in Chrome reads what’s visible on the page you have open — it is not a bulk scraper that crawls hundreds of profiles automatically. It operates within your active browser session, one page at a time, and does not bypass LinkedIn’s normal page rendering. A scraper typically makes API calls or headless browser requests at volume; Claude in Chrome is a single-session reading assistant.

    What Claude model powers Claude in Chrome?

    Claude in Chrome uses Anthropic’s Claude models — currently Claude Sonnet 4.6 is the primary model for browser interactions, balancing capability and speed. Anthropic may update the underlying model over time. You can check your current model in the extension settings.

  • The AI Operator’s Stack: How One Person Runs a Multi-Brand Content Machine

    The AI Operator’s Stack: How One Person Runs a Multi-Brand Content Machine

    Last verified: June 2026.

    Most “AI stack” articles hand you a list of tools. This one is about the wiring between them, because that is where the leverage lives. After running a multi-brand content operation end to end – research, writing, publishing, and distribution to a couple dozen destinations – one lesson keeps repeating: the tools are commodities, and the connective tissue is the moat. Here is the whole machine, and how the pieces talk to each other.

    One machine, four jobs

    Three stacked layers: chat UI, tools, agent runtime
    One machine, four jobs.

    The stack has four jobs: capture an idea, produce the content, remember everything, and distribute it where both people and AI engines will find it. Miss any one and the system stalls.

    1. Intelligence and intake

    The front door is an “AI as PR team” intake: you drop a raw thought, a link, or a voice memo, and the model turns it into the right shapes – an outline, a short post, a full brief. A lightweight signal scraper watches a professional network for the language practitioners actually use and feeds those angles back as prompts, so the writing starts from how people really talk instead of a blank page.

    2. Production

    Claude is the reasoning engine. A content pipeline turns a brief into a structured article; an image model generates the visuals; and a set of “beat desks” – small scheduled agents, each owning one topic – research, draft, quality-gate, and self-publish to WordPress through its REST API. Every desk has a freshness gate: if there is nothing genuinely new and sourceable, it skips the run rather than manufacture filler. A clean skip is a successful run.

    3. Record and state

    Notion is the control plane – the registries, the per-desk specs, the run logs, the system of record. The governing principle is load-bearing: the model is not the runtime. Claude supplies judgment; durable execution lives on schedulers and cloud jobs; Notion holds the state. Separate those three and the machine keeps running whether or not anyone is watching it.

    4. Distribution and grounding

    This is the layer most stacks forget, and the one that compounds. Publishing to your own site is half the job; the other half is getting that content into the indexes search engines and AI assistants actually read. Two moves do the heavy lifting. First, IndexNow pings the Bing index the moment anything changes – that is how new and updated content gets grounded fast instead of waiting on a crawl. Second, a social scheduler fans a tailored post out to a professional network – a personal profile plus company pages – drafted first for human approval, never blasted.

    Here is the part worth internalizing: that professional network matters far more than its follower count suggests, because it is one of the most-cited domains in AI answers. Since it flows into the same index that feeds AI grounding, every post is also a citation asset. You are not chasing likes – you are seeding the corpus that AI engines quote back to the next person who asks.

    The loop that compounds

    Four-step loop: observe, remember, act, update for managed agents
    The loop that compounds.

    The layers are not a straight line; they form a loop. A researched social post is a compressed seed. Crack it open into a full article cluster – a core piece, audience-specific variants, an FAQ, schema, internal links – publish those, then queue the new URLs back to the scheduler as future posts. Social feeds the site; the site feeds social; both feed the grounding layer. Content you already made becomes the raw material for what you make next.

    Why every layer optimizes for citation

    Four-stage funnel: citation, click, engage, convert
    Why every layer optimizes for citation.

    AI engines do not cite broad overviews. They cite operational specifics, head-to-head comparisons, and fresh, dated facts. So the whole stack is tuned for that: specific over general, “this versus that” where it genuinely helps a reader decide, and same-day freshness on anything that changes. The pages that earn the most citations are the least glamorous – the exact limits, the real configuration, the honest comparison – because those are the answers nobody else keeps current.

    The honest edges

    This is maintained, not magic. Long-form articles on a professional network have no public API, so that step is a manual paste – and it happens to be the most citation-valuable format, which means the highest-value action is also the least automatable one. Auth tokens expire and quietly break distribution until someone notices. Account IDs drift, so you verify live before any bulk action. The wiring is powerful precisely because keeping it wired is real work.

    Related on Tygart Media: Cursor command center · fleet bots · Notion second brain.

    Frequently asked questions

    Do you need to be a developer to run this?

    No, but you need to be comfortable wiring tools together – connecting an API, editing a config file, reading a log. The reasoning model closes much of that gap, but the operator still has to understand how the pieces connect.

    Why optimize for Bing and not just Google?

    Because the AI assistants people increasingly ask their questions to are grounded substantially on the Bing index. Winning that index is how you get cited in AI answers – a different and faster game than ranking on a traditional results page.

    Is the social distribution automated?

    The drafting is. Publishing is draft-first: the system stages every post for a human to approve before it goes live. Automation writes; a person decides.

    What is the single highest-leverage piece?

    The connective tissue – the model-context wiring that lets the brain reach your tools, and the distribution wiring that pushes finished content into the indexes AI reads. Start there. See our guide to connecting any tool to Claude with MCP and how AI engines actually cite content.

  • 2025 RIA TPA Scorecard: Best & Worst Restoration Programs

    2025 RIA TPA Scorecard: Best & Worst Restoration Programs

    Updated October 2026: The 2025 edition (released April 2025) is the latest RIA TPA Scorecard — no 2026 edition has been published. Since the survey, Alacrity’s managed repair division became an independent company, Altimeter Solutions Group (January 2026, backed by BV Investment Partners), and Worley acquired Alacrity Renovation Services from Lowe’s. Scores below reflect the 2025 survey as published.

    If you work insurance program work, this is the one report you should actually read. Every year, the Restoration Industry Association’s Advocacy and Governmental Affairs committee surveys contractors who have worked with TPAs in the past 12 months. No vendor marketing. No TPA spin. Just anonymous contractor ratings across 8 categories that actually matter: value, claims process, contractor support, scoring clarity, guidelines, credentialing, claim volume, and geographic coverage.

    The 2025 results are in. 379 contractors rated 13 TPAs. The industry average sits at 2.7 out of 5 — a 54% satisfaction rate. That’s not a ringing endorsement of the TPA model, but it tells you something more useful: the spread between programs is significant, and knowing who’s at the top and who’s at the bottom changes your program strategy.

    Here’s the breakdown, with the data that matters.

    The Leaderboard: Who Contractors Actually Trust

    Four cards: assignment quality, pay speed, scope fights, partner fit
    Score TPAs on what contractors feel — not the brochure.

    ONCORE Claims Network: 3.1 stars — #1 for the third consecutive year. This is the benchmark. ONCORE (formerly CORE) outperforms everyone across nearly every category: 3.4 on credentialing (the highest of any TPA), 3.3 on guidelines, 3.2 on value, and 3.0 on contractor support — the only TPA to crack 3.0 in that category. Claim volume is their soft spot at 2.7, which contractors consistently flag: the program is good, but there aren’t enough jobs to go around. If you can get in and get volume, this is the cleanest program to run.

    Lionsbridge: 3.0 stars. Tied with Sedgwick for second and rising. Lionsbridge improved 3% since 2022 and scores well on guidelines (3.1) and claims process (3.1). It operates as a CCA Global Partners cooperative — meaning members get access to significant group buying power on equipment, credit card processing, and supplies in addition to leads. The program is selective and built for established contractors. Their claim volume score of 2.4 is the weak link, but the jobs they do send tend to be cleaner to close.

    Sedgwick: 3.0 stars. The highest geographic coverage of any TPA at 3.2, tied with Alacrity and Contractor Connection. Sedgwick is a large TPA that manages claims for major commercial carriers. Their value score improved from 2022 and holds at 3.2. Contractor support fell slightly to 2.8, which is still above average. Sedgwick’s biggest contractor complaint: they want better advocacy with carriers when scope disputes arise (34% of contractors flagged this as their top improvement priority).

    The Middle of the Pack

    Westhill Global: 2.9 stars (+27% from 2022). The biggest mover in the 2025 report. Westhill climbed from 2.3 to 2.9, the largest percentage gain of any TPA. They earned the highest credentialing score in that category at 3.2, and their value rating jumped from 2.0 to 3.0. What drove it? Contractors report that Westhill made meaningful process improvements and the program became easier to actually manage. Watch this one — if the trajectory continues, they’ll be in the top tier in 2027.

    Preferred Repair Network (PRN) / Hancock Group: 2.9 stars (down from 3.5 in 2022). The biggest drop in the report. PRN was the top-rated TPA in 2022. Two years later they’ve fallen 17% across all categories — contractor support cratered from 3.5 to 2.7. The program score fell sharply (from 3.5 to 3.0), guidelines dropped, and claim volume expectations are down 23%. Contractors aren’t abandoning the program — the claim volume and geographic scores are still reasonable — but something changed in how the program is managed. If you’re heavily weighted in PRN, the trend line warrants attention.

    Direct Claims Management Group (DCMG): 2.8 stars (+12% from 2022). DCMG improved across the board and earned the highest scoring clarity rating (3.1) and tied for the top value rating. Their communication scores are better than average, and they’re rated best-in-class for not requiring contractors to take estimate-only projects. Smaller program footprint, but if you’re in their coverage area, worth evaluating.

    Alacrity Solutions/Alacrity Nexxus: 2.7 stars (down 4%). The largest program by claim volume alongside Contractor Connection — and that volume score (2.7) is their strongest asset. Contractors use Alacrity for the jobs, not the relationship. The program scored 2.3 on contractor support, the second lowest of any TPA. Key contractor complaints: 38% want better advocacy with carriers, 34% want overhead and profit addressed, 33% want more flexibility in guidelines. Alacrity knows this and has invested in contractor relations improvements (rebranding from the original Altimeter structure), but the needle hasn’t moved enough to show in the scores yet.

    The Programs That Are Losing Contractor Confidence

    Clipboard and tablet on a kitchen counter during an insurance adjuster walkthrough after water loss
    Programs losing confidence usually lose it in the scope fight.

    Brightserv: 2.6 stars (flat). No change from 2022. Contractors score timely payment as a weak point (29% flag it), and contractor support (2.3) needs work. The program hasn’t gotten worse, but in a field where others are improving, flat is a problem.

    HOMEE: 2.6 stars (new to 2025 survey). Debuted slightly below average with a concerning claim volume score of 1.8 — the lowest of any TPA. Contractor support is at 2.6, and 46% of contractors rate “improve partnership with TPA” as their top request. As a tech-forward TPA operating in the gig-economy model, HOMEE is a different kind of program — useful for certain contractors but not a primary revenue source for established restoration companies.

    Contractor Connection (Crawford): 2.6 stars. The most widely used TPA in the restoration industry — 289 contractor responses, the largest sample in the survey. Geographic coverage ties for highest (3.2), claim volume ties for highest (2.7), and they’re among the best for timely payment (only 8% of contractors flag slow payment, one of the lowest rates). The problem is everything else. Contractor support sits at 2.2 — second lowest. Contractor advocacy with carriers is the top complaint at 42%. Guidelines flexibility is flagged by 39% of contractors. They send the most work. They’re also the most frustrating to work with. The calculation you have to make: is the volume worth the margin compression and administrative friction?

    Accuserve (formerly CodeBlue): 2.1 stars — last place. The lowest-rated TPA in the 2025 report, and it’s not close. Accuserve scores below 2.0 on value (1.9), scoring clarity (1.9), claims process (1.9), and contractor support (1.9). The only category where they score above 2.5 is credentialing (2.6). Fifty percent of contractors working with Accuserve say providing pricing consistent with market value is their top requested improvement — double the industry average. This program has structural problems that go beyond management tweaks.

    What the Numbers Actually Tell You

    The overall industry average of 2.7 out of 5 means most contractors are running TPA work that’s tolerated, not preferred. The five most important things contractors want from TPAs — in order of importance they rated themselves: claims process efficiency (4.4/5 importance), contractor support/advocacy (4.2), claim volume (4.2), value/ROI (4.2), and guidelines flexibility (4.1). On every single one of those, TPAs are delivering somewhere between 2.3 and 2.9. There’s a consistent gap between what contractors need and what they’re getting.

    The other number worth noting: 53% of restoration firms now report zero TPA revenue, up from 45% the prior year. That’s not a blip — it’s a structural shift. Contractors who built their own lead channels through Google LSA, direct plumber and agent referrals, and organic SEO are generating work at better margins without the administrative overhead. The TPA model still works, but fewer operators are treating it as their primary revenue strategy.

    How to Build Your TPA Program Intelligently

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Build your TPA mix like a checklist — not a hope.

    The operators who do TPA work profitably aren’t in every program — they’re in two or three that fit their capacity, their geographic footprint, and their operational model. Here’s the framework:

    Use the RIA scorecard as a filter, not a verdict. A 3.1 from ONCORE doesn’t mean the program works in your market — claim volume (2.7) is the constraint. A 2.6 from Contractor Connection doesn’t mean you walk away from the largest volume source in the country. But it does mean you know where the friction is going to come from before you budget for it.

    Cap TPA revenue at 40-50% of total revenue. The moment more than half your revenue runs through a program, the TPA controls your business. They can change pricing, add administrative requirements, or reduce your zip code coverage — and you have no leverage. Keep direct work as your floor, TPA work as your upside.

    Track margin per TPA, not aggregate TPA margin. The programs that send the most work aren’t always the ones generating the most gross profit. A company doing $800K in Contractor Connection work at 28% gross margin is generating less than a company doing $300K in ONCORE work at 44% gross margin. Build a simple spreadsheet that tracks average gross margin per job by program. You’ll know within 90 days which programs deserve more of your capacity.

    Document your TPA scorecard complaints. The RIA survey directly affects how TPA programs are managed — TPA executives receive this data and respond to it. If you’re running program work and experiencing consistent friction with a specific TPA, log it and participate in the next RIA survey. That’s not altruism. That’s how contractors collectively move the needle on program terms.

    TPA Readiness Checklist

    TPAs don’t just score your work — they audit your back office before you ever get a job. Check every box that’s true for your company. Be honest; the TPA’s credentialing team will be.

    Your readiness score 0 of 17

    Check the boxes to see where you stand.

    Self-assessment, not a guarantee — every TPA publishes its own credentialing requirements. Use this to find your gaps before their auditor does.

    The Bottom Line

    If you’re choosing between TPA programs in 2025, the data is clear: ONCORE leads, Lionsbridge and Sedgwick are solid programs for contractors who qualify, and Westhill Global is the most improved. Contractor Connection sends the most work but has the worst contractor support score. Accuserve has structural problems that pricing alone won’t fix.

    Don’t build your business on programs. Build your business on direct marketing, strong referral relationships, and operational capability — then let TPA work be the fill you take when capacity allows. The contractors who get that order right keep their margins. The ones who get it backwards spend their careers negotiating scope with adjusters they’ll never win against.

    Source: RIA 2025 TPA Scorecard Report, Restoration Industry Association Advocacy and Government Affairs Committee. Survey conducted anonymously among 379 restoration contractors.

    THE RESIDENTIAL-TO-COMMERCIAL BRIDGE · PART 2 OF 3

    Compliance: prove your back office can handle program work

    Certifications get you in the door; TPA-grade documentation keeps you there. Xactimate fluency, S500/S520-standard documentation, and audit-ready admin are the price of commercial program revenue. Final step: aim your marketing where commercial clients actually are.

    ← Part 1: Training — the certification roadmap

    Part 3: Marketing — from residential clicks to commercial networking →

    Related on Tygart Media: RCP guide · contractor ESG clauses · FM ESG frameworks.