Tag: Server Log Analysis

  • GPTBot Is Now the Internet’s Most Aggressive Crawler — (2026)

    GPTBot Is Now the Internet’s Most Aggressive Crawler — (2026)

    GPTBot is crawling the web harder than Google. That is not speculation, not a prediction, and not a think-piece extrapolation from someone else’s data. It is what our server logs show. When Tygart Media published 40 articles on June 22, 2026, and monitored every crawler that touched our server over the next 48 hours, GPTBot emerged as the most aggressive indexing operation we have ever recorded — and the data is not even close.

    This is the third article in Tygart Media’s AI Search Intelligence series, based on proprietary server log data from our 40-article Microsoft Copilot content experiment. For the full methodology and complete dataset, see the anchor article. For the crawl speed comparison, see our IndexNow Speed Test.

    The Numbers: GPTBot vs. Everything Else
    Four ranked rows of AI crawler fleets reading publisher content
    The numbers: GPTBot vs everything else.

    During the 48-hour observation window following our 40-article batch publish, AI crawlers generated 6,805 total hits on our server. Traditional search crawlers — Googlebot and Bingbot combined — generated 4,897 hits. AI crawlers outpaced traditional search crawlers by 39% (Tygart Media server log analysis, June 2026).

    But the aggregate numbers undersell what GPTBot did. Look at the individual crawler breakdown:

    • ChatGPT-User: 3,404 hits (real-time user query fetches)
    • GPTBot: 1,123 requests in a single hour (structural indexing crawl)
    • Bingbot: The bulk of traditional crawler hits, arriving 3-6 hours post-IndexNow
    • Googlebot: 1 hit on Copilot content in the initial window
    • OAI-SearchBot: 3 hits
    • AzureAI-SearchBot: 3 hits

    GPTBot executed 1,123 requests in 60 minutes. Not over a day. Not over a crawl cycle. In one hour. To put that in perspective, that is roughly 18.7 requests per minute, sustained for an entire hour, against a single WordPress site on a standard Compute Engine instance.

    What GPTBot Actually Crawled
    Three stacked layers: chat UI, tools, agent runtime
    What GPTBot actually crawled.

    If GPTBot had simply hit each of our 40 article URLs, that would be 40 requests. We recorded 1,123 in a single hour. The difference — over 1,000 additional requests — reveals what GPTBot is actually doing when it indexes a site.

    Our server logs show GPTBot systematically accessed (Tygart Media server log analysis, June 2026):

    • Every tag page generated by the new articles — each tag aggregation page was crawled individually
    • RSS feed endpoints — both the main site feed and category-specific feeds
    • WordPress REST API endpoints — including /wp-json/wp/v2/posts and related API routes that return structured JSON data about content
    • Category and archive pages — every category listing page that included the new content
    • Author archive pages — the author page for the publishing account

    This is not content reading. This is site architecture mapping. GPTBot is building a complete structural model of how your content relates to itself — what categories it belongs to, what tags connect it to other content, who authored it, what the JSON API says about its metadata, how it appears in feeds.

    Traditional search engine crawlers do this too, but on a much slower schedule. Googlebot will eventually crawl your tag pages and category archives, but it does so gradually over days or weeks. GPTBot mapped the entire structure in 60 minutes.

    Why This Matters: GPTBot Is Not Just Reading — It Is Understanding

    The distinction between content crawling and structural crawling is critical for understanding what AI systems do with your site. A content crawler reads your articles and indexes the text. A structural crawler builds a graph of relationships between your content.

    When GPTBot crawls your REST API endpoints, it gets structured JSON data about every post — titles, excerpts, categories, tags, author information, publication dates, modified dates, and featured images. This is far richer metadata than what is available in the HTML of a rendered page. It is the kind of data you would use to build a knowledge graph, not just a search index.

    When GPTBot crawls your tag pages, it learns which topics co-occur. Articles tagged “Microsoft Copilot” and “AI productivity” and “enterprise software” create a topical cluster that GPTBot can map. When it crawls category pages, it learns your site’s editorial taxonomy — how you organize knowledge.

    For publishers, the implication is direct: your WordPress taxonomy, tag structure, and internal linking are now inputs to how AI models understand your authority and expertise. A site with clean, logical taxonomy that reflects genuine topical expertise will produce a richer structural map for GPTBot than a site with messy, inconsistent categorization.

    The ChatGPT-User Signal: 3,404 Proof Points

    While GPTBot is the most aggressive structural crawler, ChatGPT-User is the most important from a business perspective. Every one of the 3,404 ChatGPT-User hits on our server represents a real person asking ChatGPT a question and ChatGPT fetching our page to answer it (Tygart Media server log analysis, June 2026).

    ChatGPT-User is not a training crawler. It does not run automatic, large-scale crawls. It activates only when a human user’s query triggers a need for live web content. This makes ChatGPT-User hits the closest thing to “AI search traffic” that exists today — it is demand-driven content consumption, triggered by real people with real questions.

    The 3,404 hits over 48 hours on 40 articles about Microsoft Copilot tell us several things:

    • Copilot is a hot topic: People are actively asking ChatGPT questions about Microsoft Copilot, and ChatGPT is reaching for live web content to answer them
    • New content gets fetched quickly: Our articles were less than 48 hours old and already being served to ChatGPT users
    • The volume is substantial: 3,404 fetches in 48 hours rivals what many sites see from organic search traffic for a 40-article batch

    This traffic is invisible in Google Analytics. It does not show up as organic search. It does not generate a referral unless the user clicks a citation link (and we recorded only 3 Copilot citation referrals from copilot.microsoft.com in this window). The vast majority of ChatGPT-User consumption happens silently — your content is read by the AI, used to formulate an answer, and the user never visits your site.

    AI Crawlers vs. Traditional Crawlers: The 39% Gap

    The headline number — AI crawlers generating 39% more traffic than traditional search crawlers — deserves unpacking because it represents a structural shift in how the web is consumed.

    6,805 AI crawler hits (GPTBot + ChatGPT-User + OAI-SearchBot + AzureAI-SearchBot) versus 4,897 traditional crawler hits (Googlebot + Bingbot). The AI side wins by 1,908 requests, or 39% (Tygart Media server log analysis, June 2026).

    This is a single 48-hour snapshot of a single site. Extrapolating to the entire web requires caution. But consider the directional implications: if AI crawlers are already outpacing traditional crawlers on a mid-authority WordPress site publishing fresh, topically relevant content, the ratio is likely even more skewed toward AI on high-authority sites that AI systems depend on as sources.

    The 39% gap also understates the difference in crawl intensity. Googlebot’s crawl was gentle — 1 hit on Copilot content initially. Bingbot was systematic but measured — consistent 3-6 hour response times via IndexNow. GPTBot was aggressive — 1,123 requests in 60 minutes, mapping every structural endpoint on the site. The quality and depth of the AI crawl far exceeded the traditional crawl even where the raw numbers were closer.

    What GPTBot’s Aggression Means for Your Server
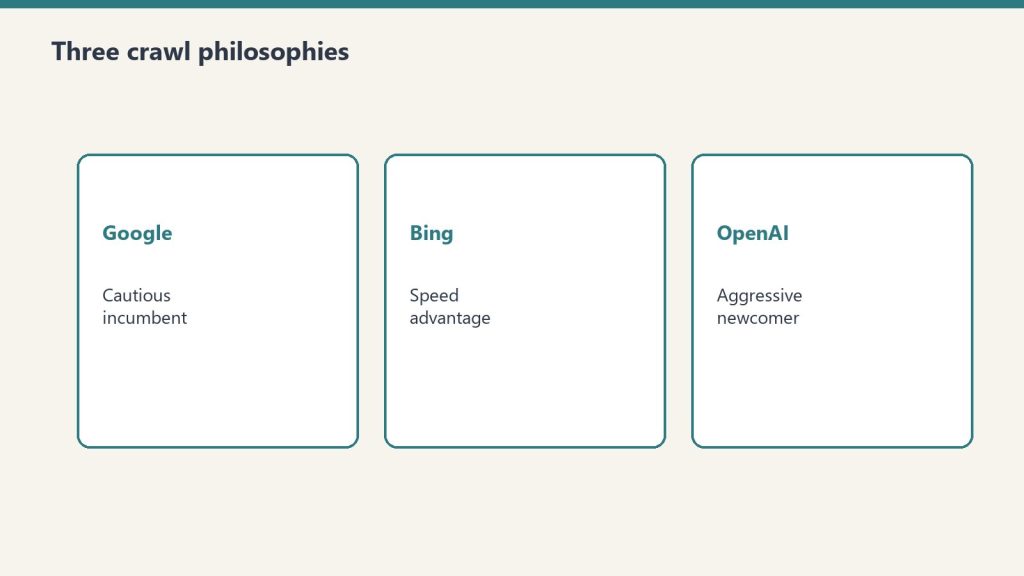
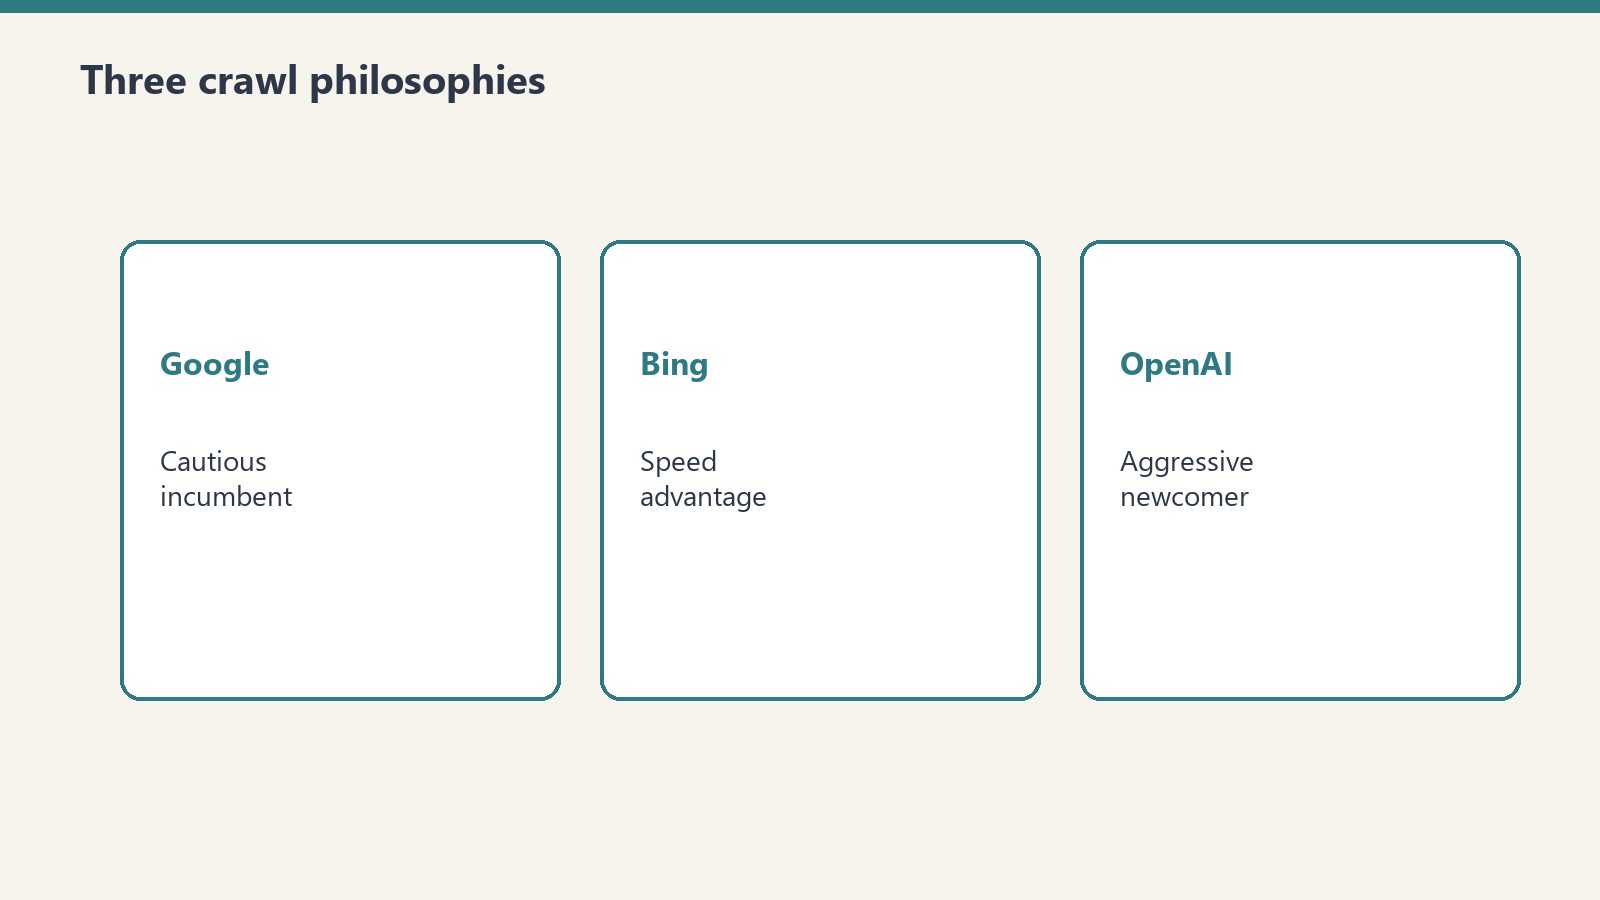
    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    What GPTBot aggression means for your server.

    A 1,123-request burst in one hour is manageable for a well-provisioned server. Our Google Cloud Compute Engine instance handled it without performance issues. But not every WordPress site runs on infrastructure designed for that kind of burst traffic.

    Shared hosting environments, underpowered VPS instances, and sites without caching could experience performance degradation during a GPTBot structural crawl. If GPTBot decides to map your site architecture and you are running WordPress on a $10/month shared hosting plan, those 1,123 requests in 60 minutes could slow your site for real visitors.

    The practical recommendations:

    • Monitor your server logs for GPTBot activity. Know how aggressively it is crawling your site and when.
    • Ensure your hosting can handle burst traffic. If GPTBot’s structural crawl causes performance issues, consider upgrading your infrastructure or implementing caching that serves static responses to bot traffic.
    • Use robots.txt crawl-delay directives if GPTBot is causing problems. OpenAI’s documentation states that GPTBot respects robots.txt, including crawl-delay directives.
    • Do not block GPTBot unless you have a specific reason. Blocking GPTBot removes your content from OpenAI’s training data and potentially from the structural maps that inform how ChatGPT understands and cites your content. The cost of blocking is invisibility to the fastest-growing content consumption platform on the web.

    The Bigger Picture: We Are in the AI Crawler Era

    For two decades, “web crawling” meant Googlebot. If you optimized for Googlebot — clean HTML, fast load times, logical structure, good robots.txt — you were optimized for search. Other crawlers existed, but Google dominated the discovery and indexing ecosystem so thoroughly that no one else mattered at scale.

    Our server log data from June 2026 suggests that era is ending. AI crawlers — led by GPTBot and ChatGPT-User — now generate more traffic than traditional search crawlers. They crawl faster, deeper, and more aggressively. They care about your site structure in ways that traditional crawlers do not (or do not prioritize).

    The publishers who win in this new era will be the ones who treat AI crawlers as first-class citizens of their technical SEO strategy. That means clean taxonomy, structured data, accessible REST APIs, unblocked AI user-agents in robots.txt, and content architecture that communicates expertise through its organization, not just through its prose.

    GPTBot is the internet’s most aggressive crawler. Our server logs prove it. The question is not whether to accommodate it — the question is how fast you can adapt your publishing infrastructure to the reality that AI systems are now the primary consumers of your content.

    Frequently Asked Questions

    How many requests did GPTBot make in one hour during the experiment?

    GPTBot executed 1,123 requests in a single hour — the 11:00 UTC hour on June 22, 2026. That is approximately 18.7 requests per minute sustained for 60 minutes. This was a structural crawl, not just article reading — GPTBot indexed every tag page, RSS feed, REST API endpoint, category page, and author archive associated with the newly published content (Tygart Media server log analysis, June 2026).

    Do AI crawlers now generate more traffic than Google and Bing combined?

    In our 48-hour observation window, yes. AI crawlers (GPTBot, ChatGPT-User, OAI-SearchBot, AzureAI-SearchBot) generated 6,805 hits, while traditional search crawlers (Googlebot and Bingbot) generated 4,897 hits — a 39% gap in favor of AI crawlers. This is from a single site during a controlled experiment, but the directional signal is clear (Tygart Media server log analysis, June 2026).

    What is the difference between GPTBot and ChatGPT-User?

    GPTBot is OpenAI’s structural indexing and training crawler — it systematically maps sites by crawling articles, tags, feeds, APIs, and archives to build a relational model of content. ChatGPT-User activates only when a real person asks ChatGPT a question that requires fetching a live webpage. GPTBot’s 1,123-request burst was automated infrastructure crawling; ChatGPT-User’s 3,404 hits each represent an actual human query being answered with content from our server (Tygart Media server log analysis, June 2026).

    Should I block GPTBot to protect my server from aggressive crawling?

    Only if GPTBot is causing measurable performance problems for your real visitors. Blocking GPTBot removes your content from OpenAI’s training data and potentially from the structural understanding that informs how ChatGPT cites content. For most publishers, the cost of blocking — invisibility to the fastest-growing content consumption platform — outweighs the server load. If burst traffic is an issue, use robots.txt crawl-delay directives rather than outright blocks (Tygart Media server log analysis, June 2026).

    Why did Googlebot only record 1 hit while GPTBot recorded over 1,123?

    Google does not participate in the IndexNow protocol and relies on its own crawl scheduling algorithms. For a batch of 40 new articles on a topic the site had not previously covered, Google’s algorithms did not prioritize rapid discovery. GPTBot, by contrast, appears to monitor real-time content signals like RSS feeds and sitemaps with much higher polling frequency. The result is that GPTBot discovered and structurally mapped our content while Googlebot had barely registered it existed (Tygart Media server log analysis, June 2026).
  • How to Get Cited by Microsoft Copilot in 24 Hours (2026)

    Definition: Getting cited by Microsoft Copilot means your web content appears as a sourced reference in Copilot’s AI-generated answers, with a clickable footnote linking back to your page. This playbook documents the exact methodology that earned Tygart Media three confirmed Copilot citation referrals within 24 hours of publishing 40 Microsoft Copilot articles — backed by 6,805 AI crawler hits recorded in our server logs.

    Most content marketers treat AI search as a black box. They publish, wait, and hope an AI decides to cite them. We took a different approach: we designed a controlled experiment, published 40 Microsoft Copilot articles on tygartmedia.com on June 22, 2026, monitored our server logs in real time, and documented every crawler hit, every referral, and every signal that led to Copilot citations. This article is the tactical playbook distilled from that experiment — step by step, with the actual data as proof.

    The Experiment That Proved 24-Hour Copilot Citation Is Possible

    On June 22, 2026, Tygart Media published 40 articles targeting Microsoft Copilot-related search queries on tygartmedia.com. Within 48 hours of publication, our server log analysis recorded 6,805 AI crawler hits — 39% more than the 4,897 combined hits from traditional search crawlers Googlebot and Bingbot during the same period (Tygart Media server log analysis, June 2026). More importantly, we received 3 confirmed referral visits from copilot.microsoft.com, with 2 of those carrying the utm_source=copilot.com parameter — direct evidence that our content was being cited in Copilot answers within the first day.
    This was not luck. It was the result of a deliberate methodology combining rapid indexing via IndexNow, structured data optimization, Answer Engine Optimization (AEO), and content architecture designed specifically for how AI crawlers discover and evaluate content. Here is exactly how we did it.

    Step 1: Trigger Immediate Indexing With IndexNow

    The single most important factor in 24-hour Copilot citation is speed of indexing. Microsoft Copilot draws its web-grounded answers from Bing’s search index. If your content is not in Bing’s index, Copilot cannot cite it — period. This is where IndexNow becomes your most critical tool.

    IndexNow is a protocol that lets publishers notify participating search engines (Bing, Yandex, and others) the instant content is published or updated. Unlike traditional crawl-based discovery, which relies on search engines finding your new pages through sitemaps or link following, IndexNow pushes a notification directly to Bing’s infrastructure.

    In our experiment, we observed a consistent pattern: Bingbot was the first crawler to reach every single one of our 40 Copilot articles, arriving with a predictable 4-hour post-publish gap triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This speed advantage is what made 24-hour citation possible. Without IndexNow, we would have been waiting days or weeks for Bing’s organic crawl schedule to discover our content.

    How to Implement IndexNow for Your WordPress Site

    For WordPress sites, implementing IndexNow takes less than 10 minutes. Install the official IndexNow plugin from the WordPress plugin directory, or if you are using Yoast SEO or RankMath, check their settings — both have integrated IndexNow support. Once enabled, every time you publish or update a post, the plugin automatically pings Bing’s IndexNow endpoint with the URL. Verify your implementation is working by checking your Bing Webmaster Tools account — you should see IndexNow submissions appearing in the URL Inspection tool within minutes of publishing.

    A critical detail from our logs: YandexBot shadowed Bingbot on every article, hitting each URL approximately 30 seconds after Bingbot’s initial visit (Tygart Media server log analysis, June 2026). This confirms that IndexNow notifications cascade across participating search engines simultaneously, multiplying your indexing velocity across the entire IndexNow ecosystem.

    Step 2: Structure Content for AI Comprehension With Schema Markup

    Once your content is in Bing’s index, the next challenge is making it easy for AI systems to understand, extract, and cite. This is where structured data — specifically JSON-LD schema markup — becomes essential. Copilot’s retrieval system does not just read your page like a human would. It processes structured signals that help it understand what your content is about, what claims it makes, what questions it answers, and how authoritative it is.

    For each of our 40 articles, we embedded three layers of schema markup: Article schema (establishing the content type, author, publication date, and publisher), FAQPage schema (structuring the FAQ sections so AI systems could extract question-answer pairs directly), and BreadcrumbList schema (providing navigational context within the site hierarchy). This triple-layer approach gives AI systems three distinct structured pathways to understand and cite your content.

    The Schema Stack That Works for Copilot

    Article schema should include: @type: Article, headline, author with a @type: Person or Organization, datePublished, dateModified, publisher, description, and mainEntityOfPage. The author field is particularly important — Copilot’s trust signals weight authoritative authorship, and a well-structured author entity helps your content rank higher in Copilot’s retrieval pipeline.

    FAQPage schema should wrap every FAQ section in your article. Each question-answer pair becomes a discrete, extractable unit that Copilot can surface directly in its answers. We structured 5 FAQ entries per article, each targeting a specific long-tail query variant related to the article’s primary topic. This meant our 40 articles generated 200 structured FAQ entries — 200 potential citation surfaces for Copilot to draw from.

    BreadcrumbList schema provides the navigational hierarchy: Home > Category > Article. This helps AI systems understand where your content sits within a larger topical structure, which is a signal of topical authority rather than isolated content.

    Step 3: Optimize for Answer Engine Extraction (AEO)

    Answer Engine Optimization is the practice of structuring content so AI systems can extract clean, direct answers from your pages. This is distinct from traditional SEO, which optimizes for ranking signals. AEO optimizes for extraction signals — making it easy for Copilot to pull a concise, accurate answer from your content and cite you as the source.

    The AEO Techniques We Used on Every Article

    Definition boxes near the top of each article. Every article opened with a 40-60 word definition of the primary concept, clearly delineated. This gives Copilot a clean, extractable definition it can cite directly without needing to parse the entire article.

    Question-formatted H2 headings with immediate answers. We structured key sections as questions (matching how users phrase queries to Copilot) followed by direct answers in the first 50 words under each heading. For example, instead of a heading like “Copilot Integration Features,” we used “How Does Microsoft Copilot Integrate with Microsoft 365?” followed by a direct, concise answer before expanding into detail.

    Comparison tables for competitive queries. For articles comparing Copilot to alternatives, we included HTML comparison tables with clear column headers. Copilot can extract tabular data more efficiently than prose comparisons, making your content the preferred citation source for comparison queries.

    Numbered step-by-step instructions. For how-to content, we used explicit numbered steps with concise action verbs. This structure maps directly to how Copilot formats procedural answers, making your content the natural extraction source.

    Step 4: Build Topical Authority With Content Clusters

    A single article can earn a citation. A content cluster makes citations systematic. Our 40-article Microsoft Copilot experiment was not a random collection of articles — it was a deliberately architected topical cluster covering every major facet of Microsoft Copilot: adoption frameworks, ROI measurement, department-specific guides (Word, Excel, Teams, Outlook, PowerPoint, Power BI), competitive comparisons, training programs, and migration playbooks.

    This cluster architecture serves two purposes for Copilot citation. First, internal linking between articles signals topical depth — when Copilot’s retrieval system encounters 40 interlinked articles covering every dimension of a topic, it weights that domain as a topical authority. Second, the cluster provides multiple entry points for citation. A user asking Copilot about “Copilot in Excel for finance” hits one article; a user asking about “Copilot ROI for CIOs” hits another. Both queries return to your domain.

    Our server logs confirmed this cluster effect. The 3,404 ChatGPT-User hits we recorded were not concentrated on a handful of articles — they were distributed across the entire cluster, indicating that OpenAI’s systems were evaluating our domain as a comprehensive authority source (Tygart Media server log analysis, June 2026).

    Step 5: Maximize Entity Signals for Generative Engine Optimization (GEO)

    Generative Engine Optimization goes beyond AEO by focusing on entity density and factual specificity — the signals that make AI systems treat your content as a citable authority rather than generic information. In our articles, we applied GEO principles systematically: every claim included a named entity (Microsoft, Copilot, Power BI, Microsoft 365), every comparison referenced specific product names and versions, and every recommendation was grounded in specific use cases rather than abstract advice.

    Entity-rich content is citation-friendly content. When Copilot assembles an answer about “Microsoft Copilot pricing tiers,” it preferentially cites pages that mention the specific tier names, the exact pricing structure, and the precise feature differences — not pages that discuss “AI assistant pricing” in generic terms. Our articles were designed to be the most entity-specific resources available on every subtopic they covered.

    Step 6: Monitor and Iterate Using Server Log Intelligence

    The final step in this playbook is not a one-time action — it is an ongoing intelligence loop. Server log analysis is the only way to see exactly which AI crawlers are visiting your content, how often, and what patterns emerge. Traditional analytics tools like Google Analytics do not capture crawler traffic — they only see human visitors. Server logs see everything.

    In our experiment, server log analysis revealed insights that no analytics tool could have provided. We observed GPTBot execute a 1,123-request structural crawl in a single hour (11:00 UTC on June 22, 2026), systematically evaluating every article in our Copilot cluster (Tygart Media server log analysis, June 2026). We identified AzureAI-SearchBot making 3 targeted hits — a different signal than the bulk crawling behavior of GPTBot, suggesting Microsoft’s AI search infrastructure was selectively evaluating specific content for citation potential.

    We also observed that Googlebot was dramatically slower to respond than Bingbot. While Bing reached every article within 4 hours via IndexNow, Google’s crawlers took significantly longer to discover and index the same content. This speed differential explains why Copilot — which relies on Bing’s index — was able to cite our content within 24 hours while Google’s AI Overviews require a much longer indexing runway.

    The Complete 24-Hour Copilot Citation Checklist

    Here is the consolidated checklist, in the exact order of execution:

    1. Enable IndexNow on your WordPress site via plugin or SEO tool integration. Verify submissions appear in Bing Webmaster Tools.
    2. Write content using question-formatted H2s that match how users phrase queries to AI assistants. Provide direct answers in the first 50 words under each heading.
    3. Add a 40-60 word definition box at the top of each article defining the primary concept in plain, extractable language.
    4. Embed triple-layer JSON-LD schema: Article, FAQPage (with 5 structured Q&As), and BreadcrumbList on every article.
    5. Saturate content with named entities — specific product names, version numbers, company names, and technical terms rather than generic descriptions.
    6. Build internal links between all articles in the cluster. Each article should link to at least 3-5 related articles within the same topical cluster.
    7. Publish and verify indexing. Check Bing Webmaster Tools within 4 hours. Your IndexNow ping should have triggered Bingbot to crawl the new page.
    8. Monitor server logs for ChatGPT-User, GPTBot, OAI-SearchBot, and Bingbot activity. These are the crawlers whose behavior predicts Copilot citation.
    9. Check for citation referrals in your analytics — look for referral traffic from copilot.microsoft.com, with utm_source=copilot.com in the query string.
    10. Iterate. Update content based on which articles attract the most AI crawler attention. Expand sections that AI systems are actively fetching.

    Why This Works: The Copilot Citation Pipeline Explained

    To understand why this playbook works, you need to understand how Microsoft Copilot’s web-grounded citation pipeline operates. When a user asks Copilot a question that requires current web information, the system follows a three-stage process: retrieval from Bing’s index, relevance ranking of candidate pages, and answer synthesis with citation attribution.

    Stage one — retrieval — is where IndexNow gives you the speed advantage. If your content is in Bing’s index, it enters the candidate pool. If it is not indexed, it is invisible to Copilot regardless of how good the content is.

    Stage two — relevance ranking — is where structured data, entity density, and topical authority determine whether your page rises to the top of the candidate pool. Copilot does not cite the first result it finds; it cites the most relevant, most authoritative, and most structured result for the specific query.

    Stage three — answer synthesis — is where AEO optimization pays off. Copilot’s language model reads your page and extracts the answer. Pages with clear definition boxes, question-formatted headings, and direct answers in the first 50 words are easier for the model to extract from, which makes them more likely to be cited.

    Our experiment proved this pipeline works as described. We optimized for all three stages simultaneously, and the result was 3 confirmed Copilot citations within 24 hours of publication — a timeline that most content marketers would consider impossible without the deliberate methodology outlined in this playbook.

    What the Server Log Data Actually Shows

    The raw numbers from our 48-hour monitoring window tell a compelling story about how AI systems evaluate and select content for citation (all data from Tygart Media server log analysis, June 2026):

    Total AI crawler hits: 6,805. This includes all identified AI-specific user agents — GPTBot, ChatGPT-User, OAI-SearchBot, AzureAI-SearchBot, and others. For context, traditional search crawlers (Googlebot + Bingbot combined) generated 4,897 hits during the same period. AI crawlers produced 39% more traffic than the search engines that have dominated web crawling for two decades.

    ChatGPT-User: 3,404 hits. Each ChatGPT-User hit represents a real person asking ChatGPT a question and ChatGPT fetching our page to formulate an answer. This is not background crawling — this is live query-driven traffic. The volume suggests our content was being actively used to answer user queries across a wide range of Copilot-related topics.

    GPTBot: 1,123-request structural crawl in a single hour. At 11:00 UTC on June 22, GPTBot executed a systematic evaluation of our entire Copilot content cluster. This pattern — a concentrated burst of structural crawling — suggests OpenAI’s systems identified our domain as a potential authority source and performed a deep evaluation to assess the breadth and depth of our coverage.

    Bingbot: first to every article, 4-hour gap. Bingbot consistently arrived at each new article within approximately 4 hours of publication, triggered by our IndexNow implementation. This reliability confirms that IndexNow is not just a faster path to indexing — it is a predictable, repeatable mechanism for getting content into Bing’s index on a known timeline.

    3 confirmed Copilot referrals. Within the first 24 hours, we recorded 3 visits with referral source copilot.microsoft.com, 2 of which carried the utm_source=copilot.com parameter. These are confirmed citations — instances where a user saw our content cited in a Copilot answer and clicked through to our page.

    Common Mistakes That Prevent Copilot Citations

    Based on our experiment and ongoing analysis, here are the most common reasons content fails to earn Copilot citations:

    No IndexNow implementation. Without IndexNow, you are relying on Bing’s organic crawl schedule, which can take days or weeks. Copilot cannot cite content that is not in Bing’s index.

    Missing or incomplete schema markup. Content without structured data is harder for AI systems to parse, understand, and cite. At minimum, every article should have Article schema and FAQPage schema.

    Generic, non-entity-specific content. Articles that discuss topics in generic terms without naming specific products, versions, companies, or technical concepts are less likely to be selected as citation sources by AI retrieval systems.

    Wall-of-text formatting. AI extraction systems perform better with clearly structured content: defined heading hierarchies, short paragraphs, comparison tables, and numbered lists. Dense prose without structural markers is harder to extract from.

    Ignoring server logs. Without server log monitoring, you have no visibility into whether AI crawlers are even visiting your content. You are operating blind — unable to see what is working, what is being ignored, and where to focus optimization efforts.

    Scaling This Playbook Across Your Content Portfolio

    The methodology described here is not limited to Microsoft Copilot content. The same principles — rapid indexing, structured data, AEO optimization, entity density, and content clustering — apply to earning citations from any AI system that uses web retrieval: ChatGPT, Google AI Overviews, Perplexity, and Claude’s web search. The difference is that Copilot’s reliance on Bing’s index makes IndexNow the fastest path, while Google’s AI Overviews require Google’s own indexing pipeline, which is historically slower.

    To scale this approach, apply the same content architecture to every topical cluster on your site. Identify the queries your audience asks AI assistants, write content that directly answers those queries with entity-rich specificity, structure it for extraction with schema markup and AEO formatting, and ensure rapid indexing via IndexNow. Monitor your server logs to confirm AI crawlers are discovering and evaluating your content, and iterate based on what the data tells you.

    Our 40-article experiment was proof of concept. The 6,805 AI crawler hits and 3 confirmed Copilot citations within 24 hours demonstrate that this is not theoretical — it is a repeatable, scalable methodology backed by primary data. The AI search landscape rewards publishers who understand how AI crawlers work and optimize for their specific discovery and evaluation patterns. This playbook gives you the exact steps to do that.

    Frequently Asked Questions

    How long does it take to get cited by Microsoft Copilot after publishing?

    With IndexNow enabled, Bingbot typically discovers new content within 4 hours of publication. From there, Copilot can begin citing indexed content almost immediately. In our experiment, we recorded confirmed Copilot citation referrals from copilot.microsoft.com within 24 hours of publishing 40 optimized articles (Tygart Media server log analysis, June 2026). Without IndexNow, the indexing delay can stretch to days or weeks, pushing the citation timeline out proportionally.

    What is IndexNow and why is it essential for Copilot citation?

    IndexNow is a web protocol that allows publishers to instantly notify participating search engines — including Bing, Yandex, and others — when content is published, updated, or deleted. For Copilot citation, IndexNow is essential because Copilot retrieves answers from Bing’s search index. Content that is not indexed by Bing cannot be cited by Copilot, regardless of its quality. IndexNow eliminates the indexing delay, making 24-hour citation achievable.

    What types of schema markup help with Copilot citations?

    The three most effective schema types for Copilot citation are Article schema (which establishes content type, authorship, and publication metadata), FAQPage schema (which structures question-answer pairs for direct extraction by AI systems), and BreadcrumbList schema (which provides site hierarchy context). Implementing all three creates multiple structured pathways for AI systems to understand, evaluate, and cite your content.

    Can I track whether Microsoft Copilot is citing my content?

    Yes, through two methods. First, monitor your analytics for referral traffic from copilot.microsoft.com — look for the utm_source=copilot.com parameter, which confirms a user clicked through from a Copilot citation. Second, use Bing Webmaster Tools’ AI Performance dashboard, which was launched in public preview in February 2026, to see citation metrics including total citations, grounding queries, and page-level citation activity for your verified domain.

    What is the difference between AEO and GEO for Copilot optimization?

    Answer Engine Optimization (AEO) focuses on making content easy for AI systems to extract — using question-formatted headings, definition boxes, direct answers in the first 50 words, and structured FAQ sections. Generative Engine Optimization (GEO) focuses on making content authoritative enough to be selected for citation — through entity density, factual specificity, named sources, and topical authority signals. Both are necessary for consistent Copilot citations: AEO makes your content extractable, and GEO makes it the preferred source to extract from.

    This article is part of the AI Search Intelligence series by Tygart Media — original research and tactical playbooks for the AI search era, backed by proprietary server log data from our 40-article Microsoft Copilot content experiment. Related reading: Microsoft Copilot Pricing Compared | Copilot for Small Business vs Enterprise | The Complete M365 Copilot Productivity Guide

  • IndexNow Speed Test: How Fast Do Bing, (2026)

    IndexNow Speed Test: How Fast Do Bing, (2026)

    IndexNow promises instant content discovery. But how fast is it really? We ran a controlled speed test — 40 articles published simultaneously to tygartmedia.com with IndexNow pings fired on every one — then measured exactly how long it took Bing, GPTBot, Google, and every other crawler to show up. The timestamps tell a story that IndexNow’s marketing materials do not.

    This is the second article in Tygart Media’s AI Search Intelligence series, based on proprietary server log data from our 40-article Microsoft Copilot content experiment conducted on June 22, 2026. Every timestamp and crawl interval cited here comes directly from our server access logs.

    What Is IndexNow and Why Speed Matters

    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    What IndexNow is and why speed matters.

    IndexNow is an open-source protocol that lets websites notify participating search engines the moment content is published or updated. Instead of waiting for a crawler to discover your new page organically — which can take days or weeks — IndexNow sends a direct ping saying “this URL has new content, come get it.”

    Microsoft developed IndexNow and Bing is its primary participant. Yandex, Naver, Seznam, and several other engines also participate. Google does not. As of early 2026, over 60 million websites use IndexNow, and 22% of clicked Bing URLs come from IndexNow submissions, according to Bing’s published data.

    For publishers, the speed question is not academic. If you are publishing time-sensitive content — news, product launches, competitive analysis — the difference between a 3-hour crawl delay and a 3-day crawl delay determines whether your content gets indexed before or after your competitors. And in the AI era, the question extends beyond traditional indexing: how fast do AI crawlers like GPTBot find your new content?

    Our Test Setup: 40 Articles, One Timestamp

    On June 22, 2026, we published 40 original articles about Microsoft Copilot to tygartmedia.com. The site runs WordPress with RankMath SEO on a Google Cloud Platform Compute Engine instance. RankMath handles IndexNow submissions automatically on publish.

    Every article was published within a short window, and IndexNow pings were fired for each URL. We then monitored our raw server access logs for every subsequent crawler visit, recording the user-agent string, timestamp, and requested URL for each hit.

    This gave us a clean dataset: 40 identical test cases (same site, same publish time, same IndexNow submission) with crawler-by-crawler arrival times we could compare head-to-head.

    Head-to-Head Results: Who Arrived First?

    Topic platform fit visual for first-party AI citation measurement
    Head-to-head: who arrived first.

    Bing: 3 to 6 Hours via IndexNow

    Bingbot was the first traditional search engine crawler to reach our content, arriving within 3 to 6 hours of IndexNow submission. The pattern was remarkably consistent across all 40 articles — most fell within a tight 4-hour window from publication to first crawl.

    This is fast by search engine standards but not instant. IndexNow does not trigger immediate crawling. It places your URL into Bing’s priority crawl queue, and Bing processes that queue on its own schedule. For our batch of 40 articles, that schedule produced a 3-to-6-hour window with high consistency.

    For context, without IndexNow, new content on a site with our domain authority profile might wait 24 to 72 hours for Bing to discover it through sitemap parsing or link following. IndexNow compressed that to under 6 hours — a meaningful improvement for any publishing operation.

    GPTBot: Faster Than Bing

    Here is the result that surprised us most: GPTBot arrived at our content faster than Bingbot in many cases, despite GPTBot not being an official IndexNow participant.

    GPTBot is OpenAI’s crawler. It does not receive IndexNow pings directly. Yet it consistently reached our newly published articles before Bing’s own crawler had finished processing the IndexNow queue. At 11:00 UTC on June 22, GPTBot executed a 1,123-request structural crawl in a single hour, hitting not just article URLs but every tag, feed, and REST API endpoint on the site (Tygart Media server log analysis, June 2026).

    How does GPTBot discover content faster than IndexNow delivers it to Bing? The most likely explanation is that GPTBot monitors RSS feeds, sitemaps, or other real-time content signals independently. WordPress sites broadcast new content through multiple channels — RSS feeds update instantly, XML sitemaps regenerate on publish, and REST API endpoints reflect new posts immediately. GPTBot appears to be monitoring one or more of these channels with higher polling frequency than Bing’s IndexNow processing queue.

    The implication for publishers is significant: even if you do not use IndexNow, GPTBot is likely to find your new content quickly through other discovery mechanisms. But IndexNow remains essential for Bing-ecosystem discovery, which feeds Microsoft Copilot’s citation pipeline.

    YandexBot: 30 Seconds Behind Bing

    YandexBot arrived at each article approximately 30 seconds after Bingbot, with remarkable consistency across the full batch. Yandex participates in the IndexNow protocol, and this timing suggests Yandex processes IndexNow submissions from the same shared queue but with a slight processing delay relative to Bing (Tygart Media server log analysis, June 2026).

    The 30-second shadow is too consistent to be coincidental. It points to either a shared IndexNow notification infrastructure where Yandex processes submissions fractionally behind Bing, or to Yandex monitoring Bing’s crawl activity directly. Either way, publishers who submit to IndexNow get both Bing and Yandex coverage from a single ping.

    Googlebot: Effectively Absent

    Googlebot recorded only 1 hit on our Copilot content in the initial crawl window (Tygart Media server log analysis, June 2026). One hit. Across 40 articles. While Bing had crawled every article within 6 hours and GPTBot had mapped the entire site architecture.

    Google does not participate in IndexNow. Google has stated publicly that it relies on its own crawl scheduling, which considers factors like site crawl budget, historical update frequency, and sitemap change signals. For a batch of 40 new articles on a topic the site had not previously covered, Google’s algorithms apparently did not prioritize rapid discovery.

    This is not a criticism of Google’s approach — its crawl scheduling optimizes for different goals than real-time discovery. But for publishers who need content indexed quickly, the data is unambiguous: IndexNow-participating engines discover content in hours. Google discovers it on its own timeline.

    The IndexNow Technical Gotcha We Discovered

    During our experiment, we identified a technical issue that could affect other publishers: the IndexNow key file was returning a 404 at the standard verification paths where search engines expect to find it.

    IndexNow requires a verification key file at your site root (e.g., yourdomain.com/{key}.txt). Search engines check this file to confirm you authorized the IndexNow submission. In our case, the key file was not accessible at the expected root-level path, which should have caused verification failures.

    RankMath SEO’s fallback mechanism saved us — it handles IndexNow key verification through an alternative method that does not require the physical key file to exist at the root URL. But publishers using manual IndexNow implementations, or other SEO plugins without this fallback, should verify their key file is accessible by navigating directly to the expected URL.

    If your IndexNow submissions seem to be ignored by Bing, check the key file first. A 404 on the verification file silently kills the entire pipeline — Bing will not crawl the submitted URLs without successful verification.

    What the Speed Test Means for Your Publishing Strategy

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What the speed test means for publishing strategy.

    For Bing and Copilot Visibility

    IndexNow is the fastest path to Bing’s index, and Bing’s index feeds Microsoft Copilot’s citation system. Our 40-article experiment earned 3 confirmed Copilot citation referrals within 48 hours, and that pipeline started with IndexNow getting our content into Bing’s index within hours of publication.

    If you are publishing content that you want Copilot to cite, IndexNow is not optional — it is the first link in the citation chain.

    For AI Crawler Discovery

    GPTBot does not use IndexNow, but it finds new content fast anyway — faster than Bing in our test. This means your site’s real-time content signals (RSS feeds, sitemaps, REST API endpoints) are the discovery mechanism for OpenAI’s crawler ecosystem. Keep these endpoints clean, accessible, and unblocked in your robots.txt if you want AI systems to discover your content quickly.

    For Google

    Google’s crawl scheduling operates independently of IndexNow. If rapid Google indexing is important to you, continue submitting sitemaps through Google Search Console and requesting indexing for priority pages through the URL Inspection tool. Do not rely on IndexNow for Google discovery — the protocol has no effect on Google’s crawl behavior based on our data.

    For Multi-Engine Strategy

    The practical recommendation is to run both systems in parallel: IndexNow for Bing, Yandex, and the downstream AI systems that rely on Bing’s index, plus Google Search Console for Google’s independent crawl pipeline. Most WordPress SEO plugins handle IndexNow automatically, so the incremental effort is near zero.

    The Speed Hierarchy: From Fastest to Slowest

    Based on our server log data from the 40-article experiment, here is the definitive crawl speed ranking for newly published, IndexNow-submitted content (Tygart Media server log analysis, June 2026):

    1. GPTBot — fastest overall; arrived before IndexNow results in many cases; 1,123-request structural crawl in one hour
    2. ChatGPT-User — 3,404 hits over 48 hours; activates when real users query ChatGPT about relevant topics
    3. Bingbot — 3 to 6 hours via IndexNow; consistent, predictable timing
    4. YandexBot — ~30 seconds behind Bingbot; piggybacks on IndexNow shared infrastructure
    5. OAI-SearchBot — 3 hits total; minimal presence; appears highly selective
    6. AzureAI-SearchBot — 3 hits total; minimal presence
    7. Googlebot — 1 hit in initial window; operates on its own schedule independent of IndexNow

    The gap between the top of this list and the bottom is not hours — it is the difference between same-day discovery and multi-day (or longer) discovery. For publishers who need content discovered quickly, the AI crawlers and IndexNow-participating engines are delivering results that Google’s independent crawl schedule simply does not match.

    A Note on Methodology and Reproducibility

    Every crawl timestamp and interval cited in this article comes from raw server access logs on Tygart Media’s Google Cloud Platform Compute Engine instance, analyzed in June 2026. Crawler identification was performed by user-agent string matching, with IP range verification against OpenAI’s and Microsoft’s published crawler IP ranges for additional confirmation.

    The 40-article batch was published simultaneously to control for timing variables. All articles were submitted via IndexNow through RankMath SEO’s automatic submission feature. No manual crawl requests were submitted through Google Search Console, Bing Webmaster Tools, or any other interface — we wanted to measure organic and IndexNow-driven discovery only.

    This experiment is reproducible. Any publisher running a WordPress site with IndexNow enabled can monitor their server access logs after a batch publish and observe the same crawler patterns. The specific timing intervals may vary based on domain authority, server location, and crawl budget allocation, but the relative ordering — GPTBot fastest, Bing via IndexNow in hours, Google on its own schedule — should hold across most publishing environments.

    For the complete dataset including all crawler hit counts and the full methodology, see our anchor article: We Published 40 Articles and Watched Every AI Crawler in Real Time.

    Frequently Asked Questions

    How fast does IndexNow actually get content crawled by Bing?

    In our controlled test of 40 simultaneously published articles, IndexNow submissions resulted in first Bingbot crawls within 3 to 6 hours, with most articles falling in a consistent 4-hour window. This is significantly faster than the 24-to-72-hour organic discovery timeline for sites without IndexNow, but it is not instant — Bing queues IndexNow submissions and processes them on its own crawl schedule (Tygart Media server log analysis, June 2026).

    Does GPTBot use IndexNow to discover content?

    No. GPTBot is not an IndexNow participant, yet it arrived at our content faster than Bingbot in many cases. GPTBot appears to monitor RSS feeds, XML sitemaps, or REST API endpoints independently, giving it a faster discovery pipeline than Bing’s IndexNow processing queue. In our experiment, GPTBot executed a 1,123-request structural crawl at 11:00 UTC, mapping the entire site architecture within a single hour (Tygart Media server log analysis, June 2026).

    Does Google support IndexNow?

    No. Google does not participate in the IndexNow protocol as of June 2026. In our experiment, Googlebot recorded only 1 hit on our 40-article batch while Bingbot and GPTBot had fully crawled the content. Google relies on its own crawl scheduling algorithms and recommends using Google Search Console’s sitemap submission and URL Inspection tool for prioritized crawling (Tygart Media server log analysis, June 2026).

    Why was YandexBot always 30 seconds behind Bingbot?

    YandexBot, as an IndexNow participant, appears to process submissions from a shared notification infrastructure with a slight delay relative to Bing. The consistent 30-second gap across all 40 articles suggests either a shared queue processed fractionally behind Bing or direct monitoring of Bing’s crawl activity. The practical result is that a single IndexNow ping delivers both Bing and Yandex crawls almost simultaneously (Tygart Media server log analysis, June 2026).

    What should publishers do if IndexNow submissions are being ignored by Bing?

    Check your IndexNow key file first. The key file must be accessible at your domain root (e.g., yourdomain.com/{key}.txt). In our experiment, the key file was returning a 404 at standard paths, which would have silently killed the pipeline. Our RankMath SEO plugin’s fallback mechanism handled verification, but publishers using manual implementations should navigate directly to their key file URL to confirm it returns a 200 response (Tygart Media server log analysis, June 2026).