Last verified: October 2026. Claude Code is Anthropic's terminal coding tool — it lives where developers live, in the command line. Around it has grown a small universe: install paths, seat pricing, credit pools, rate limits, and three sibling agent surfaces that people constantly confuse with it. This guide is the map.
Installing it: two minutes, pick your path
On Windows, it's PowerShell, one command, no Node.js required — the native install path, verified against the May 2026 installer, including the five errors you’ll hit and the exact fix for each. For the general path, it's the one-line npm CLI install plus the Desktop app, done in under two minutes, with the common errors covered.
→ Install Claude Code on Windows: 2026 Step-by-Step — the Windows path: one command, five errors, five fixes.
→ Install Claude Code: Complete Desktop & CLI Setup Guide — the general path: npm one-liner, Desktop app, troubleshooting.
What it costs: seats, tiers, and the API meter
Claude Code rides on your existing seat — Pro ($20/month), Max ($100 or $200/month), Team, or Enterprise. The API path is a separate console meter, not drawn from your seat. If you're deciding between Pro and Max for dev work, the question is usage volume: Max is for the people who live in the terminal all day.
→ Claude Code Pricing in 2026: Pro vs Max vs API Costs Explained — seats vs API, verified September 2026, with current token rates on the pricing hub.
→ Claude Code Pricing 2026: Pro, Max, and API Limits — the tier comparison for dev workflows, including Opus 4.7 API rates.
How the billing actually works: subscriptions vs credit pools
This is the part that surprises people. Interactive terminal use draws on your Pro/Max subscription — it's part of the seat. But since June 15, 2026, Agent SDK and headless (claude -p) usage moved to separate monthly billing. Same tool, two meters, depending on how you invoke it. Know which one you're on before the invoice teaches you.
→ Claude Code Billing & Monthly Credit Pools (2026) — subscription draw vs separate Agent billing, and how the credit pools work.
The limits: two clocks
Claude Code meters two clocks: a rolling 5-hour session window and a weekly bucket. The +50% weekly promo ended September 13, 2026 — what replaced it is a permanent +25% on the weekly limits. Note the model gating: Fable 5.1 is included only on Max and premium seats.
→ Claude Code Limits (September 2026) — both clocks explained, what's permanent, and where Fable 5.1 is available.
Picking your surface: Cowork vs Code vs Agent SDK vs Managed Agents
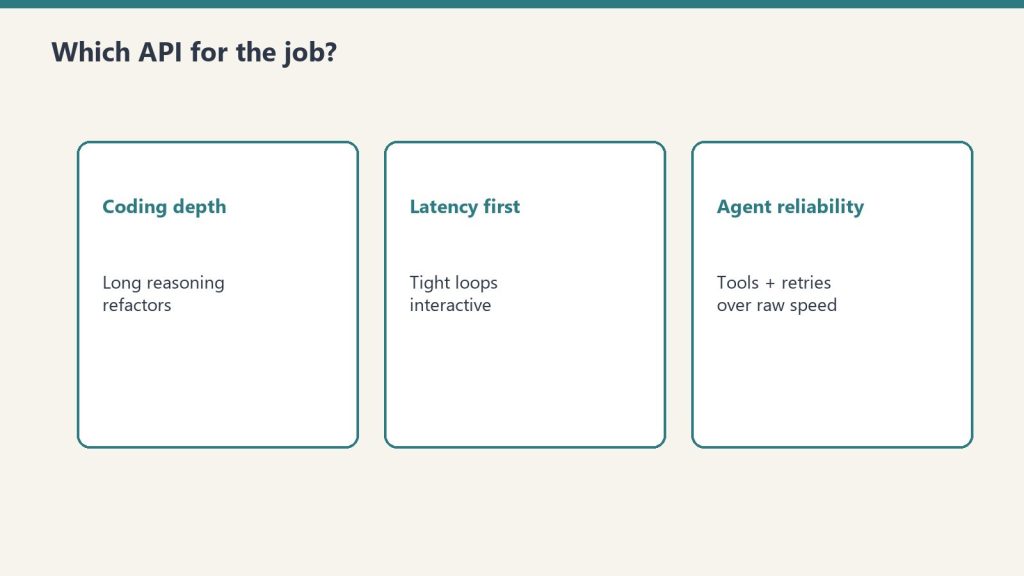
Anthropic now has four agent surfaces and they are not interchangeable: Claude Code, Claude Cowork, the Agent SDK, and Managed Agents. Interactive vs autonomous is the real dividing line — which surface fits depends on who's driving and how much autonomy the job needs.
→ Claude Cowork vs Code vs Agent SDK vs Managed Agents (2026) — the decision matrix: who each surface is for and where each runs.
Cowork in action: the daily briefing
The canonical Cowork workflow: connect your calendar, email, and tasks, write the right prompt, and schedule it to run automatically every morning. A briefing that builds itself before you've had coffee. It's the clearest demo of what the non-code surface is for.
→ Claude Cowork: Daily Briefing & Automated Sync (2026) — setup, prompt design, and scheduling.
Eight deep dives, one hub. Install it, price it, learn the billing and limits, then pick the right surface for the job.