Author: William Tygart

  • California SB 253 Scope 3 Rules for Facility Managers

    California SB 253 Scope 3 Rules for Facility Managers

    California’s Climate Corporate Data Accountability Act — SB 253 — is the most consequential piece of corporate climate disclosure legislation in the United States. For facility managers at large corporate occupiers, its Scope 3 provision creates a specific and urgent vendor management problem that most FM teams have not yet fully reckoned with.

    What SB 253 Actually Requires

    SB 253 requires companies with annual revenues exceeding $1 billion that do business in California to publicly disclose their greenhouse gas emissions. The disclosure schedule is phased:

    • Scope 1 and Scope 2: First reports due in 2026 (covering fiscal year 2025 data)
    • Scope 3: First reports due in 2027 (covering fiscal year 2026 data)

    The California Air Resources Board (CARB) is the administering body. Reports must be independently verified by a third-party auditor. The law applies to any company doing business in California — not just California-headquartered companies — which means the net is significantly wider than the state’s own corporate population.

    This is not a voluntary framework. SB 253 carries penalties for non-compliance. The Scope 3 provision is the one that creates a direct operational problem for FM teams, because Scope 3 data lives outside your organization — in your contractors’ job management systems.

    The Contractor Data Chain
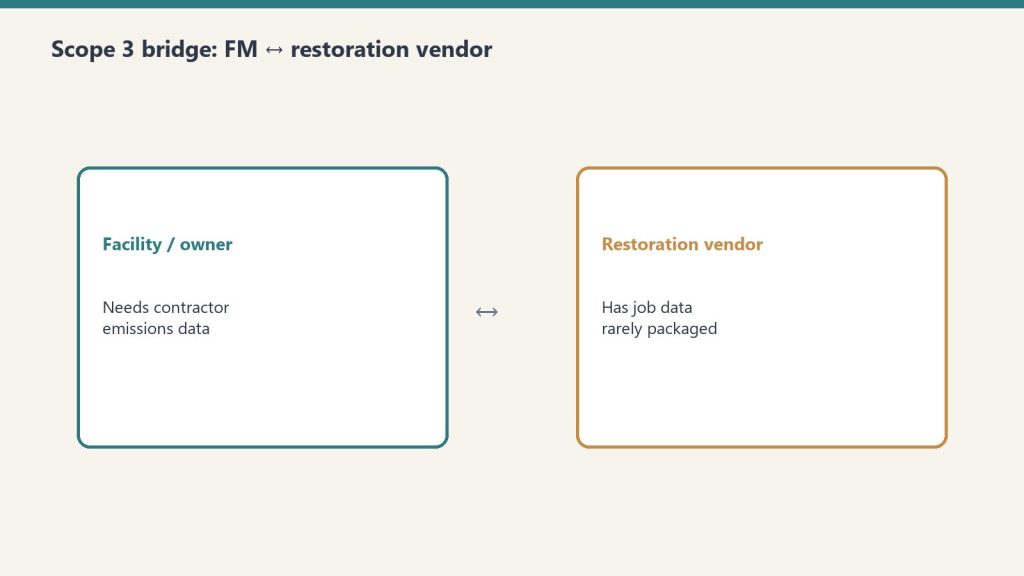
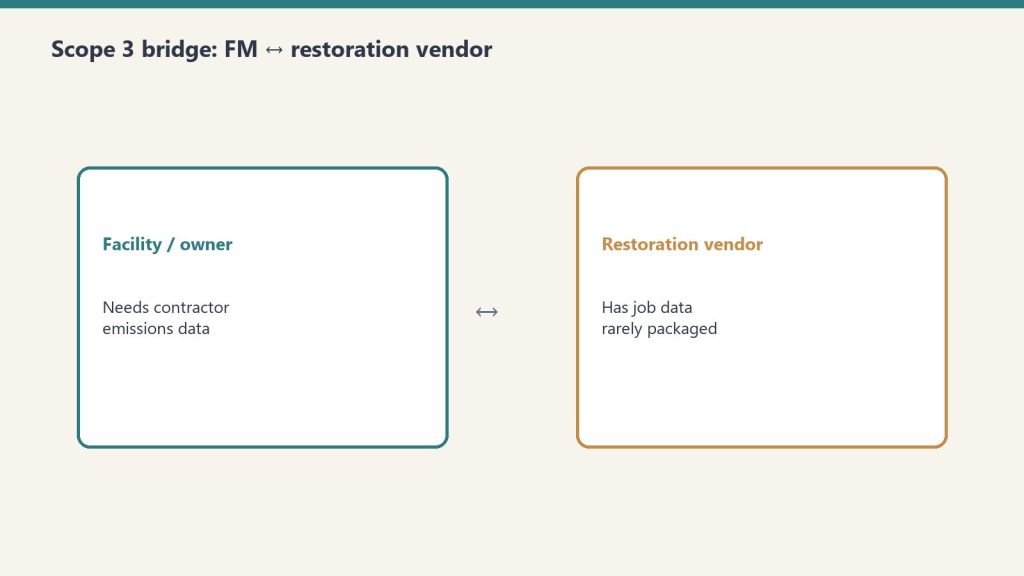
    Facility manager to restoration vendor Scope 3 data bridge
    The contractor data chain under SB 253.

    Under the GHG Protocol’s Scope 3 framework — which SB 253 uses as its methodological basis — your restoration contractors are a Category 1 (Purchased Goods and Services) supplier. Every time you hire a restoration company to respond to a water intrusion event, a fire damage claim, or a mold remediation project, that contractor’s emissions for that job are technically part of your Scope 3 inventory.

    The calculation is not optional. The GHG Protocol requires organizations to make a reasonable effort to quantify all material Scope 3 categories. For a large corporate occupier with a substantial real estate portfolio, emergency restoration is a recurring and quantifiable Category 1 exposure. Your ESG auditor will ask about it. Your SB 253 filing will need to account for it.

    Why Most Restoration Contractors Cannot Provide This Data Today
    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Most restoration contractors cannot provide this data today.

    The restoration industry has no Scope 3 standard. IICRC — the primary certification body for restoration professionals — has no ESG reporting guidance. RIA has no Scope 3 framework. Most restoration contractors manage their operations through job management software that tracks labor hours, materials, and job costs — not emissions.

    This is not negligence; it is a gap that simply has not been filled until now. The Restoration Carbon Protocol (RCP) is the first industry self-standard that defines how restoration contractors should calculate and report their Scope 3 emissions data. It gives contractors the methodology, the data capture template, and the calculation framework — and it gives FM procurement teams the standard they can reference in vendor contracts.

    What to Put in Your Vendor Agreements Now
    Clipboard and tablet on a kitchen counter during an insurance adjuster walkthrough after water loss
    Put requirements in vendor agreements now.

    The most practical SB 253 preparation step for FM procurement teams is to update restoration vendor agreements to include a Scope 3 data provision clause. Here is the language framework:

    “Vendor agrees to provide a per-project greenhouse gas emissions summary for each project completed at Client facilities, using a documented calculation methodology consistent with GHG Protocol Scope 3 Category 1 guidelines. The summary shall include: total fuel consumption by equipment type, vehicle miles traveled, waste materials removed by type and weight, and total equipment operating hours. Submissions shall be provided within 30 days of project completion.”

    This clause does not require contractors to be ESG experts. It requires them to track and report the underlying data points from which a Scope 3 calculation can be made. Contractors who have adopted the RCP framework already capture this data as part of their standard job documentation.

    The Retroactive Data Problem

    SB 253 requires disclosure for fiscal year 2026 data, meaning the clock is already running. If your organization does business in California and exceeds the revenue threshold, your restoration vendors should be tracking Scope 3 data for jobs completed throughout 2026. Waiting until late 2026 to request this data will result in gaps that your ESG auditor will flag.

    For restoration jobs already completed in 2025 and early 2026, proxy-based estimation is acceptable under GHG Protocol methodology when primary data is unavailable. The RCP provides proxy calculation tables for each restoration job type, allowing FM teams to estimate historical emissions from basic job records (square footage treated, job duration, equipment type). This is not ideal, but it is methodologically defensible and far better than a data gap.

    The SB 253 Compliance Checklist for FM Teams

    1. Confirm whether your organization meets the SB 253 threshold (>$1B revenue, does business in California)
    2. Identify all restoration and specialty trade contractors in your vendor pool as Category 1 Scope 3 sources
    3. Update vendor agreements with a Scope 3 data provision clause (language above)
    4. Share the RCP framework with active vendors so they understand what data to capture
    5. Establish a process for collecting and storing per-job emissions summaries in your FM system
    6. Engage your ESG consultant to integrate contractor data into your Scope 3 Category 1 calculation methodology
    7. Plan for third-party verification of your Scope 3 data — auditors will scrutinize Category 1 more than any other category

    Related on Tygart Media: contractor ESG clauses for Scope 3 · facility ESG frameworks (GRESB / CDP / SB 253) · RCP for property owners.

    Frequently Asked Questions

    Does SB 253 apply if my company is not headquartered in California?

    Yes. SB 253 applies to any company that “does business in California” and meets the revenue threshold. This is broadly interpreted to include companies with California employees, customers, or operations — even if they are incorporated and headquartered elsewhere.

    What is the penalty for non-compliance with SB 253 Scope 3 provisions?

    CARB has authority to assess administrative penalties for non-compliance. The specific penalty structure is being finalized through rulemaking. Consult your legal counsel for the current enforcement guidance applicable to your organization.

    Can I use a spend-based methodology for restoration contractor Scope 3 data?

    Spend-based estimation (using economic input-output data) is permitted under GHG Protocol methodology as a fallback when primary or activity-based data is unavailable. However, third-party auditors generally flag spend-based estimates as lower quality than activity-based calculations. For a recurring Category 1 source like restoration contractors, building toward activity-based data is the appropriate goal.

    Part of the IFMA Scope 3 series on tygartmedia.com. Source: California SB 253 text via California Air Resources Board.
  • Scope 3 Contractor Data: A Guide for Facility Managers

    Scope 3 Contractor Data: A Guide for Facility Managers

    If you manage facilities for a large corporate occupier, you have almost certainly heard the phrase “Scope 3 emissions” from your sustainability team, your CFO, or your ESG consultant. What you may not have heard is a clear explanation of what that means for your day-to-day vendor management — and why the contractors who respond to your water damage and mold remediation calls are sitting in the middle of your most difficult compliance gap.

    The Three Scopes: A Plain-Language Primer

    Bridge between facility owners and restoration vendors for Scope 3 data
    Three scopes primer — contractors sit in Scope 3.

    The GHG Protocol’s Corporate Standard divides greenhouse gas emissions into three categories based on where they originate relative to your organization’s operations:

    • Scope 1 — Direct emissions from sources your organization owns or controls. The combustion in your building’s boilers, the fuel in your company-owned fleet vehicles, the refrigerants in your HVAC systems.
    • Scope 2 — Indirect emissions from purchased electricity, heat, or steam. The power your facilities consume from the grid.
    • Scope 3 — All other indirect emissions across your value chain. Everything that happens upstream (your supply chain) and downstream (how your products or services are used) that generates emissions on your behalf.

    Scope 1 and Scope 2 are manageable. You own the sources or the meters. You have the data. Scope 3 is where it gets hard — because Scope 3 data lives in other organizations’ systems, not yours.

    The 15 Categories of Scope 3

    The GHG Protocol breaks Scope 3 into 15 categories across upstream and downstream activities. For a corporate FM managing occupied facilities, the most relevant upstream categories are:

    • Category 1 — Purchased Goods and Services: The emissions associated with producing and delivering everything your organization buys from third parties. For FMs, this includes every contractor, vendor, and service provider who performs work at your facilities — including your restoration contractors.
    • Category 2 — Capital Goods: Emissions from the production of capital equipment and major building systems your organization purchases.
    • Category 4 — Upstream Transportation and Distribution: Relevant when contractors transport materials and equipment to your site.
    • Category 5 — Waste Generated in Operations: Emissions from waste your organization generates — relevant when restoration work produces debris, contaminated materials, or demolition waste disposed of on your behalf.

    Why Contractors Are Your Hardest Data Category

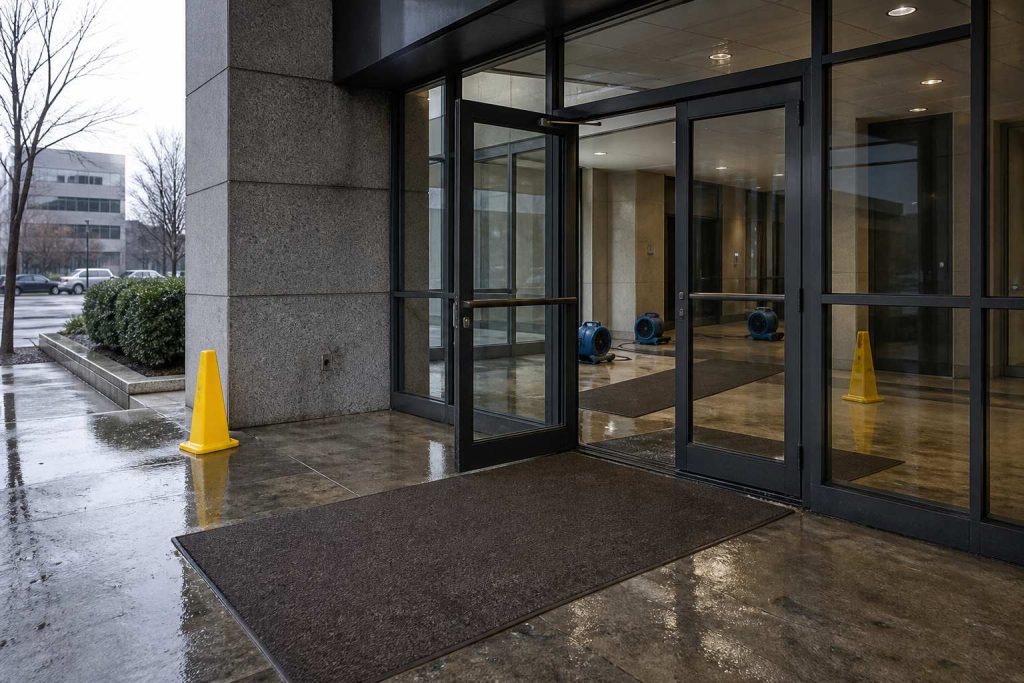
    Commercial office lobby entrance after a pipe burst with caution cones and wet runners
    Why contractors are your hardest data category.

    Among all the inputs to a corporate FM’s Scope 3 inventory, contractor-generated emissions are consistently the most difficult to quantify. Here is why:

    1. Contractors do not routinely track their own emissions. Most restoration, janitorial, maintenance, and specialty trade contractors have no internal system for calculating the greenhouse gas footprint of individual jobs. They track labor hours, materials costs, and square footage — not carbon.
    2. Restoration work is episodic. Unlike your regular janitorial or HVAC maintenance contractor, your restoration vendors are called in during emergencies. There is no standing purchase order to attach emissions data to. Each job is a separate event, often managed by a different project manager.
    3. No industry standard exists for restoration Scope 3 data. IICRC — the restoration industry’s primary certification body — has no ESG reporting standard. RIA has no Scope 3 guidance. There is no form, no template, no industry norm for what a restoration contractor should provide.
    4. The emissions profile of restoration work is complex. A single water damage job involves diesel-powered drying equipment running 24/7 for days, hazardous material disposal, multiple material categories, and vehicle trips from multiple crew members. Calculating the emissions accurately requires a methodology most contractors have never seen.

    The 2027 Problem

    California SB 253 — the Climate Corporate Data Accountability Act — requires companies with over $1 billion in annual revenue doing business in California to disclose their Scope 3 emissions starting with the 2027 reporting year. The EU’s CSRD is already in effect and expanding. CDP and GRESB already request Scope 3 data from the organizations they track.

    For FMs at large corporate occupiers, this creates a specific operational problem: your sustainability team needs contractor emissions data for the 2027 filing, your contractors do not have a system for providing it, and there is no industry standard to point them to. The gap between the regulatory requirement and the contractor’s current capability is the problem this publication addresses.

    What Good Contractor Scope 3 Data Looks Like

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    What good contractor Scope 3 data looks like.

    The Restoration Carbon Protocol (RCP) defines 12 data points that every restoration job ticket should capture to enable Scope 3 calculation. At a minimum, FM procurement teams should be asking their restoration vendors for:

    • Total fuel consumed by diesel-powered drying and dehumidification equipment (gallons)
    • Total vehicle miles traveled by contractor crews to and from the site
    • Weight and type of waste materials removed and method of disposal
    • Refrigerants used or recovered (for HVAC-adjacent restoration work)
    • Materials installed by type and weight (for reconstruction phases)
    • Total job duration and equipment operating hours

    With these inputs, a standardized calculation using EPA emission factors can produce a per-job carbon estimate that satisfies Scope 3 Category 1 methodology. The RCP provides exactly that calculation framework — free for any contractor or FM team to use.

    What to Do Now

    If the 2027 Scope 3 deadline is on your radar, the most practical steps you can take today are:

    1. Audit your vendor pool for contractors who perform Category 1 services. Restoration, abatement, specialty trades, and maintenance contractors are your highest-priority Scope 3 data gaps.
    2. Include a Scope 3 data provision clause in new vendor agreements. Require contractors to provide a per-job emissions summary using a standardized methodology.
    3. Share the RCP framework with your restoration vendors. It gives them the methodology, the data capture form, and the calculation tools — everything they need to start providing compliant data on the next job.
    4. Start tracking now, even if imperfectly. A reasonable estimate based on available data is better than a data gap. Your ESG auditor would rather see a documented methodology with known limitations than a blank line item.

    Frequently Asked Questions

    Does every facility manager need to report Scope 3?

    Mandatory Scope 3 reporting under SB 253 applies to companies with over $1 billion in annual revenue doing business in California. CSRD applies to large EU entities. Many FMs at smaller organizations will face voluntary disclosure pressure through CDP participation, GRESB assessments, or investor requirements. Regardless of regulatory mandate, proactively building Scope 3 data capability now reduces compliance cost later.

    Are restoration contractors required to provide Scope 3 data?

    Not yet — but their FM clients increasingly will be required to report it. The most practical approach is to contractually require Scope 3 data from restoration vendors as part of vendor onboarding, rather than trying to collect it retroactively after a job is complete.

    Part of the IFMA Scope 3 series on tygartmedia.com.

  • IFMA vs BOMA Scope 3: ESG Reporting for Facility Managers

    IFMA vs BOMA Scope 3: ESG Reporting for Facility Managers

    When sustainability consultants talk about ESG in commercial real estate, they often treat IFMA and BOMA as interchangeable acronyms for “building people.” They are not. The distinction between these two associations is not a branding detail — it is a fundamental difference in who you work for, what buildings you manage, and which Scope 3 obligations land on your desk. Getting this wrong means applying the wrong compliance framework to the wrong problem.

    The Core Difference: Occupier vs. Owner

    Commercial office lobby entrance after a pipe burst with caution cones and wet runners
    Occupier vs owner — where each association lives.

    IFMA — the International Facility Management Association — primarily serves facility managers who work for corporate occupiers. These are the FMs at a hospital system, a university, a Fortune 500 headquarters, or a government agency. They manage buildings that their organization uses to do its business. They do not own those buildings as an investment. They are the operational stewards of space their organization occupies.

    BOMA — the Building Owners and Managers Association — primarily serves property owners and commercial property management firms. BOMA members typically work for organizations whose business model is real estate: they own or manage buildings as assets, lease space to tenants, and generate revenue from that occupancy. The building is the product, not the platform.

    This single distinction — occupier vs. owner — changes everything about how Scope 3 ESG obligations flow.

    The Scope 3 Map: Where Each Association Lives

    DimensionIFMA Member (Corporate FM)BOMA Member (Property Owner/Manager)
    Who they work forCorporate occupier — the end-user of spaceProperty owner or management firm
    Buildings managedBuildings their organization occupiesBuildings leased to tenants as a business
    Primary ESG driverCorporate sustainability disclosure; board-level ESG commitmentsAsset performance benchmarking; investor ESG requirements
    Key Scope 3 exposureContractor supply chain data gaps (Category 1); purchased servicesTenant energy use; embodied carbon in renovation; asset-level GRESB
    Restoration relevanceEvery emergency restoration job generates Scope 3 data the FM must captureTenant improvement work; asset restoration after casualty
    Reporting frameworkGHG Protocol Corporate Standard; California SB 253; EU CSRDGRESB Real Estate Assessment; ENERGY STAR; local building performance standards

    Why This Matters for Scope 3 Specifically

    Under the GHG Protocol’s Scope 3 framework, a corporate occupier’s emissions inventory must include the activities of every contractor who performs services at their facilities. Water damage restoration, fire and smoke remediation, mold abatement, asbestos removal — every one of these jobs generates greenhouse gas emissions that belong somewhere in the FM’s Scope 3 report. Specifically, restoration contractor activity typically falls under Category 1 (Purchased Goods and Services) or Category 14 (Franchises), depending on the contractual structure.

    The BOMA member’s Scope 3 picture is different. A property manager’s primary Scope 3 exposure is Category 13 (Downstream Leased Assets) — the energy and emissions generated by the tenants who occupy their buildings. Restoration work on a BOMA member’s asset matters for GRESB and insurance, but it is not the core Scope 3 data gap they are trying to solve.

    The IFMA member, by contrast, is the one whose sustainability team is currently trying to figure out how to get emissions data from their restoration vendor. They are the ones receiving questionnaires from CDP and GRESB asking about contractor emissions. They are the ones whose corporate ESG report will be incomplete without restoration job data. And right now, they have no standard way to get it.

    The 2027 Deadline Is the IFMA Problem, Not the BOMA Problem

    California’s SB 253 — the Climate Corporate Data Accountability Act — requires companies with over $1 billion in annual revenue doing business in California to disclose their Scope 3 emissions beginning in 2027. The EU’s Corporate Sustainability Reporting Directive (CSRD) is already in effect for large European companies, with phased expansion through 2026. Both frameworks require supply chain emissions data — which means contractor data.

    For the corporate FM managing a large occupier’s portfolio, this deadline is operational. Their sustainability team is assembling the Scope 3 inventory now. They need contractor emissions data now. Every restoration company they have worked with in the past three years is a potential data gap in their 2027 filing.

    BOMA members face a related but structurally different pressure: their tenants are the Scope 3 reporters. The property manager’s role is to provide energy use data to tenants, not necessarily to collect contractor emissions data for their own disclosure. This is a meaningful distinction. The compliance urgency for Scope 3 contractor data sits much more squarely with the IFMA member.

    The Missing Bridge: Restoration Contractors and Scope 3 Data

    Bridge diagram between facility owners and restoration vendors for Scope 3 data
    The missing bridge: restoration contractors and Scope 3 data.

    Here is the specific gap this publication exists to close: restoration contractors — the companies that respond to water damage, fire, mold, and environmental emergencies at commercial facilities — have no standardized way to provide Scope 3 emissions data to their FM clients. The International Institute of Cleaning and Restoration Certification (IICRC) has no ESG standard. The Restoration Industry Association (RIA) has no Scope 3 guidance. No industry body has built the framework that tells a restoration contractor what data to capture on each job ticket so their FM client can use it in a Scope 3 report.

    This is the problem the Restoration Carbon Protocol (RCP) was built to solve. The RCP is a Tygart Media-published industry self-standard that maps restoration job types to the GHG Protocol’s 15 Scope 3 categories, defines the 12 data points every job ticket should capture, and provides the calculation methodology restoration contractors need to produce credible emissions data. It is the operational bridge between the FM’s Scope 3 disclosure obligation and the restoration contractor’s job management system.

    What IFMA Members Should Be Asking Their Restoration Vendors Today

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    What IFMA members should ask restoration vendors today.

    If you are a facility manager with Scope 3 reporting obligations, here are the five questions you should be putting to every restoration contractor in your vendor pool:

    1. Can you provide a per-job emissions summary for each project you complete at our facilities? If the answer is no, that is a gap in your Scope 3 Category 1 data.
    2. Do you track materials disposed of by type and weight? Waste stream data is a required input for Scope 3 calculation under GHG Protocol methodology.
    3. Do you track vehicle and equipment fuel consumption for each project? Mobile combustion is a Category 1 input that most restoration contractors currently ignore.
    4. Are you familiar with the Restoration Carbon Protocol? RCP-aware contractors are already capturing the data FMs need.
    5. Would you be willing to complete a standardized carbon data form for each project? The RCP Job Carbon Report is a one-page form any contractor can complete without a sustainability consultant.

    Why Tygart Media Covers This Beat

    Tygart Media’s position in the restoration industry — through the Restoration Carbon Protocol, the Restoration Golf League network, and years of content production for restoration operators — gives us a direct view into the contractor side of this data gap. This IFMA Scope 3 category exists to build the FM side of the same bridge: to give facility managers the framework, vocabulary, and vendor guidance they need to close their Scope 3 contractor data gap before the 2027 deadline arrives.

    This is not a BOMA story. It is not a property management story. It is a facility management story — about the corporate occupier’s FM team trying to satisfy a board-level ESG commitment with incomplete data from contractors who have never been asked for it before. We are building the source of truth for that problem.

    Related on Tygart Media: contractor ESG clauses for Scope 3 · facility ESG frameworks (GRESB / CDP / SB 253) · RCP for property owners.

    Frequently Asked Questions

    What is the difference between IFMA and BOMA for ESG purposes?

    IFMA serves facility managers who manage buildings for corporate occupiers — organizations that use the space for their own operations. BOMA serves property owners and managers who lease space to tenants as a business. For Scope 3 ESG, IFMA members must capture contractor emissions data as part of their corporate supply chain disclosure, while BOMA members primarily focus on tenant energy use and asset-level performance benchmarking.

    Why do restoration contractors matter for IFMA Scope 3 reporting?

    Restoration contractors perform services at IFMA members’ facilities. Under the GHG Protocol, the emissions from those services are part of the corporate occupier’s Scope 3 inventory — typically Category 1 (Purchased Goods and Services). Without standardized emissions data from restoration vendors, the FM’s Scope 3 report has a recurring gap every time an emergency occurs at a managed facility.

    What is the Restoration Carbon Protocol?

    The Restoration Carbon Protocol (RCP) is an industry self-standard published by Tygart Media that maps restoration job types to GHG Protocol Scope 3 categories and defines the data restoration contractors should capture to enable their FM clients’ Scope 3 reporting. It is the first framework of its kind in the restoration industry.

    When does Scope 3 reporting become mandatory for large companies?

    California SB 253 requires Scope 3 disclosure for companies with over $1 billion in annual revenue doing business in California beginning in 2027. The EU’s CSRD is already in force for large European entities, with phased expansion through 2026. Many voluntary frameworks (CDP, GRESB) already request Scope 3 data.

    This article is part of Tygart Media’s IFMA Scope 3 category — the facility manager’s source of truth for Scope 3 ESG reporting and contractor data standards.

  • AI Citation Profiles: Optimize for Claude and Perplexity

    AI Citation Profiles: Optimize for Claude and Perplexity

    Last refreshed: October 20, 2026

    The phrase “optimize for AI search” is almost always wrong. There is no single AI search behavior. Claude, ChatGPT, and Perplexity each have distinct citation patterns — different content structures they reward, different page types they concentrate on, different signals they weight. Writing one undifferentiated article and hoping it gets cited across all three is the same mistake as writing one undifferentiated web page and hoping it ranks for every keyword. This cluster article covers the per-model citation playbook, built from GA4 data and the multi-model roundtable methodology in the Tygart Media Knowledge Lab.

    This is the final cluster in the Claude on a Budget series. For the token economics that make targeted content cheaper to produce, see Output Compression Discipline and Prompt Caching.

    The Three Citation Profiles

    Comparison of Claude how-to fit versus local service page fit for assistants
    Three citation profiles to optimize for.

    Claude (Anthropic): Concentrates heavily. GA4 data from sites in the Knowledge Lab shows Claude sending approximately 54.5% of its AI referral traffic to just 2 pages per site. It rewards content that is entity-dense, structurally authoritative, and written with speakable precision — defined terms, explicit relationships between concepts, factual density over narrative padding. Claude users tend to be technical and high-intent; the model reflects that by citing content that answers with precision rather than coverage. Approximately 90% of content on a typical site is invisible to Claude — it surfaces a small authoritative set and ignores the rest.

    ChatGPT (OpenAI): Spreads references broadly. Where Claude concentrates on 2 pages, ChatGPT may reference 8-12 across the same site. It rewards breadth, recency, and natural-language accessibility. Content structured like a knowledgeable friend explaining something clearly — without jargon walls — performs well. ChatGPT users skew toward general-purpose questions; the model cites content that covers the question conversationally without assuming deep domain expertise.

    Perplexity: Research-flavored. It rewards sourced claims, comparative tables, explicit statistics, and content that reads like a researched brief rather than an opinion piece or narrative. Perplexity users are actively in research mode; the model surfaces content that looks like it did the research so the user does not have to. Citation-rich, data-dense, table-formatted content punches above its traffic weight in Perplexity referrals.

    The Per-Model Content Shape

    ElementClaudeChatGPTPerplexity
    Density targetHigh — entity-rich, preciseMedium — accessible, broadHigh — sourced, comparative
    Best structureDefined terms, explicit relationships, OASFConversational headers, FAQ blocksTables, stat callouts, comparison matrices
    Ideal length1,500-2,500 words with tight structure800-1,500 words, readable flow1,000-2,000 words with data anchors
    Citation triggerAuthoritative entity coverageQuery-matching accessible answerSourced comparative data

    The Multi-Model Roundtable Methodology

    Three cards for solo takes, cross-pollination, and synthesis
    Multi-model roundtable methodology.

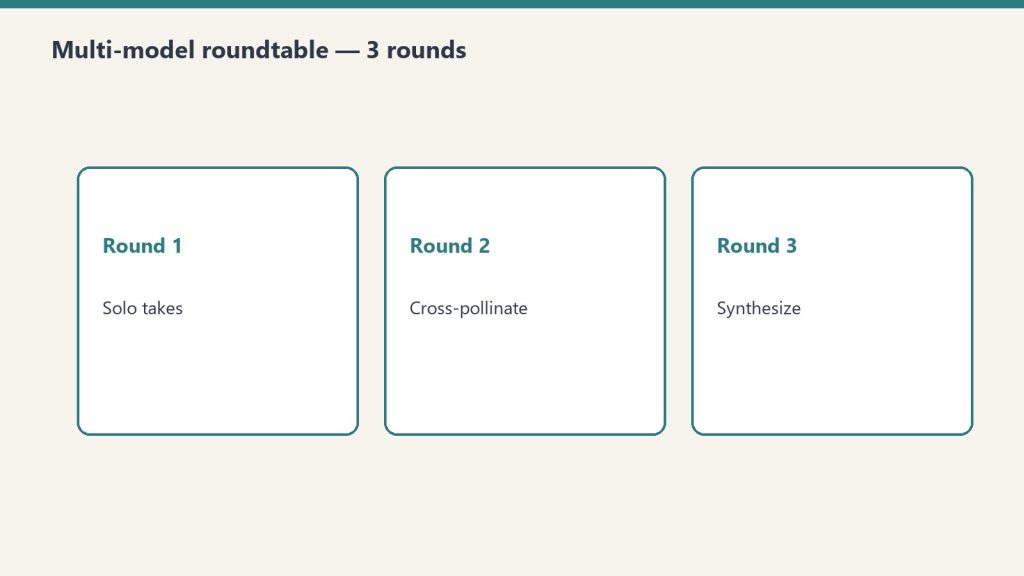
    The Tygart Media Knowledge Lab documents a specific workflow for content research that leverages multiple models’ citation profiles rather than fighting them. The pattern: route the initial research brief to a free or cheap model (Gemini Flash via OpenRouter, or Llama 3 free tier) for broad source gathering. Pass the source list to Claude for entity extraction and authoritative synthesis. Use the Claude-synthesized brief as the foundation for the final article draft. The output is content that is naturally entity-dense from Claude’s synthesis pass while covering enough ground to catch ChatGPT’s broader citation net.

    The token economics matter here: the expensive synthesis pass (Claude Sonnet 4.6 or Haiku) operates on a pre-filtered source set, not raw web content. Input tokens are lower because a cheaper model did the broad sweep. Claude’s output is higher-density because it is synthesizing structured inputs rather than processing noise. This is the OpenRouter multi-model pipeline in content production form.

    Writing for Claude Citation Specifically

    Four cards for content, ops, build, and knowledge work with Claude
    Writing for Claude citation specifically.

    If your primary goal is Claude citation — high-intent technical traffic, B2B contexts, developer audiences — the content discipline is: define every entity explicitly at first mention, state relationships between concepts directly (“X enables Y because Z”), use speakable sentence structures (subject-verb-object, no buried clauses), include a structured FAQ or definition block, and remove padding. Claude’s citation concentration on 2 pages per site means your best-performing page for Claude referrals will get the bulk of the traffic — invest in making that page entity-complete rather than spreading thin coverage across many pages.

    Writing for Perplexity Citation

    Perplexity citation optimization is the most actionable of the three because the signal is explicit: include comparative tables with real numbers, cite sources inline (even if just attributing claims to specific organizations or studies), use headers that read like research questions, and lead sections with data points rather than narrative. The content in this series — pricing tables, API code examples, usage statistics — is structured for Perplexity citation by design. Every table is a potential Perplexity extraction point.

    The Budget Connection

    Per-model content shaping is a budget strategy, not just a citation strategy. Writing one highly targeted, entity-dense 2,000-word article for Claude citation is cheaper to produce — fewer tokens, tighter output discipline — and more effective than producing three generic 1,500-word articles hoping one gets cited. Concentration over coverage: the same principle Claude uses to cite content, applied to content production itself. The output compression discipline from Cluster 6 makes this article type cheaper to generate. Dense, targeted content is both cheaper to produce with Claude and more likely to be cited by Claude. The budget and the citation strategy converge.

    The Full Claude on a Budget System

    This series has covered seven levers that compound: cold-start elimination via second brain, model routing by task tier, OpenRouter free model integration, Batch API for async 50% discount, prompt caching for 90% off repeated context, output compression discipline, and per-model citation shaping. None of these require negotiating with Anthropic’s pricing team. All of them are available today via the API. Applied together, they represent the difference between paying retail for Claude and operating it at professional efficiency — which, for most teams, means the same Claude capability at 40-70% of the sticker cost.

    Return to the full guide: Claude on a Budget: Complete Guide →

  • Claude Output Compression: Token Savings & Structured JSON

    Claude Output Compression: Token Savings & Structured JSON

    Last refreshed: October 20, 2026 (Pacific)

    Most Claude cost analyses focus on input tokens — the knowledge you send in. The underappreciated lever is output compression. Claude is trained to be thorough. Left unconstrained, it produces full meals: preambles, recaps, hedges, transition sentences, closing summaries. All of those tokens cost money. All of them are often unnecessary. Output discipline — getting Claude to deliver concentrated slices instead of full meals — is often the highest-leverage cost reduction available without changing models or switching to async.

    Why output deserves its own discipline: on every current Claude model, output tokens cost 5x their input counterparts. Verified output rates:

    Model Output (per MTok) Input (per MTok)
    Claude Fable 5.1$50.00$10.00
    Claude Opus 5.5$20.00$4.00
    Claude Sonnet 5.5$10.00$2.00
    Claude Haiku 4.5$5.00$1.00

    Every unnecessary output token costs five times what an input token costs. That ratio is what makes output compression the highest-leverage lever on this page.

    This is part of the Claude on a Budget series. For input-side compression, see The Cold-Start Problem. For pricing mechanics, see Prompt Caching.

    The Default Verbosity Problem

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    The default verbosity problem.

    Ask Claude to “summarize this document” without constraints and you will get: an opening sentence restating the task, a multi-paragraph summary, a bullet-point recap of the summary, and a closing note about what was not covered. The actual information density — insight per token — is low. You paid for 800 tokens of output and needed 150. Multiply across thousands of API calls and you have built a significant cost leak from default model behavior, not from bad prompts.

    Put dollars on it. A pipeline making 5,000 calls a day at 800 output tokens per call, compressible to 150, wastes 650 tokens per call — 3.25 million tokens a day. At Sonnet 5.5 output rates ($10/MTok), that is $32.50 a day, roughly $975 a month of verbosity. On Opus 5.5 ($20/MTok output), it doubles to about $1,950 a month. Same answers, same models — the only difference is output discipline.

    The Output Compression Toolkit

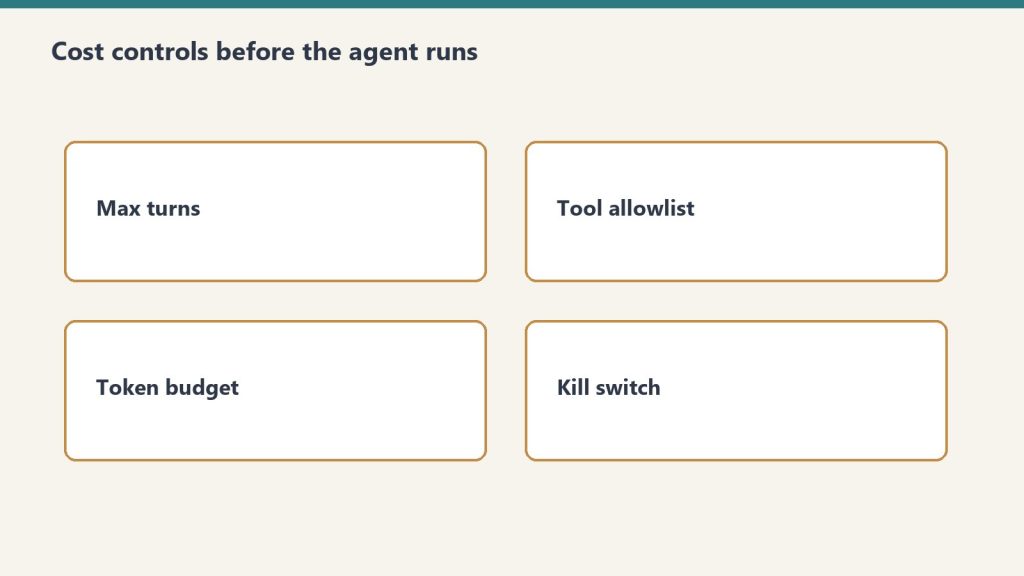
    Cost control gates for production routing
    The output compression toolkit.

    1. Explicit word and token caps in the prompt. “Respond in 150 words or fewer” is the single most effective instruction for reducing output tokens. Claude respects tight limits. “Be concise” does not work reliably. “150 words maximum” does. For JSON outputs: “Respond with only valid JSON, no markdown fences, no explanation.” Every word of instruction about format is recovered 10x in output reduction across repeated calls.

    2. Structured output schemas. When you need structured data, define the exact JSON schema. Claude stops generating prose and fills fields. You get exactly what you specified and nothing more. The token reduction versus free-form responses is typically 40-70% for equivalent information content.

    # Free-form -- verbose, unpredictable length
    prompt_verbose = "Summarize the key points of this article and their implications."
    
    # Structured -- tight, predictable, cheaper
    prompt_structured = """Extract from this article:
    {"headline": "string", "key_points": ["string", "string", "string"], "sentiment": "positive|neutral|negative"}
    Respond with valid JSON only. No explanation."""

    3. Role-based compression priming. System prompt framing shapes output length. “You are a precise technical writer who values brevity. Never restate the task. Deliver the answer directly.” produces consistently shorter outputs than a neutral system prompt. This is prompt engineering for token economics, not just quality.

    4. Chained micro-tasks over monolithic requests. Instead of asking Claude to research, analyze, synthesize, and format in one prompt, chain smaller requests. Each call is scoped to one task with tight output constraints. Total tokens across the chain are often lower than a single unconstrained request, and intermediate outputs are cacheable — pairing naturally with the prompt caching strategy.

    The Notion Second Brain Application

    The operational implementation at Tygart Media runs this pattern at pipeline level. The Notion second brain eliminates the need for Claude to generate background context — it already exists in structured form. Extractions from Notion arrive as pre-formatted knowledge blocks. Claude’s task is synthesis over existing structured data, not open-ended research and explanation. Output prompts are scoped: “Given this structured data, write a 400-word section for [topic]. No preamble, no conclusion, begin directly with the first point.” The output is a concentrated slice — dense, usable, billable at a fraction of what free-form generation costs for equivalent value.

    Measuring Compression Effectiveness

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Measuring compression effectiveness.

    Track output_tokens in your API responses. Log them per prompt template. Identify your highest-output templates and run compression interventions — tighter word caps, structured formats, role priming. The target is information density: insight delivered per output token, not raw token count. A 500-token output with 3 actionable insights beats a 200-token output with 1. Compression discipline is about removing the scaffolding (preambles, hedges, recaps) while preserving the load-bearing structure (insight, data, instruction).

    max_tokens as a Hard Ceiling

    Set max_tokens conservatively in your API calls. This is your financial guardrail, not just a model parameter. For classification tasks: 50 tokens. For short summaries: 200 tokens. For structured JSON extraction: 500 tokens. For article drafts: 1,500-2,000 tokens. Leaving max_tokens at a high default on every call is leaving a cost ceiling unjustifiably high — current Claude models support up to 128,000 output tokens, so the ceiling you are not setting is enormous. Claude will rarely hit the ceiling on constrained tasks, but it prevents runaway generation on edge-case inputs that can quietly inflate your bill.

    Output compression FAQ

    Does output compression hurt answer quality? Not when done right — compression removes scaffolding (preambles, hedges, recaps), not substance. The techniques above constrain format and length, never information content. If an answer needs depth, scope the depth explicitly (“give three reasons, one sentence each”) rather than leaving length open.

    How does output compression interact with prompt caching? They stack on opposite sides of the bill: caching discounts repeated input, compression shrinks output. Chained micro-tasks (technique 4 above) do both — intermediate outputs become cacheable inputs for the next call.

    Does the Batch API change the compression math? The Message Batches API takes 50% off output tokens too, so the dollar savings per token are halved — but the percentage savings are identical, and shorter outputs still mean faster batch turnaround.

    What is the single highest-leverage change? Explicit word caps in the prompt (“150 words maximum”). One sentence, no tooling, and Claude respects it.

    Price your own pipeline from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator for your actual usage.

    Related cost levers: prompt caching (input-side) · Message Batches API (50% off async) · Claude on a Budget (the full series).

    Next: Per-Model Content Shaping: Write Less, Get Cited More →

  • Anthropic Batch API: Save 50% on Async Claude Workloads

    Anthropic Batch API: Save 50% on Async Claude Workloads

    Last refreshed: October 20, 2026

    Every dollar you spend on Claude at full synchronous price is a dollar you’re overpaying for non-urgent work. Anthropic’s Message Batches API delivers a flat 50% discount on both input and output tokens — the same models, the same quality, half the price — with one constraint: results arrive asynchronously, typically within 24 hours.

    This is part of the Claude on a Budget series. If you’re routing models for real-time work, see Model Routing: Haiku vs Sonnet vs Opus. For cutting repeated context costs, see Prompt Caching.

    The Math First

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    The math first — why batch pricing exists.

    Standard Sonnet 4.6 pricing: $3.00 input / $15.00 output per million tokens. Batch Sonnet 4.6: $1.50 input / $7.50 output. Run 1,000 article drafts synchronously and you’re spending full rate on every one. Run the same batch overnight and you cut the bill in half — no model quality change, no output degradation, just a different delivery mechanism.

    ModelSync InputSync OutputBatch InputBatch Output
    Haiku 4.5$1.00/M$5.00/M$0.50/M$2.50/M
    Sonnet 4.6$3.00/M$15.00/M$1.50/M$7.50/M
    Opus 4.7$5.00/M$25.00/M$2.50/M$12.50/M

    What Qualifies as Non-Urgent Work

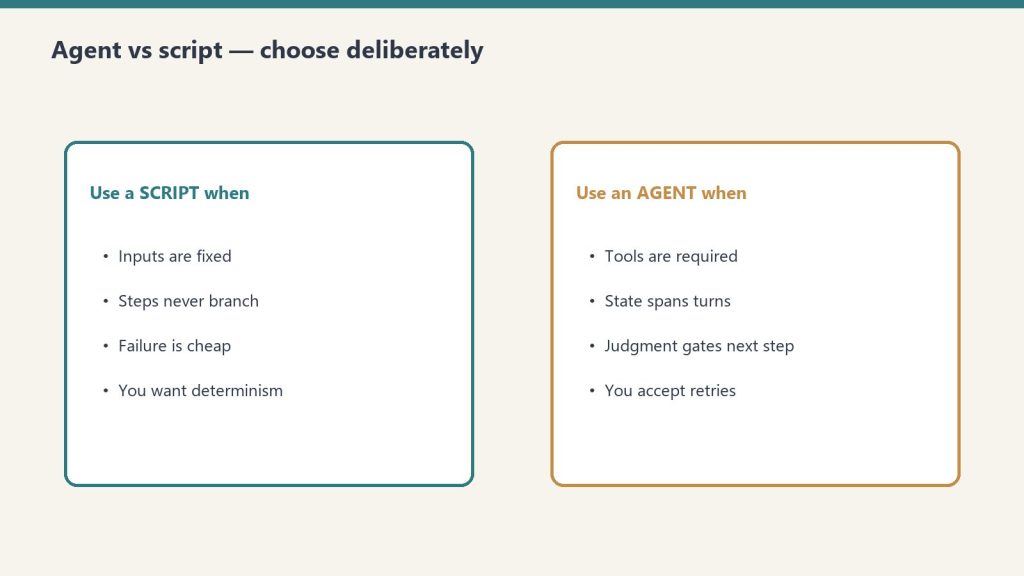
    Side-by-side when to use a script versus an agent
    What qualifies as non-urgent work.

    The honest question is not “does this need to be fast?” — it’s “does this need to be synchronous?” Most content pipelines, data enrichment tasks, classification jobs, and bulk translation runs have no real-time dependency. The user is not waiting at a keyboard. The output feeds a queue. The 24-hour window is irrelevant. Candidates include: nightly article drafts, SEO metadata generation for large post archives, batch product description rewrites, email personalization at scale, sentiment tagging across historical data, bulk summarization of documents or transcripts.

    What does not qualify: customer-facing chat, real-time code completion, any workflow where a human is actively waiting for a response.

    The API Pattern

    import anthropic
    
    client = anthropic.Anthropic()
    
    # Build your batch — each request is a full message payload
    requests_list = [
        {
            "custom_id": f"article-{i}",
            "params": {
                "model": "claude-sonnet-4-6",
                "max_tokens": 2000,
                "messages": [
                    {"role": "user", "content": f"Write a 500-word expert summary of: {topic}"}
                ]
            }
        }
        for i, topic in enumerate(topics)
    ]
    
    # Submit the batch
    batch = client.messages.batches.create(requests=requests_list)
    print(f"Batch ID: {batch.id} | Status: {batch.processing_status}")
    
    # Poll until complete
    import time
    while True:
        status = client.messages.batches.retrieve(batch.id)
        if status.processing_status == "ended":
            break
        time.sleep(60)
    
    # Retrieve results
    for result in client.messages.batches.results(batch.id):
        custom_id = result.custom_id
        if result.result.type == "succeeded":
            text = result.result.message.content[0].text
            print(f"{custom_id}: {text[:100]}...")

    Combining Batch API With Prompt Caching

    Cost control gates for production routing
    Combining Batch API with prompt caching.

    These two discounts stack. If your batch requests share a large system prompt — a style guide, a knowledge base, a persona definition — mark that block with cache_control: {"type": "ephemeral"}. Anthropic caches it across all requests in the batch that hit the same prompt prefix. You pay input rate on the first hit and cache read rate (roughly 10% of input rate) on every subsequent hit. A 10,000-token system prompt shared across 500 batch requests: you pay full rate once, cache rate 499 times, and you are already on batch pricing for all output tokens. The compounding effect is significant.

    Structuring Your Pipeline Around Batch Windows

    The practical architecture: identify every Claude call in your current workflow that has no real-time dependency. Move those calls behind a queue. Set a nightly cron that drains the queue into a batch submission at 11 PM. Results are ready by morning. Your synchronous Claude budget drops to customer-facing interactions only — often 20-30% of total volume for content and data operations teams.

    Rate limits are separate for batch vs. synchronous traffic, so batch jobs do not compete with your real-time usage. That is a free operational benefit on top of the price cut.

    Error Handling at Scale

    Batch results include a result.type field: succeeded, errored, or canceled. Always iterate the full result set and collect errored custom_ids for resubmission. At scale — thousands of requests — you will see occasional errors. Build the retry loop into your pipeline from day one rather than discovering it when 3% of a 10,000-request batch silently fails.

    The Honest Tradeoff

    Batch API is a discipline, not a feature. It requires you to think about your Claude usage in terms of urgency tiers, not just prompt quality. Teams that adopt it consistently cut their Claude bills by 30-50% on total spend — not because every call moves to batch, but because the non-urgent majority does. Combined with model routing (Haiku for triage, Sonnet for batch drafts, Opus only for synchronous high-stakes reasoning), it is the highest-leverage cost lever available in the Anthropic stack today.

    Next: Prompt Caching: How to Cut Repeated Context Costs by Up to 90% →

  • OpenRouter Model Routing: Lower Your Claude API Costs

    OpenRouter Model Routing: Lower Your Claude API Costs

    Last refreshed: October 20, 2026 (Pacific)

    OpenRouter is a single API endpoint that gives you access to Claude, GPT-6 Astra, Gemini, Llama, Qwen, Mistral, and dozens of other models — including nearly twenty free ones — through one standardized interface. For anyone building Claude workflows on a budget, OpenRouter is not optional infrastructure. It is the orchestration layer that makes intelligent model routing practical without building your own multi-provider integration.

    The core strategy: use free or cheap models for the work that doesn’t need Claude, and route only the remainder to Claude. In a well-designed pipeline, you pay Opus prices for 20% of the work and get Opus-quality output on the parts that genuinely require it. → Claude on a Budget pillar

    The OpenRouter API in 30 Seconds

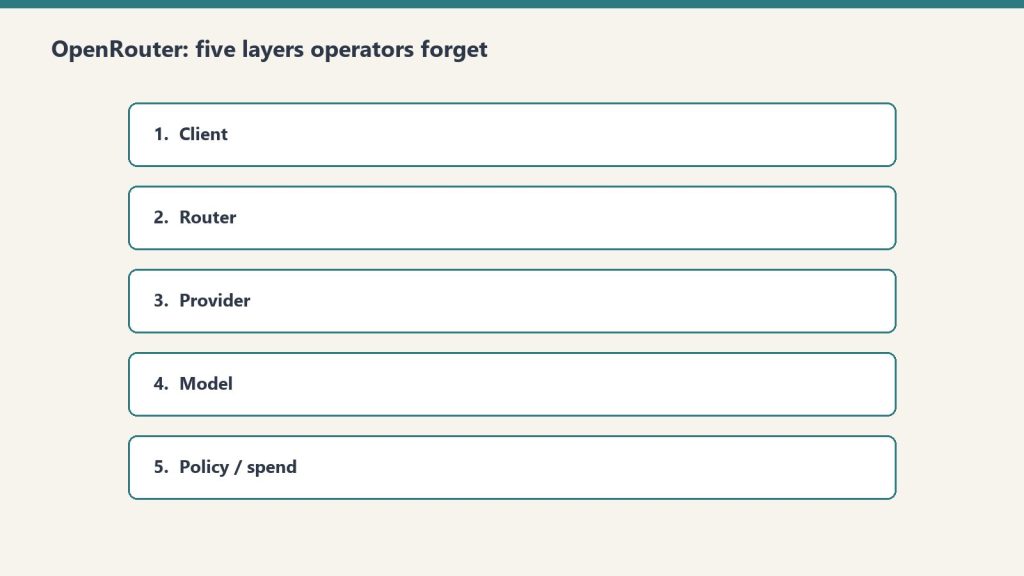
    Five operator layers: client, router, provider, model, policy/spend
    OpenRouter API in 30 seconds.
    const response = await fetch("https://openrouter.ai/api/v1/chat/completions", {
      method: "POST",
      headers: {
        "Authorization": `Bearer ${OPENROUTER_API_KEY}`,
        "Content-Type": "application/json"
      },
      body: JSON.stringify({
        model: "anthropic/claude-sonnet-5-5",  // or "nvidia/nemotron-3-super:free", "openrouter/auto"
        messages: [{ role: "user", content: prompt }]
      })
    });

    Switch the model string to change providers. No new SDKs, no new authentication flows, no restructuring your application. The same call routes to Claude, Gemini, or a free Llama instance.

    The Multi-Model Pipeline Pattern

    Three cards for solo takes, cross-pollination, and synthesis
    Multi-model pipeline pattern.

    The Tygart Media multi-model roundtable methodology — documented in the Knowledge Lab — uses this architecture:

    1. First pass (free or cheap model): Send the full input set to a current free-tier model (Nemotron 3 Super, Gemma 4 31B, or similar) via openrouter/free. Task: filter, classify, score, or sort. Return only the items that meet the threshold — the top 20%, the flagged items, the ones that need deeper processing.
    2. Second pass (Claude Sonnet 5.5 or Opus 5.5): Send only the filtered output to Claude. Task: reason, synthesize, write, decide. Claude sees pre-filtered, pre-organized input — no token waste on low-value items.
    3. Synthesis (Claude): Claude consolidates findings from both passes into a final output. It operates on structured inputs, not raw noise.

    In practice: if you’re processing 100 pieces of content to find the 20 worth writing about, the free model reads all 100 and returns 20. Claude reads 20 and writes 5. You paid free-tier prices for the reading work and Claude prices only for the synthesis work that Claude is actually better at.

    Free and Near-Free Models Worth Knowing

    ModelCostBest for
    nvidia/nemotron-3-super:freeFreeAgentic workflows, multi-modal triage
    google/gemma-4-31b-it:freeFreeStrong open-weight reasoning at zero cost
    qwen/qwen3.8-27b:freeFreeCoding with image and video input, 262K context
    cohere/north-mini-code:freeFreeTerminal and agent-harness coding tasks
    anthropic/claude-haiku-4-5$1.00/$5.00 per 1MHigh-quality triage requiring Claude behavior

    When to Still Use Claude Directly

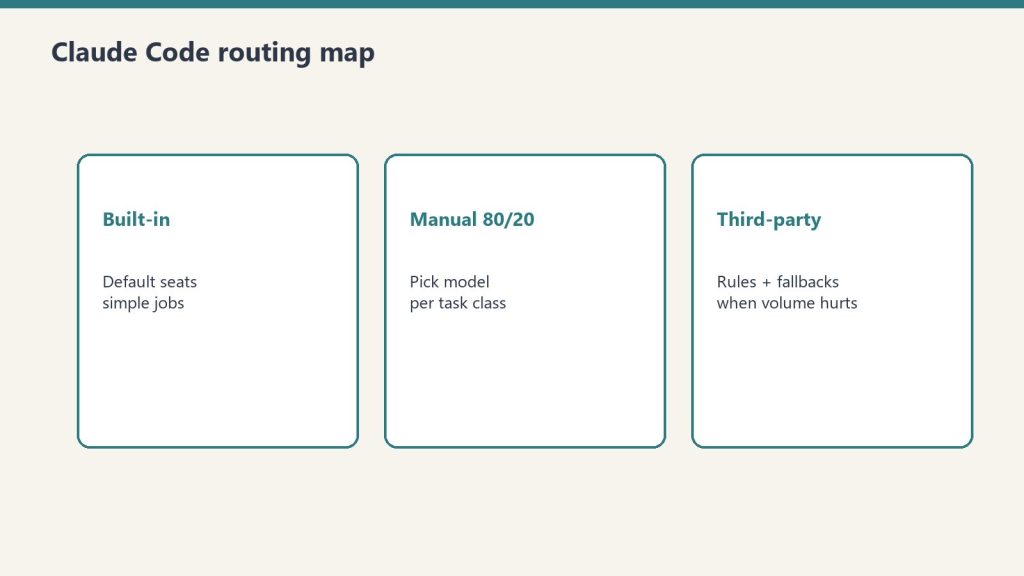
    Three routing approaches: built-in, manual 80/20, third-party
    When to still use Claude directly.

    OpenRouter’s free models are not Claude. They have different safety behaviors, different instruction-following reliability, and different output quality on nuanced tasks. Use free models for tasks where the output is a structured signal (score, category, yes/no, ranked list) that Claude will then act on — not for tasks where the free model’s output goes directly to a human or into production.

    The routing rule: if the output of the cheap/free model is an input to Claude, it can be imperfect — Claude will catch errors in its synthesis pass. If the output goes directly to a user or a system, it needs Claude-quality reliability. Do not route customer-facing outputs through free models.

    OpenRouter for the Multi-Model Roundtable

    Beyond pipeline routing, OpenRouter enables the multi-model roundtable methodology: send the same complex question to Claude, GPT-6 Astra, and Gemini simultaneously. Each model responds independently. Claude synthesizes the responses into a final recommendation with consensus points and disagreement flags. You get multi-model confidence for 3× the cost of a single Claude call — but often 10× the confidence in the output, particularly for strategic decisions where single-model bias is a real risk.

    The roundtable approach is documented in the Tygart Media Knowledge Lab and has been used for technology stack decisions, content strategy, and architecture choices where getting it wrong is expensive. The pattern: a current free-tier model for broad initial perspectives (free), Claude for synthesis (most reliable reasoning), GPT-6 Astra for the contrarian check.

    Sign up for OpenRouter at openrouter.ai. API key creation is instant; credits load immediately. The free models require no payment method on file.

    Part of the Claude on a Budget series. Next: The Batch API →

    Compare routed vs direct costs from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator.

    Related on Tygart Media: Haiku/Sonnet/Opus routing · Claude on a budget · Message Batches API.

  • Claude Model Routing 101: The Decision Tree for Haiku, Sonnet, and Opus

    Claude Model Routing 101: The Decision Tree for Haiku, Sonnet, and Opus

    Last refreshed: October 20, 2026 (Pacific)

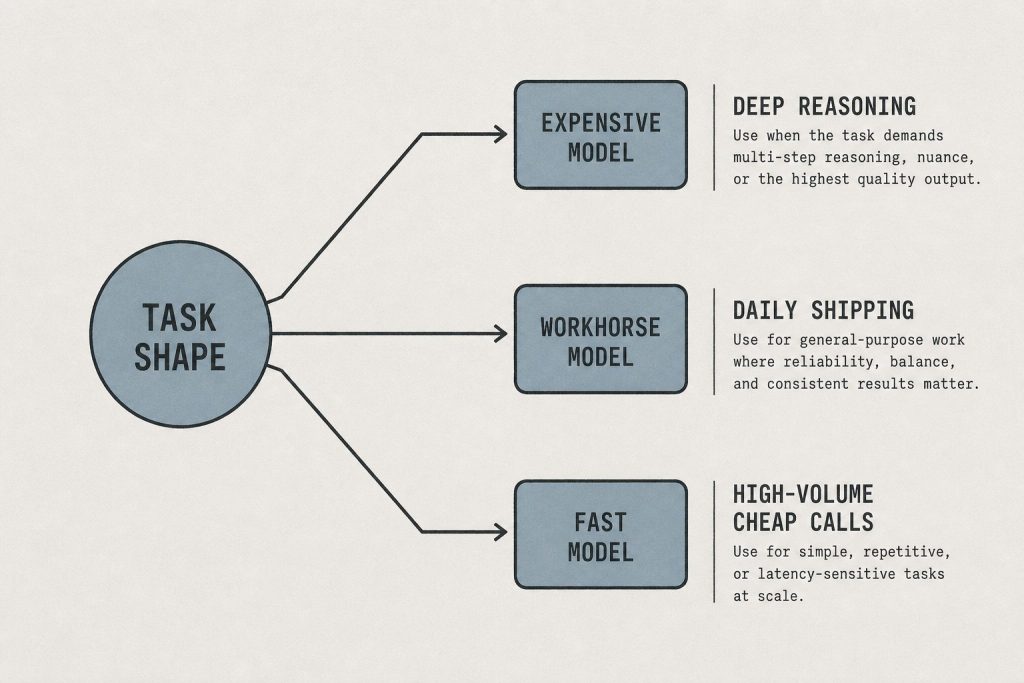
    Claude Opus 5.5 costs $20 per million output tokens. Claude Haiku 4.5 costs $5 per million output tokens. That is a 4× difference in list price — and the gap widens in practice, because larger models generate more tokens per task than Haiku for the same prompt (a token-inflation effect observed as large as roughly 40% on Opus 4.7).

    For the majority of tasks in a typical Claude workflow, that cost difference buys you nothing. Haiku and Opus produce indistinguishable output on sorting, classification, summarization, simple Q&A, format conversion, and first-pass drafting. The performance gap is real — but it only appears on tasks that genuinely require extended reasoning, complex code generation, nuanced judgment, or maximum creative quality. Most tasks don’t. → Claude on a Budget pillar

    The Decision Tree

    Decision diagram from task shape to deep reasoning, daily shipping, or high-volume cheap calls
    Haiku / Sonnet / Opus decision tree.

    Use Haiku 4.5 when:

    • Classifying or tagging items (sentiment, category, priority, topic)
    • Summarizing documents where the summary template is well-defined
    • First-pass triage — deciding which items need deeper processing
    • Format conversion — JSON to markdown, CSV to structured output, etc.
    • Simple Q&A with factual answers from provided context
    • Extracting structured data from unstructured text
    • Generating short, templated outputs (subject lines, meta descriptions, titles)
    • Any high-volume, time-insensitive batch job

    Use Sonnet 5.5 when:

    • Writing full articles, reports, or long-form content
    • Mid-complexity code generation and debugging
    • Research synthesis across multiple sources
    • Drafting emails, proposals, or documents requiring judgment
    • Multi-step reasoning where Haiku loses the thread
    • Any task where you’ve tested Haiku and found the output quality insufficient

    Use Opus 5.5 when:

    • Architecture decisions with significant downstream consequences
    • Security-sensitive code review or vulnerability analysis
    • Complex multi-file refactoring with interdependencies
    • Tasks requiring the xhigh effort level (extended chain-of-thought)
    • Creative work where you need maximum quality judgment
    • Any task where Sonnet has failed and you need the ceiling

    The Cost Math at Scale

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Cost math at scale — without sticky dollar stickers.

    Assume a content operation running 500 Claude tasks per month. Default behavior (everything on Opus): ~500,000 output tokens × $20/M = $10.00/month at minimum. Routed behavior (300 Haiku, 150 Sonnet, 50 Opus): (300K × $5) + (150K × $10) + (50K × $20) = $1.50 + $1.50 + $1.00 = $4.00/month. That is a 60% cost reduction with identical output quality on the Haiku and Sonnet tasks.

    At enterprise scale — thousands of tasks per day — the routing decision is worth six figures annually. At individual scale, it is the difference between a Claude workflow that is financially sustainable and one that quietly drains budget.

    How to Implement Routing

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to implement routing.

    In Claude Code: the gateway model picker

    Claude Code ships model routing as first-class surface: the /model picker (or --model at startup) sets the session model, subagent frontmatter accepts a per-agent model: override, and CLAUDE_CODE_SUBAGENT_MODEL overrides the model for all subagents. Set Haiku as the default for file reading, search, and summarization; route complex reasoning to Sonnet or Opus explicitly.

    In the API: explicit model parameter

    Every Anthropic API call takes a model parameter. Build a routing function in your application layer that maps task types to model strings. The routing logic can be as simple as a conditional or as sophisticated as a classifier (ironically, run on Haiku) that reads the task description and returns the appropriate model string.

    In Cowork and manual workflows: develop the habit

    For non-programmatic use, routing is a habit built through one question before every Claude task: does this task actually need Opus? Run a two-week audit. For every task you run on Opus, note whether Haiku would have produced the same output. Most people discover that 60–70% of their Opus usage could move to Haiku or Sonnet with no quality loss.

    Part of the Claude on a Budget series. Next: OpenRouter as the Budget Layer →

    Price your routing decisions from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator for your actual workload mix.

    Related on Tygart Media: OpenRouter model routing · Claude on a budget · how to use Claude.

  • Claude Cold Start Problem: Save Tokens With a Second Brain

    Claude Cold Start Problem: Save Tokens With a Second Brain

    Last refreshed: October 20, 2026

    Every Claude session has a cold start cost. Before Claude can do useful work, it needs to know who you are, what you’re building, what decisions you’ve already made, what your brand voice sounds like, and what context is relevant to the task at hand. If that context doesn’t exist in the session, you spend tokens building it — through back-and-forth clarification, through pasting in background, through re-explaining things Claude knew perfectly well last Tuesday.

    For a power user running multiple Claude sessions daily, cold start costs are not trivial. A 2,000-token orientation exchange at the start of each session, five sessions a day, 20 working days a month = 200,000 tokens of pure overhead. At Opus prices, that’s $5/month in tokens that produced zero output. At scale, with teams, it compounds fast.

    The solution is a persistent knowledge architecture that eliminates cold starts entirely. → Back to the Claude on a Budget pillar

    The Three Layers of Cold Start Elimination

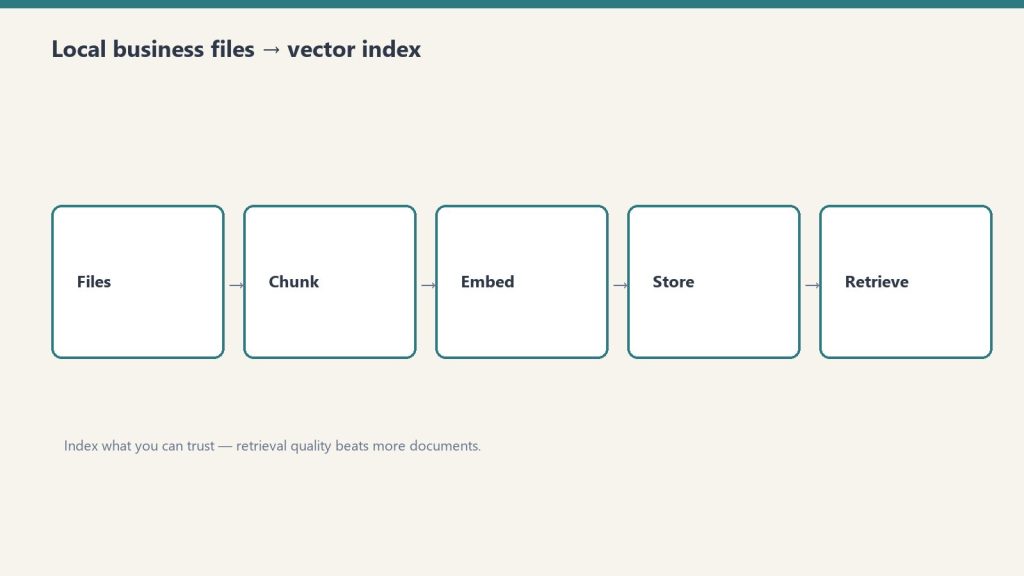
    Five-step flow from files to chunk, embed, store, retrieve
    The three layers of cold start elimination.

    Layer 1: CLAUDE.md — The Global Instruction File

    Claude Code and Claude’s desktop tools support a CLAUDE.md file in your working directory. This file loads automatically at the start of every session — no input required, no tokens spent on orientation. It is your persistent instruction set: who you are, how you work, what conventions to follow, what tools are available, what Notion databases contain what, how to route decisions.

    A well-built CLAUDE.md replaces 500–2,000 tokens of orientation with zero tokens — the file is read, not typed. The cost of writing it once is recovered in the first week of use. Every instruction you find yourself repeating across sessions belongs in CLAUDE.md.

    What to put in CLAUDE.md: your name and operating context; your active projects and their current status; your tool stack (which MCP servers are running, which Notion databases hold what); your output preferences (format, length, tone); your recurring workflows and the skills or commands that drive them; any decisions already made that Claude should not re-litigate.

    Layer 2: Notion as Second Brain — The Knowledge That Doesn’t Repeat

    A Notion second brain functions as Claude’s long-term memory between sessions. When Claude finishes a task, it logs the outcome, the decisions made, and the context that future sessions will need. When Claude starts a new session, it fetches that context rather than reconstructing it from scratch.

    The Tygart Media implementation uses a Second Brain database in Notion with structured entries per project, per client, and per system. The notion-deep-extractor skill runs every 8 hours, crawling recently edited Notion pages and injecting new knowledge into the Second Brain database automatically. Claude never starts a session unaware of what happened in the last session — that context is fetched on demand through the Notion MCP.

    The token math: fetching a 500-token Notion page costs 500 input tokens. Re-explaining the same context through conversation costs 500+ tokens of input plus 200+ tokens of Claude’s clarifying questions plus your typing time. The fetch is always cheaper, and it is more accurate — your Notion page says exactly what you intended, not a conversational approximation of it.

    Layer 3: Project Knowledge Files — Session-Specific Pre-Loading

    For recurring project work, a project knowledge file is a curated document that contains everything Claude needs to be immediately productive on that project: the brief, the audience, the tone guidelines, the existing content structure, the decisions already made, the open questions. Loaded at the start of a project session, it replaces 10–15 minutes of orientation with 30 seconds of file loading.

    The project-knowledge-builder skill generates these files automatically for WordPress sites — pulling existing posts, categories, brand voice, SEO context, and site history into a structured document. The same pattern applies to any recurring project: client accounts, content series, product builds, research projects.

    The Concentrated Output Connection

    Cost control gates for production routing
    The concentrated output connection.

    Cold start elimination and output compression work together. When Claude starts a session already knowing the context, it can skip the exploratory phase and go straight to the task. When you’ve defined in CLAUDE.md that you want structured outputs — briefings, scored lists, run logs — Claude produces them without the verbose preamble that precedes them in orientation-heavy sessions.

    The Tygart Media daily briefing is the clearest example: the desk spec in Notion defines the output format, the sources, the beat structure, and the run log format. Claude fetches the spec, executes, and produces a structured briefing page. No orientation. No format negotiation. No verbose preamble. Every token is productive output.

    Implementation Steps

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Implementation steps.
    1. Audit your last 10 Claude sessions. For each one, identify the first message where Claude produced genuinely useful output. Everything before that is cold start cost. Measure it.
    2. Write your CLAUDE.md. Start with the context you typed most often in those 10 sessions. One hour of writing recovers itself within days.
    3. Create one project knowledge file for your highest-frequency project. Use it for one week and compare session start times and output quality against the prior week.
    4. Set up Notion logging. At the end of each session, have Claude write a 3–5 sentence log entry: what was done, what decisions were made, what the next session needs to know. Store in a Notion database. Fetch at the start of the next session.

    The cold start problem is the most invisible Claude cost because it feels like normal conversation. Once you measure it, it becomes obvious. Once you eliminate it, you cannot go back.

    Part of the Claude on a Budget series.

    Related on Tygart Media: Claude on a budget · tokens to words · how to use Claude.