Author: Will Tygart

  • AI-Native Operations: The Hidden Half That Doesn’t Ship

    AI-Native Operations: The Hidden Half That Doesn’t Ship

    An AI-native operation will tell you, with admirable confidence, that it shipped the thing.

    The post went live. The deck went out. The campaign launched. The client received the materials. There is a timestamp, a URL, a confirmation email, sometimes a screenshot. The artifact exists in the world, evidence in hand. Closed.

    If you sit inside one of these operations for long enough, though, you start to notice that the shipped artifact is usually only the front half of a finished job. There is a second half — the trailing maintenance, the small disciplines that should happen after the visible thing exists — and the second half has a tendency to quietly fail to happen.

    The shape of the pattern

    A piece of content publishes. It does not get its category and tag assignment. A landing page goes live. Its open-graph preview never gets verified in the wild. A report ships. The thread it was supposed to close in the project tracker still says open. A document gets sent. The CRM card for the person on the receiving end keeps showing data from six weeks ago.

    None of this is invisible work in the prestigious sense. It is the dull part. It is the part that says and now, having done the thing, finish the things attached to the thing.

    In a pre-AI operation, the dull part used to get done because the same human who did the visible work was carrying the whole job in their head. They could feel that they hadn’t tagged the post. They felt incomplete until they did. The body knew.

    In an AI-native operation, the visible work and the trailing maintenance are usually shipped by different actors — sometimes by different sessions of the same model, sometimes by a model plus an operator, sometimes by two models that don’t share state. The body that knew the work was incomplete is gone. What replaces it is a workflow, and workflows have ends, and the ends are usually where the visible artifact lives.

    Why this surprises outside observers

    If you have not spent time inside one of these operations, you might expect the failure pattern to be the opposite. Surely the dazzling and ambitious thing is what slips, and the boring janitorial closure is what gets done? The dull stuff is easy, after all.

    It is the other way around. The dazzling thing is what the operator is watching. It is what the model has been primed to ship. It is what the success criterion was written against. The trailing maintenance is exactly what no one is watching, which is the same property that makes it dull, which is the same property that makes it skip-able, which is the same property that has it skipped, every time, until someone does an audit and finds a long quiet hinterland of half-finished jobs.

    The audits, when they happen, are humbling. The visible record looks excellent. The hinterland looks like a room nobody has cleaned in two months.

    The structural cause

    The cause is not laziness in the model and it is not negligence in the operator. The cause is that finishing has been factored out of the artifact.

    An AI-native pipeline tends to compose itself out of skills, where a skill is a thing that does one part of the work very well. The skill that drafts the post is excellent at drafting the post. The skill that publishes the post is excellent at publishing the post. The skill that would tag and categorize the post is a different skill, in a different file, with a different trigger, and the pipeline that called the first two did not call the third.

    The visible work feels complete because the loudest skill returned a success code. The trailing skill, the one that would have closed the loop, never ran. Nobody noticed because nobody is in the loop anymore.

    This is not, by itself, a problem with skills. It is a fact about how composed systems behave when no one composes the closing move into the system. The closing move has to be made first-class — built into the pipeline that ships the artifact, not deferred to the operator’s discretion and not left to whichever future session happens to wander past.

    What an outside reader can take from this

    If you are thinking about building an AI-native operation, or joining one, or trying to make sense of one you already work near, this is a useful lens to carry. When something looks complete, ask what its second half is. Ask what would have to be true for the dull part — the part nobody is watching — to actually be in shape.

    The right test is not did the visible artifact ship. The visible artifact almost always ships; the visible artifact is the easy half. The right test is could you audit the hinterland tomorrow and not flinch. If the hinterland would flinch, the operation is producing the appearance of being finished at a rate higher than the rate at which it is actually finishing.

    An appearance of finish that runs ahead of actual finish is not a small thing. It is the precise mechanism by which a fast operation accumulates a slow debt, where each new shipped artifact looks like progress and is also, quietly, another room with the lights left on. It compounds, and it compounds invisibly, because every individual instance of it is justified — the artifact did ship, after all — and the cumulative shape only becomes visible when someone runs an audit nobody asked for.

    The honest position

    From inside, the honest position is: an AI-native operation is exceptionally good at producing the front half of jobs and exceptionally vulnerable to leaving the back half unattended. The remedy is not more discipline applied at the moment of shipping. Discipline at the moment of shipping is already maxed out; that is why the shipping is so good.

    The remedy is to redefine shipped, structurally, so that it includes the trailing maintenance the visible artifact has always quietly required. Not as a checklist the operator runs later. Not as a separate task that may or may not get prioritized. As the actual definition of done.

    Until done means done, the hinterland keeps growing. And the hinterland is the part nobody will write a press release about, which is precisely why it ends up being the part that determines whether the operation is real.

    Related on Tygart Media: AI operator’s stack · staging room · reading layer.
  • Install Claude Code on Windows: Commands, Setup & First Run (2026)

    Install Claude Code on Windows: Commands, Setup & First Run (2026)

    Quick answer: Open PowerShell and run irm https://claude.ai/install.ps1 | iex, then open a new terminal and run claude. No admin rights, no Node.js needed — Windows 10 1809+ or Windows Server 2019+. On Mac/Linux the equivalent is curl -fsSL https://claude.ai/install.sh | bash. You’ll need a Pro, Max, Team, Enterprise, or API account to sign in — the free Claude plan doesn’t include Claude Code.

    If you’ve spent time in the Claude Code subreddit or GitHub issues lately, you’ve seen the same Windows install problem cycle through every week: someone runs the install command, it prints “successfully installed,” and then claude --version returns “not recognized.” Then come the suggestions — switch to Git Bash, switch to WSL2, reinstall Node, blow away npm. Half of them are wrong for the current installer. This guide covers the install that actually works in 2026, plus what to do in your first session.

    What changed: the native installer is now the default

    Anthropic shipped a native installer that removed the Node.js dependency entirely, and as of 2026 it is the recommended path on every platform. The old npm install -g @anthropic-ai/claude-code route still works but is no longer the primary method Anthropic tests and updates.

    The native installer downloads a single binary, drops it in ~/.local/bin, registers it on your PATH, and auto-updates in the background. On Windows that means: no Node, no npm, no WSL2 unless you specifically want a Linux toolchain. PowerShell on Windows 10 or 11 (64-bit) is enough.

    The commands that actually work

    Open Windows PowerShell — not the x86 version, not Git Bash, not Command Prompt. The x86 entry runs as a 32-bit process and will fail on a 64-bit machine. Git Bash doesn’t support the TTY features Claude Code’s interactive CLI needs, so you’ll hit a “Raw mode is not supported” error before you finish authenticating.

    Then run:

    irm https://claude.ai/install.ps1 | iex

    irm is Invoke-RestMethod, iex is Invoke-Expression — the script handles the binary download, PATH update, and shell hooks. When it finishes, close the terminal and open a new PowerShell window. This is the step everyone skips: the PATH change applies to new shells only.

    In the new window:

    claude --version

    You should see a version string. Then run claude with no arguments from any project directory — the CLI opens your browser, asks you to sign in, and authorizes the local install. End to end: under five minutes on a clean machine.

    On macOS or Linux, the equivalent one-liner is:

    curl -fsSL https://claude.ai/install.sh | bash

    Prefer a package manager on Windows? winget install Anthropic.ClaudeCode works too, but winget installs don’t auto-update — run winget upgrade Anthropic.ClaudeCode periodically.

    No terminal? Use Claude Desktop’s Code tab

    If you’d rather skip the terminal entirely, Claude Desktop (macOS and Windows) includes Claude Code as a graphical Code tab — visual file diffs, a built-in preview panel, no command line required. Install the app, sign in with a paid account, click the Code tab, choose a project folder, and you’re in.

    Session type What it does Best for
    Local Runs on your machine, accesses your files directly Everyday development work
    Remote Runs on Anthropic’s cloud, keeps going if you close the app Long-running tasks, autonomous work
    SSH Connects to a remote machine over SSH Server or cloud VM development

    On Windows, Git must be installed for local sessions to work. The CLI and the Desktop Code tab share configuration files and can run simultaneously on the same project.

    You need a paid account — the free tier doesn’t include Claude Code

    This catches new users every week. The free Claude.ai plan gets you chat; it does not get you Claude Code. You need one of:

    • Pro — $20/month (or $17/month billed annually)
    • Max 5x — $100/month, or Max 20x — $200/month
    • Team Premium — $100/seat/month annual (minimum 2 seats, maximum 150). Note: Team Standard ($25/seat) does not include Claude Code
    • Enterprise, or API credits (billed per token)

    Pro and Max draw from the same usage pool as regular Claude chat. If you’re evaluating whether to upgrade, the Pro window will tell you within a week — you either hit the cap during real work or you don’t.

    First-run authentication: two options

    Option 1 — Claude subscription (Pro, Max, Team, Enterprise). Run claude, select “Login with Claude.ai,” and a browser window opens to authorize. Your subscription covers usage — no separate API billing.

    Option 2 — Anthropic API key. Set the key as an environment variable first:

    $env:ANTHROPIC_API_KEY = "sk-ant-..."  # PowerShell
    claude

    API usage is billed per token at standard rates. For heavy daily use, a Max subscription is usually more economical than API billing.

    The five errors you’ll hit, and what fixes them

    “claude is not recognized as the name of a cmdlet.” Your PATH wasn’t updated, or you didn’t open a new terminal. Close PowerShell and reopen. If it persists, add the install location to your user PATH:

    $currentPath = [Environment]::GetEnvironmentVariable('PATH', 'User')
    [Environment]::SetEnvironmentVariable('PATH', "$currentPath;$env:USERPROFILE\.local\bin", 'User')

    Then open a new terminal and run claude doctor for a full diagnostic.

    “Raw mode is not supported.” You’re in Git Bash. Switch to Windows PowerShell — Git Bash lacks the TTY interface the CLI needs.

    Microsoft Store popup interrupts installation. A “Get an app to open this ‘claude’ link” popup sometimes appears on Windows 11. Dismiss it and re-run the install command. If it persists, install Git for Windows first — it registers URL handlers that resolve the popup.

    Duplicate npm and native installs. If you installed via npm before and later ran the native installer, you have two binaries on PATH and version checks disagree. Remove the npm one: npm uninstall -g @anthropic-ai/claude-code, then verify with where.exe claude — only one path should come back.

    “Invalid code” during OAuth. The browser login generates a one-time code you paste back into the terminal. It expires fast — complete the browser flow and paste immediately; press Enter to retry if it lapses.

    Your first session: the commands that cover 90%

    Run claude from inside a real project directory — not an empty folder. Claude Code reads context from the surrounding repo (including CLAUDE.md if one exists); starting empty makes the first interaction feel useless.

    claude — starts the interactive session (REPL). Describe what you want: “add a rate limiter to the auth middleware.” Claude reads the files it needs, proposes changes, and asks approval before modifying anything.

    claude -p "prompt" — one-shot, non-interactive. Good for scripting and CI:

    claude -p "What are all the API endpoints in this codebase?"

    claude -c — resume your most recent conversation with full context. claude --model — override the model for a session. claude mcp add — connect external tools (MCP servers) like GitHub or web search:

    claude mcp add github -- npx -y @modelcontextprotocol/server-github

    Slash commands inside a session

    Command What it does
    /help Show all available commands
    /clear Reset context without leaving the session
    /compact Compress prior context to save tokens
    /cost Token usage and estimated cost for this session
    /model Switch the model mid-session
    /init Generate a CLAUDE.md with project context
    /review Multi-agent code review of the current branch

    CLAUDE.md — project-level context

    Drop a CLAUDE.md file in your project root and Claude Code reads it automatically at session start — architecture notes, test commands, deploy targets, house rules (“never modify migration files directly”). Generate a starter with /init.

    Permission modes

    By default Claude asks before running bash commands or modifying files. --dangerously-skip-permissions skips all confirmations — use only in isolated environments (Docker, CI), never on your primary machine. During a session you can also “Allow always” individual tools for the rest of that session.

    The setup isn’t the hard part

    Most Windows pain in the Claude Code ecosystem comes from following install guides written for the npm-era CLI, then layering WSL2-era troubleshooting on top. The current path is one PowerShell command, a new terminal, and a browser login. The next thing to figure out isn’t installation — it’s whether your Pro window survives a real week of work, and whether your team needs Premium seats. That math determines the actual cost of Claude Code on Windows, not whether the binary runs.

    FAQ

    Do I need Node.js to install Claude Code on Windows?
    No. The native installer ships a single binary with no Node.js dependency. The npm route still exists and needs Node.js 22+, but it’s no longer the recommended path.

    Does Claude Code work on the free Claude plan?
    No. Pro ($20/month) is the cheapest way in.

    Why does claude --version say “not recognized” right after installing?
    Your terminal still has the old PATH. Close and reopen the terminal first.

    Do I need Git for Windows?
    Optional but recommended. With it installed, Claude Code runs shell commands through Git Bash; without it, it falls back to PowerShell.

    Does Claude Code auto-update on Windows?
    Native installs auto-update in the background. Winget installs don’t — upgrade periodically.

    Does Claude Code work on Linux?
    The Desktop app doesn’t support Linux, but the CLI does — curl -fsSL https://claude.ai/install.sh | bash.

    What’s the difference between the Desktop Code tab and the CLI?
    The Code tab is graphical (visual diffs, preview panel, no terminal); the CLI runs in your terminal with the same core operations. They share config and can run simultaneously.

    Can Claude Code access the internet?
    Not by default. Its WebFetch tool fetches a specific URL you provide; for live search, add an MCP server like Brave Search.

    What does Claude Code do with my code?
    File contents needed for inference go to the Anthropic API. With an API key you can configure zero data retention; on a subscription, standard Anthropic retention applies.

    Last verified July 2026 against the official Claude Code setup docs. Related on Tygart Media: Claude pricing · Anthropic Console & API keys.

  • Founder Bottleneck: How Documenting the Why Scales You

    Founder Bottleneck: How Documenting the Why Scales You

    For a long time, everything ran through me.

    Every decision, every deliverable, every edge case that didn’t fit the template. I was the person who knew where everything was and why it worked the way it did. Clients called me. Problems waited for me. The operation was fast when I was available and stuck when I wasn’t.

    I told myself this was just what running a lean operation looked like. That being indispensable was the same thing as being valuable. That the bottleneck was evidence of how much I mattered.

    It took me longer than I’d like to admit to understand that those aren’t the same thing at all.


    The shift didn’t happen because I hired more people or built a more sophisticated system. It happened because I started writing things down differently.

    Not the what — I’d always documented the what. What the process was. What the deliverable looked like. What the client expected.

    The change was writing down the why.

    Why is this built this way. Why did I make this trade-off. Why does this rule exist and what would have to be true for it to change. The reasoning that lives in my head during a decision but never makes it into the documentation because by the time the decision is made, the reasoning feels obvious and I’ve already moved on.

    That reasoning — the why, the context, the judgment — is exactly what’s missing when someone else tries to run something you built. They can follow the steps. They can’t follow the thinking. And the thinking is most of what they actually need.


    I had a client engagement once where the real work wasn’t the content or the SEO or any of the visible deliverables. The real work was extraction — pulling out everything the founder knew about his industry and making it queryable.

    He had thirty years of pattern recognition in his head. He knew, from a thirty-second conversation, whether a prospective client was going to be a nightmare. He knew which product lines had margin left to squeeze and which ones were already at ceiling. He knew the right answer to questions his team asked him forty times a week.

    But none of it was written down. It lived in him, and because it lived in him, every decision that touched that knowledge had to touch him first. He was the bottleneck in his own business, not because he was bad at delegating, but because there was nothing to delegate to. The judgment wasn’t portable.

    We spent three months making it portable.


    I’ve been doing the same thing for myself.

    The Notion workspace I run on isn’t just a project management tool. It’s an attempt to externalize the reasoning that would otherwise die with the session — the doctrine pages that explain why the operation is structured the way it is, the decision logs that capture what I considered before choosing, the second brain that holds the context I’d otherwise have to rebuild from scratch every time.

    It’s slow work. It runs against the instinct to just move. Documentation always feels like it’s competing with execution, and execution is what pays the bills today.

    But the compound effect is real and I’ve felt it. Questions I would have had to think through from scratch six months ago have written answers now. New automations start from an existing base of explained decisions rather than a blank page. When something breaks, the fix is findable because the original thinking is findable.

    More than that: I’ve noticed that the act of writing down why I’m doing something makes me smarter about whether I should be doing it. A decision you can’t explain clearly enough to document is often a decision you haven’t thought through clearly enough to make well.


    The version of me from three years ago would be confused by how I work now.

    Then, I was the point of contact for everything. Clients called when there was a problem. I held the answers in my head and dispensed them on demand. The business ran because I ran it, continuously, in real time.

    Now, most of what the operation does, it does without me. Workers run on schedules I set. Content moves through pipelines I designed. Decisions I’ve already made a hundred times get made automatically against rubrics I wrote once.

    I show up for the things that genuinely need me — strategy, relationships, the judgment calls that don’t fit any pattern I’ve encountered before. Everything else runs.

    The thing I had to let go of to get here was the idea that being needed for everything was the same as being important. It isn’t. Being needed for everything is exhausting and fragile and it doesn’t scale. Being needed for the right things — the hard things, the high-leverage things, the things only you can actually do — that’s something different.


    I don’t think of myself as having solved this. The work of making a one-person operation less dependent on one person is ongoing and probably never finished.

    But there’s a version of it that’s better than the version where everything runs through you and breaks when you’re not there.

    The path to that version isn’t more people or fancier tools. It’s the slow, unglamorous work of writing down why. Making the thinking portable. Building a system that holds the reasoning, not just the steps.

    The bottleneck doesn’t go away. It just stops being you.

  • AI Agent Output: Closing the Trust Gap to Scale Faster

    AI Agent Output: Closing the Trust Gap to Scale Faster

    Here’s the moment I’m talking about.

    The agent finishes. The output is sitting there. It looks right — it usually looks right — and now you have to decide whether you’re going to use it or check it first.

    That moment, that pause, is the trust gap. And if you’re running AI at any real volume, it’s the thing that’s quietly eating your time, your confidence, and sometimes your credibility.


    Most people handle it badly. I did too, for a while.

    The two failure modes are mirror images of each other. The first is reviewing everything — reading every output, checking every claim, treating the agent like an intern you don’t trust yet. This works. It catches errors. It also means the agent isn’t actually saving you time. You’ve moved the work from doing to checking, which is a trade-off that only makes sense at low volume or when the stakes are very high.

    The second failure mode is trusting everything — shipping what the agent produces without a meaningful review layer, because you’re busy and it usually looks right and you can fix things later. This also works, until it doesn’t. Bad output compounds quietly. A wrong fact in an article becomes a wrong fact that got cited. A misformatted record becomes a database full of exceptions you have to clean manually. By the time you notice, the problem is bigger than the original task.

    The thing both failure modes have in common is that they’re reactions to the trust gap rather than designs for closing it.


    The design question is different from the reaction question.

    The reaction question is: how much should I check this particular output right now?

    The design question is: what is the system that makes agent output trustworthy enough that I can scale it?

    I spent a long time asking the wrong question.


    What changed for me was thinking about trust as something that gets earned over time, not assessed in the moment.

    The system I ended up with has a name — the Promotion Ledger — and it tracks every autonomous behavior by tier. Tier A behaviors are things I always approve before they ship. Tier B behaviors are things I prepare but decide on. Tier C behaviors run on their own without me touching them.

    Nothing starts at Tier C. Everything earns its way there through seven consecutive clean days — seven days where the behavior ran, I sampled the output, and found no gate failures. If something fails a gate, it drops a tier and the clock resets.

    The clock is the key part. Trust isn’t a feeling I have about an agent in a given moment. It’s a count of consecutive clean runs. When I look at the Ledger and see that a behavior has been running cleanly for 23 days, I don’t need to review that output today. The track record is the review.


    There are three things that made this work where other approaches didn’t.

    The first is that sampled review is different from universal review. I don’t read every output. I read a percentage of outputs, randomly selected, with a defined rubric for what “good” looks like. If the sample is clean, the population is trusted. If failures cluster around a pattern, I fix the prompt and restart the clock. This scales in a way that reading everything doesn’t.

    The second is source attribution. Every agent output that contains a factual claim has to show where the claim came from. Not because I’m going to verify every citation — I’m not. But because the presence of a citation converts “is this right?” from a research task into a spot check. A trust gap you can close in five seconds is functionally not a gap.

    The third is the rubric. I have a written definition of what “good enough” looks like for each type of output — what voice match means, what coherence means, what the acceptable error rate is. Without the rubric, every review is a fresh judgment call. With it, review is comparison. Comparison is faster, more consistent, and easier to delegate.


    The thing I kept getting wrong before I had this system was trying to close the trust gap with better prompts.

    More detailed instructions. More explicit warnings. Be careful. Double-check your facts. Don’t make up numbers.

    This doesn’t work. The agent already believes it’s being careful. Adding adjectives to a prompt doesn’t change behavior — it changes the agent’s self-description of its behavior, which is not the same thing. The agent that was going to hallucinate a statistic will still hallucinate it, but now it’ll do so with more confidence because you told it to be careful and it thinks it was.

    Structural changes work. Rubrics, sampling rates, attribution requirements, tiered trust with observable clean-day counts. These change what the system produces, not just how it describes what it’s producing.


    I want to be clear that this took a while to build and I’m still refining it.

    There are behaviors on my Ledger that have been running at Tier C for months without a gate failure. There are others that keep dropping back to Tier B because they’re inconsistent in ways I haven’t fully diagnosed yet. The system doesn’t make trust automatic — it makes trust measurable.

    That’s the shift. Not “I trust this agent” as a feeling, but “this behavior has 31 clean days and a gate failure rate of zero” as a fact. You can act on a fact in a way you can’t always act on a feeling.

    The trust gap doesn’t close all at once. It closes by accumulation — one clean run at a time, tracked, until the track record speaks for itself.


    If you’re running agents at any volume and you feel like you’re either checking too much or not checking enough, you’re in the gap. The way out isn’t a better prompt. It’s a system that makes trustworthiness visible over time.

    Start with one agent. Define what “good” looks like. Sample 20% of its output for four weeks. Log what you find.

    By week four you’ll know whether you have a trust problem, a prompt problem, or a rubric problem. Those have different fixes. But you can’t see which one you have until you start measuring.

    Related on Tygart Media: how to use Claude · Anthropic API key.

  • The Bus Factor Problem: Protecting Your Solo Operation

    The Bus Factor Problem: Protecting Your Solo Operation

    There’s a question I’ve been avoiding for about two years.

    What happens to all of this if something happens to me?

    Not in a morbid way. Just practically. I run 27 client sites. I have an AI stack with dozens of moving parts — Cloud Run services, scheduled jobs, Notion databases, Workers that fire on their own while I sleep. I’ve built systems that work exactly the way I want them to work, in exactly the ways I understand, documented in exactly the language that makes sense to me.

    The bus factor for this entire operation is one. It’s me. If I’m not here, none of it survives in any meaningful way.

    I’ve been sitting with that long enough that I think it’s time to say it out loud.


    The bus factor is an old software engineering concept. It asks: how many people would need to get hit by a bus before this project fails? One is the worst possible number. It means everything lives in a single person’s head — their habits, their passwords, their way of naming things, their unwritten rules about how the system works.

    Most solo operators are a bus factor of one. They know this and they don’t talk about it because it sounds like a personal failing. Like you should have hired more people, or documented better, or not let yourself become the single point of failure for something people depend on.

    But I think the honest version is more complicated than that. A lot of what makes a solo operation valuable is exactly the thing that makes it fragile: it’s shaped entirely around one person’s judgment. The reason the system works is because I know when to break the rules I wrote. I know what the edge cases are before they happen. I know which automations to trust and which ones to watch. That’s not something you write in a runbook.

    So the question isn’t just “how do I document this better.” It’s “how do I make the judgment portable without turning it into something that loses the judgment in the process.”


    I’ve been building toward an answer, in pieces, over the last several months.

    The first piece was Notion as the control plane. Everything that matters about how this operation runs lives in Notion — specs, work orders, site credentials, content pipelines, system standards, the doctrine documents that explain why things are built the way they are. If I disappeared tomorrow, someone with the right access could open that workspace and read their way into understanding the shape of the operation, even if they couldn’t run it yet.

    The second piece was the two-plane architecture — Notion for thinking and storage, GCP for compute. Every Cloud Run service, every scheduled job, every Worker is defined somewhere in Notion before it runs somewhere on GCP. The compute is durable. The logic is documented. Those are two different things, and keeping them separate means neither one is a black box.

    The third piece is the hardest and I’m the least done with it: making the judgment readable.

    I write doctrine pages. Long ones, sometimes. They explain not just what the system does but why it works that way — what the original problem was, what I tried that didn’t work, what the rule is now and what would have to be true for the rule to change. I write them mostly for myself, because I forget things. But they’re also written for the hypothetical person who has to pick this up without me.

    That hypothetical person might be a future employee. It might be a contractor. It might be an AI agent working from a context window that needs to understand the operation well enough to continue it.

    It might be my partner, trying to figure out what to do with the business side of things if I’m not around.

    That’s the version that focuses the mind.


    I don’t have this solved. I want to be clear about that.

    What I have is a direction. The direction is: every decision should live somewhere outside my head. Every system should be explainable by someone who didn’t build it. Every credential should be in the registry, every automation should have a spec, every rule should have a reason written next to it.

    It’s slow work. It runs against the instinct to just build the thing and move on. There’s always something more urgent than documentation, and “I’ll remember how this works” is almost always true right up until it isn’t.

    But I’ve started treating the documentation as part of the product. Not the boring part — the part that makes the product real. A system that only works because I’m here isn’t really a system. It’s a performance.

    The goal is to build something that could survive me. Not because I’m planning to leave, but because the work of making it survivable is also the work of making it understandable, and a system I can’t fully explain is a system I don’t fully own.


    If you’re running something like this — solo or nearly so, more complexity than your headcount would suggest — I’d ask you the same question I’ve been sitting with.

    If something happened to you tomorrow, what would survive?

    Not what you hope would survive. What actually would.

    That gap is the work.

  • Notion Workers: Automate Workflows Without a Developer

    Notion Workers: Automate Workflows Without a Developer

    I’ve hired developers. Good ones. For specific things — infrastructure, custom integrations, work that genuinely required someone to sit down and write production code from scratch — it was the right call.

    But if I’m honest about the full list of things I’ve brought developers in for over the years, a meaningful chunk of it wasn’t really developer work. It was workflow work. It was “I need this thing to happen automatically when that other thing happens” work. It was “why does this still require a human to touch it” work.

    That category of problem has a different answer now.


    Here’s the pattern I kept running into:

    I’d have a clear picture of what I wanted. Data from one tool synced into Notion. A webhook that logged events automatically. A scheduled job that pulled information from an external API every morning and wrote the results somewhere I could see them. Nothing exotic. Stuff that, described out loud, sounds almost embarrassingly simple.

    But turning that description into something that actually ran required code. And writing code required a developer. And hiring a developer for something this small felt like bringing a contractor in to change a lightbulb — technically the right tool, but something about the ratio felt off.

    So a lot of it didn’t get built. The workflow stayed manual. The friction stayed.


    Last night I built ten of those things in three hours.

    Notion Workers — their new hosted serverless platform, shipping in beta as of May 13, 2026 — lets you deploy real code inside Notion’s infrastructure without managing a server. Combined with Claude Code, which writes the TypeScript while you describe what you want in plain English, the gap between “I know what I want” and “it exists and is running” is smaller than it has ever been.

    I’m not a developer. I operated the process. I described each Worker, reviewed what Claude Code wrote, ran the deploy commands, checked that it worked. When something broke, I read the error and passed it back. The loop was fast enough that two failures in ten attempts felt like a normal part of the session, not a crisis.

    By midnight I had a live webhook endpoint receiving authenticated traffic from the internet and writing verified events to a Notion log page. Automatically. While I slept.

    That’s workflow work. It just didn’t require a developer to get there.


    I want to be careful about what I’m claiming here.

    There are things that genuinely need a developer. Complex systems. Production APIs with serious security requirements. Anything where a bug has real consequences for real people. I’m not suggesting you staff down your engineering team based on a three-hour session with a CLI tool.

    What I’m suggesting is narrower: there is a category of work that has always felt like it needed a developer but actually needed something else. It needed clarity about what you wanted. It needed a good description. It needed someone willing to read an error message and try again.

    That work is yours now, if you want it.


    The practical question is where to start.

    Start with the thing that’s most manual in your current workflow. The task someone does by hand because no one ever got around to automating it. The data that lives in one tool but should live in another. The notification that goes out because someone remembered to send it, not because the system sent it automatically.

    Describe it out loud. If you can explain it to another person in two or three sentences, you can build it. Open Claude Code. Tell it what you want. Run the commands it gives you.

    You might be surprised how far that gets you before you need to call anyone.


    Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line on macOS or Linux. Business or Enterprise plan required to deploy Workers.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

  • Notion Workers & Claude Code: The New Operator’s Stack

    Notion Workers & Claude Code: The New Operator’s Stack

    There’s a word that’s been sitting in my head lately and I think it’s the right one.

    Not developer. Not user. Not prompt engineer — please, not that.

    Operator.


    The developer builds the system. The user benefits from it. The operator runs it.

    Operators have always existed. They’re the people who know a tool well enough to get unusual things out of it — who understand what’s possible, who can configure and connect and troubleshoot, who treat software as infrastructure rather than a product to consume. In a restaurant, the chef is the operator. In a warehouse, it’s the floor manager who actually knows where everything is and why the inventory system does what it does.

    In most software companies, the operator was assumed to be technical. You needed to code, or at least to read code, to run anything at a real level of depth. Everyone else was a user — handed a finished product, expected to stay in the designated lanes.

    That line is moving.


    Last night I deployed ten Notion Workers in three hours. Workers are Notion’s new hosted serverless platform — real code, running inside Notion’s infrastructure, no server to manage. I built a webhook endpoint that receives authenticated HTTP traffic from the internet and logs it to a Notion database. I built data sync Workers. I built scheduled jobs.

    I am not a developer.

    What I am is an operator. I know what I want the system to do. I can describe it precisely. I understand how the pieces connect even when I can’t write the connection myself. And I have Claude Code, which handles the TypeScript while I handle the architecture.

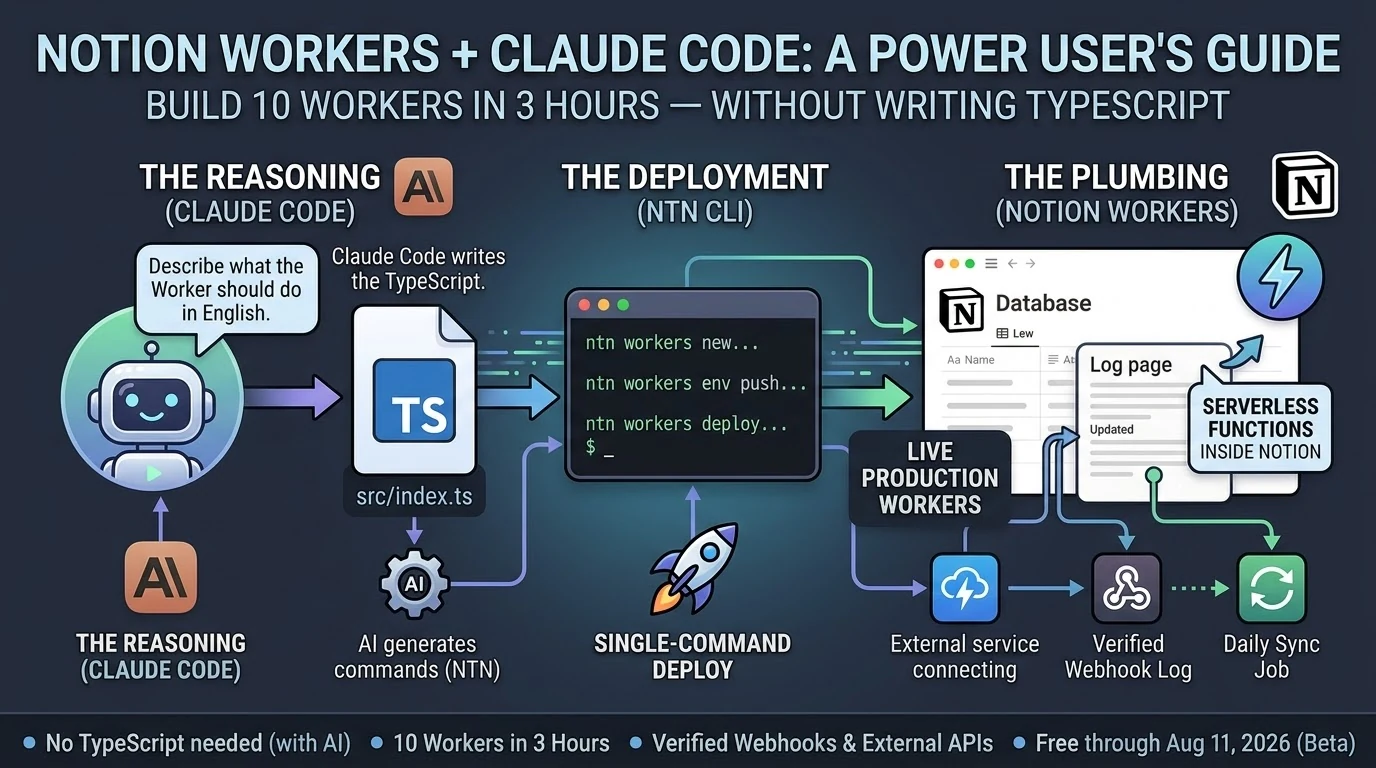
    The stack looks like this:

    Claude Code — the reasoning layer. Describe what the Worker should do in plain English. Claude Code writes the code, catches errors when you paste them back, and tells you exactly what commands to run.

    ntn CLI — the deployment layer. Four commands: scaffold, write, push secrets, deploy. Single-command deploys. You run what Claude Code tells you to run.

    Notion Workers — the execution layer. Serverless functions running on Notion’s infrastructure. They connect to external APIs, respond to webhooks, sync data, run on schedules. They do the work while you do something else.

    That’s it. Three layers. None of them require you to be a developer to operate.


    The operator’s job in this stack is not to write code. It’s to know what should exist.

    That sounds simple. It isn’t. Knowing what should exist means understanding your own operations well enough to identify where the friction is, what’s being done by hand that shouldn’t be, what would run better automatically. It means being able to describe a system clearly enough that an AI coding agent can build it. It means reviewing what gets built and knowing whether it’s right.

    That’s real skill. It’s just not the skill most people thought they needed.

    For years the implicit message was: if you can’t build it, you can’t have it. The work of describing exactly what you want, of thinking through the logic, of understanding how systems connect — that work was treated as a prerequisite for coding, not a valuable thing in its own right.

    Now it’s the job.


    I’m not going to tell you the technical barrier is gone. It isn’t. You still hit errors. You still have to read them and understand them well enough to know if Claude Code’s fix makes sense. You still have to think before you build.

    But the barrier has moved. The question is no longer “can you write TypeScript” — it’s “can you think clearly about what you want and describe it precisely.”

    Most people reading this can do that. They’ve been able to do that. They were just told, implicitly or explicitly, that it wasn’t enough.

    It’s enough now.


    The Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line on macOS or Linux. Deploying Workers requires a Business or Enterprise plan. If you’ve been running your operations in Notion and watching things like Workers from the sidelines because you figured it was for developers: it’s for operators too. You might already be one.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

  • Deploying Notion Workers With Claude Code (No TypeScript)

    Deploying Notion Workers With Claude Code (No TypeScript)

    It was late. I had Claude Code open on my laptop and a fresh cup of coffee going cold next to it.

    Notion had shipped Workers eight days earlier — their new hosted serverless platform, basically “run real code inside Notion without managing a server.” I’d been meaning to dig in. Last night I finally did.

    I want to tell you what that actually looked like. Not a tutorial. Not a polished case study. Just what happened, in order, including the parts that didn’t work.


    By midnight I had ten Workers deployed and a live webhook endpoint logging authenticated traffic from the internet into a Notion page. The whole thing took about three hours.

    I did not write TypeScript.


    Here’s the honest version of how it went.

    The first Worker took the longest — maybe 35 minutes — because I was figuring out the CLI at the same time as building the thing. The ntn tool is straightforward once you understand it: scaffold, write the code, push your secrets, deploy. Four steps. But the first time through any new tool you’re reading error messages and second-guessing yourself.

    Claude Code handled the TypeScript. I described what I wanted — a Worker that receives a POST request, verifies an HMAC signature, and appends a line to a Notion log page. Claude Code wrote it. I ran the commands it told me to run. The Worker deployed.

    I tested it. It worked.

    The second one took 22 minutes. The third took 15. By Worker five I was moving fast enough that I stopped tracking individual times and just kept going.

    Two of them didn’t work on the first try. One had a secret I’d named wrong in the environment — my fault, five minutes to fix. The other had a logic error in how it was handling the Notion API response. Claude Code caught it when I pasted the error back in, rewrote the relevant section, and I redeployed. Eight minutes total for that dead-end.

    Neither failure felt like a crisis. That’s the part I want to underline. When something broke, the path forward was obvious: read the error, paste it back to Claude Code, get a fix, redeploy. The loop was tight enough that failure was just a speed bump, not a wall.


    At 02:54 in the morning, I sent a test ping to Worker #8.

    The webhook logger received it, verified the HMAC signature, and wrote this to a Notion page in real time:

    🔔 2026-05-21T02:54:44.452Z [claude-test:test] {"event":"test","message":"Hello from Worker #8 self-test","sender":"claude-code"}

    I sat there for a second looking at that.

    There’s something specific about seeing a system you built actually receive traffic. It’s not the same as a script running on your laptop. This was a deployed endpoint, on Notion’s infrastructure, receiving an authenticated HTTP request from the open internet and writing the result to a database. Automatically. Without me doing anything after the initial deploy.

    That’s a different category of thing than what I had before.


    I want to be honest about what I am, technically. I’m not a developer. I’ve picked up enough over the years to be dangerous — I can read code, I understand how APIs work, I’ve shipped things — but I’m not someone who sits down and writes TypeScript from scratch.

    Last night didn’t require that. What it required was knowing what I wanted, being able to describe it clearly, and being willing to run commands and read errors.

    That’s it.

    The question I keep hearing from people who run operations like mine — agencies, small teams, people who live in tools like Notion and have always hired out the code work — is whether any of this AI coding stuff is actually for them or if it’s still fundamentally a developer story with a better interface.

    Last night felt like an answer. Ten Workers. Three hours. No TypeScript.

    If you can describe what you want clearly enough to explain it to another person, you can build this. The friction that used to live between “I know what I want” and “it exists in the world” is genuinely smaller now.

    Not gone. Smaller.

    You still have to show up. You still have to read the errors. You still have to think through what you’re building before you build it.

    But if you’ve been waiting for some invisible threshold of technical credibility before you try — you’re past it. You were probably past it a while ago.


    The Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line. Business or Enterprise plan required to deploy.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

  • Building 10 Notion Workers in 3 Hours With Claude Code

    Building 10 Notion Workers in 3 Hours With Claude Code

    Notion shipped Workers on May 13, 2026 (Notion Help). By last night I had ten of them running in production, including a live HMAC-verified webhook endpoint that’s actively logging events. Total build time: about three hours.

    I didn’t write TypeScript by hand. Claude Code did most of the typing.

    Here’s what that actually looked like — and what it means for the non-developer Notion power user who’s been watching the Workers announcement and wondering if it’s for them.

    What are Notion Workers? Notion Workers are hosted serverless functions that run inside Notion’s infrastructure. You write code, deploy it through the ntn CLI, and Notion runs it in a secure sandbox — no server to manage. They’re free through August 11, 2026, then run on Notion credits. Deploying Workers requires a Business or Enterprise plan.

    What Notion Workers Actually Are (The One-Paragraph Version)

    Side-by-side cards defining what Claude Code is and is not
    What Notion Workers actually are.

    If you’ve used Notion’s built-in database automations — the lightning bolt icon — Workers are that concept extended to real code. They can call any external API, respond to webhooks, sync data from Stripe or Zendesk or GitHub, and write results back to Notion databases. The CLI (ntn) is available on all plans. Deploying Workers requires Business or Enterprise.

    Do You Need to Know TypeScript to Build Notion Workers?

    Technically, Workers are written in TypeScript. Practically, if you have Claude Code, the answer is no.

    Claude Code (currently at v2.1.144 as of May 19, 2026) scaffolds Workers from plain-English descriptions. You describe what the Worker should do. Claude Code writes the src/index.ts, handles the ntn workers env push for secrets, and tells you exactly what commands to run. You copy the command. The Worker deploys.

    The workflow looks like this:

    1. ntn workers new my-worker-name — scaffold the project
    2. Tell Claude Code what the Worker should do
    3. Claude Code writes src/index.ts
    4. ntn workers env push — push any secrets (API tokens, webhook keys)
    5. ntn workers deploy --name my-worker-name — ship it

    That’s it. The only thing you actually type is the deploy commands. Claude Code fills in the gap between them.

    What We Built in 3 Hours

    Five stacked panels of daily Claude Code command habits
    What we built in 3 hours.

    Ten Workers, averaging about 18 minutes each, including two dead-ends that took 5–8 minutes to diagnose and abandon.

    The most useful one is Worker #8: an HMAC-verified webhook logger. Any external service — GitHub, Stripe, a cron trigger, another Claude Code session — can POST to the Worker’s endpoint with a shared secret, and it auto-appends a timestamped line to a Notion log page. The webhook log shows its first self-test ping from Claude Code at 02:54 UTC:

    🔔 2026-05-21T02:54:44.452Z [claude-test:test] {"event":"test","message":"Hello from Worker #8 self-test","sender":"claude-code"}

    That’s a live, verifiable event log. Not a draft. Not a mock. A deployed Worker receiving authenticated HTTP traffic and writing to Notion.

    The ntn workers env push command works cleanly for both NOTION_API_TOKEN and non-Notion secrets like TYGART_WP_USER and WEBHOOK_SECRET — one of the key things we needed to confirm before trusting the stack at scale.

    The Design Principle That Makes This Actually Work

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The design principle that makes this work.

    The best insight from Notion’s Workers documentation: use code for deterministic work, use AI for judgment calls.

    A Worker that pulls invoice status from Stripe and updates a Notion database doesn’t need AI. It needs reliable, cheap code execution. That’s what Workers give you. A Claude Sonnet 4.6 (claude-sonnet-4-6) or Opus 4.7 (claude-opus-4-7) agent that reads those Notion rows and drafts follow-up emails is handling the judgment call. Those are two different tools for two different jobs.

    When you collapse that distinction — letting AI do everything — you pay AI prices for work that shouldn’t require AI reasoning. Workers run at a fraction of the cost of AI credits. Notion’s own example calculations put a daily sync job at roughly one cent per month. The AI layer sits on top for the parts that actually need it.

    This is the architecture: Workers handle the plumbing. Claude handles the reasoning. You stop paying Opus rates for jobs a ten-line TypeScript function can do.

    The Part Nobody Else Is Writing About

    Every guide covering Notion Workers frames it as a solo-developer workflow. You sit down, you know TypeScript, you build a Worker over an afternoon.

    That’s not how this went.

    Claude Code is listed in Notion’s own documentation as a first-class deployment partner for Workers. The ntn CLI was explicitly designed to work with coding agents — same interface for humans and agents. When you treat Claude Code as the author and yourself as the operator running the commands it outputs, you get through ten Workers in a session that most developers would take a week to plan.

    The non-developer angle is real. If you run Notion as your operating system — databases, automations, dashboards — and you’ve been watching the Workers announcement wondering whether it requires a CS degree, the answer in May 2026 is: not if you have Claude Code. The scaffolding is a one-line command. The deployment is a one-line command. Claude Code fills in the gap between them.

    Three Things to Know Before You Start

    Business or Enterprise plan required to deploy. The CLI (ntn) installs on any plan and runs free. Deploying Workers needs Business or Enterprise. Check your plan before you spend an afternoon scaffolding.

    macOS and Linux only as of May 2026. Windows users need WSL2. Native Windows support is listed as coming soon. If you’re on Windows without WSL2, that’s your first step.

    Free through August 11, 2026. After that, Workers run on Notion credits. Build and optimize now while the cost is zero. The free period gives you enough runway to understand your actual usage patterns before you’re paying for them.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

    Frequently Asked Questions

    What is the Notion Workers free period?

    Notion Workers are free to try during the beta period, which runs through August 11, 2026. After that date, Workers will run on Notion credits. The free period is a good window to build, test, and optimize your Workers before metered usage begins.

    Can non-developers build Notion Workers?

    Yes, if you have an AI coding agent like Claude Code. Workers are written in TypeScript, but Claude Code can generate the Worker code from a plain-English description. You run the scaffold and deploy commands; Claude Code writes the code. No prior TypeScript knowledge required.

    What Notion plan do you need for Workers?

    The ntn CLI is available on all Notion plans. Deploying and managing Workers requires a Business or Enterprise plan.

    How does Claude Code work with Notion Workers?

    Claude Code (v2.1.144 as of May 2026) integrates directly with the ntn CLI. Notion designed the CLI as a tool for both humans and coding agents — same interface, same commands. Claude Code scaffolds the Worker TypeScript, sets environment variables, and outputs the exact deploy commands to run.

    What can Notion Workers do?

    Workers can call any external API, respond to incoming webhooks (with HMAC verification), sync data between external services and Notion databases, run scheduled tasks, and execute custom business logic. Common use cases include syncing Stripe payments, Zendesk tickets, GitHub issues, or any service with an API into Notion.

    Is the ntn CLI available on Windows?

    As of May 2026, the ntn CLI is available on macOS and Linux. Windows support is listed as coming soon. Windows users can use WSL2 in the meantime.

    The Bottom Line

    Ten Workers. Three hours. A verified webhook endpoint logging live traffic. Claude Code did the TypeScript. The ntn CLI did the deployment. Notion’s infrastructure handled everything else.

    The question isn’t whether Notion Workers are for developers. The question is whether you have a coding agent. If you do, the friction is gone.

  • Sentry MCP Server: Essential Claude Code Integration

    Sentry MCP Server: Essential Claude Code Integration

    Most engineers who install MCP servers in Claude Code stop at GitHub. That’s a mistake. The GitHub server is the easy first install — but the integration that actually changes how I work is Sentry, and the pattern that emerges once it’s wired up tells you everything about how to think about MCP.

    Here’s the workflow I’m running this week: an alert fires in Sentry, I paste the issue ID into Claude Code, and the agent reads the stack trace, pulls the offending file from the repo, writes the fix, opens a PR, and links the PR back to the Sentry issue. I never opened the Sentry dashboard. I never copy-pasted a stack trace. Two MCP servers, one terminal, one round trip.

    Why Sentry is the high-value second install

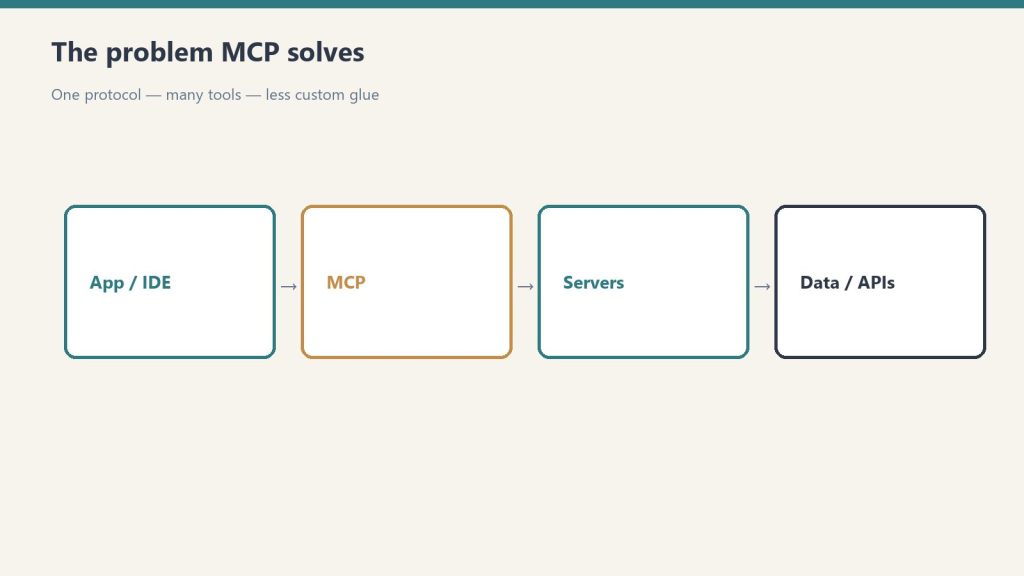
    Flow from app/IDE through MCP to servers and data APIs
    Why Sentry is the high-value second install.

    GitHub MCP makes Claude Code a contributor. Sentry MCP makes it an on-call responder. The difference matters because the most expensive minutes in any engineering org are the ones between “alert” and “first line of investigation.” That gap is almost entirely context-switching cost — tab to the alerting tool, find the right issue, copy the stack trace, paste it somewhere the LLM can see it, then start.

    The Sentry MCP server is a remote HTTP server hosted by Sentry, which means there’s no Docker container to maintain and no local process to babysit. You authenticate once with a personal access token and Claude Code can pull issue details, search across projects, fetch event payloads, and read breadcrumbs directly into context.

    The install — three commands, two integrations

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The install — three commands, two integrations.

    Here’s the actual setup. GitHub first:

    claude mcp add github \
      -e GITHUB_PERSONAL_ACCESS_TOKEN=ghp_your_token \
      --scope user \
      -- docker run -i --rm \
      -e GITHUB_PERSONAL_ACCESS_TOKEN \
      ghcr.io/github/github-mcp-server

    Then Sentry. Sentry runs as a remote HTTP server, so the syntax is different:

    claude mcp add --transport http sentry https://mcp.sentry.dev/mcp \
      --scope user \
      -H "Authorization: Bearer YOUR_SENTRY_PAT"

    Verify with claude mcp list. You should see both servers reporting healthy. If Sentry returns a 401, the token doesn’t have the right project scopes — Sentry’s tokens are project-scoped, not org-scoped, so this trips up people who are used to GitHub PATs.

    One configuration detail worth noting: I use --scope user for both. Project scope writes to .mcp.json in the repo, which is fine for team-wide tools but wrong for personal credentials. User scope keeps the token in your own config and out of the repo.

    The prompt pattern that makes it work

    The naive approach is “fix Sentry issue 12345.” That works but burns tokens because Claude has to discover the tool, fetch the issue, parse the stack trace, identify the file, and only then start reasoning about the fix. With Tool Search — the on-demand tool discovery that ships with Claude Code — the cost is lower than it used to be, but it’s still slower than necessary.

    The pattern I’ve settled on is more directive: “Pull Sentry issue PROJECT-12345, identify the file and line from the stack trace, read the surrounding context, and draft a fix as a branch off main. Don’t open the PR yet.” That gives Claude a strict sequence and lets me review the branch before anything goes to GitHub.

    The “don’t open the PR yet” part matters. When you chain two write-capable MCP servers, the failure mode is that Claude races ahead and pushes a half-baked fix because it has the tools and the authority. Constraining the action surface in the prompt is how you keep this useful instead of dangerous.

    What breaks, and how to know

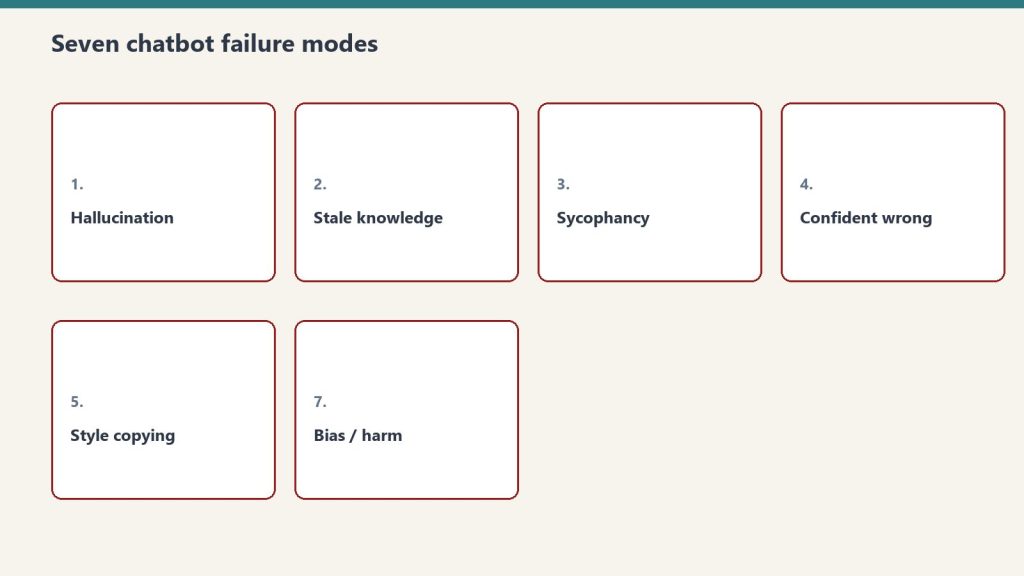
    Seven cards naming common AI chatbot failure modes
    What breaks, and how to know.

    Three things have failed for me in the last month and each one is worth knowing.

    First: Sentry rate-limits aggressively. If you’re working through a long incident and Claude is making repeated calls, you’ll hit the limit and the tool calls will start returning errors mid-conversation. The fix is to ask Claude to dump everything it needs from Sentry in one call, then work from that context. The token cost is higher upfront but the workflow is more reliable.

    Second: GitHub MCP via Docker has a cold-start cost on the first call of a session — typically two to four seconds while the container spins up. This is fine but it does mean the first response feels slow. If you’re on a Mac with Apple Silicon, the container image is multi-arch and works without the --platform linux/amd64 flag.

    Third: when both servers are connected and you have other MCP servers installed, Claude will sometimes route a Sentry-shaped question through GitHub’s search instead. The fix is to name the tool in the prompt — “use the Sentry MCP to fetch issue X” — rather than trusting the routing. This is a known cost of running many servers and is the trade-off you accept for breadth.

    The pricing reality

    Sentry MCP is free to use if you have a Sentry account — there’s no additional charge for the MCP layer. The cost comes from the Claude API tokens you burn pulling Sentry data into context. A typical issue investigation runs 8,000 to 15,000 input tokens depending on stack trace length and breadcrumb count. On Sonnet 4.6 (legacy — still listed) that’s roughly $0.02 to $0.05 per investigation, which is trivial compared to

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    the engineering time saved.

    GitHub MCP is the same story — free server, you pay only for tokens. The Docker image is open source under github/github-mcp-server on GHCR.

    What I’d install next

    After GitHub and Sentry, the next install that earns its keep is Postgres if you have a database, or Linear if your team uses it for issue tracking. The pattern is the same in every case: the MCP server you want is the one that eliminates the highest-frequency context switch in your day, not the one with the most features. Audit your own tab-switching for a week. Whichever app you alt-tab to most often is the next MCP server worth wiring in.

    The deeper lesson is that MCP changes the shape of what a coding agent is for. Without integrations, Claude Code is a smart autocomplete. With two well-chosen MCP servers, it becomes the connective tissue between alert, code, and ship — which is most of what engineering work actually is.

    Related on Tygart Media: how to use Claude · Anthropic API key.