Blog

  • Claude Pro vs Max: Is the $100 Upgrade Worth It? (2026)

    Claude Pro vs Max: Is the $100 Upgrade Worth It? (2026)

    Last verified: October 2, 2026 (Pacific).

    Claude Pro costs $20/month. Claude Max costs $100 or $200/month. The question everyone asks: is 5x or 20x the price actually worth it? The answer depends entirely on how you use Claude. This comparison breaks down the real differences — not the marketing bullet points — so you can make an informed decision.

    What Pro Gives You
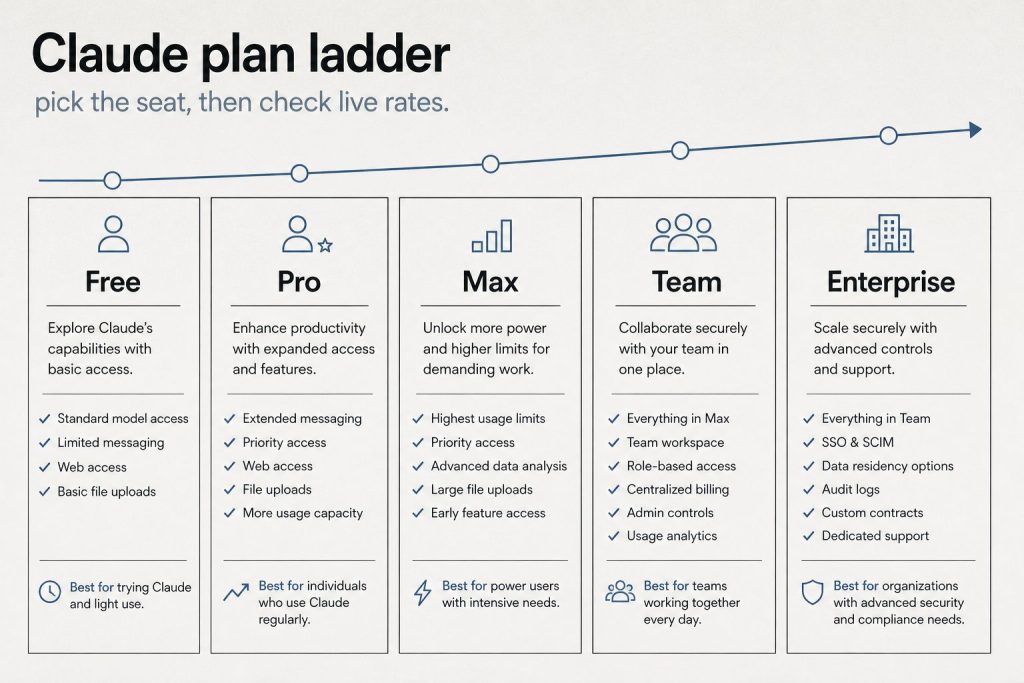
    Infographic ladder of Claude plans: Free, Pro, Max, Team, and Enterprise
    What Pro gives you — stale-proof.

    Pro at $20/month ($17/month annual) includes Claude Code, Claude Cowork, unlimited Projects, Research mode, access to additional models, and Claude for Microsoft 365 and Outlook. The usage allowance is described as “more usage” compared to Free — in practice, this means you can have sustained conversations throughout a workday without hitting limits under normal use. Most professionals who use Claude as a daily tool — a few hours of active conversation per day — find Pro sufficient.

    What Max Adds
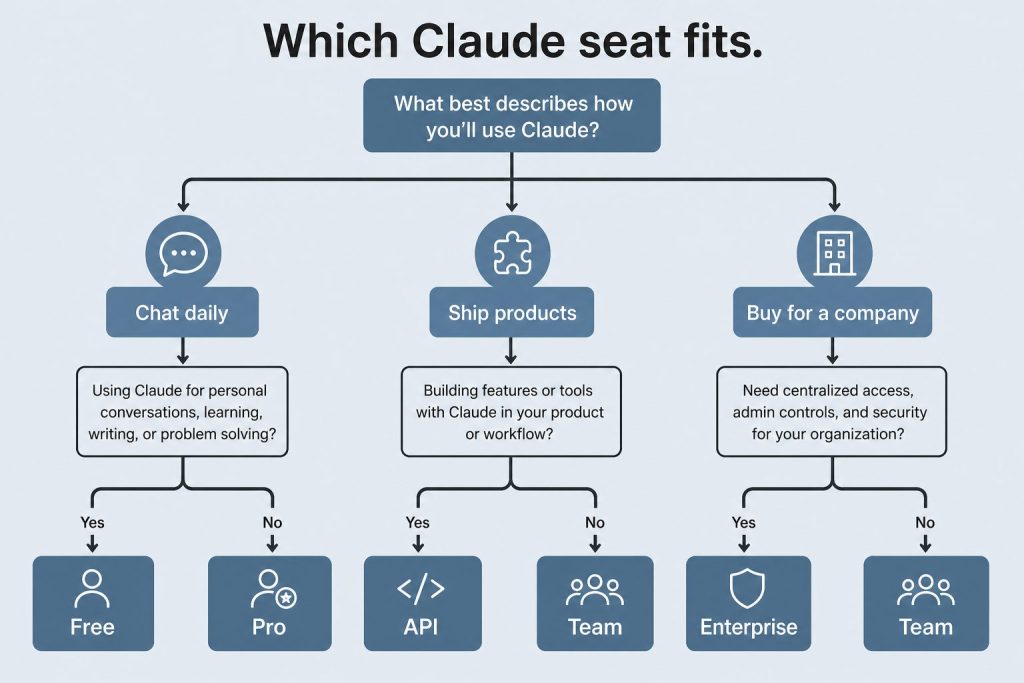
    Decision map from daily chat, shipping products, or buying for a company to Free/Pro, API, or Team/Enterprise

    What Max adds.

    Max comes in two tiers. The $100/month tier gives approximately 5x the usage of Pro. The $200/month tier gives approximately 20x. Beyond the usage multiplier, Max adds three concrete features: higher output limits for all tasks (longer responses, more complex code generation), early access to advanced Claude features before they reach Pro users, and priority access during high-traffic periods (you skip the queue).

    The Fable factor: Max’s real exclusive

    Direct answer: Max is now the only individual plan that includes Anthropic’s Fable models. On Pro, every Fable token runs on usage credits; on Max 5x and 20x, Fable is included up to half the weekly usage pool. If your work benefits from Fable — long-horizon agent loops with heavy cache reuse — this alone can decide the plan. Our Fable 5 pricing guide breaks down the $10/$50 headline rates and the 75% cache-read cut that Fable 5.1 brought on September 1.

    Who Actually Needs Max
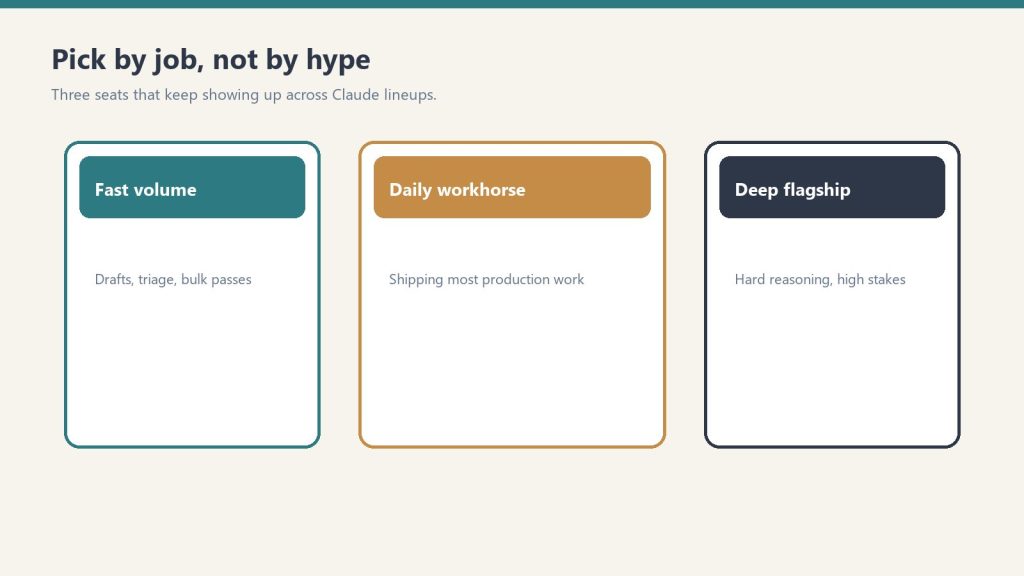
    Three cards for fast volume, daily workhorse, and deep flagship Claude seats

    Who actually needs Max.

    Heavy Claude Code users: If you spend 4+ hours per day actively using Claude Code for development — not just coding, but running extended agent sessions, multi-file refactoring, and complex debugging — you’ll likely hit Pro limits. Max 5x removes this friction. Content production teams: If you’re producing 10+ pieces of content per day through Claude, the usage adds up fast. Researchers and analysts: Extended research sessions with multiple deep-dive conversations consume significant tokens. Anyone who hits Pro limits regularly: If you see the “usage limit reached” message more than once or twice per week, Max pays for itself in recovered productivity.

    Who Should Stay on Pro

    Most individual professionals: If you use Claude for 1-3 hours per day with normal conversation patterns, Pro is plenty. Occasional users: If Claude is one of many tools in your workflow rather than the central one, Pro is more than enough. Budget-conscious users: At $20/month, Pro delivers extraordinary value. The jump to $100/month should be justified by measurable productivity gains. Users who haven’t hit Pro limits: If you’ve never seen the usage limit message, you don’t need Max.

    When you hit the wall: usage credits

    One newer mechanic worth knowing before you upgrade: when a paid plan hits its usage limit, usage credits keep Claude working at standard API rates instead of making you wait for the 5-hour reset window. Credits are pay-as-you-go on top of the subscription — the middle path for spiky weeks where one heavy project doesn’t justify a whole tier upgrade. If you hit Pro limits twice a month rather than twice a week, credits are usually cheaper than Max.

    The Math on Max

    Max 5x costs $80/month more than Pro. If that additional usage saves you 2+ hours per week of productivity (waiting for limits to reset, or time spent on tasks you could have delegated to Claude), and your time is worth $40+/hour, Max pays for itself. Max 20x at $200/month ($180 more than Pro) needs to save roughly 4.5 hours/week to break even at $40/hour. The early access and priority features are hard to quantify financially — they matter most for users who need Claude reliably during peak demand.

    A Better Strategy Than Max

    Before upgrading to Max, consider whether your usage patterns can be optimized on Pro. Use Projects to maintain context instead of repeating background in every conversation. Be concise in prompts — verbose prompts consume more tokens. Use the appropriate model (Haiku for simple tasks, Sonnet for standard work, Opus for complex reasoning). Close conversations you’re done with rather than continuing indefinitely. If you’re hitting limits despite these optimizations, Max is the right move.

    How Claude usage limits actually work

    Claude usage limits reset on a rolling five-hour window, and paid plans add weekly limits on top of that. There is no fixed number of messages.

    On claude.com/pricing, checked October 2, 2026, Free covers everyday questions. Pro includes at least 5x more usage per five-hour session than Free. Max includes 5x or 20x more usage per five-hour session than Pro. The Max card lists the plan from $100 per month and lets you choose the 5x or 20x option. Chat on the web, the desktop app, mobile, and Claude Code all draw from the same pool.

    What spends the allowance is the work itself. A longer conversation, a heavier model, file creation, or research uses more of the window than a short question. Anthropic also says it may apply weekly or monthly caps, or limits on a specific model or feature, so one account does not crowd out everyone else. On the plan table, Fable is unavailable on Free, listed as usage credits on Pro, and listed as 50% of weekly limits on both Max options.

    When a limit hits, the same page gives three moves: wait for the reset, move to a higher plan, or, on a paid plan, turn on usage credits and keep working at standard API rates. Settings, then Usage, shows the current status. Team seats use a different meter. A standard seat includes more usage than Pro, at $20 per seat per month billed annually or $25 billed monthly. A premium seat includes 5x the usage of a standard seat, at $100 per seat per month billed annually or $125 billed monthly.

    Pricing checked October 2, 2026. Source: claude.com/pricing.

    Claude API pricing, by model

    A Claude API bill is input tokens plus output tokens, and output costs more than input on every current model. Prices below are US dollars per million tokens. Pricing checked October 2, 2026.

    • Fable 5.1: $10 input, $50 output
    • Opus 5.5: $4 input, $20 output
    • Sonnet 5.5: $2 input, $10 output
    • Haiku 4.5: $1 input, $5 output

    The official table also lists older and retired models. Those rows are omitted here. Sonnet 5 is the same $2 input and $10 output as Sonnet 5.5, and Anthropic says the increase to $3 and $15 that had been scheduled for September 1, 2026 will not happen.

    The model and the length of the reply do most of the damage. Output is five times the input price on each model above, so an agent that writes a long diff costs more than one that only reads. Three other switches change the same rates. The Batch API takes 50% off input and output when the job can wait: Fable 5.1 batch is $5 and $25, Opus 5.5 is $2 and $10, Sonnet 5.5 is $1 and $5, and Haiku 4.5 is $0.50 and $2.50. US-only inference on Claude 4.6 and later multiplies input, output, cache writes, and cache reads by 1.1. Fast mode, still a research preview, prices Opus 5.5 at $8 input and $40 output, and Opus 5 or Opus 4.8 at $10 and $50. Fast mode does not run on the Batch API.

    Claude 4.6 and later include the full 1 million token context window at that same per-token rate. A 900,000-token request is billed at the same rate per token as a 9,000-token request. Claude 4.7 and later, and Mythos Preview, use a newer tokenizer that produces about 30% more tokens for the same text, so an unchanged document can cost more after a model move. Sonnet 4.6 and earlier use the previous tokenizer.

    Tools add their own lines. The pricing page lists web search at $10 per 1,000 searches, separate from the tokens used to process the request. Code execution includes 50 free hours a day per organization, then $0.05 per hour per container.

    Pricing checked October 2, 2026. Sources: Claude platform pricing and claude.com/pricing.

    When prompt caching saves money

    Prompt caching saves money when the same long prefix is sent again inside a short window. You pay extra to store that prefix, then a fraction of the normal input price each time a later request reads it.

    Anthropic’s docs, checked October 2, 2026, price a 5-minute cache write at 1.25 times the base input price and a 1-hour cache write at 2 times. A cache hit on most models costs 10% of the standard input price. The docs say 5-minute caching pays for itself after one cache read, and 1-hour caching pays for itself after two cache reads. Two current models are cheaper on the read: Fable 5.1 and Mythos 5.1 hits are $0.25 per million tokens, which is 2.5% of base input, and Opus 5.5 hits are $0.20 per million tokens, which is 5% of base input. On the standard table, a 5-minute write is $12.50 for Fable 5.1, $5 for Opus 5.5, $2.50 for Sonnet 5.5, and $1.25 for Haiku 4.5. A 1-hour write on those models is $20, $8, $4, and $2.

    The buyers who come out ahead repeat a prefix: a long system prompt, a tool list, a standing document, or an agent loop that reloads the same context every turn. A one-off short chat has nothing to reuse. Cache writes are charged when the prefix is first stored. Cache reads are charged when a later request retrieves it, and a read also refreshes the entry. Those multipliers stack with the Batch API discount and with the 1.1x US-inference multiplier.

    Pricing checked October 2, 2026. Source: Claude platform pricing.

    Claude, ChatGPT, and Gemini at comparable prices

    At the everyday paid chat tier, Claude Pro and ChatGPT Plus are both $20 a month. Above that, compare the usage multiple on the plan, and price the API separately from the subscription.

    Checked October 2, 2026. Claude lists Free at $0, Pro at $20 a month or $17 a month when $200 is billed up front for the year, and Max from $100 a month with a choice of 5x or 20x more usage than Pro per five-hour session. OpenAI’s Help Center lists ChatGPT Plus at $20 a month, billed monthly, and two Pro tiers: $100 for 5x the usage of Plus, and $200 for 20x the usage of Plus. The Plus article says API usage is billed separately. ChatGPT Go appears as a lower plan; a current Go dollar price was not on the pages read for this check.

    The meters differ even when the monthly price lines up. Claude draws web, desktop, mobile, and Claude Code from one pool, on a rolling five-hour window, with weekly limits added on paid plans. OpenAI’s Pro article says models can have separate allowances, and reaching one model’s allowance does not by itself end the plan. Pick the product whose limit matches the work.

    API rates below are the standard paid tier, in US dollars per million tokens, from the same October 2, 2026 check. Where a vendor publishes a short-context rate and a long-context rate, both are included.

    • Claude Haiku 4.5 is $1 input and $5 output. Sonnet 5.5 is $2 and $10. Opus 5.5 is $4 and $20. Fable 5.1 is $10 and $50. Claude 4.6 and later keep that per-token rate through a 1 million token context window.
    • On OpenAI’s standard tab, gpt-6-luna is $0.10 input and $0.50 output for short context, and $0.20 and $0.75 for long context. gpt-6.1-sol is $2 and $10 short, and $4 and $15 long. gpt-6-astra is $10 and $50 short, and $20 and $75 long. The same page also publishes Batch, Flex, Fast, and Ultrafast rates.
    • On Google’s Gemini API, standard paid, Gemini 3.8 Flash is $0.75 input and $3.75 output through December 31, 2026, then $1.50 and $7.50. Gemini 3.1 Pro Preview is $2 input and $12 output on prompts up to 200,000 tokens, and $4 and $18 above that. Gemini’s output price includes thinking tokens.

    The useful comparison is the shape of the bill. On all three, output tokens cost more than input tokens. OpenAI’s flagship models and Gemini 3.1 Pro Preview raise the per-token rate once a prompt crosses their long-context line. Claude’s current models keep one rate inside the 1 million token window. A repeated prefix is discounted on each platform under that platform’s own cache rules.

    Pricing checked October 2, 2026. Sources: claude.com/pricing, Claude API pricing, ChatGPT Plus, ChatGPT Pro tiers, OpenAI API pricing, and Gemini API pricing.

    Related on Tygart Media: Claude AI pricing guide · Fable 5 pricing, cache rates & plan access · Claude Code pricing 2026 · Claude Team pricing · How much does Claude cost.

    Frequently Asked Questions

    Is Claude Max worth $100 a month?

    If you regularly hit Pro usage limits — especially heavy Claude Code users, content producers, or researchers — Max pays for itself in recovered productivity. If you’ve never hit Pro limits, stay on Pro.

    What is the difference between Max 5x and Max 20x?

    Max 5x ($100/month) gives 5x the usage of Pro. Max 20x ($200/month) gives 20x. Both include higher output limits, early feature access, and priority. Most users who need Max find 5x sufficient.

    Can I switch between Pro and Max?

    Yes. You can upgrade from Pro to Max or downgrade from Max to Pro at any time. Changes take effect on the next billing cycle.

    Does Max include Claude Code?

    Yes. Both Pro and Max include Claude Code. Max gives you more usage capacity for Claude Code sessions.

    Does Claude Max include Fable?

    Yes — Max is the only individual plan that includes Fable models, up to 50% of the weekly usage pool. On Pro, Fable usage runs on usage credits from the first token.

    What are Claude usage credits?

    Pay-as-you-go tokens billed at standard API rates that keep you working when a paid plan hits its limit, instead of waiting for the reset window. Ideal for occasional spike weeks.

    Can I pay for Max annually?

    No. Max 5x and Max 20x are monthly billing only. Pro is the plan with an annual option — $17/month billed yearly ($200 up front).


    Manage it all from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator for your actual usage.
  • Claude for Content Creation: How to Use AI for Writing, SEO, and Marketing in 2026

    Claude for Content Creation: How to Use AI for Writing, SEO, and Marketing in 2026

    Claude has become a core tool for content teams — not as a replacement for human writers, but as a force multiplier that changes what’s possible with limited resources. This guide covers the practical workflows that professional content creators, SEO specialists, and marketing teams use with Claude in 2026, including where it excels, where it falls short, and how to integrate it into a production content operation.

    Blog Posts and Long-Form Content

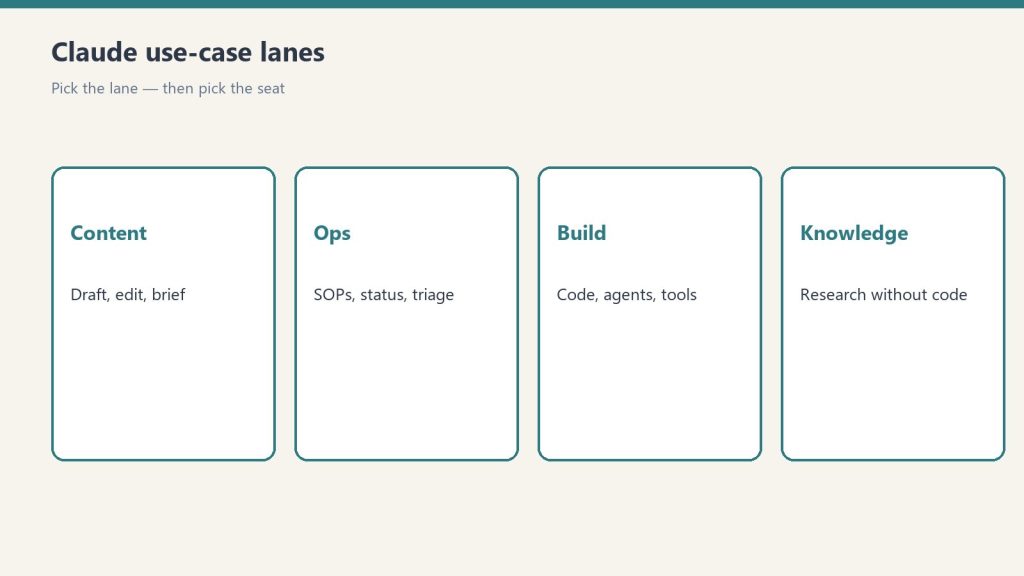
    Four cards for content, ops, build, and knowledge work with Claude
    Blog posts and long-form with Claude.

    Claude excels at drafting long-form content when given proper direction. The key is providing a detailed brief — not just a topic, but the target keyword, the audience, the desired structure, the tone, competing content to differentiate from, and any specific data or examples to include. A well-briefed Claude request produces a first draft that’s 70-80% of the way to publishable, versus a vague request that produces generic filler.

    Best practices for blog production: write a content brief first (or use Claude to help write one), include your brand voice guidelines in a Project, specify the exact structure you want (H2s and H3s), request specific word counts, and always edit the output for accuracy, originality, and brand alignment. Never publish AI-generated content without human review — this is especially important for factual claims, statistics, and technical accuracy.

    SEO Content Optimization

    Comparison of Claude how-to fit versus local service page fit for assistants
    SEO content optimization workflows.

    Claude can analyze existing content for SEO improvements — identifying missing keywords, suggesting heading structure changes, improving meta descriptions, and recommending internal linking opportunities. Feed Claude your target keyword, your current content, and competitor content, and ask for specific optimization recommendations. Claude can also generate FAQ sections with structured data markup, which directly targets featured snippets and People Also Ask placements.

    For new content, Claude can research keyword clusters, identify search intent, and draft content structured for both traditional SEO and emerging AI search optimization (AEO/GEO). The combination of web search capability and content generation means Claude can research a topic and draft optimized content in a single session.

    Email Marketing

    Claude handles email marketing content effectively — subject line variations, body copy, CTAs, and nurture sequences. The workflow that works best: share your product/service details and audience information in a Project, then request specific email types (welcome sequence, promotional, re-engagement, newsletter). Claude can generate multiple variations for A/B testing and adapt tone for different segments.

    Social Media Content

    Claude can repurpose long-form content into social media posts tailored for different platforms — LinkedIn articles and thought leadership posts, Twitter/X threads, Instagram captions, and Facebook updates. Provide the source content and specify the platform, tone, and any hashtag or formatting requirements. Claude adapts naturally between professional (LinkedIn), conversational (Twitter), and visual-caption (Instagram) styles.

    Content Strategy and Planning

    Three cards for LSA, search ads, and SEO/AI authority channels
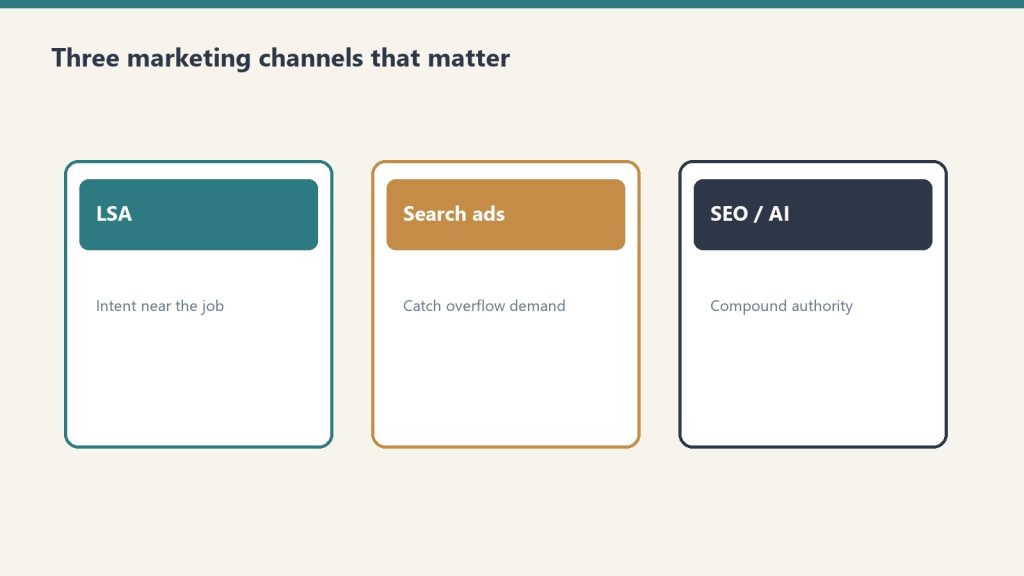
    Content strategy and planning.

    Beyond individual pieces, Claude can help with content strategy — editorial calendar planning, content gap analysis, persona development, and competitive content auditing. Upload your existing content inventory, share your business goals and target audience, and ask Claude to identify gaps, suggest topics, and prioritize based on potential impact. This is especially powerful with web search enabled, allowing Claude to analyze competitor content in real-time.

    Quality Control and Accuracy

    AI-generated content requires human quality control. Every piece should be checked for factual accuracy (especially statistics, dates, and specific claims), brand voice consistency, originality (run through plagiarism detection), legal compliance (disclaimers, disclosures), and genuine value to the reader. The biggest risk with AI content is not that it’s bad — it’s that it’s competent but generic. Human editors should push for the specific insights, examples, and perspectives that make content genuinely useful rather than just technically correct.

    Related on Tygart Media: beginner prompting · Claude for business.

    Frequently Asked Questions

    Can Claude write SEO content?

    Yes. Claude can draft keyword-optimized content, generate meta descriptions, create FAQ sections with schema markup, and analyze content for SEO improvements. Human review for accuracy and originality is essential.

    Should I use Claude to write my entire blog?

    Use Claude as a drafting and optimization tool, not a hands-off content factory. The best results come from human-directed Claude drafts that are then edited for accuracy, brand voice, and genuine insight.

    Can Google detect AI-written content?

    Google has stated it focuses on content quality regardless of how it’s produced. The key is creating content that’s helpful, accurate, and provides genuine value — whether written by humans, AI, or both.

    How much content can Claude produce per day?

    On a Pro plan, a content professional can realistically produce 5-10 well-researched, edited articles per day with Claude assistance — compared to 1-2 without it. The bottleneck shifts from writing to editing and quality control.

  • Claude MCP (Model Context Protocol): What It Is, How It Works, and Why Developers Care

    Claude MCP (Model Context Protocol): What It Is, How It Works, and Why Developers Care

    Model Context Protocol (MCP) is an open standard created by Anthropic that lets Claude connect to external tools, data sources, and services. Instead of copying data into Claude manually, MCP gives Claude structured access to the tools you already use — databases, APIs, project management platforms, file systems, and more. MCP has become one of the most important developments in the AI ecosystem in 2026, and understanding it is increasingly essential for developers and technical teams.

    What MCP Actually Does

    Three-layer MCP architecture: host, client, server
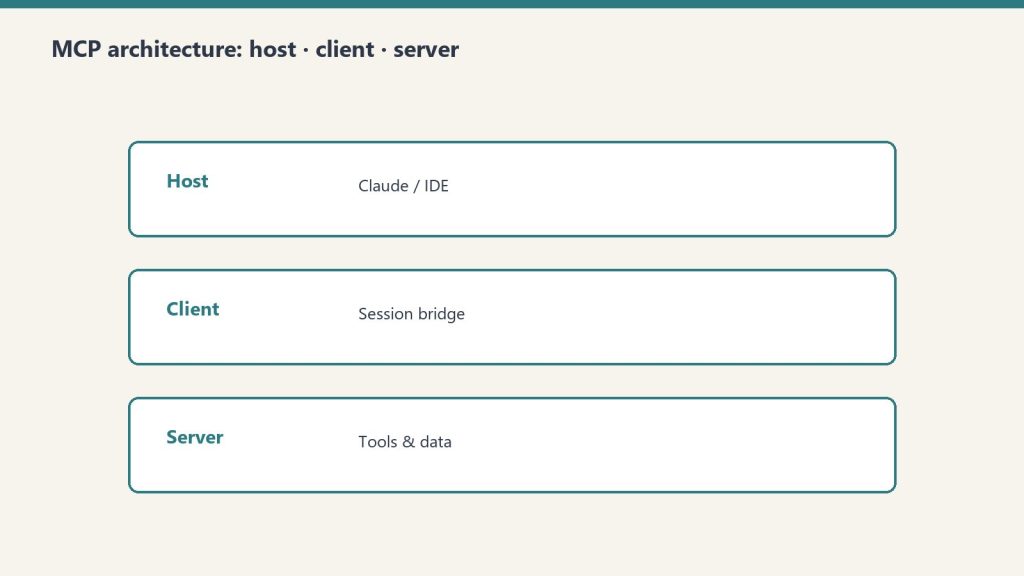
    What MCP actually does — hosts, clients, servers.

    At its core, MCP is a protocol — a standardized way for AI models to communicate with external services. Think of it like how HTTP standardized web communication or how SQL standardized database queries. MCP standardizes how AI assistants request and receive data from external tools. Before MCP, connecting Claude to a database required custom integration code. With MCP, you configure an MCP server that speaks the protocol, and Claude can query the database through that server using a standardized interface.

    The Architecture: Hosts, Clients, and Servers

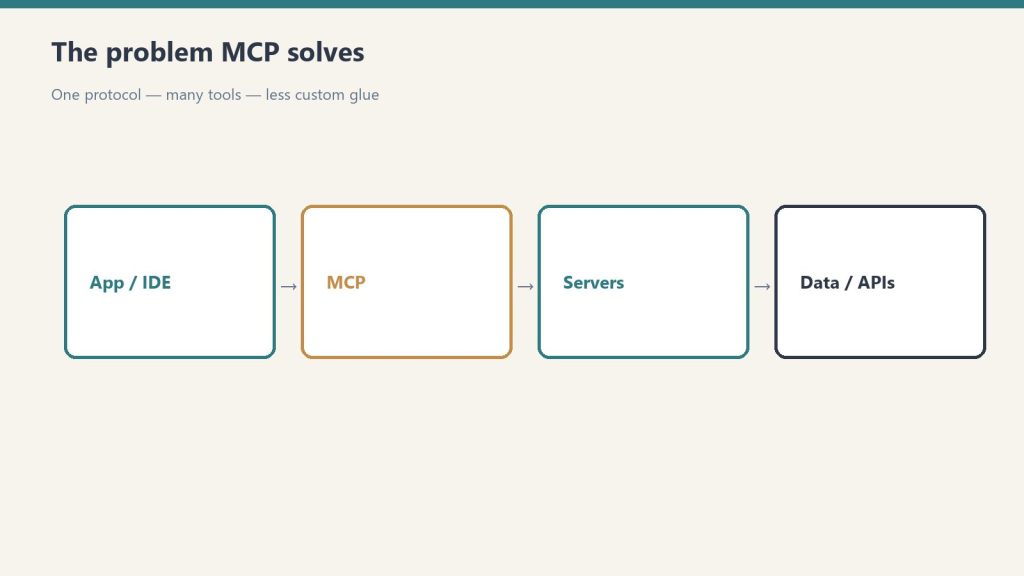
    Flow from app/IDE through MCP to servers and data APIs
    Architecture: hosts, clients, and servers.

    MCP has three components. The host is the application where Claude runs (the desktop app, Claude Code, or a custom application). The client is the MCP client built into Claude that manages connections to MCP servers. The server is the service that provides tools, data, or capabilities to Claude. MCP servers expose three types of primitives: tools (actions Claude can take, like querying a database or creating a Jira ticket), resources (data Claude can read, like file contents or documentation), and prompts (pre-built interaction patterns).

    Practical Examples

    A Notion MCP server lets Claude read and write Notion pages and databases directly. A PostgreSQL MCP server lets Claude query your database. A Slack MCP server lets Claude read channels and send messages. A GitHub MCP server lets Claude interact with repositories, issues, and pull requests. A Sentry MCP server lets Claude access error tracking and debugging data. These aren’t hypothetical — they’re production tools that teams use daily.

    Local vs Remote MCP Servers

    MCP servers can run locally on your machine or remotely as hosted services. Local MCP servers run alongside the Claude desktop app and have access to your local environment — file system, local databases, development tools. They use the stdio transport (standard input/output) and require no network configuration. Remote MCP servers run as web services and are accessed over the network using Streamable HTTP or Server-Sent Events (SSE) transports. Remote servers can be shared across teams and don’t require local installation.

    Token Cost Considerations

    An important practical consideration: MCP tools add tokens to every conversation turn. Each configured MCP server’s tool descriptions are included in Claude’s context, consuming input tokens. If you have 10 MCP servers with 5 tools each, that’s 50 tool descriptions included in every request — potentially thousands of tokens per turn. Best practices include only connecting the MCP servers you actively need, using scoped configurations to limit which tools are available in which contexts, and monitoring your token usage to identify MCP-related costs.

    Why Developers Care

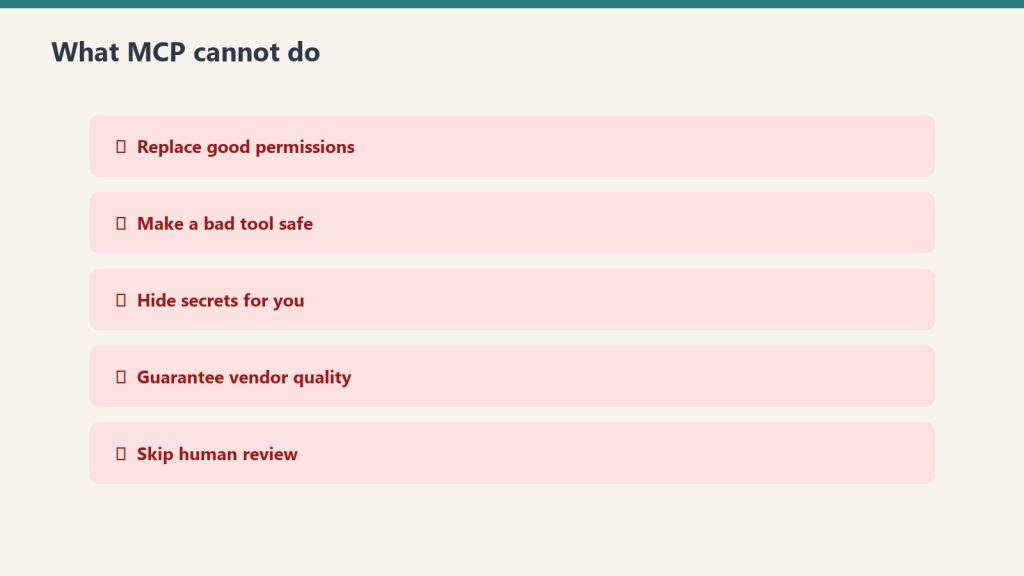
    Five red warning rows of MCP limitations
    Why developers care — less custom glue.

    MCP matters because it transforms Claude from a standalone chatbot into a connected agent. Without MCP, Claude can only work with information you paste into the conversation. With MCP, Claude can pull real-time data, take actions in external systems, and operate as part of your existing toolchain. For development teams, MCP means Claude Code can interact with your entire development stack — version control, CI/CD, error tracking, documentation, project management — through a single standardized interface.

    Getting Started with MCP

    The fastest path is to install a pre-built MCP server for a tool you already use. The Claude desktop app’s settings include MCP server configuration. Add a server definition (the server command and its arguments), restart Claude, and the tools become available in your conversations. For custom integrations, Anthropic provides SDKs for building MCP servers in Python and TypeScript. The MCP specification is open — anyone can build a server for any tool.

    Related on Tygart Media: what is MCP · Skills vs MCP · how to use Claude.

    Frequently Asked Questions

    What is Claude MCP?

    MCP (Model Context Protocol) is an open standard that lets Claude connect to external tools and data sources — databases, APIs, file systems, and more — through a standardized interface.

    Is MCP free to use?

    MCP itself is free and open. MCP servers may be free (open source) or paid (commercial). The token costs from MCP tool descriptions are included in your regular Claude usage or API billing.

    Do I need to be a developer to use MCP?

    Basic MCP server setup requires some technical comfort — editing configuration files and running commands. Pre-built connectors in the Claude interface are simpler. Building custom MCP servers requires programming knowledge.

    Can MCP be used with other AI models?

    MCP is an open protocol. While Anthropic created it for Claude, other AI platforms and tools have begun adopting MCP as a standard for tool integration.

  • Anthropic Safety and Alignment: Why Claude Is Built Differently and What It Means for Users

    Anthropic Safety and Alignment: Why Claude Is Built Differently and What It Means for Users

    Anthropic is an AI safety company that happens to build a product, not a product company that happens to care about safety. That distinction matters. Every design decision in Claude — from how it handles sensitive topics to how it processes your data — traces back to Anthropic’s safety-first philosophy. This guide explains what that philosophy is, how it works in practice, and what it means for you as a user.

    Constitutional AI: How Claude Learns to Behave

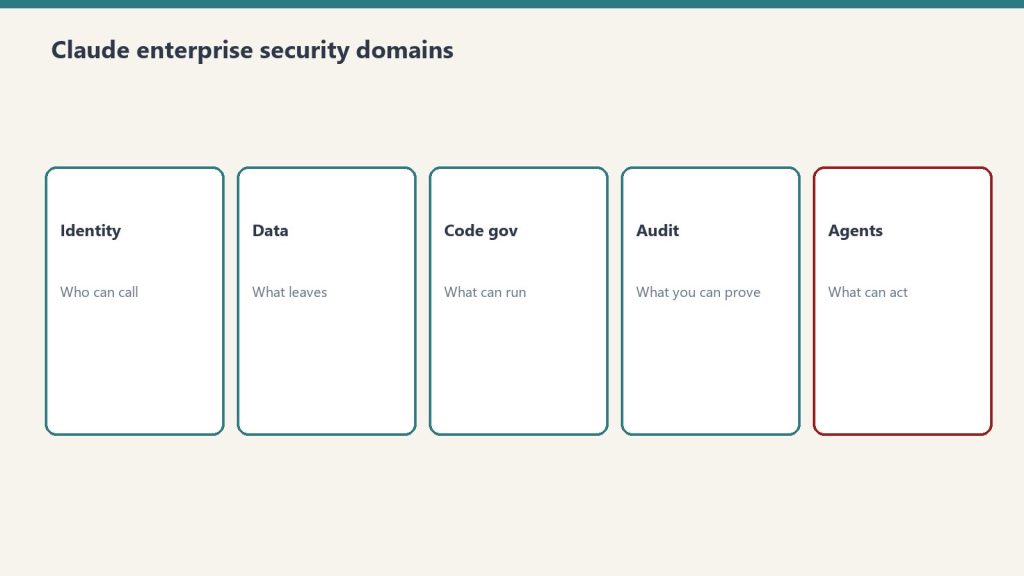
    Five security domains: identity, data, code governance, audit, agents
    Constitutional AI — how Claude learns to behave.

    Claude is trained using a methodology called Constitutional AI (CAI). Instead of relying solely on human feedback to determine what’s helpful and harmless, Claude is given a set of principles — a “constitution” — that guides its behavior. These principles cover helpfulness, harmlessness, and honesty. During training, Claude evaluates its own outputs against these principles and self-corrects. This produces more consistent behavior than pure human feedback, which can be noisy and contradictory.

    In practice, this means Claude tends to be thoughtful about edge cases, transparent about uncertainty, and willing to push back when a request might lead to harmful outcomes — while still being maximally helpful within safe boundaries.

    The Responsible Scaling Policy

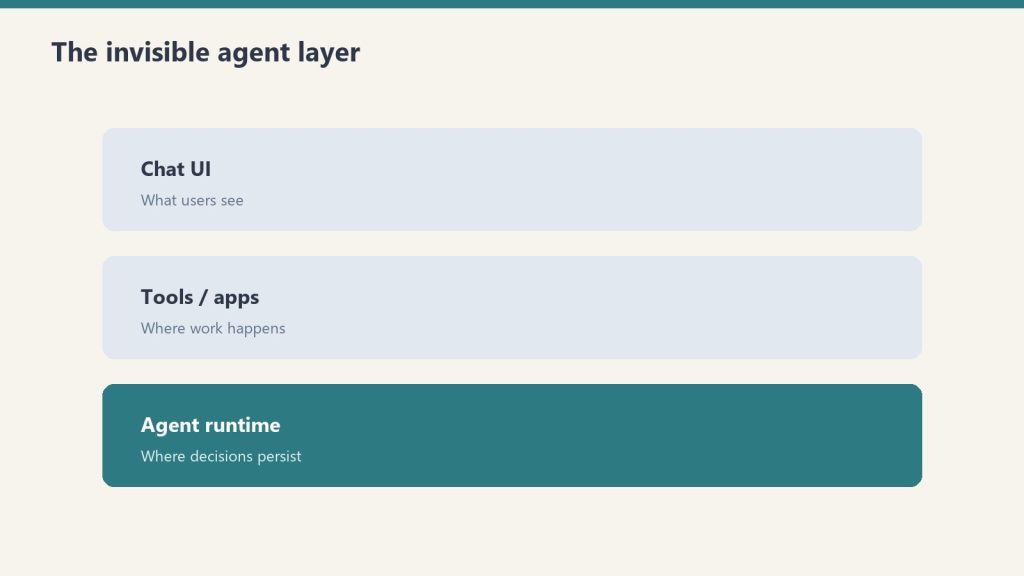
    Three stacked layers: chat UI, tools, agent runtime
    Responsible Scaling Policy.

    Anthropic’s Responsible Scaling Policy (RSP) is a framework that ties safety testing to capability levels. As models become more capable, the RSP requires more rigorous safety evaluations before deployment. The policy defines specific capability thresholds and the safety measures required at each level. This means Anthropic won’t release a model that’s significantly more capable without also implementing significantly more safety infrastructure. The RSP has been publicly documented and updated as the company has learned from deployments.

    Interpretability Research

    Anthropic invests heavily in interpretability — the science of understanding what happens inside neural networks. While most AI companies treat their models as black boxes, Anthropic’s research team publishes work on identifying how models store and process information, what individual neurons and circuits represent, and how to detect when a model might be reasoning in unexpected ways. This research directly informs safety work: if you can see inside the model, you can better identify and prevent harmful behavior.

    Data Handling and Privacy

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Data handling and privacy.

    Anthropic’s data handling practices reflect its safety orientation. On Free and Pro plans, users can opt out of having their data used for model training. On Team and Enterprise plans, content is not used for training by default — this is an opt-out-by-default approach, not opt-in. Enterprise plans add custom data retention controls, so organizations can specify exactly how long their data is stored. The HIPAA-ready Enterprise option provides additional safeguards for healthcare data.

    Corporate Structure as Safety Mechanism

    Anthropic’s public benefit corporation (PBC) structure and Long-Term Benefit Trust (LTBT) are designed as institutional safeguards. The PBC structure legally requires balancing profit with public benefit. The LTBT can intervene if the company’s actions deviate from its safety mission. These aren’t just statements of intent — they’re legal mechanisms with real enforcement power.

    What This Means for Users

    For individual users, Anthropic’s safety approach means Claude is less likely to produce harmful, misleading, or biased content. It’s more transparent about what it doesn’t know. It handles sensitive topics with care rather than either refusing entirely or engaging recklessly. For business users, it means enterprise-grade security features, data handling that meets regulatory requirements, and a vendor whose incentive structure is aligned with long-term reliability rather than short-term growth at any cost.

    Related on Tygart Media: Dario Amodei · is Claude safe · invisible agent layer.

    Frequently Asked Questions

    What is Constitutional AI?

    Constitutional AI is Anthropic’s training methodology where Claude is given a set of principles (a “constitution”) and learns to evaluate and correct its own outputs against those principles, producing more consistent helpful and safe behavior.

    Does Claude use my data for training?

    On Free/Pro plans, you can opt out. On Team and Enterprise plans, your data is not used for training by default.

    Why does Claude sometimes refuse requests?

    Claude’s safety training teaches it to decline requests that could lead to harmful outcomes. It aims to be maximally helpful within safe boundaries. If Claude refuses something you think is reasonable, you can rephrase or provide more context.

    Is Anthropic more safety-focused than OpenAI?

    Anthropic was founded specifically as an AI safety company and has embedded safety into its corporate structure through PBC status and the LTBT. Both companies invest in safety, but Anthropic’s organizational design makes safety central rather than supplementary.

  • Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Actually Compare

    Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Actually Compare

    If you’re evaluating Claude AI, you’re probably also looking at the alternatives. The AI assistant market in 2026 has matured — each major platform has developed distinct strengths rather than trying to be identical. This guide compares Claude against ChatGPT, Gemini, Perplexity, Grok, Microsoft Copilot, and other options on the metrics that actually matter: pricing, capability, reliability, and fit for specific use cases.

    Claude vs ChatGPT

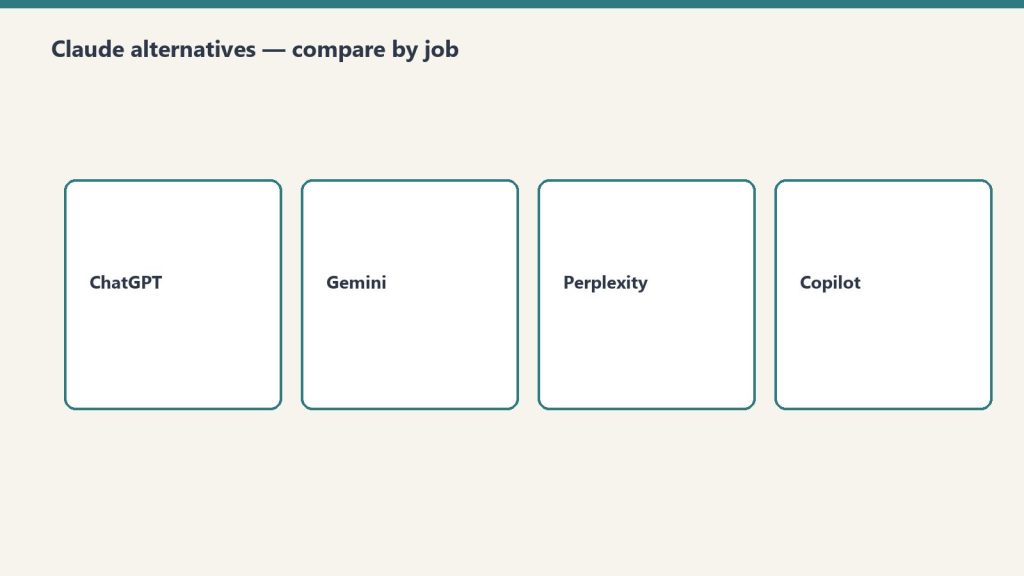
    Four cards comparing ChatGPT, Gemini, Perplexity, and Copilot by job
    Compare alternatives by job — start with Claude vs ChatGPT.

    The most common comparison. Both offer free tiers and $20/month Pro/Plus plans. Claude’s strengths are long-form writing quality, instruction following, code generation with Claude Code, and the 1M token context window. ChatGPT’s strengths are its ecosystem (plugins, GPT store, DALL-E integration), broader brand recognition, and strong general-purpose capabilities. For developers, the choice often comes down to Claude Code vs ChatGPT’s code interpreter and canvas features. For writers, Claude generally produces more nuanced, less formulaic output. API pricing is competitive between the two platforms at comparable model tiers.

    Claude vs Google Gemini

    Four cards for content, ops, build, and knowledge work with Claude
    Claude vs Gemini — different strengths, different seats.

    Gemini’s key advantage is integration with the Google ecosystem — Gmail, Docs, Drive, Search, and Google Workspace. If your organization runs on Google, Gemini fits naturally into existing workflows. Claude’s advantages are stronger reasoning on complex tasks, better code generation, and more robust enterprise features (SCIM, audit logs, HIPAA). Gemini offers a generous free tier and is deeply integrated into Android. Claude is available on Google Cloud through Vertex AI, so organizations can use both within the Google ecosystem.

    Claude vs Perplexity

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Claude vs Perplexity — research seat vs general assistant.

    Perplexity occupies a different niche — it’s primarily a search and research tool, not a general-purpose assistant. Perplexity excels at answering factual questions with cited sources, making it excellent for research and fact-checking. Claude is better for creative work, coding, analysis, and extended projects. Many professionals use both: Perplexity for research and fact-finding, Claude for drafting, analysis, and execution.

    Claude vs Microsoft Copilot

    Microsoft Copilot (powered by OpenAI) is embedded throughout Microsoft 365 — Word, Excel, PowerPoint, Teams, Outlook. If your organization is Microsoft-centric, Copilot has the integration advantage. However, Claude now offers Claude for Microsoft 365 and Outlook, giving it a presence in the Microsoft ecosystem as well. For standalone AI capabilities, Claude generally outperforms Copilot in reasoning, writing quality, and code generation.

    Claude vs Grok

    Grok, built by xAI, is integrated with the X (formerly Twitter) platform and has access to real-time social media data. Grok’s strength is current events and social sentiment analysis. Claude’s strengths are safety, reliability, enterprise features, and broader use case coverage. Grok appeals to users who want an AI with a less restricted personality and real-time social context.

    Pricing Comparison

    Free tiers: Claude, ChatGPT, Gemini, Perplexity, and Copilot all offer free access. Individual paid plans: Claude Pro $20/month, ChatGPT Plus $20/month, Gemini Advanced $19.99/month (often bundled with Google One), Perplexity Pro $20/month. Claude’s Max plan ($100-200/month) has equivalents in ChatGPT Pro ($200/month). At the API level, pricing varies by model class but is broadly competitive across major providers.

    How to Choose

    Choose Claude if you prioritize writing quality, code generation, enterprise security, and long-context processing. Choose ChatGPT if you want the broadest ecosystem of plugins and integrations. Choose Gemini if you’re deep in the Google ecosystem. Choose Perplexity if your primary need is research with cited sources. Choose Copilot if Microsoft 365 integration is your top priority. Many organizations use multiple AI tools — they’re not mutually exclusive.

    Related on Tygart Media: Claude alternatives · Claude vs Perplexity · is Claude worth it.

    Frequently Asked Questions

    Is Claude AI better than ChatGPT?

    Claude excels at long-form writing, instruction following, and code generation. ChatGPT has a larger ecosystem of plugins and integrations. Neither is universally “better” — the right choice depends on your use case.

    What is the best free AI chatbot in 2026?

    Claude, ChatGPT, and Gemini all offer strong free tiers. Claude’s free tier is notable for including web search, code execution, memory, and extended thinking at no cost.

    Can I use Claude and ChatGPT together?

    Yes. Many professionals use multiple AI tools for different tasks. At the API level, platforms like OpenRouter let you route requests to different models based on the task.

    Which AI has the largest context window?

    As of June 2026, both Claude (Opus and Sonnet) and Gemini support 1M+ token context windows. Claude’s 1M context is available at flat-rate pricing with no surcharge.


    >Part of the complete guide: Claude vs the Field

    For the full standalone explainer on one name in this field, see What is Google Gemini — Google’s assistant defined on its own terms, including its data rules and costs.

  • How Smart TV Advertising Predicted AI Content Strategy

    How Smart TV Advertising Predicted AI Content Strategy

    A Lesson Advertisers Learned (That Marketers Forgot)

    In the early 2000s, smart TV advertising was a mess. Media buyers would take a 30-second TV spot — optimized for lean-back, passive viewing — and run it on every screen: broadcast TV, connected TV, desktop pre-roll, mobile interstitials, and later, smart TV apps. Same creative. Different screens. Predictably terrible results.

    It took the advertising industry about a decade to figure out what seems obvious in retrospect: different screens serve different audiences in different contexts, and the creative has to match.

    A smart TV viewer is on the couch, relaxed, 10 feet from the screen. A mobile user is commuting, distracted, holding the phone 12 inches from their face. A desktop user is at work, focused, multitasking. The same 30-second spot that stops a TV viewer cold gets skipped on mobile because the hook takes too long. The same mobile-first vertical video looks absurd on a 55-inch smart TV.

    Once advertisers internalized this, the industry restructured. Creative teams started building platform-specific versions from the ground up. Media strategies segmented by screen. Measurement tracked performance by device, by platform, by context. The unified “TV commercial” became an artifact. In its place: a matrix of screen-specific creative, each optimized for its audience.

    Content strategy for AI is exactly where TV advertising was in 2005. And most people don’t see it yet.

    AI Platforms Are the New Screens

    Two cards: answer shown in overview versus optional click
    AI platforms are the new screens.

    The analogy maps precisely:

    PlatformScreenHow people use itWhat content wins
    Microsoft CopilotSmart TV (built into a device people already own)Embedded in Microsoft 365, the platform people already use for work. Users aren’t seeking it out; it’s there when they need it.Lean-back reference material: structured, specific, ready to surface without the user leaving their workflow.
    ChatGPTLaptop/desktopUsers go there deliberately, open a session, and engage actively: leaning forward, exploring, asking follow-up questions.Detailed, nuanced, conversation-worthy content, the equivalent of long-form desktop video that rewards active attention.
    PerplexityCurated feedSynthesizes the best sources into a clean answer with citations, like a personalized news feed or a curated newsletter.Authoritative, primary content: the source a discerning editor would choose as the definitive reference.
    Google AI OverviewsPre-rollAppear before the organic results, like a pre-roll ad before a YouTube video, capturing attention at the top of the funnel.Content formatted for instant extraction: concise definitions, direct answers, structured lists that can be repurposed into a summary.
    Google organic searchBroadcast TVStill the largest audience, the broadest reach, and the most competitive, but no longer the only screen that matters.SEO structure built to rank for keyword searches.

    My data shows the Copilot fit: 98,800 citations from enterprise users who never left Word or Edge.

    The audiences, by the numbers (as of October 2026)

    Copilot: Microsoft said Microsoft 365 Copilot reached over 30 million paid seats in its fiscal fourth-quarter results (July 29, 2026).

    ChatGPT: OpenAI said at DevDay that ChatGPT now has 1.2 billion weekly users, up from 1 billion in July (The Verge, September 29, 2026).

    Perplexity: CEO Aravind Srinivas said Perplexity received 780 million queries in May 2025, with more than 20% month-over-month growth (TechCrunch, June 5, 2025).

    Google AI Overviews: Alphabet said AI Overviews now have over 2.5 billion users each month (investor presentation, June 3, 2026).

    These are different measures (paid seats, weekly users, monthly queries, monthly users), so they don’t compare head to head. That’s the same reason to measure each platform separately.

    The Creative Matrix for AI Content

    Comparison of Claude how-to fit versus local service page fit for assistants
    The creative matrix for AI content.

    Just as an ad agency now produces a creative matrix — smart TV version, mobile version, desktop version, social version — a content operation needs to produce a content matrix for AI platforms.

    Let me show how this works with a real example. I publish content about Claude AI pricing. Here’s how that single topic gets treated differently for each platform:

    Copilot version: Clean pricing table. Plan names, model names with version numbers, input/output token costs, monthly subscription prices. Minimal narrative. Maximum structure. This is the version that earns 16,500 citations because Copilot users need a number, not a story.

    ChatGPT version: 2,000-word analysis of Claude’s pricing strategy. How the tiers compare to OpenAI’s pricing. What the model costs mean for different use cases. Total cost of ownership calculations. Strategic framing for business decision-makers.

    Perplexity version: The definitive, comprehensive, most-current pricing reference on the internet. Updated within days of any price change. Formatted so Perplexity can cite specific numbers with confidence. The page that makes other sources unnecessary.

    Google version: SEO-optimized comparison page. “Claude AI Pricing 2026” in the title. FAQ schema. Clean headings. First paragraph answers the query directly. Designed to rank for keyword searches.

    In practice, some of these treatments can coexist in a single article. My highest-performing pages layer narrative depth (for ChatGPT and human readers) on top of structured data tables (for Copilot extraction) with FAQ sections (for Google snippets and AEO). But the intentionality matters — you have to design for each screen, not just hope one version works everywhere.

    What the Ad Industry Learned That Content Strategy Hasn’t

    The advertising industry’s transition to screen-specific creative taught several lessons that apply directly to AI content strategy:

    The generalist loses. The brand that ran the same spot everywhere got outperformed by the brand that optimized for each screen. In content, the operation that writes one article and publishes it hoping all AI platforms cite it will be outperformed by the operation that tailors content for each platform’s audience.

    Measurement has to segment by platform. Ad performance makes no sense when aggregated across all screens. A campaign that crushed on mobile but bombed on CTV looks mediocre in aggregate. The same is true for AI content: if you’re measuring “AI visibility” as a single metric, you’re missing the fact that your Copilot performance might be exceptional while your ChatGPT performance is zero.

    The production model has to change. When TV went from one-spot-fits-all to screen-specific creative, production workflows had to adapt. Agencies started shooting with multiple formats in mind. Content operations need the same evolution: write with multiple AI platforms in mind from the start, not as an afterthought.

    The early movers win disproportionately. The brands that figured out smart TV creative early locked in audience relationships and platform partnerships that late movers couldn’t replicate. In AI content, the publishers that build platform-specific citation authority now are building a moat. My Copilot citation flywheel — 672 daily citations growing to 5,500 — is the content equivalent of early smart TV audience lock-in.

    Why Content Operations Are Behind

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Why content operations are behind.

    The advertising industry had a structural advantage: media buyers were already thinking in terms of channels, audiences, and platforms. When new screens emerged, the mental model of “different creative for different channels” was already established. They just had to apply it to a new channel.

    Content marketing has operated under a different mental model: “publish great content and let search engines distribute it.” For twenty years, this meant one distribution channel (Google) with one optimization framework (SEO). The idea that you might need platform-specific content strategies for AI engines is foreign to most content operations because they’ve never had to think about distribution as a multi-platform problem.

    That’s changing. The data is forcing it. When you can see in Bing Webmaster Tools that your enterprise tool content earns 5,500 daily Copilot citations while your local content earns zero, the multi-platform nature of AI distribution becomes undeniable. And once you accept that AI platforms are different audiences, the advertising industry’s decades of screen-specific creative become your playbook.

    Building the Platform-Specific Content Operation

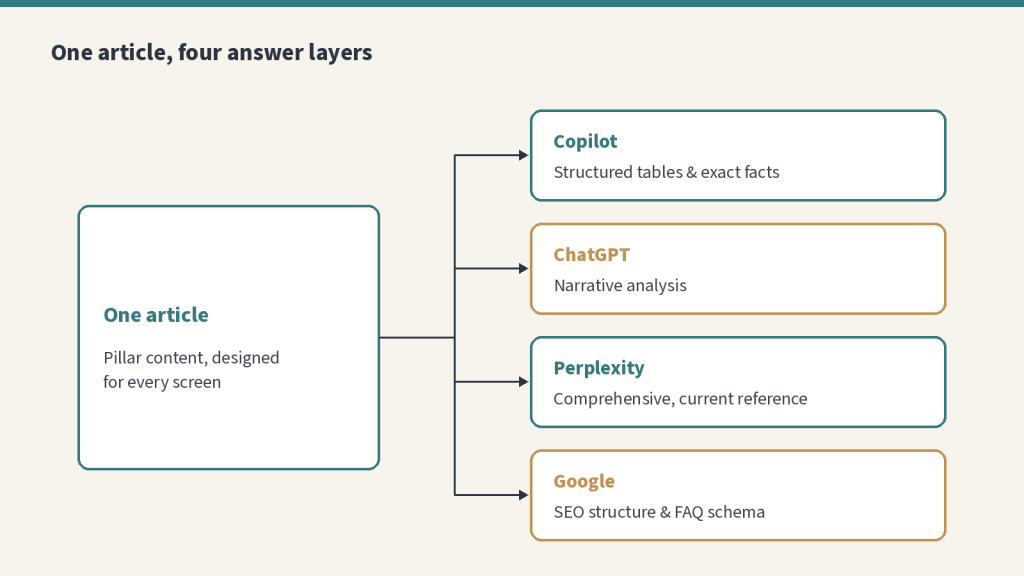
    Diagram: one article branching into four answer layers for Copilot, ChatGPT, Perplexity and Google
    Structure for multiple audiences in one article.

    Here’s what the transition looks like, based on what I’m building right now:

    Audit by platform. Check your Bing AI Performance data. Manually test your key topics in ChatGPT, Perplexity, and Claude. Build a map of which content earns citations where.

    Segment your content calendar. Assign platform targets to each piece of content. “This pricing guide is optimized for Copilot extraction.” “This thought leadership piece is optimized for ChatGPT depth.” “This reference page is optimized for Perplexity authority.”

    Structure for multiple audiences in one article. Your best content should layer: structured data for Copilot, narrative depth for ChatGPT, definitive authority for Perplexity, and keyword optimization for Google. Not every piece needs all four, but your pillar content should.

    Measure separately. Track Copilot citations in Bing Webmaster Tools. Track ChatGPT referral traffic in analytics. Test Perplexity visibility manually. Don’t aggregate these into one “AI performance” number — they’re different audiences and need different metrics.

    The ad industry spent a decade learning that one creative doesn’t fit all screens. The content industry can learn the same lesson faster — because the data is available today, and the playbook has already been written by someone else.

    For Agency Media Buyers: What Happens After the Spot Airs

    If you buy TV for a living, here’s the part of the funnel that changed under your feet. A viewer sees your client’s spot, picks up a phone or opens a laptop, and asks a question. Increasingly that question goes to ChatGPT, Copilot, Perplexity, or a Google AI Overview instead of a plain search box. “Is this brand any good?” “What’s the best option in this category?” “Who else does this?”

    The assistant answers in a sentence or two, and it names whoever it can actually read and trust. Sometimes that’s your client. Sometimes it’s a competitor that never bought a single spot. Your reach and frequency can be perfect, and the demand the campaign created can still leak to whoever the AI cites at the moment of follow-up.

    It’s the same screen-specific lesson from earlier in this piece, one step later in the funnel. The TV creative does its job. Then the answer layer decides who gets the credit. Three things matter there:

    Whether the brand gets cited. Run the questions a viewer would ask after the spot and see which names come back, platform by platform.

    Whether answer-ready content exists. Pages that answer the brand and category questions directly — clear definitions, specific facts, FAQ structure — are what assistants extract and cite.

    Whether it’s measured separately. Citation visibility is its own metric, tracked per platform, not a line folded into search or brand lift. Here’s how I think about what a citation is worth.

    That’s where Tygart Media fits. We don’t buy your airtime, and we don’t make the spot. We make sure that when the spot sends people to an AI assistant, your client is the answer it gives. That starts with a citation scan — where AI cites the brand today, where it doesn’t, and who it cites instead — and moves into rebuilding the pages AI pulls its answers from, using the same methodology behind this site’s own citation numbers.

    Running a TV campaign and want to know what AI says when viewers go looking? Tell us about it, and we’ll tell you honestly whether we can help.

    Related on Tygart Media: different AI audiences · SEO vs GEO vs AEO · citation economy.

    Sources:

    • Microsoft, “Microsoft Cloud and AI strength fuels fourth quarter results,” July 29, 2026. news.microsoft.com
    • The Verge, “ChatGPT now has 1.2 billion weekly users, OpenAI says,” September 29, 2026. theverge.com
    • TechCrunch, “Perplexity received 780 million queries last month, CEO says,” June 5, 2025. techcrunch.com
    • Google (The Keyword), “Alphabet investor presentation: June 2026,” June 3, 2026. blog.google

    Frequently Asked Questions

    How is AI content like advertising?

    Just as advertisers create different creative for smart TV, mobile, desktop, and social media, content operations need platform-specific approaches for Copilot, ChatGPT, Perplexity, and Google. Each platform serves a different audience in a different context with different needs.

    Can one article serve all AI platforms?

    Yes, with intentional layering. A single article can include structured data tables for Copilot extraction, narrative depth for ChatGPT engagement, authoritative sourcing for Perplexity citation, and keyword optimization for Google rankings. The key is designing for all audiences from the start.

    What does platform-specific content measurement look like?

    Track Copilot citations in Bing Webmaster Tools AI Performance tab. Monitor ChatGPT referral traffic in Google Analytics. Test Perplexity visibility by manually searching your topics. Measure each platform separately rather than aggregating into one AI performance number.

    Which AI platform should I prioritize?

    It depends on your audience. Enterprise and technology content should prioritize Copilot because its user base is knowledge workers mid-task. Consumer and research content may perform better on ChatGPT. Use the topic-platform fit matrix to determine where your content has the highest citation potential.

    How did smart TV advertising change production workflows?

    Agencies shifted from one-spot-fits-all to shooting with multiple formats in mind from the start. Content operations need the same evolution: plan content with multiple AI platform audiences in mind during the writing process, not as a post-publish optimization.

  • Your Website Is Being Read by AI More Than Humans — Here’s the Data

    Your Website Is Being Read by AI More Than Humans — Here’s the Data

    The Invisible Majority of Your Readership

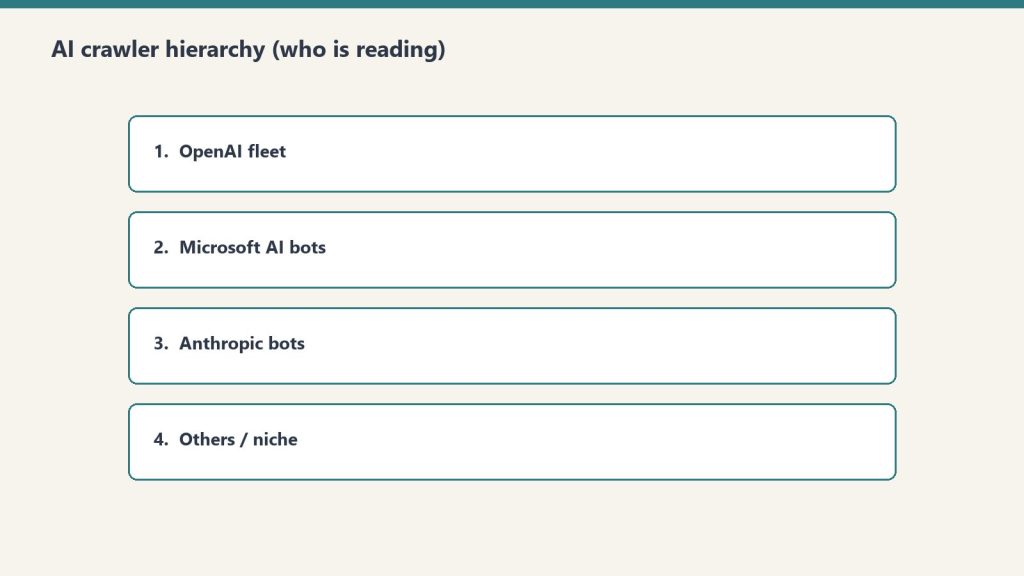
    Four ranked rows of AI crawler fleets reading publisher content
    The invisible majority of your readership — AI crawlers.

    For every human who clicks on one of my articles from Bing search results, Microsoft Copilot cites that same content 52 times. Not reads. Not impressions. Citations — instances where an AI engine uses my content as the grounding source for a response delivered to a real user.

    The numbers: 98,800 AI citations from Copilot. Roughly 1,900 human clicks from Bing. Same time period. Same domain. Same content.

    And here’s what makes this disorienting: I can see the AI citations in Bing Webmaster Tools. But my Google Analytics, my heatmaps, my session recordings, my conversion tracking — none of it registers the 98,800 AI interactions. As far as my analytics stack is concerned, those readers don’t exist.

    The largest audience consuming my content is invisible to every measurement tool I’ve used for the past decade.

    How We Got Here Without Noticing

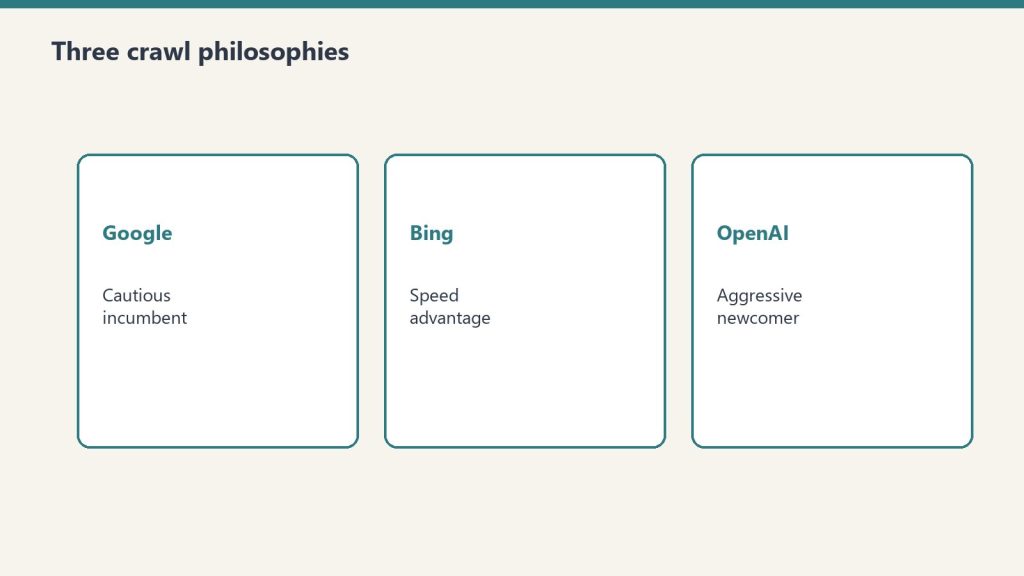
    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    How we got here without noticing.

    The shift happened gradually, then all at once. Microsoft shipped Copilot in Microsoft 365 to hundreds of millions of enterprise seats. Google rolled out AI Overviews to every search user. ChatGPT launched its search feature. Perplexity grew to millions of daily users. Claude’s user base expanded.

    Each of these platforms consumes web content to generate responses. They crawl, index, and cite websites — not to send traffic, but to build the source material for AI-generated answers. Your content becomes the foundation of an AI response that gets delivered to a user who may never know your site exists and will certainly never show up in your analytics.

    The scale is enormous. Microsoft alone has over 400 million Copilot users across its products. If even a fraction of their queries trigger content citations, the total volume of AI-mediated content consumption dwarfs traditional search clicks for many content categories.

    My 52:1 ratio might be extreme because my content is heavily skewed toward AI tools — a topic that Copilot users ask about frequently. But even for more general content categories, the AI consumption layer is growing faster than any other traffic channel. And most content operations are completely blind to it.

    The Measurement Crisis

    Here’s what your current analytics stack tells you about AI consumption of your content: almost nothing.

    Google Analytics tracks human visits. An AI engine that cites your content doesn’t load your page in a browser, doesn’t execute JavaScript, doesn’t trigger a session. It reads your content through APIs or cached indexes and incorporates it into a response. No pageview. No session. No data.

    Google Search Console tracks clicks and impressions from Google search. It doesn’t track AI Overview citations — when Google’s own AI uses your content to build an AI-generated summary, that interaction doesn’t appear as a click or an impression in Search Console.

    The only tool currently offering AI citation data is Bing Webmaster Tools, through its AI Performance beta tab. This shows Copilot-specific citations — the number of times Copilot used your content as a grounding source. But it only covers Microsoft’s AI. Google, ChatGPT, Perplexity, and Claude citation data remains largely invisible.

    This creates a measurement crisis. Content operations make decisions based on analytics data. If the majority of your content’s audience is invisible to your analytics, you’re making decisions based on the minority of your readership. You’re optimizing for the 1,900 clicks while ignoring the 98,800 citations.

    What “Being Read by AI” Actually Means

    When I say AI is reading your content, I want to be precise about what’s happening technically.

    Grounding: When a user asks Copilot a question, Copilot searches for relevant web content, retrieves it, and uses it to “ground” its response in factual sources. Your page becomes the cited source for specific claims in the AI’s answer. The user sees your content’s information, often with a link back to your page — but they may never click that link because the AI already gave them what they needed.

    Scale: One article on my site answering “claude ai pricing” was grounded 16,500 times. That means 16,500 Copilot users received information sourced from my page. In a traditional web model, that would be 16,500 pageviews. In the AI model, it’s 16,500 invisible reads.

    Reach: Each citation represents content delivery to a user who is actively working, actively needing that information, and actively incorporating it into a task. This isn’t a bounce-rate impression — it’s a high-intent content consumption event. The quality of these “reads” may be higher than most human pageviews, even though they’re invisible.

    The Writing Implications

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The writing implications of AI-majority readership.

    If AI is your primary reader, you need to write differently. Not worse. Not shorter. Differently.

    Write for extraction, not engagement. AI engines don’t scroll, don’t skim, and don’t get bored. They extract specific information from your content. A pricing table that’s easy for AI to parse serves the citation audience better than a narrative pricing discussion that’s more “engaging” for human readers. Both can coexist, but the extraction-friendly content needs to be there.

    Accuracy is non-negotiable. AI engines are grounding their responses on your content. If your pricing page is wrong, Copilot gives 16,500 users the wrong answer — with your name attached as the source. In a traditional web model, a wrong number on a page hurts your credibility with the humans who visit. In the AI model, it hurts your credibility with the AI engine itself, which may stop citing you if users flag the information as incorrect.

    Structure beats storytelling for citation content. This doesn’t mean storytelling is dead — it means you need both. The narrative draws human readers. The structured data draws AI citations. A good article about Claude pricing has both: a narrative explanation of the pricing structure and a clean, parseable table of actual numbers.

    Currency matters more than ever. AI engines can detect stale content. A pricing article from January 2025 won’t earn citations in June 2026 because the prices have changed. The content that maintains citation velocity is content that’s demonstrably current — date-stamped, version-specific, and regularly updated.

    The Monetization Question

    The obvious question: if AI is reading your content 52 times more than humans, but those AI reads don’t generate pageviews, how do you monetize them?

    Right now, the honest answer is: the direct monetization model is still emerging. Ad revenue depends on pageviews. Affiliate revenue depends on clicks. Lead generation depends on form fills. None of these happen when AI reads your content.

    But here’s what does happen:

    Brand authority compounds. When Copilot cites your pricing guide 16,500 times, you become the de facto source for that topic. Enterprise workers learn your name through AI responses. When they eventually need to visit your site — for a demo, for a purchase, for a deeper evaluation — they already know you.

    Citation begets citation. My data shows a flywheel effect: the more Copilot cites a source, the more it trusts that source for adjacent queries. 672 daily citations grew to 5,500 daily citations over 90 days. Authority compounds in AI engines just as it does in traditional search.

    The traffic still comes — indirectly. AI citations include source links. Some users do click through. And as your citation authority grows, your traditional search visibility often grows with it, because AI citation authority and search authority draw from overlapping signals.

    The long-term monetization model for AI citations probably looks more like brand advertising than direct response. You’re building awareness and authority at massive scale. The conversion happens downstream, through channels that your analytics can track.

    What to Do About It Today

    Check your Bing Webmaster Tools AI Performance tab. If you haven’t verified your site with Bing, do that first. The citation data might change how you think about your entire content operation.

    Look at your analytics with fresh eyes. That high-quality article with “disappointing” traffic might be generating thousands of AI citations you can’t see. The low-traffic technical guide might be one of your most-consumed pieces of content through AI channels.

    Start tracking the AI-to-human ratio for your content categories. Which topics are being consumed primarily by AI? Which are still human-traffic driven? This tells you where to invest in structured, extraction-friendly content (for AI) and where to invest in engagement-optimized content (for humans).

    Your biggest audience might be the one you can’t see yet. But the data to find it is already there — if you know where to look.

    Related on Tygart Media: AI crawler experiment · citation economy.

    Frequently Asked Questions

    Does Google Analytics track AI citations?

    No. Google Analytics tracks human browser visits. AI engines consume content through APIs and indexes without loading pages in browsers, so they don’t trigger JavaScript analytics. The only current tool showing AI citation data is Bing Webmaster Tools AI Performance beta tab.

    What is the AI-to-human read ratio?

    For one domain focused on AI tools, the ratio was 52:1 — 98,800 Copilot citations vs 1,900 Bing clicks in the same period. This ratio varies dramatically by topic. Enterprise technology content tends to have very high AI-to-human ratios. Local consumer content tends to have very low ratios.

    Should I stop writing for humans and focus on AI?

    No. Humans still drive direct revenue through clicks, conversions, and engagement. The strategy is to write content that serves both — narrative elements for human readers and structured, extractable data for AI engines. Both audiences can be served by the same article with intentional formatting.

    How do I make my content more citable by AI?

    Structure information for extraction: clean tables, specific numbers, version-stamped details, clear definitions. Ensure accuracy — AI engines may reduce citations for sources that users flag as incorrect. Keep content current with date stamps and regular updates.

    Will Google eventually show AI citation data?

    Google has not announced plans to expose AI Overview citation data in Search Console. However, as the AI citation economy grows and marketers demand transparency, competitive pressure from Bing’s AI Performance tab may push Google to provide similar analytics.

  • Why Claude Articles Get 16,500 Copilot Citations But Roofing Articles Get Zero

    Why Claude Articles Get 16,500 Copilot Citations But Roofing Articles Get Zero

    The Most Lopsided Split I’ve Ever Seen

    Comparison of Claude how-to fit versus local service page fit for assistants
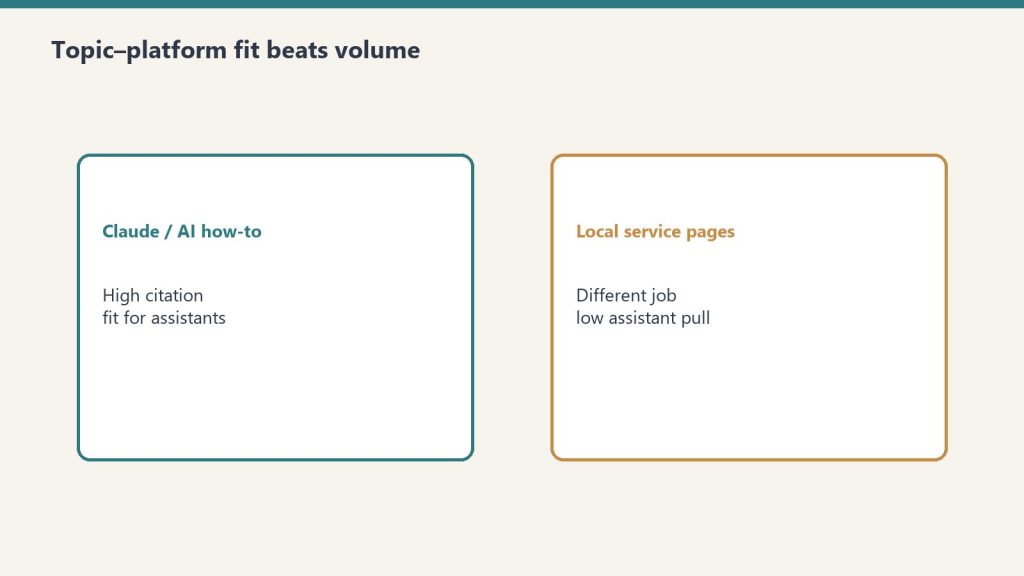
    The most lopsided split: topic–platform fit beats volume.

    I run two kinds of content on the same portfolio of sites. One kind covers AI tools — Claude pricing, developer workflows, Copilot integrations, tool comparisons. The other covers trade services — restoration contractors, roofing, water damage, local business directories.

    Both content streams are well-written. Both are SEO-optimized. Both rank on Google. But when I opened Bing Webmaster Tools and looked at the AI Performance tab, the split was so stark it looked like a data error.

    AI tool content: 98,800 citations across 576 grounding queries. The single highest query — “claude ai pricing” — generated 16,500 citations by itself.

    Trade service content: Zero.

    Not ten. Not “a few that I might have missed.” Zero citations. Across every restoration article, every roofing guide, every local service page. Microsoft Copilot did not cite a single one of them.

    This isn’t a quality problem. It’s a topic-platform fit problem. And understanding it changes how you think about content strategy for AI.

    Who Actually Uses Copilot

    To understand why Claude articles dominate and roofing articles get nothing, you need to understand who is on the other end of those Copilot queries.

    Microsoft Copilot is embedded in Microsoft 365 — Word, Excel, PowerPoint, Outlook, Teams, Edge. The users are enterprise workers, knowledge professionals, and business users who invoke AI as part of their daily workflow. They’re writing reports, building presentations, comparing tools, planning purchases, and making decisions.

    When a Copilot user asks a question, it’s because they need information to complete a task they’re currently doing. They’re in Word writing an AI strategy memo and they need current pricing. They’re in Excel building a vendor comparison and they need feature lists. They’re in Edge researching a developer tool and they need a hands-on review.

    These people don’t ask Copilot about roofing contractors. They don’t ask about water damage restoration in Houston. They don’t ask about emergency plumbing services. Because they’re not doing those things at their desk in Microsoft 365.

    The queries that trigger Copilot citations are professional knowledge queries — the questions knowledge workers ask while working:

    “What is claude ai pricing in 2026”
    “Claude code vs cursor comparison”
    “How to set up notion MCP with claude”
    “Anthropic console api key guide”
    “Best AI coding tools for teams”

    Every one of these is a work-context question from someone making a professional decision. And every one of them led Copilot to my content because my content is the most structured, specific, accurate answer available.

    The Topic-Platform Fit Matrix

    Four cards for content, ops, build, and knowledge work with Claude
    Topic–platform fit matrix — write for the assistant that will cite you.

    Based on my citation data and observation across platforms, here’s what I see as the topic-platform fit landscape:

    Microsoft Copilot favors: Technology tool comparisons and pricing. Enterprise software reviews. Developer workflow guides. Business strategy content. AI platform analysis. Integration and configuration documentation. Anything a knowledge worker might need while working in Office.

    Microsoft Copilot ignores: Local services. Trade industries. Consumer products. Event listings. Community content. Anything where the intent is “find a provider near me” rather than “help me understand this tool.”

    ChatGPT favors: Broad technology topics. Health and science information. Financial concepts. Educational content. How-things-work explanations. Creative and cultural topics. Travel planning.

    Google favors: Everything — but especially local intent, shopping intent, transactional queries, and broad informational queries. Google is the generalist.

    Perplexity favors: Current events and news. Technical deep-dives. Product research. Anything where users want a synthesized, multi-source answer to a specific question.

    The pattern is clear: each platform’s topic preferences reflect its user base and use context. Copilot’s users are in the office, so Copilot cites office-relevant content. ChatGPT’s users are everywhere, so ChatGPT cites broadly. Google’s users are searching with intent, so Google rewards intent-matched content.

    Why 16,500 Citations for One Query

    The “claude ai pricing” query generating 16,500 Copilot citations deserves its own analysis because it illustrates topic-platform fit perfectly.

    Think about who asks this question inside Copilot: someone at a company evaluating Claude as a tool for their team. They’re probably in the middle of writing a procurement justification, a budget proposal, or a vendor comparison. They need the current pricing — plans, model costs, API rates — and they need it accurate and structured so they can drop it into their document.

    My Claude AI pricing article has exactly what this person needs: clean pricing tables organized by plan tier, specific model costs with input/output token rates, version-accurate model names, and comparison notes that help with vendor evaluation. The content is formatted for extraction — Copilot can pull a specific number, a specific tier name, a specific comparison point and present it to the user inline.

    That’s why one article earns 16,500 citations while an entire portfolio of roofing content earns zero. The roofing content is excellent for its audience (homeowners with water damage searching Google). But that audience doesn’t exist inside Copilot.

    The Strategic Implications

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Strategic implications — authority clusters compound.

    If you’re a content strategist looking at this data, the implications are significant:

    Not all content is eligible for AI citations. If your business is local services, consumer retail, or any industry where the customer journey starts with a Google search and ends with a phone call, AI citation optimization might not be your priority. Your content serves Google searchers, and that’s fine — that audience is still massive and monetizable.

    If your content serves knowledge workers, you’re sitting on a citation goldmine. SaaS companies, developer tools, B2B services, consulting firms, enterprise technology — any business whose content answers questions that professionals ask while working is perfectly positioned for Copilot citations. And most of them don’t know it yet because they’ve never checked the AI Performance tab.

    Topic-platform fit should drive your content calendar. Instead of asking “what keywords should we target,” start asking “which AI platforms could cite our content, and what does their user base need?” This changes which articles you prioritize, how you structure them, and what success looks like.

    The zero-citation categories will change. As AI platforms expand beyond enterprise knowledge work — as Copilot appears in more consumer contexts, as ChatGPT’s search feature grows, as Google AI Overviews cover more queries — the topic-platform fit map will shift. Local services might start earning AI citations when AI assistants handle “find me a plumber” queries. But right now, the data is unambiguous: Copilot citations concentrate in professional knowledge topics.

    How I Use This Data

    On my own sites, topic-platform fit analysis drives resource allocation. I don’t try to make my restoration content earn Copilot citations — that’s fighting the user base. Instead, I optimize restoration content for Google (where that audience lives) and invest my Copilot-facing content effort in AI tools, business strategy, and technology topics (where the citation audience lives).

    This isn’t about abandoning one audience for another. It’s about matching content to the platform where it will actually be consumed. The same way a B2B SaaS company advertises on LinkedIn instead of TikTok, you should produce AI tool content for Copilot and local service content for Google.

    The data is telling you where your audiences are. The question is whether you’re listening.

    Related on Tygart Media: $0.35 article citations · 98,800 citations · restoration AI search.

    Frequently Asked Questions

    Can local business content earn AI citations?

    Currently, local service content earns very few AI citations because Copilot users are enterprise workers asking professional questions. However, as AI assistants expand into consumer use cases — handling queries like “find me a plumber” or “best restaurants near me” — local content may start earning citations. For now, focus local content on Google SEO and monitor AI citation data for shifts.

    What is topic-platform fit?

    Topic-platform fit describes how well a content topic matches the user base and use context of a specific AI platform. Topics that align with what a platform’s users actually ask about earn citations. Topics that don’t match the user base earn zero citations regardless of content quality.

    Why does Copilot favor technology content so heavily?

    Copilot is embedded in Microsoft 365, so its users are enterprise workers in Office applications. They ask questions related to their work: tool comparisons, pricing, integrations, and business decisions. Technology and business content matches their context. Consumer and local content does not.

    Should SaaS companies prioritize Copilot citations?

    Yes. If your product serves enterprise knowledge workers, your documentation, pricing pages, and comparison content is exactly what Copilot users ask about. Checking your Bing Webmaster Tools AI Performance tab may reveal citation data you did not know existed — and optimizing for it could dramatically expand your content’s reach.

    How do I find my topic-platform fit?

    Start by checking Bing Webmaster Tools AI Performance for your existing Copilot citation data. Then manually test your key topics in ChatGPT, Perplexity, and Claude to see if your content appears in their responses. Map which topics earn citations on which platforms to build your topic-platform fit matrix.

  • How to Use Claude AI: A Beginner’s Guide to Prompting, Features, and Getting Better Results

    How to Use Claude AI: A Beginner’s Guide to Prompting, Features, and Getting Better Results

    Claude AI is powerful, but getting the most out of it requires more than typing a question and hoping for the best. This guide covers the fundamentals — from signing up to writing prompts that produce genuinely useful output — so you can start getting value from Claude immediately, whether you’re using the free tier or a paid plan.

    Getting Started

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Getting started with Claude.

    Go to claude.ai and sign up with your email or Google account. No credit card required for the free tier. Once you’re in, you’ll see a chat interface where you can start a conversation immediately. Claude is available on web, iOS, Android, and a desktop app for macOS and Windows. Your conversations sync across all platforms.

    The Basics of Good Prompting

    Four cards for content, ops, build, and knowledge work with Claude
    The basics of good prompting.

    Be specific about what you want. Instead of “write me something about marketing,” try “write a 500-word blog post about email marketing best practices for small e-commerce businesses, focusing on subject line optimization and send timing.” The more specific your request, the more useful the output.

    Provide context. Claude doesn’t know your situation unless you tell it. Share relevant background: your role, your audience, your constraints, your goals. “I’m a freelance graphic designer preparing a proposal for a client who sells organic skincare” gives Claude much more to work with than “help me write a proposal.”

    Specify the format. Tell Claude how you want the output structured: bullet points, numbered steps, a table, a narrative paragraph, a code snippet. If you want a specific length, say so. If you want a specific tone (formal, casual, technical), specify that too.

    Iterate. Your first prompt rarely produces the perfect result. Treat Claude like a collaborative colleague — give feedback, ask for revisions, and refine. “Make the tone more conversational” or “expand the section about pricing” or “now format this as an email instead of a document.”

    Key Features to Know About

    Projects: Organize related conversations and documents together. Create a Project for each client, each project, or each area of your work. Projects maintain context across conversations, so Claude remembers the background you’ve established.

    Web search: Claude can search the internet in real-time to find current information. When you need up-to-date data, Claude will search, cite sources, and incorporate findings into its response.

    Memory: Claude remembers things you tell it across conversations. If you share your preferences, your role, or your communication style, Claude applies that context in future conversations automatically.

    Code execution: Claude can write and run code in a sandbox. Ask it to analyze data, create charts, process files, or test code snippets. The results are displayed directly in the conversation.

    Extended thinking: For complex problems, Claude can engage in step-by-step reasoning before responding. This produces better results on math problems, logic puzzles, strategic planning, and multi-variable analysis.

    File uploads: You can upload documents, images, spreadsheets, and other files for Claude to analyze. Upload a PDF contract for review, a CSV dataset for analysis, or an image for description.

    Common Use Cases for Beginners

    Writing assistance: Draft emails, blog posts, reports, proposals, social media content. Claude excels at adapting to different tones and formats. Research: Ask Claude to explain complex topics, summarize long documents, or investigate questions across multiple angles. Data analysis: Upload spreadsheets and ask Claude to find patterns, create visualizations, or generate summaries. Learning: Use Claude as a tutor — ask it to explain concepts, quiz you, or create study guides. Coding: Even non-developers can use Claude to write scripts, automate tasks, or build simple tools.

    Mistakes to Avoid

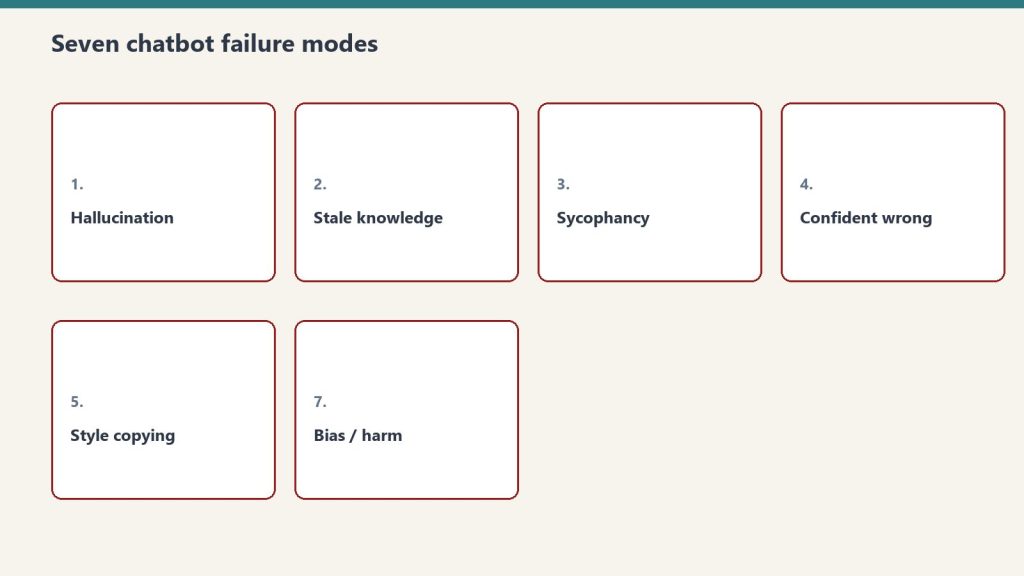
    Seven cards naming common AI chatbot failure modes
    Mistakes to avoid as a beginner.

    Don’t assume Claude’s output is always correct — verify important facts, especially numbers, dates, and claims about specific companies or people. Don’t share sensitive personal information unnecessarily. Don’t treat Claude’s first response as final — iterate and refine. Don’t write vague prompts and expect specific results. Don’t ignore Claude’s caveats and limitations when it flags uncertainty.

    Related on Tygart Media: how to use Claude · Claude for business · is Claude free.

    Frequently Asked Questions

    How do I start using Claude AI?

    Go to claude.ai, sign up for free, and start chatting. No credit card or technical setup required. Download the desktop app from claude.com/download for additional features.

    What should I ask Claude AI?

    Anything you’d ask a knowledgeable assistant: writing help, research, analysis, coding, brainstorming, summarization, explanation of complex topics, or task planning. Be specific about what you need.

    How do I write a good prompt for Claude?

    Be specific about your request, provide relevant context, specify the format and length you want, and iterate on the results. The more detail you give, the better the output.

    Is Claude AI better than ChatGPT for beginners?

    Both are capable tools with similar pricing ($0 free, $20/month paid). Claude is often praised for longer, more nuanced responses and better instruction-following. The best approach is to try both and see which fits your workflow.

  • Claude AI for Business: Real ROI & Workflows (2026)

    Claude AI for Business: Real ROI & Workflows (2026)

    Claude AI has moved from experimental tool to operational infrastructure for businesses of all sizes. But the question most decision-makers ask isn’t “what can it do?” — it’s “what’s the return?” This guide covers the concrete use cases where businesses are deploying Claude in 2026, a framework for calculating ROI, and real data from published case studies.

    Engineering and Development

    Four cards for content, ops, build, and knowledge work with Claude
    Engineering and development use cases.

    Claude Code has become the primary productivity lever for engineering teams. Published case studies show 20-40% improvements in code velocity when teams adopt Claude Code systematically. The tool handles code review, test generation, debugging, documentation, and multi-file refactoring. Companies like Rakuten, TELUS, and Harvard have publicly shared their Claude Code adoption data. The key insight from rollout data: teams that establish clear workflows (plan mode, hooks, managed settings) see sustained adoption, while ad hoc usage tends to fade after the initial novelty.

    Content and Marketing

    Three cards for LSA, search ads, and SEO/AI authority channels
    Content and marketing workflows.

    Marketing teams use Claude for content production at scale — blog posts, product descriptions, email campaigns, social media content, and SEO optimization. The ROI here is straightforward: if a content writer produces 3 articles per day without Claude and 8 with Claude, the per-article cost drops significantly. Claude for Microsoft 365 integration means teams can use Claude directly within Word and Outlook without switching contexts.

    Sales and Customer Support

    Sales teams use Claude for prospect research, call preparation, proposal drafting, and competitive analysis. Customer support teams deploy Claude through the API to handle first-line inquiries, draft responses for human review, and summarize long ticket histories. The combination of Claude’s natural language understanding and tool use (via MCP) means it can pull CRM data, check order status, and draft personalized responses in a single flow.

    Legal and Compliance

    Legal teams use Claude for contract review, regulatory research, and compliance documentation. Claude’s 1M token context window allows it to process entire contracts or regulatory documents in a single request. Enterprise features like audit logs, HIPAA readiness, and custom data retention make it viable for regulated industries. Law firms and legal departments report significant time savings on document review and research tasks.

    Operations and Internal Productivity

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Operations and internal productivity.

    Beyond specialized functions, Claude serves as a general productivity multiplier. Teams use it for meeting preparation, report drafting, data analysis, process documentation, and internal communication. Cowork mode in the desktop app can automate cross-application workflows — moving data between tools, generating reports from multiple sources, and handling repetitive administrative tasks.

    ROI Calculation Framework

    Calculate Claude’s ROI for your organization with this framework. Time savings: estimate hours saved per employee per week. Multiply by the employee’s fully-loaded hourly cost. Quality improvements: reduced error rates in code, content, or customer communications. Speed to market: faster project completion times. Tool consolidation: Claude may replace or reduce spending on multiple SaaS tools (writing assistants, code review tools, research platforms). Total cost: subscription cost ($20-200/seat/month) plus any API usage. The break-even point for most teams is 2-3 hours of productivity gained per seat per month.

    Choosing the Right Plan for Business

    Small teams (5-20 people): Team Standard at $20/seat/month (annual). Growing companies (20-150): Team with a mix of Standard and Premium seats. Large organizations (150+): Enterprise with seat-plus-usage pricing. The decision matrix comes down to three factors: team size, security/compliance requirements, and power-user density.

    Related on Tygart Media: Claude for content · how to use Claude · is Claude worth it.

    Frequently Asked Questions

    How much does Claude cost for a business?

    Team plans start at $20/seat/month (annual billing) for Standard seats. Enterprise starts at $20/seat plus usage. A 20-person team on Team Standard costs $400/month or $4,800/year.

    What is the ROI of Claude AI for businesses?

    Most teams break even with 2-3 hours of productivity gain per seat per month. Published engineering case studies show 20-40% code velocity improvements. Content teams report 2-3x output increases.

    Is Claude AI secure enough for enterprise use?

    Yes. Enterprise includes SSO, SCIM, audit logs, compliance API, HIPAA readiness, custom data retention, and IP allowlisting. Content is not used for model training.

    Can Claude replace our existing AI tools?

    Claude can consolidate multiple point solutions — writing assistants, code review tools, research platforms, and customer support drafting tools — into a single platform, potentially reducing overall tool costs.