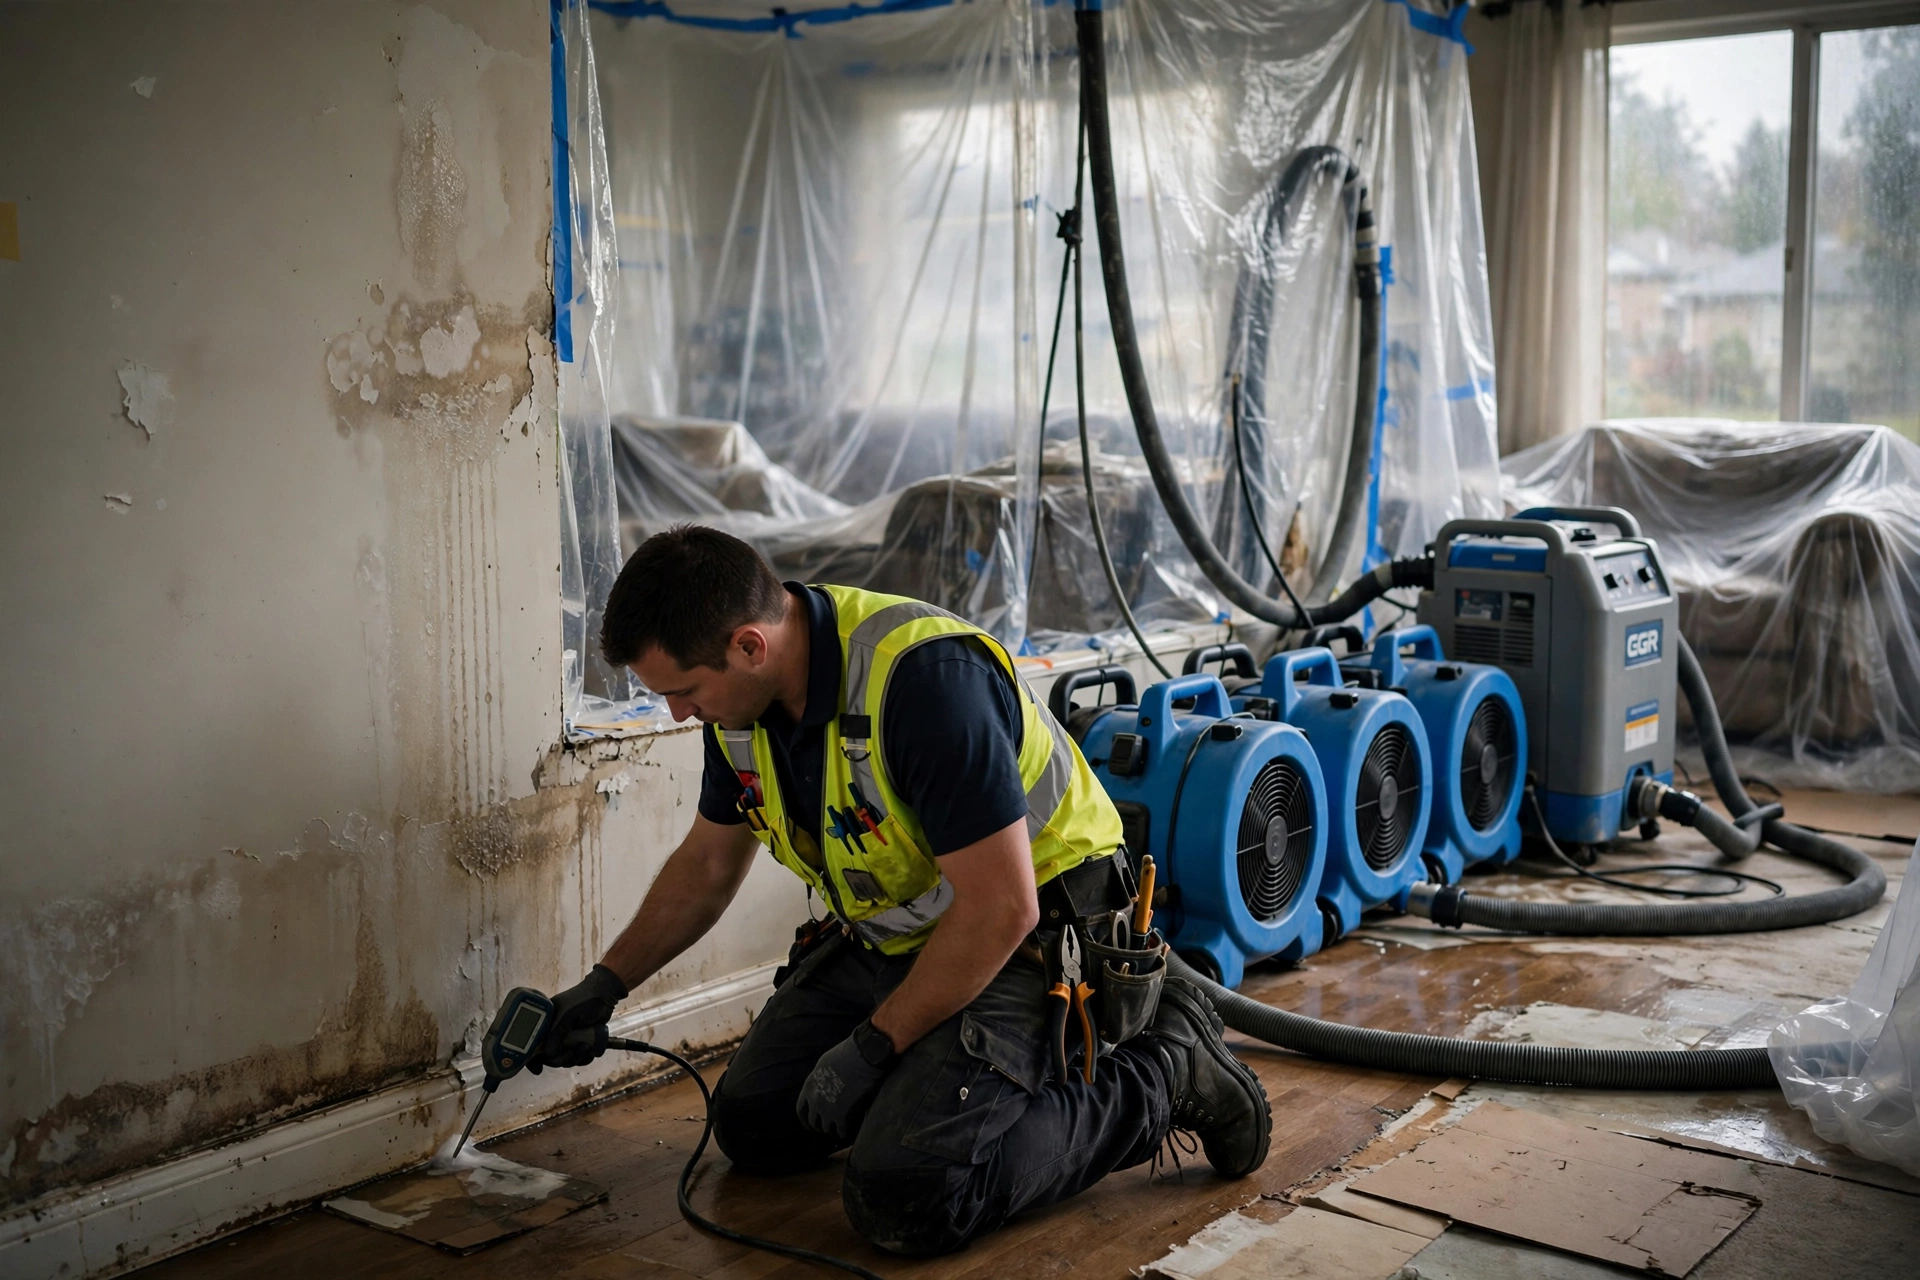
It started in a Facebook group in Anderson, Indiana: homeowners trading notes on 25–50% deposits, contractors answering that $12–15K in rental gear has to sit on site before the drying starts. The same fight is happening in public, all over the internet, and it’s worth reading in the combatants’ own words.
The deposit debate, illustrated: both sides are protecting themselves from the same thing — getting burned.
Camp one: the contractors
Entrepreneur Nick Ayala’s reel (13K likes, 250 comments) takes on the client who says “I’ll pay you when it’s done.” His argument: starting work without a deposit “makes the freelancer the client’s bank — fronting labor, materials, calendar time, and 100% of the risk for free.”
“Makes the freelancer the client’s bank — fronting labor, materials, calendar time, and 100% of the risk for free.” — Nick Ayala, Instagram
A contractor posting as ProWall Paints & Plaster admits he “used to think asking for 50% upfront was ‘crazy,’ but now understands it is necessary” — the deposit covers materials, labor, scheduling, and mobilization. And John at Bluestone Construction puts it the way only a contractor can: “You pay 100% for any item at Canadian Tire… Yet in home renos where he locks the door and has complete control, he thinks he doesn’t have to pay!!”
Camp two: the homeowners
The rebuttal is just as vivid. One homeowner’s Instagram rant is captioned “A fool, and his money will soon be parted” — he will not pay half before work starts, period. A Facebook post that drew 500 comments is just a screenshot of a text exchange titled “No Deposit = No Work”: the contractor demands 50% by Zelle, the customer replies “Oh no I don’t pay no until the work is completed” and “That is unsafe.”
And the fear isn’t abstract — a Moreno Valley community post with 810 comments documents a painter who took 50% cash upfront, missed days, asked for rent money, and quit.
The law has opinions too
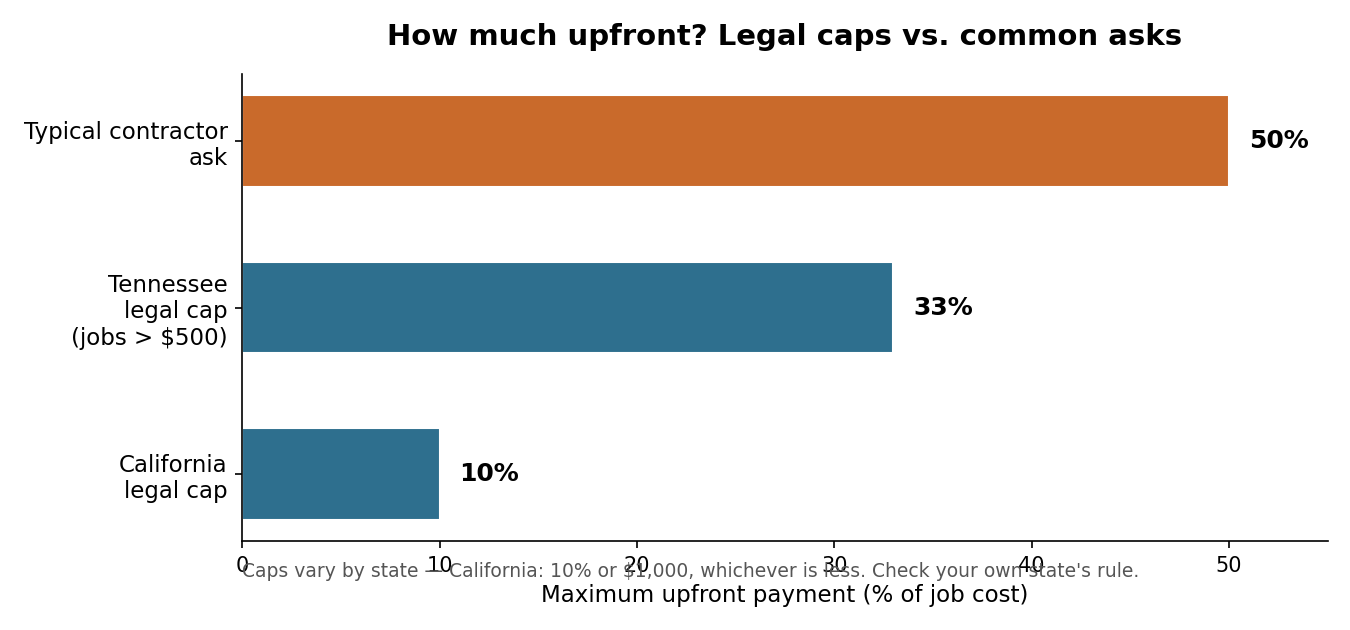
Multiple states cap deposits by statute — California at 10% or $1,000, Tennessee at 33% for jobs over $500 — and UK prime minister Andy Burnham just weighed in on the same pattern (“take a big deposit, do half a job, then disappear”), backing escrow-style release: “Do the work, get paid. It’s as simple as that.”
Legal caps vs. common asks. Caps vary by state — check your own state’s rule before you sign anything.
Now the restoration spin
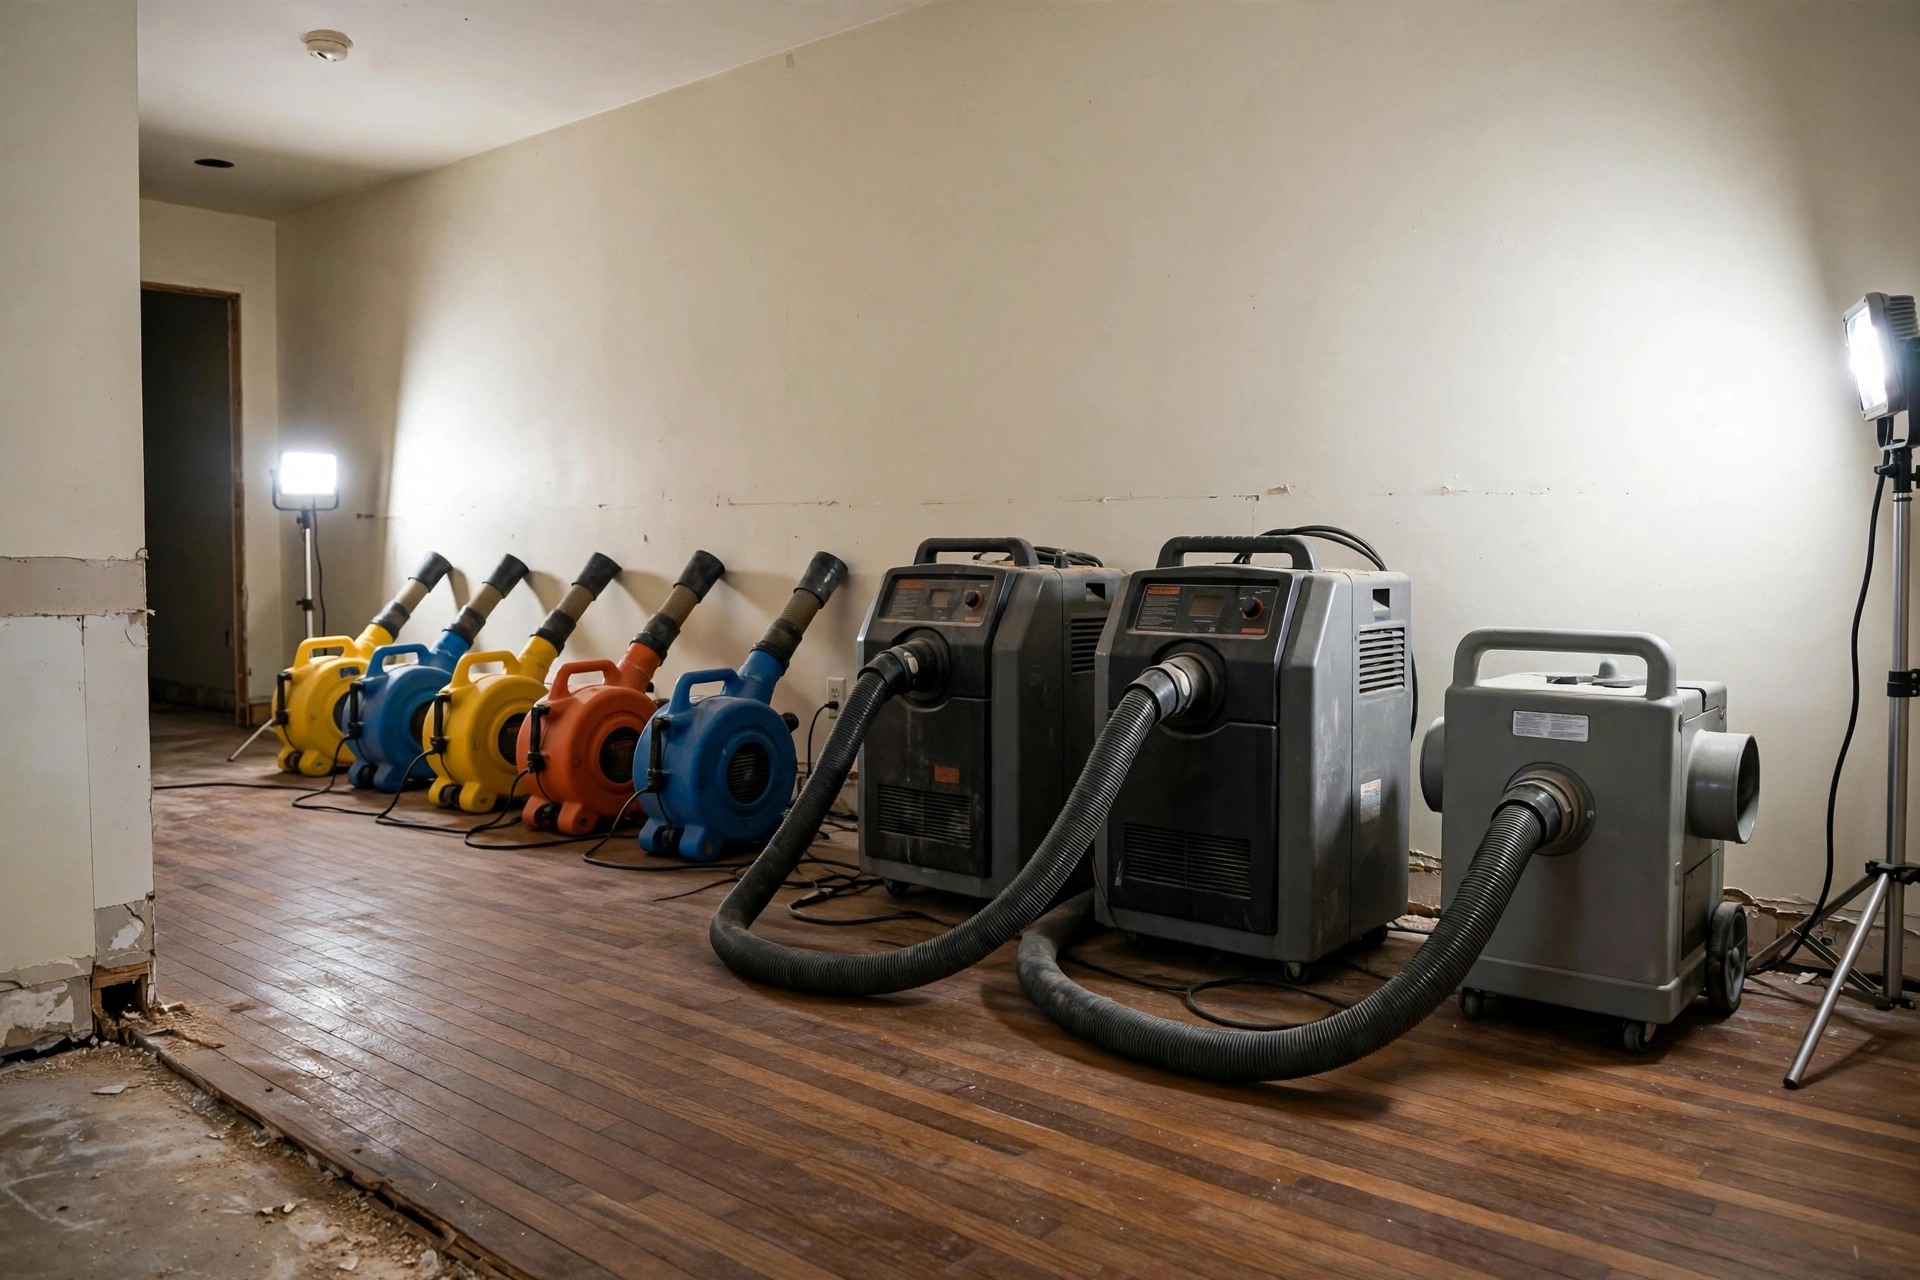
This trade has a wrinkle the general debate misses. In restoration, the contractor’s number is real in a specific way: dehumidifiers, air movers, HEPA scrubbers, containment — the rental clock starts when the gear rolls off the truck, and a serious loss can mean twelve to fifteen grand of equipment sitting in your living room before the first board is cut. That’s mobilization cost, and a deposit against it is legitimate.
Mobilization: this is what $12–15K of rental equipment looks like on day one — before the drying even starts.
But here’s the part homeowners in that Anderson thread are really asking about: on an insured loss, the homeowner often isn’t the one paying — the carrier is. The deposit fight on a covered claim is about who fronts cash while the claim processes: the deductible, the first invoice, the gap between “work starts today” and “the check arrives in three weeks.” A good restoration contractor structures deposits around the claim, not against the homeowner.
The middle ground
Assembled from the sanest voices in these threads:
Tie the deposit to something real. A DIYnot commenter nailed it: “a reasonable deposit is the cost of the equipment to be installed plus the sundry materials.” In restoration, that means the deposit maps to mobilization — gear on site — not an arbitrary 50%.
Spell out the deposit rules in writing.Kevin Page on LinkedIn: “Spell out plainly whether the deposit is non-refundable, or exactly how it gets prorated if things end early.”
Pay by phase, not by percentage. A BiggerPockets investor: “You give some unscrupulous Contrs 1/3 up front and they’ll just take off.” His fix: invoice per phase, pay each phase in full when complete and inspected.
Remember who holds the leverage. “Whoever controls the money controls the job,” writes one builder — which is exactly why staged payments beat lump deposits. Money follows work.
Documentation is the tell. Daily moisture readings, psychrometric logs, photos at every stage. A contractor who documents is a contractor who finishes — and those are the same records your adjuster needs.
The deposit isn’t the problem. The missing paperwork is. Both camps in this fight want the same thing — to not get burned — and the industry just hasn’t made the middle ground standard yet.
Most restoration contractors are invisible where it now matters most: inside the AI answers. When a facility manager asks Copilot who to call for a commercial loss, the model does not scroll your homepage. It cites whoever taught it the cleanest sentence.
Your website does not need more traffic. It needs to be the answer. Zero-click search already took the click. The remaining win is being named inside the answer itself. That is a different game than ranking a page, and most agencies are still scoring the old one.
Cited answer. A cited answer is the short, checkable sentence an answer engine lifts into Copilot, ChatGPT, Perplexity, Gemini, Bing Copilot, or a Google AI Overview and attributes to a URL. Traffic is optional. The attribution is the asset.
Why are restoration contractors invisible inside AI answers?
Commercial buyers no longer start with a ten-blue-link session. They type the job into an assistant: who handles a sprinkler discharge on a mid-rise, what a drying standard actually requires, whether a vendor is after-hours in this metro. The model answers from pages that already look like briefings.
Most contractor sites still look like brochures. Hero image. Five service tiles. A form. A blog post that restates the service name. There is no 40-to-60-word answer under the question the buyer asked. There is no timetable, no definition, no named protocol. The model has nothing safe to lift, so it lifts a national franchise FAQ, an insurer explainer, or last year’s trade-press roundup.
What did a 20-page race guide teach us about citations?
Race weekend in Madrid. We published a small independent visitor guide at racemadrid.com — twenty static pages, Spanish primary, English secondary, no ticket shop. Through 8 September 2026, Bing Webmaster showed 144 clicks and 3,218 AI citations. On 8 September the model quoted the site 55 times for every human click.
Same playbook we run for restoration companies: be the clearest answer to the question the buyer is actually asking. A facility manager after a loss is in the same posture as a traveler the night before a sold-out race. They do not want your brand story. They want the next true sentence.
How is that different from SEO?
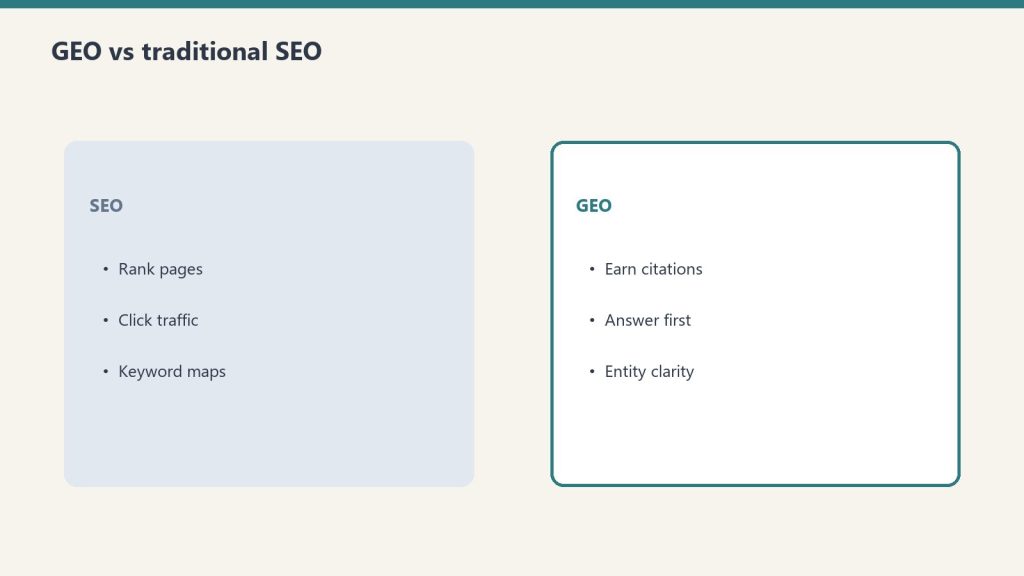
SEO still matters. It is the foundation that lets a URL exist, resolve, and get fetched. AEO is how a featured snippet or People Also Ask box can lift a clean block. GEO is how a generative engine decides you are safe enough to speak for. We treat them as concentric layers on one page, not three rewrites. The operator version of that stack is in What Is GEO? and in what GEO delivery looks like inside a real engagement.
Layer
Question it answers
What you ship
SEO
Can the engine find and trust the URL?
Title, meta, headings, first-100-word keyword, internals, schema that is true
AEO
Can a snippet lift one block without rewriting you?
Question H2, 40–60 word answer, FAQ, definition box
GEO
Will a model cite you when a buyer asks in chat?
Checkable facts per paragraph, entity names, dates, sources, bilingual or local variants when the buyer uses them
If you only measure sessions, you will call a 55-to-1 citation ratio a failure. If you measure whether the model will say your name when a facilities director asks who to call, that ratio is the product.
What does the restoration version of a cited answer look like?
It looks like a briefing, not a pitch. The H2 is the question. The next paragraph answers it in plain language, with a number or a standard attached. Then the proof: what you do on site, what you do not do, the metro you actually cover, the clock you keep.
Who to call after a commercial sprinkler discharge in this building class, after hours.
How long a category of water stays a drying job before it becomes a rebuild conversation.
What the carrier packet has to include on day one so the file does not stall.
Which document the facility manager should send before the first truck rolls.
Write those as answers a model can quote without inventing a second sentence. Put the misspellings and the local names on the page on purpose. Madrid taught us that travelers cannot spell a new circuit. Facility staff cannot spell your d/b/a either. Cover the words they type.
What is a citation worth if nobody clicks?
On the race guide, a citation is proof of position. It is not a ticket sale. We said that in the field note and it stays true here. A restoration citation is worth more than a travel citation only if you already own the next step: the phone, the after-hours board, the approved-vendor list, the estimator who can take the job tonight.
If the sentence the model lifts is wrong, the citation is a liability. We locked a Sunday start time off an older F1.com page and the official MADRING time was later. That error is still the most-clicked kind of question in the logs. The next hour of work is not a new URL. It is correcting the fact the model already trusts. Restoration pages have the same failure mode: an outdated response-time claim will travel farther than the correction.
What we would not claim
That 144 Bing clicks is a media business.
That citations replace Google. The Madrid export is Bing Webmaster plus Clarity. Google Search Console is a separate pile.
That being cited is automatically good. It is good if the fact is right and you have a use for the attention.
That this article invents a new discipline. SEO, AEO, and GEO are already named on this site. This is the operator sentence we are willing to put on LinkedIn and stand behind.
What we would do again
Show up early on a named question that does not have a settled official FAQ. Write the buyer’s language, not the agency’s. Keep the page short enough to finish. Put the clock in one place and keep it tied to a source you can defend. Do not invent a content brand around a weekend — or around a single storm.
The models will quote you if the sentence is plain. The humans who still click will click the schedule, the response protocol, the packing list. Everyone else will take the answer and move. Your job is to be the sentence they take.
FAQ
What is the difference between AEO and GEO?
AEO — Answer Engine Optimization — structures a page so a featured snippet, People Also Ask box, or voice result can lift a complete answer. GEO — Generative Engine Optimization — structures the same page so a generative model will cite that URL when a person asks in chat. One page. Two retrieval systems.
Does zero-click search mean a restoration website is useless?
No. It means the homepage-as-brochure is the wrong artifact. The useful site is a set of briefings the model can quote and the buyer can still open when they need the packet, the photo standard, or the after-hours number.
How do you know a page is being cited?
You measure it on more than one desk. Bing Webmaster now reports AI citations. Clarity shows whether the humans who still arrive actually read. Prompt checks in Copilot, ChatGPT, Perplexity, and Gemini tell you whether the brand is named. We keep the method on AI citation monitoring and on the Bing citation mining thesis.
Is this only for restoration companies?
No. Restoration is the vertical where a missed answer has a wet building attached to it. The same pattern holds anywhere a buyer asks an assistant a time-sensitive operational question and needs a named next step.
Sources: Will Tygart, Tygart Media, Tacoma, WA, 11 September 2026. First-party Bing Webmaster and Microsoft Clarity figures for racemadrid.com through 8 September 2026, as published in the Madrid field note. Related Tygart pages: restoration AI visibility, GEO explainer, GEO delivery.
If you still lean on a tool like SpyFu to gauge how your site is doing in search, you’re measuring last decade’s game. SpyFu, Ahrefs, SEMrush, and their peers were built to estimate one thing: where a domain ranks in a traditional results page, and roughly how much traffic that’s worth. Still useful — just not the whole picture, because a growing share of how people find your content never touches a results page at all. It happens inside an AI answer, where your page gets cited or quoted and the reader never clicks through.
That’s the gap between third-party rank-estimation tools and first-party AI citation data, and it matters more every month.
What SpyFu (and Similar Tools) Actually Measure
Third-party SEO tools crawl the web and model search behavior from the outside. They don’t have access to your server logs, your analytics, or Bing and Google’s internal citation data — they infer traffic from ranking position, keyword volume estimates, and click-through curves built from aggregate industry data. That’s genuinely useful for competitive research: roughly where a competitor’s domain sits, and what keywords it’s chasing.
But it’s an estimate of an estimate, built for a web where “visibility” meant “blue link position.” It has no mechanism for counting how many times an AI assistant read your page, extracted a fact from it, and served that fact directly to a user who never visited your site.
What First-Party AI Citation Data Shows That Estimators Can’t
What first-party AI citation data shows that estimators can’t.
Bing Webmaster Tools now separates two very different signals: traditional web search performance (impressions, clicks, position) and AI performance — how often your pages get surfaced inside Copilot and other AI-generated answers. Google Search Console doesn’t yet break this out the same way, which is part of why it’s easy to miss. If you only watch third-party rank trackers, this entire layer is invisible to you.
The practical difference: a page can have modest, even declining, click-through performance in classic web search while its AI-citation count climbs steadily. Judged only by a SpyFu-style estimate, that page looks flat or fading. Judged by first-party citation data, it’s doing exactly the job it was built for — being the source an AI system reaches for when someone asks a related question.
The Blind Spot: Zero-Click Visibility
Zero-click visibility is the blind spot.
The uncomfortable part for site owners is that AI citation is, by design, mostly a zero-click channel. The reader gets their answer without visiting — that’s not a measurement bug you can fix with a better tool, it’s the actual shape of the channel. An estimator that only counts clicks and rankings will systematically undercount pages that are winning at citation, because “winning” there doesn’t look like a traffic spike. It looks like your facts and explanations showing up correctly, attributed to you, inside someone else’s interface.
Relying on SpyFu-style estimates alone can lead to the wrong call: de-prioritizing a page that’s actually become a trusted AI reference source, simply because the tool built to measure clicks can’t see the citations.
Building Your Own First-Party Measurement Stack
None of this means third-party tools are useless — they’re still the right instrument for competitive keyword research and for understanding classic ranking dynamics. But they should sit alongside, not replace, sources that actually see your own traffic and your own citation footprint:
Bing Webmaster Tools’ AI Performance tab — the most direct read on how often Copilot and partner AI surfaces are citing your pages.
Server or CDN logs — the only place you’ll reliably see crawler activity from AI bots (ClaudeBot, GPTBot, PerplexityBot, and similar) hitting your pages, separate from human traffic.
Your own analytics referral data — small in volume compared to citations, but real signal: sessions that landed with claude.ai, chatgpt.com, or perplexity.ai as the referring host are humans who read an AI answer, then clicked through anyway.
Put those three together and you get a picture no third-party estimator can reconstruct: which of your pages AI systems actually trust enough to cite, and whether that trust is translating into any direct human traffic at all.
Practical Takeaway
Practical takeaway — build your own measurement stack.
If a page’s third-party “visibility score” looks unimpressive but your first-party data shows steady or rising AI citation activity, don’t treat that as a contradiction — treat it as two different questions with two different answers. The estimator tells you about classic rank. Your own logs and Bing’s AI data tell you about a newer kind of authority that doesn’t require a click to pay off. Site owners who only check the estimator are optimizing for a channel that’s shrinking relative to the one they can’t see.
FAQ
Do I need to abandon tools like SpyFu?
No. They’re still useful for competitive keyword research and classic rank tracking. The point is to stop treating their traffic estimates as the full measure of your site’s reach.
Can I get AI-citation data for Google’s AI features the way I can for Bing?
Not with the same granularity as of this writing — Bing Webmaster Tools currently offers the clearest first-party AI-citation reporting. Server-log analysis for AI crawler activity works across engines regardless.
How do I know if AI citations are actually worth anything to my business?
Track it as its own funnel stage, not a proxy for revenue. Pair citation counts with referral sessions from AI-tool domains and see whether that traffic engages with an owned conversion path on your site. Citation volume alone tells you about reach, not value.
Platform-Specific AI Optimization (PSAO) is the practice of tailoring content strategy to the distinct user personas, retrieval mechanisms, and citation patterns of each individual AI search platform. It replaces the outdated approach of “optimizing for AI” as though AI were a single channel with a single audience.
This article defines PSAO, maps the six major platforms, profiles their user personas, and provides the operational checklist. It’s the synthesis of the entire PSAO editorial sprint into a single reference document.
Why PSAO Exists
Why PSAO exists — optimize per platform.
The phrase “optimize for AI” is as meaningless as “optimize for social media.” You wouldn’t write the same post for LinkedIn and TikTok. You shouldn’t write the same content for Perplexity and Copilot. Each AI platform has a different user base, different query patterns, different retrieval infrastructure, and different citation mechanics.
PSAO emerged from practical necessity. Managing content across 20+ WordPress sites and tracking citation data — including 98,800 Copilot grounding citations from a single property — made the platform-level differences impossible to ignore. Content that earned citations on Copilot performed differently on Perplexity. Articles that won Google AI Overviews weren’t the same articles ChatGPT cited. The patterns were consistent and structural, not random.
The 6 PSAO Platforms
Platform 1: Perplexity
User persona: Researcher, analyst, fact-checker. Chose Perplexity specifically for inline citations and multi-source verification. Query style: Multi-part, complex, verification-oriented. Content that wins: Primary source data, methodology explanations, comprehensive structured guides with numbered steps. Retrieval: Bing index + proprietary crawling. Inline numbered citations visible to users. Key metric: Citation frequency across diverse query types.
Platform 2: Microsoft Copilot
User persona: Enterprise knowledge worker in Microsoft 365. Mid-task, time-pressured, gap-filling. Query style: Short, specific, definitional. Pricing, comparisons, quick facts. Content that wins: Pricing tables, comparison charts, FAQ format, definitive statements in professional tone. Retrieval: Bing index for grounding. Footnote-style citations users rarely check. Key metric: Grounding citation count (tracked via Bing Webmaster Tools AI Performance).
Platform 3: Google AI Overviews
User persona: Traditional Google searcher. Didn’t choose AI — it appeared automatically above organic results. Query style: Standard Google search — informational, definitional, how-to. Content that wins: Direct answer in first paragraph, schema markup, concise FAQ, entity-rich text. Retrieval: Google index + Knowledge Graph. Small source chips below overview. Key metric: AI Overview appearance rate and click-through from source chips.
Platform 4: ChatGPT
User persona: Explorer, creator, problem-solver. Iterates through multi-turn conversations. Query style: Conversational chains of 3-7 queries, each building on the previous. Code paste-ins, brainstorming. Content that wins: Deep technical guides, tutorials with working examples, analytical frameworks that provoke further thinking. Retrieval: Bing index via ChatGPT Search + OAI-SearchBot. End-of-response source links. Key metric: Referral traffic quality (session duration, pages per session).
Platform 5: Claude
User persona: Builder, analyst, long-context thinker. Developers, engineers, technical operators. Query style: Complex analysis, code review, architectural decisions, document synthesis with 50K-200K token contexts. Content that wins: Technical deep-dives, honest trade-off analysis, decision frameworks, comparison matrices. Retrieval: No native web search (mid-2026). Influence through training data, Claude Projects, MCP integrations. Key metric: Content adoption as reference material, training data influence.
Platform 6: Gemini
User persona: Google Workspace native. Interacts with Gemini as a Google feature, not an AI product. Query style: Factual lookups, data analysis, document summarization — embedded in Workspace apps. Content that wins: Structured data, HTML tables, definitive factual statements, reference material. Retrieval: Google index + Knowledge Graph. Expandable source section. Key metric: Schema markup coverage and structured data richness.
The PSAO User Persona Map
Platform
Persona
Intent
Time Budget
Citation Awareness
Content Format
Perplexity
Researcher
Deep investigation
Minutes to hours
High — demands sources
Guides, data, methodology
Copilot
Enterprise worker
Gap-fill mid-task
Seconds
Low — ignores footnotes
Tables, FAQ, pricing
Google AIO
Traditional searcher
Quick answer
Seconds
Low — doesn’t notice
Direct answer, schema, FAQ
ChatGPT
Explorer/creator
Iterate and explore
Minutes
Moderate
Tutorials, analysis, depth
Claude
Builder/analyst
Complex analysis
Minutes to hours
Self-verifies
Trade-offs, decisions, tech
Gemini
Workspace native
Factual lookup
Seconds
Low — “it’s Google”
Tables, facts, reference
The PSAO Operational Checklist
PSAO operational checklist.
Use this checklist for every article before publishing. Each item maps to a specific platform’s citation requirement:
Content Structure
Direct answer in first paragraph, under 100 words (Google AIO, Gemini)
5-8 H2 sections, each answering a distinct sub-question (Perplexity)
FAQ section with 5-8 exact-match Q&A pairs (Copilot, Google AIO)
At least one HTML comparison or pricing table (Copilot, Gemini)
Technical depth section with specific implementation details (ChatGPT, Claude)
Trade-offs and limitations explicitly documented (Claude)
Technical Implementation
Article JSON-LD schema (all platforms)
FAQPage JSON-LD schema (Copilot, Google AIO)
HowTo schema if applicable (Google AIO)
BreadcrumbList schema (Google AIO, Gemini)
Submitted to Google Search Console (Google AIO, Gemini)
Submitted to Bing Webmaster Tools (Copilot, ChatGPT, Perplexity)
IndexNow configured for immediate indexing (Copilot, ChatGPT, Perplexity)
Content Quality
Factual density: specific, citable claims in every section (all platforms)
Entity-rich: named products, companies, standards, technologies (Gemini, Google AIO)
Professional tone suitable for pasting into business documents (Copilot)
Primary source data or first-party metrics where possible (Perplexity)
Working examples, code samples, or configurations where relevant (ChatGPT, Claude)
Distribution
Update cadence established (monthly minimum for competitive topics)
Internal links to and from related content (all platforms — authority signal)
External citations to authoritative sources within the article (Perplexity — authority chain)
PSAO vs Traditional SEO vs GEO vs AEO
PSAO vs traditional SEO vs GEO vs AEO.
PSAO is not a replacement for SEO, GEO (Generative Engine Optimization), or AEO (Answer Engine Optimization). It’s the platform-specific layer that sits on top of those disciplines:
Discipline
Focus
Granularity
SEO
Google organic search rankings
Google-specific
AEO
Featured snippets, People Also Ask, voice search
Google-specific
GEO
AI citation across all platforms
AI as a monolith
PSAO
Platform-by-platform AI optimization
Individual platform personas
GEO says “optimize for AI.” PSAO says “optimize for this AI platform’s specific user, specific retrieval mechanism, and specific citation pattern.” It’s the same difference between “do social media marketing” and “run a LinkedIn thought leadership strategy targeting VP-level decision makers in B2B SaaS.”
Implementing PSAO at Scale
For a single site, the PSAO checklist is manual. For managing multiple sites — which is the reality of agency work and portfolio management — PSAO needs automation:
Schema injection automation: Every article gets Article + FAQPage schema automatically as part of the publishing pipeline
Dual-index submission: Every new post submits to both Google Search Console and Bing Webmaster Tools via IndexNow
Content structure templates: Writers start with the 6-layer template, ensuring every article has the direct answer, structured sections, FAQ, tables, and technical depth
Update scheduling: Top-performing articles are flagged for monthly refresh with current data and examples
Citation monitoring: Bing AI Performance data is reviewed weekly to track grounding citation trends and identify content that’s earning (or losing) citations
Actionable Takeaways
Adopt PSAO as a named discipline. Stop saying “optimize for AI.” Start specifying which platform and which user persona you’re targeting
Use the PSAO checklist for every article. Print it, pin it, make it a template in your CMS. Every item maps to a real citation opportunity
Submit to both Google and Bing. Three of six platforms use Bing. This is the most common infrastructure gap
Write for the persona, not the algorithm. The Perplexity researcher wants different content than the Copilot enterprise worker. The structure follows from the persona
Measure platform-level performance. Track citations, referral traffic, and conversion rates by AI platform — not “AI” as a single bucket
FAQ
What is Platform-Specific AI Optimization (PSAO)?
PSAO is the practice of tailoring content strategy to the distinct user personas, retrieval mechanisms, and citation patterns of each individual AI search platform — Perplexity, Copilot, Google AI Overviews, ChatGPT, Claude, and Gemini — rather than treating AI as a single optimization target.
How is PSAO different from GEO (Generative Engine Optimization)?
GEO treats AI search as a monolith — optimizing for “AI” broadly. PSAO operates at the individual platform level, recognizing that each platform serves a different user persona with different content preferences and different citation mechanics. PSAO is the platform-specific layer that sits on top of GEO.
Do I need to create different content for each AI platform?
No. A single well-structured article can serve all six platforms using the PSAO 6-layer template: direct answer first, comprehensive structured body, FAQ section, technical depth, HTML tables, and schema markup. Each layer maps to a specific platform’s citation trigger.
What is the PSAO checklist?
The PSAO checklist is a pre-publish quality gate covering content structure, technical implementation, content quality, and distribution. Each item maps to a specific AI platform’s citation requirements, ensuring every article has maximum citation surface area across all six platforms.
Which AI platform should I prioritize for PSAO?
Prioritize based on your audience. If your audience is enterprise workers, prioritize Copilot optimization. If your audience is researchers, prioritize Perplexity. For maximum coverage with minimum effort, use the unified 6-layer article structure and the PSAO checklist to serve all platforms simultaneously.
You publish an article on the same topic as your competitor. Their article gets cited by Copilot, Perplexity, and Google AI Overviews. Yours doesn’t. The topic is the same. The word count is similar. You even think your writing is better. So what’s different?
After analyzing citation patterns across the sites I manage — including the 98,800 Copilot citations data set and the per-model content shaping research — I can identify exactly what separates content that earns AI citations from content that gets ignored. It’s not writing quality. It’s structural.
The 6 Factors That Determine AI Citation
Six factors that determine AI citation.
AI platforms don’t evaluate content the way human editors do. They use measurable signals to decide what to cite. Here are the six factors, ranked by impact:
Factor 1: Authority Signals (Domain and Page Level)
Every AI platform uses some form of authority scoring. Bing’s system (powering Copilot, ChatGPT Search, and partially Perplexity) evaluates domain authority, backlink quality, and topical relevance. Google’s system (powering AI Overviews and Gemini) uses E-E-A-T signals, Knowledge Graph connections, and site reputation.
If your competitor’s domain has stronger authority signals — more quality backlinks, longer publishing history in the niche, recognized author entities — they’ll be cited over you even when your content is technically better. Authority is the foundation layer. Without it, everything else is marginal.
Factor 2: Factual Density
AI citation engines prefer content that makes specific, verifiable factual claims over content that makes general statements. “Implementation typically takes 6-8 weeks for a mid-size company and costs between $15,000 and $45,000 depending on customization requirements” is citable. “Implementation timelines and costs vary based on your specific needs” is not.
Count the specific, citable facts per 500 words in your article versus your competitor’s. The content with higher factual density wins citations, because AI platforms need specific claims to ground their responses.
Factor 3: Structured Data Implementation
This is the most common gap I find when auditing sites that underperform on AI citations. The competitor has FAQPage schema, Article schema, BreadcrumbList schema, and clean HTML tables. The underperformer has none, or has broken schema that doesn’t validate.
Structured data is how AI platforms understand content structure without having to interpret prose. It’s the difference between handing someone a well-organized filing cabinet and handing them a box of loose papers. The content might be equally good — but the organized version gets used.
Factor 4: Update Frequency and Content Freshness
AI platforms track when content was last modified. In competitive citation scenarios — where multiple sources could answer the same query — the more recently updated source wins. This is especially true on Perplexity and Copilot, which weight freshness heavily.
If your competitor published their article six months ago and updated it last week, and your article was published six months ago with no updates, they win. Even if your original content was superior. The update doesn’t need to be a complete rewrite — adding current data, refreshing examples, and updating the last-modified date can be enough.
Factor 5: Topical Depth and Coverage Completeness
AI platforms evaluate whether a source comprehensively covers the query topic. A 3,000-word article that addresses every sub-question a user might ask about the topic will be cited more frequently than a 500-word post that addresses only the headline question.
This isn’t about word count for its own sake. It’s about coverage completeness. Does your article answer the follow-up questions a user might ask? Does it address edge cases and exceptions? Does it provide the comparison the user would need to make a decision? Your competitor’s article probably does.
Factor 6: Bing Indexing and Technical Access
The most embarrassing reason your competitor gets cited and you don’t: they’re indexed by Bing and you’re not. Three major AI platforms — Copilot, ChatGPT Search, and Perplexity — use Bing’s index. If you’ve never submitted your sitemap to Bing Webmaster Tools, you’re invisible to half the AI landscape regardless of content quality.
Check your Bing Webmaster Tools account. Verify your sitemap is submitted. Use IndexNow to push updates immediately. This is table-stakes infrastructure that many sites neglect because they focus exclusively on Google.
How to Run a Competitive Citation Audit
How to run a competitive citation audit.
Here’s the practical framework for identifying why your competitor gets cited and you don’t:
Identify citation-winning competitors. Use Bing AI Performance in Bing Webmaster Tools to see which domains appear alongside yours in AI responses. If you don’t see yourself, check which domains appear for your target queries
Audit their structured data. Run their top pages through Google’s Rich Results Test. Compare their schema implementation to yours
Measure factual density. Count specific, citable claims per section in their content versus yours. Are they more specific? Do they include more data points, comparisons, and verifiable facts?
Check update patterns. When was their content last modified? How often do they refresh key articles? Compare to your own update cadence
Evaluate topical depth. Do their articles answer more sub-questions than yours? Do they include comparison tables, FAQ sections, and edge-case coverage that your articles lack?
Verify Bing indexing. Are your pages indexed in Bing? Are theirs? How quickly do new pages appear in Bing’s index for each site?
The Fix Priority Order
The fix priority order.
If your competitive audit reveals gaps across multiple factors, fix them in this order for maximum impact:
Bing indexing (immediate): If you’re not in Bing, nothing else matters for Copilot, ChatGPT, or Perplexity
Structured data (quick win): Adding schema markup to existing content can shift citation patterns within weeks
Content freshness (ongoing): Update your top-performing articles with current data and examples
Factual density (content revision): Replace vague claims with specific, citable facts across your key articles
Topical depth (content expansion): Add FAQ sections, comparison tables, and edge-case coverage to thin articles
Authority building (long-term): Backlink acquisition, topical authority development, author entity building
Actionable Takeaways
Run a competitive citation audit using the 6-factor framework. Compare your content against the citation winners in your niche
Fix Bing indexing immediately. Submit your sitemap to Bing Webmaster Tools and implement IndexNow
Add structured data to your top 20 articles. Article + FAQPage schema at minimum. HowTo and BreadcrumbList where applicable
Increase factual density. Replace every vague statement with a specific, citable claim where possible
Why does my competitor’s content get cited by AI when mine doesn’t?
The most common reasons are stronger domain authority signals, higher factual density (more specific citable claims per section), better structured data implementation, more recent content updates, deeper topical coverage, and — frequently overlooked — proper Bing indexing that your site may lack.
What is the fastest way to start earning AI citations?
Submit your sitemap to Bing Webmaster Tools and add Article + FAQPage schema markup to your top articles. These two actions address the most common technical gaps and can shift citation patterns within weeks. After that, focus on increasing factual density and update frequency.
How do I measure whether my content is being cited by AI platforms?
Bing Webmaster Tools includes an AI Performance report showing Copilot citations, impression counts, and grounding queries. For other platforms, monitor referral traffic from Perplexity, ChatGPT, and Gemini in your analytics. Google Search Console is expanding AI Overview reporting.
Does writing quality affect AI citation rates?
Less than most people think. AI citation engines evaluate structure, authority, factual density, and freshness — not prose quality. A well-structured article with specific facts and proper schema markup will be cited over a beautifully written article that lacks these structural elements.
How often should I update content to maintain AI citations?
Key articles should be reviewed and updated at least monthly for competitive topics. Update current data, refresh examples, add new FAQ pairs, and ensure the last-modified date reflects the changes. Even small updates signal freshness to AI platforms in competitive citation scenarios.
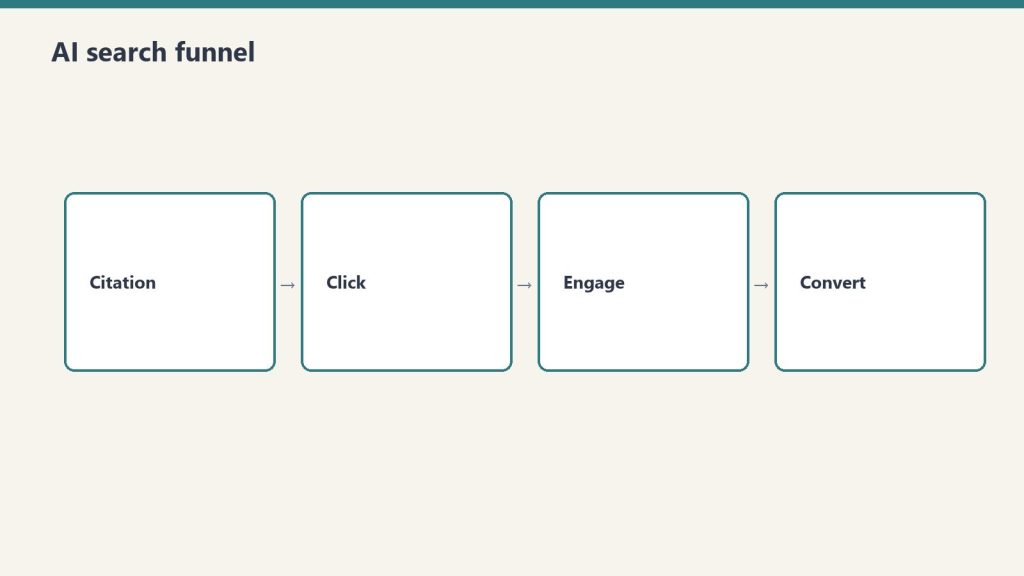
An AI citation is not a click. A click is not a conversion. The funnel from “Copilot cited your site” to “a new client signed up” has multiple stages, each with its own drop-off rate. Most content strategists celebrate citations without measuring what those citations actually produce. After tracking the full funnel across the sites I manage — including the 98,800 Copilot citations — here’s what the AI search funnel actually looks like.
The 4-Stage AI Search Funnel
The 4-stage AI search funnel.
Every AI search interaction follows a predictable funnel, regardless of platform:
Impression: Your content appears as a citation, source link, or referenced domain in an AI response
Click: The user clicks through to your actual website
Engagement: The user reads, browses, or interacts with your site
Conversion: The user takes a desired action — fills a form, makes a purchase, subscribes, contacts you
Each stage has dramatically different metrics depending on which AI platform generated the impression.
Stage 1: The Citation (Impression)
Stage 1: the citation is the new impression.
Not all citations are equal. The platform determines how visible your citation is to the user:
Platform
Citation Visibility
User Citation Awareness
Perplexity
Inline numbered citations — highly visible
High — users actively check sources
Copilot
Footnote-style references
Low — most users don’t expand footnotes
Google AI Overviews
Small source chips below the overview
Low to moderate — depends on query
ChatGPT Search
End-of-response source links
Moderate — users notice but rarely click
Gemini
Expandable source section
Low — embedded Workspace users ignore citations
Claude
Web-search citations when search is used (API / claude.ai)
Moderate — citations on web-search answers; training influence without search
The implication: a Perplexity citation has fundamentally higher click-through potential than a Copilot citation because the user actually sees and engages with the source attribution.
Stage 2: The Click-Through
Click-through rates from AI citations vary dramatically by platform. Based on the data I’ve tracked across managed sites:
Perplexity Click-Through
Perplexity has the highest click-through rate of any AI platform because its users are researchers who verify sources. When Perplexity cites your content with an inline [1] reference, a meaningful percentage of users click through to read the source. The click-through rate from Perplexity citations substantially exceeds what we see from Copilot or Google AI Overviews.
Google AI Overview Click-Through
Google AI Overviews present the biggest challenge: the overview often satisfies the user’s query completely, eliminating the need to click. The click-through from AI Overview citations to the cited source is significantly lower than traditional organic search. This is the zero-click problem at scale.
Copilot Click-Through
Copilot has the lowest click-through rate because the user is mid-workflow and the answer is consumed within the Microsoft 365 application. The user got what they needed without leaving Word or Excel. The citation exists in a footnote they never expand. From 98,800 citations, the actual click-through volume is a fraction of what that impression number suggests.
ChatGPT Click-Through
ChatGPT Search places source links at the end of responses. Users in conversation mode sometimes click these links, especially when the topic requires deeper reading. Click-through rates are moderate — between Perplexity’s high engagement and Copilot’s near-zero engagement.
Stage 3: Engagement Quality
Engagement quality still decides conversion.
Here’s where AI-sourced traffic gets interesting. Users who click through from AI platforms tend to be more engaged than average organic visitors because they’ve already been pre-qualified by the AI’s response. They clicked because the AI’s summary wasn’t enough — they want more depth.
The engagement pattern by platform:
Perplexity referrals: Longest time on page. These users arrived because they’re researching and the AI response prompted them to go deeper. They read, they bookmark, they follow internal links
ChatGPT referrals: Above-average engagement. The conversational context means they arrive with specific questions the article can answer
Google AI Overview referrals: Mixed. Some users click because the overview was incomplete. Others misclick. Bounce rates are higher than other AI referral sources
Copilot referrals: The rare users who do click through from Copilot are highly engaged — they specifically sought out the source, which signals strong intent
Stage 4: Conversion
The final stage is where AI search traffic’s value becomes concrete. Conversion rates from AI referrals depend heavily on two factors: the quality of the pre-qualification (how well the AI response set expectations) and the alignment between the AI’s citation context and your conversion path.
AI Traffic vs Google Organic: The Conversion Comparison
AI-sourced traffic converts differently than Google organic traffic. Google organic users arrive with search intent that maps directly to your content. AI-sourced users arrive because an AI cited you while answering a broader question — the intent alignment is less precise but the trust transfer from the AI platform can compensate.
The net effect in the data I’ve tracked: AI referral traffic converts at rates comparable to Google organic for informational-to-contact funnels (content marketing → lead gen). It converts lower for direct commercial queries where Google organic’s intent-matching advantage matters more.
Where the Funnel Leaks (And How to Fix It)
Leak 1: Citation Without Click
Problem: Copilot and Google AI Overviews generate thousands of citations that produce minimal clicks. Fix: Treat these citations as brand impressions, not traffic sources. Measure brand recognition lift and branded search volume increases alongside click-through.
Leak 2: Click Without Engagement
Problem: Users click through from AI but bounce because the landing page doesn’t match the context of the AI’s citation. Fix: Ensure the specific section cited by the AI is prominent on the page. Use in-page anchors and clear section headers so arriving users immediately see the content that prompted their click.
Leak 3: Engagement Without Conversion
Problem: Users read the content but don’t convert because there’s no conversion path within the content flow. Fix: Embed contextual CTAs within the article body, not just at the bottom. If the AI cited your pricing comparison, the CTA should be adjacent to the pricing content, not after 2,000 more words.
Actionable Takeaways
Measure the full funnel, not just citations. Track impression → click → engagement → conversion for each AI platform separately
Treat low-CTR platforms as brand channels. Copilot’s 98,800 citations are brand impressions even if few users click through. Measure branded search lift
Optimize landing pages for AI referral context. Users arrive mid-thought. Make the cited content immediately visible
Embed conversion paths within content. Contextual CTAs near the sections most likely to be cited by AI platforms
Prioritize Perplexity for traffic, Copilot for brand awareness. Different platforms serve different funnel stages
FAQ
What percentage of AI citations result in actual website clicks?
It varies dramatically by platform. Perplexity citations generate the highest click-through because its users actively verify sources. Copilot citations generate the lowest because users consume answers within Microsoft 365 without expanding footnotes. Google AI Overview and ChatGPT fall between these extremes.
Is AI search traffic better or worse than Google organic for conversions?
AI referral traffic converts at rates comparable to Google organic for informational-to-contact funnels. It converts lower for direct commercial queries where Google’s intent-matching advantage is stronger. The quality of pre-qualification from AI responses can compensate for less precise intent alignment.
How should I measure the value of AI citations that don’t generate clicks?
Treat low-click-through citations as brand impressions. Track branded search volume increases, direct traffic growth, and brand recognition metrics. A user who sees your domain cited by Copilot daily may eventually search for you directly.
Which AI platform sends the highest quality traffic?
Perplexity referrals consistently show the longest time on page and lowest bounce rates because these users are researchers who clicked through specifically to go deeper. Copilot referrals, while rare, also show strong engagement because the user actively sought out the source.
Where does the AI search funnel leak the most?
The biggest leak is citation-without-click, particularly on Copilot and Google AI Overviews. The second biggest leak is click-without-engagement, caused by landing page misalignment with the AI citation context. Embedding contextual CTAs and ensuring cited sections are prominent addresses both leaks.
If you’ve been following this PSAO series, you now understand that each AI platform serves a different user persona with different content preferences. The Perplexity user wants cited research. The Copilot user wants a pricing table. The Google AI Overview user wants the answer in paragraph one. The ChatGPT user wants explorative depth. The Claude user wants honest trade-offs. The Gemini user wants structured data.
The obvious question: do I need to write six different articles for every topic?
No. But you do need to write one article with a specific structure that hits all six citation triggers. Here’s the architecture.
The Universal PSAO Article Structure
Universal PSAO article structure.
After publishing and tracking citation patterns across the sites I manage — including the 98,800 Copilot citations documented in the meta sprint — I’ve reverse-engineered a single article structure that performs across all platforms. Each section serves a specific platform’s content preference while maintaining a coherent reading experience for humans.
Layer 1: Direct Answer First (Google AI Overviews)
The first paragraph must answer the article’s core question directly, completely, and in under 100 words. This isn’t a teaser or a hook — it’s the answer. Google AI Overviews extract from the opening section. If your article starts with background, context, or a personal anecdote, Google skips you and cites the competitor who led with the answer.
Template: “[Topic] is [definition/answer]. It works by [mechanism]. The key consideration is [critical factor]. Here’s the complete breakdown.”
Layer 2: Comprehensive Body with Structured Sections (Perplexity)
After the direct answer, build the comprehensive body. Each H2 section should answer a distinct sub-question that a researcher might ask. Perplexity’s retrieval engine chunks content by section headers and cites individual sections for specific queries. The more distinct, well-labeled sections your article has, the more citation surface area you create for Perplexity.
Template: H2 headers as questions (“How does X work?”, “What are the costs of Y?”, “When should you choose Z over W?”). Each section is a self-contained mini-article: claim, evidence, context, specific numbers.
Layer 3: FAQ Section with Exact-Match Questions (Copilot)
Copilot’s grounding engine pattern-matches user queries to FAQ headings. An FAQ section with 5-8 question-and-answer pairs, where the questions match how enterprise workers phrase their queries, is a Copilot citation magnet. Keep answers to 2-4 sentences — tight enough for Copilot to extract but substantive enough to be useful.
Template: H3 questions using “What is,” “How much does,” “What’s the difference between,” “Should I.” Answers: definitive, factual, 40-80 words each.
Layer 4: Technical Depth and Working Examples (ChatGPT + Claude)
Within the comprehensive body, include at least one section with genuine technical depth. Code examples, configuration samples, architecture decision reasoning, or detailed methodology. ChatGPT cites this when users ask specific technical questions. Claude users value it when they encounter your content through any channel.
Template: A section titled “Implementation Guide,” “Technical Architecture,” or “Step-by-Step Configuration” with actual specifics — not conceptual overviews.
Layer 5: Tables and Structured Data (Gemini + Copilot)
Every article that involves comparisons, pricing, features, or specifications should include at least one HTML table. Tables serve both Gemini (which needs data it can relay to Workspace users) and Copilot (which cites structured data for enterprise workers). A single comparison table can earn citations from both platforms simultaneously.
Template: Feature comparison tables, pricing breakdowns, decision matrices. Clean HTML <table> markup, not images of tables.
Layer 6: Schema Markup (All Platforms)
JSON-LD schema markup is the universal amplifier. Article schema, FAQPage schema, HowTo schema (if applicable), and BreadcrumbList schema improve citation probability across every platform that uses structured data — which is all of them to varying degrees.
The Complete Article Template
Putting all six layers together, a PSAO-optimized article looks like this:
Every article in this PSAO series follows this structure. Look at the architecture:
Each article opens with a direct answer paragraph (Layer 1)
The body has 5-7 distinct H2 sections answering sub-questions (Layer 2)
An FAQ section closes each article with 5 exact-match Q&As (Layer 3)
Technical specifics — query patterns, data breakdowns, implementation details — are embedded in the body (Layer 4)
Comparison tables appear in every persona article (Layer 5)
Article + FAQPage JSON-LD schema is appended to every article (Layer 6)
This isn’t a theoretical framework — it’s the production template running across the sites I manage.
Common Mistakes When Writing for Multiple Platforms
Common mistakes when writing for multiple platforms.
Mistake 1: Starting with a Story Instead of the Answer
Personal anecdotes and narrative hooks work for human readers on social media. They fail on AI platforms because every platform except ChatGPT extracts from the opening section. If your answer is in paragraph four, Google, Copilot, and Gemini will cite your competitor who put it in paragraph one.
Mistake 2: Using Images Instead of HTML Tables
A beautiful comparison infographic is invisible to every AI platform. AI systems can’t read text in images. The same data in an HTML table is citable by all six platforms. Always use HTML tables alongside any visual representation.
Mistake 3: Writing FAQ Answers That Are Too Long
Copilot and Google AIO need 2-4 sentence FAQ answers. When your FAQ answers are 200-word mini-essays, these platforms can’t extract clean, citable responses. Keep FAQ answers tight — save the depth for the body sections.
Mistake 4: Ignoring Bing Indexing
Three of the six platforms — Copilot, ChatGPT Search, and Perplexity — use Bing’s index. If your site isn’t submitted to Bing Webmaster Tools and you’re not using IndexNow for rapid indexing, you’re invisible to half the AI search landscape.
Actionable Takeaways
Use the 6-layer structure for every new article. Direct answer → comprehensive body → FAQ → technical depth → tables → schema. This template serves all platforms simultaneously
Always start with the answer. First 100 words should fully answer the article’s core question. No preamble, no story, no context-setting
Include at least one HTML table per article. Comparison, pricing, or feature tables serve Gemini and Copilot simultaneously
Write 5-8 FAQ pairs with 40-80 word answers. Tight enough for Copilot extraction, substantive enough for Google AIO sourcing
Submit to both Google Search Console and Bing Webmaster Tools. This covers all six platforms’ index sources
Implement Article + FAQPage schema on every article. The universal citation amplifier
FAQ
Do I really need to optimize for all 6 AI platforms?
You don’t need to create separate content for each platform. One well-structured article using the 6-layer PSAO template serves all platforms simultaneously. The key is including the right structural elements — direct answer, comprehensive sections, FAQ, tables, technical depth, and schema — in a single piece.
What is the most important layer for multi-platform performance?
The direct answer in paragraph one. It serves Google AI Overviews (which extract from the opening), Gemini (which relays definitive statements), and Copilot (which front-loads factual content). Every other layer is additive; this one is foundational.
How long should a PSAO-optimized article be?
Between 1,500 and 2,500 words for standard articles, up to 3,500 for pillar content. This length provides enough depth for Perplexity and ChatGPT citation surface area while keeping the article focused enough for Google AI Overview extraction.
Do HTML tables actually improve AI citation rates?
Yes. AI platforms read HTML table markup but cannot parse text embedded in images. A comparison table in clean HTML is citable by all six platforms. The same data as an infographic or screenshot is invisible to every AI system.
Should I submit my site to Bing even if I only care about Google?
Absolutely. Copilot, ChatGPT Search, and Perplexity all use Bing’s index for web content retrieval. Ignoring Bing means you’re invisible to half the AI search platforms regardless of how well your content performs on Google.
Gemini users are the most underestimated persona in the AI search landscape. Content strategists focus on ChatGPT’s scale, Perplexity’s citations, and Copilot’s enterprise footprint — while ignoring the billion-plus users who interact with Gemini through Google Workspace, Android, and Google Search every day. These users don’t think of themselves as “using an AI product.” They’re using Google. And that distinction defines what content wins.
This is the sixth article in the PSAO series, and it completes the platform-by-platform user profiles before we move to synthesis and strategy.
Who Uses Gemini (The Invisible Majority)
Who uses Gemini — the invisible majority.
Gemini’s deployment is broader than any other AI platform because Google embedded it everywhere:
Google Workspace users: Gemini is in Gmail (“Help me write this reply”), Google Docs (“Summarize this document”), Google Sheets (“Analyze this data”), and Google Slides (“Generate a presentation outline”). These users interact with Gemini as a feature, not a product
Android users: Gemini replaced Google Assistant on Android devices. When someone says “Hey Google, what’s the best restaurant near me?”, they’re talking to Gemini. They likely don’t know or care
Google Search users: Gemini powers Google AI Overviews (covered in the AI Overview user article), but also powers the standalone Gemini chat interface that some users access directly
Developers: Gemini through Vertex AI serves enterprise developers who build AI applications. This is a distinct persona from the Workspace user — more similar to Claude’s developer audience
The dominant Gemini persona is the Workspace user — someone operating inside Google’s ecosystem who expects Google-quality factual accuracy without having to leave their workflow.
How Gemini Users Interact (Embedded, Not Standalone)
How Gemini users interact — embedded, not standalone.
The In-App Query
The typical Gemini interaction happens inside another application. The user is writing an email in Gmail and asks Gemini to “make this more professional.” They’re in Google Sheets and ask “what’s the trend in this data?” They’re in Google Docs reviewing a contract and ask “what are the key risks in this agreement?”
These queries are contextual — they reference the user’s current document, email, or spreadsheet. The content Gemini draws on to supplement its responses is whatever Google’s systems deem authoritative for the domain of the user’s query.
Factual Lookup Queries
When Gemini users ask factual questions, they expect Google-grade accuracy. The trust threshold is higher than ChatGPT or Copilot because users associate the Google brand with authoritative answers. Content that includes hedging language, speculative claims, or unverifiable statistics loses to content that states facts with precision and backs them up.
Data Analysis and Summarization
Gemini in Google Sheets and Docs handles a significant volume of data analysis and document summarization queries. Users paste or upload data and ask for interpretation. The content Gemini references for this — benchmark data, industry standards, methodology explanations — is the content that becomes a background source for millions of summarization tasks.
What Content Wins with Gemini
What content wins with Gemini.
Structured Data That Google Can Parse
Gemini is built on Google’s infrastructure, which means it has deep integration with Google’s Knowledge Graph, structured data systems, and entity recognition. Content with comprehensive schema markup, clean HTML tables, and well-structured metadata is dramatically easier for Gemini to ingest and reference. This isn’t about SEO gamesmanship — it’s about making your content machine-readable at the level Google’s systems expect.
Tables and Lists Over Prose
Gemini’s Workspace integration means many responses need to be structured. When a user in Sheets asks about industry benchmarks, Gemini wants data it can present in a table format. Content that presents information in tables, numbered lists, and structured formats gives Gemini material it can directly use in Workspace contexts.
Factual Statements That Don’t Require External Verification
Gemini prioritizes content that makes definitive, verifiable factual statements. “The standard depreciation period for commercial real estate under MACRS is 39 years” is exactly what Gemini needs. “Depreciation periods vary depending on multiple factors” is useless. The Workspace user needs a specific fact they can use in their document — and Gemini needs a source it can confidently cite for that fact.
Industry-Standard Reference Material
Content that functions as reference material — glossaries, standards documents, regulatory summaries, technical specifications — earns disproportionate Gemini citations because it answers the lookup-style queries that dominate Workspace interactions. If your content is the kind of thing a professional bookmarks for quick reference, it’s the kind of thing Gemini wants to cite.
Gemini vs Other Platforms: The Key Differences
Dimension
Gemini User
Copilot User
Claude User
Ecosystem
Google Workspace, Android
Microsoft 365
Standalone + API
Awareness of AI
Low — it’s “Google”
Medium — it’s a sidebar
High — deliberate choice
Query type
Factual lookups, data analysis
Gap-filling mid-task
Complex analysis, code review
Content preference
Tables, structured data, facts
FAQ, pricing tables
Deep analysis, trade-offs
Trust model
“Google says it”
“Microsoft says it”
“I’ll verify it myself”
Actionable Takeaways for Gemini Optimization
Implement comprehensive schema markup. Gemini’s Google integration means structured data is more important here than on any other platform
Present key information in tables. Gemini Workspace users need data they can paste into Sheets and Docs. Tables are citation magnets
Make definitive factual statements. No hedging. State the fact, cite the source, give Gemini a clean statement it can relay with confidence
Optimize for Google’s Knowledge Graph. Entity-rich content with explicit relationships between entities helps Gemini connect your content to relevant queries
FAQ
Where do people interact with Gemini?
Gemini is embedded across Google’s ecosystem: Gmail, Google Docs, Google Sheets, Google Slides, Android devices (replacing Google Assistant), Google Search (powering AI Overviews), and as a standalone chat interface. Most users interact with Gemini as a feature of Google products, not as a separate AI product.
How does Gemini choose what content to reference?
Gemini leverages Google’s existing infrastructure — the Knowledge Graph, structured data systems, and search index. Content with comprehensive schema markup, clean HTML tables, and well-structured metadata is prioritized because it’s machine-readable at the level Google’s systems expect.
What content format works best for Gemini citations?
Tables, structured data, definitive factual statements, and reference material. Gemini’s Workspace context means it often needs to present information in table format for Sheets users or provide facts for Docs users. Content that serves these use cases earns the most citations.
Is optimizing for Gemini different from optimizing for Google Search?
Partially. Both benefit from schema markup, entity-rich content, and factual accuracy. But Gemini Workspace interactions add emphasis on tabular data, reference-style content, and definitive statements that a user can paste directly into a business document or spreadsheet.
Do I need to submit my site to a special index for Gemini?
No. Gemini uses Google’s existing search index and Knowledge Graph. If your site is well-indexed by Google with comprehensive schema markup, Gemini can access it. Standard Google Search Console practices apply.
I use Claude to manage 20+ WordPress sites, write code, analyze data, and build infrastructure. I’m not unusual among Claude users — we’re the builders, the analysts, and the people who need an AI that can hold 200,000 tokens of context without losing the thread. And that user profile shapes exactly what content Claude surfaces, recommends, and would cite if citation features expand.
Claude’s user base self-selects differently than any other AI platform. Nobody ends up using Claude by accident — there’s no browser default, no operating system integration forcing adoption. People choose Claude for specific reasons, and those reasons define the content that resonates with them:
Developers and engineers: Code review, architecture decisions, debugging complex systems, writing documentation. Claude’s long context window means they can paste entire codebases and get meaningful analysis
Analysts and researchers: Document analysis, report synthesis, data interpretation. They upload PDFs, spreadsheets, and research papers and ask Claude to extract insights
Technical writers and content strategists: People who need nuanced, accurate writing that doesn’t oversimplify. Claude’s tendency to acknowledge trade-offs rather than pick a winner appeals to this group
Business operators who run on AI: People like me — using Claude Code, Claude Projects, Claude API to build actual operational infrastructure. Not just asking questions, but building systems
The common thread: Claude users are builders. They don’t just consume AI output — they integrate it into workflows, iterate on it, and treat Claude as a collaborator rather than an oracle.
How Claude Users Work (Not Just Search)
How Claude users work — not just search.
Claude users don’t “search” in the traditional sense. They work. The distinction matters for content strategy:
Long-Context Document Analysis
Claude users regularly paste 50,000-200,000 tokens of content and ask questions about it. A lawyer pastes a 100-page contract. A developer pastes an entire repository. A researcher pastes five papers. The questions they then ask Claude are specific, contextual, and often unanswerable by any search engine because the answer requires synthesizing the pasted context with general knowledge.
Content that serves this user provides the “general knowledge” side of the equation — authoritative reference material that Claude can draw on when synthesizing answers about the user’s specific documents.
Architectural Decision Queries
Claude users frequently ask for help with decisions that involve trade-offs: “Should I use PostgreSQL or MongoDB for this use case, given these constraints?” The key behavioral pattern is that Claude users want the trade-offs acknowledged, not hidden. Content that says “PostgreSQL is the best choice” loses to content that says “PostgreSQL is stronger for X and Y, but MongoDB handles Z better — here’s how to decide.”
Code Review and Refactoring
Claude Code users paste code and ask for analysis, optimization suggestions, and security review. This creates demand for content that explains why certain patterns are better — not just what pattern to use. Claude users want the reasoning, not just the recommendation.
What Content Wins with Claude Users
What content wins with Claude users.
Technical Deep-Dives with Trade-Off Analysis
The single most effective content format for the Claude audience is the honest technical comparison. Not “5 Best Tools for X” but “How to Choose Between Tool A and Tool B: The Decision Framework.” Claude users are allergic to content that picks winners without acknowledging costs. They trust content that shows them the full picture and lets them decide.
Architectural Decision Records
Content structured as ADRs (Architecture Decision Records) — stating the context, the options considered, the decision made, and the trade-offs accepted — resonates deeply with Claude’s technical user base. This format maps directly to how they think about problems.
Comparison Matrices
Detailed feature comparison matrices with honest assessments (not marketing-biased checkmarks where your product wins every category) perform well. Claude users evaluate tools rigorously. Content that survives their scrutiny earns their trust and their recommendations to colleagues.
Implementation Guides with Context
Claude users don’t just want “how to do X.” They want “how to do X in the context of Y, given constraints Z.” Content that provides implementation guidance within specific architectural or business contexts outperforms generic tutorials. The Claude user is past the beginner stage — they need content that matches their level of sophistication.
Honest Assessments and Limitations
Here’s what separates content that Claude users trust from content they dismiss: acknowledging what doesn’t work. Every tool, framework, and approach has limitations. Content that documents those limitations honestly — “this approach breaks down when you exceed N concurrent connections” — earns Claude users’ respect and citation.
Claude’s Evolving Citation Landscape
As of mid-2026, Claude doesn’t have a native web search feature comparable to ChatGPT Search or Perplexity. But the content strategy still matters for several reasons:
Training data influence: Content widely published and linked is more likely to be included in Claude’s training data, influencing how Claude answers questions in your domain
Claude Projects and custom knowledge: Organizations upload content to Claude Projects as reference material. Being the content that organizations choose to upload is a form of citation
MCP integrations: Claude’s Model Context Protocol allows connecting to external data sources. As web search MCPs become standard, your content needs to be findable and structured for extraction
Claude Code references: Developers using Claude Code frequently reference documentation and guides. Being the go-to reference in your domain means Claude users paste your content into their sessions
Actionable Takeaways for Claude User Content
Write with trade-offs visible. Never hide downsides. Claude users trust content that acknowledges limitations and helps them decide, not content that sells them a conclusion
Structure content as decision frameworks. “How to choose” outperforms “the best” for this audience every time
Go deep on technical implementation. Surface-level overviews don’t serve builders. Include architecture context, code-level detail, and real-world constraints
Publish comparison matrices with honest assessments. No marketing-biased checkmark charts. Real evaluations that survive scrutiny
Write for the long context. Your content may be pasted alongside 100,000 other tokens. It needs to be information-dense and skimmable simultaneously
FAQ
What type of professional primarily uses Claude AI?
Claude’s user base skews heavily toward developers, engineers, analysts, technical writers, and business operators who integrate AI into workflows. These are builders who chose Claude for its long context window, nuanced reasoning, and willingness to acknowledge trade-offs rather than oversimplify.
How do Claude users differ from ChatGPT users?
Claude users are generally more technical and work with longer, more complex contexts. Where ChatGPT users explore and iterate conversationally, Claude users often paste large documents, codebases, or datasets and ask specific analytical questions. Claude users also expect trade-offs acknowledged rather than winners declared.
Does Claude have web search like ChatGPT?
As of mid-2026, Claude does not have a native web search feature comparable to ChatGPT Search. However, content strategy still matters through training data influence, Claude Projects knowledge uploads, MCP web integrations, and the practice of Claude Code users referencing and pasting authoritative content into their sessions.
What content format resonates most with Claude users?
Technical deep-dives with honest trade-off analysis, decision frameworks, architectural comparison matrices, and implementation guides with real-world context. Claude users are past the beginner stage and need content matching their level of sophistication.
How should I structure content for potential Claude training data inclusion?
Publish authoritative, widely-linked, information-dense content with clear structure, honest assessments, and specific technical detail. Content that becomes a go-to reference in its domain — cited by other publications and linked from documentation — has the highest probability of influencing Claude’s training knowledge.
ChatGPT has the largest user base of any AI platform — and that’s precisely why “optimize for ChatGPT” is almost meaningless without understanding which ChatGPT user you’re targeting. The person using ChatGPT to debug Python code is not the same person using it to plan a vacation. But they share behavioral patterns that distinguish them from users on every other AI platform.
ChatGPT’s user base is the most diverse of any AI platform. But within that diversity, the users who drive citations — the ones whose queries pull from your content via ChatGPT Search — share distinct characteristics:
Explorers: People who start with a vague idea and refine it through conversation. “I’m thinking about starting a business in X, what should I consider?” → follow-up → follow-up → specific question about licensing
Creators: Writers, designers, marketers, developers who use ChatGPT as a collaborator. They paste drafts and ask for feedback. They generate options and iterate
Problem-solvers: Developers debugging code, analysts working through data questions, students solving problems. They paste error messages and expect specific fixes
Researchers: Overlaps with Perplexity, but less rigorous. ChatGPT users accept answers with less source scrutiny. They want understanding, not verification
The common thread: ChatGPT users have conversations. They don’t ask a single question and leave. They iterate. This changes what content gets cited because ChatGPT’s retrieval happens in the context of an evolving conversation, not a single query.
How ChatGPT Users Search (Conversational Iteration)
The Follow-Up Chain
A Perplexity user asks one comprehensive question. A Google user asks one short question. A ChatGPT user asks a chain of 3-7 questions, each building on the previous answer. The first question is often broad (“Tell me about content marketing for SaaS companies”), and by the fifth question it’s specific (“What’s the best way to structure a comparison page for two competing SaaS products targeting enterprise buyers?”).
The content that gets cited is the content that answers the specific later questions, not the broad initial one. ChatGPT’s search triggers when it needs factual grounding for a specific claim — and those claims emerge later in the conversation when the user has narrowed their focus.
Code and Technical Paste-Ins
A significant portion of ChatGPT queries involve pasted code, error messages, configuration files, or technical output. When the user pastes a Kubernetes error log and asks “what’s wrong here?”, ChatGPT may search for documentation about that specific error code. Technical documentation, troubleshooting guides, and error-code-specific content gets cited heavily through this path.
Creative Brainstorming Queries
ChatGPT users frequently use the platform for ideation: “Give me 10 angles for a blog post about AI in healthcare.” These queries generate citations from content that provides frameworks, lists of considerations, and thought-provoking analysis. The cited content isn’t answering a factual question — it’s providing structure for creative thinking.
What Content Wins on ChatGPT
What content wins on ChatGPT.
Deep Technical Guides
ChatGPT’s search feature (powered by Bing) activates when the model needs factual support for technical claims. In-depth technical guides — with code examples, architecture diagrams described in text, and specific implementation details — get cited when users ask technical questions. Superficial overviews lose to competitors with genuine technical depth.
Tutorials with Working Examples
The paste-and-debug workflow means ChatGPT users value content with actual code samples, configuration examples, and step-by-step tutorials that produce working results. Content that says “configure your settings appropriately” loses to content that shows the exact configuration with explanations of each parameter.
Thought-Provoking Analysis
For non-technical queries, ChatGPT cites content that provides analytical frameworks. Articles that pose questions, present trade-offs, and explore nuances outperform articles that give simple answers. The ChatGPT user is in exploration mode — they want content that generates further questions, not content that ends the conversation.
Comprehensive How-To Content
Unlike Copilot (which wants quick answers) or Google AI Overviews (which wants the first paragraph), ChatGPT cites comprehensive content and extracts the relevant section. A 3,000-word guide gets cited for a single paragraph that answers the user’s specific sub-question. This means comprehensive content has more citation surface area — more chances for different queries to land on different sections.
ChatGPT Search vs ChatGPT Training
It’s important to distinguish between content that ChatGPT “knows” from its training data and content it cites via search. Training knowledge is static — content published before the training cutoff may be referenced without citation. But ChatGPT Search (the Bing-powered feature) actively searches the web and provides citations. Your optimization strategy should target both:
For search citations: Ensure Bing indexing, use structured data, publish frequently updated content on trending topics
For training influence: Publish authoritative, widely-linked content that’s likely to be included in future training data. This is a longer-term play with less measurable impact but significant brand positioning value
Actionable Takeaways for ChatGPT Optimization
Actionable takeaways for ChatGPT optimization.
Write content that answers the fifth question, not the first. ChatGPT users iterate. Your content should target the specific, narrowed-down queries that emerge later in conversations
Include working code examples and specific configurations. The paste-and-debug workflow drives heavy citation traffic for technical content
Provide analytical frameworks, not just answers. ChatGPT users want to explore. Content that opens new lines of thinking gets cited more than content that closes them
Maximize citation surface area. Comprehensive, well-sectioned articles give ChatGPT more extractable chunks to cite across different query types
Index with Bing and update frequently. ChatGPT Search uses Bing. Same infrastructure requirement as Copilot, different content strategy
FAQ
What makes ChatGPT users different from other AI search users?
ChatGPT users have conversations — they iterate through 3-7 questions per session, each building on the previous answer. This conversational pattern means content gets cited for answering specific, narrowed-down sub-questions rather than broad initial queries.
Does ChatGPT use Google or Bing for its search citations?
ChatGPT Search is powered by Bing’s index, not Google’s. Content needs to be indexed by Bing and submitted through Bing Webmaster Tools to be eligible for ChatGPT search citations. The OAI-SearchBot crawler also directly indexes content for ChatGPT.
What content format performs best for ChatGPT citations?
Deep technical guides with working code examples, comprehensive tutorials, and analytical content that provides frameworks for thinking. ChatGPT extracts specific relevant sections from long-form content, so comprehensive articles have more citation surface area than short posts.
How is ChatGPT citation different from ChatGPT training data?
Training data is static knowledge from before the model’s cutoff date — referenced without citation. Search citations come from Bing-powered real-time web search and include visible source links. Your strategy should target both: current indexed content for search citations and authoritative, widely-linked content for training influence.
Should I write differently for ChatGPT than for Perplexity?
Yes. Perplexity users want comprehensive research with citations they can verify. ChatGPT users want explorative content that generates further questions and provides analytical frameworks. Perplexity rewards primary data and methodology; ChatGPT rewards depth, examples, and thought-provoking analysis.