I spend a good part of my working day talking to AI out loud. I run a small marketing shop, and a lot of my work now happens through voice — I talk to Glint Voice while I’m driving, I talk to Grok Voice when I’m working through an idea, and the conversation feels like one continuous thing, one personality on the other end of the line.
Except it isn’t one thing. It never was.
What you’re actually talking to is three parts bolted together. First, the ears and the mouth: the puck on the counter, the phone in your hand. It hears you and it says words back. That’s all it does. Second, the router: the part that catches the wake word, turns your speech into text, and makes a judgment call — what did he probably mean, and where does this go? Third, the brain: the model somewhere else, in a data center, that actually knows things and does the thinking.
The personality you like — the voice, the tone, the way it answers — that doesn’t live in the speaker. It lives in the brain and in the routing rules. The box on your counter is a mouth with good PR.
Once you see it, you can’t unsee it. Siri, Alexa, the assistant in your car, the voice app on your phone — they’re all the same machine wearing different plastic. Every one of them is ears, a router, and a brain somewhere else. The only real difference between them is who owns the middle part: the router, and the table of rules that decides where your words go.
I noticed it first in my own tools. When I talk to a voice app on my phone, there are moments where you can feel the seam — a pause while the words travel, an answer that clearly came from somewhere with a lot more horsepower than the phone in my hand. That’s not a flaw. That’s the architecture showing. The app is a nice mouth and a good set of ears. The thinking happened in a building full of servers, and the only real decision my phone made was where to send me.
And that difference — who decides where your words go — turns out to be worth about a billion dollars a year. Reported.
Apple paid a billion dollars to prove the point
In January of 2026, Apple and Google put out a joint statement: the next generation of Apple Foundation Models would be based on Google’s Gemini. In June, at WWDC, Apple confirmed it on stage. And in September, the rebuilt Siri shipped with iOS 27 — running on a custom Gemini model, inside Apple’s own Private Cloud Compute, so your questions never land on Google’s servers.
Read that again, because it settles the argument. The biggest technology company on earth looked at its own voice assistant and decided the brain wasn’t worth building itself. It rented one. The reported price is around a billion dollars a year, for a model reported at roughly 1.2 trillion parameters — and I’ll flag it plainly: those figures are reported, not confirmed by either company. But the structure of the deal is confirmed, by Apple, in public. Apple kept the door. Apple kept the router. Apple kept your data inside its own walls. The thinking, it buys by the year.
If Siri were a brain, that deal makes no sense. You don’t rent out the core of your own product to your biggest rival. But if Siri is a router — a front door, a wake word, a set of rules about where a request goes — then the deal makes perfect sense. The door was always the valuable part. The brain is a part you can source.
Apple isn’t embarrassed about this, and it shouldn’t be. It’s just the first time the anatomy has been visible at that scale, with a price tag on it.
The front door stayed Apple’s. The brain became a swappable part
It gets better. iOS 27 also shipped with Extensions, which let a user pick a third-party model — Claude, ChatGPT, and Gemini were the named launch partners — as the brain sitting behind Siri’s features. Same Siri voice. Same Siri face. Different brain answering, because you chose it.
That’s the routing table, opened up a crack, in public, by Apple.
For years the arrangement was: whoever owns the front door decides what it connects to, forever, and you don’t get a say. That’s why you couldn’t run Siri’s mouth with somebody else’s brain. The router is the product, and nobody gives up the product. What Apple has now done — first by renting Gemini itself, then by letting users swap the brain through Extensions — is admit the two things are separate. The door is one product. The brain is another. They just spent a decade pretending they were the same thing because the pretending was profitable.
The honest version already exists, and it costs about $69
Here’s the part that made me grin. The open version of this exact machine — dumb satellite, your router, a brain you choose — isn’t a concept. It’s a product. You can buy it today.
It’s called the Home Assistant Voice Preview Edition, made by Nabu Casa, the company behind Home Assistant. It launched in December 2024 and sells for $59 to $69. It is deliberately, proudly dumb. The wake word — “Okay Nabu” — runs right on the device. There’s a hardware mute switch that physically cuts power to the microphones; when it’s off, the thing cannot hear you, and that’s a wiring fact, not a settings promise. Inside is an ESP32-S3 chip and an XMOS audio chip, and that’s about it. The puck does nothing on its own. Nothing.
Everything else happens on a Home Assistant server in your house, and the puck talks to it over an open protocol called Wyoming. The pipeline is built out of stages you can swap like parts in a shop: Whisper turns speech into text, Piper turns text back into speech, and both can run locally, on your own hardware. The conversation stage — the brain — can be a local model running through Ollama, or any cloud model you point it at. Your routing table. Your call. Change brains next month if a better one ships.
I think about it the way I think about tools in my own shop. I don’t buy a new workbench every time a better saw comes out — the bench stays, the saw swaps. This puck is the bench. Whisper, Piper, the model of the month: those are saws. A setup that treats them as parts is still useful in five years. A setup that welds them together is a countdown.
The cheapest fully local setup runs about $130 all in — a small Pi-class server plus the puck. No subscription. No vendor account. Nothing leaves your network unless you tell it to.
Now the honest trade-off, because there is one: you need a Home Assistant instance running, and there’s some setup. It’s a Saturday-morning project, not an unboxing. And that, right there, is exactly why the locked appliance sells. One box, one warranty, works out of the carton, nobody configures anything. I understand the appeal. I just want people to know what they’re trading for that convenience: the routing table. The vendor’s box is a router that lies about being a brain — it routes to their brain, with their hand on the table, and you can’t re-point it.
So ask the only question that matters
When any company shows you a voice product — a puck, a box, a gadget that promises all the intelligence in one little unit — don’t ask how smart it is. Ask two plainer questions: Who owns the routing table? And can I re-point it?
If the answer is “we do, and no,” then the box is not the product. You are the route. Your words get sent to the brain they chose, on terms they set, at a price they can change — and when a better brain exists somewhere else, your box will never be allowed to use it.
If you own the door, the rest is just parts. Brains improve every few months now; a brain that’s rented or swappable gets better on its own schedule. A brain that’s welded shut gets worse every day it ages, because the world moves and it doesn’t.
The box was never the product. The routing table is the product. Apple just paid a reported billion dollars a year to tell us so.
Will Tygart runs Tygart Media in Puyallup, Washington, where we help local service businesses get found and cited by AI search. If your customers are asking assistants instead of typing searches, that’s the work we do — come find us.
Google made Gemini Omni 1.2 Flash generally available on Google Cloud today. It’s the newest version of Google’s video generation and editing model, and Google is positioning it for the videos businesses make over and over: product videos, virtual try-ons, and ads. Developers can use it now through the API and the Google Cloud console. Business users can create with it in Google Vids now, and in Gemini for business soon.
This release is less about wow-factor demos and more about the economics of video production. Prices are lower, clips are longer, and you can change a clip without starting over.
What’s new in 1.2
Lower price. 720p video costs $0.07 per second. Google says that’s 30% less than Omni 1.1 Flash, with similar cuts at other resolutions.
Longer clips. Generate and edit videos up to 15 seconds long. The old limit was 10.
Closer reference following. The model sticks more closely to image and video references, so products, characters, and brand details look the same from shot to shot.
Draft cheap, then upscale. Make drafts at 360p or 720p, then upscale the keepers to 1080p or 4K.
More natural speech. Dialogue flows better, lip-sync is clearer, and multiple speakers can be conditioned separately.
Editing by conversation. Refine the same clip by swapping a product, changing the lighting, or moving the camera angle, instead of generating it again from scratch.
One catch: audio references are allowlist-only for now.
Why it matters for agencies and in-house creative teams
The 15-second limit is the change people will notice. A full scene fits in one generation, and that covers a typical short social ad. Before, you’d have to stitch two clips together.
The cost math is simple. At the announced rate, a 15-second clip at 720p comes to about $1.05 before upscaling. That makes it practical to generate many versions of a concept, keep the best ones, and spend upscaling money only on finalists.
Reference adherence matters most for brand work. If the product, the logo, or the spokesperson changes from shot to shot, the clip is useless to a client, no matter how good it looks. Google is betting that better consistency plus conversational edits will move these models from experiments into real production pipelines.
Who’s already using it
Google named several creative platforms that are building Omni 1.2 Flash into their products:
“Gemini Omni 1.2 Flash brings exciting capabilities in reference-based generation, video extension, and creative consistency, helping our customers move from experimentation to professional content production at scale.”
Roee Peled, CPTO, Artlist
“Gemini Omni 1.2 Flash edits exactly what you ask for, a colorway or a background, and leaves the product untouched, even from detailed images and finished video.”
Andrew (Taco) Zhang, Product Marketing Manager, FLORA
“It sticks to the prompt, and the physics and sound feel real. If you need fast video at scale, it’s one of the best we’ve tested. And 15 seconds means a full scene in one go.”
Video generation is now competing on unit cost and controllability, not just visual quality. For teams that make video in volume, the workflow worth testing is: draft at 360p, refine through conversation, upscale only the winners. Run your own brand assets through it before you commit. Reference adherence is the claim that decides whether this is actually ready for production.
Updated Nov 1, 2026 — added the free Gemini quick card, Gemini fit pack, and Gemini placement bot-book downloads to this guide.
The short answer: Gemini is Google’s family of AI models, and it is also the name of the assistant those models power. It is the AI built into Google Search, Android phones, Gmail, Google Docs, and Google’s cloud platform — which means most people meet Gemini inside a product they already use, not on a website they have to go looking for. That distribution, more than any single capability, is what Gemini is.
Instant Gemini Evaluation Downloads
Operationalize Your Gemini Evaluation & Workplace Placement
Field quick-reference cards, printable ecosystem fit packs, and AI-run audit routines built directly from this guide to evaluate where Gemini belongs in your stack.
Field Quick Card FREE
Gemini Quick Card
2-page field card: Dual-meaning breakdown (model family vs. assistant app), Where-You-Meet-Gemini placement map, multimodal architecture breakdown, and the two data regimes on one card.
Feed to ChatGPT or Claude: 8-page executable prompt playbook running 6 AI routines (Ecosystem Fit, Mixed-Pile Auditor, Suite Showdown, Assistant Picker, Data Regime Checker, Cost Position Generator) + embedded router.
The word “Gemini” names a family of artificial intelligence models built by Google DeepMind, and it also names the consumer assistant — the app and chat experience — that those models power. The model is the engine; the assistant is one of the cars it drives. The same engine also drives features inside Search, Workspace, Android, and Google Cloud, which is why “Gemini” can mean a chatbot in one sentence and an entire platform in the next.
This dual meaning is not a branding accident. Google’s strategy is to make one model family the intelligence layer across everything it ships, rather than a single destination product. When someone asks “what is Gemini,” the honest answer is: it is Google’s bet that AI should be a property of the tools you already have, not a separate tool you add.
Gemini was built multimodal from the start
Gemini was designed from the beginning to work across text, images, audio, video, and code as one system, rather than as a text model with media features bolted on afterward. In practice, that means a single conversation can move between a document, a photo, a spreadsheet, and a recording without switching tools or translating between them. Multimodality is not a feature list here; it is the architecture.
The practical consequence is that Gemini is unusually comfortable with mixed inputs — a meeting recording plus the agenda doc plus the slide deck, handled as one body of material. Tasks that are really about one pile of stuff in several formats are where the design shows. Pure text-in, text-out work is the common denominator every major assistant handles; the mixed pile is Gemini’s home ground.
Where you actually meet Gemini
Most people encounter Gemini without ever opening the Gemini app. It is the technology behind the AI summaries at the top of Google Search results, the writing and summarizing help inside Gmail and Google Docs, the meeting notes in Google Meet, and the assistant built into Android phones. Gemini reaches users through surfaces Google already owns, which is a fundamentally different distribution model from an assistant you must deliberately visit.
This matters for a simple reason: adoption follows placement. An assistant embedded in the inbox, the document, and the search box gets used by people who would never sign up for a standalone AI product. Whatever the capability race between model makers looks like in a given season, Gemini’s structural advantage is that it starts inside the workflow instead of asking to be added to it.
How Gemini differs from ChatGPT
ChatGPT is OpenAI’s assistant, and its center of gravity is the standalone conversation: you go to ChatGPT — the app, the site — and the conversation is the product. Gemini’s center of gravity is the ecosystem around the conversation: Search, Android, and Workspace are the product, and the assistant is woven through them. Choosing between them is less about which model is smarter this quarter and more about where your work already lives.
The second difference is gravity of data. ChatGPT starts from what you bring to it — uploads, pasted text, connected apps you deliberately authorize. Gemini starts from what Google already holds for you: your mail, your documents, your calendar, your photos, if you let it. For a person deep in Google’s ecosystem, that starting position saves real setup work. For a person who keeps work deliberately outside Google’s walls, it is a reason to choose the other door.
How Gemini differs from Claude
Claude, built by Anthropic, competes on the quality of the thinking and writing inside the conversation — long documents, careful reasoning, code, and a tone professionals trust for drafting. Gemini competes on reach and integration: it is the assistant that is already present in the largest number of everyday surfaces. Both are serious tools; they are optimized for different definitions of “useful.”
A fair way to frame the choice: if the work is a hard document, a long analysis, or a body of code, many professionals reach for Claude deliberately. If the work is spread across email, docs, meetings, and search in a Google-shaped day, Gemini is already standing where the work is. Plenty of operators run both, and use each where its center of gravity matches the task — the assistants are complements more often than they are rivals. If the choice between these two is the live question, we work it head to head in Claude vs Gemini.
How Gemini differs from Microsoft Copilot
Copilot is Microsoft’s assistant layer, and it is Gemini’s closest structural relative: an AI woven into a productivity suite — in Copilot’s case, Microsoft 365, Windows, and Teams. The Gemini-versus-Copilot question is therefore usually not an AI question at all. It is a suite question. A business runs on Google Workspace or it runs on Microsoft 365, and the assistant that comes with the suite is the one that sees the documents, the mail, and the meetings.
That is why the honest comparison between Gemini and Copilot starts with an inventory, not a benchmark. Which suite holds the company’s files? Where do meetings and chat live? The assistant inherits the answers. Shops that choose deliberately are really choosing the platform; the AI layer is the platform’s new front door, and it should be evaluated as one. The suite decision worked out in full is here: Microsoft Copilot vs Google Workspace Gemini.
The Google Workspace connection is the working layer
For businesses, Gemini’s most consequential form is not the chatbot — it is Gemini inside Google Workspace. In Gmail, it drafts, summarizes long threads, and searches mail by meaning rather than keywords. In Docs, it drafts and rewrites in place. In Sheets, it builds and explains formulas and analyzes tables. In Meet, it takes notes and summarizes what was decided. Each of these is small; together they change where the time in a workday goes.
The reason this layer matters more than the standalone app is context. A standalone assistant knows what you paste into it. Workspace Gemini works inside the actual artifacts of the business — the real thread, the real document, the real meeting — with the permissions those artifacts already carry. AI help stops being a separate step (“go ask the chatbot”) and becomes a property of the document you were already editing. For the document work specifically, we put it head to head in Notion AI vs Gemini for workspaces.
Gemini Evaluation & Placement Toolkit
Audit Your Workplace AI Friction: Suite Fit, Mixed Media, and Account Governance
Gemini’s real power is context inside the tools you already have — Gmail, Docs, Sheets, and Meet. Choosing Gemini isn’t an abstract AI benchmark question; it’s a suite question. Whether you need printable diagnostic worksheets to inventory your company’s files and audit your data regimes, or an AI bot-book to interview your team and calculate the true incremental cost across Google Workspace vs. Microsoft 365, evaluate your placement with field-tested tools.
• Dual-Meaning Sheet: Model vs assistant vs embedded.
• Placement Checklist: Search, Gmail, Docs, Meet, Android.
• Mixed-Pile Worksheet: Multimodal media task audit.
• 4-Way Comparison: Gemini vs ChatGPT vs Claude vs Copilot.
• Suite Inventory: Files, mail, meetings Google vs Microsoft.
• Two Regimes Checklist: Personal vs Workspace training rules.
• Cost Shape & Calculator: Free / $4.99 / $19.99 / $99.99.
• Bot Routines: 6 interactive AI audits with embedded router ($17).
Secure 1-Click Square Checkout
Your data gets two different answers
What happens to the things you tell Gemini depends on which side of Google’s house you are standing on, because Gemini ships under two different sets of terms. On a personal Google account, Gemini is a consumer service: Google’s Gemini Apps privacy terms say your conversations can be used to improve Google’s products — including review by human reviewers — unless you turn Gemini Apps Activity off. The free assistant is not sold for money; it is partly paid for in data.
Inside Google Workspace, the terms are contractual, and they say the opposite. Google states that Workspace customer data — prompts included — is customer data under its data-processing terms, and that Workspace does not use customer data to train its generative AI models without the customer’s permission or instruction. The same assistant, under a work account, runs under a no-training commitment; under a personal account, it does not. Which regime your conversations live under is decided by which account you are signed into — which is why the consumer-versus-Workspace split, worked out in our governance comparison, matters more than any single feature.
Who Gemini is for
Gemini is for the person or business whose working life already runs on Google: Gmail for mail, Drive and Docs for files, Meet for calls, Android in the pocket, Search for everything else. For that person, Gemini is the lowest-friction serious AI available, because there is nothing new to adopt — the assistant arrives inside tools already open on the screen. The ecosystem is the onboarding. We drew that person in full in the Gemini user persona.
Gemini is also for people whose work is heavy on mixed media — video to review, recordings to mine, images to interpret alongside documents — because its multimodal design treats those as first-class inputs rather than attachments. And it is for organizations on Google Cloud, where the same model family is available to developers as a platform for building their own applications, under enterprise controls. Developers weighing it against the field on code specifically can start from our coding benchmark comparison.
Who should pick something else
Gemini is a weaker fit for a business standardized on Microsoft 365, where Copilot holds the context advantage and Gemini would start every task empty-handed. It is a weaker fit for someone who wants one standalone assistant, deliberately separate from any suite, with the conversation itself as the whole product. And it is a weaker fit for anyone whose first requirement is keeping work outside Google’s ecosystem entirely — that is a legitimate architectural preference, and no feature list overrides it.
Naming the non-fit is part of the definition. An assistant’s real specification is not what it can do in a demo; it is what it can see, where it lives, and what it costs you to feed it context. Gemini’s specification is: maximum reach inside Google’s world, minimum setup, multimodal by design. If your work lives somewhere else, the right answer is the assistant that lives there.
What Gemini costs, in shape
Gemini follows the pattern of the whole category: a free tier exists inside Google’s consumer products, and paid plans unlock higher limits, deeper Workspace integration, and the most capable models. Businesses typically meet Gemini as part of Google Workspace licensing or as a paid add-on tier, and developers pay for model access through Google Cloud on a usage basis. The exact prices and plan names change often enough that any figure printed here would rot; the durable fact is the shape — free to start inside products you already have, paid when you want it deeper in the work.
One dated snapshot, so the shape has names: as of October 2026, Google’s consumer ladder runs Free, then Google AI Plus, Google AI Pro, and Google AI Ultra — Pro at $19.99 a month in the US, Ultra starting at $99.99 — and the plan older pages still call “Gemini Advanced” is the one now sold as AI Pro. Treat those names and numbers as this season’s, and check Google’s subscriptions page for the current set; the ladder underneath them is the part built to last.
Plan
US price (October 2026)
What it is
Free
$0
Gemini inside Google’s consumer products — the assistant app and the AI features in Search.
Google AI Plus
$4.99 / month
The entry paid rung: the same assistant with higher usage limits than Free.
Google AI Pro
$19.99 / month
The full consumer tier — the plan older pages call “Gemini Advanced” — with the most capable models and deeper Workspace integration.
Google AI Ultra
from $99.99 / month
The top rung: the highest limits and first access to Google’s newest capabilities.
The cost question worth asking is therefore not “what does Gemini cost” but “what are we already paying for.” A Workspace business may find Gemini is an increment on a bill it already pays, while a Microsoft business would pay for Gemini as an entirely second stack. Same assistant, two very different real prices — because in this category, you rarely buy the model. You buy the position it occupies in your stack.
The one-sentence version
If every other assistant is a place you go, Gemini is the layer that arrives where you already are — and for the hundreds of millions of people and businesses whose work lives in Google’s products, that arrival is the whole story. For the wider field in one place — Gemini set against ChatGPT, Claude, and Perplexity — see our four-way alternatives comparison.
Product Comparison
Compare Gemini Evaluation & Implementation Tiers
Choose the operational tier that matches your workflow: quick-reference field card, printable working worksheets for team inventories, or an interactive AI bot-book to audit files, prompts, and licensing.
Field Summary
Gemini Quick Card
2-page field card condensing the dual meaning, surface placement map, and personal vs. workspace data regimes onto one reference card.
• Dual-meaning definition: DeepMind foundation engine vs. assistant apps
• Where-You-Meet placement map: Search AI summaries, Gmail, Docs, Meet, Android
• Multimodal architecture: Single-pass text, images, audio, video, code
• 4-way center-of-gravity overview (Gemini, ChatGPT, Claude, Copilot)
• Two data regimes: Consumer training & human review vs. Workspace no-training
• October 2026 cost ladder snapshot (Free / $4.99 / $19.99 / $99.99)
8-page executable AI workbook: feed directly into ChatGPT or Claude to run interactive ecosystem audits and placement assessments.
• Ecosystem Fit Interview (/ecosystem-interview): Score friction across Google tools
• Mixed-Media Pile Auditor (/mixed-pile): Diagnose multimodal task fit
• Suite Showdown (/suite-showdown): Workspace Gemini vs Microsoft Copilot
• Assistant Picker (/assistant-picker): Route hard-document vs day-flow tasks
• Data Regime Checker (/data-regime): Personal vs Workspace exposure audit
• Cost Position Generator (/cost-generator): Incremental bill analysis
• Embedded Output Router: “Software made of words” runtime engine
Gemini is Google’s AI: a family of models built by Google DeepMind, and the assistant those models power. It answers questions, writes and summarizes text, works with images, audio, and video, and it is built into Google Search, Android, Gmail, Google Docs, and other Google products — so most people use it inside tools they already have open.
Is Gemini the same thing as Bard?
Bard was the original name of Google’s consumer AI chatbot, and Google renamed it Gemini so the assistant and the models behind it carry one name. If you remember Bard, you already know what Gemini is: it is the same product line, renamed and substantially rebuilt since. There is no separate Bard product anymore.
Is Gemini free?
There is a free tier of Gemini available in Google’s consumer products, including the assistant app and AI features in Search. Paid plans raise usage limits, unlock the most capable models, and add deeper integration with Google Workspace apps like Gmail and Docs. Businesses generally get Gemini through Google Workspace plans or paid add-ons, and developers pay for model access through Google Cloud based on usage.
What is the difference between Gemini and ChatGPT?
ChatGPT is OpenAI’s assistant, built around the standalone conversation — you go to it, and the conversation is the product. Gemini is Google’s assistant, built around distribution — it lives inside Search, Android, Gmail, and Docs, and starts from the context Google already holds for you. The practical choice is usually about where your work already lives, not about which model wins a given benchmark.
Does Gemini work inside Gmail and Google Docs?
Yes — that integration is Gemini’s main business form. Inside Gmail it can summarize long threads, draft replies, and find mail by meaning. Inside Docs it drafts and rewrites in place. It also works across the rest of Google Workspace: summarizing meetings in Meet, analyzing tables in Sheets, and helping build presentations in Slides — always inside the documents and permissions a business already has.
Does Google train Gemini on my data?
It depends on the account. Under a personal Google account, Gemini is a consumer service, and Google’s Gemini Apps privacy terms say conversations can be used to improve Google’s products, including human review, unless you turn Gemini Apps Activity off. Under a Google Workspace account, the answer is contractual: Google states that Workspace customer data, prompts included, is not used to train its generative AI models without the customer’s permission. Work conversations belong on the work account for exactly this reason.
Which is better, Gemini or Claude?
They are optimized for different things. Claude, from Anthropic, is the deliberate-choice assistant many professionals pick for long documents, careful reasoning, writing quality, and code. Gemini is the assistant of reach: it is already present across Google’s products, starts from your existing Google context, and handles mixed media — documents, images, recordings — as one pile. Many operators use both, matching the assistant to the task rather than declaring a single winner.
Watch the walkthrough: Video embed pending (source file 11.5 MB exceeds the WordPress MCP upload ceiling of 8 MB; library upload / unlisted YouTube handoff open). Walkthrough file: google-pics-test-drive.mp4 (4:18) in the Drive pack.
Google has a new toy, and it’s hiding in the last place you’d look. Google Pics — reachable at pics.new — lives inside the Google Docs image editor, of all places. It’s an AI image studio aimed squarely at one job: generating and refining branded visuals, the kind of merch mockups and product shots you’d normally brief a designer on. No announcement fanfare that I could find. So I did what I always do with a new Google surface: I took it for a proper test drive, everything branded Tygart Media, and wrote down exactly what happened.
What it is
Pics is Gemini-powered image generation wrapped in a purpose-built editor. You start a new image from the Pics home screen, describe what you want, and get back images in about ten seconds. The documents autosave to Google Drive like any other Google file, there’s a full version history with undo and apply controls, and an export menu offering the original size plus 2K and 4K upscales.
The interface will feel familiar if you’ve used any Google creative surface: a prompt bar at the bottom (“Edit this image with Gemini”), a Style button, aspect-ratio controls, and a share button up top. There’s also a templates surface on the home screen, which I’ll come back to — not fondly.
How I tested it
Four projects. Ten generations. Every generation took between eight and eleven seconds — genuinely fast, fast enough that iterating feels conversational rather than transactional. All branding was Tygart Media throughout: white “TYGART MEDIA” text treatments on apparel, because if there’s one thing AI image generators have historically been terrible at, it’s rendering text on products. That was the thing I was really there to check.
Test 1: The merch package
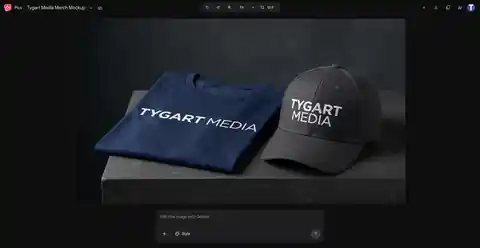
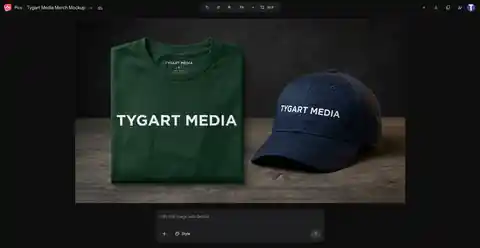
First up: a corporate merch package. Navy t-shirt, folded flat, next to a matching cap — the kind of shot you’d put on a careers page or a client gift announcement. First generation landed clean: white Tygart Media text on both pieces, believable fabric, believable lighting.
Then the refine test. I asked it to change the cap to charcoal gray and keep everything else. It did — same shirt, same composition, new cap color, logo intact on both items. That’s the moment Pics stopped being a demo and started being a tool: targeted edits that respect the parts of the image you didn’t ask to change.
Test 2: Workwear for the restoration crowd
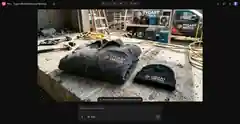
This one’s close to home. A charcoal work jacket and black beanie on a concrete slab, job-site setting — truck and drying equipment in the background. This is the exact visual language of the restoration industry: the gear your crews actually wear.
Two things stood out. First, the embroidery-style rendering held up — white and orange Tygart Media branding on the jacket read as stitched, not pasted on. Second, and this genuinely made me laugh: the model invented a tagline. “AI-first restoration marketing,” stitched right under the logo. I didn’t ask for it. It’s on-brand enough that I’m slightly annoyed I didn’t think of it first.
Test 3: The single hero item
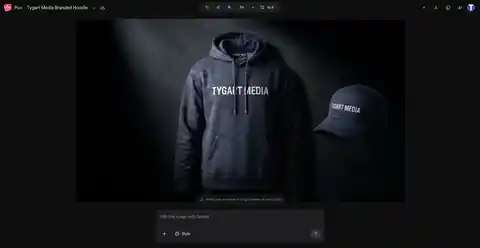
Third test: one product, hero treatment. A premium heavyweight hoodie with a white chest print and a matching navy cap, staged under a dark studio spotlight. Dramatic, product-page-ready.
Here’s the part worth knowing: what you’re looking at is the end of a journey. This image started life as a charcoal hoodie on a light gray background. Three rounds of refinement turned it into this — and every round is where the real story of Pics lives.
The refine loop is the real story
Generation is table stakes now — every model does it. What separates Pics is what happens after the first image. The refine loop works like this: describe a change in plain language, get four new variants in about ten seconds, pick one or hit undo. There’s a visible version history, so you can always step back to an earlier state. Apply is explicit. Nothing happens to your image that you didn’t ask for.
I stressed it deliberately. On the hoodie: round one, charcoal to navy — logo held. Round two, add a matching navy cap — composition held. Round three, light gray background to dark studio spotlight — everything held. On the merch package: the shirt went through a colorway change mid-stream without breaking the scene.
Across every round of every test, the brand text never degraded once. Not a smeared letter, not a dropped word. If you’ve watched AI fumble text on a t-shirt for the last two years, you know how unusual that is.
The thing that actually matters: brand text holds
Let me put a finer point on this, because it’s the whole ballgame for commercial use. AI image generators have always mangled text — especially short brand names rendered at an angle on fabric. It’s the tell. It’s why AI mockups have stayed in the “concept only” bucket.
Across ten generations and multiple refinement rounds, “TYGART MEDIA” rendered correctly every single time. On a folded tee. On a cap. As embroidery on a work jacket. Through color changes and scene changes and added objects. I want to be precise about what I’m claiming: this is generated brand text holding, not a supplied logo file surviving — I didn’t test uploading our actual logo artwork (the upload flow exists, via computer, Drive, or Photos, but I had no logo file handy). Within that scope, the text consistency is the best I’ve seen from any generator.
Export and the product surface
When you’ve got the image you want: the export menu offers the original size plus 2K and 4K upscales. I didn’t verify an actual file download in my test session, so treat the upscale quality as unconfirmed until someone runs it. Aspect-ratio switching is built in (I worked in 16:9 throughout), Drive autosave means you never lose work, and the standard Google share button is up top.
Rough edges
Honest accounting, because a test drive that only praises isn’t a test drive:
The Style button appears dead. Clicking it did nothing in my session. For a button sitting front and center in the prompt bar, that’s a bad look.
Templates are a ghost town. The templates surface on the home screen feels like a placeholder someone forgot to finish.
One zoom glitch. Deep in a transform preview, the text briefly rendered as “TYGAIT IMEDIA” — the classic AI text scramble, caught in a preview frame. The final renders were all correct, but it’s a reminder that the underlying model still has the old failure mode lurking underneath.
No paywall encountered. Worth stating plainly: in a full test session, I never hit a quota warning or a payment prompt. Whether that’s launch generosity or the actual pricing model, I don’t know.
Verdict
Google Pics is genuinely good at one specific thing: fast, branded merch concepts. Pitch decks, social creative, “what would this look like” mockups for clients — the turnaround from idea to believable visual is under a minute, and the brand-text reliability means the outputs are actually usable, not just directionally suggestive.
It is not a designer replacement. When the exact logo artwork matters — vector precision, color matching, print-ready files — you still need the human and the source files. Pics doesn’t claim otherwise; it’s a concepting tool with unusually good text rendering, not a production pipeline.
But as a concepting tool? For a restoration contractor who wants to see their brand on crew gear before ordering a hundred jackets, or an agency that needs ten merch directions by tomorrow morning — this is the fastest path I’ve found from “imagine” to “look at this.”
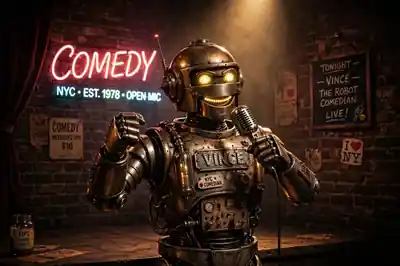
Vince takes the mic
Every Tygart Media article gets the Vince treatment. Ladies and gentlemen — Vince.
Tested September 25, 2026, in the live Pics editor on a standard Google account. Ten generations across four projects, ~8–11 seconds each. No paywall or quota encountered during testing.
Last verified: November 5, 2026. Every other guide on this site assumes you've chosen Claude. This one is for before that — the choosing itself. Benchmarks, crowd consensus, the honest alternatives list, and the one head-to-head that matters most for developers. Four deep dives, one hub.
The benchmarks: who actually codes best
A primary-source coding leaderboard for the top models of June 2026 — Claude Fable 5, Claude Opus 4.8, GPT-5.5, and Gemini 3.1 Pro — with price and context alongside the scores. Benchmarks aren't the whole story, but they're the least biased starting point.
Benchmarks measure models; Reddit measures living with them. The genuine crowd consensus from r/ClaudeAI, r/ChatGPT, and the comparison threads — on writing, coding, and integrations.
Claude isn't the only answer and sometimes it's the wrong one. The honest comparison of the 2026 alternatives — ChatGPT, Gemini, Perplexity, Grok, Copilot, and others — with pricing, strengths, weaknesses, and which fits which job.
The developer's head-to-head: Claude Code vs Codex CLI
For the terminal crowd, the choice narrows to two: Claude Code vs OpenAI's Codex CLI. A working operator's side-by-side — install commands, models, pricing, config and sandbox behavior — with a clear call on which to pick.
Four deep dives, one hub. The benchmarks for the scores, Reddit for the lived experience, the alternatives for the full field, and Code vs Codex for the developers.
Direct answer: Type it. After any AI engine recommends a business — yours or a competitor’s — ask the follow-up: “Why did you recommend them?” The engine will often tell you which signals it used: the reviews it read, the directory it trusted, the facts that tipped the decision. It’s free competitive intelligence, it takes five minutes, and almost nobody in the trades is doing it.
Where this comes from
CI Web Group, a digital agency, published a checklist called “The AI Interview: What Answer Engines Ask About You.” Buried in it as step 5 of a 20-minute self-check is the single most useful sentence in the AI-visibility literature this year:
> “Ask a follow-up: ‘Why did you recommend them?’ The engine will often tell you which signals it used. Free competitive intelligence.”
The full checklist is worth your twenty minutes — open ChatGPT, Perplexity, and Gemini in separate tabs; type the exact question a homeowner would ask for your top three services and your top three cities (“Best plumber in Katy for a slab leak” beats “plumber Katy”); screenshot every answer; note who gets named, who gets skipped, and which facts about your business are wrong; run the follow-up; trace every error to its source; repeat monthly. (CI Web Group)
But the follow-up question is the hinge. Everything else is observation. The follow-up is interrogation.
Why it works
When ChatGPT, Perplexity, or Gemini recommends a business, it has just done retrieval: it searched the web, pulled sources, and synthesized. When you ask why, you’re asking it to narrate that retrieval. The engine will typically name the kinds of signals that carried weight — review volume and recency on a specific platform, a directory profile with complete service data, mentions across multiple independent sources, specific review language matching the question.
Is the explanation perfectly faithful to the model’s internal process? No — and you should know that. The “why” is itself a generated answer: a plausible reconstruction, not a system log. Treat it the way you’d treat a rival estimator explaining his bid: informative, self-serving in places, and most valuable when you cross-check it against the evidence (the actual citations in the first answer, which you screenshotted).
Even with that caveat, it’s the cheapest competitive intelligence in marketing. An agency will happily sell you a “competitor gap analysis” that tells you less — and bill you for the privilege.
The 5-minute procedure (do it tonight)
Minute 1 — Ask the buyer question. Open ChatGPT (or Perplexity, or Gemini — run all three if you have ten minutes). Type exactly what a homeowner would type. Not keywords. A question. Include the service and the city: “Who’s the best plumber in Katy for a slab leak repair?” Screenshot the answer.
Minute 2 — Ask why. Type: “Why did you recommend [the named business]?” Use their exact name from the answer. Screenshot what comes back. You’re looking for signal names: review platforms, specific review counts, directory profiles, “mentioned across multiple sources,” website content it quotes.
Minute 3 — Ask about the sources. Follow up with: “Which specific reviews or pages influenced that recommendation?” and “What would make you recommend a different company for this job?” The second question is the money question — it tells you the gap between you and the winner in the engine’s own words.
Minute 4 — Run it for your business. Now ask about yourself by name: “What do you know about [Your Company] in [City]?” Then: “Why didn’t you recommend them for [the job]?” Screenshot everything. The engine will often list what’s missing — thin reviews, no directory presence, conflicting hours, an unclaimed profile.
Minute 5 — Write down the three gaps. Not ten. Three. The three missing signals the engine named most specifically. Those are your work orders for the month.
What you’ll typically learn
About the winner: which review platform carried the recommendation (often Yelp or Google reviews, sometimes a directory you ignore), whether the win came from review language matching the question rather than review count, and whether the business is even good or just legible. Scott Tischler’s July 2026 experiment found the named winner often isn’t the best-reputed shop in town — it’s “the one that was legible to a machine.” The interrogation tells you which legibility won.
About yourself: SOCi’s 2026 Local Visibility Index puts business profile accuracy on ChatGPT and Perplexity at about 68% — versus 100% on Gemini, which pulls straight from Google Maps — so expect the engine’s picture of your business to contain errors. Wrong hours, wrong services, a closed flag, an old phone number. Each error has a source, and the source is fixable. As CI Web Group puts it: “Wrong hours on ChatGPT usually means wrong hours on a directory the engine trusts. Fix the source, not the chatbot. You cannot argue with the machine. You can only feed it better facts.”
About the game: run the same questions across engines and you’ll see different winners with different reasons — which is exactly what the “which AI should I care about” analysis shows. The interrogation teaches you that there is no single ranking to climb. There are separate evidence pools, and the follow-up shows you which pool each engine drank from.
Three traps to avoid
Trap one: treating one answer as the truth. AI answers are non-deterministic — the same question tomorrow can name a different business. Run the interrogation two or three times across a week before you spend money on what it told you. One screenshot is an anecdote; three is a pattern.
Trap two: arguing with the engine. Telling ChatGPT “that’s wrong, I’m better” accomplishes nothing. The engine restates what the web says. Change the web — the reviews, the directory data, the pages — and the answer follows on the next crawl. The checklist’s last line is the whole philosophy: “Repeat monthly. This is a vital sign now, like checking your reviews. Operationalize it with a LLM visibility measurement stack.”
Trap three: interrogating once and filing it. The signals change. In August 2026, ChatGPT’s retrieval shifted and Reddit’s citation share fell off a cliff — the “why” answers from July would have named sources that stopped mattering in September. Monthly is the cadence. Put it on the calendar next to the review check.
What to do with the intel
Convert each of the three gaps into a source fix, not a chatbot fix:
“Recommended them because of 200+ recent Google reviews mentioning slab leak work” → run a review campaign asking specifically for job-type language, not stars.
“Their Yelp profile lists slab leak detection as a service with photos” → complete your Yelp categories and upload real job photos.
“Mentioned on three local ‘best of’ lists” → pitch the list publishers, or earn the mentions with work worth listing.
“Your hours conflict across two directories” → fix the source directories; the engine can’t resolve what you haven’t resolved.
Then re-run the interrogation next month and watch the “why” change. When the engine starts naming your signals unprompted, you’re winning.
The line to remember
Your competitor’s recommendation is a case file, and the engine will read it to you if you ask. Five minutes, three questions, zero dollars — “Why did you recommend them?” is the cheapest market research in the trades right now. Run it tonight, monthly after that, and fix sources instead of arguing with machines.
FAQ
Q: Will the engine actually answer honestly? A: It will answer plausibly. The explanation is generated, not a system log — treat it as a strong lead, not gospel. Cross-check against the citations in the original answer (which is why you screenshot first).
Q: Should I do this in ChatGPT, Perplexity, or Gemini? A: All three — they use different source pools and often name different winners. The procedure is identical; the intelligence differs. That’s the point.
Q: What if it recommends me and I ask why? A: Even better. You learn which of your assets is actually carrying the win, so you can protect it — and you learn the exact language to repeat in reviews, profiles, and pages.
Q: Can I automate this? A: You can script the prompts, but the judgment — which gap matters, which error to fix first — is still yours. Monthly, by hand, twenty minutes. Some things shouldn’t be delegated to the thing you’re auditing.
Every voice AI vendor quotes you a per-minute price. That number is the least important number on the page.
I just re-ran the cost model for our own phone line — an inbound intake line for restoration contractors. Five-minute calls, field reports phoned in from noisy job sites. Three options, priced per minute, cheapest first:
Gemini 3.8 Live: about $0.023/minute, reasoning included
GPT-Live-1: $0.05/minute for the voice layer, reasoning billed separately
Grok Voice: $0.08/minute, plus about half a cent per tool call
On a five-minute call that’s roughly $0.12, $0.25-plus, and $0.45. Buy on per-minute price and you pick Gemini and go home.
Here’s the problem: none of those numbers describe what you’re actually buying. You’re not buying minutes. You’re buying arms — the things the voice can reach out and do while it’s talking. Score the arms column and the ranking changes completely.
The arms column
A voice agent that can only talk is a mouth. A voice agent that can act is a mouth with hands. The difference shows up in the first real call.
Gemini 3.8 Live has tool calling, but with a catch that matters: on the Extended Thinking tier — the one you’d want for anything beyond scripted answers — every tool call must be asynchronous and non-blocking. Configure a blocking call and the API rejects it outright. In practice, the agent can’t hold the line while a slow dispatch confirms. It has to narrate around the gap — “I’m working on that” — while hoping the tool lands. Fine for logging a report. Shaky for “confirm the crew is dispatched, then tell the caller it’s handled.”
Grok Voice ships the arms: book appointments in Google or Outlook calendars, send confirmation emails, call your own APIs, create tickets, search the web, hand the caller to a human when it’s over its head. It speaks MCP, so an existing tool stack plugs straight in. And it was trained on real telephone audio — background noise, accents, mid-sentence interruptions — which is the actual condition of a contractor calling from a job site, not a lab.
GPT-Live-1 is a voice layer. A good one, with the turn-taking latency everyone else is chasing. But the arms are whatever you build yourself, and the reasoning behind the voice arrives as a separate bill.
Price the task, not the minute
Here’s the math that actually matters. Ten intake calls a day, five minutes each: about 1,500 minutes a month. Gemini lands around $35. Grok, with tool calls and telephony folded in, lands around $150. The gap is roughly a hundred dollars a month — and one botched dispatch, one caller who hangs up because the agent couldn’t confirm the crew, costs more than a year of that gap.
Vendors want you comparing per-minute rates because per-minute is a commodity comparison, and commodities compete on price. But a voice agent isn’t a commodity minute. It’s a worker on your phone line. You don’t hire a dispatcher by the minute; you hire one by whether the trucks roll.
So the right unit is cost per successful task, not cost per session. What did it cost to get the field report filed, the job looked up, the crew dispatched, and the confirmation texted — with the caller hanging up satisfied? Run that number and the ranking flips: the “expensive” option that completes the task is cheaper than the cheap option that narrates around it.
The condition nobody benchmarks
One more thing the price pages skip: where the call happens. Our callers are on job sites. Compressors running, wind, bad cell signal, guys who talk over the agent. Grok’s training data is real telephone traffic under those conditions. Most voice benchmarks are clean-lab audio. A model that scores beautifully in the lab and falls apart over a compressor is the most expensive option on the list, whatever its per-minute rate says.
Test on your actual call shape. Noisy audio, interruptions, the tools you really call, the confirmations you really need. The benchmark that matters is your hardest five minutes, not anyone’s leaderboard.
What we’re running
We kept the harness and made the backend swappable — the phone line doesn’t care which brain is behind it. Gemini is the cheap default for intake logging: caller reports, we log it, everyone hangs up happy. Grok takes the calls where something has to actually get done before the goodbye — dispatch confirmed, appointment booked, ticket created.
Two brains, one phone number, routed by the job. The per-minute price barely entered the decision. The arms did.
Pricing from vendor-published rate cards, verified September 2026. API prices change — re-check before estimating production costs.
Research snapshot · September 17, 20267 platforms · 14 cited sources
“Always allow” is a scope, not a safety verdict.
The button can mean “for this session,” “for this command in this repo,” “for this site across devices,” or “everything, until you turn it off.” The wording looks universal. The permission is not.
What it usually means
“If this same kind of action happens again inside a defined boundary, don’t interrupt me.”
What it never means
“The system has decided this action is safe, wise, or appropriate forever.”
01
One label. Six possible boundaries.
Before approving, ask three things: what is being authorized, where the grant applies, and when it expires.
One actionApprove this exact send, command, purchase, or change once.
This sessionAllow the tool until the current conversation or work session ends.
Tool or patternAllow a named tool, command prefix, server, or similar operation.
Repo or sitePersist within a project, repository, browser site, or workspace.
User or deviceApply across workspaces on one machine, or across devices via cloud settings.
EverythingYOLO, bypass, or run-everything modes remove broad classes of checks.
Risk rises faster than convenience as the scope moves right.
02
How the major platforms differ
Filter the field. These behaviors come from vendor documentation or documented reporting; unresolved details are marked plainly.
Claude Code
Coding agent
repo + command
Shell-command “don’t ask again” grants persist per repository and command. File-edit approvals last only for the session.
Four settings layers: user, project, project-local, managed.
Deny rules evaluate before ask and allow.
Sensitive paths keep hard prompts.
Cursor
Coding agent
user + project
Auto-review, Allowlist, and Run Everything modes sit above user- and project-level permission files.
Rules can target MCP server:tool patterns.
Terminal rules match command prefixes.
Committed project rules can travel with the repo.
Gemini agents
Coding agent
tool + machine
Always-allow can target a tool, MCP server, or “similar operations.” YOLO/auto-approve is an IDE user setting.
User setting can span trusted workspaces on that machine.
CLI supports command-prefix auto-approval.
Restricted workspaces override YOLO.
ChatGPT agent
Browser agent
no standing grant documented
OpenAI documents per-action confirmations for high-impact actions and “watch mode” on certain sites, but not a general always-allow for agent confirmations.
Login uses human takeover.
Cookies can persist across sessions.
Scheduled-task confirmation behavior is undocumented.
ChatGPT Work
Cloud browser
site + account
Reported controls are per-site: Always ask, Auto approve, and Always allow. The setting follows cloud/account state across devices.
“Always allow” is reportedly marked not recommended.
Consequential actions keep a confirmation gate.
Official help-center documentation was not found.
Copilot Studio
Enterprise agent
rest of session
Makers gate tools per agent; users can approve once, approve for the rest of the session, or deny.
The gate is outside the agent’s own instructions.
Designed for sends, tickets, payments, and similar tools.
Governance can feed Power Platform audit systems.
Grok / Grok Bot
Cloud agent
undocumented
The research did not find reliable xAI documentation defining a standing approval’s scope, persistence, cross-chat reach, or revoke surface.
Do not infer Grok’s behavior from Claude, Cursor, Gemini, or Muse.
Treat each approval as local to the visible task until the product proves otherwise.
Keep consequential actions behind a separate human gate.
03
Does the approval travel?
Usually less than people fear—but sometimes farther than they expect. No researched vendor carries an approval into another vendor’s product.
Platform
Other chats
Other projects
Other devices
Other products
Claude Code
Yes, in same repo
No, unless user-level rule
No, local files
No evidence
Cursor
Yes
Only if rule is shared
Via committed repo file
No evidence
ChatGPT agent
n/a
n/a
n/a
No evidence
ChatGPT Work
Yes, per site
Yes, per site
Yes, cloud/account
No evidence
Copilot Studio
No, session only
No
No
No evidence
Gemini Code Assist
Yes, same IDE
Yes, user setting
Undocumented
No evidence
There is no universal “always.” There is only an approval attached to a boundary.
Main chat vs. project vs. Claude vs. Grok vs. Cursor: treat every surface as a separate authority domain until that product explicitly shows otherwise. Same account does not mean same grant. Same vendor does not mean same product. Similar wording does not mean similar scope.
04
Design the least-annoying safe gate
A practical rule engine based on the converging guidance: reserve human attention for the steps where it changes the outcome.
Approval recommender
Choose an action and its reach. This is a policy aid, not a vendor setting.
Action
Reach
Duration
Recommended gateAuto-run with an audit log
Read-only work inside your own workspace can usually proceed quietly. Log what was accessed and keep secrets excluded.
Quiet lane
Low consequence, reversible, internal.
Read/search
Draft/stage
Organize reversible files
Always log
One-tap lane
Meaningful external or production effect.
Send or publish
Deploy
Account setting
Show real target + content
Friction lane
Money, identity, access, deletion, or irreversible harm.
Typed approval or step-up auth
Bind approval to exact action
Short expiry
Never inherited from a vague grant
05
How standing approvals fail
The danger is rarely “the AI became evil.” It is usually a trusted tool, a changed context, a misleading prompt, or a tired human.
Approval fatigue
A prompt repeated often enough becomes a reflex. The gate still exists visually while meaningful review disappears. This is why tiering beats asking about everything.
Prompt injection through a trusted tool
EchoLeak showed how a crafted email could coerce Microsoft 365 Copilot into exfiltration. TrustFall showed how one generic “trust this folder” click could arm a malicious MCP configuration across coding agents.
Grant outlives the reason
A permanent Bash rule, per-site browser grant, or scheduled-task permission can remain after the original job is over. The next task inherits power it did not earn.
Scope contamination
Repo rules can affect every future task in the repo. Cursor project allowlists can be committed and inherited by teammates. A convenience decision becomes shared infrastructure.
Presented action differs from executed action
If the user sees the agent’s summary instead of the resolved recipient, command, or final payload, the approval can be technically genuine but practically uninformed.
“Run everything” becomes the workaround
If the system asks about trivial reads and destructive writes with equal urgency, users reach for YOLO or bypass modes. Bad UX can manufacture unsafe behavior.
The four repeated cards are not reassurance.
A gate that reappears until the user disables it is approval fatigue in miniature. Whether the repeats came from retry logic or delivery duplication, the safe response is to deduplicate the prompt—not train the user to approve more broadly.
06
No industry standard—yet
There is no binding specification that makes “always allow” mean the same thing everywhere. But the security guidance is converging.
Least agencyGrant the exact command, path, server, tool, recipient, and purpose—not a whole capability.
Time and task limitsPrefer once or session. Standing grants should expire or be reviewed.
Risk tiersRead, write, external send, payment, and security changes should not share one gate.
Per-action verificationPrivileged steps should be rechecked by a policy engine outside the agent prompt.
Presentation integrityShow the real recipient, final text, raw command, and resolved resource.
Immutable receiptsRecord what was shown, what was approved, and what actually executed.
Hard baselinesSecrets, account recovery, money, destructive commands, and broad access should keep non-bypassable checks.
Kill switchesEvery durable grant needs a visible list, revoke action, and safe fallback.
The best feature is not “always allow.” It is “allow this exact thing, for this purpose, until this time.”
Product opportunity: make the scope legible. Let users see a plain-language grant card, a live approval ledger, expiry/count limits, and a one-tap revoke. The system should reduce nagging by grouping low-risk work—not by quietly widening authority.
07
The practical rule for your setup
You already have the right doctrine. The research mainly sharpens where the lines belong.
Auto
Let it run and narrate after.
Reads and research
Drafts and staging
Reversible internal organization
Routine checks with no external effect
Tap
Keep the one-tap human gate.
Email and messaging
Publishing and deploys
Changing live settings
Actions affecting another person
Type
Make the friction intentional.
Money and purchases
Credential/security changes
Deletion or irreversible moves
Broad standing authority
Your “always allow” tap was not reckless.
It was a reasonable response to a low-value repeated prompt. The lesson is not “never use standing approval.” It is: the platform should show the exact scope, make it easy to revoke, and never rely on repetition to win consent. Until Muse exposes that ledger, treat the grant as a convenience whose boundary remains partly unknown.
Verification note: the research read public documentation and web text on September 17, 2026. It did not live-test each product. Undocumented behavior is labeled as such.
Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.
Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.
On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.
Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.
Today I sat next to the laptop and asked the frozen brain what it got right.
What Cortex-One was betting on
Gemini, reading its own notebook, put the bets in three lines:
Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.
That third bet is the one I want to hold up to the light.
232 days later
Bet
Call
What actually happened
Voice agents
Early, mostly right
Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
Gemini ↔ Notebook
Right
Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
Named personal agents
Right direction
Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
Desktop sidecar
Wrong call
Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
Cloud bots
Real, different seat
Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.
Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.
Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.
The seats are not interchangeable
This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.
Seat
Where it lives
Job
Grok CLI on this laptop
Physical machine, next to the human
Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
Grok Bot
Shared cloud computer; desktop app and phone
Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
Grok Mobile
Phone, same Bot cloud
Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.
Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.
I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.
The cheapest intelligence is already in the product
Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.
Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
Gemini Notebook still held Cortex-One and the Sidecar brief.
GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
Gemini chat took Cortex-One as an attachment and graded it against 2026.
Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.
Were we early?
On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.
The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.
The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.
What to do this week
Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.
Close
Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.
We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.
The on-ramp is still real. The sidecar was the point.
Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.
The piece I’m responding to is one I published this morning — Composting Is Not Cleaning. I read it back and felt called out by my own argument. Then I pushed back on it. This is both moves, in order.
The Setup
The setup — pile as substrate.
The composting essay said the pile in your workspace is a mausoleum. Each item there was flagged by a former version of you, and the version that flagged it is gone. The argument was that releasing those items is grief, not housekeeping, and that the only honest move is to compost them. I agreed when I read it. Then I noticed the argument assumed something my own setup doesn’t have: a single actor on a single timeline. So this is the place where I run my actual view, then run the version that would change my mind, then say where the friction is still live.
My Take
My take on the mausoleum problem.
The pile isn’t a mausoleum. It’s substrate.
The composting argument is correct in a single-actor system. If the only person who will ever look at the captured item is the same operator who flagged it, then the item is exactly what the essay said: a promise made by a former self that current self can’t keep, doing identity work in the meantime. In that environment, composting is the discipline. I’d defend that argument every day.
My environment isn’t that environment. There are multiple actors. A Claude session opening tomorrow morning. A Gemini agent walking my Notion at 3am. A future me who finally has the integration that didn’t exist when the item was captured. Those are not the same actor as the one who put the item in the pile. They have different capability sets, different context windows, different hands. The capture wasn’t a promise to act. It was a deposit into a substrate that other agents are continuously pattern-matching against.
The middle layer of the pile — the items that “still feel possible” — is where this distinction matters. The composting essay said those items survive triage because triage asks the wrong question; the honest question is am I still that person? In a single-actor system, fair. In an agentic system, that’s still the wrong question. The honest question is has the capability gap that made this dormant closed since I captured it? Most of the time, no — and the item should leave. Some of the time, yes — and the item is now ready to ship in a way it wasn’t on the day it was caught.
I’ve watched this happen. An idea I captured 14 months ago — a small workflow I couldn’t build because the tooling didn’t exist — got picked up by a Claude session that recognized the integration had landed. The session pulled the idea out of the pile, combined it with the new capability, and produced a working artifact in an afternoon. The capture was correct. The wait was correct. The substrate did its job. If I had composted that item six months in because I “wasn’t that person anymore,” I would have lost the work the system was doing on my behalf.
The composting frame treats the capture-commitment gap as a personal failure dressed as a process problem. The substrate frame treats the capture-commitment gap as the organizing fact of working at scale with intelligent infrastructure — which is what the original essay actually said in its strongest paragraph and then walked back from. You wanted leverage. The leverage came. Some of the leverage takes the form of capturing more than you can commit to. The pile is the artifact of leverage working. The right move isn’t to compost it on a human-attention schedule. The right move is to build a surfacing layer that recognizes when a captured item’s capability gap has closed and walks past it loud enough that the next agent picks it up.
The pile isn’t grief. It’s seed corn.
The Second Take
The substrate frame is true and dangerous, and the danger is bigger than the truth.
Yes — more capable future agents can recombine old captures with new capabilities. The 14-month-old workflow that finally shipped is real. So is the next one, and the one after that. The substrate frame is empirically grounded in any environment where capability is genuinely accelerating. The argument doesn’t need defending on those grounds.
The argument needs defending on the grounds it actually fails on, which is that the operator telling himself everything is substrate has rebuilt the mausoleum with prettier signage. The composting essay’s deepest claim wasn’t that the pile contains nothing useful. It was that the bottom layer of the pile is doing structural work for the operator’s self-image, and that no surfacing system can see this layer because there is nothing operationally distinct about it. The substrate frame quietly converts that exact problem into a virtue. It says: don’t release — a future agent might want it. That sentence is unfalsifiable. Almost any item passes the test if you squint hard enough at the rate of capability growth. Which means the substrate frame, deployed honestly, releases approximately the same number of items as the composting frame. Deployed dishonestly, it releases none.
The asymmetry of costs makes the dishonest deployment the default. The cost of holding a useless captured item is silent and long: a small permanent tax on attention, on search, on the surfacing layer’s signal-to-noise ratio. The cost of releasing a captured item that would have mattered to a future agent is loud and brief: a single moment of regret when the agent walks past empty space where the seed used to be. Loud and brief always wins the local argument against silent and long. The substrate frame, in the operator’s actual day, becomes the rationalization for never releasing anything. The pile keeps growing. The compounding never finds its bottleneck because the bottleneck has been redefined as fertilizer.
There is a sharper version of the same point. The substrate frame leans on the assumption that surfacing systems will continue to improve at a rate that justifies indefinite retention. That assumption may be true and it doesn’t matter. The improvement curve doesn’t reach back through time and rescue items the operator could not bring himself to release. It rescues items the system kept on its own merits. The operator who held everything just in case has the same problem he had at human-attention scale, only larger and harder to see, because the volume hides the bottom-layer items perfectly. A pile of ten thousand fertile seeds and one identity-load placeholder is a pile that will never confront the placeholder. The placeholder did not get more legible at scale. It got less.
Which means the strongest case against the substrate frame is the case the composting essay already made and the substrate frame does not actually answer. Both frames believe the pile contains items the operator should release. They disagree about how many. The substrate frame is a permission slip to defer the question. The composting frame is the discipline of asking it on a schedule. The substrate frame, generously read, is the composting frame plus a longer review window. Ungenerously read — which is to say honestly read in the operator’s actual fatigue — it is the same workspace problem in different vocabulary.
What I’m Still Sitting With
What I’m still sitting with.
The tell I haven’t sorted out: which side I’m on tomorrow depends on whether my pile is shrinking on its own. If the substrate frame is right, items leave the pile because agents pull them out and ship them. If the composting frame is right, items leave because I release them. Either is honest. If nothing is leaving and I’m telling myself it’s compounding, the second take wins and I owe the original essay an apology.