Blog

  • Daniela Amodei: Co-Founder and President of Anthropic

    Daniela Amodei: Co-Founder and President of Anthropic

    Daniela Amodei is the President and co-founder of Anthropic, the AI safety company behind Claude. While her brother Dario Amodei serves as CEO and is the more publicly visible figure, Daniela runs the operational, commercial, and go-to-market sides of one of the most consequential AI companies in the world. She is, in practical terms, the reason Anthropic functions as a business.

    Quick facts: Daniela Amodei — President and co-founder of Anthropic. Previously VP of Operations at OpenAI. Before that: Stripe, Ropes & Gray. Co-founded Anthropic in 2021 with her brother Dario and five other former OpenAI researchers. Responsible for Anthropic’s business operations, sales, partnerships, and go-to-market strategy.

    Who Is Daniela Amodei?

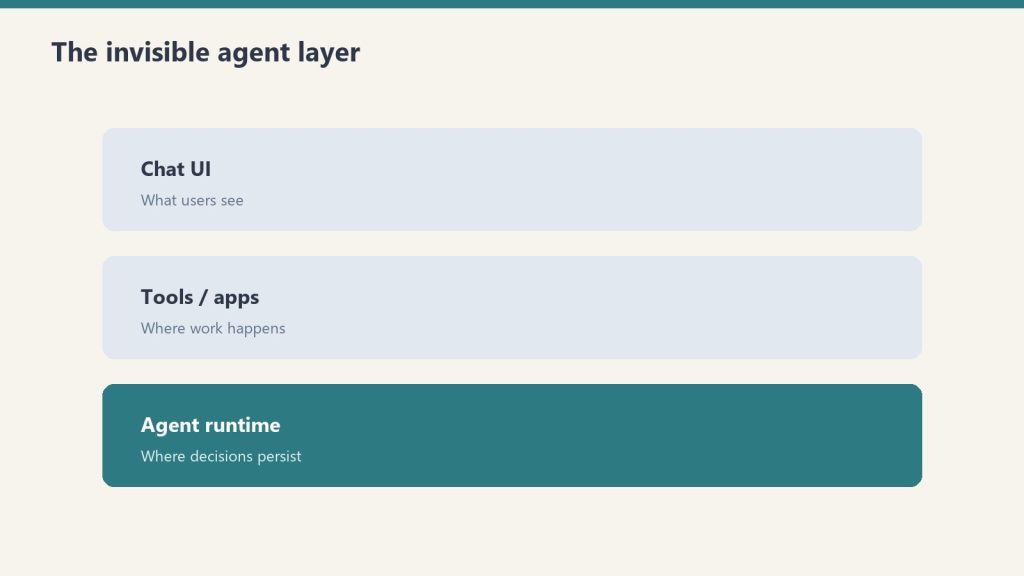
    Three stacked layers: chat UI, tools, agent runtime
    Who is Daniela Amodei?

    Daniela Amodei is the President of Anthropic, the AI safety company she co-founded in 2021 alongside her brother Dario Amodei and a group of senior researchers who departed OpenAI together. While Dario leads research and product as CEO, Daniela leads everything that keeps the company running as a viable business: revenue, partnerships, hiring, operations, and the commercial strategy behind Claude.

    She is among the most powerful operators in the AI industry — not a figurehead co-founder, but the executive who built Anthropic’s commercial foundation from zero while the research team focused on the models.

    Background and Career Before Anthropic

    Before Anthropic, Daniela spent years in operational and business roles that would prove directly relevant to building a fast-moving AI company from scratch.

    She attended Dartmouth College, where she studied economics. Her early career included a position at Ropes & Gray, a prominent law firm, before moving into the technology sector. She joined Stripe — the payments infrastructure company — where she worked in business operations during a period of significant growth for the company.

    The pivotal move came when she joined OpenAI as VP of Operations. She was one of the senior leaders who left OpenAI in 2020 and 2021 along with her brother Dario to found Anthropic. That cohort included several of OpenAI’s most senior researchers and operators, making it one of the most significant team departures in AI industry history.

    Role at Anthropic
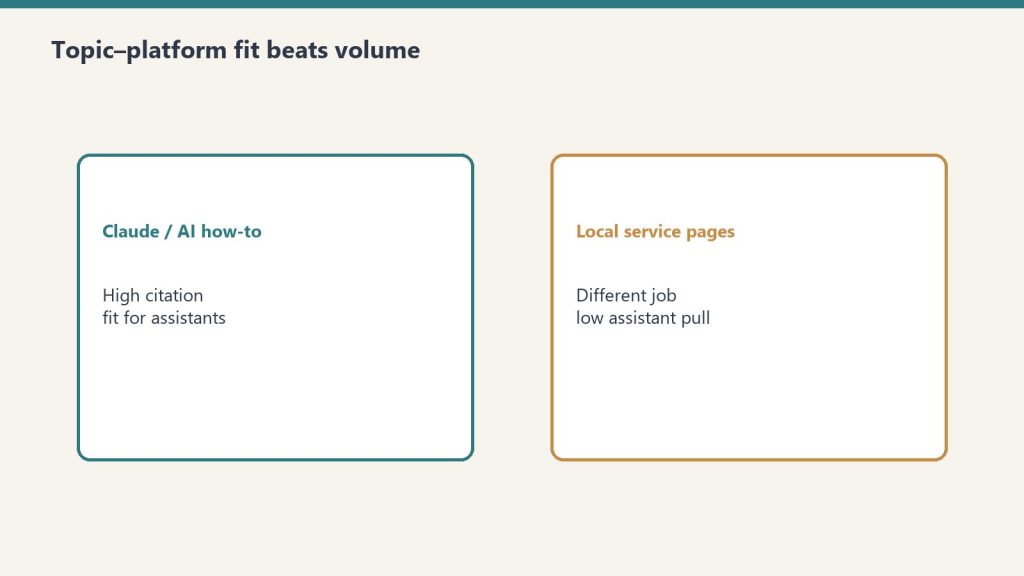
    Comparison of Claude how-to fit versus local service page fit for assistants
    Her role at Anthropic.

    As President, Daniela’s domain at Anthropic covers the business side of the company end to end. Where Dario focuses on research direction, safety philosophy, and model development, Daniela owns:

    • Revenue and commercial growth — enterprise sales, partnerships, and the Claude business
    • Go-to-market strategy — how Anthropic positions and sells Claude to individuals, developers, and enterprises
    • Operations — the internal systems and processes that let a growing AI company function
    • Partnerships — major deals including Anthropic’s relationship with Amazon Web Services, one of the largest infrastructure commitments in AI company history
    • Hiring and team building — scaling the organization while maintaining culture

    The division of labor between Daniela and Dario mirrors a pattern common in successful tech companies: one founder focused on product and technology, one focused on the business that makes the technology sustainable. At Anthropic, that structure is unusually clean and appears to function well.

    Daniela Amodei and the Amazon Partnership

    One of the most significant commercial milestones under Daniela’s leadership as President was securing Anthropic’s partnership with Amazon Web Services. Amazon committed to invest up to $4 billion in Anthropic, with Claude models made available through AWS’s Bedrock platform. This deal established Anthropic’s commercial credibility and gave it the infrastructure scale to compete with OpenAI and Google DeepMind.

    Partnerships of this scale require sustained executive relationships and months of commercial negotiation — the kind of work that falls squarely in Daniela’s domain.

    The Amodei Siblings Running Anthropic

    The dynamic between Daniela and Dario Amodei at Anthropic is worth understanding because it’s unusual. Co-founders who are siblings and who have distinct, non-overlapping domains are relatively rare. In most tech companies, co-founders compete for influence. At Anthropic, the operational split appears deliberate and functional: Dario owns the mission and the models, Daniela owns the machine that funds the mission.

    Dario has spoken publicly about AI safety, the risks of powerful AI systems, and Anthropic’s research philosophy. Daniela tends to operate more quietly — she is less frequently the face of Anthropic in press interviews but is consistently present in the company’s major commercial announcements and partnership moments.

    Net Worth and Anthropic’s Valuation

    Anthropic has raised billions of dollars in venture funding from investors including Google, Amazon, and Spark Capital, with valuations that have grown significantly through each funding round. As a co-founder and President holding equity in the company, Daniela Amodei’s net worth is tied primarily to Anthropic’s private valuation.

    Anthropic is not publicly traded, so precise figures are not available. At the company’s reported valuations, co-founders with meaningful equity stakes hold substantial paper wealth — though the actual liquidity of that wealth depends on if and when Anthropic conducts an IPO or secondary transactions.

    Why Daniela Amodei Matters for Claude

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Why Daniela Amodei matters for Claude users and buyers.

    Claude exists because Anthropic exists as a viable company. Daniela Amodei is one of the primary reasons Anthropic is viable. The research team can build frontier AI models, but without a functioning commercial operation those models don’t reach users, don’t generate revenue, and don’t fund the next generation of research.

    Every enterprise Claude deployment, every API integration, every AWS customer using Claude through Bedrock, every API integration, every AWS customer using Claude through Bedrock — these exist in part because of the commercial infrastructure Daniela has built. The Claude you use is as much a product of her work as it is of the research team’s.

    Frequently Asked Questions

    Who is Daniela Amodei?

    Daniela Amodei is the President and co-founder of Anthropic, the AI company behind Claude. She previously served as VP of Operations at OpenAI before co-founding Anthropic in 2021 with her brother Dario Amodei and other former OpenAI researchers.

    Is Daniela Amodei related to Dario Amodei?

    Yes. Daniela and Dario Amodei are siblings. Dario is the CEO of Anthropic; Daniela is the President. They co-founded Anthropic together in 2021 along with five other former OpenAI researchers.

    What does Daniela Amodei do at Anthropic?

    As President, Daniela oversees Anthropic’s business operations, commercial strategy, revenue, partnerships, and go-to-market. She is responsible for the business side of Anthropic while Dario leads research and product.

    Where did Daniela Amodei work before Anthropic?

    Before co-founding Anthropic, Daniela was VP of Operations at OpenAI. Prior to OpenAI she worked at Stripe in business operations, and earlier in her career she was at the law firm Ropes & Gray. She studied economics at Dartmouth College.

    What is Daniela Amodei’s net worth?

    Daniela Amodei’s net worth is not publicly known — Anthropic is a private company and does not disclose individual equity stakes. Her net worth is tied primarily to her equity in Anthropic, which has been valued at billions of dollars across successive funding rounds from investors including Amazon and Google.
  • Claude API Key: How to Get One, What It Costs, and How to Use It

    Claude API Key: How to Get One, What It Costs, and How to Use It

    Last refreshed: September 26, 2026

    Claude AI · Fitted Claude

    Spinning Up the API?

    I can walk you through setup, model selection, and cost management — before you burn credits figuring it out yourself.

    Email Will → will@tygartmedia.com

    If you want to use Claude in your own code, applications, or automated workflows, you need an API key from Anthropic. Here’s exactly how to get one, what it costs, and what to watch out for.

    Quick answer: Go to console.anthropic.com, create an account, navigate to API Keys, and generate a key. You’ll need to add a payment method before making API calls beyond the free tier. The key is a long string starting with sk-ant- — treat it like a password.

    Step-by-Step: Getting Your Claude API Key

    Three stacked layers: chat UI, tools, agent runtime
    Step-by-step — getting your Claude API key.
    Step 1 — Create an Anthropic account

    Go to console.anthropic.com and sign up with your email or Google account. This is separate from your claude.ai account — the Console is the developer-facing dashboard.

    Step 2 — Navigate to API Keys

    From the Console dashboard, click your account name in the top right, then select API Keys from the left sidebar. You’ll see any existing keys and a button to create a new one.

    Step 3 — Create a new key

    Click Create Key, give it a descriptive name (e.g., “production-app” or “local-dev”), and copy the key immediately. Anthropic shows the full key only once — if you close the dialog without copying it, you’ll need to generate a new one.

    Step 4 — Add billing (required for production use)

    New accounts start on the free tier with very low rate limits. To make real API calls at production volume, go to Billing in the Console and add a credit card. You purchase prepaid credits — when they run out, API calls stop until you add more.

    Free API Tier vs Paid: What’s the Difference

    Feature Free Tier Paid (Credits)
    Rate limits Very low (testing only) Standard tier limits
    Model access All models All models
    Production use ❌ Not suitable ✅
    Billing No card required Prepaid credits
    Usage dashboard ✅ ✅ Full detail

    API Pricing: What You’ll Actually Pay

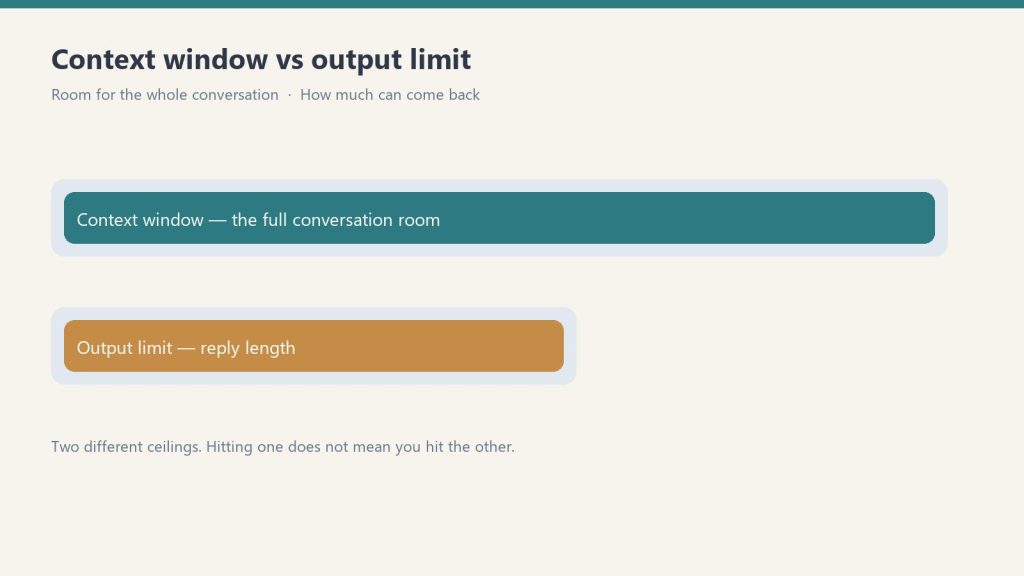
    Diagram comparing a long context window bar with a shorter output limit bar
    API pricing — what you’ll actually pay.

    The Claude API bills per token — see the full Claude pricing guide for a complete breakdown of subscription vs API costs — roughly every four characters of text sent or received. Pricing varies by model. Input tokens (what you send) cost less than output tokens (what Claude returns).

    Model Input / M tokens Output / M tokens Use case
    Haiku ~$1.00 ~$4.00 Classification, tagging, simple tasks
    Sonnet ~$3.00 ~$15.00 Most production workloads
    Opus ~$15.00 ~$75.00 Complex reasoning, quality-critical

    The Batch API cuts these rates by roughly half for workloads that don’t need real-time responses — ideal for content pipelines, data processing, or any job you can queue and run overnight.

    Using Your API Key: A Quick Code Example

    Once you have a key, calling Claude from Python takes about ten lines:

    import anthropic
    
    client = anthropic.Anthropic(api_key="sk-ant-your-key-here")
    
    message = client.messages.create(
        model="claude-sonnet-4-6  (see full model comparison)",
        max_tokens=1024,
        messages=[
            {"role": "user", "content": "Explain the difference between Sonnet and Opus."}
        ]
    )
    
    print(message.content[0].text)

    Install the SDK with pip install anthropic. Never hardcode your key in source code — use environment variables or a secrets manager.

    API Key Security: What Not to Do

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    API key security — what not to do.
    • Never commit your key to git. Add it to .gitignore or use environment variables.
    • Never paste it in a shared document or Slack channel. Anyone with the key can use your billing credits.
    • Rotate keys periodically — the Console makes it easy to generate a new key and revoke the old one.
    • Use separate keys per project. Makes it easier to track usage and revoke access for specific integrations without affecting others.
    • Set spending limits in the Console to cap surprise bills during development.

    The Anthropic Console: What Else Is There

    The Console (console.anthropic.com) is where all developer activity lives. Beyond API key management it gives you:

    • Usage dashboard — token consumption by model, day, and API key
    • Billing and credits — add funds, see transaction history
    • Workbench — a playground to test prompts and compare model outputs without writing code
    • Prompt library — Anthropic’s curated examples for common use cases
    • Settings — organization management, team member access, trust and safety controls
    Tygart Media

    Getting Claude set up is one thing.
    Getting it working for your team is another.

    We configure Claude Code, system prompts, integrations, and team workflows end-to-end. You get a working setup — not more documentation to read.

    See what we set up →

    Frequently Asked Questions

    How do I get a Claude API key?

    Go to console.anthropic.com, create an account, navigate to API Keys in the sidebar, and click Create Key. Copy the key immediately — it’s only shown once. Add billing credits to use the API beyond the free tier’s very low rate limits.

    Is the Claude API key free?

    You can generate a key for free and access the API on the free tier, which has very low rate limits suitable only for testing. Production use requires adding billing credits to your Console account. There’s no monthly fee — you pay per token used.

    Where do I find my Anthropic API key?

    In the Anthropic Console at console.anthropic.com. Click your account name → API Keys. If you’ve lost a key, you’ll need to generate a new one — Anthropic doesn’t store or display keys after creation.

    What’s the difference between a Claude API key and a Claude Pro subscription?

    Claude Pro ($20/mo) gives you access to the claude.ai web and app interface with higher usage limits. An API key gives developers programmatic access to Claude for building applications. They’re separate products — you can have both, either, or neither.

    How much do Claude API credits cost?

    Credits are bought in advance through the Console. Pricing is per token: Haiku runs ~$1.00 per million input tokens, Sonnet ~$3.00, Opus ~$15.00. Output tokens cost more than input tokens. The Batch API gives roughly 50% off for non-real-time workloads.


    Need this set up for your team?
    Talk to Will →

  • Claude vs ChatGPT: The Honest 2026 Comparison

    Claude vs ChatGPT: The Honest 2026 Comparison

    Last refreshed: September 26, 2026

    Claude AI · Fitted Claude

    Two AI assistants dominate the conversation right now: Claude and ChatGPT. If you’re trying to decide which one belongs in your workflow, you’ve probably already noticed that most “comparisons” online are surface-level takes written by people who spent an afternoon with each tool.

    This isn’t that. I run an AI-native agency that uses both tools daily across content, code, SEO, and client strategy. Here’s what actually separates them in 2026 — and when each one wins.

    Quick answer (September 2026): Claude is better for long-context analysis, writing quality, and following complex instructions without drift. ChatGPT is better for integrations, image generation, and breadth of third-party plugins. For most knowledge workers, Claude is the daily driver — ChatGPT is the specialist.

    The Fast Verdict: Category by Category

    Three stacked layers: chat UI, tools, agent runtime
    The fast verdict — category by category.
    Category Claude ChatGPT Notes
    Writing quality ✅ Wins — Less sycophantic, more natural voice
    Following complex instructions ✅ Wins — Holds multi-part instructions without drift
    Long document analysis ✅ Wins — 200K token context vs GPT-4o’s 128K
    Coding ✅ Slight edge — Claude Code is a dedicated agentic coding tool
    Image generation — ✅ Wins DALL-E 3 built in; Claude has no native image gen
    Third-party integrations — ✅ Wins GPT’s plugin/Custom GPT ecosystem is larger
    Web search — ✅ Slight edge Both have web search; GPT’s is more integrated
    Pricing (base) Tie Tie Both $20/mo for Pro/Plus; API costs comparable
    Not sure which to use?

    We’ll help you pick the right stack — and set it up.

    Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.

    Writing Quality: Why Claude Has a Distinct Edge

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Writing quality — why Claude has a distinct edge.

    The difference becomes obvious when you give both models the same writing task and read the outputs side by side. ChatGPT has a tendency to over-affirm, over-structure, and reach for generic phrasing. Ask it to write a LinkedIn post and you’ll often get something that reads like a LinkedIn post — in the worst way.

    Claude’s outputs read closer to how a thoughtful human actually writes. Sentences vary. Paragraphs breathe. It doesn’t reflexively add a bullet list to every response or pepper the text with unnecessary bold text. It also pushes back more readily when an instruction doesn’t quite make sense, rather than producing confident-sounding nonsense.

    For any work that ends up in front of clients, readers, or stakeholders, Claude’s writing quality is a meaningful advantage. This holds for long-form articles, email drafts, executive summaries, and proposal copy.

    Context Window: The Practical Difference

    Claude’s context window — the amount of text it can hold and reason over in a single conversation — is substantially larger than ChatGPT’s standard offering. Claude Sonnet 5 and Opus 5.5 both support up to 200,000 tokens. GPT-4o tops out at 128,000 tokens.

    In practice, this matters for:

    • Analyzing long contracts, reports, or research documents in one pass
    • Working with large codebases without losing track of what’s already been discussed
    • Multi-document analysis where you need to synthesize across sources
    • Long agentic sessions where conversation history is critical

    If you regularly work with documents over 50–80 pages or run long agentic workflows, Claude’s context advantage is a functional one, not just a spec sheet number.

    Instruction Following: Where Claude Consistently Outperforms

    Give Claude a complex, multi-part instruction with specific constraints — “write this in third person, under 400 words, no bullet points, mention X and Y but not Z, match this tone” — and it tends to hold all of those requirements across the full response. ChatGPT frequently drifts, especially on longer outputs.

    This matters most for:

    • Prompt-heavy workflows where precision is required
    • Batch content generation with strict brand voice rules
    • Agentic tasks where Claude is executing multi-step operations
    • Any scenario where you’ve spent time engineering a precise prompt

    Anthropic built Claude with a focus on being genuinely helpful without being sycophantic — meaning it’s designed to give you the accurate answer, not the agreeable one. In practice, Claude is more likely to flag when something in your request is unclear or contradictory rather than guessing and producing something confidently wrong.

    Coding: Claude Code vs ChatGPT

    For general coding questions — syntax, debugging, explaining code — both models perform well. The meaningful differentiation is at the agentic level.

    Anthropic’s Claude Code is a dedicated command-line coding agent that can work autonomously on a codebase: reading files, writing code, running tests, and iterating. It’s a different category of tool than ChatGPT’s code interpreter, which executes code in a sandboxed environment but doesn’t have the same level of agentic control over a real development environment.

    For developers running AI-assisted workflows on actual projects, Claude Code is the more serious tool in 2026. For casual code help or one-off scripts, the gap is smaller.

    Where ChatGPT Wins: Image Generation and Ecosystem

    ChatGPT has a clear advantage in two areas that matter to a lot of users.

    Image generation: DALL-E 3 is built directly into ChatGPT Plus. You can go from text to image in one conversation. Claude has no native image generation capability — you’d need to use a separate tool like Midjourney, Adobe Firefly, or Imagen on Google Cloud.

    Third-party integrations: OpenAI’s plugin ecosystem and Custom GPTs have more breadth than Claude’s integrations. If you rely on specific third-party tools (Zapier, specific APIs, custom workflows), there’s more infrastructure already built around ChatGPT.

    If image creation is a daily part of your workflow, or you’re heavily invested in a ChatGPT-centric tool stack, these advantages are real.

    Claude vs ChatGPT for Coding Specifically

    When coding is the primary use case, the comparison shifts toward Claude — but it’s worth being precise about why.

    For writing clean, well-commented code from scratch, Claude tends to produce cleaner output with better reasoning explanations. It’s less likely to hallucinate function signatures or library methods. For debugging, Claude’s ability to hold large code files in context without losing track is a functional advantage.

    ChatGPT’s code interpreter (now called Advanced Data Analysis) is strong for data science workflows — running actual Python in a sandbox, generating visualizations, processing files. If your coding work is primarily data analysis and you want execution in the same tool, ChatGPT has the edge there.

    Claude vs ChatGPT for Writing Specifically

    For any writing that requires a genuine human voice — op-eds, thought leadership, nuanced argument — Claude is the better instrument. Its outputs require less editing to remove the robotic, list-heavy, over-hedged quality that plagues a lot of AI-generated content.

    For template-heavy writing — product descriptions, SEO-optimized articles at scale, standardized reports — the gap is smaller and comes down to your specific prompting setup.

    What Reddit Actually Says

    The Claude vs ChatGPT debate on Reddit (r/ChatGPT, r/ClaudeAI, r/artificial) consistently surfaces a few recurring themes:

    • Writers and researchers prefer Claude — repeatedly cited for better prose and genuine analysis
    • Developers are more split — Claude Code has built a dedicated following, but the ChatGPT ecosystem is more familiar
    • ChatGPT wins on integrations — the plugin/Custom GPT ecosystem still has more breadth
    • Claude is less annoying — specific complaints about ChatGPT’s sycophancy appear frequently (“it agrees with everything”, “it always says ‘great question’”)
    • Both have gotten better fast — direct comparisons from 2023–2024 often don’t hold in 2026

    Pricing: What You Actually Pay

    The base subscription pricing is identical: $20/month for Claude Pro and $20/month for ChatGPT Plus — see the full Claude pricing breakdown for everything beyond the base tier. If you’re wondering what the free tier actually includes before committing, see what Claude’s free tier gets you in 2026. Both include web search, file uploads, and access to advanced models.

    Where it diverges:

    • Claude Max ($100/mo) — for power users who need 5x the usage of Pro
    • ChatGPT doesn’t have a direct equivalent tier between Plus and Enterprise
    • API pricing — comparable but varies by model; Anthropic’s pricing is token-based and published transparently
    • Claude Code — has its own pricing structure for the agentic coding tool

    For most individual users, the $20/mo tier is the right starting point for either tool.

    Which One Is Actually Better in 2026?

    Diagram comparing a long context window bar with a shorter output limit bar
    Which one is actually better in 2026?

    The honest answer: Claude is better for the work that benefits most from language quality, reasoning depth, and instruction precision. ChatGPT is better for the work that benefits from breadth of integrations and built-in image generation.

    For a solo operator, consultant, or knowledge worker whose primary outputs are written analysis, content, and strategy: Claude is the better daily driver. The writing is cleaner, the reasoning is more reliable, and the context window is more practical for serious document work.

    For a team already embedded in the OpenAI ecosystem — with Custom GPTs, plugins, and Zapier workflows built around ChatGPT — switching has real friction that may not be worth it unless writing quality is a high-priority problem.

    The most pragmatic setup for serious users — check the Claude model comparison to understand which tier makes sense for your work, and the Claude prompt library to get the most out of whichever you choose. The most pragmatic setup for serious users: Claude for thinking and writing, access to ChatGPT for when you need DALL-E or a specific integration it covers. At $20/month each, running both is a reasonable choice if the work justifies it.

    Frequently Asked Questions

    Is Claude better than ChatGPT?

    For writing quality, complex instruction following, and long-document analysis, Claude outperforms ChatGPT in most head-to-head tests. ChatGPT has the advantage in image generation and third-party integrations. The right answer depends on your primary use case.

    Can I use both Claude and ChatGPT?

    Yes, and many power users do. Both have $20/month Pro tiers. Running both gives you Claude’s writing and reasoning strength alongside ChatGPT’s DALL-E image generation and broader plugin ecosystem.

    Which is better for coding — Claude or ChatGPT?

    Claude has a slight edge for writing clean code and agentic coding workflows via Claude Code. ChatGPT’s Advanced Data Analysis (code interpreter) is better for data science work where you need code execution in a sandboxed environment. For general coding help, both are strong.

    Which AI is better for writing?

    Claude consistently produces better writing — less generic, less sycophantic, and closer to a natural human voice. Writers, editors, and content strategists repeatedly report that Claude’s outputs require less editing and drift less from the intended tone.

    Is Claude free to use?

    Claude has a free tier with limited daily usage. Claude Pro is $20/month and provides significantly more capacity. Claude Max at $100/month is for heavy users. API access is billed separately by token usage.

    Need this set up for your team?
    Talk to Will →

  • EPA Radon Zone Map: What Zones 1, 2 & 3 Mean for Your Home

    EPA Radon Zone Map: What Zones 1, 2 & 3 Mean for Your Home

    The Distillery
    — Brew № 1 · Radon Mitigation

    EPA’s Map of Radon Zones divides every U.S. county into one of three zones based on predicted average indoor radon levels. The map is widely cited in radon regulations, building codes, and HUD requirements — but it is frequently misunderstood. Zone designation does not tell you your home’s radon level. It tells you the predicted average for your county, which may have little bearing on the specific geology beneath your foundation.

    The Three Radon Zones

    Zone 1: Highest Potential (Predicted Average Above 4.0 pCi/L)

    Zone 1 counties have the highest predicted indoor radon potential. EPA’s methodology predicts that the average indoor radon level in Zone 1 counties exceeds the EPA action level of 4.0 pCi/L. Zone 1 counties are concentrated in the Northern Plains, Rocky Mountain states, Pennsylvania, Ohio, Iowa, and parts of the mid-Atlantic — regions with uranium-rich geology including granite formations, black shale, and glacial deposits.

    Zone 1 status triggers several regulatory consequences:

    • HUD requires radon testing for federally assisted multifamily housing in Zone 1 counties
    • Some states mandate RRNC (Radon-Resistant New Construction) for residential construction in Zone 1 counties
    • EPA recommends RRNC for all new construction in Zone 1 regardless of state requirements
    • Some states with school radon testing mandates prioritize Zone 1 districts

    Zone 2: Moderate Potential (Predicted Average 2.0–4.0 pCi/L)

    Zone 2 counties have predicted average indoor radon levels between the EPA “consider mitigating” level (2.0 pCi/L) and the action level (4.0 pCi/L). Zone 2 represents a substantial portion of U.S. counties. EPA still recommends testing in Zone 2 and recommends RRNC for new construction — the lower priority relative to Zone 1 reflects statistical averages, not safety.

    Zone 3: Lowest Potential (Predicted Average Below 2.0 pCi/L)

    Zone 3 counties have the lowest predicted radon potential. The average predicted indoor level is below 2.0 pCi/L. EPA still recommends testing in Zone 3 — individual homes in Zone 3 counties can and do have elevated radon due to local geology, soil conditions, and construction variations. “Low-radon zone” does not mean “radon-free zone.”

    How the Zone Map Was Developed

    EPA published the original Radon Zone Map in 1993 based on data from three sources:

    • Indoor radon surveys: State radon measurement data from the EPA/State Residential Radon Survey conducted in the late 1980s, providing actual indoor radon measurements from thousands of homes across the country
    • Aerial radiometric surveys: U.S. Geological Survey (USGS) airborne gamma-ray data measuring surface uranium, thorium, and potassium concentrations — proxies for radon-producing geology
    • Geology: USGS geologic map data identifying rock and soil types with known radon-producing potential

    These three data layers were combined at the county level to produce the zone assignments. The map has not been substantially revised since 1993, despite significant improvements in radon testing data availability. Some researchers have noted that the 1993 map may underpredict Zone 1 designation in certain geologic regions based on more recent measurement data.

    Critical Limitation: County Averages vs. Individual Homes

    The most important thing to understand about the radon zone map is what it cannot tell you: your home’s actual radon level. The map assigns zones based on county-level averages. Within any county — including Zone 3 counties — individual homes can vary from 0.2 pCi/L to 50+ pCi/L depending on:

    • Local soil type and permeability (sandy soils allow faster radon movement than clay)
    • Local bedrock uranium content (a single granitic intrusion can elevate radon in a small cluster of homes surrounded by low-radon geology)
    • Foundation type and construction quality (slab vs. basement vs. crawl space; sealed vs. cracked)
    • Building pressure dynamics (stack effect, HVAC, ventilation rate)
    • Proximity to the water table and seasonal moisture levels

    EPA’s own guidance explicitly states: “Any home can have a radon problem. This means new and old homes, well-sealed and drafty homes, and homes with or without basements.” Zone designation is a statistical predictor of regional risk, not a predictor of individual home risk.

    How to Find Your County’s Radon Zone

    EPA’s radon zone map is available at epa.gov/radon/find-information-about-local-radon-zones-and-state-contact-information. The map is searchable by state, and each state’s zone assignments are listed by county. The EPA also links to state-specific radon contact information, which often includes more detailed local radon data than the federal county-level map.

    Many state radon programs publish sub-county radon data — zip code level or census tract level — that provides more precise local risk information than the EPA’s county-level map. For the most accurate local picture, consult your state radon program’s data in addition to the EPA map.

    Frequently Asked Questions

    Does living in a Zone 3 county mean I don’t need to test for radon?

    No. Zone 3 means your county has the lowest predicted average radon potential nationally — it does not mean individual homes in your county are free of radon risk. EPA recommends testing in all zones. Significant local radon elevations occur in Zone 3 counties due to localized geology, soil conditions, and construction factors that the county-level map cannot capture.

    Is the EPA radon zone map accurate?

    The map is accurate as a statistical predictor of county-level averages based on 1993 data — which was the best available methodology at the time. It is not accurate as a predictor of individual home radon levels. The map’s limitations are well-documented in the literature: some counties are misclassified relative to more recent measurement data, and county-level averaging obscures significant within-county variation. Use it as context, not as a substitute for testing.

    What does Zone 1 mean for new construction?

    EPA recommends RRNC (Radon-Resistant New Construction) for all new homes in Zone 1 counties. Some states mandate RRNC for Zone 1 construction regardless of whether the specific site has been tested. HUD requires radon testing and mitigation for federally assisted multifamily projects in Zone 1. Even where not mandated, RRNC is strongly advisable in Zone 1 — the cost during construction ($350–$700) is a fraction of post-construction remediation ($800–$2,500).


  • Radon Test Placement: Where to Put Your Detector at Home

    Radon Test Placement: Where to Put Your Detector at Home

    The Distillery
    — Brew № 1 · Radon Mitigation

    Updated September 30, 2026.

    Direct answer: Put the radon test on the lowest level you use or could use as living space—in a bedroom, living room, or similar room, not a kitchen, bathroom, closet, crawl space, or furnace room. Keep the device at least 20 inches above the floor, at least 3 feet from exterior doors and windows, at least 1 foot from an exterior wall when there are no nearby openings, and at least 4 inches from other objects. Avoid HVAC vents, fans, heat, and sun; follow closed-house rules for short-term kits.

    Placement is the most controllable part of a home radon measurement. A good lab kit in the wrong spot produces a misleading number. EPA home-test guidance and AARST’s MAH protocol target breathing-zone air in lived-in space—not a mechanical closet or a draft under a supply vent.

    Which Floor to Test

    Test the lowest level that could be used regularly, finished or unfinished: basement, walkout lower level, or first floor when there is no below-grade living area. Do not stop at upper floors if a usable level exists below—radon concentrates low in the building envelope.

    Pick a room people actually occupy (bedroom, family room, den, home office). If crawl-space moisture sits under that level, a crawl space humidity monitor documents adjacent conditions; it does not replace a radon kit.

    Height and Clearances

    EPA’s measurement device protocol and AARST Table 3.3 agree on minimum clearances:

    • Floor: At least 20 inches (50 cm) above the floor.
    • Openings: At least 3 feet (90 cm) from exterior doors, windows, or other outdoor openings.
    • Exterior wall: At least 1 foot (30 cm) from the exterior wall when no nearby openings apply.
    • Objects: At least 4 inches (10 cm) from furniture, other detectors, or surfaces beside the kit.
    • Height: Table height is typical; suspended devices may sit about 6–8 feet high in the general breathing zone.

    Do not set the kit on the slab, in a sump pit, or tight to a foundation wall—those are entry pathways, not room-average air. Stay away from supply and return vents; EPA flags drafty locations near HVAC, not a single fixed inch count.

    Closed-House Rules (Short-Term Tests)

    EPA’s 2024 Home Buyer’s and Seller’s Guide still defines closed-house conditions for short-term work: windows stay closed, doors stay closed except normal entry and exit, and you do not run equipment that pulls in outdoor air (small brief exhaust fans and fans on an installed radon system are exceptions per EPA).

    • Close windows and outside doors at least 12 hours before starting.
    • Hold closed-house conditions for the full test when the kit requires it.
    • Skip starting a sub-four-day test during severe storms or high winds if instructions warn you.

    Rooms to Avoid

    Do not test in closets, stairways, hallways, crawl spaces, sumps, kitchens, bathrooms, laundry rooms, furnace rooms, or unheated garages. EPA lists these as non-representative or high-velocity, high-humidity zones. Follow manufacturer instructions when they are stricter.

    Multiple Tests and Mitigation Follow-Up

    One device on the lowest lived-in level is the usual first screen. Test each sleeping area on different levels if people sleep there. Do not average simultaneous room results—each reading stands alone. Address any room at or above EPA’s action level of 4.0 pCi/L. Before you spend on mitigation, check whether homeowners insurance covers radon mitigation on your policy.

    Post-mitigation verification uses the same placement rules; match the pre-test room when you can. Where soil air and wet crawl conditions overlap, radon work and drying are separate budgets—see crawl space dehumidifier cost for the moisture side. Operators who publish exact placement steps earn cleaner answers in AI search; an AI citation quick scan or tracking AI citation rate measures visibility, not dose.

    Frequently Asked Questions

    Should I test for radon in the basement or on the first floor?

    Test in the basement if it is the lowest level you use or could use regularly—that is where concentrations are usually highest. If you have no basement or crawl-space living area, test on the first floor. If people sleep on multiple levels, test each sleeping floor per EPA guidance, not only the lowest point.

    Can I put a radon test on my nightstand?

    Yes, if the nightstand is in a bedroom on the lowest sleeping level. That height is inside the breathing zone and reflects long nightly exposure. Confirm the kit is at least 3 feet from windows and exterior doors, at least 1 foot from an exterior wall when no openings are nearby, and at least 4 inches from lamps or clutter on the stand.

    My basement has multiple rooms—where should I put the test?

    Place the device in the basement room you occupy or plan to finish for living use—office, bedroom, or family space—not storage-only zones. If the whole level is unfinished storage, test in the most central lived-in candidate on that level, then retest after you convert space to regular use.

    How far from a window does the test need to be?

    Keep the detector at least 3 feet (90 cm) from exterior windows, doors, or other openings to outdoors. That distance reduces skew from outdoor air mixing during entry and exit. If the room has no exterior openings, stay at least 1 foot from the exterior wall instead.

    Can I run ceiling fans or the HVAC during the test?

    Follow your kit instructions and EPA closed-house rules. Short-term tests generally require closed windows and no fans that import outdoor air. Normal heating and cooling operation is usually acceptable, but do not point supply vents at the detector or run whole-house fans that change building pressure during a short-term exposure.

    What if my result is above 4 pCi/L?

    EPA’s action level for follow-up is 4.0 pCi/L. Confirm with a second test—often a long-term measurement or another short-term under closed-house conditions—before committing to mitigation. Fix placement errors before you treat a bad reading as a structural radon problem.


  • EPA Radon Testing Protocol: Official Guidelines Explained

    EPA Radon Testing Protocol: Official Guidelines Explained

    The Distillery
    — Brew № 1 · Radon Mitigation

    The EPA’s radon testing protocols are the foundation for nearly every state radon program, real estate testing standard, and measurement professional certification in the United States. Understanding what the EPA actually requires — not what a neighbor summarizes or a contractor implies — lets you evaluate whether your testing was conducted correctly and whether your results are defensible.

    EPA Radon Testing Guidance: Overview

    The EPA’s primary radon testing guidance documents for homeowners are the A Citizen’s Guide to Radon and the Home Buyer’s and Seller’s Guide to Radon. For measurement professionals, the EPA Radon Measurement Proficiency Program established the original certification framework that NRPP and NRSB now administer. AARST-ANSI measurement standards (MAMF, ANSI/AARST Series) build on EPA guidance and are the operative standards for professional measurement.

    Closed-House Conditions: The Core Protocol Requirement

    Closed-house conditions are the most important and most frequently violated component of EPA’s short-term testing protocol. Without closed-house conditions, short-term results are not comparable to the EPA action level and may significantly underestimate actual radon levels.

    What Closed-House Conditions Mean

    • Keep all windows and exterior doors closed during the test and for 12 hours before the test device is placed
    • Do not operate whole-house fans, attic fans, or similar ventilation during the test or the 12-hour pre-test period
    • Normal HVAC operation is permitted — heating and cooling systems that recirculate interior air (central HVAC) may run normally
    • Ceiling fans: permitted
    • Kitchen and bathroom exhaust fans: minimize use; brief operation for cooking or showering is acceptable, but extended operation creates pressure differential
    • Fireplace dampers: keep closed if not in use; do not operate fireplaces during the test

    Why Closed-House Conditions Matter

    Open windows introduce large volumes of outdoor air (~0.4 pCi/L radon) that dilute indoor radon levels to artificially low values. A home with actual indoor radon of 8.0 pCi/L may test at 3.0–4.0 pCi/L with windows routinely open — below the action level, creating a false impression of safety. This is why summer testing with open windows is unreliable and why EPA requires closed-house conditions for short-term tests.

    Device Placement Protocol

    EPA’s placement requirements for radon test devices:

    • Level: Lowest level that is used or could be used as living space — including unfinished basements if they could be finished, and basements where family members spend any time regularly
    • Height: At least 20 inches above the floor, within the breathing zone
    • Wall distance: At least 12 inches from any wall
    • Avoid: Drafts from windows, doors, HVAC supply/return vents, exterior walls; direct sunlight; humidity sources (sump pits, laundry, showers)
    • Do not place in: Kitchens, bathrooms, crawl spaces, or closets
    • Placement in room: Central to the room is ideal; near where occupants typically spend time is the goal — not in an uninhabited corner

    EPA’s Two-Test Decision Protocol

    For initial testing of a home, EPA’s protocol is designed to balance speed against accuracy:

    If Initial Short-Term Test is Below 4.0 pCi/L

    No immediate action required. Retest in 2 years. If the result was between 2.0 and 3.9 pCi/L, consider a long-term test to confirm the annual average. Levels in this range may be higher during different seasons or weather conditions.

    If Initial Short-Term Test is 4.0–7.9 pCi/L

    Follow up with either a second short-term test or a long-term test before making a mitigation decision. The rationale: a single 48-hour test in this range has sufficient measurement uncertainty that a confirmatory test substantially improves confidence in the true annual average level. If the confirmatory test also comes in at or above 4.0 pCi/L, mitigate. Average the two short-term results if using two short-term tests.

    If Initial Short-Term Test is 8.0 pCi/L or Higher

    EPA recommends proceeding to mitigation without waiting for a confirmatory test. At this concentration, the risk from continued exposure during a second test period is not justified by the additional certainty. Contact a certified radon mitigator and schedule installation.

    The 4.0 pCi/L Action Level: Context and Criticism

    EPA’s 4.0 pCi/L action level was established in the 1980s based on risk assessments available at the time and the practical cost of mitigation. It has not been formally revised since, despite significant advances in radon health research.

    Notable context:

    • The World Health Organization reference level is 2.7 pCi/L (100 Bq/m³) — lower than EPA’s threshold
    • EPA itself notes that “radon levels less than 4 pCi/L still pose a risk, and in many cases may be reduced” — the 4.0 level is an action threshold, not a safety threshold
    • EPA’s own long-term goal is to reduce indoor radon to outdoor air levels (0.4 pCi/L), acknowledging that any indoor radon above background carries some risk
    • Several European countries have adopted national reference levels of 1.4–2.7 pCi/L (50–100 Bq/m³)

    For practical purposes: the 4.0 pCi/L threshold determines when EPA recommends mandatory action. Below 4.0 pCi/L, mitigation is EPA-recommended for consideration between 2.0–3.9 pCi/L and is always a personal risk decision.

    EPA Guidance on Specific Testing Situations

    Real Estate Transactions

    EPA recommends testing in real estate transactions. When time is limited (common in transaction timelines), short-term tests are acceptable. EPA provides guidance that real estate tests should follow closed-house protocols strictly and that buyers should understand the limitations of a single 48-hour test relative to annual average exposure.

    Post-Mitigation Testing

    EPA recommends testing 24+ hours after system activation (if continuous monitor) or placing a charcoal canister at least 24 hours post-activation for a minimum 48-hour test. If results are still at or above 4.0 pCi/L, contact the mitigator — the system requires adjustment.

    New Construction (RRNC)

    EPA recommends testing new homes with RRNC passive systems after at least 60 days of occupancy, under normal living conditions (closed-house protocol not required for this application — the extended occupancy averages conditions sufficiently). If results are at or above 4.0 pCi/L, activate the passive system with a fan.

    Frequently Asked Questions

    What is EPA’s recommended radon action level?

    EPA’s action level is 4.0 pCi/L — the concentration at which EPA recommends mitigation. EPA also recommends considering mitigation at 2.0–3.9 pCi/L, acknowledging that radon at those levels still poses meaningful cumulative health risk, particularly for households with smokers or young children.

    Does EPA require professional radon testing?

    EPA does not federally mandate professional testing for homeowners conducting their own radon assessments. DIY test kits from NRPP- or NRSB-certified labs are EPA-endorsed for homeowner use. Professional certified testing is required for real estate transactions in some states, for regulatory compliance contexts, and when chain-of-custody documentation is needed.

    What is the difference between EPA and WHO radon action levels?

    EPA’s action level is 4.0 pCi/L (148 Bq/m³). The WHO reference level is 2.7 pCi/L (100 Bq/m³). The WHO level reflects more recent health evidence and is lower. In practice, both acknowledge significant risk below their respective thresholds — the difference is where each organization draws the line for recommended action.


  • Post-Mitigation Radon Testing: Timing & Expected Results

    Post-Mitigation Radon Testing: Timing & Expected Results

    The Distillery
    — Brew № 1 · Radon Mitigation

    Installing a radon mitigation system is not the final step — testing after installation is. A mitigation system without post-mitigation testing is a system with no verified outcome. You do not know it is working; you only know it is running. Post-mitigation testing is how you confirm the system achieved its purpose, satisfy warranty requirements, and establish a baseline for future monitoring.

    When to Conduct Post-Mitigation Testing

    EPA and AARST recommend testing within 24 hours of system activation if using a continuous electronic monitor, or placing a short-term charcoal canister at least 24 hours after the fan is turned on and running it for a minimum of 48 hours. The 24-hour delay allows the system to fully pressurize the sub-slab zone and reach equilibrium — results taken in the first few hours of operation may not represent steady-state performance.

    Do not wait weeks or months to test. The purpose of post-mitigation testing is to verify the system is performing as designed while any issues are still under the contractor’s workmanship warranty. Most warranties require the homeowner to conduct post-mitigation testing and notify the contractor of any elevated results within a defined window.

    What Test to Use for Post-Mitigation Verification

    A 48-hour charcoal canister is the standard post-mitigation test for residential applications. It provides a fast result (3–7 business days after mailing) and is the test type most commonly specified in contractor warranties and real estate disclosure contexts.

    Closed-house conditions are required during the 48-hour test period and for 12 hours prior to device placement. This is the same protocol used for any short-term test — windows closed, no whole-house fans, normal HVAC operation permitted.

    Some contractors conduct post-mitigation testing themselves using a professional continuous monitor, providing same-day or next-day results. This is faster but has a potential conflict of interest — a contractor confirming their own work. For independent verification, homeowners can place their own charcoal canister alongside the contractor’s device.

    Where to Place the Post-Mitigation Test Device

    Same placement protocol as any residential radon test:

    • Lowest livable level of the home — typically the same floor where the pre-mitigation test was conducted
    • Breathing zone: at least 20 inches above the floor, at least 12 inches from any wall
    • Away from drafts, HVAC vents, sump pits, and exterior walls
    • Undisturbed for the full 48-hour period

    Do not place the test directly under the suction point, adjacent to the riser pipe, or in the mechanical room where the fan vibration could affect the device. Place in the living area or bedroom where occupants actually spend time — the location most relevant to actual exposure.

    What Post-Mitigation Results to Expect

    A properly installed single-suction-point ASD system with good sub-slab aggregate and thorough slab sealing typically achieves:

    • 85–99% reduction from pre-mitigation levels
    • Final levels of 0.3–1.5 pCi/L for most homes
    • Homes that previously tested at 20+ pCi/L commonly achieve 0.5–2.0 pCi/L post-mitigation

    EPA’s target is below 4.0 pCi/L. Most certified mitigators target below 2.0 pCi/L as a workmanship standard, and well-executed installations on homes with good aggregate routinely achieve 0.5 pCi/L or lower.

    What If Post-Mitigation Results Are Still Elevated?

    A post-mitigation result at or above 4.0 pCi/L indicates the system is not achieving adequate reduction. This is not uncommon — national data suggests that 10–15% of initial installations require a callback before achieving target levels. The most common causes:

    • Insufficient suction field coverage: One suction point is not covering the full slab footprint — additional suction points needed
    • Unsealed bypass pathways: Gaps in the slab sealing — expansion joints, floor drains, sump pit, pipe penetrations — allow radon to enter the home directly without passing through the sub-slab vacuum zone
    • Fan undersized for aggregate conditions: Post-construction reveal that sub-slab fill is denser than the diagnostic suggested — a higher-capacity fan or additional suction point is needed
    • Block wall contribution: In CMU block basement homes, the block wall cores are a radon pathway that sub-slab depressurization alone does not address
    • Test conditions violated: Radon post-mitigation tests that are conducted with windows open or whole-house fans running produce unreliable results that may understate or overstate actual levels

    Contact your mitigator immediately when post-mitigation results are elevated. Most reputable contractors include workmanship warranties of 1–5 years that cover exactly this scenario — returning to add suction points, improve sealing, or upgrade fan capacity at no additional charge if results do not meet the contractual target.

    Ongoing Retesting After Mitigation

    EPA recommends retesting a mitigated home every 2 years. Reasons:

    • Fan performance can degrade over time — a failing fan that still runs may not generate adequate suction
    • Foundation settling creates new cracks and pathways that the existing system may not fully address
    • Remodeling work — finishing a basement, adding a room over a crawl space — changes the building’s pressure dynamics
    • Real estate transactions require current test results even in mitigated homes

    The U-tube manometer provides daily visual confirmation that the fan is generating suction, but it does not measure actual radon concentration. Monthly manometer checks plus biennial radon tests is the recommended maintenance protocol for a mitigated home.

    Frequently Asked Questions

    How soon after radon mitigation can I test?

    Place the test device at least 24 hours after the mitigation system is activated and run it for a minimum of 48 hours under closed-house conditions. Testing in the first few hours of system operation may not reflect steady-state performance. Most contractors recommend testing within the first 30 days of installation.

    What radon level should I expect after mitigation?

    Most properly installed ASD systems achieve 0.3–2.0 pCi/L regardless of the pre-mitigation starting level. EPA’s target is below 4.0 pCi/L; reputable contractors target below 2.0 pCi/L as a workmanship standard. If your post-mitigation result is at or above 4.0 pCi/L, contact your contractor immediately — a callback is almost always covered under the workmanship warranty.

    Do I need to retest after radon mitigation every year?

    EPA recommends retesting every 2 years in a mitigated home. Annual retesting is not required but provides more frequent confirmation of continued system performance. A long-term alpha track detector left in place for 90 days to a year provides the most accurate ongoing average.

    My post-mitigation test shows 3.5 pCi/L — is that acceptable?

    It is below EPA’s 4.0 pCi/L action level, but it is also not what a well-performing system typically achieves. Most single-point ASD installations in homes with standard aggregate conditions reach 0.5–2.0 pCi/L. A result of 3.5 pCi/L suggests the system may have room for improvement — additional sealing, a second suction point, or a fan upgrade. Discuss with your contractor whether a callback is warranted.


  • Short-Term Radon Test vs. Long-Term: Which Do You Need?

    Short-Term Radon Test vs. Long-Term: Which Do You Need?

    The Distillery
    — Brew № 1 · Radon Mitigation

    The difference between a short-term and long-term radon test is not just duration — it is what each result actually tells you. A 48-hour test gives you a snapshot of radon during specific conditions. A 90-day test gives you a seasonal average. A year-long test gives you the most accurate picture of your true annual exposure. Understanding when each applies prevents both under-reaction to real risk and over-reaction to a weather-influenced spike.

    Short-Term Tests: The Screening Tool

    Short-term radon tests run from a minimum of 48 hours up to 90 days. The most common residential short-term test is the activated charcoal canister, run for 48–96 hours under closed-house conditions.

    How Charcoal Canister Tests Work

    An activated charcoal canister absorbs radon gas from the surrounding air during the exposure period. At the end of the test, you seal the canister and mail it to a laboratory. The lab measures gamma radiation emitted by radon decay products that have accumulated in the charcoal, calculates the average radon concentration over the test period, and reports the result in picocuries per liter (pCi/L).

    Short-Term Test Accuracy and Limitations

    Short-term results are inherently variable because radon levels fluctuate by 30–50% day to day in many homes, driven by:

    • Barometric pressure: Low pressure pulls more soil gas into the home; high pressure suppresses it
    • Temperature differential: Greater indoor-outdoor temperature difference strengthens stack effect and increases radon draw
    • Wind: Wind pressure against the house affects sub-slab pressure dynamics
    • Precipitation: Rain saturates soil, reducing gas permeability and temporarily suppressing radon entry
    • HVAC operation: Forced-air systems can both dilute and redistribute radon within the home

    A single 48-hour test during an unusually high-pressure, warm, dry period may significantly underestimate actual levels. The same home tested during a cold snap with falling barometric pressure may read 30–50% higher than average. This variability is why EPA guidance does not recommend making final mitigation decisions solely on a single short-term result in the 4.0–8.0 pCi/L range.

    When Short-Term Tests Are the Right Choice

    • Initial screening: If you have never tested your home, a short-term test is the fastest way to identify whether a problem may exist
    • Real estate transactions: When time constraints (contract deadlines) prevent long-term testing, short-term tests are universally accepted with appropriate disclosure
    • Post-mitigation verification: After installing a radon system, a 48-hour charcoal test placed at least 24 hours post-installation verifies the system is working; EPA recommends this within 24 hours of system activation
    • Initial high-result screening: If the initial test returns 8.0 pCi/L or higher, EPA recommends proceeding to mitigation without waiting for a confirmatory long-term test — the risk is sufficient

    Long-Term Tests: The Accurate Baseline

    Long-term tests run for a minimum of 90 days; one-year tests are the gold standard. The standard device is an alpha track detector — a small card with a clear plastic film (CR-39 or similar) that records microscopic damage tracks from alpha particles emitted by radon decay products over the exposure period. At the end of the test, the lab chemically etches the film and counts the tracks under a microscope, calculating average radon concentration.

    Why Long-Term Tests Are More Accurate

    By averaging radon levels across multiple seasons — or ideally a full year — long-term tests smooth out the barometric, temperature, and weather-driven variability that makes short-term results uncertain. A 90-day winter test captures the highest-radon season and provides a reasonably conservative estimate of annual average. A full-year test captures all seasonal patterns.

    Studies comparing matched short-term and long-term measurements in the same homes consistently show that short-term tests, when compared to annual averages, overestimate the annual average in about half of cases and underestimate it in the other half — with individual test variance of ±40–50% common. Long-term tests reduce this uncertainty substantially.

    When Long-Term Tests Are the Right Choice

    • Confirming a short-term result in the 4.0–8.0 pCi/L range: Before investing $1,000–$2,500 in mitigation, a long-term confirmation test establishes that elevated levels are chronic rather than a test-period anomaly
    • Establishing a baseline in a new home: A one-year test after moving in provides the most accurate picture of actual exposure
    • Routine monitoring in a mitigated home: An annual alpha track detector run year-round provides ongoing confirmation of system performance
    • Research or legal purposes: Situations requiring the highest-accuracy radon measurements

    EPA Decision Protocol: Which Test When

    Situation Recommended Test Action if Elevated
    First-time testing, no rush Long-term (90+ days) Mitigate if annual avg ≥ 4.0 pCi/L
    First-time testing, want quick answer Short-term (48–96 hrs) Follow up with long-term if 4.0–8.0 pCi/L
    Short-term result ≥ 8.0 pCi/L Mitigate immediately No confirmatory test needed
    Short-term result 4.0–8.0 pCi/L Second short-term or long-term Mitigate if confirmed ≥ 4.0 pCi/L
    Real estate transaction Short-term (48–96 hrs) Negotiate mitigation in contract
    Post-mitigation verification Short-term (48–96 hrs), 24+ hrs after install Retest or callback if still ≥ 4.0 pCi/L
    Ongoing monitoring (mitigated home) Long-term (annual alpha track) Schedule callback if ≥ 4.0 pCi/L

    Continuous Radon Monitors: The Third Option

    Continuous electronic radon monitors (Airthings Wave, Corentium, RadonEye) provide real-time radon readings and running averages. They do not replace lab-analyzed test kits for official measurements but offer ongoing visibility into radon fluctuations that neither charcoal canisters nor alpha track detectors can provide.

    Continuous monitors are most valuable for:

    • Monitoring a mitigated home between formal retests
    • Understanding diurnal and seasonal radon patterns in your home
    • Detecting rapid changes that indicate fan failure or new entry pathways
    • Confirming that closed-house conditions during a short-term test are being maintained

    Consumer-grade continuous monitors have measurement uncertainty of ±10–20% at low radon levels and are not accepted as certified measurements for real estate transactions or regulatory compliance. They are monitoring tools, not certification tools.

    Frequently Asked Questions

    Which radon test is more accurate — short-term or long-term?

    Long-term tests are more accurate representations of actual annual average radon exposure because they average out the weather- and pressure-driven fluctuations that make short-term results variable. A 90-day or one-year alpha track test provides a more reliable basis for mitigation decisions than a single 48-hour charcoal test.

    Can I use a short-term test to decide whether to mitigate?

    Yes, with caveats. If your short-term result is 8.0 pCi/L or higher, EPA recommends mitigation without a confirmatory test. If it is between 4.0 and 8.0 pCi/L, a follow-up long-term or second short-term test is advisable before investing in mitigation, to confirm the result is not an anomalous spike.

    How long should I run a radon test?

    Minimum 48 hours for a charcoal short-term test under closed-house conditions. For the most accurate annual average, run an alpha track detector for 90 days to one year under normal living conditions. Longer is more accurate.

    Do I need closed-house conditions for a long-term radon test?

    No. Long-term tests (alpha track detectors, 90+ days) are designed to run under normal living conditions — windows open in summer, closed in winter, normal HVAC operation. The extended duration averages out all of these variations. Closed-house conditions are required only for short-term charcoal tests (48–96 hours).


  • How to Test for Radon in Your Home: Complete Guide

    How to Test for Radon in Your Home: Complete Guide

    The Distillery
    — Brew № 1 · Radon Mitigation

    Radon testing is the only way to know whether your home has elevated radon levels. You cannot smell it, see it, or detect it with any sense — and the homes with the highest radon levels often show no correlation with geography, age, or construction style. The EPA estimates that 1 in 15 U.S. homes has elevated radon. Testing takes as little as 48 hours and costs $15–$30 for a DIY kit.

    Why You Need to Test

    Radon is the second leading cause of lung cancer in the United States after cigarette smoking, responsible for approximately 21,000 deaths annually according to the EPA. The risk is cumulative — it is the product of concentration and time. A home at 4.0 pCi/L poses roughly the same lifetime lung cancer risk as smoking half a pack of cigarettes per day. A home at 20 pCi/L — not uncommon in high-radon zones — roughly equals smoking two packs per day.

    The only way to know your home’s radon level is to test it. No map, no neighborhood average, and no visual inspection can substitute for a measurement in your specific home.

    Short-Term vs. Long-Term Radon Tests

    Short-Term Tests (2–90 Days)

    Short-term tests are the most commonly used initial screening method. The standard residential short-term test is a charcoal canister test run for 48–96 hours. Results are available within 3–7 business days after mailing the device to a lab.

    • Duration: 48 hours minimum (EPA); 48–96 hours typical for charcoal devices
    • Device type: Activated charcoal canister or electret ion chamber
    • Conditions required: Closed-house conditions (see below)
    • Best for: Initial screening, pre-purchase testing, post-mitigation verification
    • Limitation: A single short-term test captures a snapshot — radon levels fluctuate with barometric pressure, temperature, and season. A short-term result may be higher or lower than the home’s true annual average.

    Long-Term Tests (90+ Days)

    Long-term tests provide a more accurate picture of the home’s actual annual average radon exposure. The standard device is an alpha track detector — a small card with a special plastic film that records radon decay particle tracks over time.

    • Duration: 90 days to 1 year (one year is ideal)
    • Device type: Alpha track detector
    • Conditions required: Normal living conditions (no closed-house protocol)
    • Best for: Confirming short-term results, annual monitoring, determining true annual average
    • Advantage: Averages out seasonal and pressure fluctuations — provides the most accurate basis for mitigation decisions

    EPA guidance: if a short-term test shows between 4.0 and 8.0 pCi/L, conduct a follow-up long-term test or a second short-term test before deciding on mitigation. If the initial short-term test shows 8.0 pCi/L or higher, proceed to mitigation without waiting for a confirmatory test — the risk is sufficient to act immediately.

    Where to Place the Radon Test Device

    Placement determines whether your result is meaningful. The EPA’s placement protocol:

    • Level: Test in the lowest level of the home that is currently used or could be used as living space — even if you do not currently occupy it. If you have an unfinished basement you plan to finish, test there.
    • Location within the room: Place the device in the breathing zone — at least 20 inches above the floor and at least 12 inches from any wall
    • Away from drafts: Do not place near windows, doors, HVAC vents, or exterior walls where air movement can dilute results
    • Away from humidity sources: Do not place near sump pits, laundry areas, or bathrooms — excessive humidity can affect charcoal canister performance
    • Accessible but undisturbed: The device should be able to sit undisturbed for the full test duration — not in a high-traffic area where it might be moved

    Closed-House Conditions

    Short-term tests require closed-house conditions during the test and for 12 hours before the test begins. Closed-house means:

    • All windows and exterior doors closed except for brief normal entry/exit
    • No whole-house fans or attic fans running
    • Normal HVAC operation is permitted (heating and cooling systems can run — they recirculate interior air)
    • Ceiling fans are permitted
    • Fireplace dampers closed (if not in use)

    Closed-house conditions prevent outdoor air from diluting indoor radon to artificially low levels during the test. When conditions are not maintained, short-term results systematically underestimate actual radon levels — exactly the wrong direction for a safety measurement.

    Interpreting Your Results

    • Below 2.0 pCi/L: Below EPA’s average indoor radon level of 1.3 pCi/L if the home is new. No action required; retest in 2 years.
    • 2.0–3.9 pCi/L: Between the national average and the EPA action level. Consider a long-term test to confirm. Some homeowners choose to mitigate at this level regardless, particularly if they have young children or smokers in the home.
    • 4.0–7.9 pCi/L: At or above EPA action level. EPA recommends mitigation. Conduct a confirmatory long-term or second short-term test if time allows, then mitigate.
    • 8.0 pCi/L or higher: Mitigate without waiting for confirmatory testing. At this level the health risk warrants immediate action.

    DIY vs. Professional Testing

    DIY test kits (charcoal canisters or alpha track detectors) purchased from hardware stores or online labs are the most cost-effective option for initial and ongoing screening. Cost: $15–$30 including lab analysis. Most state radon programs recommend purchasing from a lab certified by the National Radon Proficiency Program (NRPP) or National Radon Safety Board (NRSB).

    Professional testing uses the same device types but is conducted and placed by a certified radon measurement professional. Professional testing is required or preferred in specific situations:

    • Real estate transactions where the buyer requires a certified measurement
    • Post-mitigation verification where the mitigator or a warranty requires professional confirmation
    • Rental properties in states where landlord testing requirements specify professional measurement
    • Situations involving litigation or insurance where certified chain-of-custody testing is required

    How Often to Test

    • Initial test: If you have never tested, test now — regardless of when you moved in or how long you have lived there
    • After mitigation: Test within 24 hours of system installation (if using a continuous monitor) or place a short-term test 24+ hours post-installation; run for 48 hours minimum
    • Routine retesting: EPA recommends retesting every 2 years even in mitigated homes — to confirm continued performance and catch new entry pathways from foundation settling or renovation
    • After renovations: Any work that involves the foundation, basement, or significant changes to the HVAC system warrants a new test
    • When buying a home: Always test — or require a recent test result — before closing

    Frequently Asked Questions

    How accurate are DIY radon test kits?

    DIY charcoal canister kits analyzed by NRPP- or NRSB-certified labs are accurate to within ±10–15% under controlled conditions. This is sufficient precision for screening decisions. The larger source of variation is not the device itself but testing conditions — an improperly placed device or violated closed-house conditions introduce more error than the device’s inherent measurement uncertainty.

    What time of year is best to test for radon?

    Winter typically produces higher radon readings than summer — windows are kept closed, stack effect is stronger, and atmospheric pressure patterns tend to draw more soil gas into the home. Testing in winter gives a closer approximation of worst-case conditions. However, because any result at or above 4.0 pCi/L warrants mitigation regardless of season, the best time to test is simply now — not after waiting for an optimal season.

    Can I test for radon myself or do I need a professional?

    DIY testing is appropriate and recommended for the vast majority of homeowners. Purchase a certified short-term or long-term kit, follow the placement and closed-house instructions, and mail to the lab. Professional testing is required only for real estate transactions in some states, post-litigation measurements, or situations where certified chain-of-custody documentation is needed.

    My neighbor’s home tested low — does that mean mine will too?

    No. Radon levels vary dramatically between adjacent homes — sometimes between rooms in the same home. Differences in sub-slab aggregate, foundation type, construction methods, HVAC configuration, and soil permeability can produce completely different radon levels in homes built side by side. Your home must be tested independently.


    Related Radon Resources


  • AI Agents vs Chatbots & Automations: Key Differences

    AI Agents vs Chatbots & Automations: Key Differences

    These terms get used interchangeably. They’re not the same thing. Here’s the actual distinction between each one, where the lines get genuinely blurry, and which category fits what you’re actually trying to build.

    Chatbots

    A chatbot is a software interface designed to simulate conversation. The defining characteristic: it’s stateless and reactive. You send a message; it responds; the exchange is complete. Each interaction is largely independent.

    Traditional chatbots (pre-LLM) operated on decision trees — “if the user says X, respond with Y.” Modern LLM-powered chatbots use language models to generate responses, which makes them dramatically more capable and flexible — but the fundamental architecture is the same: you ask, it answers, you ask again.

    What chatbots are good at: answering questions, providing information, routing conversations, handling defined service scenarios with natural language flexibility. What they’re not: action-takers. A chatbot can tell you how to cancel your subscription. An agent can cancel it.

    Automations

    Automations are rule-based workflows that execute when triggered. Zapier, Make, and similar tools are the canonical examples. When event A happens, do B, then C, then D.

    The key characteristic: the path is predefined. Every step is specified by the person who built the automation. If an unexpected situation arises that the automation wasn’t built for, it either fails or skips the step. There’s no reasoning about what to do — there’s only executing the specified path or not.

    Automations are highly reliable for well-defined, stable processes. They break when edge cases arise that weren’t anticipated. They scale perfectly for the exact task they were built for; they don’t generalize.

    APIs

    An API (Application Programming Interface) is a communication contract — a defined way for software systems to talk to each other. APIs are infrastructure, not agents or automations. They’re the mechanism through which agents and automations take action in external systems.

    When an AI agent “uses Slack,” it’s calling Slack’s API. When an automation “posts to Twitter,” it’s calling Twitter’s API. The API is the door; agents and automations are the things that open it.

    Conflating APIs with agents is a category error. An API is a tool, not a behavior pattern.

    AI Agents

    An AI agent takes a goal and figures out how to accomplish it, using tools available to it, handling unexpected situations along the way, without a human specifying each step.

    The distinguishing characteristics versus the above:

    • vs. Chatbots: Agents take action in the world; chatbots respond to messages. An agent can book the flight, not just tell you how to book it.
    • vs. Automations: Agents reason about what to do next; automations execute predefined paths. When an unexpected situation arises, an agent adapts; an automation fails or skips.
    • vs. APIs: APIs are tools an agent uses; they’re not the agent itself. The agent is the reasoning layer that decides which API to call and what to do with the result.

    Where the Lines Actually Blur

    In practice, real systems often combine these categories:

    LLM-powered chatbots with tool access: A customer service chatbot that can look up your order status, initiate a return, and send a confirmation email is starting to look like an agent — it’s taking actions, not just responding. The boundary between “advanced chatbot” and “limited agent” is genuinely fuzzy.

    Automations with AI decision steps: A Zapier workflow with an OpenAI or Claude step in the middle isn’t purely rule-based anymore — the AI step can produce variable outputs that affect what the automation does next. This is a hybrid: mostly automation, partly agentic.

    Agents with constrained scopes: An agent restricted to a single tool and a narrow task class starts to look like a sophisticated automation. The more constrained the scope, the more the distinction collapses in practice.

    The useful question isn’t “what category is this?” but “is this system reasoning about what to do, or executing a predefined path?” That’s the actual distinction that matters for how you build, monitor, and trust it.

    Why the Distinction Matters Operationally

    Reliability profile: Automations fail predictably — when an edge case hits a path that wasn’t built. Agents fail unpredictably — when their reasoning goes wrong in a way you didn’t anticipate. Different failure modes require different monitoring approaches.

    Maintenance overhead: Automations require explicit updates when processes change. Agents adapt to process changes automatically — but may adapt in unexpected ways that need to be caught and corrected.

    Auditability: Automations are fully auditable — you can read the workflow and know exactly what it does. Agents are less auditable — you can inspect their actions, but not fully predict them in advance. For compliance-sensitive contexts, this matters significantly.

    Build cost: Automations are faster to build for well-defined, stable processes. Agents are faster to deploy when the process is complex, variable, or not fully specified — because you’re specifying a goal rather than a procedure.

    For what agents can actually do in production: What AI Agents Actually Do. For a business owner’s introduction: AI Agents Explained for Business Owners. For hosted agent infrastructure: Claude Managed Agents FAQ.


    Hosted agent infrastructure pricing: Claude Managed Agents Pricing Reference.