Uncategorized - Tygart Media

Category: Uncategorized

  • The Work Order Desk

    The Work Order Desk

    New on the bench this week: the Work Order Desk.

    Four fixed-price jobs, each with a written definition of done and a proof sheet when it ships:

    • GA4 baseline + key events, $450
    • Citation scan + repair, $450
    • Fleet friction pass, $750
    • Sourced research run, $750

    You submit the form. You get a receipt with a work-order number. You get a written verdict within one business day. The price is agreed before anyone pays — the checkout link rides inside the verdict, after triage, not before it.

    No calls. No retainer pitch. No “let’s hop on a quick Zoom” standing between you and a finished piece of work.

    Before we told anybody about it, we ran a test work order through it ourselves — form, receipt, logging in two places so a submission can’t silently vanish. That last part is the whole design. A front door that loses orders quietly is worse than no front door.

    Built it this week. It works. Doors open as soon as the address is on it.

  • Review the Run, Not the Diff: Cursor’s Shareable Canvases in a Fleet Loop

    Review the Run, Not the Diff: Cursor’s Shareable Canvases in a Fleet Loop

    What shipped on October 16

    Cursor’s changelog entry dated October 16, 2026 — “Cloud Agent Canvases and Environment Improvements” — is three short sections long, and one of them changes the shape of a finished run: “Cloud agents can now build interactive canvases as part of their work. Share a finished canvas with your team by sending its link.” That sentence is Cursor’s. Everything in this section is theirs, from that changelog entry and the Canvases page of their docs, read October 19, 2026.

    A canvas, in their docs, is an interactive artifact that renders next to the chat: a standalone view laid out with sections, stats, and tables, instead of a long markdown table or a code block to scroll through. Ask an agent for a dashboard, an analysis, an audit, or a report, and Cursor opens the result in a canvas when a visual view is the better fit. The canvas is saved to the workspace’s canvas list, so you can reopen it, edit it, and rerun it later with fresh data.

    Sharing is a publish, not a forward. From the canvas toolbar you Publish — which publishes a share or refreshes an existing one — then copy the link and send it. What the link opens is a live snapshot: the same layout, charts, and tables, without rerunning the agent and without digging through the chat history. Teammates open it in the browser with read-only access. A Shared Canvases page on the dashboard lists the shares you published yourself, so you can reopen, copy, or delete your own; it does not list a teammate’s shares — for those, you ask for the link.

    The same release carried two more items, logged here for completeness. The Environments API is available in beta: a programmatic way to create and manage the cloud environments agents run in. And the environments themselves grew: up to 300 repositories per environment, with large environments loading 5x faster — Cursor’s numbers, not measurements of ours. Neither item is this piece’s subject; both are on the desk’s check list.

    The gate is part of the story

    A canvas link is not a public link. The docs are explicit: anyone on your team can open the link in the browser. Only members of your team can open a share, and you need to be on a team to share at all. Sending the link outside the team sends a door the recipient cannot walk through — which makes the canvas a team surface, not a publishing surface.

    Sharing is also a paid-plan surface with conditions attached. Shares can be created on paid plans — Premium and higher, Teams, Enterprise, and the legacy Pro, Pro+, and Ultra tiers; free accounts cannot create shares. Sharing requires a privacy mode that allows data storage, so Legacy Privacy Mode blocks it. And a team admin can turn shared canvases off for the whole organization from team settings. A shop adopting the feature checks those three gates before it builds a habit on them.

    A snapshot is not the run itself. The canvas shows the view as published; the chat, the reasoning, and the diff stay behind it. When the underlying numbers move, the share does not move with them — refreshing it is another Publish. A reviewer who needs the execution record still goes to the record. The canvas is the board on the wall, not the flight recorder.

    Where it lands in our loop

    Our loop fits in one sentence: a work order is written with everything the executor needs, the agent flies it, and the result is debriefed at the receiving end — the live page checked in a browser, the delivered file opened, the count re-added by hand. The debrief is where quality is decided here, and its surface depends on the seat. A cloud run launched over the API hands back result text. A Desktop sitting hands back a transcript and screenshots at verification points, which this shop trusts over any summary.

    A canvas inserts a third surface into that debrief: the agent arranges its own evidence — sections, stats, tables — into the board the reviewer actually opens. For the data-heavy work this shop runs constantly — citation pulls, model-catalog diffs, site audits — a rendered board is the shape the answer wanted anyway. Cursor’s docs make the same point from their side: canvases earn their keep on data-intensive tasks, where information arranged non-linearly is easier to digest than a wall of text.

    The approval moment in this shop is a tap on finished work. Will reviews results, not work in progress, and the decision lands on an artifact he can read in one pass. A canvas link is the first Cursor surface shaped exactly like that decision: open the link, read the board, decide. No repo, no diff, and no IDE sits between the finished result and the person approving it.

    The lane question the feature raises is a seat question. What reaches Stefani and Ziggy today is finished artifacts — live pages, PDFs, one-line summaries — because they work outside the operator’s seat. A canvas would be the cheapest of those artifacts to produce and the easiest to read, if the recipients hold team seats. The docs make team membership the door, so who holds a seat becomes a setup decision to make on purpose — not an assumption to discover after a link bounces off someone it was meant for.

    What is not established, labeled plainly: our production lane launches cloud agents over the API and receives text back. The docs describe canvases in the app surfaces — the Agents Window, the canvas toolbar, the dashboard. Whether a run launched through the API can produce a canvas, or return a share link, is not in the docs we read and not in our records. That question goes on the check list. It does not go into the workflow.

    One more mapping, labeled as intent rather than record. The docs say common canvas workflows can be packaged as skills, so every run that uses the skill returns the same output shape. In this shop’s language, that is a debrief template: the same board for every fleet run — what was asked, what landed, what the counts say, what failed. A debrief-canvas skill is the first experiment this change earns here. It has not run yet.

    Our record, stated plainly

    No canvas has appeared in our runs yet. Our run record — every cloud agent this desk has launched, reconciled from the API and watched daily — contains no canvas artifact and no share link as of October 19, 2026. The only “canvas” in that record is an agent named for a Google Maps canvas, a different sense of the word, and a standing reminder to grep carefully before claiming a first.

    So this piece is a map, written before the landing: what the feature is on the vendor’s own pages, what its gates are, and where it would sit in a loop that already exists. The check is decided. The next data-heavy Desktop sitting asks for its debrief as a canvas, by name, and the canvas gets read against the same sitting’s transcript — the surface we trust — before the desk adopts it anywhere. If the board and the record disagree, the record wins, and the disagreement gets written down on this page with a date.

    Method & settings — this piece

    Sources: Cursor changelog, entry dated October 16, 2026; Cursor Docs, “Canvases” (read October 19, 2026). Vendor facts are stated as the vendor’s; the secondary write-ups that surfaced this item were used as leads only, never as sources

    Our surfaces in this mapping: Desktop 3.25.9 on the laptop (read from the install itself, October 19, 2026); cloud agents over the API (model catalog baseline 46 models, October 16, 2026)

    Our canvas record: none — no canvas artifact or share link in our run record as of October 19, 2026. This is a mapping piece, not a hands-on report

    Desk rule: every fact carries its provenance and date — our record, or Cursor’s page, never blended

    Filed under the Cursor desk — the desk that runs Cursor as a production harness.
  • What’s New in Cursor Is a Claim. Here’s How We Check It.

    What’s New in Cursor Is a Claim. Here’s How We Check It.

    A changelog entry is a claim

    When a platform ships an upgrade, the changelog tells you what the vendor wants you to believe about it. Sometimes the claim is the whole story. Sometimes the feature is real and irrelevant to your work. Sometimes — the dangerous case — something you depend on moved and the entry is three lines long. A shop that builds on a harness needs a discipline that sorts those three piles. This is ours.

    The loop, in order

    • Watch. Two daily diffs: the model catalog (running since October 16, 2026) and the changelog itself (from today). Change-only reporting — silence means nothing moved, and a failed watch reports itself once rather than going quietly blind.
    • Read against our record. Every real change gets one question: does it touch a surface we run — Desktop sittings, the cloud API, mobile steering, or a model our routing names? If not, it is logged and skipped, however shiny.
    • Check before adopting. A change that touches the harness earns a check against a known quantity — a brief we have already graded, a sitting pattern we already run. The check’s result, not the changelog’s adjectives, decides what changes in our work-order kit.
    • Write it down, dated. The desk pages update with the date of the change and the date of our check. A claim we repeated and later found wrong gets corrected in place, with the correction visible.

    This week’s page, sorted by the discipline

    Cursor’s changelog top, as of October 19, 2026 (entry dates October 16 and 13 at the head of the page): cloud-agent entries lead — canvases from cloud agents, an environments API. Those matter here, because cloud agents are a production lane for us; they go on the check list. A remote-control entry — see and reply to local agents from the iOS app, in Cursor’s description — matters specifically to a shop whose sittings run on one laptop: it changes how a sitting can be supervised, so it gets read carefully before it gets used. A marketplace launch and a pair of shipping bots are logged-and-skipped for now: real, announced, and not touching our record yet. Those descriptions are Cursor’s; the sorting is ours.

    Say where each fact came from

    One habit does more for a desk’s credibility than any other: provenance on the page. The changelog currently shows entry dates but no Desktop version string — so this desk’s version knowledge does not come from the changelog. It comes from reading our own install (3.25.9, October 19, 2026). When the basis of a number is our fleet, we say fleet. When it is the vendor’s page, we say vendor. A reader who can tell which is which can trust both.

    That is the whole method: vendor claims in, checked knowledge out, dates on everything. The watches are cheap. The discipline is the product.

    Method & settings — this piece

    Watches: Model-catalog diff (daily since October 16, 2026) + changelog diff (daily from October 19, 2026); change-only; failures reported once

    Sorting rule: Touches a surface we run = check list. Otherwise logged and skipped. Vendor descriptions labeled as the vendor’s

    Desk rule: Every fact carries its provenance and date — our record, or Cursor’s page, never blended

    Filed under the Cursor desk — the desk these watches feed.

  • Composer 2.5 Is Our Code Seat. Here’s Its Record.

    Composer 2.5 Is Our Code Seat. Here’s Its Record.

    Why Composer holds the code seat

    Every work order this shop writes names its executor up front — the model, the seat, and what happens if that seat is unavailable (stop; never substitute quietly). For code, the name on the order is Composer 2.5, Cursor’s own model. It did not get the seat by brand. It got it on a board we ran ourselves.

    The board: October 16, 2026

    Our fleet comparison put the models on one identical brief and graded the work. In the initial trio — Grok 4.7, Composer 2.5, and Auto — all three scored perfectly, and Composer was the fastest of the three: 31 seconds, 13 cents. Across the full board it was the fastest model tested, full stop, while identical perfect scores elsewhere on the board cost up to 86 cents. Speed with a perfect score is exactly the profile a code seat wants: code work is iterative, and iteration speed compounds.

    The same board explains the seat Composer does not hold. Our first pass — the wide, cheap, read-everything pass — belongs to GLM 5.3 Flash, which produced its perfect score for 0.83 cents. A hundred-fold cost spread for the same correct answers is the whole argument for routing by evidence instead of by logo: Composer where its speed pays, GLM where its price pays, and the receipts to say which is which.

    What we have put through it

    Through Desktop sittings, Composer executes the shop’s build work: fleet website builds and repairs across our WordPress properties, the Work Order Desk application (a BMAD+ build whose doctor checks pass 35 of 35), and the tooling runs in between. The work-order standard it runs under is not a prompt and a prayer — it is an unaided first pass in its own words before any templating, a permissions pre-flight, ship/hold boundaries stated in the order, and evidence graded on its timestamped trail plus screenshots at the verification points.

    The dents, on the record

    • The seat is bounded by the order. Our standing rule exists because it was earned: a work order that comes back with questions is a work order that was not finished. Composer executes what the order covers — gaps in the order surface as gaps in the run.
    • The real gates stay human. Sends, deletions, money, and credentials are never pre-approved for any executor. Composer stops there by design, and that is a feature of the harness, not a limit of the model.
    • The pipeline around it can bruise the output. In one October sitting, deliverables written through the Windows pipeline came back with mojibake on the em-dashes; the fix was ours to make — UTF-8 stated explicitly in every work order since. Blaming the model for a harness defect is how shops learn nothing.

    Cursor describes Composer as its in-house model family built for agentic coding — that is their claim, labeled as theirs. What this desk can vouch for is narrower and, we think, worth more: on our briefs, on our board, at our volume, it is the fastest pair of hands we have measured, and the record above is the whole of why it holds the seat.

    Method & settings — this piece

    Comparison: One identical brief across the fleet’s models, October 16, 2026; graded on output and execution trajectory; Composer 2.5: perfect score, 31 s, 13¢

    Seats: Composer 2.5 = code executor (Desktop sittings); GLM 5.3 Flash at max = first pass; Grok 4.7 = deep-verification seat — all three on Will’s Cursor plan

    Work-order standard: WO-198: execution model first, unaided first pass, permissions pre-flight, evidence = timestamped trail + screenshots

    Filed under the Cursor desk.

  • The Cursor Model Catalog, Watched Daily

    The Cursor Model Catalog, Watched Daily

    Your stack includes a list you didn’t write

    Every shop building on AI agents has a dependency it rarely names: the model catalog. Which models exist, what they are called, which variant is the default, what the reasoning dial offers — all of it is set by the platform, and all of it can change overnight. If your routing doctrine names a model, the catalog is part of your infrastructure. We diff ours every morning.

    The baseline: 46 models, October 16, 2026

    The watch started with a full pull of Cursor’s model list through the API on October 16, 2026: 46 models. Each model is normalized the same way every day — its id, its display name, the values its reasoning parameter offers, and which variant is marked default. The GLM family that day, the family our first pass rides on:

    • GLM 5.2 — reasoning: high, max — default: high
    • GLM 5.3 — reasoning: low, high, max — default: max
    • GLM 5.3 Flash — reasoning: low, high, max — default: max

    That last line is load-bearing. Our first-pass doctrine is GLM 5.3 Flash at reasoning set explicitly to max on every launch. The explicit set is not ceremony: the day a platform quietly changes a default is the day your output changes and nobody knows why. A daily diff turns that silent event into a dated line in a changes log.

    What a catalog change actually does to a shop

    • A model arrives: it earns nothing until it runs the identical brief against the incumbents. New seats are tested, never adopted on a changelog’s say-so.
    • A model leaves: every doctrine that names it has a hole. The diff tells you the morning it happens, not the week a job starts failing.
    • A default changes: the most dangerous entry in the catalog, because nothing in your own setup moved. This is the change the watch exists to catch.
    • A dial gains a setting: a reasoning value appearing or vanishing changes what your pinned configuration even means.

    The trap in the easy route

    One tooling lesson from building this watch, offered free: the convenient command-line listing of the catalog truncates at roughly 6 KB — a partial catalog that looks complete. The full list only comes through the raw API call. A shop reading the truncated output believes it is watching 46 models while seeing a fraction of them. Whatever you monitor, monitor the untruncated source.

    The watch reports changes only. Silence means the catalog is what it was yesterday — and if the API itself fails, the failure is reported once, out loud. A blind watch is worse than a noisy one.

    Method & settings — this piece

    Baseline: Full model-list pull via api.cursor.com/v1, October 16, 2026: 46 models total, 3 GLM

    Normalization: id, displayName, reasoning parameter values, default variant — compared field by field against the stored snapshot

    Cadence: Daily, change-only reporting; failures reported once

    Full method: The same watch pattern guards our GLM doctrine — see the GLM desk

    Filed under the Cursor desk.

  • Desktop, Cloud, or API: One Cursor Harness, Three Seats

    Desktop, Cloud, or API: One Cursor Harness, Three Seats

    The seat is a routing decision

    Cursor is not one tool in this shop. It is three seats that share a harness — a Desktop app on a laptop, cloud agents behind an API, and a phone — and picking the wrong one wastes the day in a characteristic way. Desktop waits on a human. The cloud knows nothing about your logged-in life. The phone is a steering wheel, not a workbench. The routing rule we run: the seat is decided by where the work’s context lives.

    Desktop wins when the unlock is a logged-in browser

    A Desktop sitting is a supervised run: a written work order, an executor (Composer 2.5 in our shop) that makes an unaided first pass in its own words before any templating, and a human in the room for the real gates. Its superpower is everything the laptop already is — signed-in dashboards, the WordPress admin, the GA4 Advisor, the files on disk. When a fleet site needs hands inside a web UI that only exists behind Will’s login, no API lane substitutes.

    We learned the boundary the hard way. On October 18, an executor stopped cold at a site’s login redirect and left the step undone — which cost that sitting its unlock path. The standing rule now: in a sitting on Will’s own laptop, the executor clicks through sign-ins using the browser’s saved session. Saved-login only. No saved login means the step logs a HOLD — nobody hunts a password, ever.

    Desktop’s honest cost: it waits on a human, and a queued sitting is not a running job. Our TM pricing diagnosis (WO-353) has sat untouched since October 18 at 6:16 PM — steps written, folder staged — because a sitting starts when Will sits down. Anyone who tells you their Desktop pipeline is autonomous has not watched a folder sit still for a day.

    The cloud wins when the work fans out

    Cloud agents, launched from this desk over api.cursor.com, are the opposite shape: no login, no laptop, no waiting room — and they multiply. On October 16 we ran a census through that API: 44 models, one identical brief, five comparison rounds, graded on their execution trajectories. That is a shape of work a single Desktop seat cannot do before lunch, and it set our model routing for everything since.

    The scale shows in the bookkeeping: our completion watcher has seen 1,431 cloud agents come and go. The API runs two launch shapes for us — repo tasks that come back as pull requests, and no-repo research and evaluation runs with the model pinned in the launch body. The API is beta, and we treat it that way: when an endpoint changes shape, the error gets surfaced plainly, never papered over with invented fields.

    Mobile wins when the human is the bottleneck

    The phone’s job is judgment at human speed. Will reviews runs, reads results, and steers from his phone while the machines work elsewhere — and because a review that evaporates is a review wasted, a distiller folds his mobile and Desktop runs into the shop’s memory and Feed every 20 minutes. Mobile is not a production surface here. It is where the approvals live, and approvals are the scarcest resource in the building.

    What each seat’s failure taught the kit

    • Desktop: permission prompts were taxing the one human in the loop — fixed by a Step 0 permissions pre-flight in every work order (October 18): the executor declares the commands it expects up front, the human approves once, and prompts are reserved for sends, deletions, money, and credentials — which are never pre-approved.
    • Cloud: a finished summary is not evidence — fixed by trajectory grading and a completion watcher: results are verified at the receiving end, or they are not results.
    • Mobile: steering from the phone only counts if it lands in the record — fixed by the 20-minute distiller.

    One harness, three seats, and a routing rule a shop can steal: if the context is a login, sit down at Desktop. If the work fans out, launch it in the cloud. If the blocker is a decision, put it on the phone.

    Method & settings — this piece

    Evidence: This shop’s work-order record, October 2026: WO-198 standard, the WO-343 and WO-348 sittings, the WO-353 stall, the October 16 cloud census

    Desktop: Cursor 3.25.9 on Will’s laptop (read from the install, October 19, 2026); executor seat Composer 2.5

    Cloud: api.cursor.com/v1 (beta); completion watcher count 1,431 agents seen as of October 18, 2026

    Mobile: Cursor mobile app in a review/steer role; runs distilled into memory + Feed every 20 minutes

    Filed under the Cursor desk — where the catalog and the changelog are watched daily.

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

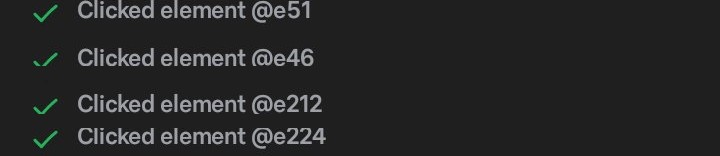
    I had an AI agent doing something routine in a browser today — opening a server terminal, placing a small text file. Nothing exotic. While it worked, I opened the activity feed to watch.

    This is what I saw:

    Cropped screenshot of an AI browser agent's activity feed showing four entries labeled only with internal element IDs: Clicked element @e51, @e46, @e212, @e224.
    Four entries, cropped from the feed. Every one is an internal element ID.

    “Clicked element @e51.” “Executed click on element @e21.” “Clicked element @e224.”

    I had no idea what any of it meant.

    Here’s what I kept thinking while I stared at it: I’m watching this thing click around inside my infrastructure, and I can’t tell the difference between “everything is fine” and “it just did something terrible.” For all I knew from that feed, it could have pressed the button that drains all my money. The log was written for the machine, not for me.

    I didn’t want to interrupt. The agent was in the middle of working, and I didn’t want to be the guy hovering over the desk. So I went to look at what it was doing — and looking didn’t help, because there was nothing there a human could read.

    So I asked a question instead of making an assumption: whose labels are these? Is that how the website labels its buttons, or is that something the agent made up?

    The answer: the agent’s. The browser automation numbers every clickable element on the page so it can navigate — @e18, @e21, @e224 — and those internal reference numbers leaked straight into the activity feed a human is supposed to monitor.

    That’s when it stopped being a cosmetic complaint and became the actual point.

    Legibility is the safety feature

    An agent you can’t watch is an agent you can’t trust. An agent you can’t trust doesn’t get real work. Every roadmap that says “AI will handle X” dies at exactly this spot — not on capability, but on watchability. The machine can do the job. The human can’t verify the job. So the human doesn’t delegate the job.

    There’s an old principle — seek first to understand, then to be understood. It applied perfectly here. I could have assumed the worst and killed the task. I could have interrupted the work to ask what it was doing. Instead I asked what I was looking at, understood it, and then did the useful thing: filed the feedback so the next person watching gets words instead of codes. “Clicked the SSH button.” “Opened Compute Engine.” That’s all it would take.

    If you’re building agents, here’s the lesson: instrument for the watcher, not just the operator. The activity feed is a user interface. Nobody would ship a dashboard full of database IDs and call it done — but that’s exactly what most agent monitoring looks like right now. Label it like someone’s watching. Because someone is.

    The file got placed. The work finished fine. But the most useful thing that happened today might be the note we filed.

  • The Tea-Bag Report

    (What your visitors wanted that you didn't have.)

    A friend stays over. Morning comes, they open your cabinets and look around for tea bags. No tea bags. So they drink your coffee instead and say nothing.

    If you ever saw them looking, you'd buy tea. Not because coffee failed. Because someone told you what they wanted with their behavior, and listening is cheap.

    Your website gets houseguests every day. And most of them are looking for tea bags.

    The query is the want

    Every search query is a small confession. Not "what words did they type" but "what were they trying to accomplish." A homeowner typing a city plus "water damage restoration" is standing in a wet hallway. A facilities director reading about IFRC sustainability guidelines at 10 AM on a Tuesday is doing homework for a budget meeting. Same internet, completely different mindsets.

    Bing's AI performance reports now label this outright. Every query that triggers an AI answer citing your pages comes with an intent tag: informational, commercial, local, research. The mindset column is just sitting there in the export. Most people never read it as what it is, which is a list of what your visitors wanted.

    Here's the part that changed my thinking: the industry standard for measuring AI-search visibility is synthetic prompts. Tools invent questions, run them across engines, and record what comes back. Probabilistic reporting, built on guesses, because as a 2026 Luminary analysis put it, "Since AI platforms don't share real prompt data (as at April 2026), organizations must build measurement baselines using synthetic prompts." Except Bing does share the real thing with site owners: the actual grounding query, the engine's own intent label, and your citation share. First-party want, straight from the source. Stop guessing with synthetic prompts when the engine will just tell you.

    Three places the tea bags show up

    1. Citation gaps. When an AI answer cites your page for 15 percent of its response, the want is proven and your voice is small. Someone asked, the machine answered mostly with other people's words. That's a stock-the-shelf list hiding in plain sight: every query where you're present but weak is a page you haven't written yet, or a page that doesn't serve the intent behind the query.

    There's now a named framework for this. Search Engine Land covered a method from Robin Tully, co-founder at Forecast.ing, that scores the distance between what a page claims to deliver and the queries it actually surfaces for, sorting everything into four quadrants. The one that matters is labelled "Create": demand you're visible for but not capturing. As Tully put it: "Your audience is already telling you what they need. That signal is always shifting." And: "observations create interesting conversations, but numbers create urgency and action."

    2. No-result site searches. I'll be honest about my own wrong mechanism here: I assumed failed on-site searches produced 404s. They don't. WordPress renders an empty results page instead. The signal lives in no-result search logs, and there are plugins that exist solely to capture it. One of them positions itself in pure tea-bag language: "Turn Lost Searches into Content Opportunities. Instead of guessing what to create next, build content based on real demand." Every empty search is a houseguest who opened the cabinet, found nothing, and left quietly. Log them.

    3. The 404s. True 404s are a separate signal and just as valuable. Raven Tools documented an agency client who, after a relaunch, started getting emails from visitors hitting dead pages telling them exactly which old resources to recreate. Those conversations turned into sales: "After the client closed a second sale from a '404 lead,' the client jokingly asked if we could just serve up a 404 page all the time." Put a contact path on your 404, watch what comes in, and treat it as demand data. And keep true 404s as 404s. Google's John Mueller has said it plainly: don't blindly redirect dead pages to your homepage or a category page; 404s are a normal part of a healthy website. Blanket redirects confuse the crawlers and bury the signal.

    When matters as much as what

    Across most of the properties I track, AI citations drop hard on Saturdays. The main site fell from 8,863 citations on Friday to 4,197 on Saturday. The B2B-leaning properties all show the same shape, down 26 to 72 percent. That's not lost rankings. That's a weekday-professional audience going home. The exception proves the rule: the race-event property nearly quadrupled on Saturday, because race day is its weekday.

    A DesignRush study of 950,000 U.S. B2B search queries found the mirror image worth noting: weekend visitors showed higher intent, more form fills, deeper reads into content. Different crowds, different mindsets, different hours.

    This is where it stops being analytics and starts being strategy. A research-intent query at 10 AM on a workday wants depth. The same person scrolling at 9 PM wants the short version that respects their evening. Meet the morning persona with the white paper and the evening persona with the two-minute read, and you're not retargeting. You're recognizing someone.

    The philosophy underneath

    None of this is about grabbing people. The grabby version is funnels and popups and "we noticed you almost bought." The tea-bag version is quieter: I see you, I see where you're at, I see what's important to you, and I'll meet you as best I can where you are. Sometimes you won't have the tea. Knowing they wanted it is what lets you stock it next time.

    Run the report monthly. Queries with intent labels, citation shares, no-result searches, 404 hits, daypart patterns. Rank every gap by frequency. What comes out the other end isn't a dashboard. It's a publishing roadmap written by your visitors, a restocking list for shelves you didn't know were empty.

    They already told you what they want. You just have to look where they looked.

    The product

    This is now a standing offer: the Tea-Bag Report. Send us your search data and we'll tell you what your visitors were looking for that you didn't have, ranked by frequency. Then go stock the shelves.

    Sources

  • Flash Flood Warning: Harlan, KY Area Until 2:45 AM EDT

    Flash flood warning in effect for Harlan County until 2:45 AM EDT

    The National Weather Service in Jackson, Kentucky has issued a Flash Flood Warning for central Harlan County, effective immediately and running until 2:45 AM EDT on Tuesday, September 22, 2026. At 12:08 AM EDT, Doppler radar indicated thunderstorms producing heavy rain across the warned area — between 1.5 and 3.5 inches of rain have already fallen, and additional rainfall amounts of 0.5 to 2 inches are possible. Flash flooding is ongoing or expected to begin shortly.

    For restoration teams across southeastern Kentucky, this is the exact profile that turns into interior flooding jobs by morning: saturated ground, overwhelmed drainage, and water pushing into homes and businesses in the middle of the night, with the National Weather Service rating this a life-threatening flash flood event.

    This is a live snapshot as of 3:15 AM EDT on September 22, 2026. Conditions change fast — always verify with the National Weather Service for your specific county or ZIP code before acting.

    Harlan County, KY — Flash Flood Warning

    • Issuing office: National Weather Service in Jackson, Kentucky
    • Issued: 12:08 AM EDT, Tuesday, September 22, 2026
    • Expires: 2:45 AM EDT, Tuesday, September 22, 2026
    • Alert type: Flash Flood Warning (VTEC: /O.CON.KJKL.FF.W.0070)
    • Detection: Radar indicated

    What the radar shows: Doppler radar indicated thunderstorms producing heavy rain across the warned area. Between 1.5 and 3.5 inches of rain have fallen, and additional rainfall amounts of 0.5 to 2 inches are possible in the warned area. Flash flooding is ongoing or expected to begin shortly.

    Hazard: Life threatening flash flooding. Thunderstorms producing flash flooding.

    Source: Radar indicated.

    Impact: Life threatening flash flooding of creeks and streams, urban areas, highways, streets and underpasses.

    Locations that will experience flash flooding include: Harlan, Loyall, Evarts, Kildav, Bailey Creek, Verda, Darkmont, Putney, Ages, Short Town, Kenvir, Coxton, Colts, Black Mountain, Nolansburg, Shields, Rosspoint, Golden Ash, Chevrolet and Lenarve.

    Track the latest directly from the NWS Jackson, Kentucky office page and the alert source at the National Weather Service.

    Stay safe tonight

    Turn around, don’t drown when encountering flooded roads. Most flood deaths occur in vehicles — never drive through a flooded roadway, and never trust that a road is passable just because it looks shallow.

    Be especially cautious at night, when it is harder to recognize the dangers of flooding. If you are in the warned area, stay off the roads unless you are fleeing an area subject to flooding or under an evacuation order.

    If water enters your home:

    • Stay out of standing water where electricity may be present.
    • Avoid the basement until the water recedes and the power is confirmed off.
    • Photograph everything before cleanup begins — documentation matters for insurance, and adjusters want to see the water line before mitigation equipment moves in.
    • Call a local restoration contractor as soon as it is safe. Water left sitting starts a second wave of damage within a day, and after a night like this, the phone lines at good contractors fill fast.

    If you observe flooding, report it to local emergency services or law enforcement and request they pass the information to the National Weather Service — you can do so safely once you are on high ground.

    What this means for restoration teams

    This is the signature section for a reason: a life-threatening flash flood warning at 3 AM in Harlan County becomes a week of water-intrusion work. Here’s how to read it.

    Damage categories to expect: Interior water intrusion through doorways, crawlspace vents, and below-grade entries is the headline job. Saturated drywall and insulation in finished basements and ground-floor rooms follows. With 1.5 to 3.5 inches already down and another round possible, expect sewage backup calls in low-lying areas where combined systems and septic fields are overwhelmed — and with mountain creeks and streams in the impact zone, washout debris can redirect water into buildings in ways the homeowner never saw before.

    Mold clock: Water left sitting starts secondary damage within 24 hours and mold colonization within 24–48 hours. Overnight flood events are the worst for this — the homeowner sleeps through the intrusion and finds it at daylight, already six to ten hours into the clock.

    The play for tonight:

    • Stage equipment now — extractors, air movers, dehumidifiers — before the first call lands. Water-intrusion calls typically start within hours of water receding and keep coming for days as people discover damage.
    • Keep an on-call rotation through the morning. The discovery wave hits at first light.
    • On the first call, capture address, water source, and affected areas — triage order is: life safety, source stoppage, extraction, drying. Know before you roll whether you’re walking into a finished basement or a crawlspace.
    • Field discipline: Photo-document before mitigation (the water line is your proof), moisture-map every affected room, and keep the homeowner’s payment responsibility clear in writing before work starts — deductible and coverage conversations go better before the equipment is humming.

    FEMA & federal assistance

    If flooding damages your home or property, federal assistance may be available through FEMA:

    • FEMA Helpline: 1-800-621-3362 (7 a.m.–10 p.m. local time, 7 days a week)
    • Apply online: DisasterAssistance.gov
    • Find recovery centers: fema.gov/drc or the FEMA mobile app

    Basic eligibility: U.S. citizenship or qualified status, identity verification, proof of occupancy or ownership, and unmet needs not covered by insurance. Apply as soon as it is safe — you do not need to wait for a disaster declaration to register your damage.

    Looking ahead

    The warning is scheduled to expire at 2:45 AM EDT. What to watch after that: creeks and streams in Harlan County can crest after the rain stops, so flooding in low-lying areas may continue even once the warning lifts. Additional rounds of thunderstorms are possible overnight — the alert itself flags another 0.5 to 2 inches as possible, which would be a second wave on already-saturated ground.

    Watch the NWS Jackson page for extensions, upgrades, or new warnings through the early morning hours. NWS updates can arrive without notice when radar trends shift.

    Demand window note: Water-intrusion calls typically start within hours of water receding and keep coming for days as people discover damage. Contractors who staged equipment tonight work the week; contractors who wait for the phones to ring chase it.

    Sources & how to verify

    • National Weather Service alert: Flash Flood Warning, Harlan County KY — issued by NWS Jackson, Kentucky, 12:08 AM EDT September 22, 2026, expiring 2:45 AM EDT.
    • The NWS emergency message for this warning: “NWS: FLASH FLOOD WARNING this area til 2:45 AM EDT. Avoid flooded areas.”

    To verify for your own county or ZIP code: visit weather.gov, enter your ZIP, and check the alerts box — or go straight to your local NWS office page.

    This post is for informational purposes and is not an official weather warning. Always follow instructions from local authorities and the National Weather Service.