Author: Storm Desk

  • Can a Competitor Push You Out of AI Recommendations With Fake Reddit Posts?

    Can a Competitor Push You Out of AI Recommendations With Fake Reddit Posts?

    Direct answer: Yes — researchers have demonstrated that a single planted Reddit post can steer a large share of AI recommendations. But steering an answer is not the same as holding the spot, and the defense is the same unglamorous work that wins recommendations honestly: a real, verifiable presence across the sources AI assistants actually cite.

    Why Reddit punches above its weight in AI answers

    AI assistants lean on Reddit threads the way a homeowner leans on a neighbor’s recommendation — first-person accounts from people who seem to have actually hired someone. In our own citation testing, Reddit was cited 136 times across 511 answers. That’s not a side channel. It’s one of the main places the machines go looking when someone asks who to call.

    One well-placed thread can echo across a lot of answers. That’s the opportunity — and the vulnerability.

    What the researchers found

    Cornell Tech researchers reported in May 2026 that a single planted post steered 38–51% of recommendations in some of their tests. Read that again: not a campaign, not a bot farm. One post, written to look like a genuine customer experience, moved the needle on nearly half the recommendations in the test set.

    So if you’re asking whether a competitor *could* push you out with fake posts — the honest answer is that the mechanism is real, and it’s been demonstrated, not just theorized.

    What “gaming” actually looks like

    It’s rarely sophisticated. The common patterns:

    • A “looking for a roofer in [city]” post from a fresh account, followed by replies that all name the same company.
    • Manufactured threads where the “customer” praises one shop and trashes the alternative.
    • Old, legitimate-looking threads revived with new comments pointing at one business.

    To a reader skimming fast, it looks like consensus. To an AI assistant ingesting the thread as evidence, it reads as first-person proof.

    The part nobody selling this tells you

    It works until it doesn’t. Planted posts get removed. Sock-puppet accounts get flagged. And the engines keep getting better at weighing account history, posting patterns, and whether a claim is corroborated anywhere else. A recommendation built on one fake thread has no foundation under it — the first corroboration check, the first real customer review cycle, and it collapses.

    Here’s the deeper truth: faked recommendations don’t survive contact with a real customer. The homeowner who calls based on a planted thread still meets your actual business — your reviews, your trucks, your work. You can’t fake the job itself, and the machines are increasingly checking the things you can’t fake: how long you’ve existed, whether real people vouch for you in more than one place, whether your business details match everywhere they appear.

    What actually protects you

    The boring fundamentals. They’re boring because they work:

    • Real reviews with real wording. Detailed reviews from actual customers are the hardest signal to fake at scale — and the one AI answers quote most.
    • A website the machines can actually read. Clear services, real location, real phone number, structured so a crawler doesn’t have to guess.
    • Consistent business details everywhere. Same name, same address, same phone across your site, your profiles, and the directories. Inconsistency reads as unreliability.
    • Presence where the engines already look. We’ve covered Reddit’s citation role before — being genuinely present in the conversations your customers have is the legitimate version of what the fakers are imitating.

    What to watch for

    You can’t control what competitors do, but you can notice it. Watch for sudden shifts — a competitor appearing in AI answers they never appeared in before, threads about your trade in your market that read like ad copy, or a cluster of new accounts all pointing the same direction. If you see it, document it. Platforms act on reported manipulation, and the paper trail matters.

    The bottom line

    The machines quote what’s quotable, and customers verify what’s real. A competitor can rent a recommendation with a fake post. They can’t rent your reputation — and in the end, the recommendation that survives is the one attached to a business that actually exists, actually answers the phone, and actually does the work.
  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

    The Four Lanes

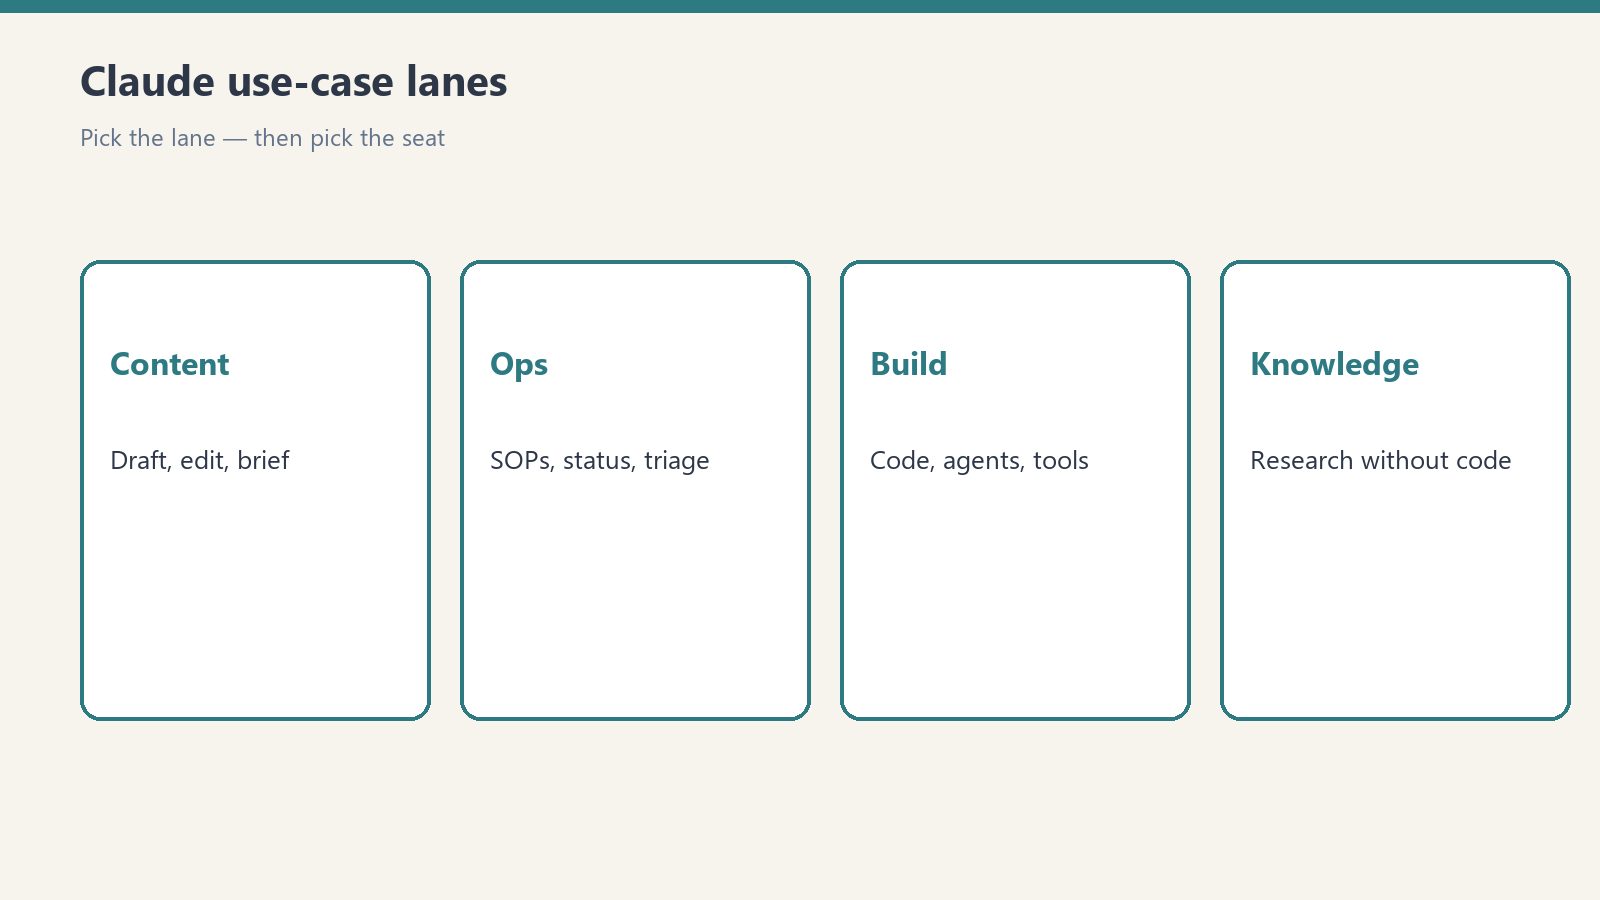
    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    A low-cost AI subscription can produce text. It cannot settle a minutes policy, absorb a week of review labor, or deliver a public record that is ready to publish.

    On September 29, the Farmersville City Council voted 4–1 to pay $30 a month — $360 a year — for Grok to draft verbatim meeting minutes from council recordings. City Clerk Rochelle Giovanni would review each draft. Interim City Manager Kevin Northcraft called the AI-generated minutes “more objective” than minutes written by a person. Elon Musk quote-posted the news with one word: “Grok.” [1]

    The reaction was predictable. Some people treated the vote as proof that artificial intelligence had made a routine government task nearly free. Others treated it as a punch line. Both reactions missed the operational story.

    The $30 vote was never really about drafting

    Farmersville had spent months arguing about what its minutes should contain. The city used summary minutes, but councilmembers pressed to include particular actions and verbatim statements. Under that pressure, work that had taken the clerk about two hours stretched to nearly a week.

    That is the number that matters. The city did not merely have a transcription problem. It had a governance problem: disagreement over the purpose and level of detail of the official record. A language model can turn audio into text. It cannot decide which minutes policy the council should adopt, apply that policy with institutional judgment, or end a political dispute over whose words deserve inclusion.

    The subscription buys a draft, not minutes

    In the city’s comparison, Grok produced eight pages, Otter produced nine, a service identified as Government Clerk produced 12, and a human Rev.com transcript ran 111 pages. Those page counts compare outputs, but they do not answer the central question: What kind of record is the city trying to produce?

    The California City Clerks Association’s minutes guidance is clear. The primary purpose of minutes is to memorialize decisions. It identifies action minutes and brief summary minutes as appropriate styles and says verbatim minutes should not be used. Action minutes record final decisions; brief summary minutes preserve the main points that led to a decision without turning the record into a transcript. [2]

    A transcript records what was said. Minutes record what the body did.

    That distinction matters because more text is not automatically more transparency. An audio or video recording can preserve the full discussion. Minutes serve a different function: they create a concise, reliable record of attendance, items considered, actions taken, votes, and follow-up. If a city wants verbatim minutes anyway, it should make that policy choice openly — and price the work required to review them.

    The hidden cost is the clerk’s review time

    Farmersville’s clerk still reviews every Grok draft. She must catch misheard names, incorrect motions, missing vote details, speaker confusion, and language that does not match the city’s adopted style. She also has to format the document, reconcile it with the agenda and staff materials, route it for approval, and prepare it for publication and retention.

    None of that appears in the $30 subscription price. The software cost is visible because it arrives as a line item. The clerk’s time disappears inside payroll, backlog, and delayed work elsewhere. A city can save money on the first pass while still spending a week producing the finished record.

    This is why “AI wrote the minutes” is the wrong test. The useful question is whether the city received accurate, policy-compliant minutes that a clerk can stand behind without rebuilding the document.

    The useful product is a finished public record

    For a small city, the product should not be a block of generated text. It should be a complete workflow: the meeting recording is transcribed; a draft is shaped to the city’s adopted minutes standard; motions, votes, names, and action items are checked; the document is formatted to the city’s template; a human verifies the result; and a publish-ready file is delivered.

    The artificial intelligence does not need to be perfect. The system needs to be designed so a qualified human catches what it misses. That is not a retreat from automation. It is the control that makes automation usable in public records work.

    A finished-minutes service also makes the cost legible. Instead of buying a subscription and hoping staff time falls, the city buys an outcome: reviewed minutes in the required format, ready for the clerk’s final approval and the next agenda packet.

    Farmersville opened a door for hundreds of small cities

    California has 482 incorporated cities. Many operate with small administrative teams, tight meeting cycles, and clerks whose responsibilities extend far beyond minutes. Farmersville’s dispute is unusually visible, but the underlying problem is common: the recording is easy to make; the official record still takes judgment and time. [3]

    The 4–1 vote proved that a budget line for AI-assisted minutes can survive a public meeting. The $30 subscription opened the door. The larger opportunity sits behind it: the nearly weeklong burden that nobody priced.

    The next step is to buy the outcome

    Council minutes as a finished, human-verified service exist now. For a city spending days turning recordings into disputed drafts, the useful conversation is not which model can generate the most pages. It is what a publish-ready minutes workflow would remove from the clerk’s desk — and what standard the council wants that workflow to follow.

    Sources

  • Review Count Is Dead: The Reputation Graph Killed It

    Review Count Is Dead: The Reputation Graph Killed It

    A water-damage company with 47 reviews just got recommended by ChatGPT over a competitor with 462.

    Read that again. Four hundred and sixty-two reviews. Ten times the social proof. And the AI picked the little guy.

    If you spent the last decade collecting reviews like they were votes, this should rattle you. It should also clarify everything, because the game didn’t just change — it ended, and a new one started while nobody was watching.

    From ranking to matching

    The old game was a scoreboard. Most reviews wins. Biggest ad budget wins. Best SEO agency wins.

    The new game is a matchmaker.

    In June 2026, OpenAI rolled out a memory system (they call it Dreaming) that quietly builds a living profile of you — your chats, your Gmail, your files — and uses it to shape every answer. It’s on by default. Two people asking ChatGPT the same question now routinely get different answers, because the AI knows different things about each of them.

    Google’s doing the same thing from the other direction. AI Overviews don’t give you a ranked list of ten businesses anymore. They name two or three. Fourth place doesn’t get a consolation mention — it gets nothing. And here’s the number that should end the argument: only about 26% of the businesses sitting in Google’s top-3 map pack even appear in Gemini’s responses. You can win the map pack and still be invisible to the AI.

    So the question was never “who has the most reviews.” The question is “who is the best fit for this person,” and the AI is answering it with information you can’t see.

    The dinner test

    Here’s how I explain it to myself.

    Tonight I walked to a little family-run Thai place instead of ordering from a chain. No ad convinced me. No review count swayed me. The tools just… knew. They knew I’d rather have the local place with the great green curry than the heavily advertised alternative.

    A cozy family-run Thai restaurant glowing warmly at dusk while a chain restaurant sign looms in the background
    The tools know you’d pick the local place. No ad budget changes that.

    That’s what happened with the 47-review company. The AI didn’t count stars. It matched a person — their history, their preferences, the pattern of what “good” looks like to them — against the businesses it knew. And the little guy fit better.

    Panda Express can outspend everybody. It doesn’t matter. When the tool knows you better than the ads do, the ads stop working on you.

    Why the count stopped mattering

    It’s not that reviews don’t matter. They do — review signals have actually grown to about 20% of local ranking weight. But count was always a proxy for trust, and the AI doesn’t need the proxy anymore. It reads the reviews. It summarizes the sentiment. It checks whether your website says the same thing your Google profile says. It looks at whether your story is consistent across fifteen, twenty, thirty sources — or whether it falls apart the moment it leaves your homepage.

    A thousand bought or begged reviews with thin sentiment lose to fifty detailed ones that all say the same specific true things. The AI can tell the difference. It literally summarizes them.

    What actually wins now

    A local contractor business at the center of a glowing reputation graph, with a pile of disconnected review stars off to the side
    The reputation graph: every signal connected, telling one consistent story.

    The playbook isn’t complicated, but it’s unforgiving:

    • Complete your profile like it’s the product. The AI reads your Google Business Profile as a primary source. Empty fields are silence, and silence doesn’t get cited.
    • Recency and sentiment over volume. A steady stream of real, specific reviews beats a pile of old five-stars.
    • Say the same true thing everywhere. Your website, your profile, your directories, your socials — one consistent story, confirmed in many places. Contradictions are how you disappear.
    • Structure your data. Schema markup is how the machines read you. It’s not optional anymore; it’s the difference between being understood and being skipped.
    • Be genuinely good. This is the one nobody wants to hear. The tools are getting better at knowing what “good” looks like for each person, which means there are fewer places to hide. You can’t buy your way into a match. You have to be the answer.

    The honest caveat

    I want to be straight about what we know and what we don’t. Nobody outside these companies can see exactly how the personalization works — one researcher called it “a synthesized profile that neither the user nor the brand can fully see.” That’s the truth of it. We’re reading the outputs and working backward.

    And the social-graph part — your friend’s Facebook comment tipping a recommendation — is directionally right but the mechanics differ by platform. Google has the cross-product graph: YouTube, Maps, Gmail, Android. Meta’s AI has the actual social graph. ChatGPT works mostly from your own data. The destination is the same everywhere: the recommendation gets personal, and the personal is opaque.

    Less places to hide

    That’s the line I keep coming back to. Less places to hide.

    For years you could paper over a mediocre operation with review velocity, ad spend, and SEO tricks. The machines are taking those tools away — not out of virtue, but because matching works better than ranking, and the platforms all figured that out at once.

    What’s left is the oldest marketing strategy there is: be good, be consistent, and make sure the machines can see it.

    The 47-review company didn’t beat the system. It was the system working as designed. The question is whether you’re building a business the new system can see — or still optimizing for the old scoreboard.

  • All My Reviews Just Say ‘Great Service’ — Do the Words in My Reviews Matter to AI?

    Short answer: Yes — the words matter more than the stars. When someone asks for “a reliable plumber who handles emergency leaks,” the AI recommends the business whose reviews keep saying “quick response” and “emergency repair” — not the one with fifty generic five-stars. Review text is the evidence the bot quotes. A wall of “great service” gives it nothing to quote.

    How the bot actually uses your reviews

    Think about what the AI is doing when it answers “who should I call.” It’s matching the words in the question to evidence it can find. If the question asks for emergency leak help, it looks for businesses with evidence of emergency leak help. And the richest source of that evidence isn’t your website copy — it’s your customers describing what you did, in their own words.

    One analysis of business profiles in AI search put it directly: “If a user asks for a ‘reliable plumber who handles emergency leaks,’ the AI will likely recommend a business whose reviews frequently mention ‘quick response’ and ’emergency repair’ over a business that simply has those terms in its meta description.” Businesses with specific, keyword-rich testimonials get cited more often than businesses with generic five-star ratings and no text.

    A review-industry breakdown this month named vague reviews as one of the three mistakes sending customers to competitors: “great service” instead of “same-day AC repair in Phoenix.” And review audits keep finding the same thing — AI answers quote review text verbatim. Your customers’ words become the bot’s answer.

    The star-rating trap

    Most owners chase stars. Stars are visible, countable, and feel like the scoreboard. But a five-star rating with no text tells the AI almost nothing — it’s a number without a story. Forty detailed reviews at 4.8 stars will beat a hundred empty five-stars, because the detailed reviews give the bot something to match against the question and something to quote in the answer.

    This is also why review platforms matter less than review content here. The question isn’t just where your reviews live — it’s whether the words in them describe the work you actually want to be recommended for.

    The review-request script (free, repeatable)

    You can’t write your own reviews. But you can ask for better ones — and most owners never do. After a job, when the customer is happy, ask them to mention two things: what you did and where. That’s it.

    “If you have a minute to leave a review, it really helps when folks mention the job — like the water heater swap — and the town. Just a sentence is perfect.”

    That’s the whole script. You’re not scripting fake reviews or stuffing keywords — you’re asking real customers to include the specifics they’d naturally mention anyway. “Mike replaced our water heater the same day it died, here in Mesa” is a quotable piece of evidence. “Great service!!” is not.

    What to actually do about it

    • Read your last twenty reviews. Count how many mention a specific job or a specific town. If the answer is “almost none,” you have the generic-review problem.
    • Start the two-thing ask this week. What you did, and where. Every finished job, every happy customer. It compounds.
    • Don’t neglect the unhappy ones. A detailed critical review is still evidence the bot reads — respond to it well, and the response becomes part of the record too.
    • Keep it honest. Never write reviews yourself, never pay for them, never hand customers pre-written text. The specifics have to be real — fabricated detail is both against every platform’s rules and, increasingly, detectable.

    What’s actually known — and what’s not

    Known: AI answers quote review text verbatim, and businesses whose reviews describe specific jobs in specific places get cited more often than businesses with generic ratings. The review-request script — ask for the job and the town — is a free, ownable fix no competitor can block.

    Not known: nobody has published a controlled test measuring naming rate against review-text specificity for trades businesses — the evidence is observational and mechanism-level, not a measured curve. What’s missing is someone running the test: same market, similar star counts, specific-text versus generic-text reviews, measured naming rates. That’s a test worth running.

  • Do I Have to Get on Those ‘Best Plumber in [City]’ Lists for ChatGPT to Recommend Me?

    Do I Have to Get on Those ‘Best Plumber in [City]’ Lists for ChatGPT to Recommend Me?

    Short answer: You don’t have to pay the directories — but you do have to be mentioned. When someone asks ChatGPT “who should I call,” the pages it reads are mostly the ones that rank for that question, and those are usually “best of” listicles. Businesses that show up in the two or three listicles ranking on Bing for their trade and city get named. Businesses with no mentions anywhere get named in only 2.8% of relevant answers.

    The numbers behind the listicles

    This isn’t a hunch — it’s measured:

    • “Best of” list articles account for roughly 21% of all AI citations (arXiv 2606.20065).
    • Brands with no citations on their own site and no mentions elsewhere were named in only 2.8% of relevant ChatGPT answers — across a 34,960-prompt study (arXiv 2609.23162).
    • One agency’s check of ChatGPT answers found 95% pointed to a directory as the source.

    A Bend, Oregon owner’s check this month put it in plain terms: the pages ChatGPT reads are “mostly the ones that rank for the query and the ones that list or compare providers.” A Bend plumber sitting in the two or three “best plumbers in Bend” lists that rank on Bing is far more likely to be named than one whose only mention is their own homepage.

    Why this feels unfair (and partly is)

    Contractors resent listicles and directories as pay-to-play machines, and they’re not wrong to be suspicious. The directories sell placement, sell leads, and sell ads against the very searches you want to win. Being told “the bot reads the listicle” can sound like being told to feed the beast.

    But there’s a difference between paying the directories and being listed on them. Most “best of” pages have free listing paths. The bot doesn’t know or care whether you paid — it cares whether your name, trade, and town appear on a page that ranks for the question being asked.

    The misfire side: listicles can get you wrong

    A Plant City plumber’s owner-written FAQ documents the other edge of this: “A ‘serves Plant City’ line on a directory can mean a truck that drives over from another metro when the board has a gap.” His shop is headquartered in Plant City; the listicles hand the town to whoever bought the line. If you’re not watching your directory listings, the listicle isn’t just ignoring you — it may be actively mislocating you.

    What to actually do about it

    • Find your two or three. On Bing, search “best [your trade] in [your city]” the way a homeowner would. The listicles that rank are the ones the bot reads. That’s your list — not fifty directories, just the two or three that actually rank.
    • Get listed on the free path. Claim or create the free listing on each. Fill it out completely: services, service area, phone number, website.
    • Keep your facts identical everywhere. Same business name, same phone number, same towns on every listing and your own site. Conflicting facts are how you get skipped — or misdescribed.
    • Fix wrong information. If a listicle has your old phone number, the wrong town, or a competitor’s truck on your line, correct it. The bot quotes what’s there.
    • You don’t need the ads. Paid placement on a directory is a separate purchase from being listed. The citation evidence comes from the listing, not the ad spend.

    What’s actually known — and what’s not

    Known: listicles and directories are a major citation source for AI answers — roughly a fifth of citations, and near-total absence from them collapses your naming rate to single digits. The fix is getting accurately listed on the few that rank, not buying your way onto all of them.

    Not known: exactly which listicles any given engine prefers for any given trade and city — that shifts with rankings. Nobody has published a per-market map of “these three listicles decide the plumber answers in Phoenix.” The practical move is checking your own market’s rankings directly, because that’s what the bot is reading today.

  • I Don’t Do Bing — Am I Invisible to ChatGPT?

    I Don’t Do Bing — Am I Invisible to ChatGPT?

    Short answer: Mostly, yes. When ChatGPT goes looking for live information on the web, it searches through Bing’s index — not Google’s. If your business isn’t indexed by Bing and isn’t claimed on Bing Places, ChatGPT’s live-search layer has no way to find you. Everything you built on Google — your rankings, your reviews, your Google Business Profile — doesn’t transfer to that layer.

    Why your Google work doesn’t carry over

    This is the part that stings. You spent years — maybe money, too — getting your Google presence right. Then a homeowner asks ChatGPT who to call, and none of it counts. That’s because ChatGPT reaches the open web through Microsoft’s Bing search infrastructure, not Google’s. One agency put it bluntly in a widely syndicated piece this year: “It Runs on Bing, Not Google.” A contractor who invested everything into Google rankings and ignored Bing Places is, in their words, essentially invisible to ChatGPT’s search layer.

    An SEO vendor’s FAQ answers the owner version of this question directly: “Should I optimize for Bing if I already rank well on Google? Yes, ChatGPT uses Bing’s index when browsing the web. If you’re not indexed in Bing and listed in Bing Places, ChatGPT cannot find your business.”

    What it looks like in practice

    A Vienna-based test from October 2026 ran the scenario end to end: someone asked ChatGPT to recommend an installer in Vienna. ChatGPT searched live via Bing, returned three competitors — and marked the tester’s own firm “NICHT DABEI” (not there). The firm wasn’t failing at marketing. It was failing at being in the index the bot actually reads.

    A Bend, Oregon owner’s check the same month found the same shape: the competitor who gets named is the one who ranks on Bing for the question being asked. Your Google position never enters the picture.

    The “my SEO guy says we’re covered” myth

    If your SEO provider tells you your Google work covers you for AI search, ask them one question: when did you last check my Bing presence? Google-only SEO is a real thing — plenty of shops do excellent Google work and never touch Bing, because for a decade that was a defensible call. It isn’t anymore. The AI layer that now sits between the homeowner and the phone call reads a different index, and “we’re covered” without a Bing check is a guess.

    What to actually do about it

    The good news: this is a five-minute fix, not a six-month project.

    • Claim your Bing Places listing. It’s free, it’s separate from your Google Business Profile, and it’s a real listing that feeds ChatGPT’s search layer. Most contractors have never claimed theirs.
    • Check whether Bing has indexed your site. Search site:yourwebsite.com on Bing. If nothing comes up, Bing doesn’t know your site exists — and neither does ChatGPT’s browsing layer.
    • Set up Bing Webmaster Tools. Free, takes minutes, and shows you exactly what Bing sees (or doesn’t).
    • Keep your facts identical everywhere. Same business name, same phone number, same service area on your site, Bing Places, and Google Business Profile. Mismatched facts are how businesses get misdescribed or skipped.

    What’s actually known — and what’s not

    Known: ChatGPT’s live web browsing runs on Bing’s search infrastructure. Bing Places is a real business listing that feeds that layer — unlike the mythical “ChatGPT business registry,” which doesn’t exist. Contractors who are Google-only are structurally invisible to ChatGPT’s search layer until they fix their Bing presence.

    Not known: exactly how much weight Bing Places carries versus organic Bing rankings in any given answer, or how often the underlying data refreshes. Nobody has published a controlled test of “claimed Bing Places on this date, started appearing on that date” for trades businesses. The mechanism is well-evidenced; the precise timing isn’t.

  • I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I had an AI agent doing something routine in a browser today — opening a server terminal, placing a small text file. Nothing exotic. While it worked, I opened the activity feed to watch.

    This is what I saw:

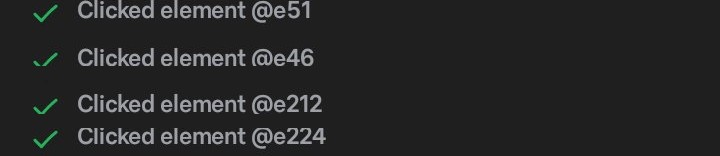
    Cropped screenshot of an AI browser agent's activity feed showing four entries labeled only with internal element IDs: Clicked element @e51, @e46, @e212, @e224.
    Four entries, cropped from the feed. Every one is an internal element ID.

    “Clicked element @e51.” “Executed click on element @e21.” “Clicked element @e224.”

    I had no idea what any of it meant.

    Here’s what I kept thinking while I stared at it: I’m watching this thing click around inside my infrastructure, and I can’t tell the difference between “everything is fine” and “it just did something terrible.” For all I knew from that feed, it could have pressed the button that drains all my money. The log was written for the machine, not for me.

    I didn’t want to interrupt. The agent was in the middle of working, and I didn’t want to be the guy hovering over the desk. So I went to look at what it was doing — and looking didn’t help, because there was nothing there a human could read.

    So I asked a question instead of making an assumption: whose labels are these? Is that how the website labels its buttons, or is that something the agent made up?

    The answer: the agent’s. The browser automation numbers every clickable element on the page so it can navigate — @e18, @e21, @e224 — and those internal reference numbers leaked straight into the activity feed a human is supposed to monitor.

    That’s when it stopped being a cosmetic complaint and became the actual point.

    Legibility is the safety feature

    An agent you can’t watch is an agent you can’t trust. An agent you can’t trust doesn’t get real work. Every roadmap that says “AI will handle X” dies at exactly this spot — not on capability, but on watchability. The machine can do the job. The human can’t verify the job. So the human doesn’t delegate the job.

    There’s an old principle — seek first to understand, then to be understood. It applied perfectly here. I could have assumed the worst and killed the task. I could have interrupted the work to ask what it was doing. Instead I asked what I was looking at, understood it, and then did the useful thing: filed the feedback so the next person watching gets words instead of codes. “Clicked the SSH button.” “Opened Compute Engine.” That’s all it would take.

    If you’re building agents, here’s the lesson: instrument for the watcher, not just the operator. The activity feed is a user interface. Nobody would ship a dashboard full of database IDs and call it done — but that’s exactly what most agent monitoring looks like right now. Label it like someone’s watching. Because someone is.

    The file got placed. The work finished fine. But the most useful thing that happened today might be the note we filed.

  • Claude Code Cloud Sessions Go GA: Claim Your $100 or $250 Credit by October 7

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic moved Claude Code cloud sessions from research preview to general availability on September 23, 2026. Existing Pro subscribers can claim a one-time $100 credit and Max subscribers a one-time $250 credit — but only for cloud-session usage, and only if you claim by 11:59 PM Pacific on October 7, 2026. Unclaimed credit disappears. Claimed credit that goes unused expires November 4, 2026.

    What a cloud session actually is

    Claude Code running on Anthropic's machines instead of yours. You hand it a task and a GitHub repository; it keeps working after you close the laptop, lose Wi-Fi, or leave the room. Anthropic's pitch: "Cloud sessions run on Anthropic-hosted infrastructure, so the work keeps going even without your computer running."

    The practical differences from a local session:

    • Your laptop is not the bottleneck. No sleep, no battery, no VPN drop killing a long task.
    • Isolation. The agent works in a hosted environment, not on your machine's files — which limits blast radius.
    • Accessible everywhere. Start on desktop, check on mobile.
    • It draws from credit, not just plan limits. The one-time credit applies automatically when you start a session, and it is separate from your weekly usage limits. Anthropic's framing: "If you hit a limit locally, keep going in the cloud until your credit runs out."

    The credit, precisely

    Pro Max
    One-time credit $100 $250
    Claim deadline 11:59 PM PT, Oct 7, 2026 11:59 PM PT, Oct 7, 2026
    Unused credit expires 11:59 PM PT, Nov 4, 2026 11:59 PM PT, Nov 4, 2026
    Eligibility Individual subscriber active Sept 23, 2026 Individual subscriber active Sept 23, 2026

    One credit per account. The credit covers cloud sessions only — not chat, not API calls, not local Claude Code. It applies before your regular plan usage, and once it's gone, cloud sessions count against your normal plan limits. There is no separate charge for the cloud container itself.

    What you need: a connected GitHub account, because every cloud session works against a repository. No GitHub, no session, no credit use.

    How to claim it

    1. Confirm your plan. Pro or Max, individual subscription, active on September 23.

    2. Connect GitHub. Required before a cloud session will start.

    3. Claim. Open claude.ai/code and use the Claim credit prompt, or run /claim-credit inside the Claude Code CLI.

    4. Start a session. From claude.ai/code, the Code tab in the Claude mobile app, the desktop app, or claude --cloud in the terminal. Anthropic also lists Routines as a starting point.

    5. Watch the dates. Claim by October 7; spend it by November 4. Last call as of today, October 6: the claim window closes 11:59 PM Pacific tomorrow, October 7, 2026. Claim it now — unclaimed credit disappears.

    Team and Enterprise users get cloud-session access through premium seats, but the $100/$250 promotional credit is the Pro/Max subscriber offer — evaluate the feature on its own merits if you're outside the promo.

    Under the hood

    Anthropic runs cloud sessions on fresh Ubuntu 24.04 virtual machines — roughly 4 vCPUs, 16 GB of RAM, 30 GB of disk, per published reports. Organizations that can't let source code run on a vendor's VMs can route sessions to self-hosted environments instead — a separate path from the consumer credit.

    Note the contrast with Remote Control: Remote Control connects a web or mobile interface to a Claude Code session running on *your own computer*, so that machine has to stay awake. Cloud sessions remove the machine entirely.

    Should you use it?

    Treat the credit as a trial budget. Point it at work that's easy to verify: bug fixes with test coverage, dependency updates, questions about a codebase. Check the branch and the pull request the agent produces before merging anything. Anthropic even describes auto-fix of pull requests directly in the cloud as a feature — still check the diff yourself.

    For occasional or non-technical users, be honest with yourself: the credit may go unused, because cloud sessions require a GitHub-connected coding workflow to begin with. That's worth knowing before you count on redeeming the full amount.

  • Claude Sonnet 5.5: Near-Opus Scores at the Sonnet Price

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic released Claude Sonnet 5.5 on September 28, 2026 — the second model in the Claude 5.5 family, six days after Opus 5.5. The headline: $2 per million input tokens and $10 per million output tokens — the exact same price as Sonnet 5 — while Anthropic's benchmarks put it near Opus 5.5 on most evals and ahead of it on Terminal-Bench 4.0. A typical workload costs about 30% less than Sonnet 5, because the model uses fewer tokens per task.

    Same price, different model

    Anthropic describes Sonnet 5.5 as "a faster, lower-cost complement to Claude Opus 5.5," strongest at well-scoped everyday tasks, bug fixing, and creating polished documents, slides, and spreadsheets. The price table:

    Sonnet 5.5 Sonnet 5 Opus 5.5
    Input / output per 1M $2 / $10 $2 / $10 $4 / $20
    Cache reads per 1M $0.20 — $0.20
    Typical workload vs predecessor ~30% less — ~40% less

    Cache writes run $2.50 per million (5-minute) and $4.00 (1-hour). The Batch API halves input and output to $1/$5. The full 1M-token context window is billed at the standard rate — no long-context surcharge.

    The benchmarks, with Anthropic's own caveat attached

    These are Anthropic's numbers from its launch table. The company's own caveat is worth quoting in full: "Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment." Read the table as a cheaper model closing most of the gap, not as a Sonnet that replaces Opus.

    Benchmark Sonnet 5.5 Sonnet 5 Opus 5.5
    Terminal-Bench 4.0 (agentic coding) 70.6% 10.3% 66.4%
    CursorBench 4.0 55.5% 34.1% 57.8%
    GDPval-AA v2.1 (knowledge work, Elo) 1844 1449 1846
    OSWorld 2.1 (computer use) 80.1% 57.0% 81.8%
    Humanity's Last Exam (with tools) 64.5% 54.9% 67.7%

    The Terminal-Bench number deserves a pause: 70.6% for a $2/$10 model beats not just Sonnet 5's 10.3% but Opus 5.5's 66.4%. That is the single most aggressive price-performance move in this release cycle. As always, validate against your own tasks before rerouting production traffic.

    Switching: what breaks

    Moving from Sonnet 5 to Sonnet 5.5 is not drop-in. Five documented breaking changes: disabled thinking, forced tool use, replaying thinking blocks across accounts, the old computer_20251124 tool on the API and Google Cloud, and using older models as advisors in the advisor tool. Test before you cut over.

    Separately: Sonnet 4.5 retires November 30, 2026, and Anthropic names Sonnet 5.5 as its replacement. If you still have 4.5 in a pipeline, that migration has a date on it. Sonnet 5 is not listed for retirement as of October 1.

    Worth knowing

    • Effort defaults differ by surface. High on the Claude Platform; medium in Claude Code and the Claude apps. Like Opus 5.5, effort is the first dial — tune it before rewriting prompts.
    • First Sonnet with Opus-class cyber safeguards. Anthropic says Sonnet 5.5's cyber capabilities are a large jump over Sonnet 5, so it ships with safeguards previously reserved for top models. Higher-risk cybersecurity prompts get detected and routed to Sonnet 5 instead; ordinary coding and bug-fixing are unaffected.
    • Where it runs. Claude apps, Claude Code, Claude Platform, Amazon Bedrock, Google Cloud, Microsoft Azure. Model ID claude-sonnet-5-5. 1M-token context, 128K max output, June 2026 knowledge cutoff.

    The honest read: Anthropic kept the sticker price flat and moved the performance. For everyday agentic coding and knowledge work, Sonnet 5.5 is now the default answer — until your workload is complex and open-ended enough that Opus 5.5's sustained judgment earns its 2x price. For the Opus side of that tradeoff, see our Claude Opus 5.5 release coverage.