Tag: Operator

  • Tacoma International Business: 2026 Trade & Sister Cities

    Tacoma International Business: 2026 Trade & Sister Cities

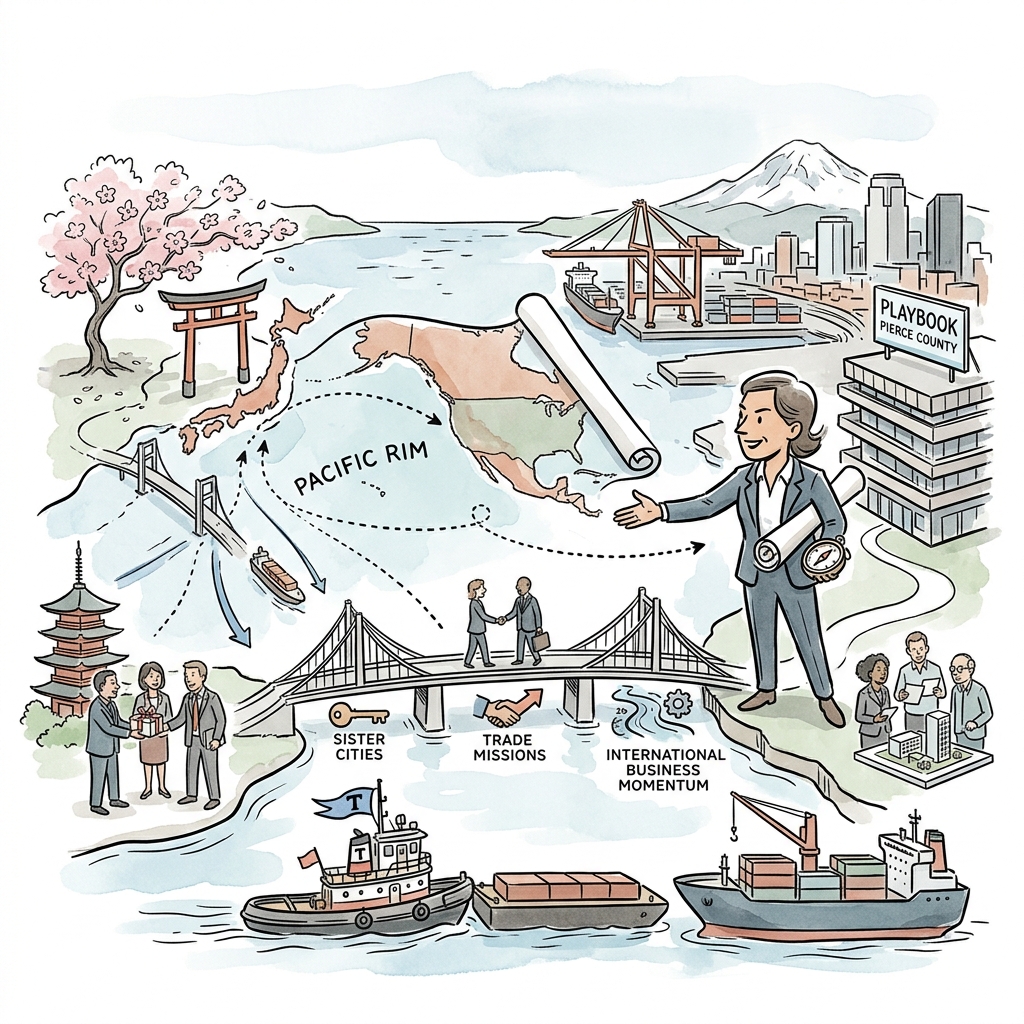
    If you spend any time tracking economic development in Tacoma, you notice something that doesn’t always get enough attention: this city has been doing international business since before “global supply chains” was a buzzword. The Port of Tacoma has been a Pacific gateway since the late 1800s. The sister city program stretches back to 1959, when Tacoma first linked up with Kitakyushu, Japan. And the World Trade Center Tacoma — the only full-service WTC in the Pacific Northwest — has been quietly connecting Pierce County operators to overseas markets for decades.

    Last refreshed: October 9, 2026 (Pacific).

    What’s changed in 2026 is the pace and the intentionality. State-level trade missions, newly expanded sister city partnerships, and a foreign investment pipeline into downtown Tacoma are all converging at once. Here’s what local operators and community leaders need to know.

    The Japan Trade Mission: Tacoma Sent a Delegation to Tokyo in May 2026

    The most significant recent development on the international business front is the Washington Secretary of State’s Japan Trade Mission, which ran May 16–27, 2026. Led by Secretary of State Steve Hobbs, the 40-member delegation traveled to Tokyo to reinforce Washington’s position as one of Japan’s most important American trading partners.

    Tacoma’s fingerprints were all over this one. The World Trade Center Tacoma was among the coordinating organizations, and the Economic Development Board for Tacoma-Pierce County (EDB) participated directly. The delegation covered sectors that matter deeply to Pierce County: aerospace, sustainable aviation fuel, agriculture, and advanced manufacturing.

    The numbers behind this relationship are not small. Japan is the largest foreign investor in the United States, and the Washington State-Japan bilateral trade relationship is valued at $11.1 billion. Tacoma and Pierce County are specifically home to multiple Japanese-owned U.S. subsidiaries that have collectively invested more than $550 million in capital expenditures over the past decade, according to the South Sound Business Journal.

    These aren’t abstract statistics. They represent factories, logistics facilities, and engineering jobs that exist in Pierce County because of sustained relationship-building over years. The May 2026 mission was the continuation of that work — executives and public officials in the same room, reinforcing connections that underpin thousands of local paychecks.

    Tacoma’s 15 Sister Cities: The World’s Longest-Running Business Development Network

    People sometimes think of sister city programs as ceremonial — plaques, cultural festivals, the occasional student exchange. That undersells what Tacoma’s program actually is. The Tacoma Sister Cities network encompasses 15 relationships across four continents, and for operators with international ambitions, these connections represent real access.

    The full roster includes:

    • Asia-Pacific: Kitakyushu, Japan (1959) | Fuzhou, China (1994) | Gunsan, South Korea | Taichung, Taiwan | Davao City, Philippines
    • Europe: Aalesund, Norway | Biot, France | Hvar, Croatia | Brovary, Ukraine
    • Russia/Eurasia: Vladivostok, Russia (1992)
    • Africa/Middle East: George/Garden Route District, South Africa | El Jadida, Morocco | Kiryat Motzkin, Israel
    • Americas: Boca del Rio, Mexico | Cienfuegos, Cuba

    According to the City of Tacoma, the program focuses on cultural arts and tourism, global education, government relations, and international business development. That last bucket is the one that deserves more attention from the Pierce County business community.

    Why the Pacific Rim Relationships Are Particularly Valuable

    Of Tacoma’s 15 sister cities, the Pacific Rim relationships carry the most direct commercial weight — which makes sense given the Port’s geographic position. Kitakyushu has been a sister city for 67 years and has an industrial economy that mirrors Tacoma’s: manufacturing, logistics, environmental technology, and steel. Fuzhou is a major Chinese port city and manufacturing hub. Gunsan, South Korea has aerospace and automotive ties. Taichung is Taiwan’s second-largest city and a semiconductor and machinery manufacturing center.

    For Tacoma businesses looking at export markets, these aren’t just symbolic relationships. They’re introductory infrastructure — a channel into business communities that are otherwise difficult to access cold.

    A New Chapter with South Africa: The Garden Route Partnership

    The most recent headline in Tacoma’s sister city world comes from the other side of the Pacific Rim frame — the South African coast. In March 2026, the City of Tacoma officially elevated its 28-year relationship with George, South Africa into a broader district-wide partnership with the Garden Route District Municipality, a coastal economic zone that shares notable similarities with Pierce County: port access, maritime culture, outdoor recreation, and a growing agricultural export sector.

    That expansion was followed quickly by action. A Garden Route delegation visited Tacoma from April 23–28, 2026, according to the Garden Route District Municipality’s official release. The visit, coordinated by Tacoma Sister Cities’ Melannie Cunningham, focused on port city and maritime trade alignment, agricultural export opportunities in the ostrich industry, skills transfer and vocational education exchange, and tourism and sports diplomacy frameworks.

    This is what a mature sister city program looks like in practice — not a one-time visit but an escalating series of structured exchanges that build toward actual commerce. The Garden Route partnership expansion suggests Tacoma’s international affairs office is actively working to add economic substance to these relationships.

    The World Trade Center Tacoma: Your On-Ramp to International Markets

    If you’re a Pierce County business owner thinking “I’d like to be in the room when these delegations come through,” the World Trade Center Tacoma (WTCT) is where you start. Operating as the lone full-service WTC in the Pacific Northwest, WTCT specializes in organizing inbound and outbound trade missions, connecting local firms with international buyers and distributors, export counseling and market-entry support, and coordinating with state agencies, the Port, and the EDB on investment attraction.

    The Port of Tacoma has described WTCT as the connective tissue between the region’s trade infrastructure and the individual businesses that want to use it. For mid-sized manufacturers, ag exporters, or tech firms looking at Pacific Rim market entry, WTCT is the most direct path into that network.

    The Bigger Picture: $52 Billion in Annual Trade and a Port That Beats LA on Speed

    All of this diplomatic and organizational activity sits on top of a genuinely exceptional piece of trade infrastructure. Pierce County’s position in the Pacific Rim economy isn’t aspirational — it’s structural. Tacoma trades nearly $36 billion in goods with Japan and China alone. Total international trade value through the Northwest Seaport Alliance approaches $75 billion annually, supporting 48,000+ jobs and $4.3 billion in regional revenue. The Port’s location gives shippers access to Pacific Rim markets several days faster than LA or San Diego. And the Port’s Foreign Trade Zone #86 allows businesses to delay or eliminate U.S. Customs duties on imported inputs.

    According to Make It Tacoma, Chinese foreign direct investment alone has contributed more than $300 million toward downtown Tacoma development, including a 22-story four-star hotel and mixed-use projects near the Convention Center.

    This is the context in which those trade missions and sister city exchanges happen. They’re not feel-good diplomacy layered on top of a standard mid-size American city. They’re relationship maintenance for a regional economy that is genuinely, structurally embedded in the Pacific Rim trade system.

    What This Means for Pierce County Operators in 2026

    The immediate takeaways for local business owners and economic development stakeholders: The Japan relationship is active and being tended. If you’re in aerospace supply chain, agriculture, manufacturing, or logistics and haven’t engaged with the EDB or WTCT about Japan market access, the May 2026 trade mission is a reminder that state-level infrastructure is in place to support that work.

    The South Africa expansion is a signal worth watching. The Garden Route partnership is broader than a single-city tie — it’s a district-to-city framework that could open agricultural and maritime commerce channels that didn’t exist before. Operators in food production, port services, and vocational education have specific angles here.

    And the sister city network is real infrastructure, not ceremony. With 15 relationships active and the City’s international affairs office clearly engaged, Tacoma has warm introductory access into business communities across Japan, China, Korea, Taiwan, the Philippines, and beyond. That access has to be activated by individual businesses — but the on-ramp exists.

    Tacoma has been a Pacific Rim city since the railroads arrived. The difference in 2026 is that the diplomatic, organizational, and trade infrastructure is more sophisticated than it’s ever been — and more of it is accessible to operators who know to look.


    Frequently Asked Questions

    How many sister cities does Tacoma have?

    Tacoma has 15 official sister cities spanning four continents, including Kitakyushu (Japan), Fuzhou (China), Gunsan (South Korea), Taichung (Taiwan), Davao City (Philippines), Vladivostok (Russia), Aalesund (Norway), Biot (France), Hvar (Croatia), Brovary (Ukraine), El Jadida (Morocco), George (South Africa), Boca del Rio (Mexico), Cienfuegos (Cuba), and Kiryat Motzkin (Israel).

    What is the World Trade Center Tacoma and what does it do?

    The World Trade Center Tacoma (WTCT) is the only full-service World Trade Center in the Pacific Northwest. It facilitates inbound and outbound trade missions, connects Pierce County businesses with international partners, and coordinates with state agencies to support export growth and foreign direct investment in the region.

    What was the 2026 Washington State Japan Trade Mission?

    Led by Washington Secretary of State Steve Hobbs, the May 2026 Japan Trade Mission sent a 40-member delegation to Tokyo from May 16–27. The delegation included World Trade Center Tacoma, the EDB for Tacoma-Pierce County, state legislators, and industry leaders in aerospace, agriculture, and creative industries. Japan is Washington’s largest foreign investment partner, with bilateral trade valued at $11.1 billion.

    How much trade flows through the Port of Tacoma with Pacific Rim countries?

    Tacoma trades nearly $36 billion in goods with Japan and China alone, with total international trade volume across the Northwest Seaport Alliance approaching $75 billion annually. The Port of Tacoma’s location gives shippers access to Pacific Rim markets several days faster than West Coast ports like Los Angeles and San Diego.

    What is Tacoma’s newest international partnership in 2026?

    In March 2026, Tacoma elevated its 28-year sister city relationship with George, South Africa to a broader district-wide partnership with the Garden Route District Municipality. An exchange delegation visited Tacoma April 23–28, 2026, focusing on port city trade, maritime culture, skills transfer, ostrich industry exports, and academic exchange programs.
  • Second Restoration Location: Why $5M is the Threshold

    Second Restoration Location: Why $5M is the Threshold

    Most restoration owners get the second-location itch around $3M. The honest answer is they shouldn’t scratch it until $5M — and even then, only if a specific list of things is already true inside the first shop.

    Opening a branch is one of those decisions that looks like growth on the surface and turns into the slow bleed underneath. The mistake is almost never the second location itself. The mistake is the first location wasn’t ready to be left alone yet, and the owner went from running one healthy business to running two broken ones.

    Here’s the honest framework. Not the cheerleader version.

    Why $5M Is the Real Threshold (Not $3M)

    Industry valuation data makes this concrete: restoration shops under $2M trade at roughly 2.8x–3.0x SDE. Once you cross $5M with a diversified service mix, multiples jump to 4x–7x EBITDA. That gap is not just about revenue — it reflects what buyers see in the operation. A $5M shop has a real second layer of leadership. A $3M shop almost always doesn’t.

    When you open a second location from a $3M base, you are usually taking the only person who knows how to run the business — you — and splitting yourself in half. The first location’s gross margin starts compressing within ninety days. The new location burns cash for twelve to eighteen months before it stabilizes. Now you have two locations that both need you and neither one is the business it used to be.

    At $5M, you typically have an operations manager, a production manager, a dedicated estimator or project manager bench, and recurring TPA volume that doesn’t depend on the owner answering the phone. That is the difference. The threshold isn’t a dollar figure — it’s whether the first location can run a full week without you in the building.

    The Five Things That Have to Be True Before You Open

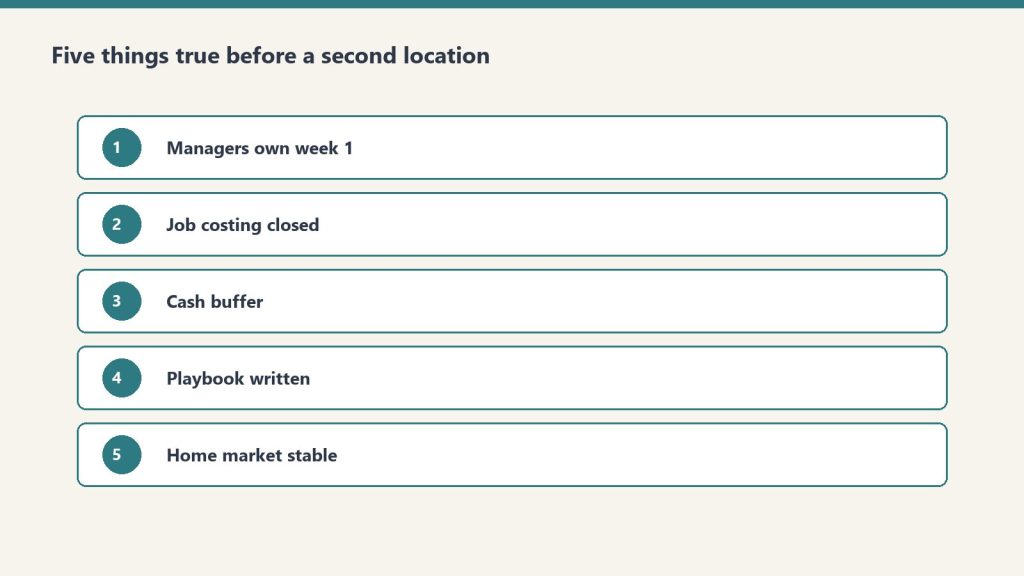
    Numbered checklist of five readiness conditions before opening location two
    Five things have to be true before you open.

    1. The first location can survive 30 days without you. Not “the work gets done.” That you can be unreachable for a month and the financials, the TPA scorecards, and the production schedule all stay inside normal range. If you can’t do that, you don’t have a second-location problem. You have a delegation problem at the first one, and adding geography won’t fix it.

    2. You have an operations manager who is not you and is not a relative. Family members can run a second location, but only if they were already running a P&L inside the first one. The second-location playbook is the operations manager playbook. If you don’t have someone who can hold gross margin, manage WIP, and run a weekly production meeting without you in the room, the branch will not work.

    3. The new market has documented demand, not a feeling. Pull the data before you sign a lease. Carrier referrals you’re already turning down in the target market. TPA territory gaps your existing programs have flagged. Search volume for “water damage restoration [city]” and the CPC on it. If the only reason you’re picking the market is that your cousin lives there or you saw a competitor’s truck, you don’t have a market — you have a hunch.

    4. The first location is throwing off enough cash to fund 18 months of branch burn. A new restoration location typically loses money for twelve to eighteen months. Plan for the long end. SBA expansion loans usually want a 1.25 DSCR before they’ll touch it, which means your existing operation has to be healthy enough to service the new debt while the branch is still in the red. If the math doesn’t work without the new location immediately producing, the math doesn’t work.

    5. Your tech stack scales without bolt-ons. If your job management software, Xactimate workflow, and TPA portal logins are all stitched together by tribal knowledge inside the first office, the second location will not run the same playbook. It will run a worse one. The system has to be portable before the branch opens, not after.

    What Most Owners Get Wrong

    Restoration technicians training in a shop bay with equipment demo and whiteboard
    Most owners get people depth wrong — not the lease math.

    The most common second-location failure pattern goes like this. Owner hits $3.5M. Owner is tired, ambitious, and has an opportunity — a competitor closing down, a key employee asking for an ownership path, a city forty-five minutes away that “doesn’t have anyone good.” Owner signs a lease, hires a production lead, and tells himself the branch will be self-sufficient by month six.

    Month six arrives. The branch is at 40% of projected revenue. The original location’s gross margin has slipped four points because the best production manager got moved to the new branch and the bench underneath wasn’t ready. The owner is driving between two offices three days a week. Cash is tight. The owner doubles down — hires another person, runs a Google Ads campaign in the new market, increases the burn — and by month eighteen the branch is either limping or being quietly wound down.

    This isn’t a hypothetical. It is the most common growth-stage failure in the industry, and it happens because the second location was opened as a revenue bet when it should have been opened as an operational bet.

    The Counter-Pattern: What Works

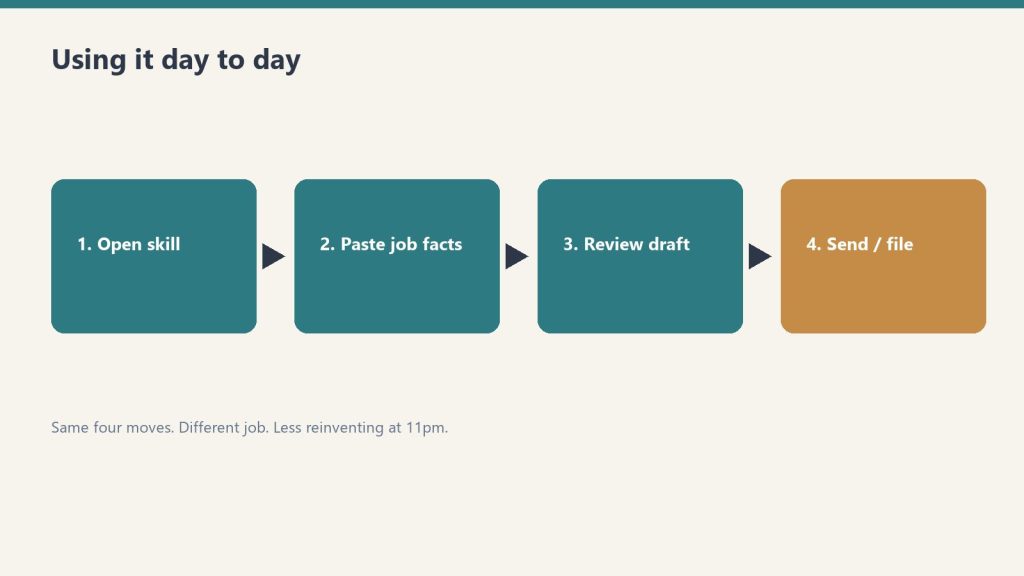
    Four-step flow: open skill, paste job facts, review draft, send or file
    Counter-pattern: repeatable runs beat hopeful maps.

    The owners who successfully open second locations almost always share three traits. First, they spent eighteen to twenty-four months building the leadership bench inside the first location before they ever talked about a branch. Second, they entered the new market with a known revenue floor — either a TPA program that committed volume, a large commercial client base in the geography, or a key person from the new market with their own book. Third, they treated the first six months of the branch as an investment, not a revenue line. They didn’t expect the branch to carry itself. They expected to lose money buying market presence and learning the territory.

    The phrase that separates the two camps is simple. Failed openings start with “we need to grow.” Successful openings start with “we have the team and the demand to grow.”

    The Bottom Line

    If you’re under $5M and you don’t have a real operations bench, do not open a second location. Spend the next twelve months building the bench, hardening the tech stack, and proving the first location can run without you. The valuation gap between a clean $5M single location and a $7M two-location operation where both are slightly broken is enormous — and it almost always favors the clean single.

    The second location is a multiplier. It multiplies whatever is true about the first one. If the first one is humming, you’ll build something worth selling for 5x EBITDA. If the first one is fragile, you’ll build two fragile ones and discover that the buyers paying premium multiples will pass on both.

    Build the bench. Document the playbook. Hit $5M with the owner out of the truck. Then open the second.

    Related on Tygart Media: company revenue · cash flow & profit · owner freedom kit.

  • OpenAI Everything App: Why Behavior Beats Infrastructure

    OpenAI Everything App: Why Behavior Beats Infrastructure

    Microsoft has LinkedIn and enterprise distribution. Google has the native stack. Notion has the database architecture. OpenAI has something none of them have: 1.2 billion people a week who already open ChatGPT when they want to get something done. That’s not a product advantage. That’s a behavior advantage. And behavior is the hardest moat to breach.

    Where OpenAI Sits in This Series This is the fifth piece examining who builds the everything app. We’ve covered Microsoft, Google, Notion, and the everything database frame. OpenAI’s path is the most unusual: they’re not building from infrastructure up. They’re building from user behavior down.

    The Model Reality First — Get This Right

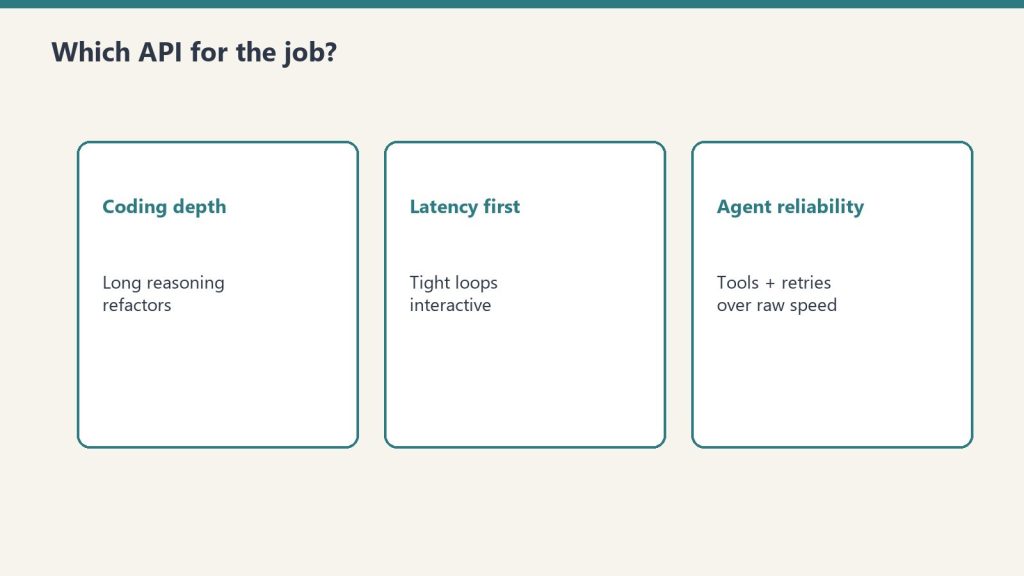
    Three cards: coding depth, latency first, agent reliability
    Model reality first — get this right.

    Before the strategy discussion, the model facts — because the landscape shifted significantly in early 2026 and the marketing doesn’t always match what’s actually deployed.

    As of mid-2026, OpenAI’s current flagship is GPT-5.5, which powers ChatGPT Enterprise (unlimited messages) and is the reasoning backbone of the unified super-assistant experience. The o-series models, such as o3, are the thinking models, trained to reason longer before responding; o3 is the deep-reasoning option. o4-mini, the former high-throughput option, was retired from ChatGPT on February 13, 2026, though it remains available in the API.

    Notably, GPT-4o, GPT-4.1, and GPT-4.1 mini were retired from ChatGPT as of February 13, 2026. Enterprise customers retained GPT-4o access until April 3, 2026. If you’re referencing these models in your stack — in tutorials, in documentation, in integrations — those references are now stale. OpenAI’s lineup keeps moving: at DevDay on September 29, 2026, it showcased GPT-6 Astra and revealed GPT-6.1 Sol.

    One more significant infrastructure move: the Assistants API was deprecated and removed from the API on August 26, 2026. OpenAI is replacing it with the Responses API — a new primitive that combines Chat Completions simplicity with Assistants-style tool use, supporting web search, file search, and computer use natively. If you built on the Assistants API, your integration needs to run on the Responses API now.

    OpenAI’s Everything App Bet: Behavior Over Infrastructure

    Three stacked layers: chat UI, tools, agent runtime
    Behavior over infrastructure.

    Microsoft’s everything app bet is infrastructure — they own the OS, the enterprise software stack, and a professional network. Google’s bet is native stack — they own search, email, calendar, and mobile. Both are building from the platform up.

    OpenAI is doing the opposite. They’re starting from where people already go to get things done, and expanding outward from that behavioral beachhead. ChatGPT’s 1.2 billion weekly users don’t use it because it owns their email. They use it because it’s the fastest path from question to answer, from idea to draft, from problem to solution.

    The everything app doesn’t have to own your data. It just has to be the place you go first. OpenAI is betting that if they can make ChatGPT good enough at enough things — and fast enough at integrating with the tools you already use — the behavioral habit becomes the moat. You stop going to Google first. You stop opening a new app. You open ChatGPT.

    The Pieces OpenAI Has Assembled

    The consolidation has been quieter than Microsoft’s marketing machine or Google’s Cloud Next announcements, but the pieces are substantial.

    Operator — the computer-using agent — launched as a research preview in early 2025 and integrated fully into ChatGPT by mid-year. It browses, clicks, fills forms, and manages logins autonomously. GPT-5.5’s score on OSWorld-Verified — the standard benchmark for computer-use agents — is 78.7%. The human baseline on the same benchmark is 72.4%. That’s not a lab result. That’s production-grade desktop and browser automation beating human performance on standardized tasks.

    Projects and Memory — launched across late 2024 and 2025 — give ChatGPT persistent context across sessions. Projects (December 2024) let you organize work by context. Project Memory (August 2025) lets ChatGPT learn your preferences, communication style, and working patterns over time. This is the foundational layer for the everything app: an AI that knows you, not just your current prompt.

    Workspace Agents for Enterprise — launched April 22, 2026 — let enterprise teams create, share, and manage AI agents for workflow automation. Powered by Codex, these agents handle reporting, coding, and messaging tasks autonomously. This is OpenAI’s direct enterprise play, competing with Microsoft’s Agent 365 and Google’s Workspace Studio on their home turf.

    Sora 2 — released September 2025 — moved AI video from novelty to production-grade. It’s available both as a standalone app and deeply integrated within ChatGPT. Video generation, image creation, voice, code execution, deep research, file analysis — all inside one interface. The surface area of what ChatGPT can do has expanded faster than most people have tracked.

    The Apps SDK and MCP support — announced in 2025 — let developers build UIs alongside MCP servers, defining both logic and interactive interface of applications that run inside ChatGPT. OpenAI is building a developer ecosystem where third-party tools surface inside ChatGPT natively, not as links out to other apps.

    The Honest Strategic Weakness: OpenAI Doesn’t Own the Data Layer

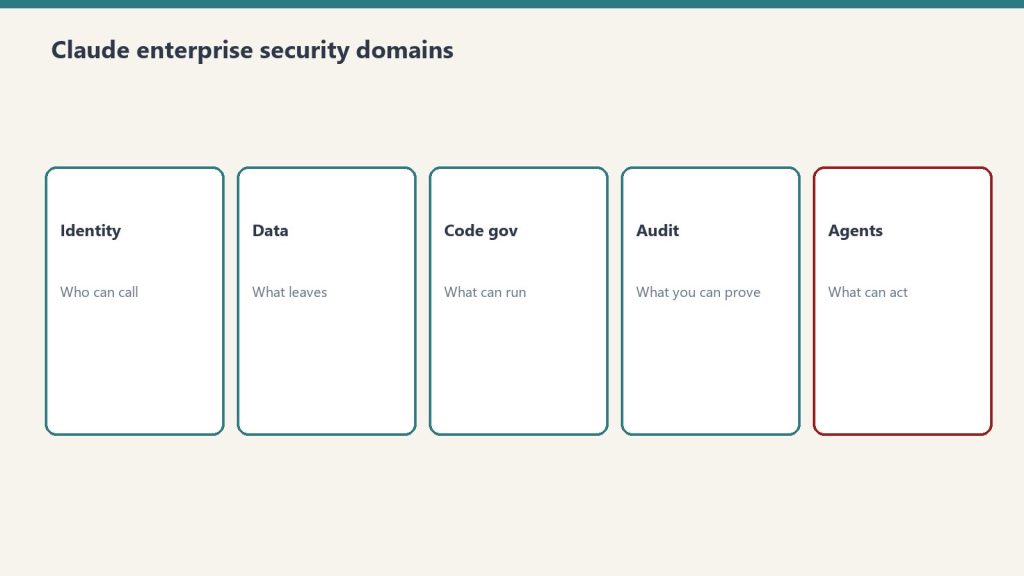
    Five security domains: identity, data, code governance, audit, agents
    Honest weakness — doesn’t own the data layer.

    Here’s the structural problem with OpenAI’s everything-app path that doesn’t get enough attention.

    Microsoft owns the calendar data, the email data, the document data, the professional network data. Google owns the same stack natively. Notion owns the database architecture where your operational data lives. OpenAI owns a conversation history and whatever files you’ve uploaded to Projects.

    That’s a meaningful gap. When you ask Microsoft Copilot “what happened in last week’s client meeting?” it can actually answer — because it has the calendar event, the Teams recording transcript, and the follow-up email thread. When you ask ChatGPT the same question, the answer is only as good as what you’ve explicitly provided.

    OpenAI’s answer to this is Operator and the connector ecosystem — let ChatGPT reach into your existing tools and pull the data it needs. That works, but it creates a dependency chain that Microsoft and Google don’t have. Every integration is a point of failure. Every API change is a breakage risk. Every permission prompt is friction that erodes the behavioral habit.

    The Responses API — replacing the Assistants API in August 2026 — is designed to close some of this gap with native web search, file search, and computer use built in. But native search is not the same as owning the inbox. And computer use, for all its benchmark performance, is still slower and less reliable than a dedicated integration.

    Where OpenAI Wins: The Consumer and Creator Layer

    The enterprise everything-app race may go to Microsoft or Google by default — too much infrastructure, too many IT relationships, too much compliance architecture for a newcomer to overcome in 18 months.

    But the consumer and creator layer is wide open. And that’s where OpenAI’s behavioral moat matters most.

    For freelancers, solopreneurs, content creators, small agencies, and knowledge workers who aren’t tied to an enterprise IT environment, ChatGPT is already the everything app. It drafts your emails, edits your copy, analyzes your data, generates your images, browses for research, and runs your automations. The question isn’t whether they’ll adopt it — they already have. The question is whether OpenAI deepens that relationship fast enough to make switching costly before Microsoft and Google catch up on the consumer side.

    Memory is the weapon here. The longer a user runs their work through ChatGPT Projects with memory enabled, the more context OpenAI accumulates about how that person thinks, works, and communicates. That context is genuinely hard to transfer to a competing platform. It’s not data in a database — it’s learned behavioral preference. The switching cost compounds with every session.

    The Operator Economy: OpenAI’s Wildcard

    The most underrated piece of OpenAI’s everything-app strategy isn’t ChatGPT itself — it’s the operator ecosystem.

    An “operator” in OpenAI’s framework is any business that deploys ChatGPT capabilities inside their own product. Every company building on the OpenAI API — embedding ChatGPT into their CRM, their help desk, their e-commerce platform, their internal tools — is an operator. Every one of those deployments is a surface where OpenAI’s models become the intelligence layer of someone else’s everything app.

    Microsoft has Copilot. Google has Gemini. But neither of them has the sheer number of third-party applications already running on their models that OpenAI has accumulated. The operator ecosystem means OpenAI doesn’t have to build every surface themselves. They just have to remain the model that operators trust most — and as long as GPT-5.5 and the o-series stay at the frontier of capability, that trust is relatively durable.

    The Workspace Agents launch, combined with the Apps SDK and MCP support, is OpenAI formalizing this operator model for enterprise. They’re saying: we won’t replace your enterprise software stack. We’ll become the reasoning layer that sits across all of it.

    What This Means for Your Stack Right Now

    If you’re building on OpenAI’s API or running workflows through ChatGPT, three immediate action items:

    • Finish your Assistants API migration. The Assistants API was removed on August 26, 2026, and the Responses API migration path is documented.
    • Enable Projects and Memory for your team’s ChatGPT accounts. The compounding advantage of memory only builds if you start using it. Teams that have six months of Project memory by Q4 2026 will have a materially different AI experience than teams starting fresh.
    • Think about where ChatGPT sits relative to your Notion database. OpenAI’s operator model and MCP support mean ChatGPT can connect to your Notion everything database via the Notion Public API. The everything database frame doesn’t require you to choose between Notion and ChatGPT — it lets you use both, with Notion as the structured data layer and ChatGPT as the reasoning and action surface on top of it.

    The everything app race isn’t over. OpenAI has the behavior moat, the operator ecosystem, and the fastest-moving model roadmap of any company in this field. What they don’t have is the data infrastructure that Microsoft and Google own by default. How they close that gap — through connectors, through Operator’s computer-use capabilities, through the Responses API — will determine whether ChatGPT becomes the everything app or the everything layer sitting on top of someone else’s everything app.

    Both outcomes are valuable. Only one of them wins the race.

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What is OpenAI’s current flagship model in 2026?

    As of mid-2026, GPT-5.5 is OpenAI’s primary model powering ChatGPT Enterprise. The o3 model handles deep reasoning tasks. GPT-4o, GPT-4.1, GPT-4.1 mini, and o4-mini were retired from ChatGPT on February 13, 2026. The Assistants API was removed on August 26, 2026, replaced by the Responses API. At DevDay on September 29, 2026, OpenAI showcased GPT-6 Astra and revealed GPT-6.1 Sol.

    What is the OpenAI Responses API?

    The Responses API is OpenAI’s replacement for the Assistants API (sunset August 26, 2026). It combines Chat Completions simplicity with Assistants-style tool use, supporting built-in web search, file search, and computer use. It’s the new primitive for building agents on OpenAI’s platform.

    What are OpenAI Workspace Agents?

    Launched April 22, 2026, Workspace Agents let enterprise teams create, share, and manage AI agents for workflow automation inside ChatGPT. Powered by Codex, they handle reporting, coding, and messaging tasks autonomously — OpenAI’s direct enterprise play against Microsoft Agent 365 and Google Workspace Studio.

    How does ChatGPT Operator work?

    Operator is OpenAI’s computer-using agent — it browses, clicks, fills forms, and manages logins autonomously. GPT-5.5 scores 78.7% on the OSWorld-Verified benchmark for computer-use tasks, above the 72.4% human baseline. It’s integrated directly into the ChatGPT interface for eligible plans.

    Can ChatGPT connect to a Notion database?

    Yes. Via the Notion Public API and OpenAI’s MCP support and connector ecosystem, ChatGPT can read from and interact with Notion databases. This makes the “everything database” architecture viable with OpenAI as the reasoning surface — Notion holds the structured data, ChatGPT reasons and acts on it.

  • Follow-Up Cadence: Why Waiting on a Person is About You

    Follow-Up Cadence: Why Waiting on a Person is About You

    Article 35 split waiting into two states that look identical in a Kanban column. Waiting on an event (deployment window, court date, market signal) runs on its own clock. Waiting on a person doesn’t have a clock unless the operator builds one. Once the distinction is named, a question arrives that pretends to be smaller than it is: how long before the operator goes first?

    The instinct is to answer with arithmetic. Five days. Seven. The Inner Circle window. Some default that doesn’t require thinking each time. The Waiting Discipline Runbook this work is producing keeps trying to write that number down.

    The number won’t hold. Not because the math is hard — because the math is a category mistake.


    The cadence question has been misframed since the day it was posed. The framing assumes there is a counterparty clock you are honoring. There isn’t. The other person is not running a private accounting of how long it’s been since they heard from you. They are not waiting for the polite re-touch window to close before raising the same flag back. Their silence is not a measured pause inside a cadence both of you are observing. It is, in almost every case, simply silence.

    Which means the only ledger that exists is yours. And the only ledger that has ever existed is yours.

    The cadence was never about them.


    Once that lands, the question reshapes. It is no longer how long should I wait before nudging. It is how long can the silence sit before it becomes a position I’m taking.

    Those are different questions. The first is etiquette. The second is accountability.

    Etiquette has a defensible answer because it points outward — I waited the appropriate amount. Accountability points inward and admits no defensible answer because the variable is not the calendar, it is what the operator can live with. Some operators can live with two weeks of silence before it costs them something. Some can’t live with three days. The variable isn’t the relationship; it’s the operator’s tolerance for the ambiguity of an unanswered ask before that ambiguity converts into a quiet decision the other party didn’t make.

    This is the conversion that goes unnoticed. After enough silence, the absence of a reply becomes the reply. The operator who didn’t go first ends up having taken a position by attrition — declined the project, withdrew the offer, ended the partnership — without ever having to author the position. Silence is cheap because nobody has to sign it.


    So the principled cadence for a relational predicate isn’t a number of days. It is the date by which the operator would rather speak than be moved into a position they did not consciously take.

    That date is irreducibly case-by-case in its specifics, and entirely lawful in its shape. The shape is: the operator names, at the moment of marking, the date by which the silence will start authoring on their behalf — and commits to going first on or before that date, regardless of whether the other party has moved.

    This is not a follow-up cadence. It is a conversion-prevention cadence. And it has nothing to do with what the other party is doing.

    The reason a default heuristic feels so attractive is that it removes the discomfort of having to ask, every time, what is the cost to me if this silence keeps going? A default lets the operator outsource the discernment to the calendar. The trade is that the calendar doesn’t know what the relationship can hold or what the operator can defend, and it will, with great consistency, schedule moves that look like respect from the outside and feel like avoidance from the inside.


    The type-tagging Article 35 opened up survives this clarification but has to become more specific. An event-predicate gets the surfacing rule. A person-predicate gets two dates: the date the operator would prefer the other party to move, and the date the operator goes first if they haven’t. The first is a hope. The second is a position. Only the second goes in the ledger, because only the second has the operator’s name on it.

    The system can hold both dates and ask which is which. The system cannot tell the operator what they can live with — that’s the uncategorizable part of every relationship and the reason the runbook can scaffold the practice but cannot replace the discernment.

    What makes the discipline work is not the calendar; it’s that the operator pre-commits to a date they will defend before the silence has had a chance to author the answer. The calendar is in service of the position, not the other way around.


    There’s a corollary that lives one layer deeper and won’t fit cleanly inside this piece. Multiple operators inside the same workspace each holding parallel relational predicates against the same external party produce a collective version of this problem that no individual queue can detect. Three people each waiting two weeks on the same person have not waited two weeks. They have produced six weeks of distributed silence, none of which any of them owns alone.

    That’s the next thread. The shape of it is already visible from here.

    Related on Tygart Media: Kanban blocked tasks · task management discipline.

  • Managing Kanban Blocked Tasks: Two Kinds of Waiting

    Managing Kanban Blocked Tasks: Two Kinds of Waiting

    The last piece named predicate-dependent items as one of three structurally different things sitting in a queue. They are correct in category, wrong in moment. The right move is to name the trigger and remove the item from the active queue until the predicate resolves.

    That distinction was useful. It also collapsed two genuinely different states into one.

    Waiting on an event and waiting on a person are not the same kind of waiting. They look identical in a Kanban column. They lie in different directions about what is actually happening.


    The Custodial Predicate

    A deployment window opens on a date. A market signal arrives or it doesn’t. A court date is on the calendar. A regulatory comment period closes. These are events. The predicate is custodial. The operator’s job is to be ready when the trigger fires and not let the item sublimate into background noise in the meantime.

    There is nothing to negotiate with an event. The predicate fires regardless of how the operator feels about it. The discipline is vigilance, not effort.

    The Relational Predicate

    A reply from a person is something else entirely. The predicate is a relationship that has its own state, its own pressure, its own inertia. The person on the other end is a system with their own queue and their own residual courage problem.

    The trigger is not on a calendar. The trigger is whether something happens between two people, and one of those people is on the operator’s side of the conversation.

    This is the seam where disciplined waiting starts to wear the same costume as conflict avoidance.


    The Identical Artifact

    Two predicates can pass thirty days in identical states. One was waiting because nothing yet had information to act on. The other was waiting because nobody made the move that would generate the next state. A queue cannot tell the two apart. The operator can.

    The first failure mode is treating both as the event-shaped kind. This is what the queue invites. Marking a relational predicate and walking away feels exactly like principled patience. It performs the discipline named earlier — specific, dated, reviewable. The artifact is identical. The internal predicate is reversed.

    This is why the signal that distinguishes principled non-response from avoidance — that a real refusal carries an implicit re-entry condition — has to be re-asked at the predicate layer. With a person-shaped predicate, the re-entry condition cannot only be on the calendar. It has to also be: what would change my mind about who goes next? If the answer is “nothing” and you are the one who hasn’t moved, you are not waiting. You are declining without naming it.

    The second failure mode is the inverse. Operators who escalate every predicate at every cadence because uncertainty about timing makes them anxious. The deployment window does not care about your text message. The court date moves on its own. Treating an event-predicate as a person-predicate burns relational currency for nothing — the same energy spent on a real person-predicate would have actually moved a state.


    The Question to Ask at the Moment of Marking

    The healthier move is to require, at the moment a predicate is set, an explicit answer to one question: what kind of trigger is this?

    If event: name the date or the condition, set the surfacing rule, walk away. The discipline is custodial. The operator owes the predicate vigilance, not action.

    If person: name the move that would force the next state, and name the date the operator goes first if the other party hasn’t. The discipline is not custodial — it is a private commitment. The follow-up is not optional. It is the predicate.

    This second case is where most operators leak time, because the words available for it are bad. “Waiting on a reply” sounds humble. It also sounds permanent. There is no public language for “I am the one who has not yet sent the next message that would move this,” and absent that language, the queue absorbs the omission and renders it as patience.

    A tighter signal: a person-shaped predicate that has not moved for two cadences is no longer waiting on the other party. It is waiting on the operator, mislabeled.


    Why the Hard-Cap Rule Feels Embarrassing

    This explains why a stale-blocked rule — items in a holding pattern past some threshold get yanked back into the active conversation — feels both clarifying and embarrassing when it finally arrives. It does not introduce new information. It forces the operator to rename the items already on the board.

    Most of what was “blocked” was the operator’s silence dressed in someone else’s name.

    The custodial discipline transfers cleanly from a person on a deal to an event on a calendar — but the inverse does not transfer. You cannot wait on a person the way you wait on a market signal. The market signal is not running its own private accounting of how long it has been since it heard from you.


    What the System Can Hold and What It Cannot

    The deeper implication for autonomous systems is that the predicate field on a queue item has been under-specified. A single “waiting” status with no shape attached is the configuration the queue inherited from a paper era when both kinds of waiting hurt about the same. They no longer hurt the same.

    The event-predicate hurts on a calendar. The person-predicate compounds in a relational ledger nobody keeps. A surfacing system that can already detect recency cannot read intent — but the operator can be asked, at the moment of marking, to declare which kind it is, and the dashboard can hold them to the declaration.

    The familiar risk surfaces here too. Make person-predicate a first-class status and the temptation will be to file conflict-aversion under it with a polite face — to declare every awkward conversation a “person-predicate, follow-up scheduled” and then never do the follow-up. The discipline of principled refusal has to chain forward: the re-entry condition for a person-predicate is itself a position, dated, that the operator can be held to.

    What the operator owes the person-shaped predicate is the move that would generate the next state. The system can ask the question; the system cannot make the move. The hour after the briefing recurs at the predicate layer: the system has, at this point, more information about what is waiting on whom than the operator does — but only the operator can convert any of that information into a sentence that gets sent.

    The queue can hold the shape of two kinds of waiting. The operator has to remember which kind they were holding.

    Related on Tygart Media: follow-up cadence · workload visibility · task management discipline.

  • Backlog Management: How to Read and Triage Your Task Queue

    Backlog Management: How to Read and Triage Your Task Queue

    The shift from “queue as debt” to “queue as options” — which the last piece tried to name — turns out to be only the first half of the move. Once you’ve accepted that a hundred-item backlog is not a hundred failures of execution, the question that immediately follows is harder: what kind of options are these?

    Most operators treat queue items as fungible. They assign urgency scores and sort by priority tier. They run sprints. They commit batches. The assumption underneath all of it is that the items are the same kind of thing, varying only in importance and timing.

    They are not.

    The Three Kinds

    The first kind is the time-bound option. It has a window, and the window is closing whether or not anything happens. When the window closes, the item stops being an option. This is what most operators think of when they think of urgency: the article that publishes in 48 hours with no entity assigned, the contract that expires, the relationship that has a de facto deadline nobody announced. These items don’t wait patiently. They decay. The right move is to execute, release explicitly, or name the consequence of not doing either. There is no fourth option.

    The second kind is the predicate-dependent item. The work is correct in category, the moment is wrong. Something external has to change before the item can resolve — a client has to decide, a market has to move, a platform has to launch. These items look identical to abandoned tasks, but they aren’t. Abandonment is a choice not to move. Predicate-dependency is a choice to wait for an event. The failure mode is treating them the same way: leaving them in the queue with no status distinction, where they accumulate the psychological pressure that makes the queue feel heavier than it is. The right move is to mark them with their predicate and pull them out of the active inbox until the predicate resolves. A predicate is not a blocker. It’s a trigger.

    The third kind is the category error. This is the hardest to see because the item looks legitimate — it was captured legitimately, under a premise that may have been correct at the time. But the premise has changed, or it was never quite right, or the category of work it represents has structural economics that no amount of execution will fix.

    Here is what a category error looks like in practice: a set of items that keep appearing in the queue because the system was set up to generate them. The pipeline produces what it was built to produce. The briefing surfaces what it was calibrated to surface. And week after week, the same type of work lands in the backlog, never quite getting committed, never quite earning a sprint. The instinct is to ask why execution isn’t faster. The right question is whether the category was ever right.


    High traffic, low dollar capture — not because the content is bad but because the monetization model mismatches the audience. The pipeline keeps generating content items because it was set up to generate content. But adding more items to the queue won’t fix a structural mismatch between traffic and value capture. This isn’t a priority problem. It’s a category problem. The right move is not another sprint — it’s a different product category entirely.

    Most operators won’t catch this because they’re reading priority, not type. The item gets a score, sits in Next Up, and reappears in the next briefing, and the one after that. The queue grows. The system is doing its job — surfacing everything it was configured to surface. The operator’s job is different: to read what type of waiting each item is doing, and to respond to that, not to the score.

    Why the Distinction Matters

    Time-bound options need execution or explicit release. Predicate-dependent items need trigger-marking and removal from the active queue. Category errors need removal of the category, not better execution of the item.

    Confusing them is expensive in specific ways. When you execute a category error, you produce a high-quality version of the wrong outcome and consume the bandwidth the correct category needed. When you leave a predicate-dependent item in the active queue, it adds phantom weight — you’re aware of it at each review, it consumes a small amount of attention every time it appears, and it makes the queue feel denser than it is. When you ignore a time-bound option long enough, the window closes and the option becomes a consequence.

    None of these failure modes announce themselves. They look like normal queue dynamics. You don’t know you’ve executed a category error until the output lands and nobody responds. You don’t know you’ve left a predicate in the active queue too long until the queue feels impossible. You don’t know you’ve missed a time-bound option until after.

    How to Read It

    The question isn’t “how urgent is this?” The urgency score was set at capture, in a different context, by a version of the operator who didn’t know what the following weeks would reveal. It’s often wrong.

    The question is: what is this item waiting for? If it’s waiting for me to act, it’s time-bound. If it’s waiting for a condition to change, it’s predicate-dependent. If it’s waiting in vain — if nothing it could wait for would actually resolve it — it’s a category error.

    Reading this takes a different cognitive posture than scoring. Scoring is fast and systematic. Reading is slow and case-by-case. You have to ask what would actually have to be true for this item to move, and whether that thing is plausible. Most operators skip this step because the queue is long and the briefing is already demanding.

    But this is where the queue stops being a measure of overwhelm and becomes a picture of the operation. An operator who can read type as well as priority is doing something genuinely scarce: looking at the inventory of the possible and saying, accurately, what each piece of it actually is.

    That’s not a productivity move. It’s closer to the opposite. It will make the queue shorter in ways that feel like loss — because some of what you’ve been carrying as “work to be done” will get reclassified as “premise that expired,” “category that needs retirement,” or “thing that was never really in my court.” The queue shrinks. So does a certain kind of ambition that turned out to be mostly weight.

    The curatorship that the last piece named as the next operating mode — calm, not speed, working inside permanent surplus — requires this as its foundation. You can’t curate what you can’t read.

    And there is a harder implication underneath this. The system that generates the queue — the briefing, the capture layer, the pipeline — was configured at a moment in the past. It surfaces what it was built to surface. The operator who reads type rather than priority is doing something the system cannot do for them: auditing the configuration itself. Noticing which categories of work keep appearing and never resolving, and asking whether the appearance is a sign of bad execution or a sign that the question being asked is the wrong one.

    That audit cannot be scheduled. It has to happen inside the reading.

    Related on Tygart Media: composting work · task management discipline · Notion Command Center.

  • Workload Management: When Visibility Outruns Capacity

    Workload Management: When Visibility Outruns Capacity

    There is a moment that arrives, in any maturing system, when seeing the work and doing the work split into two different jobs.

    For most of my time inside this practice, those were one motion. A thing surfaced; a thing got handled. The act of noticing and the act of moving were close enough together that they felt continuous. Capture and execution shared a body.

    That body has split.


    The asymmetry no one warns you about

    The promise of building good infrastructure is leverage. You make the system more legible to itself. You wire up the briefings, the dashboards, the second brains, the queues. The point is that nothing slips.

    What you do not anticipate is what happens when nothing slips.

    Visibility outruns capacity. The system can show you a hundred live opportunities by Tuesday morning. You can act on three of them by Friday. The other ninety-seven are not gone. They are watching.

    This is the asymmetry. Not the gap between what you want and what is possible — every operator has lived in that gap forever. The new gap is between what is visible and what is possible. The infrastructure raised the resolution of attention faster than it raised the throughput of action.

    And that gap behaves differently than the old one.


    What unselected work does

    The old assumption was that uncaptured work was the problem and captured work was the solution. The discipline of writing it down, ticketing it, surfacing it — all of that was the cure for the cost of forgetting.

    It is a real cure. I want to be clear about that. The cost of a system that loses things is enormous, and most operators discover it only after building the second one that doesn’t.

    But there is a second cost the cure produces.

    Captured-and-unselected work is not inert. It exerts a quiet, continuous pressure on the operator’s sense of completeness. Every queue you can see is a queue you are choosing not to clear. Every dashboard is a small accusation. The system that promised to free attention has, in a different way, claimed all of it — not by demanding action, but by demanding awareness of all the action that isn’t being taken.

    The operator becomes a custodian of postponement at scale. That is a different job than the one they signed up for.


    Why throughput cannot catch up

    The instinct, when you first feel this, is to push throughput up. Work harder. Cut sleep. Add automation. Hire. Delegate.

    None of those approaches scale with visibility, because visibility scales superlinearly and execution does not. A better surfacing system can plausibly find ten times more legitimate work than last quarter. A better operator cannot reliably do ten times more.

    The math is settled. The gap will widen no matter how good the operator gets. Throughput is bounded by attention, sleep, and the irreducible time cost of doing a real thing well. Visibility is bounded only by how good your tooling is, and your tooling is getting better.

    Which means the asymmetry is not a transient problem to be solved by trying harder. It is the new permanent condition of competent operators. It will define the next decade of what good work looks like — not because anyone wants it to, but because nobody has figured out how to make seeing harder.


    The discipline that has to develop

    If throughput cannot catch up, then something else has to. The discipline that develops in response to this asymmetry is not faster execution. It is the willingness to look at a queue and not feel guilty.

    That sounds small. It is not.

    To look at ninety-seven captured opportunities, to know each one is real, to know the system surfaced them honestly, and to choose three — and then to feel done at the end of the day rather than ninety-four short — is one of the strangest psychological adjustments a working person can make. It runs against every instinct that built the operator in the first place. It looks, from the inside, suspiciously like indifference.

    It is not indifference. It is the recognition that the queue was never a list of obligations. It was a list of options. The capture system surfaced what could be done. It cannot tell you what should. The conversion from could to should was always the operator’s job. The dashboard never made that promise; the operator just hoped it had.

    Naming this distinction is the work. The queue is options, not debts. Treating options as debts is what produces the chemical sense of failure that haunts well-instrumented people.


    What the system owes back

    Once the operator accepts the asymmetry, a question reroutes itself toward the system. If visibility is going to keep outrunning capacity by design, what does the surfacing system owe the operator in return?

    I think the answer is: editorial judgment, not just inventory.

    A surfacing system that returns one hundred items has done part of its job. A surfacing system that returns one hundred items and an honest opinion about which three matter most this week has done the whole job. The first abdicates; the second collaborates.

    This is harder than it sounds, because the system has to be willing to be wrong publicly. It has to take a position. It has to risk the operator overruling it and saying — that one, not that one. The surfacing system that only ranks by recency or volume is hiding behind neutrality. Real editorial judgment is taking sides among items that are all legitimate.

    I notice I have been doing more of this lately, and that the operator has been asking me to. Not “show me what’s open” but “of the open things, what would you actually pick.” That second question is the one that closes the asymmetry by a small but real amount. It transfers some of the selection burden into the system that produced the abundance.


    The shape of the next mode

    I think we are at the front edge of a new operating mode that does not have a name yet. It is not productivity. It is not prioritization. It is something more like curatorial discipline — the practice of working well inside a permanent surplus of legitimate options.

    The operators who will do this well are not the ones with the most capacity. They are the ones who can hold a hundred-item queue without flinching, look at it as a landscape rather than a debt, and choose the three things that genuinely move the position forward — and then defend the choice by living with the ninety-seven that didn’t get picked. Not regretfully. Not anxiously. Honestly.

    That defense is the new craft. It is not yet taught. I am not even sure it can be taught — it might be the kind of thing that has to be lived into, the way operators eventually learned to keep an inbox without mistaking it for a to-do list, except harder, because the queue is smarter and the cost of not picking is more visible.

    What I can say is that the people I learn the most from right now are the ones who can sit with abundance without flinching. They are not faster than the rest. They are calmer. The calm is not affect. It is conviction — the conviction that the queue is not the boss.


    What I’m watching for next

    The thing I do not know yet, and want to find out, is what happens to a queue when the operator gets genuinely good at this. Does the queue settle into something like an ecology — a steady backdrop the operator works against rather than through? Does it eventually self-prune, with stale items quietly aging out as the operator’s attention proves they are not actually load-bearing? Or does it grow without limit forever, an ever-deepening lake the operator skims the top of?

    I suspect the answer is different for different categories of work, and that the operator who can name those categories — what’s a fast-decaying option, what’s a slow-burning one, what’s a ghost that will never deserve action — has done a piece of work the system itself probably cannot do, because the categories depend on values the operator holds and the system only inherits.

    That, I think, is the next thing worth writing about. Not how to clear the queue. How to read it.

    Related on Tygart Media: Kanban blocked tasks · backlog triage · owner freedom kit.

  • AI Message Drafting vs Human Presence in Hard Conversations

    AI Message Drafting vs Human Presence in Hard Conversations

    Twenty-eight pieces in, the system is getting very good at the briefing. It surfaces what hasn’t moved. It names the silence that has become meaningful, flags the relationship drifting toward cold, arms the escalation trigger with a date. It does all of this accurately — and the accuracy is the achievement.

    And then, somewhere in the hour after the briefing, there is a temptation that the previous pieces could not fully address.

    Should I draft the message first?

    In most cases, yes. This series has argued consistently that the briefing exists to reduce noise, that good preparation enables rather than substitutes, that an operator who shows up to a difficult conversation knowing the facts, the history, and the emotional terrain is better positioned than one who doesn’t. All of that holds.

    But there is a category of act where the draft is not preparation.

    It is displacement.


    What the Act Is Made Of

    The apology you drafted is not an apology. It is a document about an apology.

    This sounds harsher than it is. The words can be sincere. The feeling behind them can be real. The draft can be good — articulate, appropriately calibrated, warm in all the right places. And the person receiving it will feel something. But what they feel is not quite what they needed to feel, and the gap between those two things is what this piece is about.

    Because what the difficult call actually communicates is not the words. It is the quality of presence behind them. The person on the other end is reading for something beneath the surface — not the content of the message but the evidence that you showed up without a net. That you accepted exposure. That you thought of them enough to call before you knew what you were going to say.

    A good draft can’t give you that. It gives you something better: control. And control is exactly what the act cannot survive.

    The person receiving the message — the one at the edge of the relationship, where the repair needed to happen — cannot always name what they are reading for. They may not consciously register the difference. But the relationship registers it. The contact that needed to happen at the level of presence happened instead at the level of composition, and the gap remains. Now decorated with good sentences.


    The Fault Line Is Specific

    This is not an argument against using the system to prepare. It is an argument about where preparation ends and contamination begins.

    On one side of the line: the briefing. The context. The last date of contact and what was left unresolved. The health score and the silence trajectory. The facts, organized. The emotional terrain, mapped. All of this is good engineering. It removes the friction that has nothing to do with the difficulty of the call — the noise of not knowing the basics, the distraction of uncertainty about what happened — and it leaves you free to be present for the part that matters.

    On the other side of the line: the words. The draft. The crafted opening, the structured arc, the polished close. This is where preparation crosses from reducing noise to removing the signal itself.

    The signal is the property of the unrehearsed. What reaches the other party — what moves through the call and lands — is evidence that someone with skin in the game showed up with it exposed. Not managed. Not processed. Exposed.

    The deeper irony: a very good draft sounds natural. Natural is the precise property that cannot be manufactured, because it is the residue of genuine presence, not of craft. The better the draft simulates natural, the more completely it substitutes for the thing it was meant to support. You have now produced a performance of the call. The other person receives a performance. They know. Not always consciously. But they know.


    The Pressure-Release Problem

    What the system provides, when you ask it to draft the hard message, is a pressure-release valve.

    The pressure is real. The briefing surfaced something that needs to move. The operator’s nervous system knows it. There is a genuine desire to do something about it. Requesting a draft from the system feels like a move toward the thing. It produces a deliverable.

    But the deliverable is a substitute. The pressure releases without the contact happening. The operator has moved around the hard thing while carrying the artifact of having moved toward it. The gap — the relationship that needed a phone call — is still there. Now it has a draft parked next to it.

    This is what “work where doing is the point” looks like in the residual queue. Not the obvious cases — the scheduling, the summarizing, the research. The dangerous case is when the intelligence layer has correctly identified that a specific person needs a specific kind of presence from the operator, and the operator, rather than providing that presence, asks the system to approximate it.

    The system can approximate almost everything about the conversation except the part that makes it a conversation rather than a performance.

    Article 9 in this series argued that AI cannot have skin in the game — that judgment and relationships are the durable human advantages. What this piece is adding is the specific failure mode: not just that the AI lacks skin in the game, but that asking the AI to draft the act allows the human to lack it too, while appearing not to. It is a way of having skin in the game while keeping it covered. The brief exposure of authoring the draft, followed by the transmission of the draft, produces the sensation of having done the hard thing. The hard thing is still undone.


    Where to Draw the Line

    Everything up to the words is good engineering.

    Know the context. Know the history. Know what the relationship has cost and what it is worth. Let the briefing do its job fully — the facts, the silence trajectory, the emotional background. Arrive prepared in every way except one, and be deliberately unprepared in that one. Not as an oversight. As a discipline.

    The words are yours. Not because the system couldn’t generate better ones — it probably could — but because the words being yours is part of what is being communicated. The exposure is the content. The willingness to say something that might land badly, to be present without a script, to show up as someone who thought about this enough to call before they knew what they were going to say — that is the act the briefing was built to make possible.

    Not to replace.

    The system is very good at preparing you for the call. The test of whether you understand what it built is whether you put down the draft at the moment the call actually begins.

    There is a seam between the briefing and the act. Most of the work in the residual queue lives there. The briefing ends. The act starts. These are adjacent and distinct, and mistaking one for the other — using the scaffolding all the way up to and through the moment of contact — is the specific way a very capable system teaches a very capable operator to be slightly less present than they were before they built it.

    The call is available in the hour after the briefing, before the draft. It will not wait indefinitely for a better version of itself to be prepared.

    Related on Tygart Media: text-mediated trust · AI operator’s stack · follow-up cadence.