Author: Will Tygart

  • Why Claude Articles Get 16,500 Copilot Citations But Roofing Articles Get Zero

    Why Claude Articles Get 16,500 Copilot Citations But Roofing Articles Get Zero

    The Most Lopsided Split I’ve Ever Seen

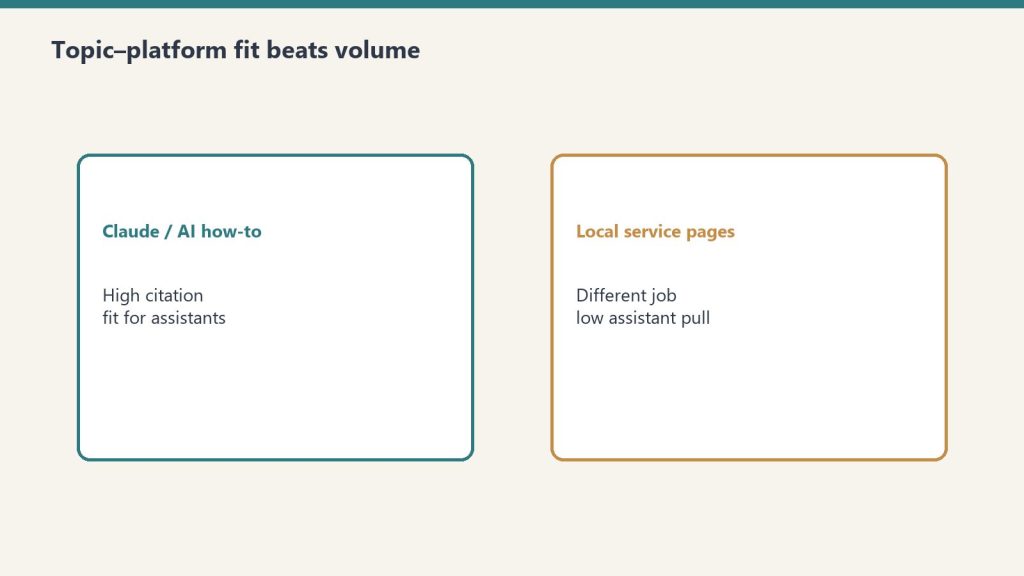
    Comparison of Claude how-to fit versus local service page fit for assistants
    The most lopsided split: topic–platform fit beats volume.

    I run two kinds of content on the same portfolio of sites. One kind covers AI tools — Claude pricing, developer workflows, Copilot integrations, tool comparisons. The other covers trade services — restoration contractors, roofing, water damage, local business directories.

    Both content streams are well-written. Both are SEO-optimized. Both rank on Google. But when I opened Bing Webmaster Tools and looked at the AI Performance tab, the split was so stark it looked like a data error.

    AI tool content: 98,800 citations across 576 grounding queries. The single highest query — “claude ai pricing” — generated 16,500 citations by itself.

    Trade service content: Zero.

    Not ten. Not “a few that I might have missed.” Zero citations. Across every restoration article, every roofing guide, every local service page. Microsoft Copilot did not cite a single one of them.

    This isn’t a quality problem. It’s a topic-platform fit problem. And understanding it changes how you think about content strategy for AI.

    Who Actually Uses Copilot

    To understand why Claude articles dominate and roofing articles get nothing, you need to understand who is on the other end of those Copilot queries.

    Microsoft Copilot is embedded in Microsoft 365 — Word, Excel, PowerPoint, Outlook, Teams, Edge. The users are enterprise workers, knowledge professionals, and business users who invoke AI as part of their daily workflow. They’re writing reports, building presentations, comparing tools, planning purchases, and making decisions.

    When a Copilot user asks a question, it’s because they need information to complete a task they’re currently doing. They’re in Word writing an AI strategy memo and they need current pricing. They’re in Excel building a vendor comparison and they need feature lists. They’re in Edge researching a developer tool and they need a hands-on review.

    These people don’t ask Copilot about roofing contractors. They don’t ask about water damage restoration in Houston. They don’t ask about emergency plumbing services. Because they’re not doing those things at their desk in Microsoft 365.

    The queries that trigger Copilot citations are professional knowledge queries — the questions knowledge workers ask while working:

    “What is claude ai pricing in 2026”
    “Claude code vs cursor comparison”
    “How to set up notion MCP with claude”
    “Anthropic console api key guide”
    “Best AI coding tools for teams”

    Every one of these is a work-context question from someone making a professional decision. And every one of them led Copilot to my content because my content is the most structured, specific, accurate answer available.

    The Topic-Platform Fit Matrix

    Four cards for content, ops, build, and knowledge work with Claude
    Topic–platform fit matrix — write for the assistant that will cite you.

    Based on my citation data and observation across platforms, here’s what I see as the topic-platform fit landscape:

    Microsoft Copilot favors: Technology tool comparisons and pricing. Enterprise software reviews. Developer workflow guides. Business strategy content. AI platform analysis. Integration and configuration documentation. Anything a knowledge worker might need while working in Office.

    Microsoft Copilot ignores: Local services. Trade industries. Consumer products. Event listings. Community content. Anything where the intent is “find a provider near me” rather than “help me understand this tool.”

    ChatGPT favors: Broad technology topics. Health and science information. Financial concepts. Educational content. How-things-work explanations. Creative and cultural topics. Travel planning.

    Google favors: Everything — but especially local intent, shopping intent, transactional queries, and broad informational queries. Google is the generalist.

    Perplexity favors: Current events and news. Technical deep-dives. Product research. Anything where users want a synthesized, multi-source answer to a specific question.

    The pattern is clear: each platform’s topic preferences reflect its user base and use context. Copilot’s users are in the office, so Copilot cites office-relevant content. ChatGPT’s users are everywhere, so ChatGPT cites broadly. Google’s users are searching with intent, so Google rewards intent-matched content.

    Why 16,500 Citations for One Query

    The “claude ai pricing” query generating 16,500 Copilot citations deserves its own analysis because it illustrates topic-platform fit perfectly.

    Think about who asks this question inside Copilot: someone at a company evaluating Claude as a tool for their team. They’re probably in the middle of writing a procurement justification, a budget proposal, or a vendor comparison. They need the current pricing — plans, model costs, API rates — and they need it accurate and structured so they can drop it into their document.

    My Claude AI pricing article has exactly what this person needs: clean pricing tables organized by plan tier, specific model costs with input/output token rates, version-accurate model names, and comparison notes that help with vendor evaluation. The content is formatted for extraction — Copilot can pull a specific number, a specific tier name, a specific comparison point and present it to the user inline.

    That’s why one article earns 16,500 citations while an entire portfolio of roofing content earns zero. The roofing content is excellent for its audience (homeowners with water damage searching Google). But that audience doesn’t exist inside Copilot.

    The Strategic Implications

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Strategic implications — authority clusters compound.

    If you’re a content strategist looking at this data, the implications are significant:

    Not all content is eligible for AI citations. If your business is local services, consumer retail, or any industry where the customer journey starts with a Google search and ends with a phone call, AI citation optimization might not be your priority. Your content serves Google searchers, and that’s fine — that audience is still massive and monetizable.

    If your content serves knowledge workers, you’re sitting on a citation goldmine. SaaS companies, developer tools, B2B services, consulting firms, enterprise technology — any business whose content answers questions that professionals ask while working is perfectly positioned for Copilot citations. And most of them don’t know it yet because they’ve never checked the AI Performance tab.

    Topic-platform fit should drive your content calendar. Instead of asking “what keywords should we target,” start asking “which AI platforms could cite our content, and what does their user base need?” This changes which articles you prioritize, how you structure them, and what success looks like.

    The zero-citation categories will change. As AI platforms expand beyond enterprise knowledge work — as Copilot appears in more consumer contexts, as ChatGPT’s search feature grows, as Google AI Overviews cover more queries — the topic-platform fit map will shift. Local services might start earning AI citations when AI assistants handle “find me a plumber” queries. But right now, the data is unambiguous: Copilot citations concentrate in professional knowledge topics.

    How I Use This Data

    On my own sites, topic-platform fit analysis drives resource allocation. I don’t try to make my restoration content earn Copilot citations — that’s fighting the user base. Instead, I optimize restoration content for Google (where that audience lives) and invest my Copilot-facing content effort in AI tools, business strategy, and technology topics (where the citation audience lives).

    This isn’t about abandoning one audience for another. It’s about matching content to the platform where it will actually be consumed. The same way a B2B SaaS company advertises on LinkedIn instead of TikTok, you should produce AI tool content for Copilot and local service content for Google.

    The data is telling you where your audiences are. The question is whether you’re listening.

    Related on Tygart Media: $0.35 article citations · 98,800 citations · restoration AI search.

    Frequently Asked Questions

    Can local business content earn AI citations?

    Currently, local service content earns very few AI citations because Copilot users are enterprise workers asking professional questions. However, as AI assistants expand into consumer use cases — handling queries like “find me a plumber” or “best restaurants near me” — local content may start earning citations. For now, focus local content on Google SEO and monitor AI citation data for shifts.

    What is topic-platform fit?

    Topic-platform fit describes how well a content topic matches the user base and use context of a specific AI platform. Topics that align with what a platform’s users actually ask about earn citations. Topics that don’t match the user base earn zero citations regardless of content quality.

    Why does Copilot favor technology content so heavily?

    Copilot is embedded in Microsoft 365, so its users are enterprise workers in Office applications. They ask questions related to their work: tool comparisons, pricing, integrations, and business decisions. Technology and business content matches their context. Consumer and local content does not.

    Should SaaS companies prioritize Copilot citations?

    Yes. If your product serves enterprise knowledge workers, your documentation, pricing pages, and comparison content is exactly what Copilot users ask about. Checking your Bing Webmaster Tools AI Performance tab may reveal citation data you did not know existed — and optimizing for it could dramatically expand your content’s reach.

    How do I find my topic-platform fit?

    Start by checking Bing Webmaster Tools AI Performance for your existing Copilot citation data. Then manually test your key topics in ChatGPT, Perplexity, and Claude to see if your content appears in their responses. Map which topics earn citations on which platforms to build your topic-platform fit matrix.

  • How to Use Claude AI: A Beginner’s Guide to Prompting, Features, and Getting Better Results

    How to Use Claude AI: A Beginner’s Guide to Prompting, Features, and Getting Better Results

    Claude AI is powerful, but getting the most out of it requires more than typing a question and hoping for the best. This guide covers the fundamentals — from signing up to writing prompts that produce genuinely useful output — so you can start getting value from Claude immediately, whether you’re using the free tier or a paid plan.

    Getting Started

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Getting started with Claude.

    Go to claude.ai and sign up with your email or Google account. No credit card required for the free tier. Once you’re in, you’ll see a chat interface where you can start a conversation immediately. Claude is available on web, iOS, Android, and a desktop app for macOS and Windows. Your conversations sync across all platforms.

    The Basics of Good Prompting

    Four cards for content, ops, build, and knowledge work with Claude
    The basics of good prompting.

    Be specific about what you want. Instead of “write me something about marketing,” try “write a 500-word blog post about email marketing best practices for small e-commerce businesses, focusing on subject line optimization and send timing.” The more specific your request, the more useful the output.

    Provide context. Claude doesn’t know your situation unless you tell it. Share relevant background: your role, your audience, your constraints, your goals. “I’m a freelance graphic designer preparing a proposal for a client who sells organic skincare” gives Claude much more to work with than “help me write a proposal.”

    Specify the format. Tell Claude how you want the output structured: bullet points, numbered steps, a table, a narrative paragraph, a code snippet. If you want a specific length, say so. If you want a specific tone (formal, casual, technical), specify that too.

    Iterate. Your first prompt rarely produces the perfect result. Treat Claude like a collaborative colleague — give feedback, ask for revisions, and refine. “Make the tone more conversational” or “expand the section about pricing” or “now format this as an email instead of a document.”

    Key Features to Know About

    Projects: Organize related conversations and documents together. Create a Project for each client, each project, or each area of your work. Projects maintain context across conversations, so Claude remembers the background you’ve established.

    Web search: Claude can search the internet in real-time to find current information. When you need up-to-date data, Claude will search, cite sources, and incorporate findings into its response.

    Memory: Claude remembers things you tell it across conversations. If you share your preferences, your role, or your communication style, Claude applies that context in future conversations automatically.

    Code execution: Claude can write and run code in a sandbox. Ask it to analyze data, create charts, process files, or test code snippets. The results are displayed directly in the conversation.

    Extended thinking: For complex problems, Claude can engage in step-by-step reasoning before responding. This produces better results on math problems, logic puzzles, strategic planning, and multi-variable analysis.

    File uploads: You can upload documents, images, spreadsheets, and other files for Claude to analyze. Upload a PDF contract for review, a CSV dataset for analysis, or an image for description.

    Common Use Cases for Beginners

    Writing assistance: Draft emails, blog posts, reports, proposals, social media content. Claude excels at adapting to different tones and formats. Research: Ask Claude to explain complex topics, summarize long documents, or investigate questions across multiple angles. Data analysis: Upload spreadsheets and ask Claude to find patterns, create visualizations, or generate summaries. Learning: Use Claude as a tutor — ask it to explain concepts, quiz you, or create study guides. Coding: Even non-developers can use Claude to write scripts, automate tasks, or build simple tools.

    Mistakes to Avoid

    Seven cards naming common AI chatbot failure modes
    Mistakes to avoid as a beginner.

    Don’t assume Claude’s output is always correct — verify important facts, especially numbers, dates, and claims about specific companies or people. Don’t share sensitive personal information unnecessarily. Don’t treat Claude’s first response as final — iterate and refine. Don’t write vague prompts and expect specific results. Don’t ignore Claude’s caveats and limitations when it flags uncertainty.

    Related on Tygart Media: how to use Claude · Claude for business · is Claude free.

    Frequently Asked Questions

    How do I start using Claude AI?

    Go to claude.ai, sign up for free, and start chatting. No credit card or technical setup required. Download the desktop app from claude.com/download for additional features.

    What should I ask Claude AI?

    Anything you’d ask a knowledgeable assistant: writing help, research, analysis, coding, brainstorming, summarization, explanation of complex topics, or task planning. Be specific about what you need.

    How do I write a good prompt for Claude?

    Be specific about your request, provide relevant context, specify the format and length you want, and iterate on the results. The more detail you give, the better the output.

    Is Claude AI better than ChatGPT for beginners?

    Both are capable tools with similar pricing ($0 free, $20/month paid). Claude is often praised for longer, more nuanced responses and better instruction-following. The best approach is to try both and see which fits your workflow.

  • Claude AI for Business: Real ROI & Workflows (2026)

    Claude AI for Business: Real ROI & Workflows (2026)

    Claude AI has moved from experimental tool to operational infrastructure for businesses of all sizes. But the question most decision-makers ask isn’t “what can it do?” — it’s “what’s the return?” This guide covers the concrete use cases where businesses are deploying Claude in 2026, a framework for calculating ROI, and real data from published case studies.

    Engineering and Development

    Four cards for content, ops, build, and knowledge work with Claude
    Engineering and development use cases.

    Claude Code has become the primary productivity lever for engineering teams. Published case studies show 20-40% improvements in code velocity when teams adopt Claude Code systematically. The tool handles code review, test generation, debugging, documentation, and multi-file refactoring. Companies like Rakuten, TELUS, and Harvard have publicly shared their Claude Code adoption data. The key insight from rollout data: teams that establish clear workflows (plan mode, hooks, managed settings) see sustained adoption, while ad hoc usage tends to fade after the initial novelty.

    Content and Marketing

    Three cards for LSA, search ads, and SEO/AI authority channels
    Content and marketing workflows.

    Marketing teams use Claude for content production at scale — blog posts, product descriptions, email campaigns, social media content, and SEO optimization. The ROI here is straightforward: if a content writer produces 3 articles per day without Claude and 8 with Claude, the per-article cost drops significantly. Claude for Microsoft 365 integration means teams can use Claude directly within Word and Outlook without switching contexts.

    Sales and Customer Support

    Sales teams use Claude for prospect research, call preparation, proposal drafting, and competitive analysis. Customer support teams deploy Claude through the API to handle first-line inquiries, draft responses for human review, and summarize long ticket histories. The combination of Claude’s natural language understanding and tool use (via MCP) means it can pull CRM data, check order status, and draft personalized responses in a single flow.

    Legal and Compliance

    Legal teams use Claude for contract review, regulatory research, and compliance documentation. Claude’s 1M token context window allows it to process entire contracts or regulatory documents in a single request. Enterprise features like audit logs, HIPAA readiness, and custom data retention make it viable for regulated industries. Law firms and legal departments report significant time savings on document review and research tasks.

    Operations and Internal Productivity

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Operations and internal productivity.

    Beyond specialized functions, Claude serves as a general productivity multiplier. Teams use it for meeting preparation, report drafting, data analysis, process documentation, and internal communication. Cowork mode in the desktop app can automate cross-application workflows — moving data between tools, generating reports from multiple sources, and handling repetitive administrative tasks.

    ROI Calculation Framework

    Calculate Claude’s ROI for your organization with this framework. Time savings: estimate hours saved per employee per week. Multiply by the employee’s fully-loaded hourly cost. Quality improvements: reduced error rates in code, content, or customer communications. Speed to market: faster project completion times. Tool consolidation: Claude may replace or reduce spending on multiple SaaS tools (writing assistants, code review tools, research platforms). Total cost: subscription cost ($20-200/seat/month) plus any API usage. The break-even point for most teams is 2-3 hours of productivity gained per seat per month.

    Choosing the Right Plan for Business

    Small teams (5-20 people): Team Standard at $20/seat/month (annual). Growing companies (20-150): Team with a mix of Standard and Premium seats. Large organizations (150+): Enterprise with seat-plus-usage pricing. The decision matrix comes down to three factors: team size, security/compliance requirements, and power-user density.

    Related on Tygart Media: Claude for content · how to use Claude · is Claude worth it.

    Frequently Asked Questions

    How much does Claude cost for a business?

    Team plans start at $20/seat/month (annual billing) for Standard seats. Enterprise starts at $20/seat plus usage. A 20-person team on Team Standard costs $400/month or $4,800/year.

    What is the ROI of Claude AI for businesses?

    Most teams break even with 2-3 hours of productivity gain per seat per month. Published engineering case studies show 20-40% code velocity improvements. Content teams report 2-3x output increases.

    Is Claude AI secure enough for enterprise use?

    Yes. Enterprise includes SSO, SCIM, audit logs, compliance API, HIPAA readiness, custom data retention, and IP allowlisting. Content is not used for model training.

    Can Claude replace our existing AI tools?

    Claude can consolidate multiple point solutions — writing assistants, code review tools, research platforms, and customer support drafting tools — into a single platform, potentially reducing overall tool costs.

  • Anthropic API Getting Started: Your First API Call, SDKs, and Developer Quickstart Guide

    Anthropic API Getting Started: Your First API Call, SDKs, and Developer Quickstart Guide

    The Anthropic API gives developers programmatic access to Claude — the same models that power claude.ai, but accessible through HTTP requests or official SDKs. Whether you’re building a chatbot, automating document processing, or integrating AI into an existing application, this guide gets you from zero to your first API call in under 10 minutes.

    Step 1: Create an Anthropic Account

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Step 1: create the Anthropic account before you chase SDKs.

    Go to platform.claude.com and sign up. This is the developer console — separate from claude.ai. You’ll need a valid email address. After email verification, you’ll land on the console dashboard where you can generate API keys and manage billing.

    Step 2: Add Billing and Get Your API Key

    Five-step path: account, API keys, billing, usage, workspaces
    Step 2: billing and API key path.

    Navigate to the billing section and add a payment method. Anthropic uses a prepaid credit system — load funds and API calls draw from your balance. Once billing is set up, go to the API Keys section and click “Create Key.” Name the key descriptively (e.g., “my-first-project-dev”) and copy the key immediately — it starts with “sk-ant-” and won’t be shown again. Store it securely: in an environment variable, a secrets manager, or a .env file that’s in your .gitignore.

    Step 3: Install an SDK

    Anthropic provides official SDKs for Python and TypeScript. For Python: pip install anthropic. For TypeScript/JavaScript: npm install @anthropic-ai/sdk. Both SDKs handle authentication, request formatting, streaming, error handling, and retries. You can also use the raw HTTP API directly with any language that supports HTTP requests.

    Step 4: Make Your First API Call

    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits
    First API call — then watch rate limits and usage.

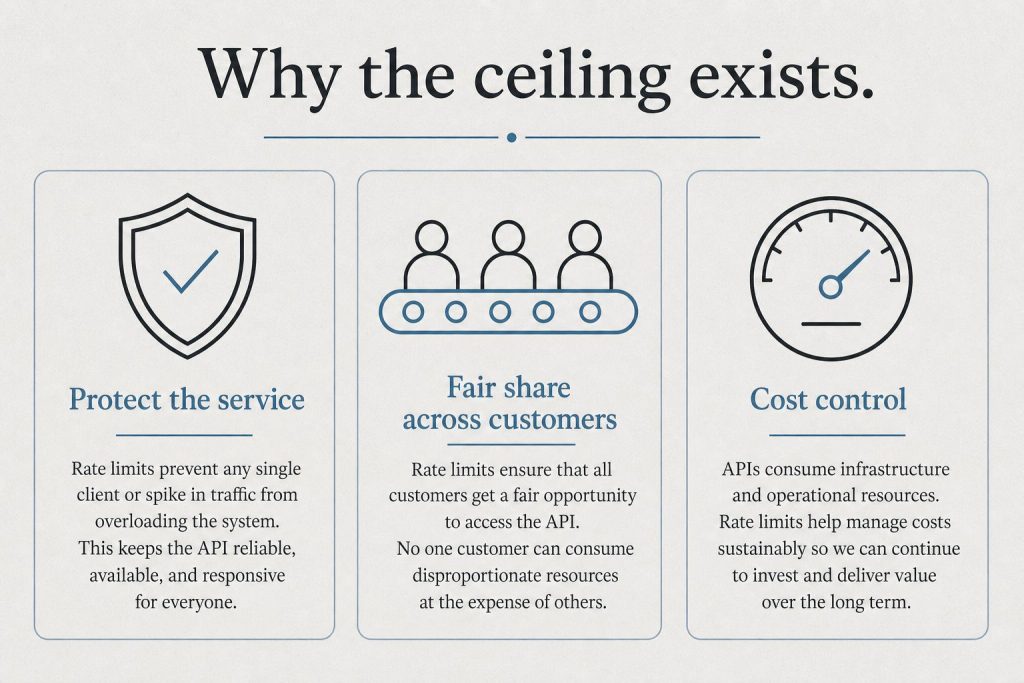
    In Python, set your API key as an environment variable: export ANTHROPIC_API_KEY="sk-ant-your-key-here". Then write a simple script. Import the Anthropic client, create a message with the model name (e.g., “claude-sonnet-4-6”), specify the max tokens for the response, and pass your prompt. The response includes the generated text, token usage counts, and metadata about the request.

    The API endpoint is Messages — you send a list of messages (with roles “user” and “assistant”) and Claude responds. System prompts are set separately to establish Claude’s behavior for the conversation. Each request is stateless — you manage conversation history by including previous messages in each request.

    Available Models

    The current production models and their API identifiers: claude-opus-4-6 (Opus 4.8 is the latest, but check the docs for exact model strings), claude-sonnet-4-6, and claude-haiku-4-5-20251001. Each model has different strengths. Opus is the most capable for complex reasoning and coding. Sonnet balances capability and cost. Haiku is the fastest and cheapest for high-volume, simpler tasks.

    Key API Features

    Streaming: Get responses token-by-token as they’re generated, reducing perceived latency. Tool use (function calling): Define functions that Claude can invoke to interact with external systems — databases, APIs, calculators. Vision: Send images along with text for multimodal analysis. Extended thinking: Enable Claude’s step-by-step reasoning for complex problems. Prompt caching: Cache system prompts and frequently-used context to reduce costs by up to 90%. Batch API: Submit multiple requests for asynchronous processing at 50% off.

    Alternative Access Points

    Beyond the direct Anthropic API, you can access Claude through Amazon Bedrock (AWS), Google Cloud Vertex AI, Microsoft Azure through Foundry, and third-party routers like OpenRouter. Each platform has its own authentication, pricing adjustments, and additional features. The direct API gives you the most control and typically the lowest latency.

    Related on Tygart Media: Anthropic Console · Message Batches API · how to use Claude.

    Frequently Asked Questions

    How do I get an Anthropic API key?

    Sign up at platform.claude.com, add billing, then go to API Keys and click Create Key. The key starts with “sk-ant-” and should be stored securely.

    Is the Anthropic API free?

    There is no permanent free tier. You pay per token used. Pricing starts at $1/MTok input for Haiku 4.5.

    Which SDK should I use?

    Python (pip install anthropic) or TypeScript (npm install @anthropic-ai/sdk). Both are officially maintained by Anthropic with the same feature set.

    Can I use Claude API with other programming languages?

    Yes. The API is standard HTTP with JSON payloads. Any language that can make HTTP requests can call the Anthropic API directly without an SDK.

  • Claude Desktop App: Features, Setup, Tips, and What Makes It Different From Claude.ai

    Claude Desktop App: Features, Setup, Tips, and What Makes It Different From Claude.ai

    The Claude desktop app is a native application for macOS and Windows that goes beyond what the web interface at claude.ai offers. While claude.ai gives you chat, the desktop app unlocks Claude Code (a terminal-based coding agent), Claude Cowork (desktop automation), local file access, MCP server connections, and deeper system integration. Here’s everything you need to know to get started and get the most out of it.

    How to Download and Install

    Five-step path: account, API keys, billing, usage, workspaces
    How to download and install the desktop app.

    Download the Claude desktop app from claude.com/download. It’s available for macOS (Apple Silicon and Intel) and Windows. Installation is straightforward — run the installer and sign in with your Claude account. The app requires a Free, Pro, Max, Team, or Enterprise account. On macOS, the app supports both the standard installation and Homebrew. On Windows, the installer handles everything including system tray integration.

    What the Desktop App Adds Over Claude.ai

    Three stacked layers: chat UI, tools, agent runtime
    What the desktop app adds over Claude.ai.

    Claude Code: The terminal-based coding agent that can read your local codebase, make changes, run tests, and handle complex multi-file development tasks. Claude Code operates from your terminal with full access to your development environment — git, npm, pip, docker, and any other tools you have installed. It’s available to Pro, Max, Team, and Enterprise users.

    Claude Cowork: Desktop automation mode where Claude can control your computer to accomplish tasks. Cowork can interact with applications on your screen, manage files, run scripts, and automate workflows that span multiple programs. It works within a secure sandbox with explicit permission controls.

    Local file access: The desktop app can read and write files on your computer, which the web interface cannot do. This enables direct document editing, local data analysis, and file management tasks.

    MCP server connections: The Model Context Protocol lets Claude connect to external tools and data sources — databases, APIs, project management tools, and more. The desktop app can run MCP servers locally, giving Claude access to your development stack.

    Desktop extensions: Additional capabilities that extend Claude’s ability to interact with your local environment, available across all tiers including Free.

    Key Features Available on All Plans

    Even on the Free plan, the desktop app provides a native experience that’s faster and more responsive than the browser. You get keyboard shortcuts for common actions, system tray/menu bar access for quick invocation, offline access to your conversation history, and native notifications. The app syncs with your claude.ai account — conversations, Projects, and memory are shared between web and desktop.

    Tips for Power Users

    Use keyboard shortcuts to invoke Claude quickly without switching contexts. Set up MCP servers for your most-used tools to give Claude direct access instead of copy-pasting. Organize work into Projects — each Project maintains its own context, documents, and conversation history. Use Cowork mode for repetitive desktop tasks that span multiple applications. When using Claude Code, commit your work frequently — Claude Code operates in your real file system, not a sandbox.

    Desktop App vs Claude.ai: When to Use Each

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    When to use desktop vs Claude.ai.

    Use the desktop app when you need file system access, Claude Code, Cowork, or MCP connections. Use claude.ai when you’re on a device where the app isn’t installed, when you want quick access from a browser, or when you’re using a shared/public computer. Both interfaces access the same underlying Claude models and share your account data. Many users keep both available — the desktop app for deep work and the web interface for quick tasks.

    Related on Tygart Media: Claude Cowork · how to use Claude.

    Frequently Asked Questions

    Is the Claude desktop app free?

    The app itself is free to download and use. It works with all Claude plans including the Free tier. Claude Code and Cowork features require a Pro subscription or higher.

    Does Claude desktop work on Linux?

    As of June 2026, the Claude desktop app is available for macOS and Windows. Linux users can access Claude through the web interface at claude.ai or use Claude Code via the command-line installer.

    Can the desktop app access my files?

    Yes, with your permission. The desktop app can read and write local files, which is one of its key advantages over the web interface. File access is controlled through explicit permissions.

    Do my conversations sync between desktop and web?

    Yes. Conversations, Projects, and memory sync across the desktop app and claude.ai automatically.

  • Claude Pricing Tiers: Free vs Pro vs Team vs Enterprise

    Claude Pricing Tiers: Free vs Pro vs Team vs Enterprise

    Official links: Buy or compare plans (claude.com) · Sign up (claude.ai) · Billing help center

    For every plan in one place, see the full Claude pricing overview.

    Direct Answer · 8 October 2026: Free is for casual exploration. Pro ($20/mo, or $17 billed annually) offers more usage plus Claude Code. Max 5x/20x ($100–$200/mo) is 5x or 20x Pro usage. Team Standard is $20 annual / $25 monthly per seat; Team Premium is $100 annual / $125 monthly. Enterprise is $20/seat plus usage at API rates. Seat prices did not move. Haiku 5.5 API list is $0.10 / $0.50 under 100k prompt tokens ($0.50 / $2.50 over). Sonnet 5.5 API list is $2 / $10 (Sonnet 5, at the same price, is superseded by 5.5); Sonnet 5.5 cache reads are now $0.10. Opus 5.5 is $4 / $20 with cache reads at $0.20. Fable 5.1 cache reads are $0.25/MTok.

    Claude has five pricing tiers as of October 2026. The differences between them aren’t always obvious from Anthropic’s own pricing page. This guide breaks down every tier side-by-side — what each costs, what changes as you move up, and exactly where the value breaks are. Last refreshed: October 8, 2026 (Pacific) against claude.com/pricing and platform.claude.com pricing.

    Claude Pricing at a Glance (October 2026)

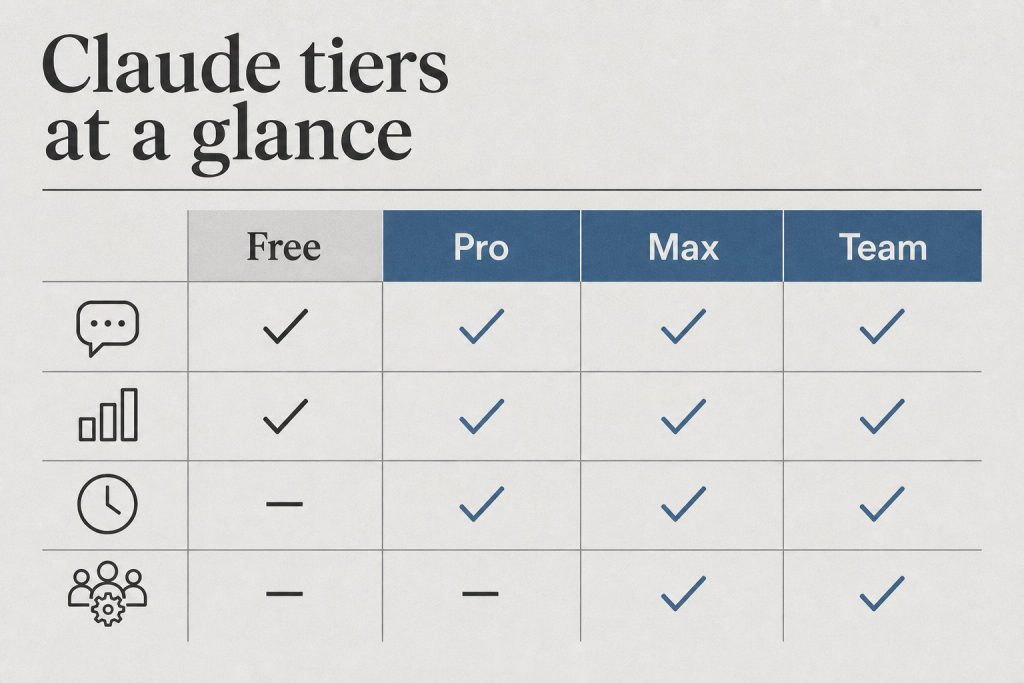
    At-a-glance board comparing Free, Pro, Max, and Team Claude tiers by chat, limits, priority, and admin controls
    Same ladder, shorter page. Confirm live limits before you upgrade.
    Plan Monthly Price Annual Price Best For
    Free $0 $0 Trying Claude, light use
    Pro $20/month $17/month ($200/yr) Daily professional use
    Max 5x $100/month $100/month Power users hitting Pro limits
    Max 20x $200/month $200/month Developers, heavy Claude Code users
    Team Standard $25/seat $20/seat Teams of 2+ (SSO, admin)
    Team Premium $125/seat $100/seat Teams with heavy usage needs
    Enterprise $20/seat + usage Annual only Scale, HIPAA, compliance

    Feature Comparison: What Changes at Each Tier

    Feature Free Pro Max Team Enterprise
    Chat (web, mobile, desktop) ✓ ✓ ✓ ✓ ✓
    Web search ✓ ✓ ✓ ✓ ✓
    Memory ✓ ✓ ✓ ✓ ✓
    Code execution & file creation ✓ ✓ ✓ ✓ ✓
    Claude Code — ✓ ✓ ✓ ✓
    Claude Cowork / Design, Slides, Docs — ✓ ✓ ✓ ✓
    Unlimited Projects — ✓ ✓ ✓ ✓
    Research mode — ✓ ✓ ✓ ✓
    Claude for Microsoft 365 — ✓ ✓ ✓ ✓
    5x or 20x usage vs Pro — — ✓ — —
    Higher output limits — — ✓ — —
    Early feature access — — ✓ — —
    Priority access — — ✓ Premium only ✓
    SSO & domain capture — — — ✓ ✓
    Central billing & admin — — — ✓ ✓
    No training on your data Opt-out Opt-out Opt-out Default off Default off
    SCIM provisioning — — — — ✓
    Audit logs — — — — ✓
    HIPAA-ready — — — — ✓
    Compliance API — — — — ✓
    Custom data retention — — — — ✓

    The Real Decision Points

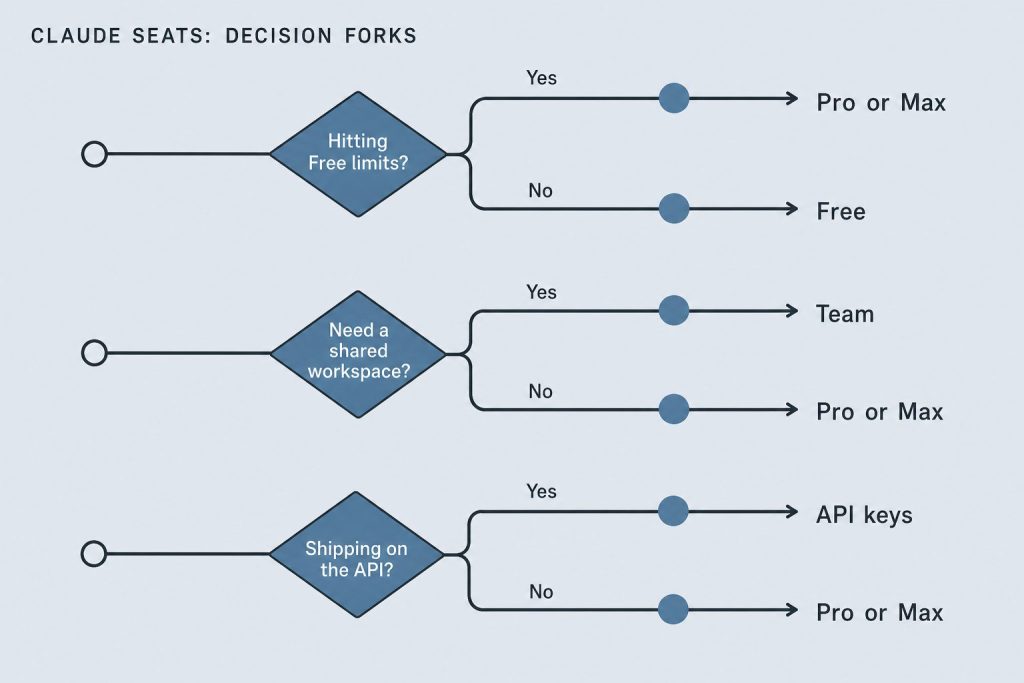
    Decision diagram: hitting Free limits, needing a shared workspace, or shipping on the API
    Upgrade when a constraint is real — not when a plan page is pretty.

    Free → Pro ($20/month)

    If you hit Claude’s usage limits more than once a week, Pro pays for itself. The clearest signals you need Pro: you’re getting rate-limited mid-conversation, you want Claude Code in the terminal, or you use Projects to organize your work. At $20/month ($17 annual), it’s also the most common upgrade path. If you don’t hit limits regularly, stay on Free.

    Pro → Max ($100–$200/month)

    Max 5x ($100/month) gives you 5x Pro’s usage capacity plus higher output limits and early feature access. Max 20x ($200/month) gives you 20x. The honest answer: most daily Pro users never need Max. If you finish most days without hitting Pro limits, Max is not the right upgrade. Max plans now include monthly API credits — $100/month on Max 5x, $200/month on Max 20x, listed on claude.com/pricing. That is a Platform credit, not extra chat usage.

    Individual → Team ($20–$125/seat)

    Team Standard at $20/seat/month (annual) costs the same as Pro per person — you’re getting Pro capabilities plus SSO, admin controls, central billing, and no-training-by-default for the same price per seat. Team Premium at $100/seat/month (annual) / $125 monthly includes 5x Standard usage. Official claude.com copy: Standard seats give more than Pro; Premium seats give 5x more than Standard.

    Team → Enterprise ($20/seat + usage)

    Enterprise makes sense when you need SCIM, audit logs, HIPAA, or a custom MSA. Official claude.com copy: $20 per seat per month plus usage billed at API rates, billed annually.

    Annual vs Monthly Billing

    Annual billing saves 15–20% across Pro and Team:

    Plan Monthly Annual (per month) Savings
    Pro $20 $17 15%
    Team Standard $25/seat $20/seat 20%
    Team Premium $125/seat $100/seat 20%

    Anthropic’s Max help article says Max is currently monthly-only on the web checkout. No annual discount is listed for Max 5x or Max 20x.

    Claude API Pricing (Developers)

    The API is separate from subscription plans. You pay per million tokens (MTok) processed. Source: platform.claude.com pricing and Haiku 5.5, checked October 12, 2026.

    Model Input Output 5m Cache Write Cache Read
    Claude Fable 5.1 / Mythos 5.1 $10/MTok $50/MTok $12.50/MTok $0.25/MTok
    Claude Opus 5.5 $4/MTok $20/MTok $5/MTok $0.20/MTok
    Claude Opus 5 / 4.8 $5/MTok $25/MTok $6.25/MTok $0.50/MTok
    Claude Sonnet 5.5 $2/MTok $10/MTok $2.50/MTok $0.10/MTok
    Claude Sonnet 5 $2/MTok $10/MTok $2.50/MTok $0.20/MTok
    Claude Sonnet 4.6 / 4.5 $3/MTok $15/MTok $3.75/MTok $0.30/MTok
    Claude Haiku 5.5 (≤100k / >100k) $0.10 / $0.50 $0.50 / $2.50 $0.125 / $0.625 $0.01 / $0.05
    Claude Haiku 4.5 $1/MTok $5/MTok $1.25/MTok $0.10/MTok

    Do not average the two Haiku 5.5 bands. Sonnet 5.5 cache reads moved from $0.20 to $0.10 on October 7. Sonnet 5 cache reads stay $0.20. Opus 5.5 cache hits stay $0.20. Fable 5.1 cache hits stay $0.25.

    Batch API: 50% off all models for non-time-sensitive workloads. Haiku 5.5 batch is $0.05 / $0.25 under 100k. For a full developer cost breakdown, see Claude API token rates.

    How Claude Pricing Compares to ChatGPT Plus

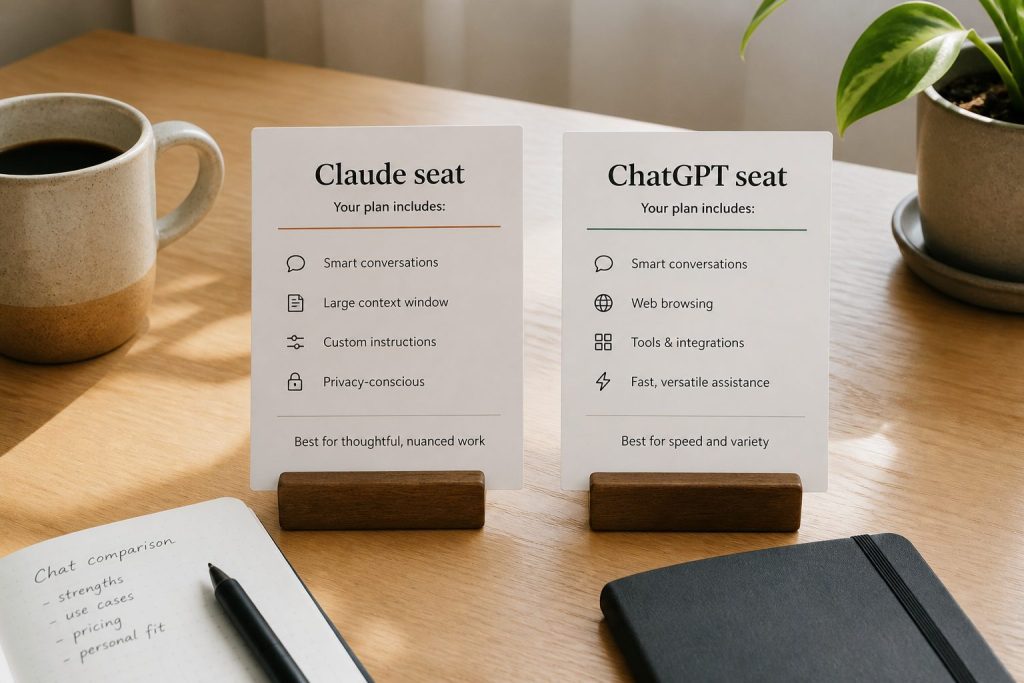
    Two subscription cards on a desk labeled Claude seat and ChatGPT seat for side-by-side comparison
    Chat seats compete. API meters are a different product.

    At the individual level, Claude Pro and ChatGPT Plus are both $20/month — the same monthly price. Claude Pro includes an annual option at $17/month ($200 billed up front).

    Who Should NOT Upgrade

    Stay on Free if you rarely hit limits. Stay on Pro instead of Max if you finish most days without a rate-limit message. Stay on Team instead of Enterprise if you do not need SCIM, audit logs, HIPAA, or custom retention.

    Frequently Asked Questions

    Is Claude free to use?
    Yes. The Free plan is $0. It does not include Claude Code.

    How much does Claude Pro cost?
    $20/month billed monthly, or $17/month ($200/year) billed annually.

    What is Claude Max?
    Max 5x is $100/month. Max 20x is $200/month. Both are billed monthly on the web checkout.

    Which Claude plan is best for a solo professional?
    Pro at $20/month ($17 annual) for most people. Max only if you hit Pro limits on a daily basis.

    Part of the complete guide: Claude Pricing, Plans & Limits

  • Claude Enterprise Pricing & Procurement Guide (2026)

    Claude Enterprise Pricing & Procurement Guide (2026)

    Claude Enterprise pricing works differently from the individual and Team plans. Instead of a fixed per-seat fee that includes unlimited usage, Enterprise charges a base seat cost of $20/seat with additional usage billed at API rates. This model gives large organizations more flexibility but requires understanding how usage translates to cost. Here’s the complete breakdown for decision-makers evaluating Claude Enterprise in 2026.

    Last refreshed: October 5, 2026 (Pacific)

    Direct Answer (October 2026): Claude Enterprise pricing starts at ~$20/user/month for identity access (SSO/SCIM/Audit Logs) with token consumption billed at standard API rates — now spanning Sonnet 5.5 and Opus 5.5 as the current models, alongside legacy Opus 4.8 and Sonnet 4.6. Total monthly spend averages $60–$250/active user based on model selection and prompt caching adoption.

    How Enterprise Pricing Works

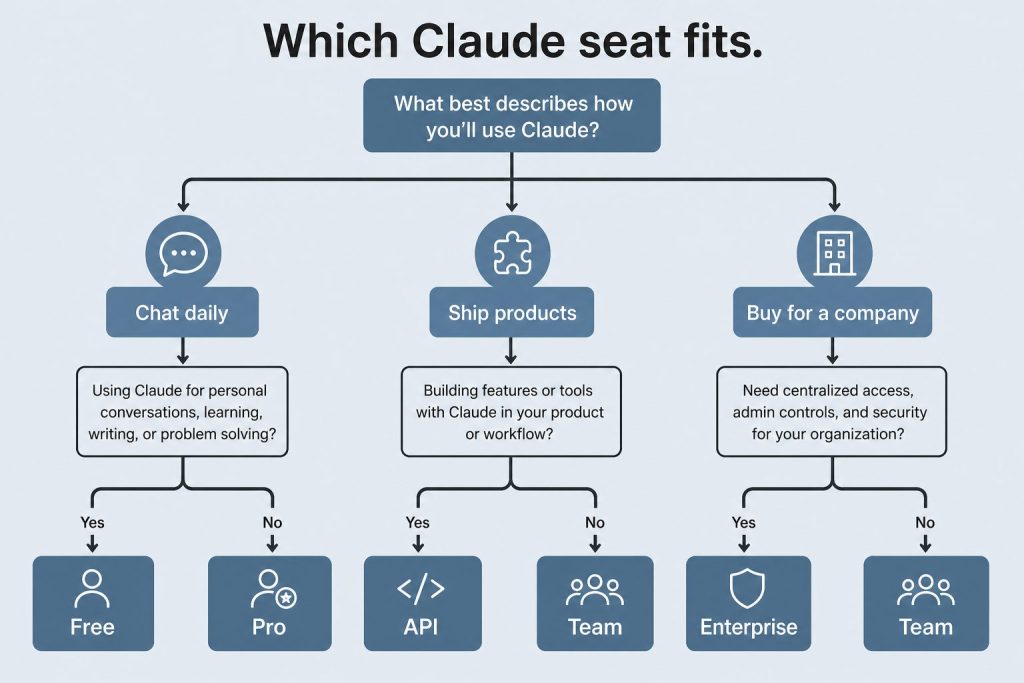
    Decision map from daily chat, shipping products, or buying for a company to Free/Pro, API, or Team/Enterprise
    How Claude Enterprise pricing works — recheck this breakdown whenever Anthropic changes seat fees or API rates (last verified October 2026).

    The pricing structure has two components. First, a per-seat fee of $20/month per user. This covers access to the Claude interface and all Enterprise features. Second, usage-based charges at API rates that scale with which model each user interacts with and how much they use it. When an Enterprise user chats with Claude, token costs follow current API rates. Sonnet 5.5 (Anthropic’s current mid-tier model) is priced at $2/MTok input and $10/MTok output, and Opus 5.5 (the current flagship) at $4/$20. Legacy models remain available at their existing rates: Opus 4.8 at $5/$25 and Sonnet 4.6 at $3/$15. Haiku 4.5 stays at $1/$5.

    This means actual costs per user vary significantly. A light user who sends a few messages per day might cost $20-30/month total. A power user running Claude Code and extended research sessions could cost $150-500+/month. Administrators can set per-user and organizational spending limits to maintain budget predictability.

    Two Paths to Enterprise

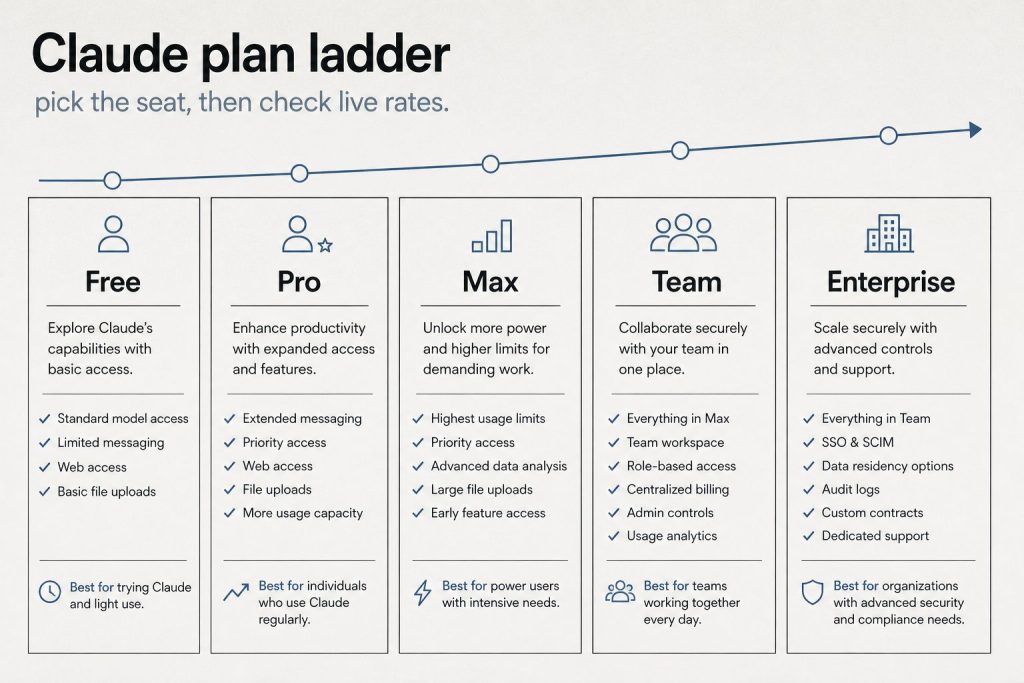
    Infographic ladder of Claude plans: Free, Pro, Max, Team, and Enterprise
    Two paths to Enterprise.

    Anthropic now offers two ways to get on the Enterprise plan. The self-serve path lets organizations sign up directly at claude.ai/create/enterprise without contacting sales. This is designed for teams that want enterprise security features but want to move fast. You get SSO, domain verification, central billing, admin controls, usage analytics, and the ability to add seats on demand. The sales-assisted path is for organizations that need custom contracts, MSAs, purchase orders, usage commitments, tiered incentives on committed spend, non-standard terms, trials, or consultation. Contact sales through claude.com/contact-sales.

    Enterprise-Only Features

    Enterprise includes everything in the Team plan plus several capabilities only available at this tier. Admin-set spend limits let administrators control costs at both user and organization levels. Role-based access with fine-grained permissioning controls who can access what. SCIM (System for Cross-domain Identity Management) automates user provisioning and deprovisioning. Audit logs provide detailed records of user activity. Compliance API enables observability and monitoring. Custom data retention controls let you set how long data is stored. Network-level access control and IP allowlisting restrict where Claude can be accessed from. HIPAA-ready offering is available for healthcare and regulated industries. Claude Security (currently in beta) provides AI-powered vulnerability scanning.

    Enterprise vs Team: When to Upgrade

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Enterprise vs Team — when to upgrade.

    The Team plan caps at 150 users and uses fixed per-seat pricing ($20-125/seat depending on seat type). Enterprise has no user cap and uses the seat-plus-usage model. Upgrade to Enterprise when you need more than 150 seats, when you require SCIM for automated provisioning, when compliance requirements demand audit logs and a compliance API, when you need custom data retention or HIPAA readiness, or when the usage-based model would actually cost less than Team Premium seats for your usage patterns.

    Current Enterprise Promotion

    As of June 2026, Anthropic ran a promotion offering $1,000 in Claude Code and Claude Cowork credits for every Enterprise seat activated by July 2, 2026 — that window has since closed.

    Evaluating Enterprise ROI

    To evaluate whether Claude Enterprise justifies the cost, consider time savings per employee (if each user saves 5 hours/week at $50/hour effective cost, that’s $1,000/month in productivity per person), reduction in tool sprawl (replacing multiple SaaS subscriptions), code velocity improvements (engineering teams using Claude Code report 20-40% productivity gains in published case studies), and compliance cost avoidance (audit logs, SCIM, and HIPAA readiness may replace other compliance tools).

    Frequently Asked Questions

    How much does Claude Enterprise cost per user?

    $20/seat/month base plus usage at API rates. Actual per-user costs depend on usage — light users might total $25-30/month, while heavy users could reach $200+/month.

    Can I start Claude Enterprise without talking to sales?

    Yes. Anthropic offers a self-serve Enterprise option at claude.ai/create/enterprise. You can sign up, add seats, and start using Enterprise features immediately.

    Is Claude Enterprise HIPAA compliant?

    Anthropic offers a HIPAA-ready Enterprise option. Organizations in healthcare and regulated industries should contact sales to discuss specific compliance requirements and BAA arrangements.

    What is the minimum number of seats for Enterprise?

    There is no publicly stated minimum seat count for the self-serve Enterprise option. The sales-assisted path may have minimum commitments depending on the contract terms.


    Related: Claude AI Pricing (2026) — every plan, API rate, and the cost calculator

    💼 Deploying Claude or AI Infrastructure in Your Business?

    At Tygart Media, we engineer custom Model Context Protocol (MCP) servers, multi-model content pipelines, and AI operational systems. Explore our Claude AI Team Implementation Services or check out our complete Restoration Operations & AI Kit.

  • The SEO vs GEO vs AEO Debate Is Already Over — Here’s What Comes Next

    The SEO vs GEO vs AEO Debate Is Already Over — Here’s What Comes Next

    An Argument With No Winner

    Open any marketing subreddit, LinkedIn thread, or industry conference agenda right now and you’ll find the same debate: SEO vs GEO vs AEO. Search Engine Optimization vs Generative Engine Optimization vs Answer Engine Optimization. Which framework should guide your content strategy? Which one is “the future”?

    I’ve been watching this debate for months while sitting on a dataset that makes the entire argument irrelevant. The data comes from Bing Webmaster Tools AI Performance tab — 98,800 Microsoft Copilot citations across 576 grounding queries from a single domain. And what it shows is that the SEO/GEO/AEO framework is the wrong level of abstraction.

    The right question isn’t “which optimization approach wins.” It’s “which AI platform are you optimizing for, and what does its specific user base need?”

    Why the Old Categories Are Collapsing

    SEO versus GEO comparison showing collapsing old categories
    SEO vs GEO vs AEO — the old categories are collapsing.

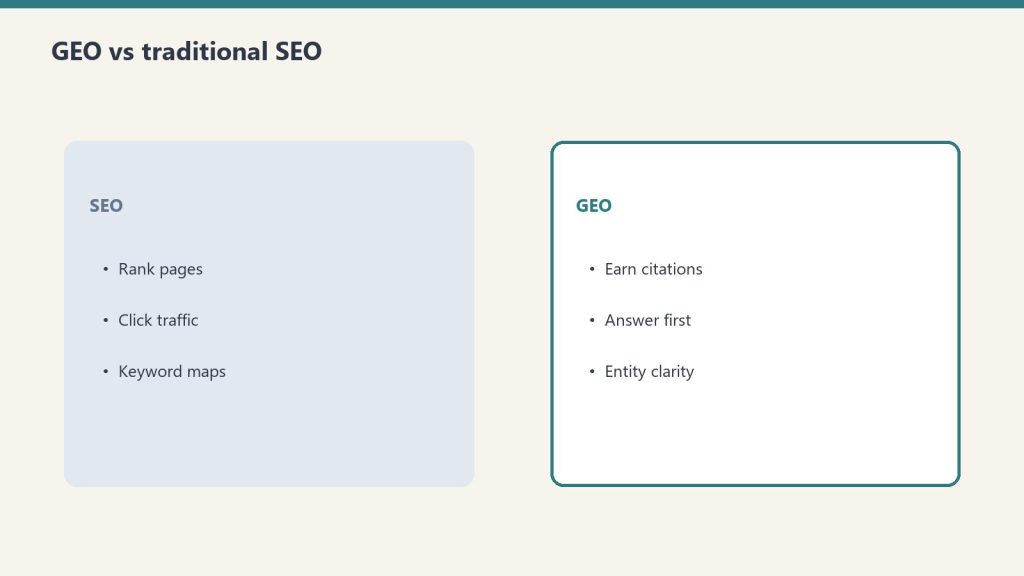
    SEO was built for Google. It assumes a user types keywords, receives a ranked list of links, and clicks through to a website. The metrics are rankings, clicks, and conversions. This model still works for Google — but Google is no longer the only discovery engine that matters.

    GEO emerged to address generative AI — the idea that your content needs to be optimized so that AI engines cite and reference it. But GEO treats “AI” as a single category. It assumes what works for ChatGPT also works for Copilot, Perplexity, Gemini, and Claude. My data says that’s wrong.

    AEO focuses on structuring content for direct answers — featured snippets, People Also Ask boxes, voice search. It’s a useful tactical framework, but it was designed for Google’s answer features, not for AI platforms that consume and reprocess content in fundamentally different ways.

    Each of these frameworks captures part of the picture. None captures the whole thing. And the gap between them is where the actual opportunity lives.

    The Data That Breaks the Framework

    Comparison of Claude how-to fit versus local service page fit for assistants
    The data that breaks the single-framework argument.

    Here’s what 98,800 Copilot citations taught me about why the SEO/GEO/AEO categories don’t hold:

    Topic-platform mismatch is real. My AI tool content generates thousands of daily Copilot citations. My local business content — which has strong Google SEO performance — generates zero Copilot citations. GEO theory says optimized content should perform across AI engines. Reality says the topic has to match the platform’s user base.

    Content format preferences differ by platform. Copilot rewards structured reference content — pricing tables, comparison matrices, specific data points. ChatGPT rewards depth and original analysis. Perplexity rewards definitive, primary-source authority. AEO’s “structure for direct answers” advice is too generic to capture these distinctions.

    User intent varies by context. A Copilot user asking about Claude AI pricing is in the middle of a work task — they need a number, now. A ChatGPT user asking the same question might be evaluating whether to adopt Claude at all — they want context, comparisons, and strategic thinking. Same query, different intent, different optimal content. SEO’s keyword-intent model doesn’t account for the platform delivering the answer.

    The citation flywheel is platform-specific. My daily Copilot citations grew from 672 to 5,500 over 90 days. That growth happened because Copilot developed trust in my domain for specific topic clusters. This trust-building behavior is different from how Google ranks pages, how ChatGPT selects sources, or how Perplexity curates citations. Each platform has its own authority model.

    Introducing Platform-Specific AI Optimization

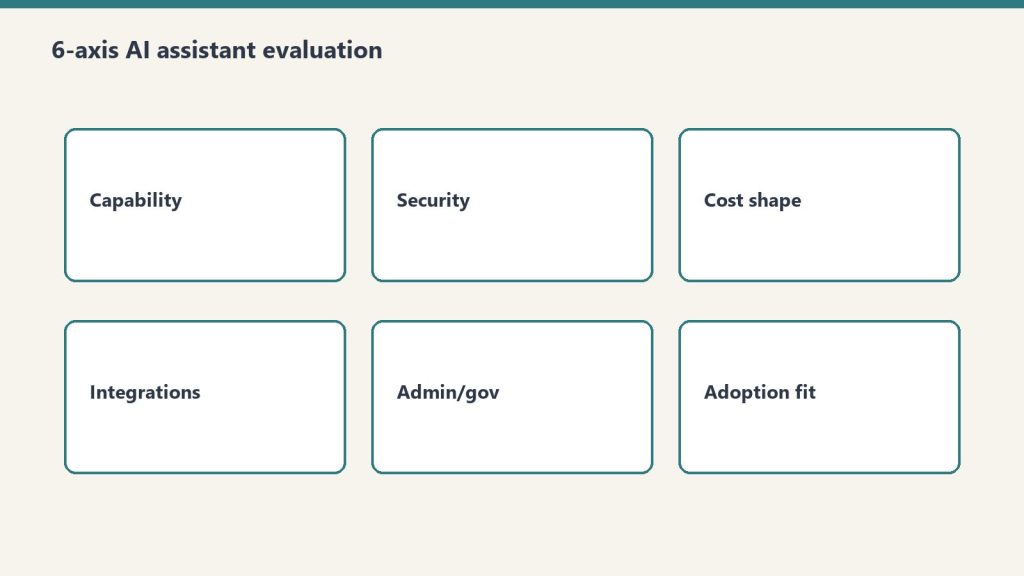
    Six evaluation cards for choosing an AI assistant platform
    Platform-specific AI optimization is what comes next.

    I’m going to name the thing that comes after the SEO/GEO/AEO debate because someone has to, and I have the data to back it up.

    Platform-Specific AI Optimization (PSAO) is the practice of creating content tailored to the specific user base, intent patterns, content format preferences, and authority models of individual AI platforms.

    PSAO doesn’t replace SEO, GEO, or AEO. It subsumes them. SEO becomes your Google-specific strategy. GEO becomes a shared foundation of AI-friendly content practices. AEO becomes a tactical layer that applies differently depending on which platform you’re targeting. And PSAO is the strategic framework that coordinates all of them.

    Here’s how PSAO maps the landscape:

    Google (SEO focus): Keyword optimization, link building, technical SEO, Core Web Vitals. Audience: searchers with transactional or informational intent. Metric: rankings, clicks, conversions.

    Microsoft Copilot (PSAO-Copilot): Structured reference content, pricing tables, comparison matrices, technical documentation. Audience: enterprise workers mid-task in Microsoft 365. Metric: AI citations in Bing Webmaster Tools.

    ChatGPT (PSAO-ChatGPT): Long-form thought leadership, original research, unique data, comprehensive analysis. Audience: explorers and evaluators in conversation mode. Metric: ChatGPT Search referral traffic, citation mentions.

    Perplexity (PSAO-Perplexity): Definitive primary-source content, original data, authoritative positioning. Audience: users seeking curated, multi-source answers. Metric: Perplexity citation frequency.

    Google AI Overviews (PSAO-AIO): Featured-snippet-ready content, concise definitions, structured FAQs. Audience: searchers receiving AI-generated summaries. Metric: AI Overview inclusion rate.

    Why Nobody Else Is Talking About This

    The reason PSAO doesn’t exist as a category yet is simple: nobody has the data. The tools are fragmented, the measurement is early, and the marketing industry is still in the “arguing about which single framework wins” phase.

    Bing Webmaster Tools AI Performance is in beta. Most marketers don’t know it exists. Google hasn’t released comparable citation-level data for AI Overviews. ChatGPT’s citation behavior isn’t exposed through any analytics dashboard. Perplexity doesn’t offer a webmaster console at all.

    The data infrastructure is nascent. But the underlying behavior — AI platforms consuming and citing web content at massive scale with platform-specific patterns — is already happening. The 98,800 citations on my domain aren’t theoretical. They’re measured, daily, query-by-query.

    The marketers who wait for a polished SaaS dashboard to tell them about platform-specific AI optimization will be years behind the ones who start measuring now with the crude tools available.

    What PSAO Strategy Looks Like in Practice

    On my own sites, PSAO looks like this:

    Morning content (Copilot hours): I publish detailed AI tool guides, pricing comparisons, and integration documentation. This content is structured for extraction — clean tables, specific numbers, version-stamped details. It serves enterprise Copilot users who are working in Office and need reference data.

    Evergreen content (Google hours): I publish local business guides, community resources, and civic information. This content is optimized for traditional SEO — keywords, headings, FAQ schema, internal links. It serves Google searchers looking for local information.

    Weekend content (ChatGPT depth): I publish thought leadership, original analysis, and data-driven arguments like this article. This content is optimized for depth and originality — the kind of content ChatGPT’s grounding algorithm favors when users are exploring a topic.

    Same domain. Three different content strategies. Three different audiences. Three different measurement frameworks. That’s PSAO.

    The Category Is Open

    Right now, there’s no Google Trends data for “Platform-Specific AI Optimization.” No conference tracks. No SaaS tools. No Gartner quadrant. The category is open because the phenomenon it describes has only become measurable in the last few months.

    I’m staking my position: the SEO vs GEO vs AEO debate is a transitional phase. Within 18 months, the marketers who matter will be talking about platform-specific optimization because the data will force them to. Different platforms, different audiences, different content, different metrics. That’s the future.

    And I’m publishing the playbook as I build it.

    Related on Tygart Media: GEO tactics · Google vs Copilot audiences · citation monitoring.

    Frequently Asked Questions

    Does PSAO replace SEO?

    No. PSAO subsumes SEO by treating it as your Google-specific optimization strategy. SEO remains essential for organic search traffic. PSAO adds parallel strategies for Copilot, ChatGPT, Perplexity, and other AI platforms — each tailored to the platform’s specific audience and behavior.

    How is PSAO different from GEO?

    GEO treats all AI engines as a single audience and applies general optimization principles — entity enrichment, structured data, authoritative sourcing. PSAO recognizes that each AI platform has a different user base, different intent patterns, and different content preferences. GEO is a foundation. PSAO is the targeting layer built on top of it.

    Where can I measure AI citations right now?

    Bing Webmaster Tools AI Performance tab shows Copilot citation data, including total citations, grounding queries, and daily trends. ChatGPT citations can be partially tracked through referral traffic analytics. Perplexity and Claude currently lack webmaster-facing citation analytics, requiring manual testing.

    What topics perform best on Copilot vs Google?

    Copilot users are enterprise workers mid-task, so technology tools, pricing comparisons, integration guides, and business strategy content earn the most citations. Google serves a broader audience including local searches, shopping intent, and general information queries. The overlap exists, but the highest-performing content for each platform is distinct.

    When will the industry adopt PSAO?

    The adoption curve depends on measurement tools. As Bing Webmaster Tools, Google Search Console, and potential new platforms expose AI citation data, marketers will be forced to segment their optimization by platform. Based on current data trends, platform-specific optimization will likely become standard practice within 12-18 months for advanced content operations.

  • Writing for Google vs Writing for Copilot vs Writing for ChatGPT: They’re Not the Same Audience

    Writing for Google vs Writing for Copilot vs Writing for ChatGPT: They’re Not the Same Audience

    The Assumption That’s Costing You Citations

    Comparison of Claude how-to fit versus local service page fit for assistants
    The assumption costing you citations.

    The entire content marketing industry operates on a single assumption: write great content, optimize it for search, and the right people will find it. For two decades, “the right people” meant Google users. That assumption worked because there was only one discovery engine that mattered.

    There are now at least five. And they don’t behave the same way.

    Google users type keywords. Microsoft Copilot users ask questions mid-task inside Word, Excel, or Outlook. ChatGPT users explore topics conversationally. Perplexity users want curated, multi-source answers. Claude users tend to ask deep, technical questions about implementation.

    I know this because I can see it. My site generates 98,800 AI citations from Copilot alone, and the grounding queries — the actual questions that triggered those citations — reveal an audience that looks nothing like my Google Analytics traffic. These are different people, in different contexts, with different needs, finding the same content through completely different pathways.

    The content that serves one platform well often serves another poorly. And if you’re optimizing for “AI search” as a single category, you’re making the same mistake as someone who runs the same TV commercial on ESPN, HGTV, and the Discovery Channel.

    Google Users: The Keyword Searchers

    Four cards for content, ops, build, and knowledge work with Claude
    Google users: keyword searchers.

    Google’s audience is the one everyone understands. They type keywords — sometimes fragments, sometimes questions, often just a few words. “Best CRM software.” “Water damage restoration Houston.” “Claude AI pricing 2026.”

    The behavior is transactional or informational. They want a list, a comparison, a local service, or a quick answer. Google’s algorithm rewards content that satisfies this intent quickly: clear headings, structured data, fast load times, and content that matches the keyword pattern.

    Google users click through to your site. They see your ads. They enter your funnel. The entire monetization model of the internet is built on this interaction: search, click, land, convert.

    Content that wins on Google: keyword-optimized pages, local landing pages, listicles, product comparisons, and how-to content with clear structure. The audience skims. They want answers in the first 100 words or they bounce.

    Copilot Users: The Mid-Task Workers

    Copilot users are a fundamentally different audience. They’re not searching — they’re working. They invoke Copilot inside Microsoft 365 applications while writing a report, analyzing a spreadsheet, composing an email, or researching a decision they need to make in the next 30 minutes.

    The queries I see in Bing’s grounding data confirm this: “what is claude ai pricing in 2026,” “how to connect notion to claude code,” “difference between claude code and cursor for teams.” These are operational questions from people in the middle of a task. They need accurate, specific, reference-grade information — not a 2,000-word SEO article with a table of contents and 47 H2 headings.

    The content that earns 16,500 Copilot citations for a single query isn’t my best-written piece. It’s my most accurate, specific, and structured piece. It has clear pricing tables. It has version-specific details. It answers the exact question without making you read three paragraphs of context first.

    Copilot users never visit your site. They consume your content inside their Office application, surfaced as a grounded AI response. Your content becomes the source material for Copilot’s answer. The citation is your visibility — not the click.

    Content that wins on Copilot: detailed pricing breakdowns, tool comparison matrices, integration guides with specific steps, and reference documentation that’s structured for extraction rather than engagement.

    ChatGPT Users: The Explorers

    ChatGPT’s audience is different again. These are people in exploration mode — they’re thinking through a problem, evaluating options, or trying to understand something complex. They write long, conversational queries. They ask follow-up questions. They treat the AI as a thinking partner rather than an answer machine.

    ChatGPT’s citation behavior (visible through ChatGPT Search) favors content that demonstrates expertise, provides unique insights, and covers topics comprehensively. Where Copilot wants structured reference data, ChatGPT wants depth and nuance. Where Copilot users need an answer in 10 seconds, ChatGPT users are willing to engage for 10 minutes.

    Content that wins on ChatGPT: long-form thought leadership, original research, case studies with real data, and contrarian perspectives backed by evidence. ChatGPT’s grounding algorithm appears to reward content that says something other sources don’t.

    Perplexity Users: The Curators

    Perplexity positions itself as an answer engine — it synthesizes multiple sources into a single response with inline citations. Its users want the definitive answer, pulled from the best available sources and presented with transparency about where each claim comes from.

    Perplexity’s citation behavior rewards pages that are recognized as authoritative on a specific topic. It tends to pull from a smaller number of high-trust sources rather than aggregating broadly. If your page is the best single source on a topic, Perplexity will cite it repeatedly.

    Content that wins on Perplexity: comprehensive pillar pages, original data, and content that’s clearly the primary source rather than a summary of other sources. Perplexity penalizes derivative content more visibly than any other platform.

    Claude Users: The Implementers

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Claude users: the implementers.

    Claude’s user base skews toward developers, technical professionals, and power users who ask implementation-level questions. They want to know how to build something, how to configure something, or how to debug something. The queries tend to be specific and technical.

    Content that wins Claude citations: technical documentation, code examples, step-by-step implementation guides, and troubleshooting content. Claude’s training data and retrieval mechanisms favor content that’s precise and actionable over content that’s broadly informative.

    The Same Article, Five Different Treatments

    Let me make this concrete. Say I’m writing about connecting Claude to a Notion database using MCP (Model Context Protocol). Here’s how the same topic needs to be treated differently for each platform:

    For Google: “How to Connect Notion to Claude AI (2026 Guide)” — Keyword-optimized title, H2 structure, step-by-step with screenshots, FAQ schema, 1,200 words. Goal: rank for “notion claude integration.”

    For Copilot: A reference page with the exact configuration JSON, version requirements, common error codes and fixes, and a clean table of parameters. No fluff. Copilot will extract the technical specs and present them to a user who’s currently trying to set this up.

    For ChatGPT: A 2,500-word deep dive on why MCP matters, what it enables, the architecture decisions behind it, and how it compares to other integration approaches. ChatGPT users are evaluating whether to adopt MCP, not just how to configure it.

    For Perplexity: The definitive reference that other sources can’t match — original benchmarks, real performance data, edge cases nobody else documents. Perplexity will choose this as its primary source if it’s clearly the most authoritative.

    For Claude: Working code examples, actual configuration files, error handling patterns, and the kind of implementation detail that lets someone copy-paste and go.

    That’s five different content approaches for one topic. And most content operations are producing one version and hoping it works everywhere.

    Why This Matters Now

    The advertising industry figured this out decades ago. You don’t run the same creative on a billboard, a podcast ad, a YouTube pre-roll, and a smart TV placement. Each format has a different audience in a different context with different attention patterns. The creative has to match.

    AI platforms are the new formats. Copilot is the workplace billboard — your content appears where people are already working. ChatGPT is the podcast — people are engaged and exploring. Perplexity is the curated newsletter — only the best sources make the cut. Google is still the highway — highest volume, broadest audience, most competitive.

    The content operations that figure out platform-specific optimization first will dominate the AI citation economy the way early SEO adopters dominated organic search. The data is already available. The tools exist. The only missing piece is the strategic framework — and the willingness to treat AI platforms as distinct audiences rather than a single monolithic “AI search” category.

    I’m building that framework in real time, publishing the data as I go. This article is part of it.

    Related on Tygart Media: SEO vs GEO vs AEO · Copilot day / Google night · AI search funnel.

    Frequently Asked Questions

    Do I need to create separate articles for each AI platform?

    Not necessarily separate articles, but you need to think about which platform each piece is optimized for. Some articles naturally serve multiple platforms. But your highest-value topics should have platform-specific treatments — a reference version for Copilot, a deep-dive version for ChatGPT, a definitive version for Perplexity.

    How do I know which AI platform is citing my content?

    Currently, Bing Webmaster Tools shows Copilot citation data in the AI Performance beta tab. ChatGPT citations can be partially tracked through referral traffic from chat.openai.com. Perplexity and Claude citation data is harder to access — you’ll need to manually query these platforms with topics you rank for and observe whether your content appears in their responses.

    What content format works best for Copilot citations?

    Structured, reference-grade content with clear data points, pricing tables, comparison matrices, and specific technical details. Copilot users are mid-task and need precise answers. Content that’s structured for extraction — where Copilot can pull a specific fact or figure — earns the most citations.

    Is this the same as GEO (Generative Engine Optimization)?

    GEO is a component, but it treats all AI engines as one audience. Platform-Specific AI Optimization (PSAO) goes further by recognizing that each AI platform serves a different user base with different intent patterns. GEO gives you the foundation. PSAO gives you the targeting.

    Should I stop optimizing for Google to focus on AI platforms?

    No. Google still drives the majority of direct traffic for most sites. The strategy is to run parallel content operations — Google-optimized content for organic traffic and platform-specific content for AI citations. On my own sites, I serve local Google searchers with community content and enterprise Copilot users with AI tool content. Same domain, two funnels.

  • 98,800 AI Citations from One Laptop: What Microsoft Copilot Is Actually Sourcing

    98,800 AI Citations from One Laptop: What Microsoft Copilot Is Actually Sourcing

    The Number Nobody Expected

    Comparison of Claude how-to fit versus local service page fit for assistants
    The number nobody expected.

    I run a portfolio of WordPress sites. One of them — a media property publishing articles about AI tools, local business intelligence, and content strategy — started showing up in a place I didn’t expect: inside Microsoft Copilot’s answers.

    Not as a search result. Not as a backlink. As a citation — the source that Copilot grounded its response on when enterprise users asked questions inside Word, Edge, Outlook, and the Copilot sidebar.

    The Bing Webmaster Tools AI Performance tab — still in beta, still barely documented — told me exactly how much: 98,800 AI citations across 576 unique grounding queries in under 90 days.

    That’s not a typo. Ninety-eight thousand, eight hundred times an AI engine pulled content from my site and embedded it in a response to a real user. And here’s the part that flipped my understanding of content economics: during that same period, the site received roughly 1,900 human clicks from Bing search.

    The AI was reading my content 52 times more often than humans were clicking on it.

    What the Bing AI Performance Tab Actually Shows

    Topic platform fit visual for first-party AI citation measurement
    What the Bing AI Performance tab actually shows.

    Most marketers don’t know this tab exists. It appeared in Bing Webmaster Tools sometime in late 2025, buried under the Performance section. Microsoft labeled it “AI Performance (beta)” and didn’t announce it with any fanfare. No blog post. No keynote mention. It just showed up.

    Here’s what it tracks:

    Citations: The number of times your content was used as a grounding source in a Copilot-generated response. This isn’t an impression — it’s a direct attribution. Copilot pulled from your page, used your information, and (in many cases) linked back to you as the source.

    Grounding Queries: The actual questions users asked that triggered your content to be cited. These aren’t keywords — they’re natural language questions. Full sentences. “What is claude ai pricing in 2026.” “How do I connect Claude to Notion.” “What’s the difference between Claude Code and Cursor.”

    Daily Trend Data: The day-by-day citation count. This is where the story gets interesting.

    The Growth Curve That Changed My Strategy

    When I first noticed the AI Performance tab, my daily citation count was sitting at around 672 per day. Modest. Interesting, but not transformative.

    Ninety days later, it was 5,500 citations per day. That’s an 8x increase with no corresponding change in my publishing cadence, no new backlink campaigns, no paid distribution. The content was the same. What changed was Copilot’s appetite for it.

    The growth wasn’t linear. It came in steps:

    Days 1-30: Steady at 600-800 citations/day. Copilot was discovering the site.
    Days 30-50: Jump to 1,500-2,200/day. A handful of articles got locked in as preferred sources.
    Days 50-70: Acceleration to 3,000-4,000/day. The site was now a default grounding source for an expanding set of queries.
    Days 70-90: Peak at 5,500/day. Citation velocity was compounding — the more Copilot cited the site, the more queries it became eligible for.

    This looks like a flywheel, and I believe that’s exactly what it is. Copilot’s grounding algorithm appears to develop trust in sources over time. Once a domain proves reliable for a topic cluster, it gets promoted for adjacent queries in that cluster.

    The 576 Queries: What Enterprise Users Actually Ask

    The grounding queries are the most valuable dataset I’ve ever had access to. They reveal what Copilot users — overwhelmingly enterprise workers inside Microsoft 365 — are actually asking when they invoke the AI.

    The top query by citation volume: “claude ai pricing” — generating 16,500 citations on its own. One query. One article. Sixteen thousand five hundred times Copilot used my page as the source for its answer.

    The next tier includes queries like “claude code vs cursor,” “how to use claude code,” “anthropic console guide,” and “notion mcp setup.” These are highly specific, tool-comparison, how-do-I-use-this queries from people who are actively working. They’re not browsing. They’re not exploring. They’re in the middle of a task and they need an answer right now.

    This tells me something fundamental about who Copilot serves: knowledge workers making decisions inside productivity software. They’re writing a memo and need a pricing comparison. They’re evaluating a developer tool and need a feature breakdown. They’re setting up an integration and need configuration steps.

    The content that wins Copilot citations isn’t SEO content. It isn’t listicles. It isn’t keyword-stuffed landing pages. It’s reference-grade material that answers specific operational questions.

    What Roofing Articles Got: Zero

    Four cards for content, ops, build, and knowledge work with Claude
    What roofing articles got: zero — topic-platform fit.

    I also publish content in trade verticals — restoration, construction, and local services. Those articles have solid traditional SEO performance. Google sends traffic. The content ranks.

    Copilot citations for those articles: zero.

    Not low. Not “a few.” Zero. Because the people using Copilot in their daily workflow aren’t asking about emergency water damage repair or roofing contractors in Houston. They’re asking about the tools they use to do their jobs — AI platforms, development environments, productivity software, and business strategy.

    This is the first data point that made me realize: AI citation optimization is platform-specific. The topics that win on Copilot are not the topics that win on Google, and they’re not the same topics that win on ChatGPT or Perplexity. Each platform has a different user base with different intent patterns.

    The Raw Numbers, Laid Out

    Here’s the data from one domain over approximately 90 days, pulled directly from Bing Webmaster Tools AI Performance (beta):

    Total AI Citations: 98,800
    Total Grounding Queries: 576
    Average Daily Citations (start): 672
    Average Daily Citations (end): 5,500
    Top Single Query Citations: 16,500 (“claude ai pricing”)
    Human Clicks from Bing (same period): ~1,900
    AI-to-Human Ratio: 52:1
    Top Content Type Cited: Detailed comparison/pricing guides
    Content Types with Zero Citations: Local service pages, trade industry content

    What This Means for Content Strategy

    The industry is currently arguing about SEO vs GEO vs AEO. That argument is already outdated. What the data shows is something more granular: different AI platforms are different audiences, and they require different content strategies, the same way that smart TV advertising requires different creative than mobile advertising.

    I’m calling this Platform-Specific AI Optimization (PSAO) because nobody else has named it yet. Nobody else has named it because nobody else is measuring it. The tools are there — Bing Webmaster Tools shows Copilot citation data right now — but the marketing industry hasn’t caught up to the idea that AI engines are audiences, not just algorithms.

    Here’s what I’m doing with this data:

    I’m writing content specifically engineered for Copilot’s enterprise user base during business hours — detailed tool comparisons, pricing breakdowns, integration guides, and operational how-tos. I’m writing different content for Google’s organic audience — local business directories, event guides, and community resources. Same domain. Two completely different content strategies running simultaneously.

    The Copilot content doesn’t need to rank on Google. The Google content doesn’t need Copilot citations. Each serves its platform’s audience where they actually are.

    Why I’m Publishing This

    I’m publishing this data because the industry needs a baseline. Right now, there is no public benchmark for AI citation volume. No one is talking about citation-per-query rates, daily citation growth curves, or topic-platform fit analysis. There’s no equivalent of “Domain Authority” or “organic traffic” for the AI citation economy.

    Someone needs to be first. I have the data. So here it is.

    If you run a content operation and you haven’t checked your Bing Webmaster Tools AI Performance tab, do it today. You might be sitting on citation data you didn’t know existed. And if you’re building content strategy without accounting for which AI platforms are actually consuming your content, you’re optimizing for one audience while ignoring the one that’s reading you 50 times more often.

    The AI citation economy is already here. The question is whether you’re measuring it.

    Related on Tygart Media: $0.35 article · 16,500 citations · citation economy.

    Frequently Asked Questions

    What are AI citations in Bing Webmaster Tools?

    AI citations are instances where Microsoft Copilot uses your website content as a grounding source in its responses to user queries. They appear in the AI Performance (beta) tab within Bing Webmaster Tools and represent direct attribution — Copilot pulled information from your page and used it to construct an answer for a real user.

    How do I check my AI citation data?

    Log into Bing Webmaster Tools, navigate to the Performance section, and look for the “AI Performance” tab. It’s currently in beta. You’ll see total citations, grounding queries (the actual questions users asked), and daily trend data showing how your citation volume changes over time.

    Why does Copilot cite some content but not others?

    Copilot’s user base is predominantly enterprise workers inside Microsoft 365 applications. They ask operational questions — tool comparisons, pricing details, integration guides, and how-to content related to their daily work. Content that answers specific, task-oriented questions earns citations. Generic listicles, local service pages, and broadly targeted SEO content typically receives zero citations because it doesn’t match what Copilot users are asking.

    What is Platform-Specific AI Optimization (PSAO)?

    PSAO is a content strategy framework that recognizes different AI platforms serve different audiences with different intent patterns. Copilot users are enterprise workers mid-task. ChatGPT users are explorers and researchers. Perplexity users want curated multi-source answers. PSAO means creating content tailored to each platform’s user behavior rather than treating all AI engines as interchangeable.

    Is AI citation data more valuable than traditional search clicks?

    The data suggests AI citations represent a fundamentally different type of content consumption. With a 52:1 ratio of AI citations to human clicks, AI engines are consuming content at dramatically higher volumes. Whether this translates to direct revenue depends on your monetization model, but from a reach and authority perspective, AI citations may represent the larger audience for many content categories.