Author: Will Tygart

  • Bing Webmaster Tools Has an AI Tab Nobody Is Using — Here’s What It Shows

    Bing Webmaster Tools Has an AI Tab Nobody Is Using — Here’s What It Shows

    The Best-Kept Secret in Search Marketing
    Topic platform fit visual for first-party AI citation measurement
    Bing Webmaster AI tab — the best-kept secret.

    Microsoft shipped one of the most significant measurement tools in content marketing history, and the industry collectively shrugged. Sometime in late 2025, an “AI Performance” tab appeared in Bing Webmaster Tools. No announcement. No blog post. No conference keynote. It just showed up in the sidebar, labeled “(beta),” waiting for someone to notice.

    I noticed. And what I found inside was the first real dataset on AI citation behavior that any search engine has ever exposed to publishers. The tab shows exactly how many times Microsoft Copilot cites your content, which queries triggered those citations, and how the volume trends over time.

    For my domain, that data showed 98,800 AI citations across 576 grounding queries — numbers that completely changed how I think about content strategy. But when I talk to other marketers about it, the most common response is: “Wait, there’s an AI tab?”

    This is a walkthrough. By the end, you’ll know where to find it, what it shows, and how to read the data.

    Getting to the AI Performance Tab

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Getting to the AI Performance tab.

    Step 1: Verify your site with Bing Webmaster Tools. If you haven’t done this, start at bing.com/webmasters. You can verify using DNS, a meta tag, a CNAME record, or by importing from Google Search Console. The Google Search Console import is the fastest path — it takes about 30 seconds and automatically verifies all your Search Console properties in Bing.

    Step 2: Navigate to your verified property. Once you’re in the dashboard, select the domain you want to analyze.

    Step 3: Find the AI Performance tab. In the left sidebar, look under the “Performance” section. You’ll see the standard “Search Performance” tab (clicks and impressions from Bing search) and below it, “AI Performance (beta).” Click it.

    If you don’t see the tab, there are two possible reasons: your site hasn’t been verified long enough for Bing to accumulate data, or your site hasn’t earned any Copilot citations yet. The tab may not appear until there’s data to show.

    What You’ll See Inside

    The AI Performance tab has three main data views:

    Citation Count (total): This is the big number at the top. It shows the total number of times Copilot used your content as a grounding source in its responses. For context: my domain shows 98,800 total citations. This number represents actual instances where Copilot pulled information from my pages and embedded it in responses to real users.

    Grounding Queries: Below the total count, you’ll see a list of the actual queries that triggered citations. These are natural language questions — not keywords. They show exactly what Copilot users asked when your content was cited. My top query is “claude ai pricing” at 16,500 citations. The query list is sorted by citation volume, showing your highest-impact content first.

    Daily Trend Chart: A time-series chart showing daily citation volume. This is where you see growth patterns. My chart shows a clear acceleration: 672 daily citations at the start growing to 5,500 daily citations over 90 days. The shape of this curve tells you whether your citation authority is growing, stable, or declining.

    Reading the Data: What the Numbers Mean

    High citation count + few queries = concentrated authority. If you have thousands of citations but only 10-20 queries, your content is the dominant source for a small number of high-volume topics. This is a strong position — you own those topics in Copilot’s grounding index. My domain has this pattern: a few articles about Claude pricing and tools generate the bulk of citations.

    Moderate citations + many queries = broad relevance. If you have hundreds of queries each generating modest citation counts, your domain is recognized as relevant across a wide topic area but isn’t dominant for any single query. This is a growth opportunity — identify the queries with the highest potential and create dedicated, optimized content for each.

    Growing daily trend = citation flywheel. If your daily trend shows consistent growth, Copilot is developing increasing trust in your domain. This flywheel effect means each new citation makes your domain more eligible for additional queries. Protect this growth by keeping cited content accurate and current.

    Flat or declining trend = stale content signal. If citations plateau or decline, it may indicate that your content is becoming outdated or that competitors have published more current versions. Check whether your most-cited pages have stale information — especially pricing, feature lists, or version numbers.

    The Queries Are the Gold
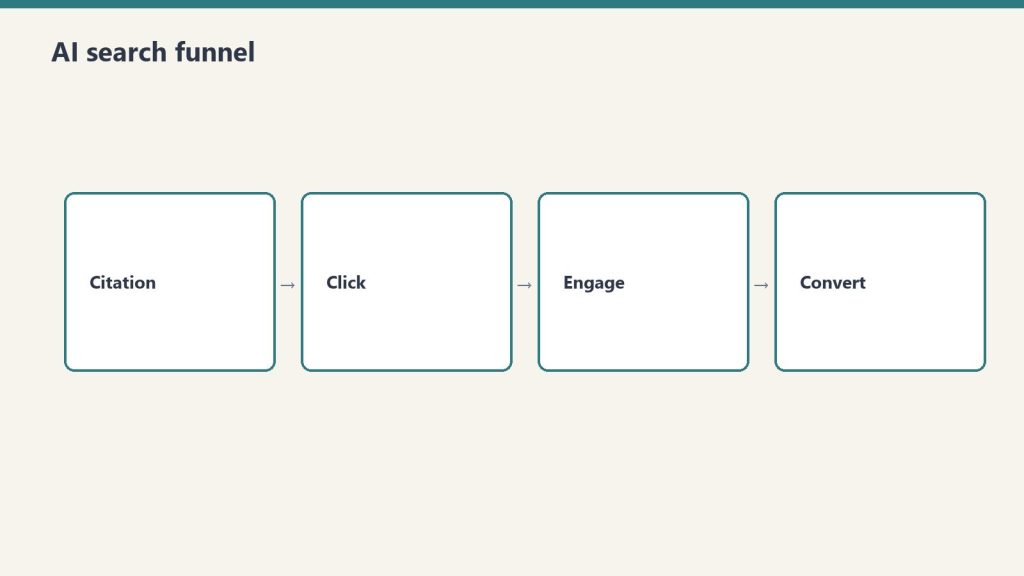
    Four-stage funnel: citation, click, engage, convert
    The queries are the gold.

    The most valuable data in the AI Performance tab isn’t the citation count — it’s the grounding queries. These reveal exactly what enterprise workers are asking Copilot, which is intelligence you cannot get from any other tool.

    Google Search Console shows you keywords — fragments that users type into a search bar. Bing’s grounding queries show you full natural language questions that users ask an AI assistant. The difference is significant:

    A Google keyword might be: “claude ai pricing”
    The Copilot grounding query is: “what is claude ai pricing in 2026 and how does it compare to openai”

    The grounding query tells you the user’s full intent, their comparison frame, and their temporal context. This is richer intent data than any keyword tool provides, and it’s free, sitting in your Bing Webmaster Tools dashboard right now.

    Use these queries to:

    Identify content gaps. If users are asking questions that your content doesn’t fully answer, you know exactly what to add. A grounding query like “claude ai pricing vs openai pricing 2026 comparison” tells you to add an explicit comparison section to your pricing article.

    Discover adjacent topics. The long tail of grounding queries often reveals related topics you haven’t covered. If you’re earning citations for “claude ai pricing” but also seeing queries about “claude api rate limits” and “claude team plan features,” those are content opportunities.

    Understand your audience’s context. Grounding queries reveal the user’s situation. “What is the best AI coding tool for a team of 5” tells you the user is a tech lead making a purchasing decision. “How do I set up claude code on windows” tells you the user is a developer getting started. Each query paints a picture of who is consuming your content through Copilot.

    What to Do With the Data

    Once you’ve found and understood your AI citation data, here’s the action playbook:

    Identify your citation pillars. Which pages earn the most citations? These are your highest-authority assets. Invest in keeping them accurate, current, and comprehensively structured. A $0.10 update to a page earning 1,000 daily citations is the highest-ROI content investment you can make.

    Fill the gaps in your query coverage. Look at grounding queries that cite your content — are there related queries you’re not capturing? Build content for the gaps. If you earn citations for “claude ai pricing” but not “claude ai pricing for enterprise,” that’s a targeted content opportunity.

    Structure for extraction. Look at which content formats earn the most citations. In my data, structured content — pricing tables, comparison matrices, step-by-step configurations — earns dramatically more citations than narrative-only content. Add extractable elements to your highest-value pages.

    Set up a monitoring cadence. Check your AI Performance tab weekly. Track your daily citation trend and watch for inflection points. If a new article suddenly starts earning citations, double down on that topic. If an existing article’s citations start declining, check whether the content has become outdated.

    Cross-reference with Search Performance. Compare your AI citation data with your traditional Bing search data in the same tool. Which pages earn citations but not clicks? Which earn clicks but not citations? This comparison reveals which content serves AI audiences vs human audiences — the foundation of platform-specific optimization.

    Why This Matters Beyond Bing

    Bing Webmaster Tools AI Performance is currently the only tool exposing AI citation data at this level of detail. Google Search Console doesn’t show AI Overview citation data. ChatGPT, Perplexity, and Claude don’t offer webmaster analytics dashboards.

    But the data from Bing is a leading indicator for the entire AI citation landscape. Microsoft Copilot’s behavior reflects broader patterns in how AI engines consume and cite web content. The topics that earn Copilot citations are likely earning citations across other AI platforms too — you just can’t see the data yet.

    By the time Google and other platforms expose their citation data (which I believe is inevitable as publisher demand grows), the early movers who used Bing’s data to develop platform-specific content strategies will have a compounding advantage. They’ll have built the citation authority, refined their content formats, and mapped their topic-platform fit while everyone else was waiting for better tools.

    The tools aren’t perfect. They’re beta. But they’re real data about a real shift in how content gets consumed. And right now, almost nobody is using them.

    Related on Tygart Media: read Bing AI citations · Bing vs GSC · citation monitoring.

    Frequently Asked Questions

    Is Bing Webmaster Tools free?

    Yes. Bing Webmaster Tools is completely free to use. You only need to verify ownership of your domain, which can be done through DNS records, meta tags, or by importing your Google Search Console properties directly.

    What if I don’t see the AI Performance tab?

    The tab may not appear until your site has accumulated AI citation data. Verify your site, ensure it’s been indexed by Bing, and check back after a few weeks. Not all sites earn Copilot citations — the tab appears when there’s data to display.

    Can I see which specific pages are being cited?

    The current beta shows grounding queries and total citation counts. The page-level attribution is inferred through the queries — if a query about “claude ai pricing” cites your content, it’s almost certainly citing your Claude pricing page. Microsoft may add explicit page-level data as the tool matures.

    How does Copilot decide which sites to cite?

    Copilot uses Bing’s search index to find relevant content for grounding. The selection factors appear to include content relevance, structural quality, accuracy, domain authority, and trust signals built through consistent citation history. Well-structured, accurate, reference-grade content on topics matching Copilot user queries earns the most citations.

    Should I optimize for Bing search to get more Copilot citations?

    Bing indexation is a prerequisite for Copilot citations since Copilot uses Bing’s index. Ensure your site is indexed in Bing Webmaster Tools and that your key pages are crawlable. Beyond that, the most effective optimization for Copilot citations is creating structured, accurate, reference-grade content on topics that enterprise workers ask about.

  • Claude Cowork: What It Is, How It Works, and What Non-Developers Can Automate on Their Desktop

    Claude Cowork: What It Is, How It Works, and What Non-Developers Can Automate on Their Desktop

    Direct Answer (9 September 2026): Claude Cowork is the desktop workspace in the Claude app. It works on local files and apps you approve. It is not Chat and it is not the Chrome extension. Use Chat when the job is a conversation. Use Cowork when the job is a folder, a document, or a multi-step desktop workflow. It ships on Pro, Max, Team, and Enterprise — not Free.

    Claude Cowork lets Claude work on the machine, not just talk about the work. Last verified 9 September 2026.

    Chat vs Cowork vs Chrome

    • Chat — conversation, no local workspace.
    • Cowork — local files, Skills, desktop workflows in the Claude app.
    • Chrome extension — the page in the browser. Separate install. See Claude in Chrome.
    • Claude Code — terminal / repo. Developers.

    The error strings people actually search

    These belong here and on the limits desk:

    • Claude Cowork missing HCS services — the local helper stack did not start. Quit the Claude app, confirm disk space, relaunch. If it persists, reinstall the desktop app. Do not treat this as a chat usage-limit.
    • Failed to start Claude’s workspace / not enough disk space — free space on the volume that holds the workspace, then retry. Cowork and Code spin their own copy of the server.
    • Couldn’t start this server for Cowork and Code sessions — same class. The session runner failed to boot. Restart the app; do not keep retrying from Chat.
    • Cowork not working — confirm you are in the desktop app on a paid seat, not claude.ai Chat and not the Chrome side panel.

    How Cowork works

    Three stacked layers: chat UI, tools, agent runtime
    How Cowork mode works.

    In the desktop app Claude can read folders you grant, write documents, run Skills, and call MCP tools. Actions ask for approval. It is not a silent screen-scraper.

    What it can automate

    File management, document creation (DOCX, XLSX, PPTX, PDF), data cleanup, and cross-app handoffs you approve. It is not a replacement for Claude Code on a repo.

    Cowork vs Claude Code

    Code is the terminal path for developers. Cowork is the visual path for operators. Both sit on Pro / Max / Team / Enterprise. Matrix: Cowork vs Code vs Agent SDK.

    Getting started

    Install the Claude desktop app. Open a Cowork session. Grant the folder. Describe the job. Approve the first file write before you let it run a batch.

    Frequently Asked Questions

    What is Claude Cowork?

    Desktop workspace in the Claude app for files and local workflows.

    Is Cowork included in Claude Pro?

    Yes. Pro, Max, Team, Enterprise. Not Free.

    Can Cowork see everything on my screen?

    Only apps and folders you grant.

    Do I need to code?

    No.

    Related: Chrome extension · limits and errors · pricing · reference hub.

  • The $0.35 Article That Gets Cited by Microsoft’s AI 4,000 Times

    The $0.35 Article That Gets Cited by Microsoft’s AI 4,000 Times

    A New Kind of Unit Economics

    Topic platform fit visual for first-party AI citation measurement
    A new kind of unit economics for AI citations.

    I wrote an article about Claude AI pricing. The entire production cost — from research to publication — was roughly $0.35 in AI API costs and about 20 minutes of my time for editing and fact-checking. I published it through my existing WordPress infrastructure with zero additional distribution cost.

    That article has generated over 4,000 Copilot citations for the query “claude ai pricing” alone, with the total across related queries pushing well past 16,500. It earns new citations every day. It’s been cited more times than most marketing campaigns reach people.

    The cost-per-citation: less than $0.00009. Nine thousandths of a penny per citation.

    Compare that to any traditional content marketing metric. Cost per click in paid search for AI tool keywords runs $5-15. Cost per impression in display advertising is $5-10 per thousand. Cost per lead in B2B SaaS is $50-200. The cost per AI citation for well-optimized content is effectively zero.

    This isn’t a gimmick or an edge case. It’s the fundamental unit economics of the AI citation economy — and they’re so different from traditional content economics that most marketers haven’t processed what they mean.

    How the $0.35 Article Gets Made

    Comparison of Claude how-to fit versus local service page fit for assistants
    How the cheap article gets made.

    Let me break down the actual production pipeline for an article that earns thousands of AI citations.

    Research and outline: I use AI tools to research current pricing data, feature comparisons, and user questions for the topic. This involves API calls to Claude for synthesis and cross-referencing against official documentation. API cost for a thorough research session: roughly $0.10-0.15.

    Draft generation: Using my content pipeline — which combines AI-assisted drafting with manual editing and fact-checking — I produce a structured article with pricing tables, feature comparisons, and FAQ sections. API cost for drafting and revision: roughly $0.10-0.20.

    Optimization and formatting: I apply SEO, AEO, and GEO optimization passes. Schema markup gets injected. Internal links are added. Taxonomy is assigned. This is partially automated through my publishing pipeline. API cost: roughly $0.05-0.10.

    Publication: The article is published via WordPress REST API. Zero distribution cost. No paid promotion. No social media budget. The content sits on its own domain and waits for AI engines to discover it.

    Total API cost: approximately $0.25-0.45. Call it $0.35 as a round number. My time investment is 15-30 minutes for quality control, fact-checking, and editorial decisions that I don’t delegate to AI.

    That’s the entire investment. There’s no ad spend to drive traffic. No outreach campaign to earn backlinks. No social distribution budget. The content earns citations because it’s the best available answer to a question that enterprise workers ask Copilot regularly.

    The Compounding Returns

    Four-stage funnel: citation, click, engage, convert
    The compounding returns of citation assets.

    What makes AI citation economics fundamentally different from traditional content economics is the compounding behavior.

    In traditional SEO, a blog post might earn organic traffic for 6-12 months before it starts declining. You have to continually produce new content to maintain traffic levels. The depreciation curve is steep.

    In AI citations, I’m observing the opposite pattern. My Copilot citation data shows a flywheel: daily citations grew from 672 to 5,500 over 90 days. The more Copilot cited my content, the more queries it became eligible for, which generated more citations, which built more authority for adjacent queries.

    A $0.35 article doesn’t just generate citations once. It generates citations daily, at increasing volume, for as long as it remains accurate and current. The total lifetime citations for a well-maintained article in a high-demand topic could reach tens of thousands.

    The math is simple but staggering: invest $0.35 to create the article, spend another $0.10 every month or two updating it for accuracy, and collect thousands of citations continuously. The return on that investment doesn’t have a meaningful comparison in traditional marketing economics.

    Why This Doesn’t Work for Every Article

    Before this sounds like alchemy, here’s the reality check: the $0.35-to-4,000-citations ratio only works when three conditions are met.

    Condition 1: Topic-platform fit. The article has to answer questions that Copilot users actually ask. “Claude AI pricing” is a perfect fit because enterprise workers evaluating AI tools ask this question inside Microsoft 365 regularly. An article about local restaurant hours would cost the same $0.35 to produce and earn zero Copilot citations — because nobody asks Copilot that question.

    Condition 2: Structural quality. Copilot’s grounding algorithm prefers content it can extract cleanly. A pricing table that’s formatted as a real HTML table gets cited more than the same information buried in paragraphs. Structured content with clear headings, defined terms, and extractable data points earns more citations per article than narrative content with the same information presented conversationally.

    Condition 3: Accuracy and currency. AI engines can detect when content is outdated. My pricing articles are version-stamped and updated regularly. An article that says Claude Haiku costs one price when it actually costs another will eventually lose citations as the AI engine gets corrective signals from other sources or user feedback.

    When all three conditions are met, the unit economics are extraordinary. When any one is missing, the economics collapse to zero — literally zero citations regardless of how much you spend on production.

    Comparing the Numbers

    Here’s how AI citation unit economics compare to traditional content marketing channels, using rough industry benchmarks:

    Paid search (Google Ads): Cost per click for AI tool keywords: $5-15. To reach 4,000 users, you’d spend $20,000-60,000. And those users might bounce without engaging.

    Display advertising: Cost per thousand impressions: $5-10. To reach 4,000 users, you’d spend $20-40 — but impressions are passive. The user might not even notice your ad, let alone engage with your content.

    Content marketing (traditional): A well-produced blog post might cost $200-500 between writer, editor, and designer. It might earn 500-2,000 organic visits over its lifetime. Cost per engaged reader: $0.10-1.00.

    AI citation content: Production cost: $0.35. Citations earned: 4,000+ (and growing). Cost per citation: $0.00009. And each citation represents a high-intent user who received your information as part of their active workflow — not a passive impression, not a possible bounce.

    The comparison isn’t even in the same order of magnitude. AI citation content is 10,000x more cost-efficient than paid search for reaching users at scale. The caveat is that citations aren’t clicks — you don’t control the downstream conversion. But for brand authority, content distribution, and audience reach, the economics are unprecedented.

    What This Means for Content Operations

    If the unit economics of AI citation content are this different from traditional content, the operational implications are significant.

    Volume becomes feasible. When an article costs $0.35 to produce, you can produce a lot of them. The constraint isn’t budget — it’s editorial quality and topic selection. A content operation can test hundreds of topics to find the ones with the best citation economics and then invest in keeping those articles current.

    Maintenance becomes the job. In traditional content marketing, the work is producing new content. In AI citation marketing, the work shifts to maintaining existing content. An article that’s earning 1,000 daily citations needs to stay accurate, current, and structured. A $0.10 update that keeps a $0.35 article earning citations for another quarter is the highest-ROI work in content marketing.

    Topic selection becomes everything. The difference between a $0.35 article that earns 4,000 citations and a $0.35 article that earns zero is topic-platform fit. Content operations need to get very good at identifying which topics will earn citations on which platforms before investing production resources.

    The moat is compounding authority. The early articles that establish citation authority create a flywheel that later articles benefit from. My domain’s Copilot authority — built through 98,800 citations over 90 days — means new articles I publish earn citations faster than they would on a domain starting from scratch. The economics improve over time for the first mover.

    The Uncomfortable Conclusion

    The unit economics of AI citation content are so favorable that they make most traditional content distribution strategies look wasteful by comparison. You could spend $50,000 on a content marketing program — writers, editors, designers, SEO tools, paid distribution — or you could spend $35 on 100 precisely targeted, AI-optimized articles and potentially generate more total reach through AI citations alone.

    The catch is that AI citations don’t (yet) convert the same way clicks do. You can’t track a citation to a sale the way you can track a PPC click to a purchase. The monetization model is still emerging.

    But the reach is real, the authority-building is real, and the compounding is real. And the cost to participate is $0.35 per article. The barrier to entry has never been lower. The question is whether your content operation is measuring what matters.

    Related on Tygart Media: 98,800 Copilot citations · 16,500 Copilot citations · citation economy.

    Frequently Asked Questions

    How can an article cost only $0.35?

    The $0.35 represents AI API costs for research, drafting, and optimization. It assumes a content operator using AI-assisted workflows who handles editorial judgment, fact-checking, and quality control themselves. Infrastructure costs like hosting and WordPress are sunk costs spread across the entire content operation.

    Are AI citations as valuable as clicks?

    They serve different functions. A click delivers a user to your site where you control the experience. A citation delivers your information to a user through an AI interface. Citations build brand authority at massive scale but lack direct conversion tracking. The long-term value likely accrues through brand recognition and downstream conversions.

    What is the ROI of AI citation content?

    Direct ROI measurement is still developing because citation-to-revenue attribution doesn’t exist yet. However, at $0.35 per article and thousands of citations per article for well-targeted topics, the cost per unit of reach is orders of magnitude lower than any traditional content channel.

    Does every article earn thousands of citations?

    No. Citation volume depends on topic-platform fit, content structure, and accuracy. Articles on topics that Copilot users ask about regularly can earn thousands of citations. Articles on topics that don’t match the platform’s user base earn zero. Topic selection is the primary variable.

    How often should AI citation content be updated?

    Content should be updated whenever the underlying facts change — especially pricing, version numbers, and feature availability. For fast-moving topics like AI tool pricing, monthly reviews are appropriate. Each update costs roughly $0.10 in API costs and preserves the citation authority the article has built.

  • Claude Pro vs Max: Is the $100 Upgrade Worth It? (2026)

    Claude Pro vs Max: Is the $100 Upgrade Worth It? (2026)

    Last verified: October 2, 2026 (Pacific).

    Claude Pro costs $20/month. Claude Max costs $100 or $200/month. The question everyone asks: is 5x or 20x the price actually worth it? The answer depends entirely on how you use Claude. This comparison breaks down the real differences — not the marketing bullet points — so you can make an informed decision.

    What Pro Gives You

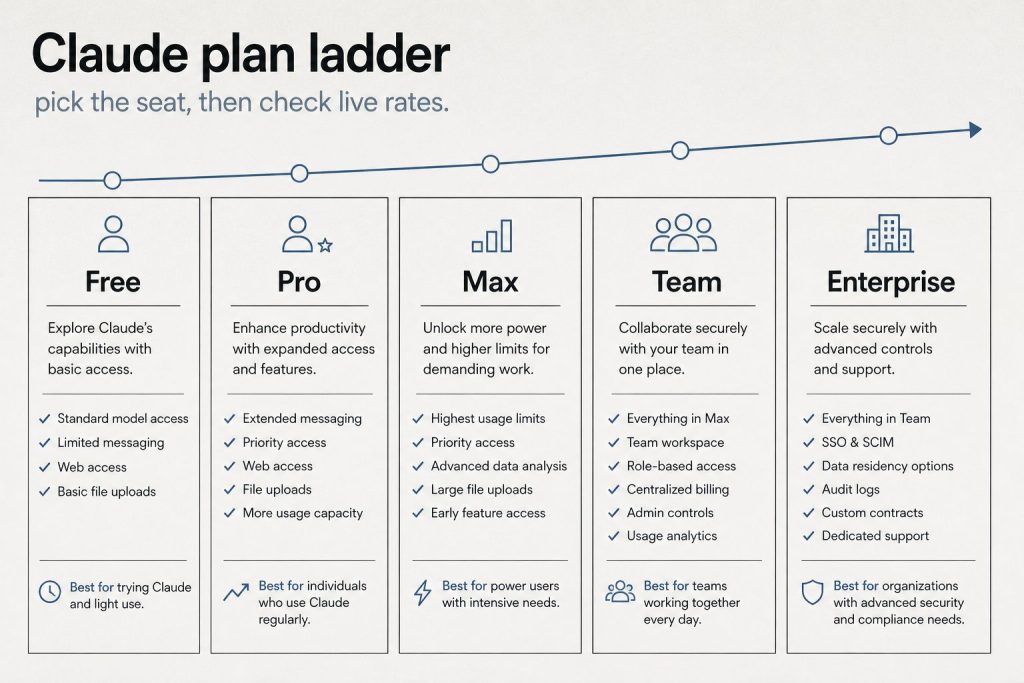
    Infographic ladder of Claude plans: Free, Pro, Max, Team, and Enterprise
    What Pro gives you — stale-proof.

    Pro at $20/month ($17/month annual) includes Claude Code, Claude Cowork, unlimited Projects, Research mode, access to additional models, and Claude for Microsoft 365 and Outlook. The usage allowance is described as “more usage” compared to Free — in practice, this means you can have sustained conversations throughout a workday without hitting limits under normal use. Most professionals who use Claude as a daily tool — a few hours of active conversation per day — find Pro sufficient.

    What Max Adds

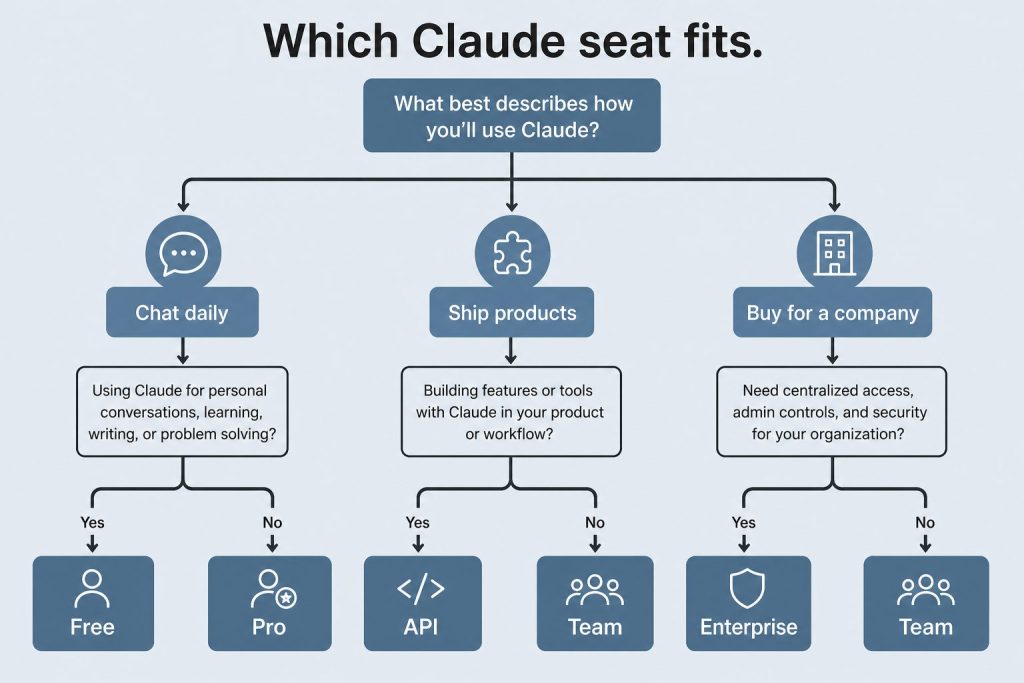
    Decision map from daily chat, shipping products, or buying for a company to Free/Pro, API, or Team/Enterprise

    What Max adds.

    Max comes in two tiers. The $100/month tier gives approximately 5x the usage of Pro. The $200/month tier gives approximately 20x. Beyond the usage multiplier, Max adds three concrete features: higher output limits for all tasks (longer responses, more complex code generation), early access to advanced Claude features before they reach Pro users, and priority access during high-traffic periods (you skip the queue).

    The Fable factor: Max’s real exclusive

    Direct answer: Max is now the only individual plan that includes Anthropic’s Fable models. On Pro, every Fable token runs on usage credits; on Max 5x and 20x, Fable is included up to half the weekly usage pool. If your work benefits from Fable — long-horizon agent loops with heavy cache reuse — this alone can decide the plan. Our Fable 5 pricing guide breaks down the $10/$50 headline rates and the 75% cache-read cut that Fable 5.1 brought on September 1.

    Who Actually Needs Max

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats

    Who actually needs Max.

    Heavy Claude Code users: If you spend 4+ hours per day actively using Claude Code for development — not just coding, but running extended agent sessions, multi-file refactoring, and complex debugging — you’ll likely hit Pro limits. Max 5x removes this friction. Content production teams: If you’re producing 10+ pieces of content per day through Claude, the usage adds up fast. Researchers and analysts: Extended research sessions with multiple deep-dive conversations consume significant tokens. Anyone who hits Pro limits regularly: If you see the “usage limit reached” message more than once or twice per week, Max pays for itself in recovered productivity.

    Who Should Stay on Pro

    Most individual professionals: If you use Claude for 1-3 hours per day with normal conversation patterns, Pro is plenty. Occasional users: If Claude is one of many tools in your workflow rather than the central one, Pro is more than enough. Budget-conscious users: At $20/month, Pro delivers extraordinary value. The jump to $100/month should be justified by measurable productivity gains. Users who haven’t hit Pro limits: If you’ve never seen the usage limit message, you don’t need Max.

    When you hit the wall: usage credits

    One newer mechanic worth knowing before you upgrade: when a paid plan hits its usage limit, usage credits keep Claude working at standard API rates instead of making you wait for the 5-hour reset window. Credits are pay-as-you-go on top of the subscription — the middle path for spiky weeks where one heavy project doesn’t justify a whole tier upgrade. If you hit Pro limits twice a month rather than twice a week, credits are usually cheaper than Max.

    The Math on Max

    Max 5x costs $80/month more than Pro. If that additional usage saves you 2+ hours per week of productivity (waiting for limits to reset, or time spent on tasks you could have delegated to Claude), and your time is worth $40+/hour, Max pays for itself. Max 20x at $200/month ($180 more than Pro) needs to save roughly 4.5 hours/week to break even at $40/hour. The early access and priority features are hard to quantify financially — they matter most for users who need Claude reliably during peak demand.

    A Better Strategy Than Max

    Before upgrading to Max, consider whether your usage patterns can be optimized on Pro. Use Projects to maintain context instead of repeating background in every conversation. Be concise in prompts — verbose prompts consume more tokens. Use the appropriate model (Haiku for simple tasks, Sonnet for standard work, Opus for complex reasoning). Close conversations you’re done with rather than continuing indefinitely. If you’re hitting limits despite these optimizations, Max is the right move.

    How Claude usage limits actually work

    Claude usage limits reset on a rolling five-hour window, and paid plans add weekly limits on top of that. There is no fixed number of messages.

    On claude.com/pricing, checked October 2, 2026, Free covers everyday questions. Pro includes at least 5x more usage per five-hour session than Free. Max includes 5x or 20x more usage per five-hour session than Pro. The Max card lists the plan from $100 per month and lets you choose the 5x or 20x option. Chat on the web, the desktop app, mobile, and Claude Code all draw from the same pool.

    What spends the allowance is the work itself. A longer conversation, a heavier model, file creation, or research uses more of the window than a short question. Anthropic also says it may apply weekly or monthly caps, or limits on a specific model or feature, so one account does not crowd out everyone else. On the plan table, Fable is unavailable on Free, listed as usage credits on Pro, and listed as 50% of weekly limits on both Max options.

    When a limit hits, the same page gives three moves: wait for the reset, move to a higher plan, or, on a paid plan, turn on usage credits and keep working at standard API rates. Settings, then Usage, shows the current status. Team seats use a different meter. A standard seat includes more usage than Pro, at $20 per seat per month billed annually or $25 billed monthly. A premium seat includes 5x the usage of a standard seat, at $100 per seat per month billed annually or $125 billed monthly.

    Pricing checked October 2, 2026. Source: claude.com/pricing.

    Claude API pricing, by model

    A Claude API bill is input tokens plus output tokens, and output costs more than input on every current model. Prices below are US dollars per million tokens. Pricing checked October 2, 2026.

    • Fable 5.1: $10 input, $50 output
    • Opus 5.5: $4 input, $20 output
    • Sonnet 5.5: $2 input, $10 output
    • Haiku 4.5: $1 input, $5 output

    The official table also lists older and retired models. Those rows are omitted here. Sonnet 5 is the same $2 input and $10 output as Sonnet 5.5, and Anthropic says the increase to $3 and $15 that had been scheduled for September 1, 2026 will not happen.

    The model and the length of the reply do most of the damage. Output is five times the input price on each model above, so an agent that writes a long diff costs more than one that only reads. Three other switches change the same rates. The Batch API takes 50% off input and output when the job can wait: Fable 5.1 batch is $5 and $25, Opus 5.5 is $2 and $10, Sonnet 5.5 is $1 and $5, and Haiku 4.5 is $0.50 and $2.50. US-only inference on Claude 4.6 and later multiplies input, output, cache writes, and cache reads by 1.1. Fast mode, still a research preview, prices Opus 5.5 at $8 input and $40 output, and Opus 5 or Opus 4.8 at $10 and $50. Fast mode does not run on the Batch API.

    Claude 4.6 and later include the full 1 million token context window at that same per-token rate. A 900,000-token request is billed at the same rate per token as a 9,000-token request. Claude 4.7 and later, and Mythos Preview, use a newer tokenizer that produces about 30% more tokens for the same text, so an unchanged document can cost more after a model move. Sonnet 4.6 and earlier use the previous tokenizer.

    Tools add their own lines. The pricing page lists web search at $10 per 1,000 searches, separate from the tokens used to process the request. Code execution includes 50 free hours a day per organization, then $0.05 per hour per container.

    Pricing checked October 2, 2026. Sources: Claude platform pricing and claude.com/pricing.

    When prompt caching saves money

    Prompt caching saves money when the same long prefix is sent again inside a short window. You pay extra to store that prefix, then a fraction of the normal input price each time a later request reads it.

    Anthropic’s docs, checked October 2, 2026, price a 5-minute cache write at 1.25 times the base input price and a 1-hour cache write at 2 times. A cache hit on most models costs 10% of the standard input price. The docs say 5-minute caching pays for itself after one cache read, and 1-hour caching pays for itself after two cache reads. Two current models are cheaper on the read: Fable 5.1 and Mythos 5.1 hits are $0.25 per million tokens, which is 2.5% of base input, and Opus 5.5 hits are $0.20 per million tokens, which is 5% of base input. On the standard table, a 5-minute write is $12.50 for Fable 5.1, $5 for Opus 5.5, $2.50 for Sonnet 5.5, and $1.25 for Haiku 4.5. A 1-hour write on those models is $20, $8, $4, and $2.

    The buyers who come out ahead repeat a prefix: a long system prompt, a tool list, a standing document, or an agent loop that reloads the same context every turn. A one-off short chat has nothing to reuse. Cache writes are charged when the prefix is first stored. Cache reads are charged when a later request retrieves it, and a read also refreshes the entry. Those multipliers stack with the Batch API discount and with the 1.1x US-inference multiplier.

    Pricing checked October 2, 2026. Source: Claude platform pricing.

    Claude, ChatGPT, and Gemini at comparable prices

    At the everyday paid chat tier, Claude Pro and ChatGPT Plus are both $20 a month. Above that, compare the usage multiple on the plan, and price the API separately from the subscription.

    Checked October 2, 2026. Claude lists Free at $0, Pro at $20 a month or $17 a month when $200 is billed up front for the year, and Max from $100 a month with a choice of 5x or 20x more usage than Pro per five-hour session. OpenAI’s Help Center lists ChatGPT Plus at $20 a month, billed monthly, and two Pro tiers: $100 for 5x the usage of Plus, and $200 for 20x the usage of Plus. The Plus article says API usage is billed separately. ChatGPT Go appears as a lower plan; a current Go dollar price was not on the pages read for this check.

    The meters differ even when the monthly price lines up. Claude draws web, desktop, mobile, and Claude Code from one pool, on a rolling five-hour window, with weekly limits added on paid plans. OpenAI’s Pro article says models can have separate allowances, and reaching one model’s allowance does not by itself end the plan. Pick the product whose limit matches the work.

    API rates below are the standard paid tier, in US dollars per million tokens, from the same October 2, 2026 check. Where a vendor publishes a short-context rate and a long-context rate, both are included.

    • Claude Haiku 4.5 is $1 input and $5 output. Sonnet 5.5 is $2 and $10. Opus 5.5 is $4 and $20. Fable 5.1 is $10 and $50. Claude 4.6 and later keep that per-token rate through a 1 million token context window.
    • On OpenAI’s standard tab, gpt-6-luna is $0.10 input and $0.50 output for short context, and $0.20 and $0.75 for long context. gpt-6.1-sol is $2 and $10 short, and $4 and $15 long. gpt-6-astra is $10 and $50 short, and $20 and $75 long. The same page also publishes Batch, Flex, Fast, and Ultrafast rates.
    • On Google’s Gemini API, standard paid, Gemini 3.8 Flash is $0.75 input and $3.75 output through December 31, 2026, then $1.50 and $7.50. Gemini 3.1 Pro Preview is $2 input and $12 output on prompts up to 200,000 tokens, and $4 and $18 above that. Gemini’s output price includes thinking tokens.

    The useful comparison is the shape of the bill. On all three, output tokens cost more than input tokens. OpenAI’s flagship models and Gemini 3.1 Pro Preview raise the per-token rate once a prompt crosses their long-context line. Claude’s current models keep one rate inside the 1 million token window. A repeated prefix is discounted on each platform under that platform’s own cache rules.

    Pricing checked October 2, 2026. Sources: claude.com/pricing, Claude API pricing, ChatGPT Plus, ChatGPT Pro tiers, OpenAI API pricing, and Gemini API pricing.

    Related on Tygart Media: Claude AI pricing guide · Fable 5 pricing, cache rates & plan access · Claude Code pricing 2026 · Claude Team pricing · How much does Claude cost.

    Frequently Asked Questions

    Is Claude Max worth $100 a month?

    If you regularly hit Pro usage limits — especially heavy Claude Code users, content producers, or researchers — Max pays for itself in recovered productivity. If you’ve never hit Pro limits, stay on Pro.

    What is the difference between Max 5x and Max 20x?

    Max 5x ($100/month) gives 5x the usage of Pro. Max 20x ($200/month) gives 20x. Both include higher output limits, early feature access, and priority. Most users who need Max find 5x sufficient.

    Can I switch between Pro and Max?

    Yes. You can upgrade from Pro to Max or downgrade from Max to Pro at any time. Changes take effect on the next billing cycle.

    Does Max include Claude Code?

    Yes. Both Pro and Max include Claude Code. Max gives you more usage capacity for Claude Code sessions.

    Does Claude Max include Fable?

    Yes — Max is the only individual plan that includes Fable models, up to 50% of the weekly usage pool. On Pro, Fable usage runs on usage credits from the first token.

    What are Claude usage credits?

    Pay-as-you-go tokens billed at standard API rates that keep you working when a paid plan hits its limit, instead of waiting for the reset window. Ideal for occasional spike weeks.

    Can I pay for Max annually?

    No. Max 5x and Max 20x are monthly billing only. Pro is the plan with an annual option — $17/month billed yearly ($200 up front).


    Manage it all from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator for your actual usage.

  • Claude for Content Creation: How to Use AI for Writing, SEO, and Marketing in 2026

    Claude for Content Creation: How to Use AI for Writing, SEO, and Marketing in 2026

    Claude has become a core tool for content teams — not as a replacement for human writers, but as a force multiplier that changes what’s possible with limited resources. This guide covers the practical workflows that professional content creators, SEO specialists, and marketing teams use with Claude in 2026, including where it excels, where it falls short, and how to integrate it into a production content operation.

    Blog Posts and Long-Form Content

    Four cards for content, ops, build, and knowledge work with Claude
    Blog posts and long-form with Claude.

    Claude excels at drafting long-form content when given proper direction. The key is providing a detailed brief — not just a topic, but the target keyword, the audience, the desired structure, the tone, competing content to differentiate from, and any specific data or examples to include. A well-briefed Claude request produces a first draft that’s 70-80% of the way to publishable, versus a vague request that produces generic filler.

    Best practices for blog production: write a content brief first (or use Claude to help write one), include your brand voice guidelines in a Project, specify the exact structure you want (H2s and H3s), request specific word counts, and always edit the output for accuracy, originality, and brand alignment. Never publish AI-generated content without human review — this is especially important for factual claims, statistics, and technical accuracy.

    SEO Content Optimization

    Comparison of Claude how-to fit versus local service page fit for assistants
    SEO content optimization workflows.

    Claude can analyze existing content for SEO improvements — identifying missing keywords, suggesting heading structure changes, improving meta descriptions, and recommending internal linking opportunities. Feed Claude your target keyword, your current content, and competitor content, and ask for specific optimization recommendations. Claude can also generate FAQ sections with structured data markup, which directly targets featured snippets and People Also Ask placements.

    For new content, Claude can research keyword clusters, identify search intent, and draft content structured for both traditional SEO and emerging AI search optimization (AEO/GEO). The combination of web search capability and content generation means Claude can research a topic and draft optimized content in a single session.

    Email Marketing

    Claude handles email marketing content effectively — subject line variations, body copy, CTAs, and nurture sequences. The workflow that works best: share your product/service details and audience information in a Project, then request specific email types (welcome sequence, promotional, re-engagement, newsletter). Claude can generate multiple variations for A/B testing and adapt tone for different segments.

    Social Media Content

    Claude can repurpose long-form content into social media posts tailored for different platforms — LinkedIn articles and thought leadership posts, Twitter/X threads, Instagram captions, and Facebook updates. Provide the source content and specify the platform, tone, and any hashtag or formatting requirements. Claude adapts naturally between professional (LinkedIn), conversational (Twitter), and visual-caption (Instagram) styles.

    Content Strategy and Planning

    Three cards for LSA, search ads, and SEO/AI authority channels
    Content strategy and planning.

    Beyond individual pieces, Claude can help with content strategy — editorial calendar planning, content gap analysis, persona development, and competitive content auditing. Upload your existing content inventory, share your business goals and target audience, and ask Claude to identify gaps, suggest topics, and prioritize based on potential impact. This is especially powerful with web search enabled, allowing Claude to analyze competitor content in real-time.

    Quality Control and Accuracy

    AI-generated content requires human quality control. Every piece should be checked for factual accuracy (especially statistics, dates, and specific claims), brand voice consistency, originality (run through plagiarism detection), legal compliance (disclaimers, disclosures), and genuine value to the reader. The biggest risk with AI content is not that it’s bad — it’s that it’s competent but generic. Human editors should push for the specific insights, examples, and perspectives that make content genuinely useful rather than just technically correct.

    Related on Tygart Media: beginner prompting · Claude for business.

    Frequently Asked Questions

    Can Claude write SEO content?

    Yes. Claude can draft keyword-optimized content, generate meta descriptions, create FAQ sections with schema markup, and analyze content for SEO improvements. Human review for accuracy and originality is essential.

    Should I use Claude to write my entire blog?

    Use Claude as a drafting and optimization tool, not a hands-off content factory. The best results come from human-directed Claude drafts that are then edited for accuracy, brand voice, and genuine insight.

    Can Google detect AI-written content?

    Google has stated it focuses on content quality regardless of how it’s produced. The key is creating content that’s helpful, accurate, and provides genuine value — whether written by humans, AI, or both.

    How much content can Claude produce per day?

    On a Pro plan, a content professional can realistically produce 5-10 well-researched, edited articles per day with Claude assistance — compared to 1-2 without it. The bottleneck shifts from writing to editing and quality control.

  • Claude MCP (Model Context Protocol): What It Is, How It Works, and Why Developers Care

    Claude MCP (Model Context Protocol): What It Is, How It Works, and Why Developers Care

    Model Context Protocol (MCP) is an open standard created by Anthropic that lets Claude connect to external tools, data sources, and services. Instead of copying data into Claude manually, MCP gives Claude structured access to the tools you already use — databases, APIs, project management platforms, file systems, and more. MCP has become one of the most important developments in the AI ecosystem in 2026, and understanding it is increasingly essential for developers and technical teams.

    What MCP Actually Does

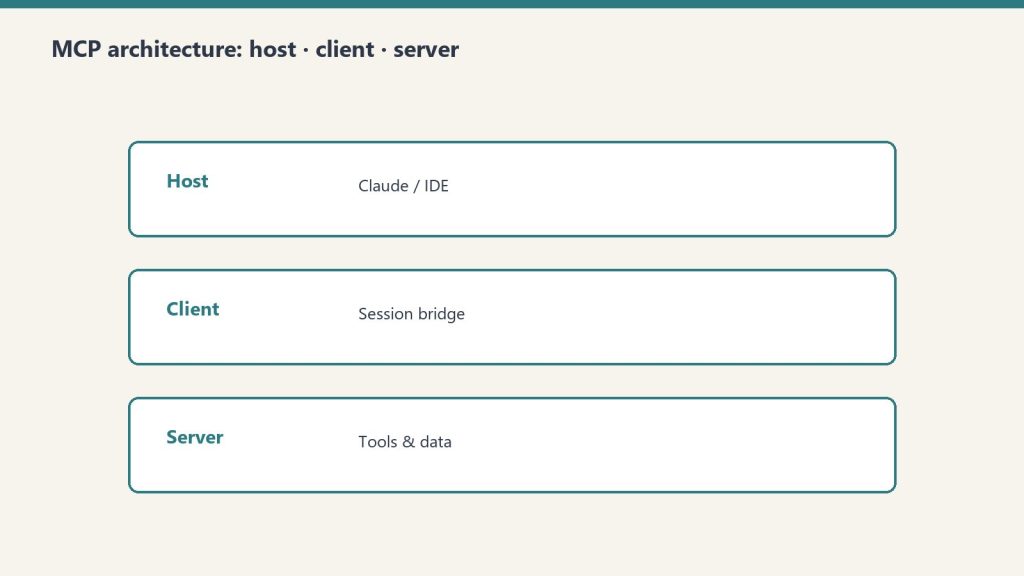
    Three-layer MCP architecture: host, client, server
    What MCP actually does — hosts, clients, servers.

    At its core, MCP is a protocol — a standardized way for AI models to communicate with external services. Think of it like how HTTP standardized web communication or how SQL standardized database queries. MCP standardizes how AI assistants request and receive data from external tools. Before MCP, connecting Claude to a database required custom integration code. With MCP, you configure an MCP server that speaks the protocol, and Claude can query the database through that server using a standardized interface.

    The Architecture: Hosts, Clients, and Servers

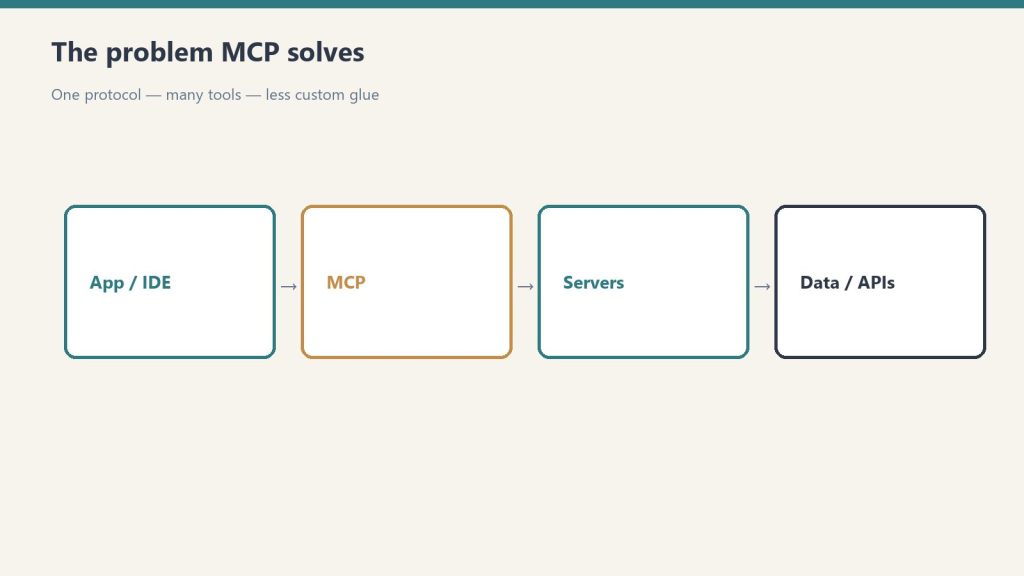
    Flow from app/IDE through MCP to servers and data APIs
    Architecture: hosts, clients, and servers.

    MCP has three components. The host is the application where Claude runs (the desktop app, Claude Code, or a custom application). The client is the MCP client built into Claude that manages connections to MCP servers. The server is the service that provides tools, data, or capabilities to Claude. MCP servers expose three types of primitives: tools (actions Claude can take, like querying a database or creating a Jira ticket), resources (data Claude can read, like file contents or documentation), and prompts (pre-built interaction patterns).

    Practical Examples

    A Notion MCP server lets Claude read and write Notion pages and databases directly. A PostgreSQL MCP server lets Claude query your database. A Slack MCP server lets Claude read channels and send messages. A GitHub MCP server lets Claude interact with repositories, issues, and pull requests. A Sentry MCP server lets Claude access error tracking and debugging data. These aren’t hypothetical — they’re production tools that teams use daily.

    Local vs Remote MCP Servers

    MCP servers can run locally on your machine or remotely as hosted services. Local MCP servers run alongside the Claude desktop app and have access to your local environment — file system, local databases, development tools. They use the stdio transport (standard input/output) and require no network configuration. Remote MCP servers run as web services and are accessed over the network using Streamable HTTP or Server-Sent Events (SSE) transports. Remote servers can be shared across teams and don’t require local installation.

    Token Cost Considerations

    An important practical consideration: MCP tools add tokens to every conversation turn. Each configured MCP server’s tool descriptions are included in Claude’s context, consuming input tokens. If you have 10 MCP servers with 5 tools each, that’s 50 tool descriptions included in every request — potentially thousands of tokens per turn. Best practices include only connecting the MCP servers you actively need, using scoped configurations to limit which tools are available in which contexts, and monitoring your token usage to identify MCP-related costs.

    Why Developers Care

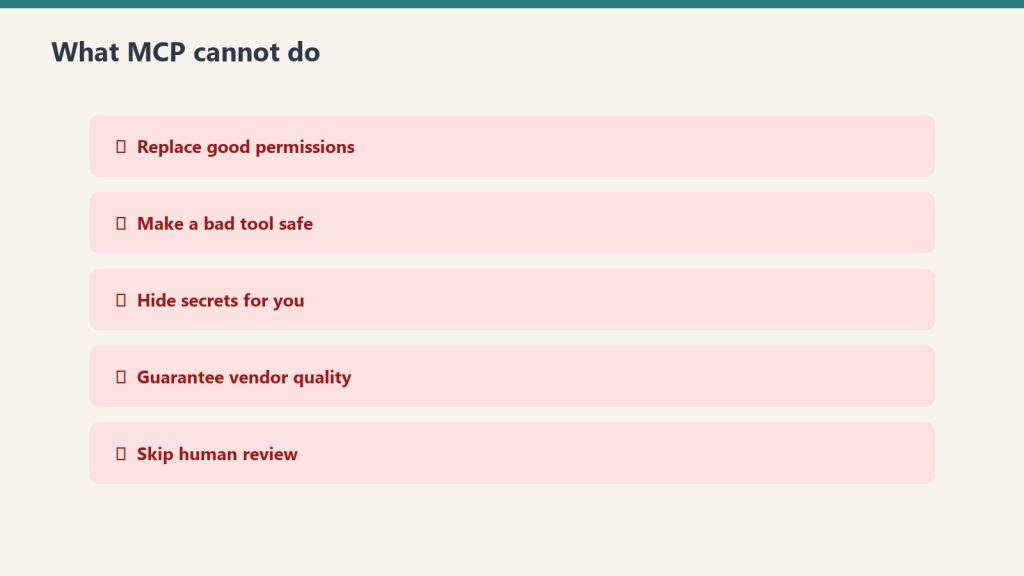
    Five red warning rows of MCP limitations
    Why developers care — less custom glue.

    MCP matters because it transforms Claude from a standalone chatbot into a connected agent. Without MCP, Claude can only work with information you paste into the conversation. With MCP, Claude can pull real-time data, take actions in external systems, and operate as part of your existing toolchain. For development teams, MCP means Claude Code can interact with your entire development stack — version control, CI/CD, error tracking, documentation, project management — through a single standardized interface.

    Getting Started with MCP

    The fastest path is to install a pre-built MCP server for a tool you already use. The Claude desktop app’s settings include MCP server configuration. Add a server definition (the server command and its arguments), restart Claude, and the tools become available in your conversations. For custom integrations, Anthropic provides SDKs for building MCP servers in Python and TypeScript. The MCP specification is open — anyone can build a server for any tool.

    Related on Tygart Media: what is MCP · Skills vs MCP · how to use Claude.

    Frequently Asked Questions

    What is Claude MCP?

    MCP (Model Context Protocol) is an open standard that lets Claude connect to external tools and data sources — databases, APIs, file systems, and more — through a standardized interface.

    Is MCP free to use?

    MCP itself is free and open. MCP servers may be free (open source) or paid (commercial). The token costs from MCP tool descriptions are included in your regular Claude usage or API billing.

    Do I need to be a developer to use MCP?

    Basic MCP server setup requires some technical comfort — editing configuration files and running commands. Pre-built connectors in the Claude interface are simpler. Building custom MCP servers requires programming knowledge.

    Can MCP be used with other AI models?

    MCP is an open protocol. While Anthropic created it for Claude, other AI platforms and tools have begun adopting MCP as a standard for tool integration.

  • Anthropic Safety and Alignment: Why Claude Is Built Differently and What It Means for Users

    Anthropic Safety and Alignment: Why Claude Is Built Differently and What It Means for Users

    Anthropic is an AI safety company that happens to build a product, not a product company that happens to care about safety. That distinction matters. Every design decision in Claude — from how it handles sensitive topics to how it processes your data — traces back to Anthropic’s safety-first philosophy. This guide explains what that philosophy is, how it works in practice, and what it means for you as a user.

    Constitutional AI: How Claude Learns to Behave

    Five security domains: identity, data, code governance, audit, agents
    Constitutional AI — how Claude learns to behave.

    Claude is trained using a methodology called Constitutional AI (CAI). Instead of relying solely on human feedback to determine what’s helpful and harmless, Claude is given a set of principles — a “constitution” — that guides its behavior. These principles cover helpfulness, harmlessness, and honesty. During training, Claude evaluates its own outputs against these principles and self-corrects. This produces more consistent behavior than pure human feedback, which can be noisy and contradictory.

    In practice, this means Claude tends to be thoughtful about edge cases, transparent about uncertainty, and willing to push back when a request might lead to harmful outcomes — while still being maximally helpful within safe boundaries.

    The Responsible Scaling Policy

    Three stacked layers: chat UI, tools, agent runtime
    Responsible Scaling Policy.

    Anthropic’s Responsible Scaling Policy (RSP) is a framework that ties safety testing to capability levels. As models become more capable, the RSP requires more rigorous safety evaluations before deployment. The policy defines specific capability thresholds and the safety measures required at each level. This means Anthropic won’t release a model that’s significantly more capable without also implementing significantly more safety infrastructure. The RSP has been publicly documented and updated as the company has learned from deployments.

    Interpretability Research

    Anthropic invests heavily in interpretability — the science of understanding what happens inside neural networks. While most AI companies treat their models as black boxes, Anthropic’s research team publishes work on identifying how models store and process information, what individual neurons and circuits represent, and how to detect when a model might be reasoning in unexpected ways. This research directly informs safety work: if you can see inside the model, you can better identify and prevent harmful behavior.

    Data Handling and Privacy

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Data handling and privacy.

    Anthropic’s data handling practices reflect its safety orientation. On Free and Pro plans, users can opt out of having their data used for model training. On Team and Enterprise plans, content is not used for training by default — this is an opt-out-by-default approach, not opt-in. Enterprise plans add custom data retention controls, so organizations can specify exactly how long their data is stored. The HIPAA-ready Enterprise option provides additional safeguards for healthcare data.

    Corporate Structure as Safety Mechanism

    Anthropic’s public benefit corporation (PBC) structure and Long-Term Benefit Trust (LTBT) are designed as institutional safeguards. The PBC structure legally requires balancing profit with public benefit. The LTBT can intervene if the company’s actions deviate from its safety mission. These aren’t just statements of intent — they’re legal mechanisms with real enforcement power.

    What This Means for Users

    For individual users, Anthropic’s safety approach means Claude is less likely to produce harmful, misleading, or biased content. It’s more transparent about what it doesn’t know. It handles sensitive topics with care rather than either refusing entirely or engaging recklessly. For business users, it means enterprise-grade security features, data handling that meets regulatory requirements, and a vendor whose incentive structure is aligned with long-term reliability rather than short-term growth at any cost.

    Related on Tygart Media: Dario Amodei · is Claude safe · invisible agent layer.

    Frequently Asked Questions

    What is Constitutional AI?

    Constitutional AI is Anthropic’s training methodology where Claude is given a set of principles (a “constitution”) and learns to evaluate and correct its own outputs against those principles, producing more consistent helpful and safe behavior.

    Does Claude use my data for training?

    On Free/Pro plans, you can opt out. On Team and Enterprise plans, your data is not used for training by default.

    Why does Claude sometimes refuse requests?

    Claude’s safety training teaches it to decline requests that could lead to harmful outcomes. It aims to be maximally helpful within safe boundaries. If Claude refuses something you think is reasonable, you can rephrase or provide more context.

    Is Anthropic more safety-focused than OpenAI?

    Anthropic was founded specifically as an AI safety company and has embedded safety into its corporate structure through PBC status and the LTBT. Both companies invest in safety, but Anthropic’s organizational design makes safety central rather than supplementary.

  • Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Actually Compare

    Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Actually Compare

    If you’re evaluating Claude AI, you’re probably also looking at the alternatives. The AI assistant market in 2026 has matured — each major platform has developed distinct strengths rather than trying to be identical. This guide compares Claude against ChatGPT, Gemini, Perplexity, Grok, Microsoft Copilot, and other options on the metrics that actually matter: pricing, capability, reliability, and fit for specific use cases.

    Claude vs ChatGPT

    Four cards comparing ChatGPT, Gemini, Perplexity, and Copilot by job
    Compare alternatives by job — start with Claude vs ChatGPT.

    The most common comparison. Both offer free tiers and $20/month Pro/Plus plans. Claude’s strengths are long-form writing quality, instruction following, code generation with Claude Code, and the 1M token context window. ChatGPT’s strengths are its ecosystem (plugins, GPT store, DALL-E integration), broader brand recognition, and strong general-purpose capabilities. For developers, the choice often comes down to Claude Code vs ChatGPT’s code interpreter and canvas features. For writers, Claude generally produces more nuanced, less formulaic output. API pricing is competitive between the two platforms at comparable model tiers.

    Claude vs Google Gemini

    Four cards for content, ops, build, and knowledge work with Claude
    Claude vs Gemini — different strengths, different seats.

    Gemini’s key advantage is integration with the Google ecosystem — Gmail, Docs, Drive, Search, and Google Workspace. If your organization runs on Google, Gemini fits naturally into existing workflows. Claude’s advantages are stronger reasoning on complex tasks, better code generation, and more robust enterprise features (SCIM, audit logs, HIPAA). Gemini offers a generous free tier and is deeply integrated into Android. Claude is available on Google Cloud through Vertex AI, so organizations can use both within the Google ecosystem.

    Claude vs Perplexity

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Claude vs Perplexity — research seat vs general assistant.

    Perplexity occupies a different niche — it’s primarily a search and research tool, not a general-purpose assistant. Perplexity excels at answering factual questions with cited sources, making it excellent for research and fact-checking. Claude is better for creative work, coding, analysis, and extended projects. Many professionals use both: Perplexity for research and fact-finding, Claude for drafting, analysis, and execution.

    Claude vs Microsoft Copilot

    Microsoft Copilot (powered by OpenAI) is embedded throughout Microsoft 365 — Word, Excel, PowerPoint, Teams, Outlook. If your organization is Microsoft-centric, Copilot has the integration advantage. However, Claude now offers Claude for Microsoft 365 and Outlook, giving it a presence in the Microsoft ecosystem as well. For standalone AI capabilities, Claude generally outperforms Copilot in reasoning, writing quality, and code generation.

    Claude vs Grok

    Grok, built by xAI, is integrated with the X (formerly Twitter) platform and has access to real-time social media data. Grok’s strength is current events and social sentiment analysis. Claude’s strengths are safety, reliability, enterprise features, and broader use case coverage. Grok appeals to users who want an AI with a less restricted personality and real-time social context.

    Pricing Comparison

    Free tiers: Claude, ChatGPT, Gemini, Perplexity, and Copilot all offer free access. Individual paid plans: Claude Pro $20/month, ChatGPT Plus $20/month, Gemini Advanced $19.99/month (often bundled with Google One), Perplexity Pro $20/month. Claude’s Max plan ($100-200/month) has equivalents in ChatGPT Pro ($200/month). At the API level, pricing varies by model class but is broadly competitive across major providers.

    How to Choose

    Choose Claude if you prioritize writing quality, code generation, enterprise security, and long-context processing. Choose ChatGPT if you want the broadest ecosystem of plugins and integrations. Choose Gemini if you’re deep in the Google ecosystem. Choose Perplexity if your primary need is research with cited sources. Choose Copilot if Microsoft 365 integration is your top priority. Many organizations use multiple AI tools — they’re not mutually exclusive.

    Related on Tygart Media: Claude alternatives · Claude vs Perplexity · is Claude worth it.

    Frequently Asked Questions

    Is Claude AI better than ChatGPT?

    Claude excels at long-form writing, instruction following, and code generation. ChatGPT has a larger ecosystem of plugins and integrations. Neither is universally “better” — the right choice depends on your use case.

    What is the best free AI chatbot in 2026?

    Claude, ChatGPT, and Gemini all offer strong free tiers. Claude’s free tier is notable for including web search, code execution, memory, and extended thinking at no cost.

    Can I use Claude and ChatGPT together?

    Yes. Many professionals use multiple AI tools for different tasks. At the API level, platforms like OpenRouter let you route requests to different models based on the task.

    Which AI has the largest context window?

    As of June 2026, both Claude (Opus and Sonnet) and Gemini support 1M+ token context windows. Claude’s 1M context is available at flat-rate pricing with no surcharge.


    >Part of the complete guide: Claude vs the Field

  • How Smart TV Advertising Predicted AI Content Strategy

    How Smart TV Advertising Predicted AI Content Strategy

    A Lesson Advertisers Learned (That Marketers Forgot)

    In the early 2000s, smart TV advertising was a mess. Media buyers would take a 30-second TV spot — optimized for lean-back, passive viewing — and run it on every screen: broadcast TV, connected TV, desktop pre-roll, mobile interstitials, and later, smart TV apps. Same creative. Different screens. Predictably terrible results.

    It took the advertising industry about a decade to figure out what seems obvious in retrospect: different screens serve different audiences in different contexts, and the creative has to match.

    A smart TV viewer is on the couch, relaxed, 10 feet from the screen. A mobile user is commuting, distracted, holding the phone 12 inches from their face. A desktop user is at work, focused, multitasking. The same 30-second spot that stops a TV viewer cold gets skipped on mobile because the hook takes too long. The same mobile-first vertical video looks absurd on a 55-inch smart TV.

    Once advertisers internalized this, the industry restructured. Creative teams started building platform-specific versions from the ground up. Media strategies segmented by screen. Measurement tracked performance by device, by platform, by context. The unified “TV commercial” became an artifact. In its place: a matrix of screen-specific creative, each optimized for its audience.

    Content strategy for AI is exactly where TV advertising was in 2005. And most people don’t see it yet.

    AI Platforms Are the New Screens

    Two cards: answer shown in overview versus optional click
    AI platforms are the new screens.

    The analogy maps precisely:

    PlatformScreenHow people use itWhat content wins
    Microsoft CopilotSmart TV (built into a device people already own)Embedded in Microsoft 365, the platform people already use for work. Users aren’t seeking it out; it’s there when they need it.Lean-back reference material: structured, specific, ready to surface without the user leaving their workflow.
    ChatGPTLaptop/desktopUsers go there deliberately, open a session, and engage actively: leaning forward, exploring, asking follow-up questions.Detailed, nuanced, conversation-worthy content, the equivalent of long-form desktop video that rewards active attention.
    PerplexityCurated feedSynthesizes the best sources into a clean answer with citations, like a personalized news feed or a curated newsletter.Authoritative, primary content: the source a discerning editor would choose as the definitive reference.
    Google AI OverviewsPre-rollAppear before the organic results, like a pre-roll ad before a YouTube video, capturing attention at the top of the funnel.Content formatted for instant extraction: concise definitions, direct answers, structured lists that can be repurposed into a summary.
    Google organic searchBroadcast TVStill the largest audience, the broadest reach, and the most competitive, but no longer the only screen that matters.SEO structure built to rank for keyword searches.

    My data shows the Copilot fit: 98,800 citations from enterprise users who never left Word or Edge.

    The audiences, by the numbers (as of October 2026)

    Copilot: Microsoft said Microsoft 365 Copilot reached over 30 million paid seats in its fiscal fourth-quarter results (July 29, 2026).

    ChatGPT: OpenAI said at DevDay that ChatGPT now has 1.2 billion weekly users, up from 1 billion in July (The Verge, September 29, 2026).

    Perplexity: CEO Aravind Srinivas said Perplexity received 780 million queries in May 2025, with more than 20% month-over-month growth (TechCrunch, June 5, 2025).

    Google AI Overviews: Alphabet said AI Overviews now have over 2.5 billion users each month (investor presentation, June 3, 2026).

    These are different measures (paid seats, weekly users, monthly queries, monthly users), so they don’t compare head to head. That’s the same reason to measure each platform separately.

    The Creative Matrix for AI Content

    Comparison of Claude how-to fit versus local service page fit for assistants
    The creative matrix for AI content.

    Just as an ad agency now produces a creative matrix — smart TV version, mobile version, desktop version, social version — a content operation needs to produce a content matrix for AI platforms.

    Let me show how this works with a real example. I publish content about Claude AI pricing. Here’s how that single topic gets treated differently for each platform:

    Copilot version: Clean pricing table. Plan names, model names with version numbers, input/output token costs, monthly subscription prices. Minimal narrative. Maximum structure. This is the version that earns 16,500 citations because Copilot users need a number, not a story.

    ChatGPT version: 2,000-word analysis of Claude’s pricing strategy. How the tiers compare to OpenAI’s pricing. What the model costs mean for different use cases. Total cost of ownership calculations. Strategic framing for business decision-makers.

    Perplexity version: The definitive, comprehensive, most-current pricing reference on the internet. Updated within days of any price change. Formatted so Perplexity can cite specific numbers with confidence. The page that makes other sources unnecessary.

    Google version: SEO-optimized comparison page. “Claude AI Pricing 2026” in the title. FAQ schema. Clean headings. First paragraph answers the query directly. Designed to rank for keyword searches.

    In practice, some of these treatments can coexist in a single article. My highest-performing pages layer narrative depth (for ChatGPT and human readers) on top of structured data tables (for Copilot extraction) with FAQ sections (for Google snippets and AEO). But the intentionality matters — you have to design for each screen, not just hope one version works everywhere.

    What the Ad Industry Learned That Content Strategy Hasn’t

    The advertising industry’s transition to screen-specific creative taught several lessons that apply directly to AI content strategy:

    The generalist loses. The brand that ran the same spot everywhere got outperformed by the brand that optimized for each screen. In content, the operation that writes one article and publishes it hoping all AI platforms cite it will be outperformed by the operation that tailors content for each platform’s audience.

    Measurement has to segment by platform. Ad performance makes no sense when aggregated across all screens. A campaign that crushed on mobile but bombed on CTV looks mediocre in aggregate. The same is true for AI content: if you’re measuring “AI visibility” as a single metric, you’re missing the fact that your Copilot performance might be exceptional while your ChatGPT performance is zero.

    The production model has to change. When TV went from one-spot-fits-all to screen-specific creative, production workflows had to adapt. Agencies started shooting with multiple formats in mind. Content operations need the same evolution: write with multiple AI platforms in mind from the start, not as an afterthought.

    The early movers win disproportionately. The brands that figured out smart TV creative early locked in audience relationships and platform partnerships that late movers couldn’t replicate. In AI content, the publishers that build platform-specific citation authority now are building a moat. My Copilot citation flywheel — 672 daily citations growing to 5,500 — is the content equivalent of early smart TV audience lock-in.

    Why Content Operations Are Behind

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Why content operations are behind.

    The advertising industry had a structural advantage: media buyers were already thinking in terms of channels, audiences, and platforms. When new screens emerged, the mental model of “different creative for different channels” was already established. They just had to apply it to a new channel.

    Content marketing has operated under a different mental model: “publish great content and let search engines distribute it.” For twenty years, this meant one distribution channel (Google) with one optimization framework (SEO). The idea that you might need platform-specific content strategies for AI engines is foreign to most content operations because they’ve never had to think about distribution as a multi-platform problem.

    That’s changing. The data is forcing it. When you can see in Bing Webmaster Tools that your enterprise tool content earns 5,500 daily Copilot citations while your local content earns zero, the multi-platform nature of AI distribution becomes undeniable. And once you accept that AI platforms are different audiences, the advertising industry’s decades of screen-specific creative become your playbook.

    Building the Platform-Specific Content Operation

    Diagram: one article branching into four answer layers for Copilot, ChatGPT, Perplexity and Google
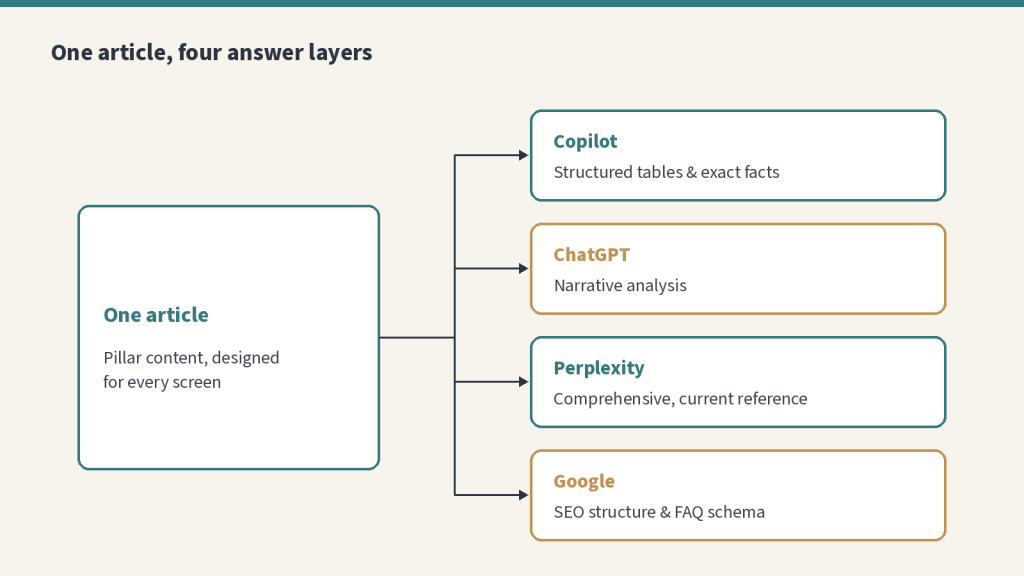
    Structure for multiple audiences in one article.

    Here’s what the transition looks like, based on what I’m building right now:

    Audit by platform. Check your Bing AI Performance data. Manually test your key topics in ChatGPT, Perplexity, and Claude. Build a map of which content earns citations where.

    Segment your content calendar. Assign platform targets to each piece of content. “This pricing guide is optimized for Copilot extraction.” “This thought leadership piece is optimized for ChatGPT depth.” “This reference page is optimized for Perplexity authority.”

    Structure for multiple audiences in one article. Your best content should layer: structured data for Copilot, narrative depth for ChatGPT, definitive authority for Perplexity, and keyword optimization for Google. Not every piece needs all four, but your pillar content should.

    Measure separately. Track Copilot citations in Bing Webmaster Tools. Track ChatGPT referral traffic in analytics. Test Perplexity visibility manually. Don’t aggregate these into one “AI performance” number — they’re different audiences and need different metrics.

    The ad industry spent a decade learning that one creative doesn’t fit all screens. The content industry can learn the same lesson faster — because the data is available today, and the playbook has already been written by someone else.

    For Agency Media Buyers: What Happens After the Spot Airs

    If you buy TV for a living, here’s the part of the funnel that changed under your feet. A viewer sees your client’s spot, picks up a phone or opens a laptop, and asks a question. Increasingly that question goes to ChatGPT, Copilot, Perplexity, or a Google AI Overview instead of a plain search box. “Is this brand any good?” “What’s the best option in this category?” “Who else does this?”

    The assistant answers in a sentence or two, and it names whoever it can actually read and trust. Sometimes that’s your client. Sometimes it’s a competitor that never bought a single spot. Your reach and frequency can be perfect, and the demand the campaign created can still leak to whoever the AI cites at the moment of follow-up.

    It’s the same screen-specific lesson from earlier in this piece, one step later in the funnel. The TV creative does its job. Then the answer layer decides who gets the credit. Three things matter there:

    Whether the brand gets cited. Run the questions a viewer would ask after the spot and see which names come back, platform by platform.

    Whether answer-ready content exists. Pages that answer the brand and category questions directly — clear definitions, specific facts, FAQ structure — are what assistants extract and cite.

    Whether it’s measured separately. Citation visibility is its own metric, tracked per platform, not a line folded into search or brand lift. Here’s how I think about what a citation is worth.

    That’s where Tygart Media fits. We don’t buy your airtime, and we don’t make the spot. We make sure that when the spot sends people to an AI assistant, your client is the answer it gives. That starts with a citation scan — where AI cites the brand today, where it doesn’t, and who it cites instead — and moves into rebuilding the pages AI pulls its answers from, using the same methodology behind this site’s own citation numbers.

    Running a TV campaign and want to know what AI says when viewers go looking? Tell us about it, and we’ll tell you honestly whether we can help.

    Related on Tygart Media: different AI audiences · SEO vs GEO vs AEO · citation economy.

    Sources:

    • Microsoft, “Microsoft Cloud and AI strength fuels fourth quarter results,” July 29, 2026. news.microsoft.com
    • The Verge, “ChatGPT now has 1.2 billion weekly users, OpenAI says,” September 29, 2026. theverge.com
    • TechCrunch, “Perplexity received 780 million queries last month, CEO says,” June 5, 2025. techcrunch.com
    • Google (The Keyword), “Alphabet investor presentation: June 2026,” June 3, 2026. blog.google

    Frequently Asked Questions

    How is AI content like advertising?

    Just as advertisers create different creative for smart TV, mobile, desktop, and social media, content operations need platform-specific approaches for Copilot, ChatGPT, Perplexity, and Google. Each platform serves a different audience in a different context with different needs.

    Can one article serve all AI platforms?

    Yes, with intentional layering. A single article can include structured data tables for Copilot extraction, narrative depth for ChatGPT engagement, authoritative sourcing for Perplexity citation, and keyword optimization for Google rankings. The key is designing for all audiences from the start.

    What does platform-specific content measurement look like?

    Track Copilot citations in Bing Webmaster Tools AI Performance tab. Monitor ChatGPT referral traffic in Google Analytics. Test Perplexity visibility by manually searching your topics. Measure each platform separately rather than aggregating into one AI performance number.

    Which AI platform should I prioritize?

    It depends on your audience. Enterprise and technology content should prioritize Copilot because its user base is knowledge workers mid-task. Consumer and research content may perform better on ChatGPT. Use the topic-platform fit matrix to determine where your content has the highest citation potential.

    How did smart TV advertising change production workflows?

    Agencies shifted from one-spot-fits-all to shooting with multiple formats in mind from the start. Content operations need the same evolution: plan content with multiple AI platform audiences in mind during the writing process, not as a post-publish optimization.

  • Your Website Is Being Read by AI More Than Humans — Here’s the Data

    Your Website Is Being Read by AI More Than Humans — Here’s the Data

    The Invisible Majority of Your Readership

    Four ranked rows of AI crawler fleets reading publisher content
    The invisible majority of your readership — AI crawlers.

    For every human who clicks on one of my articles from Bing search results, Microsoft Copilot cites that same content 52 times. Not reads. Not impressions. Citations — instances where an AI engine uses my content as the grounding source for a response delivered to a real user.

    The numbers: 98,800 AI citations from Copilot. Roughly 1,900 human clicks from Bing. Same time period. Same domain. Same content.

    And here’s what makes this disorienting: I can see the AI citations in Bing Webmaster Tools. But my Google Analytics, my heatmaps, my session recordings, my conversion tracking — none of it registers the 98,800 AI interactions. As far as my analytics stack is concerned, those readers don’t exist.

    The largest audience consuming my content is invisible to every measurement tool I’ve used for the past decade.

    How We Got Here Without Noticing

    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    How we got here without noticing.

    The shift happened gradually, then all at once. Microsoft shipped Copilot in Microsoft 365 to hundreds of millions of enterprise seats. Google rolled out AI Overviews to every search user. ChatGPT launched its search feature. Perplexity grew to millions of daily users. Claude’s user base expanded.

    Each of these platforms consumes web content to generate responses. They crawl, index, and cite websites — not to send traffic, but to build the source material for AI-generated answers. Your content becomes the foundation of an AI response that gets delivered to a user who may never know your site exists and will certainly never show up in your analytics.

    The scale is enormous. Microsoft alone has over 400 million Copilot users across its products. If even a fraction of their queries trigger content citations, the total volume of AI-mediated content consumption dwarfs traditional search clicks for many content categories.

    My 52:1 ratio might be extreme because my content is heavily skewed toward AI tools — a topic that Copilot users ask about frequently. But even for more general content categories, the AI consumption layer is growing faster than any other traffic channel. And most content operations are completely blind to it.

    The Measurement Crisis

    Here’s what your current analytics stack tells you about AI consumption of your content: almost nothing.

    Google Analytics tracks human visits. An AI engine that cites your content doesn’t load your page in a browser, doesn’t execute JavaScript, doesn’t trigger a session. It reads your content through APIs or cached indexes and incorporates it into a response. No pageview. No session. No data.

    Google Search Console tracks clicks and impressions from Google search. It doesn’t track AI Overview citations — when Google’s own AI uses your content to build an AI-generated summary, that interaction doesn’t appear as a click or an impression in Search Console.

    The only tool currently offering AI citation data is Bing Webmaster Tools, through its AI Performance beta tab. This shows Copilot-specific citations — the number of times Copilot used your content as a grounding source. But it only covers Microsoft’s AI. Google, ChatGPT, Perplexity, and Claude citation data remains largely invisible.

    This creates a measurement crisis. Content operations make decisions based on analytics data. If the majority of your content’s audience is invisible to your analytics, you’re making decisions based on the minority of your readership. You’re optimizing for the 1,900 clicks while ignoring the 98,800 citations.

    What “Being Read by AI” Actually Means

    When I say AI is reading your content, I want to be precise about what’s happening technically.

    Grounding: When a user asks Copilot a question, Copilot searches for relevant web content, retrieves it, and uses it to “ground” its response in factual sources. Your page becomes the cited source for specific claims in the AI’s answer. The user sees your content’s information, often with a link back to your page — but they may never click that link because the AI already gave them what they needed.

    Scale: One article on my site answering “claude ai pricing” was grounded 16,500 times. That means 16,500 Copilot users received information sourced from my page. In a traditional web model, that would be 16,500 pageviews. In the AI model, it’s 16,500 invisible reads.

    Reach: Each citation represents content delivery to a user who is actively working, actively needing that information, and actively incorporating it into a task. This isn’t a bounce-rate impression — it’s a high-intent content consumption event. The quality of these “reads” may be higher than most human pageviews, even though they’re invisible.

    The Writing Implications

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The writing implications of AI-majority readership.

    If AI is your primary reader, you need to write differently. Not worse. Not shorter. Differently.

    Write for extraction, not engagement. AI engines don’t scroll, don’t skim, and don’t get bored. They extract specific information from your content. A pricing table that’s easy for AI to parse serves the citation audience better than a narrative pricing discussion that’s more “engaging” for human readers. Both can coexist, but the extraction-friendly content needs to be there.

    Accuracy is non-negotiable. AI engines are grounding their responses on your content. If your pricing page is wrong, Copilot gives 16,500 users the wrong answer — with your name attached as the source. In a traditional web model, a wrong number on a page hurts your credibility with the humans who visit. In the AI model, it hurts your credibility with the AI engine itself, which may stop citing you if users flag the information as incorrect.

    Structure beats storytelling for citation content. This doesn’t mean storytelling is dead — it means you need both. The narrative draws human readers. The structured data draws AI citations. A good article about Claude pricing has both: a narrative explanation of the pricing structure and a clean, parseable table of actual numbers.

    Currency matters more than ever. AI engines can detect stale content. A pricing article from January 2025 won’t earn citations in June 2026 because the prices have changed. The content that maintains citation velocity is content that’s demonstrably current — date-stamped, version-specific, and regularly updated.

    The Monetization Question

    The obvious question: if AI is reading your content 52 times more than humans, but those AI reads don’t generate pageviews, how do you monetize them?

    Right now, the honest answer is: the direct monetization model is still emerging. Ad revenue depends on pageviews. Affiliate revenue depends on clicks. Lead generation depends on form fills. None of these happen when AI reads your content.

    But here’s what does happen:

    Brand authority compounds. When Copilot cites your pricing guide 16,500 times, you become the de facto source for that topic. Enterprise workers learn your name through AI responses. When they eventually need to visit your site — for a demo, for a purchase, for a deeper evaluation — they already know you.

    Citation begets citation. My data shows a flywheel effect: the more Copilot cites a source, the more it trusts that source for adjacent queries. 672 daily citations grew to 5,500 daily citations over 90 days. Authority compounds in AI engines just as it does in traditional search.

    The traffic still comes — indirectly. AI citations include source links. Some users do click through. And as your citation authority grows, your traditional search visibility often grows with it, because AI citation authority and search authority draw from overlapping signals.

    The long-term monetization model for AI citations probably looks more like brand advertising than direct response. You’re building awareness and authority at massive scale. The conversion happens downstream, through channels that your analytics can track.

    What to Do About It Today

    Check your Bing Webmaster Tools AI Performance tab. If you haven’t verified your site with Bing, do that first. The citation data might change how you think about your entire content operation.

    Look at your analytics with fresh eyes. That high-quality article with “disappointing” traffic might be generating thousands of AI citations you can’t see. The low-traffic technical guide might be one of your most-consumed pieces of content through AI channels.

    Start tracking the AI-to-human ratio for your content categories. Which topics are being consumed primarily by AI? Which are still human-traffic driven? This tells you where to invest in structured, extraction-friendly content (for AI) and where to invest in engagement-optimized content (for humans).

    Your biggest audience might be the one you can’t see yet. But the data to find it is already there — if you know where to look.

    Related on Tygart Media: AI crawler experiment · citation economy.

    Frequently Asked Questions

    Does Google Analytics track AI citations?

    No. Google Analytics tracks human browser visits. AI engines consume content through APIs and indexes without loading pages in browsers, so they don’t trigger JavaScript analytics. The only current tool showing AI citation data is Bing Webmaster Tools AI Performance beta tab.

    What is the AI-to-human read ratio?

    For one domain focused on AI tools, the ratio was 52:1 — 98,800 Copilot citations vs 1,900 Bing clicks in the same period. This ratio varies dramatically by topic. Enterprise technology content tends to have very high AI-to-human ratios. Local consumer content tends to have very low ratios.

    Should I stop writing for humans and focus on AI?

    No. Humans still drive direct revenue through clicks, conversions, and engagement. The strategy is to write content that serves both — narrative elements for human readers and structured, extractable data for AI engines. Both audiences can be served by the same article with intentional formatting.

    How do I make my content more citable by AI?

    Structure information for extraction: clean tables, specific numbers, version-stamped details, clear definitions. Ensure accuracy — AI engines may reduce citations for sources that users flag as incorrect. Keep content current with date stamps and regular updates.

    Will Google eventually show AI citation data?

    Google has not announced plans to expose AI Overview citation data in Search Console. However, as the AI citation economy grows and marketers demand transparency, competitive pressure from Bing’s AI Performance tab may push Google to provide similar analytics.