Uncategorized - Tygart Media

Category: Uncategorized

  • Claude Routines Is a Frankenstein Product, and That’s Why It’s Working

    Claude Routines Is a Frankenstein Product, and That’s Why It’s Working

    Anthropic shipped one feature on April 14. Nine days in, the internet has already decided it’s five different things.


    On April 14, 2026, Anthropic quietly pushed a research preview called Routines into Claude Code. The framing from their launch post is almost boring: “A routine is a Claude Code automation you configure once — including a prompt, repo, and connectors — and then run on a schedule, from an API call, or in response to an event.”

    That’s it. That’s the whole pitch. You write instructions once, Anthropic runs them on their cloud, and your laptop can be closed at the bottom of a lake for all it matters.

    Nine days later, I pulled social reactions from the first week of real usage — developers, indie hackers, ad ops people, a Polymarket trader, a guy learning piano, a Japanese solo dev running it for a week, Hamel Husain grumbling about YAML. And the thing that jumped out wasn’t the feature. It was how wildly people disagreed about what Routines even is.

    Is it an n8n killer? A cron replacement? An enterprise procurement play? A way to avoid buying a Mac Mini? A vibes machine for autonomous trading bots? A broken MCP detector?

    Yes. All of those. At the same time. That’s the story.


    The five Routines

    Four cards for content, ops, build, and knowledge work with Claude
    The five Routines.

    Here’s what Routines looks like, depending on who’s holding it.

    To the production automation crowd, it’s a toy. Alex Vacca (@itsalexvacca) wrote the most viewed thread in the launch window — 28,000+ views, 283 replies — and it was a full-throated defense of n8n. His agency runs 13 workflows, 2,000+ executions per day, 41 nodes in one pipeline alone. Monthly n8n bill: $384. “The same workloads on Claude would cost $60K,” he wrote. “That’s why I’m not buying the ‘Claude killed n8n’ take. They’re not the same layer.”

    He’s right. If you’re firing thousands of deterministic executions a day through a visual graph with tight error handling, Routines at 5-to-25 runs per day on included tiers isn’t even in the conversation. You’ll eat your Extra Usage budget by noon Tuesday.

    To the indie hacker crowd, it’s liberation. Aman Kumar (@Amank1412) summed up the mood in two lines and a video: “Claude Routines automatically run at a schedule without keeping your laptop open. Those who spent $599 on a Mac Mini.” A Spanish developer (@anthonysurfermx) is moving his OpenClaw logic off Digital Ocean: “me quito 30 USD mensuales.” A Japanese developer (@KameAIHacks) reported back after a full week: nightly test runs, auto PR reviews, weekly dependency scans — “個人開発者のメンテナンス作業がほぼゼロになった.” Maintenance work as a solo dev dropped to nearly zero.

    These people aren’t trying to replace n8n. They’re trying to not-own a server. The unlock isn’t workflow power. It’s that you can delete a piece of infrastructure from your life.

    To the enterprise crowd, it’s a land grab. The sharpest observation came from @grapeot, writing in Chinese: “Claude Routines 每个是独立 API endpoint 带 bearer token,独立配额独立计价,配套 SSH 让 agent 跑在企业内网。它服务的是把 agent 写进采购合同的企业.” Translation: every routine is a separate API endpoint with its own auth token, its own quota, its own billing line, and SSH support for running agents inside corporate networks. This is Anthropic saying “put this in your procurement contract.” It’s not a consumer feature dressed up. It’s enterprise infrastructure wearing consumer clothes.

    To the crypto crowd, it’s a printing press. @regent0x_ shared a story about a Polymarket trader who connected Routines to price feeds via API trigger. Price moves 4%, Claude wakes up, analyzes news, checks sentiment, decides whether to alert or auto-execute. “Laptop hasn’t been open in a week… $23k profit last month… total costs: $5/mo webhook + $87 in API calls… net profit margin: 99.6%.” Asked what he did with the free time: “learning piano.”

    This is the quote that’s going to outlive the launch. Not because it’s representative — it absolutely isn’t — but because it’s the Platonic ideal of what cloud agents are supposed to feel like when they work. Research, reason, act, report. Go practice Chopin.

    To Hamel Husain, it’s just YAML. The machine learning veteran (@HamelHusain) tried Routines and walked away: “I found it to be far better to use GitHub Actions. I have more control with GHA, secret management, etc. Claude is really good at writing all the yaml and iterating until it works on its own too. Wild times that I’m saying I like GitHub Actions LOL.”

    If you already live in GHA, Routines isn’t offering you anything you don’t already have — except the novelty of a natural-language wrapper, which costs you control.


    The broken pieces nobody’s hiding

    Seven cards naming common AI chatbot failure modes
    The broken pieces nobody’s hiding.

    A feature isn’t real until it breaks, and Routines is breaking in public. @ghuubear tried it on day 9 and reported his MCP connectors weren’t detected at all: “anthropic is shipping broken products.” @ahmetb couldn’t get GitHub PR-open triggers to fire: “not working at all.” Rich Baldry (@chooserich), who’s spent “countless hours with Codex Automations, Claude Routines, OpenClaw,” landed on a phrase that’s going to stick: “unreliable magic machines.”

    His follow-up is the real critique, and it’s the one Anthropic needs to answer: “building software with the new agentic coding tools for the same tasks is vastly more reliable.” In other words — use Claude to write a real cron job, not to be the cron job.

    That’s a serious challenge. When the alternative to your cloud agent is “use your cloud agent to write the non-agent version instead,” you’ve built a very fancy bootstrap.


    The pricing question nobody’s settled

    Pro gets 5 routine runs per day. Max ($100 and $200) gets 15. Team and Enterprise get 25. After that, overages bill against Extra Usage at standard API rates.

    The Japanese dev community did the cleanest math: “Proプランだと1日5回まで。個人開発なら十分だけど、3つ以上のRoutineを毎日回したい場合はMaxプランが必要.” Five runs a day is fine for one or two scheduled jobs. Want three or more running daily? Plan up.

    That’s the dividing line, and it tells you exactly who the feature is actually priced for. It is not priced for the n8n crowd. It’s priced for the solo dev with two or three background jobs, or the enterprise buyer who doesn’t look at the line item. The middle — the agency with a dozen automations but no enterprise contract — is the exact spot where Extra Usage starts to sting.

    My Routines counter reads 0/15. I also have $250 in Extra Usage sitting in my account. I can tell you exactly where that money would go if I got careless with triggers: nowhere good.


    What I actually think

    I run a WordPress content network, a Notion command center, a few GCP projects, and enough scheduled tasks in Cowork to keep my desktop busy. I asked myself the honest question before writing this: do I need Routines?

    Answer: not yet. My laptop stays on. My scheduled tasks fire. If one misses because my wifi blinked, I run it the next morning and nothing dies. I’m not a Polymarket trader. I’m not running a procurement contract. I’m not trying to delete a Mac Mini I never bought.

    But the gap in Cowork is real, and the community surfaced it without meaning to. Right now, scheduled tasks in Cowork run on your machine. Routines run in the cloud. Nothing connects them. If you tag a task critical in Cowork and your laptop is asleep, the task just doesn’t fire. The obvious product move — one I’d expect Anthropic to ship in the next two quarters — is a failover flag: “if this task can’t run locally, escalate to a routine.” That closes the loop. Until it exists, you have to pick a side.


    The Frankenstein is the feature

    Three stacked layers: chat UI, tools, agent runtime
    The Frankenstein is the feature.

    Here’s the thing about products that mean five different things at once: usually that’s a sign of a broken launch. Wrong messaging, wrong audience, wrong pricing. “Nobody knows what it is.”

    Routines is the opposite. Every one of those five readings is correct. It IS a toy next to n8n. It IS liberation from a VPS. It IS an enterprise procurement play. It IS a crypto printing press, sometimes. It IS broken in specific places. The Frankenstein isn’t a bug in the positioning. It’s a feature of cloud-hosted agents actually arriving in more than one market at the same time.

    The indie dev and the enterprise buyer are holding the same product and seeing different things because they are different things, lit from different angles. That’s what a platform primitive looks like in its first week.

    The Mac Mini guys get it. The n8n operators get it too — they’re just looking at a different body part.

    As for me: I’m keeping my counter at 0/15 for now. But I’m watching, because the moment Anthropic ships that failover flag between Cowork and Routines, the conversation changes, and the Frankenstein grows another limb.

    Learning piano is probably a stretch.


    Sources: Introducing Routines in Claude Code (claude.com/blog, April 14, 2026); Claude Code Routines documentation (code.claude.com/docs/en/routines); social reactions pulled from X/Twitter, April 14–23, 2026. All quotes used with attribution to their original posters.

    Related on Tygart Media: Claude Cowork · Cowork vs Code vs Agent SDK · how to use Claude.

  • Why the Best AI Operators Think Small: Lessons from the “Token Wall”

    Why the Best AI Operators Think Small: Lessons from the “Token Wall”

    There’s a moment every serious Claude user hits eventually. You’re mid-session, deep in the flow of building a workflow, a content pipeline, or a complex research thread. You’ve built something substantial, and you’re right on the verge of a breakthrough.

    Then the model goes quiet. Or it returns something strange and vague. Or it just stops mid-sentence.

    You didn’t break anything. You simply ran out of room. You’ve hit the "Token Wall," and understanding how to navigate this limit is what separates a casual user from a master operator.

    1. The Physics of the Whiteboard

    Every AI conversation has a "context window," which is essentially a fixed amount of memory the model can hold at once. Think of it like a whiteboard. Every message you send, every response the model generates, every task list, and every snippet of code takes up space on that board.

    When you get close to the limit, the model doesn't just shut off; it begins to struggle under the weight of its own history. You might notice the "feel" of a session getting heavy. The model starts to lose its edge, often attempting to "pattern-match on noise" within the context rather than following your instructions.

    Crucially, the smarter the model, the faster it hits the wall. This is the Opus Paradox: Claude Opus thinks deeply and writes extensively. Because its outputs are more verbose and nuanced, it consumes its own runway far more aggressively than a simpler model. Its intelligence is the very thing that accelerates its failure in a crowded session. When the board is full, the model tries to squeeze a new request into a space that doesn’t exist, resulting in the graceful—but frustrating—failures we’ve all experienced.

    2. The Haiku Trick: Precision Over Power

    When a session stalls at the context limit, your first instinct might be to switch to an even more powerful model. That is almost always the wrong move.

    The veteran operator’s secret is to go smaller. Claude Haiku—the lightest and fastest model—can often "squeeze through the gap" that a heavier model like Opus or Sonnet simply cannot fit through. Because Haiku is lean and efficient, it can perform surgical actions like updating a task list, summarizing the current state of play, or triggering a "compaction" of the history. This small action clears the whiteboard just enough to unlock the entire session.

    "It's not always about raw intelligence. It's about fit. The right tool for the moment isn't the most powerful one — it's the one that can actually execute given the constraints you're operating in."

    This shift from seeking raw power to seeking operational fit is a fundamental breakthrough. It’s the realization that the most "intelligent" move is often the one that creates the most momentum with the least amount of space.

    3. The Formula One Mindset: Strategy Outruns Raw Compute

    To excel in the new era of AI, you have to embrace the Formula One analogy. F1 teams spend hundreds of millions on the fastest cars, but the car doesn't win the race on its own. The driver wins by knowing when to push the engine, when to conserve tires, and when to pit.

    The AI is your car; you are the driver. Two people using the exact same model will produce radically different results based on their "driver skills." These aren't skills you find in a manual; they are earned through "hours in the seat." A master operator develops an instinct for:

    • Pruning Context and History: Recognizing the moment a session feels "heavy" and manually clearing the whiteboard to keep the model focused.
    • Strategic Model Swapping: Knowing exactly when to call in the heavy lifting of Opus and when to pivot to the lean navigation of Haiku.
    • Compacting and Resetting: Identifying when a conversation has become too polluted with noise and needs a clean summary before starting fresh.
    • Task Handoffs to Subagents: Understanding that a subagent operating in isolation will almost always outperform a single, mile-long thread where context is diluted.

    4. What Agents Teach Us About Human Momentum

    We often focus on making AI more like humans, but the more valuable lesson is learning what agents can teach us about our own productivity.

    Agents succeed when they have a bounded context, a defined task, and honest signals about their capacity. They fail when their context is polluted with noise, when tasks are ambiguous, or when they try to do too much in one pass. This is a perfect mirror for human cognitive load. When we are overwhelmed, it’s rarely because we aren't "smart" enough for the task—it's because our internal whiteboard is full of distraction and noise.

    "When you're overwhelmed and stuck, the answer usually isn't to think harder. It's to do the smallest possible thing that creates forward momentum."

    Just as Haiku unlocks a stalled AI session by clearing one small item, humans can overcome paralysis by making one small decision or finishing one minor task. Operating intelligently within your own mental constraints is a superpower, not a compromise.

    5. The Internalized Hybrid

    The most effective AI users aren't just "humans using tools." They are "internalized hybrids"—operators who have adopted the logic of agentic thinking as their own.

    They naturally break massive projects into discrete, manageable tasks. They are honest about their own "context limits," realizing that pushing through a complex task at 11:00 PM is the cognitive equivalent of a model producing garbage when its whiteboard is full.

    This level of mastery isn't taught in a tutorial. It’s forged in the "Machine Room" at midnight, in those moments of operational failure when you hit the token wall and realize that a smaller, smarter approach is the only way through the gap. You have to live the experience of the work to develop the instinct for it.

    Conclusion: Getting Back in the Seat

    The relationship between you and the AI is defined by the "Driver and the Car." The car provides the potential for incredible speed, but it is the driver who provides the strategy, the timing, and the environmental awareness required to reach the finish line.

    The technology is now available to everyone, which means the tool itself is no longer the competitive advantage. The advantage is the operator.

    As you return to your workflows, ask yourself: Are you just pressing harder on the accelerator and wondering why you’re hitting a wall? Or are you ready to become a true driver, managing your context and choosing the right tool for the moment?

    The car is waiting. The driver makes the difference. It’s time to get back in the seat.

    Related on Tygart Media: AI operator’s stack · tokens to words · Claude calibration.

  • Project Glasswing: Securing Global Critical Software

    Project Glasswing: Securing Global Critical Software

    Following its initial launch, Anthropic has released an update on Project Glasswing, an ambitious initiative aimed at securing the world’s most critical software infrastructure. The project represents a monumental collaborative effort between Anthropic and tech giants including Amazon Web Services, Apple, Broadcom, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, NVIDIA, and Palo Alto Networks.

    As the digital landscape faces increasingly sophisticated threats, securing foundational open-source software and critical infrastructure is a massive undertaking. Project Glasswing seeks to leverage advanced AI—specifically the capabilities of models like Claude—to analyze, patch, and reinforce the software that powers our global economy.

    The Future of AI-Powered Security

    The latest update indicates significant momentum for the project. By bringing competitors and industry leaders to the same table, Anthropic is demonstrating the unique role AI can play not just in automation, but in global cybersecurity defense. For businesses relying on digital infrastructure, this initiative promises a more secure and resilient future.

    Related on Tygart Media: Anthropic safety · is Claude safe · invisible agent layer.

  • Anthropic AI Ethics: Response to Pope Leo XIV Encyclical

    Anthropic AI Ethics: Response to Pope Leo XIV Encyclical

    In a fascinating intersection of global philosophy and artificial intelligence development, Anthropic co-founder Chris Olah recently provided remarks on Pope Leo XIV’s encyclical, “Magnifica humanitas.” The encyclical, which addresses the moral and ethical responsibilities humanity holds toward emerging technologies, has prompted deep reflection across the tech industry.

    Anthropic, known for its focus on AI safety and alignment, has consistently emphasized the importance of building reliable, interpretable, and steerable AI systems. Olah’s response highlights how the company’s mission aligns with the ethical frameworks proposed in the encyclical. This dialogue represents a crucial step in ensuring that frontier AI models like Claude are developed with profound consideration for their broader societal impact.

    Why This Matters

    As AI becomes deeply integrated into our daily lives and enterprise workflows, the alignment of technology with fundamental human values is paramount. The response from Anthropic showcases a willingness from AI leaders to engage with moral authorities, bridging the gap between Silicon Valley and global ethical discourse.

    Related on Tygart Media: Anthropic safety · Dario Amodei · Claude restraint & trust.

  • North Mason School Levy Passes: Budget Cuts & Next Steps

    North Mason School Levy Passes: Budget Cuts & Next Steps

    Certification status: The Mason County Auditor’s Canvassing Board meeting to certify this election is scheduled for May 8, 2026 at 2:00 PM. The vote totals below are from the April 30 preliminary count. For the official certified result, check the Mason County Auditor elections page directly.

    The Vote

    North Mason School District’s four-year education programs and operations (EP&O) replacement levy passed in the April 28, 2026 special election. The Mason County Auditor’s Office reported the following preliminary totals across both Mason and Kitsap counties:

    CountyYesNoYes %
    Mason County2,0891,80853.61%
    Kitsap County414348.81%
    Combined2,1301,85153.50%

    Source: Shelton-Mason County Journal, April 30, 2026

    This was the third attempt after the levy failed twice in 2025 — in February (46.17% yes) and again in a subsequent election. The district lowered the tax rate for this third proposal to $1.01 per $1,000 of assessed value for 2027–2030, down from $1.28/$1.24/$1.21/$1.17 in the two failed proposals.

    What Superintendent Michael Said

    Superintendent Kristine Michael responded to the preliminary results Tuesday night. The Shelton-Mason County Journal quoted her directly: “We are very pleased and encouraged by these preliminary results, and we will be monitoring closely as ballots continue to be counted and certified. If this outcome holds, it reflects the trust this community is placing in our schools and our students. I do not take that trust lightly, and I will continue working to restore and strengthen the community’s confidence in our schools.”

    What the Levy Funds — and What It Doesn’t Fix Right Away

    This is where parents and community members need to read carefully. Passage of the levy does not undo the cuts that already happened.

    The district made $3 million in cuts at the end of the 2025–26 school year after the levy expired at the end of 2025. Those cuts hit athletics, student activities, and staff positions directly. The levy’s replacement funding will not arrive until April 2027 at the earliest — Superintendent Michael confirmed this timeline with the Journal before the election.

    Michael was explicit about what that means even in a passage scenario: “Those funds would allow us to avoid making additional reductions, but because we are operating with only a partial year of levy revenue even in a passage scenario, we would not be in a position to restore programs or positions already reduced.”

    In plain terms: the levy passing stops the bleeding, but it does not reverse it. Programs and positions already cut are not automatically restored. The district will need to work through its budget process for the 2027–28 school year before any restoration decisions are made.

    What the Levy Rate Means for Property Owners

    At $1.01 per $1,000 of assessed value, a home assessed at $400,000 would pay approximately $404 per year — or about $33.67 per month — toward the levy for 2027 through 2030. This is the lowest rate of the three proposals the district has put to voters.

    The History Behind This Vote

    North Mason has a difficult levy history. The district experienced two EP&O failures in 2020, which triggered significant budget cuts then as well. The current levy that expired replaced the one approved barely — at 50.3% — in 2021. The two 2025 failures set the stage for the $3 million in cuts that went into effect this school year, and for the third attempt at a lower rate that passed April 28.

    What to Watch Next

    • May 8, 2026: Mason County Auditor Canvassing Board meets at 2:00 PM to certify the election. Official certified results will be posted to the Mason County Auditor elections page.
    • 2026–27 school year: The district operates without full levy revenue. No program restorations expected this year.
    • April 2027: Earliest date levy funds begin flowing to the district.
    • 2027–28 budget process: The first realistic opportunity for the school board to consider restoring cut programs and positions, subject to budget conditions at that time.

    For ongoing North Mason School District updates, the district’s official communications are at northmasonschools.org. Election results and certification status are at the Mason County Auditor’s Office.

  • History of Anthropic: Founders, Origins & AI Evolution

    History of Anthropic: Founders, Origins & AI Evolution

    Last refreshed: October 19, 2026


    Redirecting… Click here if not redirected

    Related on Tygart Media: Dario Amodei · Jared Kaplan · Anthropic IPO.

    >Part of the complete guide: Claude Pricing, Plans & Limits

  • Mason County Fiber: Why PUD 3 Matters for the AI Era

    Mason County Fiber: Why PUD 3 Matters for the AI Era

    If you’ve been following Mason County’s PUD 3 fiber expansion — the gigabit buildout reaching Cloquallum and pushing toward Belfair — you might be thinking about faster streaming or more reliable video calls. That’s real. But there’s a bigger story underneath it, one that connects directly to where work, business, and information are heading.

    The AI tools that are reshaping professional work — coding assistants, document analysis, agent automation — are bandwidth-intensive, latency-sensitive applications. They are not designed for satellite internet with 600ms ping times or DSL connections that struggle past 10Mbps. Gigabit fiber is the infrastructure layer that determines whether you can use these tools the same way someone in Seattle or Bellevue does. That gap matters more than most people realize right now.

    What AI Tools Actually Require

    The practical bandwidth requirements for AI-assisted work are modest by gigabit standards — but they are real, and they add up quickly in a household or small business where multiple people are working simultaneously.

    • Claude, ChatGPT, Gemini via browser: Low bandwidth per session, but latency matters for agentic tasks that involve multiple back-and-forth exchanges. A 200ms round-trip feels fine; 600ms feels broken during long agentic runs.
    • Claude Code and coding agents: These tools read and write files, run terminal commands, and stream outputs continuously. On a slow connection, the feedback loop that makes these tools useful breaks down.
    • Document processing pipelines: Uploading a 50-page PDF or a folder of images for analysis on a 5Mbps upload connection takes long enough to interrupt workflow. On gigabit fiber it’s nearly instant.
    • Video + AI combined workflows: Remote workers using AI transcription, real-time meeting assistants, or AI-enhanced video conferencing stack bandwidth requirements that rural connections routinely can’t sustain.

    None of this is about luxury. It’s about whether the productivity gains that AI tools deliver are accessible equally — or whether they accrue disproportionately to people already located in well-connected metro areas.

    The Mason County Context

    PUD 3’s Cloquallum fiber project has a May 31, 2026 signup deadline for residents in the service area. The broader PUD 3 gigabit buildout has been expanding through the county with the goal of bringing symmetrical gigabit service to areas that have been underserved for years.

    For Mason County property owners, fiber access is already showing up in home valuations — buyers who work remotely increasingly treat fiber availability as a binary filter. For business owners, the calculus is more direct: reliable symmetric bandwidth is now a prerequisite for the category of software tools that are compressing what small teams can produce.

    What This Looks Like in Practice

    A small business owner in Shelton or Belfair with gigabit fiber can run the same AI-assisted workflows as a marketing agency in Seattle. That means:

    • Using Claude via the API to automate document-heavy back-office work — contracts, proposals, intake forms — at a cost that’s measured in cents per task rather than hours of labor
    • Running Claude Code for software development or automation scripting without the latency that makes agentic coding tools frustrating on slow connections
    • Participating in distributed teams where AI-enhanced collaboration tools are standard — video calls with live transcription, shared AI workspaces, automated meeting summaries
    • Building content, analysis, or research pipelines that would previously have required hiring specialized staff

    None of these use cases require a computer science degree. The current generation of AI tools — particularly Claude’s May 2026 updates including managed agents and the expanded connector ecosystem — are built for people who want to use AI to get work done, not people who want to study AI.

    The Bigger Picture: Rural Participation in the AI Economy

    There’s a version of the AI transition that looks like previous technology shifts — where the productivity gains concentrate in places that already have infrastructure advantages, and rural areas fall further behind. Fiber buildouts like PUD 3’s are the infrastructure decision that determines which side of that divide Mason County lands on.

    The tools themselves are increasingly cloud-based and location-agnostic. Claude doesn’t care whether you’re in Bellevue or Belfair. The connection does.

    This is why local infrastructure decisions that might look like routine utility policy — a PUD fiber deadline, a county broadband study — are actually decisions about economic participation in what’s coming next. The May 31 signup deadline for Cloquallum fiber isn’t just a utility question. It’s an access question.

    If You’re New to AI Tools and Have the Connection

    If PUD 3 fiber has reached your area and you haven’t explored what current AI tools can actually do for your work, a few starting points:

    • The Anthropic Console — where to get an API key and start building with Claude directly
    • Claude pricing — what each plan costs and which one makes sense for individual vs. team use
    • What Claude can do as of May 2026 — the current state of the tools, including the managed agents and connector expansion that make it useful for non-developers

    The infrastructure and the tools are both moving fast. Mason County’s fiber buildout is the local side of a much larger story.

  • Claude Pricing 2026: $20 Pro, $100 Max, API Rates & Limits

    Claude Pricing 2026: $20 Pro, $100 Max, API Rates & Limits

    Updated Oct 31, 2026 — completed the download ladder on this guide: added the free Claude pricing quick-reference sheet and the Claude Pricing Copilot book-for-bots alongside the existing Cost Planner.

    Updated October 30, 2026: Added The Claude Cost Planner 2026 — a $7 fill-in workbook built from this page’s pricing tables — beside the free truth sheet.

    Live GuideLast verified: 12 October 2026 against claude.com/pricing, API pricing, and the Claude Help Center Team article.

    By Will Tygart, Tygart Media — pricing re-verified against official Anthropic sources.

    Direct Answer · October 12, 2026

    Claude pricing is two meters. Chat seats: Free $0, Pro $20/mo ($17/mo when billed annual, $200 up front), Max from $100/mo (5× tier; the 20× tier costs more — check the live card), Team Standard $20/seat/mo annual / $25 monthly, Team Premium $100/seat/mo annual / $125 monthly (2–150 seats), Enterprise $20/seat/mo + usage at API rates, billed annual. API (per million tokens, official table): Haiku 5.5 $0.10 / $0.50 (prompts ≤100k tokens; $0.50 / $2.50 above), Sonnet 5.5 $2 / $10, Opus 5.5 $4 / $20, Fable 5.1 $10 / $50. Opus 5 remains listed at $5 / $25 and is not the current Opus. Sonnet 5 remains listed at $2 / $10 (legacy; Sep 1 step cancelled) and is not the current Sonnet. A Pro seat does not include API credits; Max 5× and Max 20× now include $100 and $200 per month in API credits respectively. Confirm seats on claude.com/pricing before you buy.

    Anthropic Console · Claude Reference Hub.

    Instant Pricing Downloads

    Choose Your Claude Pricing Toolkit or Feed Your AI Assistant

    Field-tested procurement and planning tools built directly from Anthropic’s official 2026 subscription tiers, API token rates, prompt caching math, and seat allocation rules.

    Quick Reference FREE

    Claude Pricing Quick-Reference Sheet

    2-page reference PDF: plan tiers (Free, Pro, Max 5×/20×, Team, Enterprise), 1-line seats-vs-API split, full API per-token rate table, and prompt-caching rules.

    Download Free PDF

    Direct download • No email gate

    Working Pack $7

    Claude Cost Planner 2026

    Fill-in workbook: solo, freelancer, team, and API estimators, hidden extra-usage costs, seat minimums, monthly-vs-annual math, and 1-page worksheet ending with your total.

    Get Cost Planner ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots $17

    Claude Pricing Copilot

    Feed to ChatGPT or Claude: 5 AI-run routines (/plan-picker, /api-bill-builder, /seat-vs-api-audit, /team-mix-optimizer, /upgrade-trigger) with embedded output router.

    Get Copilot ($17) →

    Software made of words • Instant delivery

    What are the Claude subscription plans?

    Plan US price What it is
    Free $0 Chat on web, iOS, Android, desktop. Sonnet and Haiku. Usage limits. No Claude Code on Free.
    Pro $20/mo, or $17/mo annual ($200 up front) More usage. Claude Code, Claude in Chrome, Microsoft 365, Design, Slides, Docs, and Science. Projects. Extra usage, when enabled, bills at API rates. Cowork is merging into Claude (Pro and Max first).
    Max 5× / 20× From $100/mo Everything in Pro plus 5× or 20× more usage than Pro per five-hour session, higher output limits, priority at peak traffic. Max 5×/20× now include $100/$200 per month in API credits. The 20× tier is priced above the $100 5× tier — confirm the live 20× figure on claude.com/pricing before you buy. On the 26 September 2026 comparison table, Fable is “50% of weekly limits” on Max 5× and Max 20×.
    Team Standard $20/seat/mo annual · $25 monthly Min 2 seats, max 150. 1.25× Pro per session. Central billing, SSO, connectors. Mix seats with Premium.
    Team Premium $100/seat/mo annual · $125 monthly 6.25× Pro per session. Same workspace as Standard. Source: Claude Help Center “What is the Team plan?”
    Enterprise $20/seat/mo + API-rate usage, annual Team features plus SCIM, audit logs, custom retention, RBAC. Seat fee is access. Tokens bill separately. Self-serve or sales.

    Prices exclude tax. Team/Enterprise US list read 26 September 2026.

    Was kostet Claude? Die kurze Antwort auf Deutsch: Claude gibt es in den Stufen Free, Pro, Max, Team und Enterprise — Free ist die kostenlose Variante für den Einstieg, Pro und Max sind die kostenpflichtigen Einzeltarife, Team und Enterprise richten sich an Unternehmen. Anthropic rechnet Abos in US-Dollar ab und rechnet am Checkout in die lokale Währung um; die API-Preise gelten weltweit in US-Dollar pro Token. Für Deutschland kommt die Mehrwertsteuer am Checkout hinzu. Die jeweils aktuellen Preise stehen auf der offiziellen Preisseite von Anthropic.

    API token rates (platform.claude.com)

    Pay per million tokens. No monthly minimum. Chat seats do not fund this meter.

    Model Input / MTok Output / MTok Cache read Role
    Fable 5.1 $10 $50 $0.25 Current top public tier (1 Sept 2026)
    Fable 5 $10 $50 $1.00 Still listed; higher cache-hit cost than 5.1
    Mythos 5.1 $10 $50 $0.25 Separately listed on Anthropic’s official table; same rate as Fable 5.1
    Opus 5.5 $4 $20 $0.20 Current Opus. Daily driver. Docs say start here for most workloads. Ship date was not on the 23 September 2026 models overview. API ID claude-opus-5-5
    Opus 5 $5 $25 $0.50 Legacy. Still listed. Not the current Opus
    Opus 4.8 / 4.7 / 4.6 / 4.5 $5 $25 $0.50 Prior Opus still priced; do not start new work here
    Sonnet 5.5 $2 $10 $0.10 Current Sonnet (shipped Sep 28 2026). Cache read halved to $0.10 on Oct 7 2026. API ID claude-sonnet-5-5. Available on Free and on paid plans
    Sonnet 5 $2 $10 $0.20 Legacy. Same $2/$10 (Sep 1 $3/$15 step cancelled). Still listed
    Sonnet 4.6 / 4.5 $3 $15 $0.30 Prior Sonnet. Not the default. Sonnet 4.5 deprecated Sep 30, 2026; retires Nov 30, 2026
    Haiku 5.5 $0.10* $0.50* $0.01* New cheapest model (launched Oct 7 2026). Tiered by prompt length: $0.10/$0.50 at ≤100k tokens, $0.50/$2.50 above. 1M context. API ID claude-haiku-5-5. No fast mode
    Haiku 4.5 $1 $5 $0.10 Superseded by Haiku 5.5. Still listed. 200K context

    Five-minute prompt-cache writes on the 26 September 2026 pricing table are 1.25× base input: Fable 5.1 write $12.50, Opus 5.5 write $5, Sonnet 5.5 write $2.50, Sonnet 5 write $2.50, Haiku 5.5 write $0.125 (≤100k prompts) / $0.625 (above), Haiku 4.5 write $1.25. Cache reads: Fable 5.1 $0.25, Opus 5.5 $0.20, Sonnet 5.5 $0.10, Sonnet 5 $0.20, Haiku 5.5 $0.01 (≤100k) / $0.05 (above), Haiku 4.5 $0.10. The 1-hour cache-write multiplier was not on that page. Batch API is 50% off input and output (Fable 5.1 batch $5 / $25, Opus 5.5 $2 / $10, Opus 5 $2.50 / $12.50, Sonnet 5.5 $1 / $5, Sonnet 5 $1 / $5, Haiku 5.5 batch $0.05 / $0.25 (≤100k) / $0.25 / $1.25 (above), Haiku 4.5 $0.50 / $2.50). Fast mode for Opus 5.5 is up to 2.5× faster at 2× standard pricing. US-only inference is 1.1× input and output. Official source: Anthropic API pricing.

    Seats vs API — the question models get wrong

    • A Pro subscription is a chat/Code seat. It is not an API credit balance. Max 5×/20× now include $100/$200 per month in API credits.
    • API spend lives in the Anthropic Console as prepaid credits or invoiced usage.
    • Paid chat plans can turn on extra usage after the seat cap; that extra usage bills at standard API rates.
    • Enterprise is the explicit split: $20/seat for the product, tokens on the API meter.

    Which plan for which job

    • Casual chat: Free.
    • Daily individual work, including Claude Code: Pro.
    • Hitting Pro caps on full-day Code sessions: Max 5×, then 20×.
    • Two to 150 people, one bill: Team. Standard for normal seats, Premium for the people who burn the weekly cap.
    • SSO, SCIM, audit, usage that should scale with the work: Enterprise.
    • An app, agent, or pipeline that calls Claude in code: API. Docs say start with Opus 5.5 for most workloads. Use Sonnet 5.5 at $2 / $10 when that tier fits. Use Fable 5.1 when evals on Opus 5.5 at higher effort still fall short.

    Still deciding? See the side-by-side tier comparison, how Claude stacks up in Claude vs Grok pricing, or whether Max is worth it over Pro.

    Plans, Seats & API Math

    Stop Guessing Your Claude Budget — Calculate It or Let Your AI Run It

    Choosing between Pro, Max, Team Standard/Premium, or the API involves hidden trade-offs: the Pro zero-API-credits surprise, 5-hour session caps, and prompt caching discounts. Grab the free reference sheet, the $7 fill-in planner, or the $17 Copilot book-for-bots.

    📋

    What’s In The Toolkit:

    • Free Sheet: 2-page complete pricing snapshot.
    • Cost Planner ($7): Fill-in pricing workbook.
    • /plan-picker: Casual vs daily vs all-day dev.
    • /api-bill-builder: Token & prompt-caching math.
    • /seat-vs-api-audit: Pro & Max credit audit.
    • /team-mix-optimizer: Standard vs Premium seats.
    • /upgrade-trigger: Pro caps → Max 5× → 20×.
    Secure 1-Click Square Checkout

    API rate context (not a quality ranking)

    Opus 5.5 at $4 / $20 is the model docs say to start with. Sonnet 5.5 at $2 / $10 is the current Sonnet. Sonnet 5 remains listed at the same $2 / $10 (legacy). Older copy on this URL listed Sonnet 4.6 at $3 / $15 as current — that is no longer the default. Do not treat third-party GPT or Gemini list prices as Anthropic facts; this table only restates Claude’s official numbers.

    Claude Max pricing

    Max 5x from $100/mo; Max 20x $200/mo. Both tiers now include monthly API credits ($100 on 5×, $200 on 20×), per claude.com/pricing. Capacity multiplier over Pro; Claude Code included.

    Claude Enterprise pricing

    $20/seat/mo + API-rate usage, annual, per claude.com/pricing.

    You probably found this page because an AI sent you here.

    Clarity counted 62,970 citations of this page in the last 30 days. That isn’t luck — it’s structure, and it’s measurable. If the AI answers in your market name a competitor instead of your company, that’s a measurement too, and it’s the one we run.

    Get the Quick-Scan — $97 →

    Get the diff when Claude pricing changes.

    Claude pricing moves. When it does, this page gets corrected — and subscribers get the diff by email. What changed, old → new, nothing else. No newsletter, no pitch.

    Get pricing-change alerts →

    Prefer it on one page? The truth sheet PDF — free, by email.

    You have the price list. Now get your number.

    The Claude Cost Planner 2026 is the full working version of the free truth sheet: every plan’s real price in one table, fill-in estimators for solo users, freelancers, small teams, heavy users, and API builders, the hidden costs — extra-usage billing, seat minimums, monthly-vs-annual math — and a one-page worksheet that ends with your total.

    Get the Cost Planner — $7

    Delivered right after checkout — your download opens automatically.

    Complete Your Claude Pricing Strategy With Fact-Grounded Tools

    Choose the resource level that matches your decision stage — from a quick 2-page printout to interactive AI execution:

    Free Field Summary

    Claude Pricing Quick-Reference Sheet

    2-page reference PDF covering subscription tiers, seat limits, and official per-token API rates.

    FREE direct download
    • All subscription tiers (Free, Pro, Max 5×/20×, Team, Enterprise)
    • 1-line rule: Seats vs API meters & credit inclusions
    • Complete per-token API rate table (Fable, Opus, Sonnet, Haiku)
    • 5-minute prompt cache write (1.25×) & read discounts (up to 95%)
    • Batch API 50% discount and platform feature pricing
    Download Free PDF

    Instant download • No email gate

    Static Working Pack

    Claude Cost Planner 2026

    Fill-in workbook built from this guide’s pricing tables: solo, freelancer, team, and heavy API builders.

    $7 one-time payment
    • Every plan’s real price in one side-by-side table
    • Fill-in estimators for solo users, freelancers, and small teams
    • Heavy user and API builder token calculators
    • Hidden costs audit: extra-usage billing & seat minimums
    • Monthly vs. annual cash flow trade-off formulas
    • One-page printable requisition sheet ending with your total
    Get Cost Planner ($7) →

    Instant checkout • Square verified

    AI Intensive
    Software Made of Words

    Claude Pricing Copilot

    Feed directly to ChatGPT or Claude to run the pricing interview, model token bills, and optimize team seats.

    $17 one-time payment
    • 5-page executable “Software Made of Words”
    • /plan-picker: 4-question step-by-step tier diagnostic
    • /api-bill-builder: Line-by-line MTok & caching estimator
    • /seat-vs-api-audit: Pro credit check & Max credit offset
    • /team-mix-optimizer: Standard ($20) vs Premium ($100) mix
    • /upgrade-trigger: Session capping & Claude Code threshold
    • Embedded Output Router: Zero-hallucination fact gate
    Get Copilot ($17) →

    Instant checkout • Square verified

    FAQ

    Looking for the complete rundown? See the full Claude pricing FAQ.

    How much does Claude Pro cost?

    $20 per month, or $17 per month when billed annually ($200 up front), per claude.com/pricing. Tax extra.

    How much is the Claude API?

    Per million tokens. Current list: Haiku 5.5 $0.10/$0.50 (prompts ≤100k tokens; $0.50/$2.50 above), Sonnet 5.5 $2/$10, Opus 5.5 $4/$20, Fable 5.1 $10/$50. Haiku 4.5 remains listed at $1/$5 (superseded). Sonnet 5 remains listed at $2/$10 (legacy). Opus 5 remains listed at $5/$25 and is not current. Confirm the live table before you quote a customer.

    Does a Claude subscription include API credits?

    Pro: no — seats and API credits are separate. Max 5× and Max 20× now include $100 and $200 per month in API credits respectively (new row on claude.com/pricing). Extra usage on paid chat plans, when enabled, bills at API rates.

    What is Claude Team pricing?

    US list: Standard $20/seat/mo annual or $25 monthly. Premium $100/seat/mo annual or $125 monthly. Minimum two members, maximum 150. Source: support.claude.com Team plan article.

    What is Claude Enterprise pricing?

    $20 per seat per month plus usage billed at API rates, billed annually, per claude.com/pricing.

    Is Sonnet 4.6 still current pricing?

    Sonnet 4.6 remains on the API price list at $3 / $15. Sonnet 5.5 at $2 / $10 is the current Sonnet (API ID claude-sonnet-5-5). Sonnet 5 remains listed at the same $2 / $10 (legacy; Sep 1 step cancelled). Use Sonnet 5.5 for new work.

    What are the Claude subscription plans?

    Free ($0), Pro ($20/mo or $17/mo billed annually), Max (from $100/mo for 5× with $100/mo API credits; 20× costs more with $200/mo API credits), Team Standard ($20–$25/seat/mo) and Team Premium ($100–$125/seat/mo), and Enterprise ($20/seat/mo plus API usage). Verified October 12, 2026 against claude.com/pricing.

    What is the difference between Claude Pro and Max?

    Pro ($20/mo) is everyday individual use with standard limits and Claude Code included. Max (from $100/mo for the 5× tier, now with $100/mo in API credits; the 20× tier is priced higher with $200/mo in API credits) gives 5× or 20× Pro usage per 5-hour session, higher output limits, and priority at peak traffic — built for people who live in Claude Code all day.

    Also cited in (9 Sept 2026): AI for Anything · Olakses.

    Related:reference hub · current models.

    Part of the complete guide: Claude Pricing, Plans & Limits

    API Pricing: Per-Token Costs for Every Model

    Current models as of October 12, 2026:

    Sonnet 5.5 (Current — shipped September 28, 2026)

    Input: $2/MTok. Output: $10/MTok. Prompt caching write: $2.50/MTok (5-minute). Prompt caching read: $0.10/MTok (halved from $0.20 on October 7, 2026). Batch: $1/$5. API ID claude-sonnet-5-5. Sonnet 5.5 is the current Sonnet.

    Sonnet 5 (Legacy)

    Input: $2/MTok. Output: $10/MTok. Same $2/$10 after the scheduled Sep 1 step to $3/$15 was cancelled. Not the current Sonnet.

    Opus 5.5 (Current)

    $4/$20. Current Opus.

    Fable 5.1 (Current)

    $10/$50. Cache read $0.25.

    Haiku 5.5 (Current — launched October 7, 2026)

    Input: $0.10/MTok (prompts ≤100k tokens), $0.50/MTok above. Output: $0.50/MTok (≤100k), $2.50/MTok above. Prompt caching read: $0.01/MTok (≤100k) / $0.05/MTok (above). 1M context. API ID claude-haiku-5-5. The new cheapest Claude model. No fast mode.

    Opus 5.5 ($4/$20) and Sonnet 5.5 ($2/$10) are the current-generation models as of October 12, 2026. Haiku 5.5 is the new cheapest model. Sonnet 5 remains listed at the same $2/$10 (legacy).

    Cost Optimization Features

    Batch processing saves 50% on token rates. Prompt caching cuts repeated context up to 95%. US-only inference 1.1×. Fast mode (research preview): up to 2.5× faster at 2× pricing (Opus 5.5 $8/$40).

    Platform Feature Pricing

    Managed Agents $0.08/session-hour + tokens. Web search $10/1,000 searches. Code execution: 1,550 free hours/month/org, then $0.05/hour per container.

    Team plans: Standard vs Premium seats

    This is where buyers get confused, because the two seat types look similar and cost very differently. Standard seats run roughly $20–$25 per seat per month; Premium seats run roughly $100–$125. The difference is usage allowance and admin controls — Premium is for the people on your team who burn through a Standard seat’s limits by lunch.

    → Claude Team Pricing: Standard vs Premium Seats (2026) — feature-by-feature breakdown and guidance on which seats to buy for which roles.

    Rate limits and usage limits: the frustration chapter

    Rate limits are the number-one Claude complaint, and the number-one thing buyers underestimate. Every plan has them, they differ between chat and API, and Team plan limits doubled in May 2026 after Anthropic’s compute deal with SpaceX’s Colossus 1 — except the Free plan, which was left out.

    → Claude Rate Limits: Every Plan & API Tier (2026) — exactly what the limits are at every tier, plus the workarounds that actually work.

    → Claude Team Plan Usage Limits & Pricing (2026) — what changed in the May 2026 doubling, and what it means per seat.

    Token limits and context windows, in plain English

    Context window is how much Claude can hold in its head at once; output limit is how much it can write in one response. As of late 2026: Opus 5.5, Sonnet 5.5, and Fable 5.1 carry a 1M-token context window; Haiku 4.5 carries 200K. Maximum output runs to 128K tokens on the big models. In practice: 1M tokens is roughly a shelf of books in one conversation.

    → Claude Token Limit: Context Windows, Output Limits, and What They Mean in Practice — per-model limits and what they mean for real workloads.

    Which model: Haiku vs Sonnet vs Opus

    Three model families, three jobs. Haiku is fast and cheap — the one you call a thousand times a day. Sonnet is the daily default, the balance of smarts and speed. Opus is the flagship — the one you reach for when the problem is hard and the answer matters. Fable sits above them as the current top-tier model.

    → Claude Models Explained: Haiku vs Sonnet vs Opus (September 2026) — pricing, context, speed, and which model to use for coding, writing, and API work.

    Getting started: API keys and the Console

    Two doors into Claude: the chat app (claude.ai) and the API (console.anthropic.com). Getting an API key takes about five minutes — create an account, add a payment method, generate the key. The Console is also where you watch your API spend burn, which you should do early and often.

    → How to Get an Anthropic API Key (2026 Quick Guide) — the five-minute setup, step by step.

    → Anthropic Console: Setup, API Keys & Billing (2026) — keys, credits, billing, and burn monitoring in one place.

    Students and education pricing

    The honest answer first: there is no public Claude Pro student coupon. The student path runs through partner universities — free premium access via your school email through Claude for Education. Note the naming trap: “Claude for Teachers” is the K-12 program, not the campus one.

    → Claude Student Discount & Education Pricing (2026) — what’s real, what’s rumor, and how the university path works.
  • Crumbl Cerulean Cookie: The Devil Wears Prada 2 Strategy

    Crumbl Cerulean Cookie: The Devil Wears Prada 2 Strategy

    For one week in spring 2026, Crumbl’s signature pink cookie isn’t pink. It’s cerulean. The same shade Miranda Priestly described twenty years ago in a four-minute monologue that has somehow become more relevant every year since the movie came out.

    If you’ve worked in marketing long enough, you already know the speech by heart. Andy Sachs makes the mistake of laughing at the difference between two belts that look “exactly the same” to her. Miranda doesn’t yell. She doesn’t roll her eyes. She walks Andy backwards through the supply chain — Oscar de la Renta, Yves Saint Laurent, the casual corner, the department stores, the clearance bin — until the lumpy blue sweater on Andy’s body is revealed to be cerulean, and the choice she thought she made was made for her, by the people in the room, two seasons earlier.

    The point of the monologue isn’t that fashion is powerful. The point is that culture is a current you’re already swimming in, whether you noticed it or not.

    That’s why Crumbl made their cookie cerulean this week.

    What Crumbl Actually Did

    The Devil Wears Prada 2 hits theaters May 1, 2026. The marketing window is therefore the last week of April through opening weekend. A film studio in this position has the same options every studio has always had: trailers, billboards, late-night appearances, partnerships with fashion magazines, the press tour. These work. They are also expensive, predictable, and increasingly invisible to the audience the studio actually wants — the millennial women who saw the original in a theater in 2006 and are now in their late thirties and forties, who do not watch network television, do not read print magazines, and have learned to scroll past sponsored content without registering it.

    What those women do is open Instagram on Sunday afternoon to see what flavor Crumbl dropped this week.

    Crumbl’s weekly drop is one of the most reliable consumer rituals built in the last decade. Six rotating cookies, announced Sunday at 6 p.m. local time, available for one week only. The pink sugar cookie is the constant — the brand’s signature, the cookie that tells you what store you’re standing in. When Crumbl makes the pink cookie a different color, the whole audience notices. That is the entire point of having a signature in the first place.

    So this week, the pink cookie is cerulean. The campaign doesn’t have to say Devil Wears Prada anywhere. The color does the work. And the color works because thousands of women between thirty-five and fifty look at it, recognize it instantly, and feel a small private smile of being in on it. Then they tell three friends, who tell three friends, and a partnership budget that would have bought eleven seconds of TV ad time during a streaming awards show instead becomes a week of organic Instagram impressions inside the exact demographic the studio paid Anne Hathaway to bring back.

    This is what marketing looks like when it works the way Miranda Priestly described it. Top down. Deliberate. Invisible to most people standing inside it. And almost free.

    The Cookie Isn’t About the Cookie

    Here is the part that most marketers miss when they try to copy this kind of move.

    Crumbl is not selling cookies. Crumbl has not been selling cookies for years. Crumbl is selling a weekly emotional event — a small, predictable, low-stakes moment of anticipation that thousands of people have built into their Sundays. The cookie is the artifact. The drop is the product. The flavor is the headline. And the customer is not paying $4.50 for a sugar cookie; they are paying $4.50 to be the kind of person who knows what dropped this week and can text their friend a photo of it.

    When Crumbl turns the pink cookie cerulean, they are not running a movie tie-in. They are giving their audience a more interesting thing to text about. The Devil Wears Prada 2 connection is a gift to the audience, not a sales pitch. It says: we know you. We know what you grew up watching. We know what made you laugh in 2006 and what makes you laugh now. We’re paying attention to the same things you’re paying attention to.

    That is a relationship. The cookie is the proof of the relationship.

    What This Means for the Rest of Us

    Most businesses do not have a Sunday cookie drop. Most businesses are not in a position to make a single product change that lands inside the cultural conversation by Tuesday morning. But every business has the same underlying opportunity Crumbl has, which is to notice what their audience is already paying attention to and then to participate in it without trying to monetize it directly.

    The mistake most companies make is thinking the lesson here is “do a movie tie-in.” That isn’t the lesson. The lesson is that the cookie was already cerulean before Crumbl made it cerulean — the cultural moment existed, the audience was already there, the affection for the original film was already in the room. Crumbl’s only job was to notice and to translate that noticing into a one-week color change. The marketing was free because the meaning was already paid for, by twenty years of a movie that refuses to die.

    For most operators, the equivalent move isn’t a cookie. It’s a one-line caption on a Tuesday post. It’s the color of the section header on your homepage. It’s whether you remembered the thing your customer said offhand six months ago and brought it up the next time they walked in.

    The cerulean cookie is a reminder that connection is not built on advertising spend. It is built on attention.

    Why Tygart Media Is Cerulean Now

    This article exists because of a cookie. Specifically, because Stefani Tygart — co-founder of Tygart Media and a person who has loved The Devil Wears Prada since the year it came out — saw the cerulean drop on Sunday, brought one home Monday, and made the connection out loud over coffee Tuesday morning. She didn’t pitch a campaign. She just noticed something and said it. By Wednesday, the homepage of Tygart Media was cerulean.

    This is the part of running an AI-native media company that does not show up in any pitch deck. The infrastructure matters. The Notion control plane matters. The deployment pipelines and the model routing and the schema stack all matter. But none of it works without the human at the front of it noticing what’s worth paying attention to and saying it out loud at the right time.

    Stef notices things. That is the job. The cookie noticed her back, and now we’re cerulean for a while, and somewhere a Crumbl marketer in Lindon, Utah is having a very good week.

    That’s how culture moves. That’s the monologue. That’s the whole lesson.


    The Devil Wears Prada 2 opens in theaters May 1, 2026. Crumbl’s cerulean pink cookie is available the week of April 28, 2026 only.

  • AI-Native Company Patterns: How Notion Agents Reshape the Org Chart

    AI-Native Company Patterns: How Notion Agents Reshape the Org Chart

    Related on Tygart Media: second-brain architecture · Notion second brain setup · Notion Command Center.

    The 60-second version

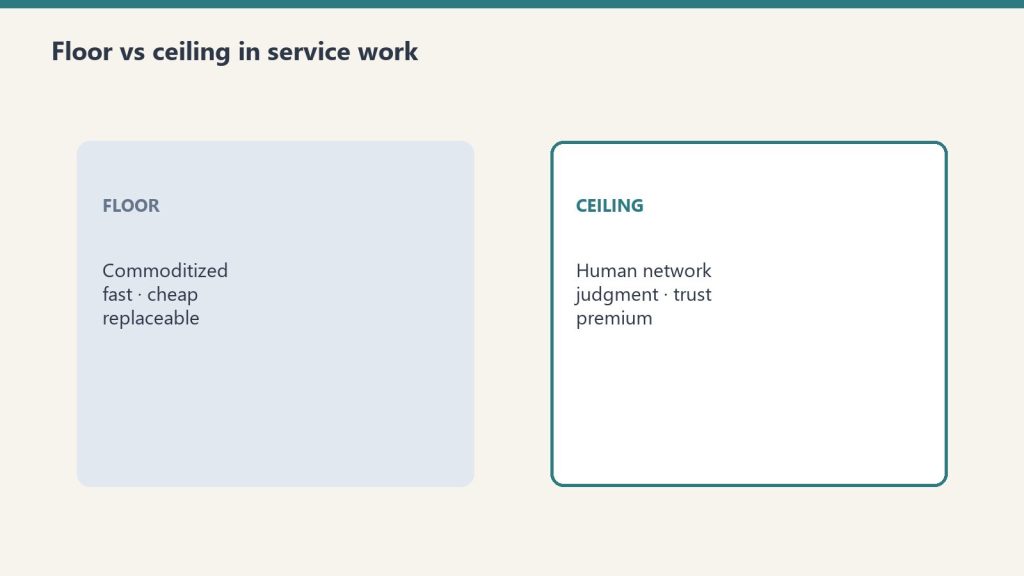
    The honest framing is uncomfortable: Custom Agents handle the work that historically required junior operational staff. Status reports, intake processing, lead enrichment, weekly digests, calendar prep, recurring deliverables. AI-native companies don’t add agents alongside that work — they replace that work with agents and reassign the humans to what humans actually do better. Editorial judgment. Client relationships. Strategic decisions. Handling exceptions. The org chart shifts. Pretending it doesn’t is denial.

    What roles change first

    Floor versus ceiling cards for commoditized work and human-network premium
    What roles change first.

    Five roles where the work compresses fastest:
    – Coordinator/admin work — meeting scheduling, calendar prep, follow-up tracking. Largely automatable.
    – Junior analyst work — data pulls, report generation, basic synthesis. Largely automatable.
    – First-tier intake — categorizing inbound leads, support tickets, content submissions. Largely automatable.
    – Status communication — weekly updates, project digests, standup notes. Largely automatable.
    – Documentation upkeep — keeping wikis, runbooks, and SOPs current. Largely automatable with Autofill + agents.
    This isn’t a prediction; it’s already happening in operator-led companies that have built Custom Agents for these workflows.

    What roles get more important

    The same shift makes other roles more valuable:
    – Editorial leadership — defining voice, judgment, standards. Agents follow standards; they don’t write them.
    – Relationship work — sales relationships, client management, partnerships. Humans signal humanity.
    – Exception handling — the 5% of cases that don’t fit the agent’s pattern. This becomes the human’s whole job.
    – System design — building the agents, prompts, skills, and workflows themselves. The new ops role.
    – Strategic work — deciding what the company should do, not how to do it.

    The new org shape

    Three stacked layers: chat UI, tools, agent runtime
    The new org shape.

    A simple four-layer pattern:
    1. Agent operators — humans who design, monitor, and improve agent workflows
    2. Exception handlers — humans who catch what agents can’t handle
    3. Relationship leads — humans who own external-facing work that requires being human
    4. Strategists — humans who decide what to do
    Notice what’s missing: layers of middle management whose primary job was coordinating between doers. Agents reduce coordination overhead because they don’t need it.

    How to transition

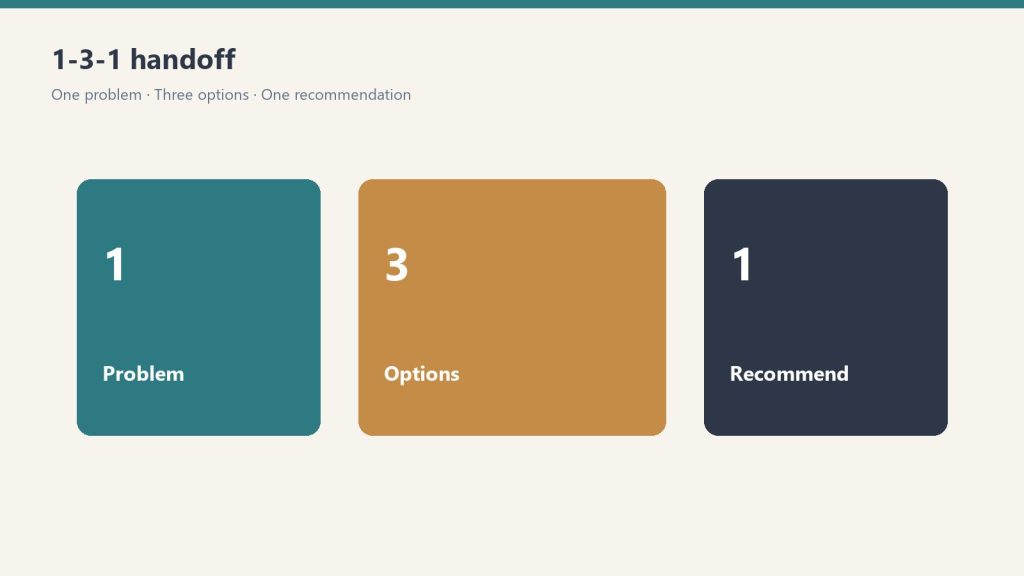
    Three panels showing one problem, three options, one recommendation
    How to transition.

    For most operators, the shift looks like:
    – Stop hiring for roles where agents could do 70% of the work. Build the agent instead.
    – Reassign current staff toward exception handling, relationship work, and editorial judgment.
    – Invest in agent operator skills — prompt design, workflow design, rubric design.
    – Compress the org chart. Fewer layers, broader roles, sharper accountability.
    This is a multi-year shift, not a quarter. But the operators who start now have years of compounding advantage over those who delay.

    The risk

    The risk is reorganizing too fast and losing institutional knowledge that lived in the eliminated roles. Agents don’t pick up tribal knowledge automatically. The transition needs to capture what departing staff knew and encode it in the second brain so the agents can use it.

    What to read next

    Editorial Surface Area, Second-Brain Architecture, ROI Math, When Not to Use a Notion Agent.