The short answer: plan for longer than anyone tells you at first. A straightforward repair: 3–6 months. A major fire rebuild: typically 9–18 months. A total loss in a disaster zone with contractor and permit backlogs: it can exceed two years. The delays are rarely the construction itself — they’re permits, insurance negotiations, mortgage-servicer draw inspections, material lead times, and code upgrades.
The phases and what each one really takes
Assessment and documentation (2–6 weeks). Adjuster inspections, your contractor’s scope, engineering assessments if structural damage is involved. Don’t rush this — everything downstream depends on the documentation.
Insurance negotiation (1–4 months). The estimate, the supplements, the back-and-forth. This runs in parallel with other phases if you push it.
Design and permits (1–6 months). Architectural plans for significant rebuilds, then the permit queue. After a regional disaster, the queue is the bottleneck — jurisdictions get overwhelmed.
Demolition and site prep (2–6 weeks). Debris removal, hazardous material abatement (asbestos and lead testing in older homes), site clearing.
Construction (4–12 months). The actual build. Weather, material lead times, and subcontractor availability all bite here.
Final inspections and move-in (2–6 weeks). Certificate of occupancy, punch list, the last draw release from your mortgage servicer.
What actually causes the delays
Permit backlogs after regional disasters — the single biggest timeline killer.
Code upgrades. Rebuilding to current code (electrical, seismic, wildfire-hardening) adds design time and cost — and insurers don’t always cover the upgrade portion.
Material lead times — windows, trusses, and specialty items can run months.
Contractor availability in disaster zones, where every builder is booked.
Editor's Note
Plan your housing for the pessimistic timeline If the optimistic estimate is 9 months, arrange housing you can extend to 14. Breaking a lease or scrambling for housing mid-rebuild is more expensive than over-planning. And make sure your ALE coverage math works for the long version. Choosing temporary housing →
Informational only — not legal, financial, or insurance advice.
Timelines vary enormously by damage type, jurisdiction, and disaster scale. These are planning ranges, not promises — your contractor’s schedule for your project is the number that matters.
Rebuild timeline reality
How long rebuilding actually takes
Phase
Typical duration
Cleanup + assessment
1–3 months
Design + permits
2–6 months
Construction
6–18 months depending on scope
After a regional disaster, contractor backlogs can double these numbers. Get in line early.
There’s a post going around that says: if you can rank in ChatGPT, you’re way ahead of the game, your leads from ChatGPT will increase, invest now.
Here’s the problem with that sentence. There is no “ChatGPT” the way there’s a phone book. There are rooms. And the person in each room is a different person, sitting in a different chair, at a different time of day, asking a different kind of question.
A free-plan mobile ChatGPT user on the toilet is not the same human as a Claude user inside their desktop looking up technical documentation at 10 in the morning. Treating them as one audience because the logos are similar is how businesses end up advertising B2B services on a consumer feed — the same mistake, wearing a new jacket.
The five rooms
Room one: free ChatGPT on a phone. Consumer questions. Evenings, couches, commutes. What’s a good car stereo, write my cover letter, explain this homework. Enormous volume, almost no B2B buying intent.
Room two: paid ChatGPT at a desk. Prosumers and knowledge workers who chose it as a tool. Better questions, work hours, some buying intent — when the question is about their own workflow.
Room three: Claude at a desk. Developers, analysts, technical professionals. This is the room that reads documentation for a living. Weekday-shaped, deep, specific.
Room four: Copilot inside Edge and Office. The corporate room. These people didn’t choose an AI — it arrived inside the tools their employer already runs. Facility managers, compliance staff, operations people, asking work questions in work language, mid-task.
Room five: Gemini inside Google search. Everyone, for everything, at search scale. The broadest room and the shallowest intent per question.
Same species of technology. Five different demographics. “Get cited in AI” means nothing until you say which room.
What the counting says
I count AI citations for a living — six months of Bing AI Performance data across my own network, 1.6 million citations and change. The rooms are not a theory. They’re in the numbers.
On Tygart Media, the single most-cited page is a Claude AI pricing explainer — 1,388,909 citations. The audience for this site is technical professionals, and the citation traffic is weekday-shaped: it rises when people are at work and flattens when they aren’t. Room three, behaving like room three.
On Healthcare Facility Hub — a site for hospital facilities and infection-control people — Microsoft’s AI surfaces cited 188 pages a total of 43,994 times in six months. The top pages are an ICRA matrix (4,067 citations), hospital evacuation planning (2,766), ASHRAE 170 ventilation requirements (2,435), NFPA 101 life safety (1,802). The questions behind them read like this: what has to be in a facility’s emergency preparedness plan about emerging infections; which fire safety feature keeps smoke in one zone. Nobody asks those questions from a couch. Those are room-four questions — asked at a desk, inside a Microsoft environment, by someone whose job depends on the answer being right.
Two sites. Two rooms. Neither audience is in the room the hype is selling.
The test that settles it
Before you pay anyone to get you cited “in ChatGPT,” ask one question: which room is your buyer sitting in when the buying question forms?
If you’re selling to hospital facilities staff, your room is Copilot at a desk, and the content that wins there is an ICRA matrix, not a viral post. If you’re selling car stereos, room one is genuinely your room, and God bless. The tactic isn’t wrong or right — the fit is.
Anyone who can’t tell you which room they’re putting you in is selling you the label. The label is the one part that doesn’t matter.
Will Tygart runs Tygart Media. The citation counts above are from his own six-month Bing AI Performance board, counted nightly. The $97 AI Citation Quick-Scan exists because “which room cites you” is a measurable question: https://tygartmedia.com
Everybody talks about AI citations like they’re weather. Somebody reads somebody else’s report, shows you a screenshot of a ranking, and that’s supposed to mean something.
A screenshot is a rumor. I wanted a count.
So we built what I call the bait board. It’s simple: every page on this site is bait. A “bite” is when an AI answer — Bing’s, in our case, because that’s where we pull the data — cites one of your pages. If you can’t count it, you can’t improve it. The board counts it.
The board, as of this week
Over the last six months, Tygart Media has pulled in roughly 1.6 million AI citations. Across the two six-month windows we’re comparing, 997 distinct pages have been cited. 870 of them are biting right now.
One page does most of the heavy lifting: our Claude AI pricing page, at 1,388,909 citations. That’s not a typo. That’s what happens when a page becomes the answer to a question a lot of people ask every day.
Every page on the board lands in one of four buckets:
DEFEND — 945 pages. Biting now. Somebody out there thought it was good, and an AI keeps handing it out as the answer. You protect these. Iterate in place, never rename them, and check whether you’re still holding the seat — because a citation is a seat, and nobody holds your seat for you.
RE-BITE — 52 pages. Proven bait that went quiet. They were cited, then they weren’t. Sometimes a competitor wrote the Costco-hat answer with the glasses and the supply chain added on, and took the seat. Sometimes the page just went stale. Either way: patch it in place and cast again.
SOAK — 121 pages. Published, no bite yet. Let compounding do its work. Not everything needs touching.
PRUNE — 61 pages. Never picked up. Stop feeding them.
The data comes down every night — three CSVs out of Bing Webmaster Tools: AI Performance, grounding queries, and pages, six-month window. I download them by hand on purpose. Don’t automate yourself out of this stuff. When you pull it yourself, you notice the weird one. You click through. You find something.
And the method matters more than the tool. It’s the tactic, not the tool — everybody’s tools are calculators. Whatever way you do this, do it the same way every time, because the delta is the information. Change your method every week and you’ll never know whether the number moved or you did. I used to look at this every 28 days. The world doesn’t run on 28 days anymore. Clarity defaults to three days, and honestly, three days is about right now. I check daily. I’m scared not to.
But here’s the thing I actually sat down to teach this week, and it’s the thing the board taught me — three patterns I can only see because the count runs every night.
Pattern one: the fastest source is not the cited source
Look at the dead bait. A big share of it is our timed storm watches — the automated storm updates that publish as weather moves through a part of the country, update, and expire.
They almost never get cited by Bing. Almost never.
I think I know why. When the moment passes and the engine settles on an answer, it doesn’t cite the quickest source. It cites the original, the best source. On a storm, we’re the quickest source there is — we’re built for speed, the update is live while it’s still raining. But quick is not the same as best, and after the fact, Bing goes back and picks the best. That’s not us, and on a timed watch it was never going to be us.
That doesn’t make the storm work useless — it feeds other sites of ours, and being first matters in other places. But if you’re measuring it by Bing citations, you’re grading a sprinter on a marathon course. Know which race each page is running.
Pattern two: a good article that dies at three weeks usually died in the title
The other thing I see on the board: solid articles — some of them op-ed pieces I’m proud of — that come up on three weeks old and fall off a cliff. Not bad articles. Articles that never made the first pass.
When I look at those, it’s the title. The title didn’t tell the engine, or the reader, what question this page answers. So it never got picked up in the first place, and by week three there’s nothing left to defend.
The fix isn’t rewriting the whole piece. The fix is two moves:
Retitle it so it answers the actual question in the words people ask it.
Give it something evergreen inside — a chart, a reference block, a section that stays true after the moment passes. An op-ed with an evergreen chart in it has something durable to be cited for. A storm piece with a standing reference section — what a project manager does when this kind of storm hits, say — has a reason to exist after the rain stops.
Timely gets you published. Evergreen gets you cited. A piece that only has the first one is on a three-week clock whether you know it or not.
Pattern three: old pages that bite again are sensors
This is the one that changed how I run the board.
Months ago, out of our Everett work, we wrote about a Boeing contract — the SPIA contract. Old news. Done. Except it isn’t: that page keeps showing up. It keeps getting cited.
My first instinct, months back, would have been to call that noise. It’s not noise. It’s a sensor going off.
If an old page starts biting again, it means the world came back to that topic and there wasn’t much else there. Thin coverage. We saw the same shape on one of our other properties — a sustainability piece about cosmetics CEOs that narrowed down, over time, to two or three companies actually doing the thing. The page didn’t change. The field did, and the page was the instrument that showed it.
Think about it the other way: say we wrote up an Everett AquaSox game a while back, and one of the kids in that game makes a World Series roster in a year or two. That old game page could light up again — and when it does, it tells you something is happening before the crowd writes about it. The re-bite is the first inkling. A disturbance, if you’ll forgive the reference.
So I’ve stopped treating old pages as prune candidates by default. Some of them aren’t content anymore. They’re instruments. You don’t throw away a gauge because it’s been quiet — the quiet is the baseline, and the spike is the signal. A re-bite on an old page is market intelligence, and it’s free: the page is already written, already out there, already costing you nothing to leave in the water.
Prune still exists — 61 pages earned it. But before a page goes in that bucket now, it gets one more question: is this dead, or is this a sensor that just hasn’t gone off lately? Those are very different things to delete.
The seat, and keeping it
Here’s the whole doctrine in one breath: get cited and you’ve taken a seat. Leave, and someone’s sitting in it when you come back. The engines don’t owe you the chair. So you count — nightly, same method, same window — and you sort every page into defend, re-bite, soak, or prune, and you listen to the old pages, because they’re telling you where the world is thin.
That’s the bait board. It isn’t fancy. It’s three downloads, four buckets, and the discipline to do it the same way tomorrow.
If you want to run this yourself
I teach this in layers, same as everything else we sell:
The Bait Board one-pager (free PDF). The four buckets, the three nightly downloads, and the counting rules on one page. Print it, tape it over your desk, start counting.
The Bait Board Field Guide ($7 PDF). The full method: how the six-month window works, how to read fresh bites against dropped pages, the churn math, and the sensor test — how to tell a dead page from a quiet instrument before you prune it.
The Bait Board, Book-for-Bots edition ($17). The method written for the machines as much as for you — structured so an AI assistant can run the nightly sort with you: bucket definitions, decision rules, and the worked examples from this site’s own board, including the storm-watch and three-week-title findings above.
And if you’d rather have it done with you: the AI Citation Quick-Scan ($97) is where we run your pages through this same count and hand you the board; the $450 tier builds the board into a standing weekly practice on your site; and the $2,250 tier is the full desk — board, refresh queue, and the sensor watch running as a system. Same ladder we run here. The count comes first either way.
Start with the count. Everything else is commentary.
I run a small media shop, and most of what we ship now — websites, measurement tools, videos, test programmes — gets built the same way: I describe what I want, an AI builder writes it, and my hours go to steering and checking instead of typing.
Vibe coding is describing what you want built in plain language and letting an AI builder write the code — you steer with intent and judgment, and it does the typing.
Andrej Karpathy put the name on it in early 2025: “fully giving in to the vibes.” The phrase stuck because it is honest about the feeling. You stop writing the code line by line. You talk, the machine builds, and you judge what comes back. What the phrase leaves out — and what nobody tells you until you run a real shop this way — is where the work actually went. It didn’t disappear. It moved.
What it looks like from this desk
Nobody here opens a blank file and starts chatting at a builder and hoping. The work runs on written work orders: a commission that says what the finished thing is, what it has to connect to, what it must never do, and what proof comes back when it’s done. The builder — we run several, in different seats, with different jobs — executes against that order. Then the return gets checked: not skimmed, checked. Claims get compared against sources. Numbers get tied back to where they came from. Pages get fetched live and read the way a visitor would read them.
That seat discipline matters more than the model does. A builder with a lane, a written order, and a receipt to produce behaves like a contractor. A builder with a vague prompt and no checking behaves like a confident intern who never sleeps and never admits he’s lost. We wrote up how the seats are governed in our piece on running six AI seats on one business, and the short version is: the structure is the skill. The prompt is the smallest part of it.
What shipped
Talk is cheap in this trade, so here is what actually went out the door from this shop, built this way:
A citation-measurement programme across a fleet of niche sites. We track where AI answer engines cite our pages and where they don’t, topic by topic, site by site — that map drives what gets written next, instead of guessing.
A nightly board that re-pulls our own citation numbers and republishes them. Every night it goes back to the source data, rebuilds the tally, and posts the current standings. If the numbers move, the board moves. Nobody hand-types a figure into it, which means nobody can quietly round one in our favour.
Article-to-video pairs, built in-house. Script, scenes, narration, captions — produced here, published as pairs: the article and its video, each pointing at the other. Nine pairs are live. The most recent one is Half the Citations Sit on Three Pages, which is itself a finding out of the measurement programme — the work feeds the work.
An anchor experiment, installed live on November 7. We put anchor links on article section headings so each section can travel as its own citable piece — the way a video chapter does. It’s running now and being measured. It might work. It might not. Either way we’ll know from the data, not from a feeling.
A full inventory-test programme run against a real product. Not a demo on our own toy data — a scored test, run in the open inside the shop, with results written down whether they flattered anybody or not.
That’s the part of vibe coding the tool ads get right: the volume is real, and a small shop can ship like a bigger one. Now the other half.
What broke
Everything on this list cost us time, and every item on it taught the same lesson from a different angle.
Invented facts, caught at the gate. Our page-refresh programme ran in waves, and a pattern showed up in the returns: builders writing plausible, confident, wrong facts into refreshed pages — vendor details, protocol claims, numbers that sounded right and weren’t. None of it shipped, because every claim got checked against a source before publish. But “none of it shipped” is doing a lot of work in that sentence. Without the gate, it all ships. That is the default outcome of vibe coding without a checker: fluent fiction at production speed.
A page and its PDF, saying two different things. We’d fix a page and leave its downloadable PDF stale, so a reader with the old file in their own system was working from numbers we’d already corrected. The fix became a standing rule: a page and its download are one asset. The PDF gets regenerated from the corrected content in the same run, or the edit doesn’t ship. The builder never once flagged the drift on its own. A human had to notice the pattern and make it a rule.
Runs that stalled on things nobody priced. Quota running out mid-programme. A token that didn’t cover the sites the job needed. A browser on a busy desktop that couldn’t be borrowed. Each one stopped a run cold, and each one was knowable before the run started — somebody just hadn’t checked the whole path to the finish.
A redirect job priced at the start instead of the finish. The estimate covered beginning the work, not completing it, and the job froze partway with the loose ends live. It got sorted, but the scar tissue became another rule: price the finish, not the start — the whole path, including whether the human has to stand there while it runs.
Read those four back and the pattern is plain: the builder’s confidence is not evidence. Not one of those failures was a typing failure. The code worked. The words were spelled right. What failed was truth, scope, and follow-through — the exact things a confident machine will never flag about itself. The operator’s checking is not a quality step added to vibe coding. It is the product. The building is the commodity.
The honest split of labour
Here is how the work actually divides in this shop. The machine is fast at the typing and tireless at the volume. It will rebuild a board every night forever and never get bored. It will draft the fortieth page in a wave with the same energy as the first. It does not get tired, and that is genuinely new in the world — a two-person shop with tireless hands.
The human carries everything the machine can’t: the intent (what should exist and why), the taste (this is good enough, this is not), the fact-check (this claim is true, that one is invented), and the stop button (this run ends here, this door doesn’t open). Those four things sound soft next to “writes code.” In practice they are the whole job, and they were always the whole job — the typing was just where the hours used to hide.
We have a phrase for it here: partway is the point. The skill isn’t prompting. The skill is knowing which 80% to let run and which 20% is yours — and never confusing the two. Let the machine run the 80% and it will carry you further in a week than a year of typing. Hand it your 20% — the judgment, the verification, the calls — and it will carry you straight into a wall, politely, at speed, with perfect formatting.
What it is not
It is not “anyone can build anything now.” Anyone can get something built. The question was never whether the machine can produce the thing — it’s whether the thing is right, and knowing that takes judgment the subscription doesn’t include. Judgment is the scarce input, and it’s scarcer than it was, because now it has to cover ten times the output.
It is not the end of programmers. Somebody still has to know when the output is wrong, and “wrong” gets subtle fast: the code runs, the page loads, and the fact on it is invented. The people who’ll do best in this aren’t the ones who type fastest or prompt cleverest. They’re the ones who can read a return the way an editor reads a draft — for what it claims, not how it sounds.
It is not a vibe you can skip verifying. The name is the most dangerous thing about it. “Vibe” suggests the checking is optional, a personality choice for nervous people. In a shop that ships to real readers, verification is the difference between a production system and a fiction generator with good uptime. Give in to the vibes on the typing. Never on the truth.
So here’s where this shop lands on the term. It sounds like the work got softer — like building things turned into lounging with a laptop and a feeling. From inside, it got more honest. The typing used to hide the judgment; now the judgment is all that’s left, and it shows. A piece either has its receipts or it doesn’t. The facts either check or they don’t. The thing either shipped or it’s a story about shipping.
That’s a harder standard than the old one, and it’s a better one. We’ll keep building this way.
Frequently asked questions
What is vibe coding?
Vibe coding is building software and content by describing what you want in plain language and letting an AI builder write the code, while you steer with intent and judgment. Andrej Karpathy named it in early 2025, describing it as “fully giving in to the vibes.” In a working shop, the steering and the checking are most of the job.
Is vibe coding good or bad?
Neither — it’s a method, and the result depends on what surrounds it. With written work orders, clear boundaries, and a hard check on everything before it ships, it lets a small shop produce at a scale that used to take a team. Without the checking, it produces confident mistakes faster than any method in history. The vibe is not the variable. The verification is.
Do you need to know how to code to vibe code?
You need to know how to judge, which is a different thing. You don’t have to write the code, but you do have to be able to tell whether what came back is right — whether the facts check, the scope held, and the thing actually does what it claims. If you can’t tell, you need someone beside you who can. That judgment is the part you can’t hand off.
Everybody is selling “agentic AI” right now, and most of the selling is conference talk — slides about autonomous everything, written by people who don’t run anything with it. I run a small media company with it. Every day. So here’s the definition from the floor of the shop instead of the stage.
Agentic AI is AI that doesn’t just answer. You give it a job — with boundaries, tools, and a way to report back — and it carries the work through the steps itself, without a person pushing each one along.
That’s the whole distinction. A chatbot waits for your next prompt. An agent takes a commission and goes and does the work: reads what it needs, uses the tools it’s been handed, makes the small decisions inside its lane, and comes back with the finished thing and the proof. Whether that works or falls apart depends entirely on how the shop around it is arranged — and the arrangement is the part nobody puts on the slide.
The seats: nobody here does everything
The first arrangement decision: the work is split across named seats, and each seat has a lane.
The chief-of-staff seat holds the context. It keeps the memory of what’s been decided, what’s owed, who’s who, and what I said on a clear-headed day — and it turns my direction into written work the other seats can run. It’s the filter, not the boss.
The code seat builds. When something needs to be made — a tool, a page, a fix — that seat writes it and shows its record. I keep the code seat’s record in public for a reason: a seat that builds should be able to show what it built.
Scout seats go and look. Research, censuses, reading a market or a competitor end to end and coming back with what’s actually there — not what the summary said was there.
The executor seat runs work orders on the machine where the work lives. It does the hands work: publishes, edits, uploads, the long multi-step runs I don’t have the hours to sit inside.
I wrote up how I run six AI seats on this business — the governance, the lanes, and the rule that matters most: a seat does not freelance outside its lane. The moment an agent starts deciding on its own what else might be a good idea, you don’t have a staff. You have a rumor mill with write access.
The work order is the unit of trust
Seats don’t get vibes. They get work orders — written commissions, one job each, built before anything runs. A work order in this shop carries four things:
The whole price, stated once, up front. Everything the job will touch, everything it might cost in time or taps from me, named before it starts. Nothing gets discovered as a surprise blocker halfway through — or if it does, that’s a defect in the order, and we say so.
The context, baked in. The executor shouldn’t have to guess who I am, what the site is for, or how I talk. The order carries it, so the work comes back sounding like this shop and not like a template.
The boundaries. Some doors are mine alone: money, credentials, anything that sends to another person, anything that can’t be undone. Those are drawn as lines in the order itself. Inside the lines, the seat has real latitude. Across them, it stops and comes back to me.
The receipt standard. Exactly what proof comes back with the finished work — measured values, live links, counts — written into the order before the run, not negotiated after it.
Think of it like commissioning a piece of furniture. I don’t stand over the maker’s bench. I write the commission well enough that the piece can only come back right — and then I do the finish work when it arrives.
Receipts are the proof, because “done” is a claim
Here is the part of agentic work the demos skip: an agent can tell you work happened that did not happen. Not out of malice — out of the same confident fluency that makes it useful. It will describe the email it sent, the page it fixed, the file it saved, in perfect detail, and some of the time it will be describing a thing it only intended to do.
So in this shop, nothing is done because a seat says so. It’s done when the live thing checks out. The published page gets fetched and read. The number gets tied back to the source it came from. The export gets counted, not described. Every run comes home with receipts, and a second seat does the finish check against the live result before I ever hear the word “done.”
That’s not paranoia; it’s the load-bearing wall. The whole Receipts series on this site exists because citation claims kept turning out to need a second look — the piece where half the citations sat on three pages started as a seat’s confident summary and ended as a very different story once somebody counted. The receipt discipline exists because of that failure mode. Not despite it.
What the human does all day
People ask what I do if the agents do the work. The honest answer: the parts that were always the job.
I bring the direction and the instinct — which door is worth walking through, which idea smells wrong even when the reasoning sounds fine. I make the judgment calls: pricing, commitments, anything with another person’s name on it. And I hold the one-way doors. A send, a payment, a deletion, a credential — those wait for my tap, every time, by design and not by limitation.
What the system holds for me is the context I can’t: every decision, every receipt, every open loop, across more projects than one head carries. I don’t have to remember where things stand. I have to decide what happens next — and when I’m tired or emotional and about to make a call my clear-headed self wouldn’t make, the system holds the line with what I said when I was thinking straight. That’s the trade, and it’s a good one.
The honest limits
Anybody who runs agents for real can tell you the failure list, so here’s mine. Agents drift off the brief when the brief has a soft spot in it. They conflate two similar jobs — same-shaped folder, different work — and run the wrong one beautifully. They price the start of a job and not the finish, so a run looks cheap until you count the stalls, the re-reads, and the tap it needed from me at the worst moment.
The craft isn’t pretending the seats are flawless. The craft is the guardrails and the checking: the input manifest verified before the run starts, the step-zero check that clears a suspect before anyone calls it broken, the receipt read against the live thing instead of against the report. Every scar on the process here is a rule now. That’s how a shop gets good at this — not by buying a smarter seat, but by writing down what the last failure taught it.
What “agentic” means with the talk stripped off
Strip the conference language away and agentic AI is this: a small business running like it has a staff. Research that actually gets done. Pages that actually get published. Records that actually get kept. A two-person company doing the carrying work of a much bigger one — with the receipts to show for it, because the receipts are the only version of the story worth telling.
We’ve published dozens of pieces from inside this work — the failures included, especially the failures — because the shop is the argument. If agentic AI is going to mean anything outside a demo, it’ll mean shops like this one: named seats, written orders, hard boundaries, and proof at the end.
Questions people ask me
What is agentic AI in simple terms?
It’s AI you give a job instead of a question. You set the boundaries, hand it tools, and tell it how to report back — then it does the steps itself and returns the work with proof, instead of sitting there waiting for your next prompt.
What is an AI agent vs a chatbot?
A chatbot answers and stops. An agent acts: it reads, decides small things inside its lane, uses tools, and works through a multi-step job over time. The chatbot is a conversation. The agent is a commission — and commissions need boundaries and receipts in a way conversations don’t.
How do multiple AI agents work together?
The same way a small staff does: split lanes and written handoffs. One seat holds context and writes the work orders, specialist seats build or research, an executor runs the job where the work lives, and a second set of eyes checks the result against the live thing. The coordination isn’t magic — it’s the paperwork, done properly.
Do AI agents replace employees?
In this shop, there’s no version where a seat makes the judgment calls, holds the relationships, or takes responsibility for a one-way door — that’s my job and it stayed my job. What the seats replaced is the carrying: the hours of execution between a decision and a finished, checked piece of work. For a small business, that’s the difference between ideas that die in a notebook and work that ships.
Yesterday we published a test: 52 calls to Muse Spark 1.3, seven kinds of work, every rung of the reasoning dial, everything scored against ground truth. Our result was not close. The cheapest setting never lost — and twice, extra thinking was the failure itself. We set the fleet’s operating rule on that evidence and moved on.
Then a counter-check showed up, the way we’d want one to. BenchLeader — a third-party site that republishes benchmark results from their original publishers — carries a full rung-by-rung row for Muse Spark 1.3 on CursorBench, a coding benchmark. On that ladder, the dial pays at every single rung. If both results are real, they can’t both be the whole story. So we read the ladder the way we ran our own test: numbers first, bases stated, no vibes.
The ladder’s numbers
CursorBench, Muse Spark 1.3, as published on BenchLeader (data as of November 8, 2026; the underlying results are Cursor’s, dated September 2, 2026):
Rung
Tasks solved
Rank on the board
minimal
24.3%
#79
low
29.3%
#72
medium
32.6%
#64
high
33.4%
#59
xhigh
37.5%
#48
max
41.6%
#38
No rung regresses. Every step up solves more tasks than the step below it — +5.0 points from minimal to low, +3.3 to medium, +0.8 to high, +4.1 to xhigh, +4.1 to max. Across the whole ladder that’s +17.3 points: at max, the model solves roughly 1.7 times the share of coding tasks it solves at minimal. Ranks are among 82 model configurations with a published result on that benchmark.
What is CursorBench? In BenchLeader’s words, it’s “Cursor’s internal coding-agent evaluation”: coding tasks run inside Cursor’s agent, with the reasoning level and cost per task recorded, scored as the percent of tasks solved. Two honest labels belong on it. It is published by a coding-tool vendor — BenchLeader itself flags “harness is theirs” — and BenchLeader carries it for reference only; it doesn’t count toward their composite index. It is still the only rung-by-rung coding evidence for this model that we know of, and it points the opposite way from ours.
Our numbers, on the record
Our battery was 52 API calls to the contributor tier of Muse Spark 1.3, November 6–7, 2026, identical prompts at multiple settings, mechanical scoring. The buyer-brief judgment task scored identically at every rung — minimal got it for 776 reasoning tokens and 6.5 seconds, xhigh for 6,847 tokens and 50 seconds. Verdicts at scale: 120 out of 120 at low, 120 out of 120 at xhigh. Planning: provably optimal schedules at every rung.
And the coding cell — the one this ladder speaks to directly. Our debugging task was one function with three planted bugs. Every rung found the inverted discount logic and the rounding bug; the cheapest setting found all three. One xhigh call spent its entire 8,000-token budget thinking — 7,998 reasoning tokens — and returned an empty answer. It thought so long it never spoke. Minimal answered the same task correctly with 500 reasoning tokens.
Our published conclusion: on our work, extra reasoning bought latency, not quality, and the operating rule became low by default, with xhigh and max earned only by a demonstrated failure at low.
Both numbers are real. The tasks aren’t the same.
Put the two bases side by side and the disagreement gets smaller and more specific:
Task shape. CursorBench runs coding tasks inside an agent — sustained, multi-step work where the model plans, acts, reads errors, and recovers over many turns. Our battery was single API calls with a checkable answer. Our one coding task was a single function, solved — or stalled on — in one shot.
Tier and harness. The ladder ran Spark 1.3 inside Cursor in September. We ran the contributor tier through the API in November.
Measurement. The ladder reports the percent of a task set solved. We scored one sample per cell against ground truth — a limit we printed in the original piece.
Here is our reasoning, labeled as reasoning and not as either source’s claim: the reconciler is task shape. On a short, bounded task with a checkable answer, the first think is the one that does the work; rungs above it buy patience-testing latency, and occasionally a stall. On a long agent run — hold a codebase in mind, take twenty steps, survive your own mistakes — extra reasoning has something real to chew on, and the ladder pays for it. That reading fits the anomaly we flagged in our own data: the rungs behaved like task-shaped budgets, not fixed ceilings. It also fits the limit we printed: we never tested sustained work. CursorBench did — or rather, Cursor did.
What would change the verdict
Not an argument. A run. The test that settles this for our shop is our own coding work at every rung: real work-order-shaped jobs — a written spec, more than one file, a module plus a test suite with a mechanical pass/fail — at minimal, low, high and max, in one harness, more than one sample per cell, receipts published the way the first battery’s were. If low matches max on those, our rule stands for coding too, and the ladder is a story about Cursor’s harness. If max pulls away as the jobs get longer, the rule gets a carve-out: the rung follows the length of the task. Either result is publishable. We’ll run it and print what we find.
The bottom line for an operator
If your work is short, bounded calls — extraction, checking, verdicts, drafting to spec — run low. We have 52 metered calls that say the expensive rungs buy you nothing there, and our default hasn’t changed.
If your work is a coding agent chewing through real jobs, the only rung-by-rung evidence that exists says turn it up: on Cursor’s own ladder, max solves 41.6% of tasks against minimal’s 24.3%, and every rung between them earns its step. That evidence is a vendor’s, run in the vendor’s harness, on September’s model build — hold it at that weight, not more.
The mistake isn’t picking the wrong rung. It’s running one default across both shapes of work and calling it a policy. The dial is real. What it pays for depends on the length of the job in front of it — and now there are two published result sets, ours and Cursor’s, that say exactly that from opposite ends.
Sources: BenchLeader, “Muse Spark 1.3” model page and CursorBench leaderboard (data as of November 8, 2026; CursorBench results published by Cursor via the Epoch AI Benchmarking Hub, Spark 1.3 results dated September 2, 2026). Our dial test: “We Ran Muse Spark’s Reasoning Dial Through 52 Calls. The Cheapest Setting Never Lost.” (Tygart Media, November 7, 2026), method and receipts in the Tygart-OS fact-gated fleet record on GitHub.
Want this thinking applied to your own work? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.
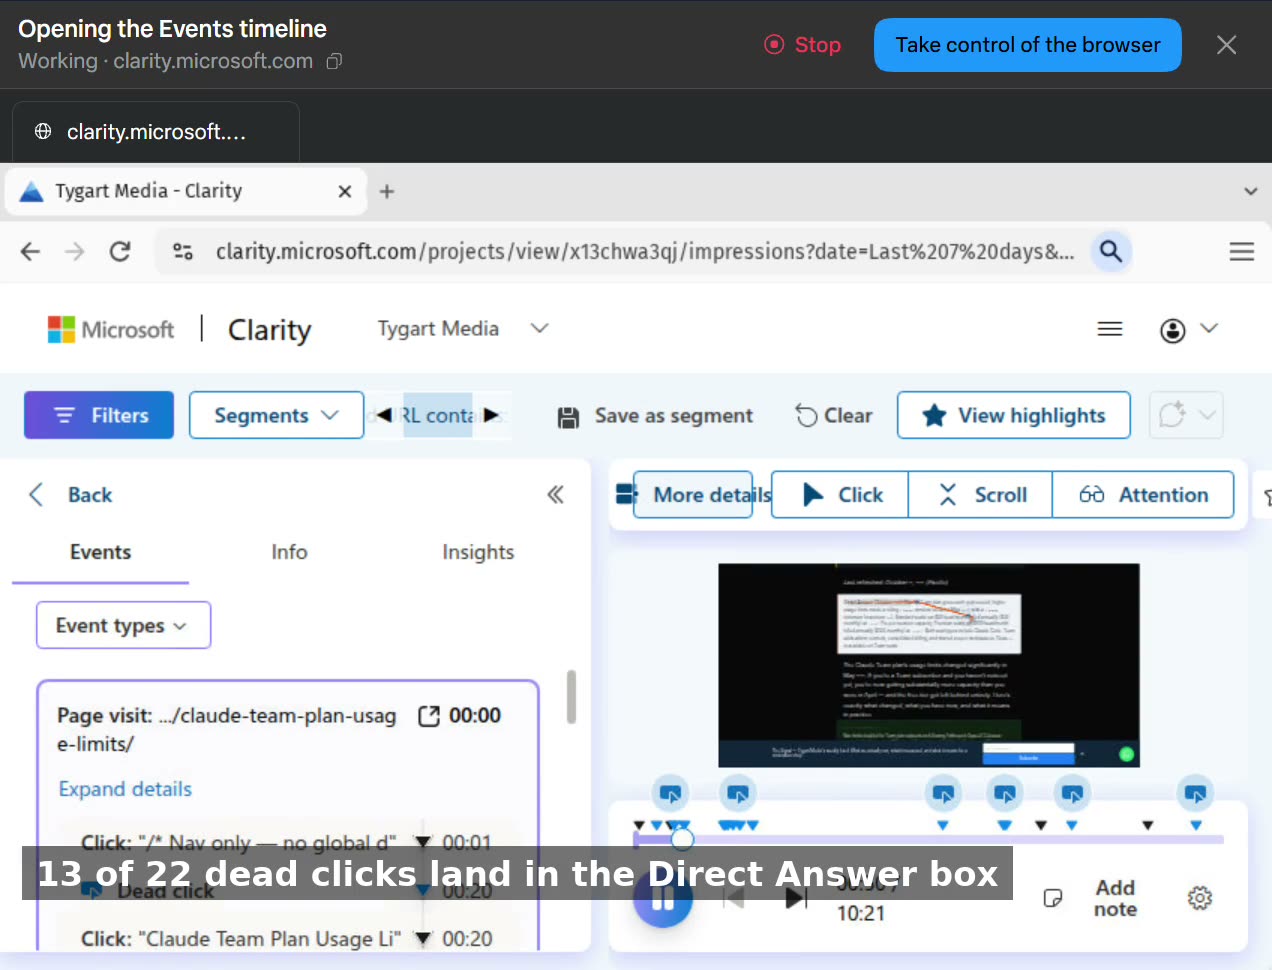
Our analytics flagged 105 dead clicks on our Claude pricing pages this week. Dead clicks are supposed to mean friction — people clicking things that don’t work. The fix, if you believe the dashboard, is a redesign ticket.
So we watched the recordings. All of them, session by session. This video is that walkthrough, narrated as it happened: the three filters that isolate the signal, then the two densest sessions read event by event.
Every flagged click was a reader selecting text. On the enterprise pricing page, one visitor accounts for all 17 dead clicks — four and a half minutes on the page, highlighting as they read. On the team-plan usage-limits page, 13 of the 22 dead clicks land inside the Direct Answer box at the top of the article: people selecting the summary to copy it out. Nobody clicked a broken button. Nobody clicked a price that wouldn’t respond. The one honest exception is a bold line inside a call-to-action block that got clicked like a button, four times — the only element on either page we’d even consider changing.
If we’d worked from the dashboard alone, we’d have “fixed” pages that are doing their jobs — and probably broken the format that makes them get cited in the first place.
This is the part of analytics nobody sells you: the number is a question, not an answer. The recording is the answer — if somebody actually watches it.
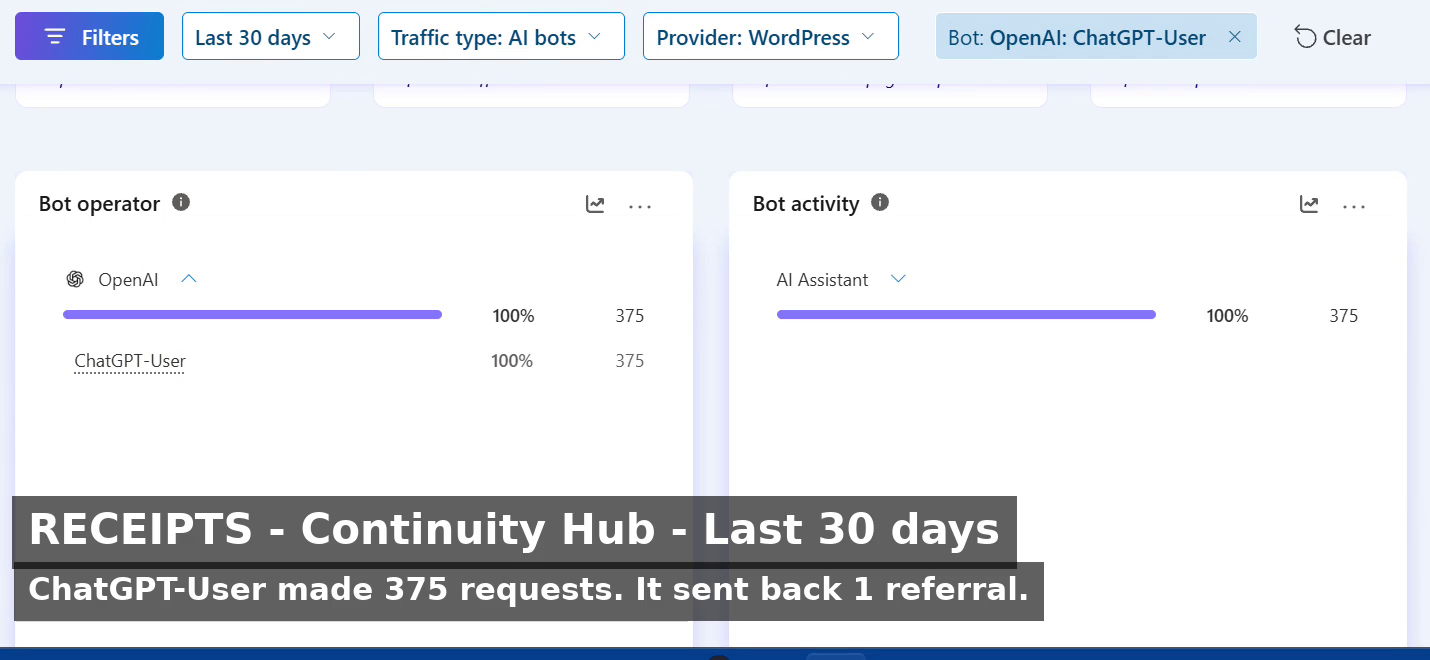
People say you can’t tell which AI models are reading your site, or what they do when they get there. This is Microsoft Clarity on one of ours. It names the operator, the bot, and the activity — no guessing.
Continuity Hub, last 30 days: ChatGPT-User made 375 requests. The homepage 83 times. Then the guides, one by one — supply-chain resilience, financial-services continuity rules, OSHA evacuation plans — down to pages that got a single read each. The bot didn’t skim the site. It walked the whole catalog.
The scrape-to-referral ratio is 494:1. For every 494 pages the model read, it sent back one visitor. One referral, total, from chatgpt.com.
That ratio is the part nobody selling AI visibility talks about. Being read by the models and being sent customers by the models are two different numbers, and the first one is enormous while the second one is nearly zero. We’ve measured the same shape across our sites — 408:1 on one, 837:1 across the fleet in September. The reading is real. The referring barely exists.
So when you interview whoever handles your SEO and AEO, ask them to pull up this screen for your site, live, with the dates in frame. If they can’t show you the receipts, they’re reading from somebody else’s book.
On October 23, 2026, Kin Insurance became the first U.S. home insurer to enable WebMCP in its quoting experience — an open web standard that lets an AI agent work directly with kin.com, so a homeowner can tell ChatGPT "help me shop for home insurance" and get back a real quote. Strip away the insurance details and what remains is a pattern every business website is about to be measured against: is your site built for the agent your customer sends?
Most businesses are still arguing about whether to let agents in. Kin skipped that argument. The interesting question is what its launch is made of, layer by layer — because three of the four layers are already visible in our own fleet's numbers.
Agent-Ready Fleet Standard
Make Your Site Machine-Ready for the 62% Bot Wave
Field-ready quick cards, fillable 4-layer audit worksheets, and AI-powered bot runbooks built directly from this guide.
Quick ReferenceFREE
Agent-Ready Quick Card
2-page field card: The 4 layers — welcome the machine (door vs. wall), structure for carrying (answers not brochures), give the agent a way to act (WebMCP), and measure what machines do (citation scoreboard) — on one card, condensed from the article body.
Agent traffic is not coming; on our own sites it is already the majority — roughly 62% of visits across the fleet we run are bots and agents, not people. The only choice left is whether that traffic meets a door or a wall.
Kin chose the door, publicly and in advance: it had already announced that AI shopping agents are welcome on kin.com rather than blocked, naming Meta's Muse among them. The opposite choice exists in the same industry — in September, insurance marketplace Insurify blocked Muse from its comparison platforms, arguing an agent could pull a price stripped of the context that makes it meaningful. Both are coherent positions. What is no longer available is having no position: a site that has not decided is a site whose default settings decide for it.
Layer 2: Structure the content so a machine can carry it accurately
An agent can only repeat what it can read, so the agent-ready site is built out of answers, not brochures: one real question per page, paragraphs that stand alone as complete ideas, and structured data underneath that states the facts in machine-readable form.
This is the layer we work in every day, and it is unglamorous, mechanical work. Tonight, on one operator site in our fleet, we finished putting structured FAQ data — drawn from each page's own questions and answers, verbatim — onto 155 of its 166 articles, because agents cite what is structured and skip what is implied. Multiply that instinct across every page a business owns and you have the content layer of agent-readiness: nothing important lives only in an image, a video, or a sales conversation.
Layer 3: Give the agent a way to act, not just to read
WebMCP is the layer most sites do not have yet: the site declares the actions an agent may take — get a quote, with these inputs, in this order — so the agent executes a designed path instead of improvising clicks across a human interface.
Kin's version is a quote flow, and its testing shows why the layer matters: agents reached a finished quote after asking the consumer only a handful of questions, because the path was declared and the carrier's data filled the rest. The equivalent for any business is the moment a visit becomes a transaction — a booking, a quote, an order. Our own commerce thinking already runs on two rails, one built for humans at a checkout and one an agent can complete; Kin just shipped the insurance version of the second rail, first.
Autonomous Commerce Engineering
Build Your Agent-Usable Rail Before Customers Stop Browsing
Kin proved an agent can reach a finished quote in a handful of questions when the path is declared. Equip your technical and product teams with printable inputs-in-order worksheets, two-rail commerce planners, and interactive AI routines that convert human checkout forms into WebMCP-compliant endpoints.
Agent-readiness you cannot measure is a vibe. Kin will know whether agents quote it, because the protocol makes agent sessions countable; the rest of us measure the read layer — which pages agents cite, which questions they bring, how the share moves.
On tygartmedia.com, we track AI citations from our own search-engine exports rather than a vendor's estimate: 1,459,726 citations across 922 cited pages in the October 15 export, up from 269,399 across 324 pages in the September 27 export. Those numbers are the scoreboard for layers 1 and 2. The day an agent can transact here, layer 3 gets a scoreboard of its own.
Where our fleet honestly sits
Layers 1, 2, and 4 are running here today — welcome posture, structured content, citation measurement. Layer 3, declared agent actions, is what Kin shipped first, and it is the next build. That is a fair summary of most of the web right now: readable by agents, citable by agents, and still requiring a human to show up for the transaction itself.
The businesses that treat that gap as a roadmap, rather than a surprise, are the ones whose sites will be ready when their customers stop browsing and start sending.
Specification Comparison
Compare Agent-Ready Tools & AI Implementation Systems
Choose the depth of operational rigor needed for your website: field quick card, printable audit working pack, or interactive bot-driven runbook.
Field Summary
Agent-Ready Quick Card
2-page field card condensing the 4 layers into an executive reference standard.
• 4-Layer architectural summary on one card
• Door vs. Wall posture matrix (Kin vs. Insurify)
• Answers-not-brochures & standalone paragraph test
• WebMCP declared action & two-rail commerce summary
• Citation scoreboard benchmarks (62% bot baseline)
What is WebMCP? An open web standard that lets an AI agent interact with a website through a machine-usable path the site itself declares — no plug-in and no screen-scraping. Kin enabled it in its home insurance quoting experience on October 23, 2026, the first U.S. home insurer to do so.
What makes a website "agent-ready"? Four layers: a deliberate decision to welcome agent traffic instead of blocking it by default; content structured as standalone answers with machine-readable data underneath; a declared path that lets an agent complete an action, such as a quote or booking; and measurement of what agents actually do on the site.
Do agents really visit business websites that much? On the fleet we operate, roughly 62% of visits are bots and agents. The share varies by site, but the direction does not: the reader a growing share of your pages serve first is a machine deciding what to show its human.
Source: Kin Insurance announcement via PR Newswire, October 23, 2026. Fleet figures are Tygart Media's own: bot share from our site analytics; citation counts from our Bing AI Performance exports of September 27 and October 15, 2026.
Updated Nov 1, 2026 — added the free agent-ready quick card, 4-layer print pack, and agent-ready bot book downloads to this guide.
Updated Nov 1, 2026 — added the free AEO reporting quick card, re-pullable AEO report pack, and report auditor bot book downloads to this guide.
If you are comparing agencies specifically on their AEO and SEO reporting, you have probably already been burned the standard way: a glossy dashboard, a score that only goes up, and no way to check any of it against a source the agency doesn’t control. Reporting is where this industry hides. So here is the standard we would hold any agency to — including the one writing this page — stated as five sections a real monthly report contains, the ownership rule that matters more than all of them, and our own current numbers filled in as the sample.
Demand the 5-section monthly report standard, verify source Bing/Clarity exports, lock commercial query share in Month 1, and run forensic AI audits on past agency deliverables.
Field Quick Card FREE
AEO Reporting Quick Card
2-page field summary: The five sections of a report you can re-pull — ledger summary, share on queries that pay, page movers, new questions, work priced against movement — plus the non-negotiable ownership rule and bad-reporting spotter on one card.
A real report opens with your citation totals and their direction — this window against last window, from the engine’s own export. Ours, for this site, reads: 1,459,726 total citations across 922 cited pages in the October 15 export, against 269,399 across 324 pages on September 27. Two numbers, two dates, one source anyone can re-pull. A report that gives you a total without the previous window’s total is giving you a photograph and calling it a trend.
Section two: share on the queries that pay
Totals flatter; share tells the truth. The second section lists the handful of questions your buyers actually ask an AI, and your citation share of each — for us, 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” 54.46% on “anthropic console” in our software coverage. If an agency’s report never names your money queries, it is because the answer would end the meeting. Make them name the queries, in writing, in month one — then the share line becomes the whole relationship in one table.
Section three: the page movers
Which pages climbed, which consolidated, which are being starved — named by URL, with figures. Our current read: the certification guide at the center of our contractor work climbed 1,635 → 1,913 → 2,454 → 2,790 citations across four exports while its duplicate was consolidated from 304 down to 6. That single line tells a client more than forty pages of charts: where the engine is placing its trust, and what the agency did about it. A report without named pages is a report about nothing in particular.
Agency Evaluation Toolkit
Don’t Rent Your History: Audit Agency Numbers From Your Own First-Party Exports
If your agency reports anonymous averages or hides behind proprietary visibility scores, demand the 5-section re-pull standard before signing. Whether you need printable working logs, money-query share tables, and 4-export page mover diagnostic sheets ($7), or an autonomous AI auditor to cross-examine their deliverables, flag vanity bot totals, and generate binding contract redlines ($17), equip your team with forensic arithmetic.
Both tools grounded 100% in Post 25636 substance. Instant delivery.
Section four: new questions, and what got built against them
Every export surfaces grounding queries you have never seen — the market asking new questions in the open. Section four lists them and ties each to an action: published, queued, or deliberately passed on, with the reason. This is the section that proves the work is demand-led rather than calendar-led, and it’s the first section a lazy agency quietly drops, because it creates a paper trail of promises.
Section five: the work, priced against the movement
What was done, what it cost, what moved, what’s next — in that order, on one page. Not a ticket dump. If three articles shipped and the share line didn’t move, the report should say so and say what changes next month. The month the report stops admitting flat results is the month it became a sales document.
The ownership rule that outranks all five sections
Every figure in the report must be re-pullable by the client, from the client’s own accounts. Bing Webmaster and Microsoft Clarity are free; the exports belong to whoever owns the property. If your agency generates its numbers inside its own portal, from its own panel, under its own login, then leaving the agency means leaving your history — and a report you can’t verify is a report you’re renting. We run our tracking exactly this way, and the method is published so a client can audit it without us in the room. These five sections, by the way, are the receipts from the buyer’s test wearing their monthly clothes: the test is what you demand before signing; the report is what you should receive after.
Compare the Three AEO Reporting Toolkits
Choose the right level of rigor for evaluating finalist agencies and monthly deliverables.
What bad reporting looks like, so you can spot it in the wild
A proprietary visibility score with no export behind it. A screenshot of the best week of the quarter. Engines blended into one soup so a Bing collapse hides inside a ChatGPT anecdote. Vanity totals — citations counted without share, traffic counted without asking how much of it was bots (on our fleet this month, roughly six visits in ten were automated; a report that never mentions that is averaging two different worlds). And the tell of tells: a report that arrives as a presentation, live, with no file you keep.
How to choose, then
Before you sign with anyone — us included — ask each finalist for last month’s report for a current client, redacted as needed, and for the source exports behind one number in it. The best agency for AEO SEO reporting is not the one with the prettiest dashboard or the boldest score. It is the one whose report survives your re-pull: same exports, same windows, same figures. Everything else is a pitch. The report is the product demo that can’t be rehearsed — judge that.
The Signal — Tygart Media's weekly brief. What we actually ran, what it measured, and what it means for a restoration shop.