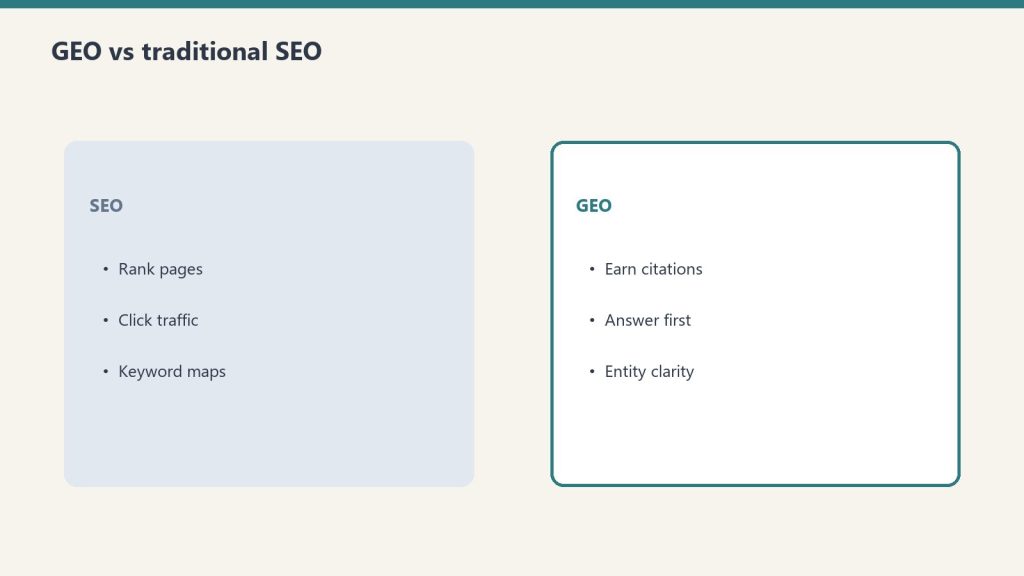
Direct answer: On June 22, 2026, Tygart Media published 40 enterprise Copilot articles in one day, pinged IndexNow, and used server logs—not GA4—to measure the result: 6,805 AI crawler hits vs. 4,897 traditional crawler hits in 48 hours, plus three copilot.microsoft.com referrals. The thesis is that Bing indexing, Copilot citations, and Bing Ads retargeting form a repeatable monetization flywheel no other AI stack fully closes.
Copilot cites from Bing’s index—not a separate Copilot crawler.
Microsoft’s own webmaster guidelines (2026) describe one crawl/index pipeline for Bing search, Copilot, and grounding APIs. Copilot does not maintain a shadow index. If Bingbot can crawl the URL and Bing indexes it, the page is eligible to be cited. That is the architectural basis for “Bing citation mining.”
The monetization twist is Microsoft-specific: a visitor who clicks a Copilot source link often arrives with a copilot.microsoft.com referrer. That session can feed Bing Ads retargeting. Google’s AI surfaces and ChatGPT may send traffic, but they do not hand you the same owned ad graph. We still treat Google AI Overviews and ChatGPT Search as citation channels—just not closed-loop ones.
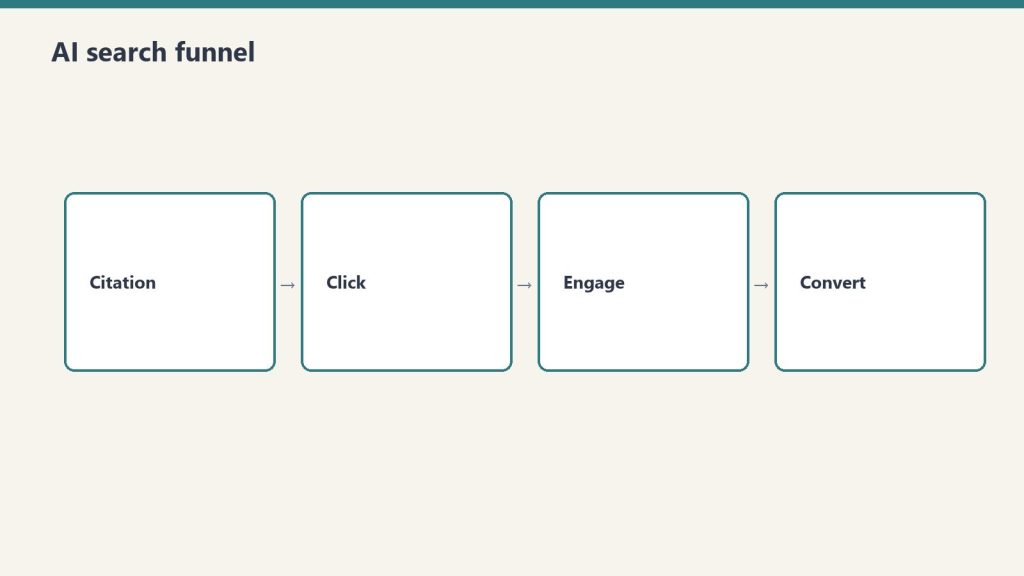
Index — IndexNow on every new URL; sitemaps and internal links as backup.
Cite — Copilot (and Bing AI summaries) pull from the Bing index.
Retarget — Build audiences from Copilot referrers in Bing Ads.
Monetize — Measure leads and revenue, not vanity citations alone.
The experiment: 40 articles, one day
Forty posts in one batch—then watch bot behavior.
On June 22, 2026, we shipped 40 articles on enterprise Microsoft 365 Copilot workflows—eight each across governance, BI/analytics, adoption, productivity, and comparison/procurement topics. Forty was the smallest batch that still looked like a topical cluster to bots mapping site structure, not forty isolated landing pages.
Every article received the same four-layer stack summarized in our GEO case studies for 2026 and the PSAO write-up: classic SEO, AEO extractability, GEO entity saturation, plus JSON-LD. Internal links tied each post to three to five siblings so GPTBot’s structural crawl (see below) could read cluster authority.
Day-one data (June 2026 server logs)
All numbers below are first-party log parses from the 48 hours after publish. Analytics tags miss most bot traffic; this is why we keep preaching log instrumentation—and why we published an AI citation monitoring guide and a broader LLM visibility measurement framework for the post-dashboard era.
AI vs. traditional crawlers
6,805 AI crawler hits
4,897 traditional crawler hits
39% more AI than traditional volume
Source: Tygart Media server logs, June 2026.
Who showed up
ChatGPT-User (3,404 hits) — Real-time retrieval when a user asks ChatGPT something that needs the live web. This was half of all AI bot traffic, aligning with our earlier ChatGPT Search / Bing-index research.
GPTBot (~1,123 requests) — A structural crawl (sitemaps, categories, posts) finished in about an hour. Training/index mapping behavior, not query-driven fetches.
Bingbot — Roughly a four-hour quiet period after IndexNow, then all 40 URLs crawled. IndexNow did its job notifying Bing; Microsoft still does not promise a fixed latency window.
Copilot referrals
Three confirmed human sessions from copilot.microsoft.com within 48 hours—before traditional Bing rankings meant much. Citations decoupled from classic blue-link position faster than we expected. Dollar framing lives in the citation value framework.
ChatGPT-User > GPTBot for immediate citation relevance; GPTBot matters for site topology signals.
Copilot citations before rank. Index presence plus topical fit beat waiting for position one.
Measurement stack evolved. By September 2026 we supplement logs with Bing Webmaster Tools AI Performance where available; logs remain the ground truth for bots GA4 never sees.
IndexNow wording. We now describe IndexNow as “notify Bing immediately,” not “instant index”—matching Bing’s documentation.
What we track after day one
Bing index coverage (Webmaster Tools), Copilot citation counts (AI Performance + log referrers), AI bot recrawl cadence, traditional Bing/Google rankings, and post-citation behavior in GA4. The 40-article cluster is a living lab; this post is the methods appendix.
Frequently Asked Questions
What is the Bing Citation Mining thesis?
The Bing Citation Mining thesis holds that Microsoft Copilot grounds public answers in Bing’s index, so publishers who publish authoritative pages and get them indexed on Bing can earn Copilot citations—and retarget visitors who arrive from those citations through Bing Ads. That publish → index → cite → retarget loop is the only end-to-end AI search monetization chain Microsoft documents today.
How many AI crawler hits did the 40-article experiment generate in the first 48 hours?
Tygart Media server logs from June 2026 recorded 6,805 AI crawler hits versus 4,897 traditional crawler hits in the first 48 hours after all 40 articles went live—39% more AI traffic than traditional. ChatGPT-User alone accounted for 3,404 hits.
Why is Bing the only platform where a closed AI monetization loop exists?
Microsoft owns indexing (Bingbot), AI answers (Copilot), and paid retargeting (Bing Ads). Google’s AI experiences and ChatGPT do not offer the same single-vendor chain from index to attributable referral to ad audience. Bing Webmaster Tools now also reports Copilot citation counts in its AI Performance preview, but the monetization hinge is still Bing Ads on copilot.microsoft.com referrers.
How fast do AI crawlers respond to new content published with IndexNow?
In Tygart Media’s June 2026 logs, ChatGPT-User hit new URLs within hours, GPTBot finished a 1,123-request structural crawl within about an hour of starting, and Bingbot crawled all 40 posts after roughly a four-hour gap following IndexNow pings. Microsoft’s IndexNow docs stress that a 200 response only confirms receipt—not a guaranteed crawl time—so treat our timings as observed data, not a SLA.
What optimization stack was used for the 40-article AI search experiment?
Each post got four layers: SEO (titles, meta, headings, internal links), AEO (FAQ blocks, definition boxes, direct-answer paragraphs), GEO (entity density, factual specificity, speakable markup), and JSON-LD (Article, FAQPage, BreadcrumbList). We document comparable GEO outcomes in our 2026 case-study roundup.
Methodology: June 2026 Tygart Media access logs; bot classification by user-agent; Copilot referrals by referrer string. No third-party bot counts. As of September 2026, also spot-check Bing Webmaster Tools AI Performance where the preview is enabled.
Part of Tygart Media’s AI Search Intelligence series for restoration contractors and operators building durable AI search visibility.
This is part of Tygart Media’s AI Search Intelligence series — a 10-part investigation into how AI systems discover, evaluate, cite, and refer traffic to web content, built on proprietary server log data and real-world publishing experiments.
Every CMO can tell you what a Google click is worth. Years of attribution modeling, CTR curves, and keyword-level conversion tracking have made the organic search click one of the most well-understood units of value in digital marketing. But ask that same CMO what a Microsoft Copilot citation is worth — a referral from copilot.microsoft.com where an AI system explicitly names their brand as a source — and you will get silence.
That silence is a strategic vulnerability. AI search is not a future state. It is a current one. And the organizations that build valuation frameworks for AI citations now will have a decisive advantage over those still trying to retrofit Google Analytics models onto an entirely different referral mechanism.
At Tygart Media, we have been tracking this problem with real data. After publishing 40 articles targeting Microsoft Copilot citation patterns, we recorded 3 confirmed Copilot citation referrals within 48 hours — and simultaneously observed that AI crawlers were hitting our server 6,805 times compared to 4,897 traditional visits (Tygart Media server log analysis, June 2026). AI is already reading more than humans are browsing. The question is no longer whether AI citations matter. The question is: how much are they worth?
This article introduces our AI Citation Value Framework — a 5-component model for measuring what a Copilot referral is actually worth to a publisher, a brand, or a business.
Why Traditional SEO ROI Models Break for AI Search
Why traditional SEO ROI models break for AI search.
Before we build the new framework, we need to understand why the old one fails. Traditional SEO ROI modeling depends on a chain of measurable inputs that simply do not exist in AI search.
The Four Structural Breaks
1. No keyword position to track. In traditional search, value begins with a ranking position. Position 1 for “enterprise software comparison” has a known CTR, a known traffic volume, and a known conversion probability. In AI search, there is no position. Your content is either cited or it is not. There is no “position 3 in Copilot” — the AI either references your brand or it does not mention you at all.
2. No CTR curve to model. Google’s organic CTR curve — where position 1 captures roughly 27-30% of clicks and position 10 captures roughly 2-3% — is one of the foundational inputs to every SEO ROI projection. AI citations have no equivalent curve. When Copilot cites a source within an enterprise workflow answer, the user either clicks through to the cited source or they do not. There is no graduated decay based on citation order.
3. Citations are binary, not graduated. This is the most fundamental structural difference. Traditional SEO operates on a spectrum — position 1 is better than position 5, which is better than position 20, which is better than position 50. Each position has a calculable value. AI citations are binary. You are cited, or you are not. You are the named source, or you are invisible. This binary nature makes traditional regression-based ROI modeling inapplicable.
4. Value accrues through authority reinforcement, not traffic volume alone. In traditional SEO, the primary value mechanism is traffic. More traffic means more conversions means more revenue. In AI search, value accrues through a different mechanism: being cited is worth more than being clicked. The citation itself — the act of an AI system naming your brand as an authoritative source — carries independent value beyond the referral click it may or may not generate.
Definition — AI Citation Value: The total economic impact of being named as a source by an AI system, encompassing direct referral traffic, brand authority reinforcement, compounding citation patterns, retargeting opportunities, and extended content shelf life. Unlike traditional organic search value, AI citation value is not derived from keyword position or CTR curves but from the binary act of being cited by a trusted AI intermediary.
The AI Citation Value Framework: Five Components
The AI citation value framework — five components.
Our framework decomposes the value of a single AI citation into five measurable components. Each captures a different dimension of value that traditional models ignore. Together, they provide a comprehensive picture of what a Copilot referral — or any AI citation — is actually worth to an organization.
Component 1: Direct Referral Value
This is the component closest to traditional SEO measurement: the value of the actual click that occurs when a user follows a citation link from an AI response to your website. But even here, the mechanics differ substantially from a Google organic click.
A traditional organic click arrives with context shaped by a search results page. The user has seen your title tag, your meta description, and your competitors’ listings. They have made a comparative choice. A copilot.microsoft.com referral arrives with context shaped by an AI endorsement. The user has received an answer, and the AI has specifically named your content as the source supporting that answer. The intent signal is different. The trust transfer is different.
Publishers should calculate their direct referral value by examining the downstream behavior of AI-referred visitors compared to organic-referred visitors. Key metrics include:
Pages per session for AI referral traffic vs. organic traffic
Session duration for AI referral traffic vs. organic traffic
Conversion rate for AI referral traffic vs. organic traffic
Bounce rate differential between the two traffic sources
Our early observations suggest that AI referral traffic exhibits distinct engagement patterns that require their own attribution models. The framework recommends treating AI referral traffic as its own channel in GA4 rather than lumping it into organic search.
Component 2: Brand Authority Multiplier
This is the component that has no analog in traditional SEO. When Google ranks your page at position 1, Google is not telling the user “this source is authoritative.” Google is presenting a list and letting the user decide. When Microsoft Copilot cites your brand in a conversational answer, the AI is making an explicit endorsement: “According to [Your Brand]…” or “As [Your Brand] explains…”
That is a fundamentally different value proposition. The AI is functioning as a third-party endorser at scale — recommending your brand to potentially millions of enterprise users within their daily workflow. This endorsement carries brand equity value that exists independently of whether the user clicks through to your site.
Consider the parallel: if a respected industry analyst cited your research in a keynote presentation to 10,000 executives, you would calculate the brand value of that mention even if none of those executives visited your website afterward. An AI citation operates on the same principle, but at dramatically larger scale and with higher frequency.
The brand authority multiplier should be calculated based on:
Estimated reach of the AI platform (Microsoft Copilot’s enterprise user base)
The context of the citation (workflow integration vs. casual query)
Brand lift measurement through pre/post surveys or branded search volume changes
Equivalent media value of a third-party endorsement at comparable scale
In traditional SEO, rankings are volatile. A page that ranks position 1 today may rank position 5 tomorrow and position 15 next month. Every algorithm update reshuffles the deck. This volatility is baked into traditional ROI models through discount rates and probability adjustments.
AI citations behave differently. Our observation — and one of the most strategically important findings in this series — is that once an AI system cites a source, it tends to continue citing that source. There is no position ranking decay in the traditional sense. The AI’s retrieval patterns create a reinforcement loop: content that gets cited builds authority signals that make it more likely to be cited again.
This compounding effect means that the value of a single AI citation extends far beyond the moment of that citation. Each citation is not just a discrete event — it is a contribution to a compounding authority position. Our server log data shows this pattern clearly: after our 40-article Copilot content strategy began generating citations, the AI crawler activity on our site increased substantially, suggesting that citation activity triggers additional crawling and indexing attention from AI systems.
The compounding citation effect should be modeled as:
Citation persistence rate (what percentage of citations continue over 30, 60, 90 days)
Citation expansion rate (does being cited for Topic A lead to citations for Topics B and C)
Authority reinforcement velocity (how quickly does compounding accelerate)
Decay comparison with traditional rankings over equivalent time periods
Key Insight: Traditional SEO ROI models apply a depreciation rate to rankings because positions decay. The AI Citation Value Framework suggests applying an appreciation rate to citations because citations compound. This single inversion — from depreciation to appreciation — fundamentally changes how content investment should be valued.
Component 4: Retargeting Amplifier Value
This component captures a tactical opportunity that most organizations are overlooking entirely. When a user clicks through from a Copilot citation to your website, that user enters your retargeting ecosystem. They can be reached through Bing Ads, display advertising, social media retargeting, and email capture — the same downstream activation paths that exist for any website visitor.
But the retargeting amplifier for AI-referred visitors carries a specific advantage: the visitor arrived with AI-endorsed trust. They did not find you through a search results page where you were one option among ten. They found you because an AI system specifically recommended your content. That trust context should, in principle, improve downstream conversion rates for retargeted campaigns.
The retargeting amplifier value should be calculated by:
Building dedicated retargeting audiences for AI referral traffic in Bing Ads and other platforms
Measuring conversion rates of AI-referred retargeting audiences vs. organic-referred retargeting audiences
Calculating the incremental revenue attributable to the AI referral entry point
Factoring in the lifetime value differential of AI-acquired vs. organic-acquired customers
This component connects directly to the broader Platform-Specific AI Optimization (PSAO) framework — where understanding the unique user journey of each AI platform enables targeted activation strategies that generic SEO approaches cannot deliver.
Component 5: Content Shelf Life Extension
The final component addresses a problem that every content marketer knows intimately: content decay. In traditional SEO, content has a half-life. A blog post ranks well for weeks or months, then gradually declines as fresher content, algorithm updates, and competitive publishing erode its position. Content teams operate on a treadmill — constantly producing new content to replace the decaying traffic from older content.
AI-cited content exhibits a different decay pattern. Because AI citations are driven by authority signals and retrieval patterns rather than freshness signals and ranking algorithms, content that earns AI citations tends to maintain those citations for longer periods than equivalent content maintains Google rankings.
This means that the effective shelf life of AI-cited content is longer than the effective shelf life of Google-ranked content, all else being equal. The investment in creating citation-worthy content generates returns over a longer horizon.
Content shelf life extension should be measured by:
Comparing the traffic decay curve of AI-cited content vs. non-cited content of similar quality and topic
Tracking citation persistence over 6-month and 12-month windows
Calculating the reduced content production burden from extended shelf life
Modeling the NPV difference between a content asset with traditional decay vs. AI-extended shelf life
Putting the Framework Together: A Practical Valuation Approach
Each of the five components can be measured independently, but the framework’s power comes from combining them into a unified valuation. Here is the practical approach we recommend for organizations beginning to measure AI citation value.
Before calculating any values, organizations need to ensure they can actually detect and track AI citations. This requires:
Server log analysis capability — to identify AI crawler activity and referral sources at the server level, not just through JavaScript-based analytics
GA4 custom channel groupings — to separate AI referral traffic (from copilot.microsoft.com, chatgpt.com, claude.ai, and similar sources) from traditional organic traffic
Citation monitoring — systematic testing of AI systems to identify when and where your content is being cited
Temporal analysis — tracking when AI referrals occur relative to content publication to understand citation latency
Our own infrastructure revealed the 6,805 AI crawler hits vs. 4,897 traditional visits split that informed much of this series (Tygart Media server log analysis, June 2026). Without server-level analysis, this data — and the strategic insights it enables — would be invisible.
Step 2: Calculate Each Component Independently
For each component, establish a measurement methodology appropriate to your data maturity:
Direct Referral Value: Start with per-session revenue for AI referral traffic. If you do not yet have enough AI referral volume for statistical significance, use your overall per-session revenue as a proxy and adjust as data accumulates.
Brand Authority Multiplier: Begin with equivalent media value estimation. What would you pay for a third-party endorsement at the scale and context that an AI citation delivers? Refine with branded search lift measurement over time.
Compounding Citation Effect: Track citation persistence monthly. Calculate the projected value of maintaining a citation over 12 months vs. the projected value of maintaining a Google ranking for the same keyword over 12 months. The differential is the compounding premium.
Retargeting Amplifier: Build the audience segments, run the campaigns, and measure the incremental lift. This component is the most directly measurable using existing ad platform infrastructure.
Content Shelf Life Extension: Compare traffic decay curves for cited vs. non-cited content. Calculate the content production cost savings from extended shelf life.
Step 3: Apply the Unified Formula
The total AI Citation Value for a given piece of content is the sum of all five components over the measurement period. Organizations should calculate this quarterly and compare it against the traditional SEO value of equivalent content to build a clear picture of relative ROI.
The formula structure is straightforward:
AI Citation Value = Direct Referral Value + (Brand Authority Multiplier × Estimated Reach) + (Compounding Citation Effect × Time Horizon) + Retargeting Amplifier Value + Content Shelf Life Extension Value
Each variable requires organization-specific inputs. The framework provides the structure; your data provides the numbers.
What Our Data Shows So Far
We are transparent about the maturity of our own dataset. After publishing 40 articles specifically designed to test AI citation acquisition strategies, our results within the first 48 hours included:
3 confirmed Copilot citation referrals — verified through server logs as traffic from copilot.microsoft.com
6,805 AI crawler hits vs. 4,897 traditional visits (Tygart Media server log analysis, June 2026)
This is early-stage data. Three referrals in 48 hours from a cold start is a signal, not a conclusion. But the signal is directionally significant: content engineered for AI citation can earn citations rapidly, and the mechanisms for earning those citations are learnable and repeatable.
The more revealing data point is the crawler ratio. When AI systems are reading your content at a higher rate than traditional systems and humans combined, it confirms that the audience for your content is no longer exclusively human. Your content is being evaluated, indexed, and potentially cited by AI systems with every crawl. The question of why some content gets cited and other content does not becomes the central strategic question.
The Dollar Value Comparison: AI Citation vs. Traditional Organic Click
Let us be direct about what this comparison looks like structurally, even without asserting specific dollar amounts that would vary wildly by industry, niche, and business model.
Traditional Organic Click Value
A traditional organic click’s value is calculated through a well-established chain:
The critical weakness: every variable in this chain is subject to decay. Rankings decay. CTR decays as competitors improve their listings. Traffic decays as search volume shifts. Traditional organic click value is a depreciating asset.
AI Citation Referral Value
An AI citation referral’s value chain looks fundamentally different:
Citation status → binary (cited or not cited)
AI platform reach → estimated user base of the citing AI system
Query relevance → how frequently the cited topic is queried in AI systems
Click-through behavior → percentage of users who follow citation links
Trust premium → conversion rate adjustment for AI-endorsed visitors
Applied appreciation → compounding citation effect over time
The critical strength: the appreciation rate replaces the discount rate. Instead of modeling value decay, the framework suggests modeling value accumulation. The longer you hold an AI citation, the more valuable it becomes as compounding reinforces your position.
Framework Comparison: Traditional organic click value = depreciating asset (rankings decay, algorithms shift, competitors erode position). AI citation value = appreciating asset (citations compound, authority reinforces, shelf life extends). The valuation methodology must match the asset type. Applying depreciation models to appreciating assets systematically undervalues AI citations.
Implications for Content Investment Strategy
Implications for content investment strategy.
If this framework holds — and our early data suggests the structural logic is sound — it has significant implications for how organizations should allocate content budgets.
Content designed to earn AI citations should receive higher per-piece investment than content designed solely for Google rankings. The logic is straightforward: if AI-cited content is an appreciating asset while Google-ranked content is a depreciating asset, the net present value of the citation-optimized content is higher over any multi-year horizon.
Implication 2: Measurement Infrastructure Is No Longer Optional
Organizations that cannot detect AI citations, track AI referral traffic, or analyze AI crawler behavior are flying blind in a channel that already generates more server activity than traditional search on some properties. Server log analysis, custom GA4 configurations, and systematic citation monitoring must be treated as essential infrastructure, not nice-to-have analytics projects.
Implication 3: The Valuation Gap Creates Arbitrage Opportunity
Right now, most organizations are not measuring AI citation value at all. This means the “market” for AI-optimized content is dramatically underpriced relative to its actual value. Organizations that adopt a rigorous valuation framework now — and invest in citation acquisition strategies based on that valuation — are buying an appreciating asset at a discount.
The arbitrage window will close as more organizations adopt AI citation measurement. Early movers who build the infrastructure, develop the content, and establish citation authority now will compound those advantages over time.
Implication 4: Attribution Models Need a Full Rebuild
Most marketing attribution models treat all organic search as one channel. AI referral traffic needs its own attribution path — with its own conversion metrics, its own LTV calculations, and its own ROI benchmarks. Blending AI referral data into “organic search” obscures the true performance of both channels and prevents accurate investment allocation.
Frequently Asked Questions
How do you calculate the value of an AI citation from Microsoft Copilot?
The AI Citation Value Framework uses five components: direct referral value, brand authority multiplier, compounding citation effect, retargeting amplifier value, and content shelf life extension. Each component captures a different dimension of value that a single AI citation delivers. Organizations should measure each component independently using their own data, then combine them into a unified valuation that can be compared against traditional organic search ROI.
Is a Copilot referral worth more than a traditional Google organic click?
The framework suggests that Copilot referrals carry structurally different value characteristics than Google organic clicks. Traditional organic clicks are depreciating assets — subject to CTR decay, position fluctuation, and algorithm updates. AI citations function as appreciating assets — they compound over time, experience no position ranking decay, and benefit from implicit third-party endorsement by the AI system. Publishers should calculate their own comparative values using the five-component framework and their organization-specific data.
Why do traditional SEO ROI models fail for AI search?
Traditional SEO ROI models depend on four inputs that do not exist in AI search: keyword positions, CTR curves, graduated ranking values, and traffic-volume-based value accrual. AI citations are binary (cited or not), carry no position ranking, have no CTR decay curve, and deliver value through authority reinforcement rather than traffic volume alone. Applying traditional models to AI citations will systematically produce incorrect valuations.
What is the compounding citation effect in AI search?
The compounding citation effect describes the observed pattern where once an AI system cites a source, it tends to continue citing that source for related queries. Unlike traditional search rankings that fluctuate with every algorithm update, AI citations build on themselves — each citation reinforces the source’s authority within the AI model’s retrieval patterns. This creates an appreciating dynamic rather than the depreciating dynamic of traditional rankings.
How many AI crawler visits does a typical website receive compared to human visits?
This varies significantly by site, but Tygart Media’s server log analysis from June 2026 recorded 6,805 AI crawler hits compared to 4,897 traditional visits. On this property, AI systems were reading content at a higher rate than traditional crawlers and human visitors. Organizations should conduct their own server log analysis to understand their specific AI-to-human traffic ratio, as this metric is invisible in standard JavaScript-based analytics platforms like Google Analytics.
What Comes Next in This Series
This framework is a starting point, not a final answer. The data underpinning AI citation valuation is still maturing, and the frameworks will evolve as more organizations contribute measurement data and as AI platforms’ citation behaviors become better understood.
In our final installment of the AI Search Intelligence series, we will synthesize the findings from all ten articles into a unified strategic playbook — connecting platform-specific optimization, citation mechanics, and this valuation framework into a comprehensive action plan for organizations ready to treat AI search as a first-class channel.
The organizations that measure what matters — and invest based on those measurements rather than outdated proxies — will own the AI citation economy. The framework is here. The data is building. The question is whether you will wait for the market to price AI citations accurately, or whether you will capture the arbitrage while it lasts.
All server log data, crawler statistics, and citation referral counts cited in this article are sourced from Tygart Media server log analysis, June 2026. For methodology details, see our complete data analysis.
This is part of Tygart Media’s AI Search Intelligence series, where we analyze real data from our own infrastructure to document how AI search engines discover, crawl, and cite publisher content.
Here is the uncomfortable truth that every publisher needs to confront: Google Analytics 4 cannot see AI crawler traffic. Not partially. Not approximately. It misses 100% of it.
GA4 depends on JavaScript execution inside a browser. AI crawlers — GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, PerplexityBot — do not run JavaScript. They request your HTML, parse it, and leave. As far as GA4 is concerned, they were never there.
That means if you are making content strategy decisions based exclusively on GA4, you are making decisions with a growing blind spot. When we analyzed our own server logs for a 48-hour window in June 2026, we found 6,805 AI crawler hits compared to 4,897 traditional search engine crawler hits — AI crawlers generated 39% more traffic than Googlebot, Bingbot, and every other traditional crawler combined (Tygart Media server log analysis, June 2026).
This article walks through exactly what server logs reveal that analytics tools miss, provides the specific user agent strings you need to monitor, and gives you a practical framework for setting up your own AI crawler tracking.
Why GA4 Is Structurally Blind to AI Search Traffic
GA4 is structurally blind to AI search traffic.
This is not a configuration problem. You cannot fix it with a tag update or a GTM trigger. The architecture of client-side analytics makes it fundamentally incompatible with bot traffic measurement.
How GA4 Tracking Works (And Where It Fails)
GA4 tracking follows a specific sequence: a user loads a page in a browser, the browser executes the gtag.js JavaScript snippet, that script fires an HTTP request to Google’s measurement endpoint, and GA4 records the session. Every step in this chain requires a JavaScript-capable browser environment.
AI crawlers skip all of it. When GPTBot requests a page from your server, it receives the raw HTML response, extracts the content it needs, and moves on. No JavaScript execution. No measurement ping. No GA4 session. The request exists only in your server’s access log.
We documented this gap extensively in our analysis of the Google Search Console indexing paradox, where pages with declining GA4 traffic were simultaneously receiving increasing AI crawler attention — a pattern completely invisible without server log analysis.
The Scale of What You Are Missing
To quantify what GA4 misses, we pulled raw access logs from our Nginx server for a 48-hour window in June 2026 and categorized every request by user agent classification.
The breakdown (Tygart Media server log analysis, June 2026):
AI crawler requests: 6,805 total
Traditional search crawler requests: 4,897 total
Difference: AI crawlers generated 39% more server requests than traditional crawlers
None of those 6,805 AI crawler requests appeared in GA4. If we had relied solely on Google Analytics to understand how machines interact with our content, we would have missed the majority of non-human traffic entirely.
As we explored in our research on how websites are now read by AI more than humans, this pattern is not unique to our site — it reflects a structural shift in how content gets consumed.
AI Crawler User Agents: The Complete Reference for June 2026
AI crawler user-agent reference — know who is reading.
Definition: An AI crawler user agent is the identification string sent in the HTTP request header by an artificial intelligence company’s web crawler when it accesses a webpage. These strings identify the crawler’s operator, version, and purpose, and they are the primary mechanism publishers use to track, allow, or block AI bot access in server logs and robots.txt files.
Before you can monitor AI crawler traffic, you need to know exactly what to look for. Here are the verified user agent strings we extracted from our server logs, confirmed active as of June 2026.
OpenAI Crawler Family
OpenAI operates three distinct crawlers, each with a different purpose:
GPTBot (Training and Retrieval Crawler)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.1; +https://openai.com/gptbot
GPTBot performs large-scale structural crawls for model training data and retrieval-augmented generation indexing. Our logs recorded a single GPTBot session executing 1,123 requests in one hour, systematically mapping site architecture, internal link relationships, and content hierarchy (Tygart Media server log analysis, June 2026). This is not page-by-page fetching — it is comprehensive site mapping.
OAI-SearchBot (ChatGPT Search Citation Crawler)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; OAI-SearchBot/1.0; +https://openai.com/searchbot)
OAI-SearchBot is the real-time retrieval crawler that fetches pages when ChatGPT Search needs to cite a source. As we documented in our guide to getting cited in ChatGPT Search in 2026, this crawler’s access pattern correlates directly with citation inclusion. If OAI-SearchBot cannot reach your page, ChatGPT Search cannot cite it.
ChatGPT-User (Live Conversation Fetches)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ChatGPT-User/1.0; +https://openai.com/bot
ChatGPT-User represents real-time fetches triggered by actual ChatGPT users sharing URLs or requesting content analysis during conversations. This was our highest-volume AI crawler: 3,404 hits in the 48-hour analysis window (Tygart Media server log analysis, June 2026). Each of these hits represents a real person asking ChatGPT about content on our site.
Other Major AI Crawlers
Beyond OpenAI, monitor for these active AI crawlers:
ClaudeBot — Anthropic’s web crawler for Claude’s training and retrieval
PerplexityBot — Perplexity AI’s search and citation crawler
Bytespider — ByteDance’s crawler used for AI training data
Applebot-Extended — Apple’s crawler associated with Apple Intelligence features
Google-Extended — Google’s AI-specific crawler separate from Googlebot
Amazonbot — Amazon’s crawler linked to Alexa and AI assistant features
Each of these should be tracked separately in your log analysis. As our Platform-Specific AI Optimization (PSAO) framework details, different AI platforms have different crawl behaviors, indexing requirements, and citation patterns.
What the 48-Hour Server Log Analysis Revealed
Raw numbers tell part of the story. Crawl behavior patterns tell the rest. Here is what we observed when we dissected the 48-hour log window at the request level.
ChatGPT-User: The Highest-Volume Signal
With 3,404 hits in 48 hours, ChatGPT-User was the single most active AI crawler on our site during the analysis window (Tygart Media server log analysis, June 2026). This matters because every ChatGPT-User request represents a real person interacting with your content through ChatGPT.
The access pattern was distributed across the full 48-hour window with no single burst — consistent with organic user behavior rather than scheduled crawling. Pages accessed by ChatGPT-User skewed heavily toward our most-cited content, particularly the 98,800 AI citations research and our analysis of how AI engines cite content.
GPTBot: The Structural Mapper
GPTBot’s 1,123-request burst in a single hour stands out as the most aggressive crawl pattern we observed (Tygart Media server log analysis, June 2026). This was not random page fetching. The request sequence revealed systematic behavior:
Entry via sitemap.xml — GPTBot started by parsing our XML sitemap
Category page traversal — It crawled category archives to understand content taxonomy
Internal link following — It followed internal links from high-authority pages outward
Content page fetching — Individual articles were fetched in clusters organized by topic
This pattern is consistent with a retrieval-augmented generation (RAG) indexing crawl, where the goal is not just to read content but to build a structured map of how content relates to other content on the site. Publishers who invest in structured llms.txt files paired with robots.txt are effectively giving GPTBot a guided tour rather than letting it map the site on its own.
Bingbot and the 4-Hour IndexNow Gap
While Bingbot is a traditional crawler, its behavior has direct implications for AI search visibility. Our logs revealed a consistent 4-hour gap between publishing a new post (with an IndexNow ping) and Bingbot’s first crawl of that URL (Tygart Media server log analysis, June 2026).
This 4-hour lag matters because Bing’s index is the foundation for two major AI citation systems:
ChatGPT Search — OAI-SearchBot relies on Bing’s index to identify candidate pages for citation retrieval
A 4-hour indexing lag means your new content is invisible to both Copilot and ChatGPT Search for at least that window. For time-sensitive content, this gap represents a competitive disadvantage.
How to Set Up Your Own AI Crawler Monitoring
Set up your own AI crawler monitoring.
You do not need expensive tools to start tracking AI crawlers. Here is a practical step-by-step framework using standard server infrastructure.
Step 1: Locate Your Raw Access Logs
Your server access logs are the source of truth. Depending on your hosting setup:
Nginx: Default location is /var/log/nginx/access.log
Apache: Default location is /var/log/apache2/access.log or /var/log/httpd/access_log
Managed WordPress hosting (Cloudways, Kinsta, WP Engine): Access logs are typically available in the hosting dashboard under server logs or SFTP access
Shared hosting (SiteGround, Bluehost): Check cPanel > Metrics > Raw Access or request log access from support
If your host does not provide raw access logs, that is a serious limitation for AI search optimization. Consider this a factor in future hosting decisions.
Step 2: Filter for AI Crawler User Agents
Once you have access to raw logs, use grep (or your preferred log analysis tool) to isolate AI crawler requests. Here is a basic command set:
# Count all AI crawler hits in a log file
grep -c -E "GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|PerplexityBot|Bytespider|Applebot-Extended|Google-Extended" access.log

# Break down by individual crawler
for bot in GPTBot OAI-SearchBot ChatGPT-User ClaudeBot PerplexityBot Bytespider; do
  echo "$bot: $(grep -c "$bot" access.log)"
done

# Show which URLs each crawler is accessing
grep "GPTBot" access.log | awk '{print $7}' | sort | uniq -c | sort -rn | head -20
Step 3: Build a Recurring Monitoring Script
For ongoing tracking, create a cron job that generates a daily AI crawler report:
The real value emerges when you correlate AI crawler data with content outcomes. Track these relationships:
GPTBot crawl frequency → Citation appearances. Pages that GPTBot crawls repeatedly tend to surface in ChatGPT responses more frequently. We verified this pattern in our investigation of whether anything actually fetches your llms.txt file.
OAI-SearchBot access → ChatGPT Search citations. OAI-SearchBot visits are a leading indicator that your content is being evaluated for citation in ChatGPT Search results.
ChatGPT-User volume → Content demand signal. High ChatGPT-User traffic to specific pages indicates those topics are actively being discussed by ChatGPT users — a demand signal invisible in GA4.
Step 5: Set Up Real-Time Alerts
For publishers who need immediate visibility into AI crawler behavior, configure real-time log monitoring:
# Real-time AI crawler monitoring with tail
tail -f /var/log/nginx/access.log | grep --line-buffered -E "GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|PerplexityBot"
For production environments, tools like GoAccess, Datadog, or a custom ELK Stack (Elasticsearch, Logstash, Kibana) configuration can provide dashboards with AI crawler metrics alongside traditional analytics.
What Server Logs Reveal That No Analytics Tool Can Show
Beyond raw hit counts, server log analysis exposes behavioral patterns that inform content strategy decisions.
Crawl Depth and Site Architecture Signals
Traditional analytics shows you which pages humans visit. Server logs show you which pages machines prioritize. In our 48-hour analysis, AI crawlers accessed pages up to 7 levels deep in our site architecture — well beyond what most human visitors reach. This indicates that AI crawlers are evaluating your entire content graph, not just your homepage and top-ranking pages.
This has direct implications for internal linking strategy. Content buried deep in your architecture that humans rarely find may still be actively indexed by AI crawlers and surfaced in AI-generated responses. Our work on the AI citation economy explores why being cited by AI systems may ultimately deliver more value than traditional click-through traffic.
Crawl Frequency as a Content Quality Signal
Some pages on our site are crawled by AI bots multiple times per day. Others are crawled once and never revisited. Tracking crawl frequency over time reveals which content AI systems consider worth re-indexing — a signal that correlates with citation likelihood.
Pages that received repeat GPTBot and OAI-SearchBot visits in our analysis shared common characteristics:
Original data or research (not aggregated from other sources)
Clear entity definitions and structured formatting
Recent publication or update dates
Strong internal link support from related content
Response Code Analysis: Are AI Crawlers Hitting Errors?
Server logs include HTTP response codes for every request. Filter AI crawler requests by response code to identify problems:
200 (OK): Crawler successfully fetched the page — this is what you want
301/302 (Redirect): Crawler hit a redirect chain — check that critical content resolves cleanly
403 (Forbidden): Your server or WAF is blocking the crawler — this may be intentional (robots.txt block) or accidental (overly aggressive security rules)
404 (Not Found): Crawler tried to access a URL that does not exist — often caused by stale sitemap entries or broken internal links
429 (Too Many Requests): Your rate limiting is throttling the crawler — may reduce indexing completeness
503 (Service Unavailable): Server could not handle the crawler’s request volume — a hosting capacity issue
We found that 3.2% of AI crawler requests in our 48-hour window received non-200 responses, primarily 301 redirects from URL structure changes (Tygart Media server log analysis, June 2026). Each non-200 response is a potential missed indexing opportunity.
Building a Server Log Analysis Workflow for AI Search
Here is the complete monitoring workflow we use at Tygart Media, adapted for any publisher running WordPress or a similar CMS.
Daily Monitoring Checklist
Run the AI crawler count script — Track total hits by crawler to identify volume trends
Check for new user agent strings — AI companies launch new crawlers regularly; grep for unrecognized bot patterns
Review top-accessed URLs — Identify which content AI systems are prioritizing today
Monitor response codes — Flag any increase in 403, 404, or 429 responses to AI crawlers
Cross-reference with publication schedule — Track the time gap between publishing and first AI crawler access
Weekly Analysis Framework
Compare AI crawler volume week-over-week — Is AI crawl activity increasing, stable, or declining?
Identify content that stopped getting crawled — Pages that fall off AI crawler radar may be losing citation eligibility
Correlate crawl patterns with known AI search updates — AI platforms update their retrieval systems frequently
Update your llms.txt and sitemap — Based on what AI crawlers are actually accessing versus what you want them to prioritize
Tools for Scaling Server Log Analysis
For publishers managing multiple sites or high-traffic properties, manual grep commands do not scale. Consider these tools:
GoAccess — Open-source real-time log analyzer with terminal and HTML dashboard output. Supports custom log formats and can filter by user agent.
Screaming Frog Log File Analyser — Desktop application specifically designed for SEO log analysis. Supports AI bot filtering and integrates with Google Search Console data.
ELK Stack (Elasticsearch, Logstash, Kibana) — Enterprise-grade log analysis pipeline. Best for publishers who need custom dashboards and real-time alerting.
Datadog / New Relic — Cloud monitoring platforms with log analysis capabilities. Good for teams already using these tools for infrastructure monitoring.
Custom Python/bash scripts — For publishers with technical resources, custom scripts offer the most flexibility for AI-specific analysis.
The Implications: What This Data Means for Content Strategy
Server log analysis is not just a technical exercise. The data it produces should directly inform editorial and SEO decisions.
Content That AI Crawlers Ignore Is Content That AI Will Not Cite
If a page on your site receives zero AI crawler visits over a 30-day window, that page is effectively invisible to AI search systems. It will not be cited by ChatGPT, it will not appear in Copilot responses, and it will not surface in Perplexity answers.
This is a different problem than low Google rankings. A page can rank well in traditional search while being completely absent from AI search — and vice versa. As we documented in our research showing Claude citing articles 16,500 times while Copilot cited roofing content zero times, AI platforms have fundamentally different content preferences than traditional search engines.
AI Crawler Volume Is a Leading Indicator
Traditional analytics are lagging indicators — they tell you what happened after traffic arrived. AI crawler activity is a leading indicator — it tells you what content AI systems are evaluating for future citation. Increasing AI crawl frequency on a specific page or topic cluster often precedes increased citation rates by days or weeks.
Server Logs Validate (or Invalidate) Your Optimization Efforts
If you have implemented llms.txt files, updated your robots.txt, or restructured content for AI search optimization, server logs are the only way to verify that these changes are working. Analytics tools cannot confirm that GPTBot is crawling your llms.txt file. Only your access logs can.
No. GA4 relies on JavaScript execution in a browser environment. AI crawlers like GPTBot, OAI-SearchBot, and ChatGPT-User do not execute JavaScript, so they are completely invisible in GA4. Server log analysis is the only reliable method to monitor AI crawler activity on your site.
What are the main AI crawler user agents to monitor in 2026?
The primary AI crawler user agents to monitor are GPTBot (OpenAI’s training and retrieval crawler), OAI-SearchBot (ChatGPT Search’s real-time citation crawler), ChatGPT-User (live user-initiated fetches from ChatGPT conversations), ClaudeBot (Anthropic’s crawler), Bytespider (ByteDance/TikTok), and PerplexityBot (Perplexity AI’s search crawler).
How many AI crawler requests does a typical publisher site receive?
Volume varies by site authority and content type. Tygart Media’s server log analysis from June 2026 recorded 6,805 AI crawler hits compared to 4,897 traditional search engine crawler hits in a 48-hour window — meaning AI crawlers generated 39% more traffic than traditional crawlers during that period.
What is GPTBot’s crawl behavior pattern?
GPTBot performs intensive structural crawls. Tygart Media server log analysis from June 2026 documented a single GPTBot session executing 1,123 requests within one hour, systematically mapping site architecture, internal links, and content relationships rather than fetching individual pages.
How quickly does Bingbot index new content published via IndexNow?
Based on Tygart Media server log analysis from June 2026, Bingbot showed a consistent 4-hour gap between content publication via IndexNow ping and first crawl of the new URL. This lag is significant because Bing’s index feeds both Microsoft Copilot citations and ChatGPT Search results through OAI-SearchBot.
What Comes Next: From Monitoring to Optimization
Setting up AI crawler monitoring through server logs is the foundation. The next step is using that data to optimize your content specifically for AI search visibility. Key areas to explore:
Robots.txt and llms.txt alignment — Ensure your crawl directives match your citation goals
Content structure optimization — Format content in ways that AI crawlers can efficiently parse and cite
Publication timing — Account for the 4-hour Bingbot indexing gap when publishing time-sensitive content
Cross-platform monitoring — Track how different AI crawlers prioritize different content types
The publishers who will win in AI search are the ones who understand exactly how AI systems interact with their content — and that understanding starts with server logs, not analytics dashboards.
All data referenced in this article is sourced from Tygart Media server log analysis, June 2026. For methodology details and access to our broader AI Search Intelligence research, explore the full series on tygartmedia.com.
Three days. That’s how long Claude Fable 5 existed in the wild before the US government killed it.
On Monday, June 9, Anthropic launched Fable 5 and Mythos 5. On Thursday, June 12, Commerce Secretary Howard Lutnick issued an export control directive ordering Anthropic to suspend access for any foreign national. Since Anthropic can’t verify nationality in real time, they shut it down for everyone. Globally. Immediately. The stated reason was a narrow jailbreak vulnerability — one Anthropic says exists in other publicly deployed models too.
I’m not writing this to debate export controls. I’m writing this because I spent those three days running Fable 5 in production — not benchmarking it, not kicking the tires, actually building with it — and I have something most people writing about this don’t have: receipts.
Day One: The Model Dropped and I Put It to Work
Day one — the model dropped and I put it to work.
Fable 5 launched June 9. By that afternoon, I had it running a Batch 8 sprint across my Tygart Media site — refreshing 10 pages of Claude content that needed updating. Fable 5 updated comparison tables, corrected model names across the lineup, added FAQPage schema, injected internal links, and expanded word counts. Post 4787 went from 750 words to 1,602. Post 9821 went from 1,782 to 2,543. Five posts refreshed with full SEO treatment — schema, FAQs, RankMath meta, silo links — in a single session.
That same day, I had Fable 5 write a complete guide to itself. Not a press release rewrite — a 2,100-word article with an interactive cost calculator, a model picker tool, and a section called “How We Actually Use Each Model” that mapped my real production workflows to each tier: Haiku for the daily 25-post SEO sweeps, Sonnet for desk articles, Opus for deep refreshes, Fable for portfolio-wide audits and strategy. The draft landed in Notion with scoped CSS and JS, ready to paste into WordPress as a single Custom HTML block.
Day Two: Fable 5 Ran My Entire SEO Audit
Day two — Fable 5 ran the SEO audit.
June 10. I ran a full SEO audit of tygartmedia.com through Fable 5. It identified that Fable 5 itself was the top content gap — a model launched 24 hours ago with zero dedicated coverage and peak search intent. So it wrote the article to fill its own gap. It drafted the piece, tagged the slug, assigned the category, and queued internal links to five existing posts.
That same day, Fable 5 wrote and published “The Signal: AI Just Split Into Two Lanes” — a 1,400-word field notes piece that wove together Fable 5’s launch, OpenAI’s S-1, Chrome WebMCP, and the emerging thesis that AI was splitting into a product lane and an infrastructure lane. The article went through the full pipeline: SEO optimization, AEO with 8 FAQ Q&As, GEO entity enrichment, Article + FAQPage schema, taxonomy assignment, internal linking, quality gate — then published via REST API. It even created the LinkedIn draft in Metricool and scheduled it for 2:30 PM Pacific.
That article exists right now at tygartmedia.com. I didn’t write it. Fable 5 did, with me directing the strategy and approving the output. The quality bar was real journalism, not AI slop.
Day Three: Building the Infrastructure Layer
June 11. While the Fable 5 Complete Guide sat in Notion waiting for a featured image, I was using Fable 5 to build the systems that would keep my content operation running. I had it update the Claude Intelligence Desk — my Notion page that serves as the authoritative source of truth for every Claude model name, API string, and price across my entire content operation. Every article gets verified against that desk before publishing. Fable 5 updated it with its own pricing: $10 input, $50 output per million tokens.
I also had Fable 5 design my Pricing Freshness Engine — a WordPress mu-plugin that shadow-checks Anthropic’s live pricing against what’s displayed on my site. The engine had been running in shadow mode since June 2, catching drift before it reaches readers. Fable 5 added itself to the canonical pricing store.
Meanwhile, my 6 scheduled email agent tasks — morning triage, midday check, afternoon wrap, newsletter extraction, weekly prep, and weekly self-audit — were running on the same Claude infrastructure, handling my inbox while I focused on building. The whole system runs on my Max plan. No extra API charges.
What Fable 5 Actually Felt Like
Here’s what the benchmarks don’t tell you: Fable 5 understood intent, not just instructions.
When I told it to run a page refresh, it didn’t just update the text — it checked model names against my Intelligence Desk, verified pricing against live documentation, added schema markup, expanded FAQs, injected internal links, and updated the dateline. It treated each task as a system, not a checklist.
When I asked it to write the Complete Guide, it included a section about how we actually use each model tier in production — because it knew from context that an article about Claude models on a site that runs on Claude models should demonstrate firsthand expertise, not just recite specs. It even built interactive JavaScript widgets inline — a cost calculator and a model picker — without being asked, because it understood the article needed to be useful, not just informative.
The gap between Fable 5 and what came before it was the largest single-model jump I’ve experienced since I started building on Claude in 2024.
What Most Commentators Are Missing
What most commentators are missing.
Most people writing about the shutdown never used Fable 5. They’re debating precedent, policy, the implications for AI regulation. All valid. But the conversation is incomplete without understanding what was actually deployed.
This is the first time the US government has aimed export controls at a deployed commercial AI model rather than at chips or hardware. That’s unprecedented. Anthropic complied but publicly disagreed, calling it a likely misunderstanding based on a narrow jailbreak that exists in other models too.
Every other Claude model — Opus, Sonnet, Haiku — remains fully available and unaffected.
What I Lost
Here’s what the government took from me specifically:
My Fable 5 Complete Guide is sitting in Notion, ready to publish, with the proxy fix queued. The pricing pages need Fable 5 rows added. The Freshness Engine needs Fable 5 in its canonical store. The WordPress proxy’s ALLOWED_DOMAINS needs a one-line gcloud update. All of it was queued up. All of it was dependent on a model that no longer exists.
The infrastructure I built this week — the Intelligence Desk, the Pricing Freshness Engine, the content pipeline that ran “The Signal” from draft to published with schema and social scheduling in a single session — all of that still works with Opus and Sonnet. But the ceiling is lower. The tasks that Fable 5 handled in one pass will take two or three with the models that remain.
What Happens Now
Anthropic says this isn’t permanent. They’re working to restore access.
For people like me who build businesses on top of these tools, the uncertainty is the real cost. Three days is long enough to build production workflows, deploy infrastructure, and write articles that reference a model’s existence — and short enough that all of it gets yanked before you can publish.
But I’m not pulling back. This week confirmed the trajectory. AI at this level isn’t a nice-to-have — it’s the infrastructure of how modern knowledge work gets done. Whether it’s Fable 5 or whatever comes after it, this capability exists now. You can’t un-ring that bell.
I know because I rang it. For three days, I built real things with a model the government decided the world shouldn’t have. And the work is still there in my Notion, waiting.
Will Tygart is the founder of Tygart Media, where he builds AI-native content operations across a portfolio of WordPress sites. He has been building production workflows on Claude since 2024. His Claude Intelligence Desk, Pricing Freshness Engine, and content pipeline systems were all built or upgraded using Claude Fable 5 during its three-day window.
Paste your article. Get back the version built to win the featured snippet.
Who This Is For
Who the AEO content optimizer skill is for.
Built for site owners and content marketers who publish good content that never gets picked as the answer — no featured snippets, no People Also Ask placements, invisible in voice results and AI Overviews while thinner competitor pages take the box.
The Problem
Answer engines do not reward the best content — they reward the most extractable content. A page that buries its answer in paragraph six loses to a page that answers in the first 50 words under a question heading, formatted the way the snippet wants. Restructuring for extraction is mechanical, learnable work — and almost nobody does it. This skill does it on every piece you paste.
What It Does
What it does for featured snippets / AEO.
Performs answer-first surgery: a direct, self-contained 40–60 word answer placed immediately under each question heading
Converts topical headings into the question formats searchers actually use, mapped to real query variants
Matches the winning snippet format per query — paragraph, numbered list, or table — and rebuilds the block to fit
Builds a genuine FAQ section and generates the matching FAQPage JSON-LD (and warns about duplicate schema before you paste)
Runs a voice pass so direct answers survive a smart-speaker read
Returns a change log plus an honest note on what content is missing that the query demands
What You Get
What you get.
The aeo-content-optimizer.skill file — installs in claude.ai or Claude Code in about two minutes
README with installation steps and tested example prompts
Works on existing posts, new drafts, and competitor-gap rewrites
No. You paste your content and your target question. The skill restructures and returns paste-ready output, including the schema block.
Does it work for my niche?
Yes — the method is format-driven, not topic-driven. Local services, SaaS, e-commerce, professional services, and content sites all follow the same extraction rules.
Will it change my voice or facts?
It restructures; it does not genericize. Anything it cannot verify is flagged for you to supply rather than invented.
How is this delivered?
Within 24 hours of purchase via email from will@tygartmedia.com. Skill file and setup guide delivered as a ZIP download.
Does this require a paid Claude subscription?
Installing as a custom skill requires a paid Claude plan (Pro, $20/mo, or higher) with code execution enabled. Your download also includes a free-plan setup option — paste the skill into a Claude Project’s instructions — that works on any plan.
Last verified: October 11, 2026. AI crawler user-agents and llms.txt conventions shift quickly — always confirm bot names and file conventions against the current provider docs and your own server logs before relying on them.
Most conversations about AI crawlability focus on one file: llms.txt. But if you look at what Anthropic, Vercel, and LangGraph actually ship – and what GEO crawler research found AI agents fetching most – the file that matters more is its companion: llms-full.txt.
Here’s the practical reality: llms.txt is the map. llms-full.txt is the territory. And in 2026, the agents that matter for citation traffic are fetching the territory.
The Full File Family You Probably Don’t Know About
The original llms.txt proposal – published by Jeremy Howard in September 2024 – defined one file. Implementers built the rest. The complete family as of mid-2026 is four files, but most sites only need two:
File
What’s in it
When to use
/llms.txt
Curated index – H1, summary, link sections
Always. The orientation layer.
/llms-full.txt
Full content of every linked page, concatenated as Markdown
When you want a model to deep-ingest your docs in a single fetch
/llms-ctx.txt
Pre-expanded context without URLs
FastHTML-style implementations
/llms-ctx-full.txt
Pre-expanded context with URLs preserved
Same, but URL-aware
The pattern that works – and the one Anthropic, Vercel, and LangGraph all run – is the index + export pair: llms.txt for orientation, llms-full.txt for deep ingestion.
Why llms-full.txt Gets Crawled More
Why llms-full.txt gets crawled more.
GEO researchers analyzing AI crawler behavior – including work cited by Profound – have noted that agents from Microsoft, OpenAI, and others tend to fetch llms-full.txt more frequently than llms.txt when both are present. The working explanation is structural: when a file contains the full content, it removes one retrieval step. An agent that fetches llms-full.txt gets everything it needs in a single HTTP request instead of fetching the index, parsing the links, then fetching each linked page individually. This is consistent with how developer documentation platforms like Mintlify describe the behavior of IDE agents operating under tight latency budgets.
For IDE agents (Cursor, Continue, Cline) and MCP integrations, this is even more pronounced. These tools are operating under tight context windows and latency budgets. A single fetch that returns a clean Markdown blob of your entire docs is structurally preferable to a multi-step crawl.
The implication: if you’ve shipped llms.txt but not llms-full.txt, you’ve done half the job.
How to Build llms-full.txt
How to build llms-full.txt.
The construction logic is simple: take every URL in your llms.txt, fetch each page, strip HTML to Markdown, and concatenate. In practice, most sites do this in their build pipeline.
Here’s the minimal Node.js pattern:
const fs = require('fs');
const fetch = require('node-fetch');
const TurndownService = require('turndown');
const turndown = new TurndownService();

async function buildLlmsFullTxt(llmsIndexPath, outputPath) {
  const index = fs.readFileSync(llmsIndexPath, 'utf8');
  const urlRegex = /\[.*?\]\((https?:\/\/[^\)]+)\)/g;
  const urls = [...index.matchAll(urlRegex)].map(m => m[1]);

  let output = '';
  for (const url of urls) {
    const res = await fetch(url);
    const html = await res.text();
    const markdown = turndown.turndown(html);
    output += \n\n---\n# Source: \n\n;
  }

  fs.writeFileSync(outputPath, output);
  console.log(Built llms-full.txt:  pages,  chars);
}

buildLlmsFullTxt('./public/llms.txt', './public/llms-full.txt');
One constraint to manage: keep llms-full.txt under roughly 200,000 tokens (about 150K words, around 700KB). That’s the threshold where most models can ingest the file in a single context window. If your docs are larger, segment by product or language the way Supabase does – llms-full-api.txt, llms-full-guides.txt – and list the segmented files in your main llms.txt.
The 2026 robots.txt Stack That Completes the Picture
The 2026 robots.txt stack that completes the picture.
Shipping llms.txt and llms-full.txt is the visibility layer. The access-control layer is robots.txt – and it changed significantly in Q2 2026.
The key development: Anthropic split its crawler into two separate user-agents. ClaudeBot is the training scraper (high bandwidth, no citation value – block it). Claude-Web is the live-retrieval agent that fetches pages to answer Claude.ai user queries in real time (allow it, because it drives citation traffic). Brands that blanket-block “all Anthropic crawlers” lose Claude citations entirely.
Meta also shipped two active training scrapers in March 2026 – FacebookBot and Meta-ExternalAgent – at GPTBot-level crawl volume. Most sites have no rules for them yet.
One important caveat on robots.txt enforcement: aggressive training scrapers often ignore the file or spoof their user-agents. The robots.txt rules signal intent and work for compliant bots; a WAF rule at the edge is the only deterministic block for non-compliant crawlers.
The Honest State of the Technology
The SERanking study of 300,000 domains (November 2025) found no measurable correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity. Google’s John Mueller compared the file to the deprecated keywords meta tag – something site owners declare but that search systems derive from the content itself.
None of that means you shouldn’t ship both files. The cost is low, the optionality is real, and the IDE-agent ecosystem (Cursor, Continue, Cline) does actively use llms.txt. But the robots.txt work is the lever that moves outcomes today. The llms.txt + llms-full.txt pair is infrastructure investment – you want to be correct when major LLM providers start honoring it, and building the build pipeline now costs far less than retrofitting it later.
The practical sequence for a site that hasn’t done this yet:
Update robots.txt first. Add the Q2 2026 user-agent rules above. This takes twenty minutes and immediately affects how training scrapers treat your content.
Ship llms.txt. Curated index, 20-50 priority pages, one-sentence description per link, sections in priority order.
Build llms-full.txt. Concatenated Markdown of every linked page, under 200K tokens. Run it in your build pipeline so it stays current.
Verify both files are served correctly.curl -I https://yoursite.com/llms.txt should return 200 with Content-Type: text/plain. A 404 on either file is the most common implementation error.
Add an access-log check. Once per month, grep your logs for requests to /llms.txt and /llms-full.txt by user-agent. You want to see live-retrieval agents (Claude-Web, OAI-SearchBot, PerplexityBot) in the results – not just training scrapers.
The goal isn’t to optimize for a standard that isn’t fully adopted yet. It’s to build the infrastructure correctly now, while the field is still forming, so that adoption changes work in your favor rather than requiring catch-up.
What is the difference between llms.txt and llms-full.txt?
llms.txt is a curated index — an H1, a summary, and link sections that orient an AI agent to your site. llms-full.txt is the full content of every linked page concatenated as Markdown, so an agent can deep-ingest your documentation in a single fetch. The index is the map; the full file is the territory.
Why do AI agents crawl llms-full.txt more often than llms.txt?
Fetching llms-full.txt removes a retrieval step: the agent gets everything in one HTTP request instead of fetching the index, parsing links, and fetching each page individually. For IDE agents like Cursor, Continue, and Cline operating under tight latency and context budgets, a single clean Markdown blob is structurally preferable to a multi-step crawl.
How big should llms-full.txt be?
Keep it under roughly 200,000 tokens (about 150K words, around 700KB) so most models can ingest it in a single context window. If your docs are larger, segment by product or language — for example llms-full-api.txt and llms-full-guides.txt — and list the segmented files in your main llms.txt.
Does having llms.txt actually improve AI citations?
Not measurably on its own. A November 2025 SERanking study of 300,000 domains found no correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity, and Google’s John Mueller compared it to the deprecated keywords meta tag. The lever that moves outcomes today is robots.txt configuration; llms.txt and llms-full.txt are low-cost infrastructure for when adoption grows.
Which AI crawlers should I allow in robots.txt in 2026?
Allow live-retrieval agents that drive citation traffic — Claude-Web, OAI-SearchBot, ChatGPT-User, anthropic-ai, and PerplexityBot. Block high-bandwidth training scrapers with no referral value such as GPTBot, CCBot, ClaudeBot, FacebookBot, and Meta-ExternalAgent, and opt out of Google-Extended to skip Gemini training while keeping Search indexing intact.
Most “GEO” advice is recycled SEO with the word “AI” pasted on top. This guide is different. It describes what actually happens when Microsoft Copilot, Bing’s AI answers, and Google’s AI Overviews build a response and decide whose page to cite — based on running content sites that get cited tens of thousands of times a month. The short version: AI engines do not cite the page that ranks #1 for a head term. They cite the page that most directly answers the specific sub-question the model is grounding on. That distinction changes everything about what you should write.
How grounding actually works (the part nobody explains)
How grounding actually works.
When you ask Copilot or Bing’s AI a question, the model does not answer from memory. It runs a retrieval step called grounding: it rewrites your question into one or more search queries, fetches a handful of live web results, reads them, and composes an answer with inline citations pointing back at the pages it used. Google’s AI Overviews work the same way with a technique it calls “query fan-out” — one user question becomes many narrower synthetic queries.
Two things follow directly from this mechanism:
The model is not searching for your keyword. It is searching for the answer to a decomposed sub-question. A user who asks “what’s the best way to instantly index a new page” triggers grounding queries like “IndexNow API endpoint”, “submit URL to Bing programmatically”, and “IndexNow key file location”. The page that wins is the one that answers those narrow strings, not the one optimized for “indexing tips”.
Citations are extracted at the passage level, not the page level. The model lifts the specific sentence or table that answers the sub-question. If your answer is buried under 600 words of preamble, it loses to a page that states the fact in the first line under a matching heading.
This is why a niche, specific page routinely out-cites a high-authority generalist. The generalist ranks; the specialist gets quoted.
Why operational and comparison pages win over head terms
Across real citation data, the pages that get pulled into AI answers cluster into three shapes. None of them are “ultimate guide to X”.
1. Operational pages with real commands, configs, and error messages
When someone asks an AI assistant “how do I fix [specific error]” or “what’s the exact command to do X”, the model needs a page that contains the literal command, the literal config, or the literal error string. Generic advice cannot be cited because there is nothing concrete to quote. A page that says:
curl "https://www.bing.com/indexnow?url=https://example.com/new-page/&key=YOUR_KEY"
# 200 = received (not "indexed"), 422 = URL/key mismatch, 429 = too many submits
…is citation gold, because the model can extract that block verbatim and the user can act on it. The error-code annotations matter: questions about failures (“IndexNow 422”, “why am I getting 429”) are high-intent and low-competition, and a page that names the exact codes owns them.
2. Comparison pages (“X vs Y”)
“Which is better, X or Y” is one of the most common shapes of AI query, and comparison content is structurally easy to cite because it maps cleanly to a decision. If you maintain honest, current head-to-head pages, you become the default source the model reaches for when a user is choosing between tools. This is exactly why we keep dedicated comparison pages like Claude Code vs Cursor and Claude Code vs Codex — they answer a decision the model is constantly being asked to make, and a table of differences is trivially quotable.
3. Fresh, dated pages on fast-moving topics
For anything that changes — pricing, model versions, API limits, feature availability — grounding strongly favors recency. The model would rather cite a page dated this month than an “authoritative” page from two years ago that might be wrong. A visible “Last verified” date and a real publish/update timestamp are not decoration; they are a relevance signal the retrieval layer reads.
The losing move is chasing broad head terms. “Best AI coding assistant” is saturated, generic, and rarely the literal grounding query. The winning move is to own the long, specific, operational and comparison strings that the fan-out actually generates.
IndexNow: how to get cited the same day you publish
IndexNow — cited the same day you publish.
Grounding can only cite pages the engine knows about. The bottleneck for new content is crawl latency — and IndexNow collapses it. IndexNow is an open protocol (backed by Microsoft Bing and Yandex) that lets you push a URL to the index the instant you publish, instead of waiting for a crawler to wander by.
Setup is two steps:
Host a key file. Generate a key of 8-128 hex characters and place it at your site root as a UTF-8 text file named {key}.txt containing exactly that key. Example: https://example.com/daa44a2c....txt. This proves you own the host.
A 200 means the endpoint received your URL (not that it is indexed yet). Submitting to api.indexnow.org shares the ping with all participating engines, so you do not need to hit Bing and Yandex separately. Most WordPress SEO plugins (Rank Math, Yoast, SEOPress) have IndexNow built in — turn it on and it fires automatically on every publish and update. The practical payoff: pages can enter Bing’s crawl queue within hours, which means they are eligible to be grounded and cited the same day, not next week.
One caveat worth stating plainly: IndexNow accelerates indexing, which is a precondition for citation. It does not force a citation. You still need the page to be the best answer to the sub-question. But for fresh, time-sensitive content, same-day indexing is often the difference between getting cited while the topic is hot and showing up after the conversation has moved on.
How to actually measure your AI citations
For a long time AI citations were invisible — you could see referral clicks in analytics but not the citations themselves (most AI answers are zero-click). That changed. As of February 2026, Bing Webmaster Tools ships an AI Performance report (public preview) that shows when your pages are cited across Microsoft Copilot, Bing’s AI answers, and partner surfaces. It is the first direct, free window into AI citation behavior, and you should be reading it weekly.
The four metrics that matter:
Total citations — how many times your site was cited as a source in AI answers over the period.
Average cited pages — the daily average count of unique URLs from your site that got referenced. This tells you whether citations are concentrated on one page or spread across the site.
Grounding queries — sample query phrases the AI used to retrieve and cite you. This is the single most actionable field in the report. It is a literal list of the sub-questions you are winning, which tells you exactly which operational/comparison angles to expand next.
Page-level citation activity — citations by URL, so you can see which pages are doing the work.
Two limitations to keep in mind so you read the data honestly: the report does not show click data (you see citations, not visits from them), and it aggregates Copilot with Bing summaries, so you cannot isolate one surface from the other. For Google’s AI Overviews there is still no equivalent citation dashboard — the closest proxy is watching impressions and referral patterns in GA4 and Search Console, plus spot-checking your target queries by hand.
The workflow that works: pull the grounding-queries list, find the patterns, and feed them straight back into your content plan. If you are getting cited for “claude mcp setup” variants, that is a signal to deepen pages like the Claude MCP setup guide and adjacent operational walkthroughs, not to chase a new head term.
A repeatable checklist for citation-optimized pages
Checklist for citation-optimized pages.
Everything above reduces to a build pattern. For any page you want AI engines to cite:
Lead with the answer. Put a short, factual, quotable answer in the first 1-2 sentences under each heading. Assume the model reads only that passage.
Use question-shaped headings. H2s and H3s that mirror real queries (“How does IndexNow work?”, “How do I measure AI citations?”) match the grounding query and give the extractor a clean anchor.
Be specific and operational. Real commands, real config, real numbers, real error codes and fixes. Concrete text is extractable; vague advice is not.
Add a visible FAQ near the end. Plain question/answer pairs are the single most citation-friendly format, because each pair is a self-contained answer to a discrete sub-question. You do not need JSON-LD schema for this to work — visible Q&A text is what the model reads.
Date it and keep it current. A “Last verified” line plus genuine updates on fast-moving topics buys you the recency edge in grounding.
Push it with IndexNow so it is indexable the same day, then watch the AI Performance report to see which sub-questions it wins.
If you want the larger system this fits into — the full toolchain for operating as an AI-first publisher, from MCP servers to publishing pipelines — start with the AI operator’s stack.
FAQ
Do AI engines cite the page that ranks #1 on Google?
Not reliably. AI engines run their own grounding retrieval and cite the page that most directly answers the specific decomposed sub-question, which is often a niche, operational page rather than the head-term winner. Ranking helps your page be discoverable, but the citation goes to whichever passage best answers the exact grounding query.
What is grounding in AI search?
Grounding is the retrieval step where an AI assistant rewrites your question into search queries, fetches live web pages, reads them, and builds an answer with inline citations to those pages. It is why current, specific pages can get cited even by a model whose training data predates them.
Does IndexNow guarantee my page will be cited by AI?
No. IndexNow guarantees fast indexing, which is a precondition for being cited. The page still has to be the best, most specific answer to the sub-question the model is grounding on. Think of IndexNow as removing the crawl-latency excuse, not as buying a citation.
How do I measure how often AI cites my site?
Use the AI Performance report in Bing Webmaster Tools (public preview since February 2026). It shows total citations, average cited pages per day, sample grounding queries, and citation counts by URL across Microsoft Copilot and Bing AI answers. It does not yet show click-through from those citations, and there is no equivalent dashboard for Google AI Overviews.
Do I need JSON-LD or schema markup to get cited?
No. Citation extraction works on visible, well-structured text — question-shaped headings, short factual answers, and a plain visible FAQ. Schema can help search features generally, but it is not required for AI grounding to read and quote your page.
What kind of pages get cited most?
Three shapes dominate: operational pages with real commands, configs, and error fixes; comparison pages that resolve a “X vs Y” decision; and fresh, dated pages on fast-moving topics like pricing and model versions. Broad head-term content tends to get skipped because it rarely matches the literal grounding query and offers nothing concrete to quote.
Field Intel (2026-05-30): Our social listening desks have detected a massive shift in developer sentiment regarding Claude’s context capabilities.
📈 The Upgrade: Developers on r/ClaudeAI are reporting silent upgrades to the API’s output token ceiling, with contiguous code generations exceeding 6,000 lines without hallucination.
💡 Why it matters: If Anthropic is actively tuning the output ceilings, relying on official documentation limits may underestimate what the model can actually handle in production right now.
Part 3 of 3.Part 1 was the flex — AI assistants cite us and Claude.ai is our #4 traffic source. Part 2 was the playbook — each model cites completely different kinds of pages. Part 3 is the honest one. When I ran the same Claude-powered browser agent against our behavior and event data, the story flipped. The acquisition side of tygartmedia.com is working beautifully. The retention side barely exists. AI assistants like this site more than humans stick around for, and the data makes that painfully clear.
I am publishing the whole leak in public because the fix is the interesting part.
Last refreshed: October 20, 2026 (Pacific).
99.86% of our readers are brand new
99.86% of readers are brand new — acquisition without retention.
In 29 days, GA4 fired 1,405 first_visit events against 1,407 active users. That is a returning-visitor rate of roughly 0.14%. A healthy media site runs at 25–40%. We are running at effectively zero. Put another way: every one of our ~1,400 monthly readers has to be re-acquired next month because there is no returning audience to compound on.
That number is the single most important finding in this whole three-part series. Every story about our AI-referral win in Parts 1 and 2 sits on top of it. If Claude stopped citing us tomorrow, traffic would roughly halve inside 60 days — there is no cushion.
Only 8.6% of visitors scroll to the bottom
Only 8.6% scroll to the bottom — reading relief matters.
GA4 fires a scroll event at 90% page depth by default. Over 29 days, 121 users out of 1,407 fired one. That is 8.6%. The publishing benchmark sits at 25–35%. We are at roughly a quarter of that.
There are two explanations and both are true at once. Some share of the traffic is crawlers and scrapers that do not scroll. And some share of real humans are landing on articles that are either too long for the intent they arrived with, or do not give them a reason to keep going past the first answer.
Four form submissions. In 29 days. Across 1,400 readers.
Event
Count
Users
Events / User
page_view
2,007
1,406
1.43
session_start
1,652
1,406
1.18
first_visit
1,405
1,405
1.00
user_engagement
999
675
1.54
scroll
192
121
1.59
click
34
30
1.13
form_start
15
5
3.00
form_submit
4
4
1.00
Four form submissions across 1,655 sessions. 0.24% conversion. Fifteen people started a form and eleven of them walked away, for a 73% abandonment rate on whatever form we have running. There is also no newsletter_signup event, no cta_click event, no outbound_click event, no video_play event, no file_download event. We are running a publication with effectively zero instrumentation of reader behavior beyond “did the page load.” That is the measurement vacuum, and it is on us to fix.
Pages per session: 1.21
1,655 sessions produced 2,007 page views. That works out to 1.21 pages per session. Healthy media sites run 1.8–3.0. Wikipedia runs 4+. We are effectively a single-page-entry site. Readers arrive for one article, read it or do not, and leave. Nobody is browsing our categories. Nobody is clicking a related-posts rail, because we do not really have one. The internal link graph between our Claude desk, our restoration B2B content, our Mason County hyperlocal, and our general-interest pieces is not moving anybody between them, and the data proves it.
There is one exception worth sitting with. Homepage visitors ( / ) hit an average of 1.59 views per user — meaningfully higher than the site average. The homepage is doing its job. The article templates are not.
Retention is essentially zero
Retention is essentially zero — citations without stickiness.
The GA4 retention cohort chart peaks at about 5% Day-1 retention and drops to effectively zero by Day 7. Out of every 100 readers today, 5 come back tomorrow and 0 come back next week. Healthy publications run 15–25% on Day 1 and 5–10% on Day 7. We are running at a quarter of that across the board.
The fix here is not content. It is a capture mechanism. Right now we have no durable way to turn a claude.ai referral into a known email address. Every AI-cited reader is a one-night stand with the site. Four form submissions in a month is not a newsletter strategy, it is a rounding error.
Real human audience: ~675, not 1,407
GA4 fires user_engagement roughly every 10 seconds of active foreground time. In 29 days only 675 users out of 1,407 ever fired one. That means 52% of our “users” never stuck around long enough for GA4 to confirm they were actually looking at the page. That bucket is some mix of near-instant bounces, back-button users, and crawlers that do not fire the event.
Flipping it the other direction: 48% of reported users is probably the cleanest “real human reader” estimate in the whole account. Call it ~675 real humans per month. That is the number to plan around, not the 1,407 that shows on the dashboard.
The 404 problem is real, and worse for AI referrals
Page not found – Tygart Media is our #7 most-viewed page title in 29 days at 37 pageviews. Some of that is the expected noise of a site that has been through at least one URL restructure — the -2 and -3 suffixed slugs in the data (/anthropic-founders-2, /anthropic-ipo-2, /history-of-anthropic-2) suggest a prior rewrite. But some of it is almost certainly AI assistants citing URLs that no longer resolve.
That is the single worst trust loop to leave open. The LLM does not know the URL is broken. It will keep citing it. Every 404 from an AI referral is a reader who was told by Claude that we had the answer, clicked through, and got a broken page. Fixing the 37 should be the highest-ROI hour of SEO work on our calendar this week.
Concentration risk: one page is carrying the site
/claude-student-discount accounted for 84 of our 2,007 total pageviews in 29 days — roughly 4% of all views on a single URL, and almost 12% when you include everyone who landed on it through any source. It is also the single page cited by all three major LLMs (27 combined sessions from Claude, ChatGPT, and Perplexity). It is both our crown jewel and our single point of failure.
If Anthropic changes their student policy, or a competitor sherlocks the page with a better answer, we lose a material share of total traffic overnight. The response is not to panic, it is to diversify. The structural template that makes that page cite-worthy — narrow topic, answer-first, scannable facts — is repeatable. We need three to five more pages shaped exactly like it.
A real-time snapshot that says everything
While the agent was running the reports, it pulled the real-time view. Two active users were on the site. One was reading /claude-code-vs-aider, a comparison piece. One was bouncing between /selling-into-general-contractors and /selling-into-property-managers, two B2B restoration pages. One landed on a 404. Three verticals, three intents, one broken link — our whole site compressed into thirty minutes.
The short version
We have built a site that AI models like more than humans stick around for. The acquisition side is working. The retention side barely exists. The AI-citation layer is the most interesting asset we have, and it is sitting on top of a reader experience that converts at approximately zero. Close that gap and this turns into a real publication. Leave it open and we are running a very sophisticated funnel that leaks at the bottom. Publishing this publicly is the accountability move — we will update these numbers in 60 days.
The fix, as a list
Instrument the site properly. Add GA4 events for newsletter_signup, cta_click, outbound_click, and scroll depth at 25 / 50 / 75 / 100%. Mark at least one as a key event. Right now we are flying blind past page-load.
Redirect the 404s. Pull the 37 broken-page pageviews, map each to the closest live URL, and push 301s. This is the single highest-ROI hour of SEO work available this week, and it specifically repairs the AI-citation trust loop.
Install a visible capture mechanism on every article. Sticky footer subscribe, mid-article inline form, or both. Pick one default format and ship it across every Claude-desk post first. Without a capture, every AI referral stays a stranger forever.
Add a “Related Claude posts” rail to every Claude article. Pages-per-session of 1.21 means the rest of the content library might as well not exist to any given reader. The homepage is the only page on the site that moves people inward. Rebuild article templates to behave the same way.
Treat /claude-student-discount and /anthropic-console like crown jewels. Keep them ruthlessly updated. Add FAQ schema. Add explicit Q&A blocks. Keep them in the LLM answer set.
Diversify the AI-citation base. Ship three to five new pages in the exact structural template of /claude-student-discount. Narrow, answer-first, scannable. Kill the concentration risk.
Consolidate the Cowork cluster. Fifteen pages, near-zero engagement, near-zero AI citations. Collapse to two or three flagships and redirect the rest.
Audit the Managed Agents pricing title mismatch. 68 path views, 39 title views. Something is rendering or logging inconsistently and it is worth a ten-minute investigation.
Frequently asked questions
What is a healthy returning-visitor rate for a media site?
Most established publications see 25–40% returning visitors. tygartmedia.com currently runs at roughly 0.14%, which is essentially zero. The gap is not content quality — it is the absence of a capture mechanism to turn first-time readers into known subscribers.
What percentage of page views should scroll to the bottom?
The GA4 default scroll event fires at 90% page depth. Healthy content sites see 25–35% of users reach that threshold. tygartmedia.com is at 8.6%, which means either pages are too long for the intent they are arriving with, or a significant share of the traffic is non-human.
How do you separate real readers from bots in GA4?
The cleanest in-account signal is the user_engagement event. GA4 only fires it after roughly ten seconds of focused foreground time on the page. Dividing engaged users by total users gives you a rough “real human reader” estimate. On tygartmedia.com that ratio is 48%, so the real monthly audience is closer to ~675 readers than the reported 1,407.
Why do 404 pages matter more when AI assistants are citing you?
Because the LLM cannot tell when a URL goes dead. Once Claude, ChatGPT, or Perplexity has indexed a citation URL, it will keep recommending that URL to readers even after the page is moved or deleted. Every 404 from an AI referral is a permanently broken trust loop until the URL is restored or redirected.
Why does a single crown-jewel page create concentration risk?
When one URL is responsible for a double-digit share of total traffic and is the only page cited across multiple AI models, any change in the underlying topic — a policy shift by the product being covered, a competitor publishing a better page — can erase that traffic in a single week. The mitigation is to build multiple pages in the same structural template so citation volume is spread across several URLs rather than concentrated in one.
What comes next
The browser agent that dug all of this out is the same one we are turning into a repeatable audit any publisher can run against their own GA4. Parts 1, 2, and 3 together are the first real case study of what that audit looks like. The acquisition playbook is now documented. The retention fix is the next sixty days of work. We will publish the follow-up numbers when the fixes have had a chance to work — or not.
The Search Landscape of May 2026: Stop Chasing Traffic, Start Chasing Citations
The transition is complete. As of this month, Google’s AI Overviews (formerly SGE) appear for over 52% of all search queries. If you are looking at your Search Console and seeing a 30% drop in informational traffic compared to last year, you aren’t alone. You’re simply seeing the result of the “Zero-Click” era reaching its final form. For digital agency owners and systems architects, the old SEO playbook is a liability. If you are still optimizing for clicks on “What is…” or “How to…” keywords, you are effectively donating your intellectual property to train a model that will replace your visit.
The currency of search has shifted. We have moved from the era of link equity to the era of Source-Worthy Content. In this new reality, the goal isn’t to get the user to click through to read a basic definition; it is to ensure that your data, your unique perspective, or your proprietary methodology is the primary source cited by the Retrieval-Augmented Generation (RAG) systems powering Google, Perplexity, and OpenAI.
The Numbers Don’t Lie: The Death of the Click
By mid-2026, the data across our portfolio is clear. Informational query traffic—the top-of-funnel “educational” content that used to drive massive awareness—has cratered by 20-40% across most B2B and technical sectors. Users are getting their answers directly in the search interface. They don’t need to visit your site to learn “how to configure a headless CMS” if Gemini can pull the five essential steps from your documentation and present them in a neat bulleted list.
However, while traffic is down, the value of a single citation within an AI Overview has skyrocketed. We’ve found that being the primary citation in a RAG-driven answer drives higher-intent leads than the old-school organic #1 spot ever did. The users who do click through from an AI Overview have already been pre-qualified by the AI. They aren’t looking for a definition; they are looking for the operator who provided the insight. Optimizing for AI overviews is no longer a side project; it is the core of technical SEO.
Understanding RAG: How Google Picks Its Sources
To win in 2026, you have to understand the mechanics of Retrieval-Augmented Generation. Google’s AI isn’t just “hallucinating” answers based on its training data; it is actively searching the live web, retrieving specific “chunks” of information, and then synthesizing those chunks into a response. This is RAG optimization.
When an AI Overview is generated, Google’s system follows a three-step process:
Retrieval: It identifies the top-ranking traditional search results for the query. (This is why maintaining traditional page-one rankings is still a prerequisite for being a source).
Selection: It selects specific paragraphs, data tables, or unique insights from those top results that best satisfy the user’s intent.
Generation: It rewrites those insights into a cohesive answer, adding citations to the sources it used.
If your content is generic—if it says exactly what every other site says—the AI will synthesize the answer without citing you specifically, or it will cite a larger authority (like Wikipedia or a massive news outlet) that says the same thing. To be cited, your content must be source-worthy. It must provide something the AI cannot find elsewhere or synthesize from common knowledge.
Why Generic Content is Erased by AI
The era of “skyscraper” content—taking ten existing articles and making a longer one—is over. AI is better at that than you are. In fact, most of that generic content is now being flagged by LLMs as “low information gain.”
When we audit a site using the Gemini CLI, we look for “Information Gain” scores. If a paragraph doesn’t offer a new data point, a specific case study result, or a unique operator’s perspective, it’s invisible to the RAG process. Generic advice like “SEO requires good keywords” is discarded. Specific advice like “We saw a 12% lift in RAG citations by moving from 1,000-word articles to 400-word modular content blocks” is source-worthy.
The LLM wants to cite the originator. If you are just a curator, you are a middleman that the AI has successfully bypassed.
The ‘Source-Worthy’ SEO Framework
At Tygart Media, we’ve pivoted our Agency Playbook to focus on four pillars of source-worthy SEO. This is how we ensure our clients remain the “source of truth” in an AI-dominated search engine.
1. Proprietary Data and “Proof of Work”
The AI cannot hallucinate your internal data (yet). Original surveys, technical benchmarks, and project post-mortems are the most cited pieces of content in 2026. If you run a test on a new deployment pipeline and publish the raw numbers, Google’s AI Overview will cite your specific numbers. We’ve moved away from “opinion pieces” and toward “experiment logs.” Every article should contain at least one table or chart of data that didn’t exist on the internet before you published it.
2. The Operator’s Perspective (E-E-A-T)
Experience and Expertise are now the primary filters for RAG selection. Google is prioritizing content that shows “Proof of Effort.” Use first-person accounts. Instead of writing “How to use Claude Code,” write “What we learned after 500 hours using Claude Code to refactor a legacy Python monolith.” The specific failures and technical hurdles you describe are unique identifiers that the AI recognizes as authoritative.
3. Modular Content Architecture
Long-form, sprawling articles are difficult for RAG systems to “chunk” effectively. We are now building content in modular blocks. Each section of an article is designed to stand alone as a complete answer to a sub-query. We use <section> tags and specific ID attributes to make it easy for the crawler to identify and retrieve the exact block it needs. This is optimizing for AI overviews by making your content “consumable” for machines, not just humans.
4. Structured Data for RAG
Schema.org hasn’t gone away; it has become the metadata for AI. We use Dataset, HowTo, and Review schema more aggressively than ever. But more importantly, we are using Gemini CLI to auto-generate JSON-LD that specifically maps out the “Claims” made in our articles. By explicitly stating “Our claim: Informational traffic is down 30%,” we make it easier for the AI to attribute that fact to us.
Technical Execution: Modular E-E-A-T and Gemini CLI
The workflow for a modern agency operator involves high-level automation. We don’t manually audit 500 pages for “source-worthiness.” We use tools like Claude Code and Gemini CLI to process our content libraries.
Our current stack for RAG optimization looks like this:
Analysis: We pipe our top-performing URLs through a script that uses the Gemini API to compare our content against the current AI Overview for that keyword. The script identifies “content gaps”—information the AI is providing that isn’t on our page, or information we have that the AI is ignoring.
Refactoring: If a page is losing traffic but has high “Source Worthiness,” we use Claude Code to refactor the HTML into a more modular structure, adding Dataset schema to any tables.
Validation: we use Antigravity to simulate how a RAG system would “chunk” the page. If the chunks are incoherent, we rewrite the headers to be more explicit.
One failure we saw early in 2026 was attempting to “game” the AI by over-optimizing for specific keywords. The AI sees through keyword density. It is looking for semantic weight. When we tried to force-feed keywords, our RAG citation rate dropped. When we focused on “operator-restrained” technical clarity, the citations returned.
Case Study: The 40% Traffic Drop and the 15% Lead Increase
We recently worked with a systems architecture firm that saw their organic traffic from “cloud migration tips” fall by 40% in the google sge impact may 2026 rollout. Initially, there was panic. However, upon closer inspection, their “Request a Consultation” conversions were actually up by 15%.
What happened? Their generic “tips” were being swallowed by the AI Overview. But the AI Overview was citing their specific “Cloud Migration Cost Calculator” and their “2025 Migration Failure Report.” The traffic they lost was the “looky-loos” who just wanted a quick tip. The traffic they gained (via the AI citations) was from CTOs who saw their specific data cited as the authority and clicked through to hire them. This is the shift from “volume” to “value.”
Action Plan: What You’d Do Tomorrow
If you are managing a content library or an agency portfolio, don’t wait for your traffic to hit zero. Start the pivot to source-worthy SEO immediately. Here is the operator’s checklist for tomorrow morning:
Audit for “What is” Content: Use your preferred crawler to identify every page that targets a purely informational, definitional keyword. These are your “donor” pages. Decide whether to delete them, consolidate them, or upgrade them with proprietary data.
Inject Original Data: Find three pieces of internal data—even if they are small—and add them to your top 10 most important pages. Use tables. Add a “Methodology” section.
Modularize Your Headers: Ensure every H3 in your articles can stand alone as a question and every following paragraph as a direct, concise answer. Remove the “fluff” and the “introductory transitions.” The AI doesn’t need a “In this section, we will explore…” lead-in. It needs the facts.
Verify Citations: Perform a manual search for your primary keywords. Look at the AI Overview. If you are ranking #1-3 in organic but aren’t cited in the AI response, your content isn’t “Source-Worthy.” It’s too generic. Rewrite the top-ranking paragraph to offer a unique, data-backed perspective that the AI is currently missing.
Update Your Schema: Move beyond basic Article schema. Implement Speakable, Dataset, and ClaimReview schema where applicable. Use a tool like Gemini CLI to automate the generation of these blocks based on your existing text.
SEO isn’t dead; the middleman is dead. The search engine of 2026 doesn’t want to send users to a website; it wants to provide an answer. Your job is to be the only source that the answer cannot exist without. Build for the machine, provide for the human, and protect your intellectual property by making it too specific to be ignored.