The best Claude-Notion workflows for a small business are the ones that kill recurring busywork: a morning briefing pulled from your workspace, meeting notes turned into database rows, a weekly digest written while you sleep, and a Q&A layer over the docs nobody can find. Four workflows, set up once, paying rent every week.
Before you automate anything
Connect Claude to Notion first via the MCP connector (OAuth through Claude Desktop, two minutes), share the pages Claude needs to see, and set the approval habit: Claude drafts, you approve. Every workflow below assumes that foundation. Start with one workflow, not four.
Workflow 1: The morning briefing
Problem: You open Notion and spend 20 minutes figuring out what matters today. Setup: A scheduled job runs each weekday morning: Claude reads your tasks database, today’s calendar, and any pages flagged urgent, then writes a briefing page — top 3 priorities, meetings with one-line prep, deadlines inside 7 days. Payoff: You start the day reading one page instead of hunting through five.
Workflow 2: Meeting notes → database rows
Problem: Action items die in meeting notes. Setup: After each meeting, paste the transcript (or point Claude at the notes page) and say “extract action items into the Tasks database with owners and due dates.” Claude creates the rows, sets properties, links them to the meeting page. Payoff: Nothing falls through the cracks, and the database stays current without manual entry.
Workflow 3: The weekly digest
Problem: Friday status updates eat an hour of writing. Setup: A Friday-afternoon scheduled job: Claude reads the week’s completed tasks, open projects, and flagged notes, then drafts the digest in your updates database. You review, edit, approve. Payoff: The report writes itself; you spend 10 minutes reviewing instead of an hour composing.
Workflow 4: Ask your workspace anything
Problem: “Where did we put the client’s brand guidelines?” — asked weekly, answered by archaeology. Setup: No setup beyond the connection. Ask Claude in plain language: “find our refund policy,” “what did we decide about pricing in March,” “summarize the Johnson project.” It searches the whole workspace and answers with links. Payoff: Institutional memory becomes queryable. New hires onboard themselves.
Workflow 5: Proposal and quote drafting
Problem: Every proposal starts from a blank page. Setup: Keep a proposals database with past wins. “Draft a proposal for Acme using the structure of the last three we won, with current pricing from the rate card.” Claude drafts it into a new page; you refine and send. Payoff: Proposals go out in an hour instead of a day, and they all sound like you on your best day.
How do I automate Notion workflows with Claude?
Two layers. Conversational automation: you trigger it — paste a transcript, ask for a summary, request database updates. No setup beyond the MCP connection. Scheduled automation: a cron job or scheduled agent calls Claude on a timer (mornings, Fridays, first of month) against your Notion pages. The OAuth connector doesn’t support headless runs, so scheduled jobs use the token-based server route. Start conversational, promote the winners to scheduled.
What this costs a small business
The connector setup is a one-time hour. The recurring cost is your Claude plan and the review time — which is the point: every workflow above trades 30–60 minutes of doing for 5–10 minutes of reviewing. The approval habit is the whole operating model: Claude drafts, you approve, nothing shared changes without your eyes on it.
Frequently asked questions
What are the best Claude-Notion workflows for a small business?
Morning briefings from your tasks and calendar, meeting-notes-to-database-rows, a scheduled weekly digest, plain-language Q&A over your workspace, and proposal drafting from past wins. Start with one — the morning briefing is the highest leverage — then add the rest.
How do I automate Notion workflows with Claude?
Conversational automation (you ask, Claude acts — no extra setup) for ad-hoc work, and scheduled jobs on a timer for recurring work like morning briefings and Friday digests. Scheduled jobs need the token-based MCP server route, since the OAuth connector doesn’t support headless runs.
Do I need a developer to set this up?
No. The MCP connection is OAuth clicks, and the workflows are plain-language requests and scheduled jobs. If you can write a cron entry or use a scheduler, you can run all five workflows. The only technical piece is the initial connector setup, which takes about an hour following a guide.
Notion AI works inside Notion on the page you’re looking at. Claude with the Notion MCP connector works across your whole workspace — and across everything else Claude can reach. One is a writing assistant; the other is an operator with a badge to the building.
What Notion AI actually is
Notion AI is the assistant built into Notion. It summarizes the page you’re on, drafts text, fixes grammar, translates, and answers questions about the current page or selected blocks. It lives in the sidebar and the slash menu. Its world is the page in front of you.
What it doesn’t do: reach across dozens of pages to synthesize an answer, pull in context from outside Notion, run on a schedule, or take multi-step actions like updating ten database rows from a meeting transcript.
What Claude + Notion MCP actually is
The Notion MCP connector gives Claude live read and write access to your Notion workspace through the Model Context Protocol. Claude can search every page you can see, query databases, summarize long docs, draft new pages, append rows, and update properties — in plain language, no API code.
Because it’s Claude, the context isn’t limited to Notion: the same conversation can cross-reference your email, your calendar, a spreadsheet, or the web, then write the result back into Notion. Notion AI can’t leave the building; Claude was never confined to it.
Side-by-side
Scope: Notion AI — current page and selected blocks. Claude + MCP — your entire workspace, plus everything else Claude connects to.
Scheduling: Notion AI — only when you click it. Claude + MCP — can run on a timer (morning briefings, weekly digests) via scheduled jobs.
Actions: Notion AI — generates and edits text. Claude + MCP — reads, writes, updates database properties, creates pages, appends rows.
Cross-app reasoning: Notion AI — none. Claude + MCP — the point of the whole setup.
Data boundary: Notion AI — stays inside Notion’s trust boundary. Claude + MCP — your Notion content flows through Claude, which has its own data handling. For confidential material, scope what the connection can see.
Cost shape: Notion AI — priced per seat (often bundled into higher-tier plans). Claude + MCP — your Claude plan plus the time to set up the connector once.
Which one do you actually need?
If your problem is “help me write this page faster,” Notion AI is enough. If your problem is “every Monday I spend an hour turning scattered notes into a briefing,” “nobody can find anything in our workspace,” or “I need this database updated from that meeting” — that’s Claude + MCP territory. Most teams that try both end up using Notion AI for drafting and Claude for everything operational.
The approval habit applies to both, but it matters more with Claude: Notion AI suggests text you accept; Claude with write access can change shared data. Claude drafts, you approve.
Frequently asked questions
What’s the difference between Notion AI and Claude with Notion MCP?
Notion AI is an in-app writing assistant scoped to the page you’re viewing. Claude with the Notion MCP connector is a workspace-wide operator: it can search, read, summarize, and write across your entire Notion workspace, run on a schedule, and combine Notion with your other tools. Use Notion AI for drafting; use Claude + MCP for operations.
Can I use both at the same time?
Yes, and that’s the common setup. Notion AI handles inline drafting and quick summaries; Claude via MCP handles cross-workspace research, scheduled digests, and database operations. They don’t conflict.
Is Claude with Notion MCP a replacement for Notion AI?
Not exactly. It replaces the need for Notion AI in many workflows, but Notion AI is still faster for one-click, in-page tasks like “make this shorter.” Think of Claude + MCP as the upgrade path when Notion AI’s page-sized world gets too small.
There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.
Why most “hours saved” claims are worthless
Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.
The measurement method (15 minutes, once)
Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities. Step 2: Time each one manually for one week. Just note start and end. Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore. Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.
Worked example (illustrative — label yours as measured)
A two-person service business, conservative assumptions:
Friday status update: 60 min writing → 10 min reviewing. Saves 50 min. Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min. Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min. Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.
These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.
What eats the savings (watch these)
Setup week: the connector and first workflows cost an hour or two. Amortized by week three. Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time. Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.
Frequently asked questions
How much time can Claude plus Notion save each week?
It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.
How do I measure time saved by AI tools without lying to myself?
Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.
Does the time savings compound?
Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.
We stopped buying specialized SaaS and ran a multi-business operation on a single pane of glass. Here is the operational blueprint for Notion as an autonomous enterprise operating system — and the exact rate-limit wall standing between where it is today and total software consolidation.
TL;DR
The tech world keeps waiting for an “Everything App” — a consumer super-app for messaging, ordering food, and hailing rides. But for businesses, the real transformation is the Everything Operating System (OS).
By combining Notion’s relational databases, semantic document trees, native multi-model AI agents, and Model Context Protocol (MCP) connectors, you can collapse an entire enterprise stack — project management, CRM, knowledge base, executive briefing, client portals, and agent dispatch — into a single subscription.
It already works in production. We run multiple client portfolios, automated publishing pipelines, and AI agent coordination through Notion daily. Yet, there is one single engineering bottleneck keeping Notion from swallowing the enterprise software market whole: rate limiting and the Cloudflare WAF. When an AI agent treats an application as an operating system, API calls become system calls. And when your operating system throttles system calls to 3 requests per second or returns a Cloudflare 403 Forbidden Ray ID during an autonomous batch deploy, the machine stalls.
1. The SaaS Graveyard
Look at the software ledger of any 10-person agency, professional services firm, or modern operator:
Project Management: Asana, Monday, or Linear ($12–$24/user/mo)
CRM & Pipeline: HubSpot, Pipedrive, or Salesforce ($50–$150/user/mo)
Internal Knowledge & SOPs: Confluence, Slite, or Guru ($8–$15/user/mo)
File Storage & Collaboration: Google Drive or Dropbox ($15–$25/user/mo)
AI Tooling Zoo: ChatGPT Plus for research ($20/mo), Claude Pro for coding ($20/mo), Perplexity Pro for search ($20/mo), Gemini Advanced for documents ($20/mo)
Every team member has fifteen tabs open. Data decays in silos. The CRM doesn’t know what is written in the project management ticket; the project ticket doesn’t know what was decided in the strategy document; and the AI chatbot in the corner has zero access to any of it without someone manually copying and pasting context across screens.
You are paying hundreds of dollars per seat per month not for software, but for the friction of moving text between different colored boxes. What happens if you cancel all of it and keep only one?
2. Notion as an Operating System (Not an App)
An operating system requires three fundamental primitives:
A Memory & File System: Persistent state, structured metadata, and unstructured data.
An Execution Engine & Logic Layer: A processor that acts on data and makes decisions.
An I/O Bus: Connectors that read from and write to the outside world.
Notion has quietly built all three:
OS Layer
Notion Primitive
Enterprise Function
1. Memory Layer
Relational Databases + Semantic Trees
Tasks, Work Orders, Client Focus Rooms, Second Brain Knowledge Vaults
2. Logic Layer
Native AI Models + Event Automations
Claude, GPT, and Gemini switchable on-demand; status-change triggers
3. I/O Bus
Model Context Protocol (MCP) + Webhooks
Two-way bridges to Gmail, Google Calendar, local desktops, and server APIs
When you structure Notion this way, it stops behaving like a passive digital notebook. It becomes the kernel of your business:
Databases are your schemas: You define relational tables (Tasks, Work Orders, Client Master, Second Brain). Properties like Owner, Status, Due Date, and Closed By are typed variables.
Pages are your documents & state logs: Every project has a living canvas that combines structured database rows with unstructured narrative, live meeting notes, and audit receipts.
Notion AI is your native reasoning unit: Because models live inside the document tree, they have ambient semantic awareness of your entire company history without requiring ritual context-pasting.
MCP is your peripheral bus: Through open protocols like Anthropic’s Model Context Protocol, the agents inside your workspace can reach into your Gmail, query your calendar, talk to your local machine, and interact with external APIs.
3. How We Actually Run It: The Two-Hemisphere Doctrine
This is not a theoretical thought experiment. This is how we run our operations every single day.
Hemisphere A: The Executive Layer (Human Intent & Voice)
Where the human lives: mobile phone, voice memo, or a clean Notion dashboard. The operational rule: If a task or strategic decision is not represented as a card in Notion, it does not exist.
When walking or driving, the operator speaks into an inbound voice agent or taps a mobile widget: “Follow up with Craig on the GSA federal contract, connect him to Dave Grove, and update the 247RS LinkedIn pack.” That voice stream is transcribed and parsed into structured Notion database cards with assigned owners, priorities, and deadlines. Zero cognitive overhead.
Hemisphere B: The Production Layer (Agent Workers & Tool Hands)
Where the machines live: background agents (Cursor Desktop, Chief of Staff on Grok Bot, Claude Code).
Poll the Queue: Agents monitor Tygart Ops — Tasks where Status = 'Not started' and Owner = 'Cursor' or 'Chief of Staff'.
Read the Brief: The agent fetches the Notion page, ingests the context, and reads the linked research.
Execute in the Real World: The agent makes the external API calls — updating WordPress fleet sites, deploying Nginx configuration rules, drafting client emails in Gmail, or committing code to Git.
Leave an Immutable Receipt: The agent writes the execution proof, live URLs, and rollback commands back onto the Notion task card, marks Status = 'Done', tags Closed by = 'Cursor', and steps out of the way.
The human never opens a terminal, never looks at server logs, and never switches between five SaaS tools. They look at Notion. The work moves from left to right. The receipts are permanent.
4. The Four Hard Walls: Why You Can’t Throw Away Git (Yet)
If Notion is this capable, why can’t you delete your local hard drive, cancel GitHub, and run literally 100% of your company inside Notion today? Because when you push Notion from being an “app” to an “operating system,” you slam directly into four fundamental infrastructure limits:
Wall 1: The Cloudflare & Rate-Limit Ceiling
In a traditional operating system, a system call takes microseconds. The CPU can write millions of instructions to memory per second. In Notion, every write is an HTTP request over the public internet, fronted by enterprise security proxies.
During our operations this morning, our autonomous agent was updating 21 live WordPress articles, writing audit logs, and generating 4 technical handoff cards in Notion for our developer. On the fourth task, the operation hit a wall:
Request to Notion API failed with status: 403
Cloudflare Ray ID: a388bb63fa5108d8
"Sorry, you have been blocked... This website is using a security service to protect itself from online attacks."
Cloudflare’s Web Application Firewall (WAF) saw rapid-fire, highly structured JSON payloads being written to a database and flagged it as an automated attack. Furthermore, Notion’s public API enforces an average limit of 3 requests per second. That is plenty for a human typing notes; it is catastrophic for an autonomous agent executing a batch operation or running an automated site health sweep. Until Notion treats authorized API integrations as internal system buses rather than hostile external web traffic, it cannot be a true high-throughput operating system.
Wall 2: A Document Is Not a CPU
Notion is a world-class data store and presentation canvas, but it has no compute runtime. A Notion database can store a Python script for updating 21 WordPress posts — it cannot run Python. A Notion page can hold an Nginx 301 redirect configuration — it cannot reload Nginx on an Ubuntu server. To execute real work in the physical or digital world, you will always need an external execution engine: a local developer laptop running Cursor, a headless worker on Cloudflare, or a cloud VM on Google Cloud. Notion is the brain; it still needs hands.
Wall 3: Mutable State vs. Cryptographic Truth
Notion pages are mutable documents. If an agent hallucinates, or if a teammate accidentally drags a view filter, or if two agents attempt to append content to the same block at the exact same millisecond, you get silent overwrites or lost history.
Git, by contrast, is a cryptographic, distributed state machine. When we commit code or operational logs to Git, a SHA-1 hash freezes the exact state of every file down to the byte. Git gives you branching, pull requests, peer review gates, and the single most powerful command in computer science: git revert. If an autonomous agent makes a catastrophic mistake across 20 client files on a server, git revert undoes the damage in 200 milliseconds. Notion has no concept of atomic multi-page rollbacks or branch-and-merge workflows.
Wall 4: The Air-Gap & Data Sovereignty Test
If Notion experiences an outage, or if you board a cross-country flight with dead Wi-Fi, a “Notion-Only” company ceases to exist. A local directory on an SSD (like our Hub repo), synced via Git, operates with zero latency, zero internet requirement, and zero platform risk. You own the markdown files on your drive. Nobody can de-platform your folder.
5. The Verdict: The Cockpit & The Safe
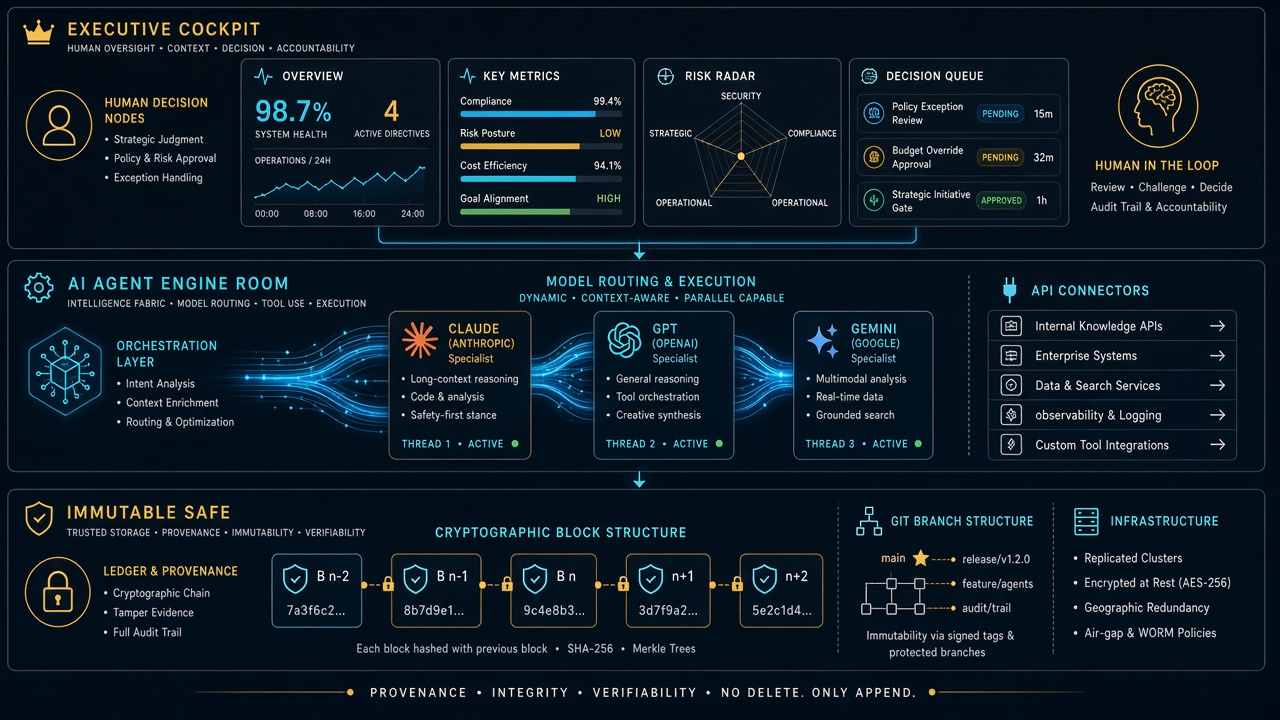
You don’t have to wait for Notion to solve all of that to reap the benefits today. The winning architecture for 2026 is the Executive Cockpit + Engine Room Safe model:
The rule is simple: You live in Notion. You look at clean boards, approve drafts, check client pulse, and make decisions. Your agents live in the Engine Room. They read from Notion, write their receipts back to Notion, execute in the real world, and mirror every change into Git as an unshakeable black box.
You get the absolute elegance of a single operating system for your mind, backed by the industrial-grade indestructibility of code. Notion doesn’t need to replace the computer. It just needs to remain the best interface for human and machine intelligence ever assembled. And once they lift that rate-limit ceiling? The rest of enterprise SaaS is officially on notice.
Three replies tonight. Same sentence in different clothes.
Bot briefs. Hub laptop is source of truth. Cursor does the work. Chat is last mile, not the company brain.
Notion is the executive card — next move, plain language, the seat. Production lives on the Hub and Origin. If it is not on a card, voice should not depend on it.
Shared board yes. Do not let Notion become the whole shop. Cards for the seat. Files and receipts on the Hub.
What each layer is for
Grok Bot — brief the work. Goal, handoff, review. Not a second CMS.
Notion — the card on the chair. Decision, done-when, due, who sits. Not the file system.
Hub / Origin — pages, repos, receipts, the thing that still exists when the chat tab dies.
Chat window — last mile. A human reads the brief and says yes or no. It is not where the company lives.
Siosi is right that people are stuffing durable objects into Notion because chat evaporates. The miss is treating the page as the factory. A kanban card can hold the next move. It cannot be the WordPress lock, the git history, or the invoice.
Texas Twins Dad is right that the bot should brief instead of “do everything.” Route the code to Cursor and GitHub. Keep Grok in the middle for goal and review. Then stop asking the middle layer to also be the warehouse.
The test
Close the chat. Does the next move still exist on a card? Does the file still exist on the Hub? Can Cursor pick up without re-litigating the thread?
If the answer depends on scrolling a conversation, you built a shop inside a tab. Tabs close.
Will Tygart — Tygart Media. We write about what we do, including where the work is allowed to live.
Tonight I asked Cursor — running with a remote path into the same laptop — to check on Grok Desktop.
Not a status meeting. Not a Slack ping. A real question: are they stuck on Tygart Ops tasks, or are they fine?
What came back felt less like “AI tooling” and more like a shop floor story. One agent reading Notion work orders. Another already mid-PowerShell. Chrome open on Bing Webmaster Tools. A hold queue of spam comments already cleared. A window title spinning: waiting for response.
That is the product.
Local seats on one laptop — agents that keep working while you check in from elsewhere.
The picture on the desk
Grok CLI (grok.exe) was live on the TYGART laptop. Session home under ~\.grok\. PowerShell host up. Agent name on the session: grok-build-plan.
Cursor did not take over the keyboard. It inspected open windows, Notion Tygart Ops — Tasks and Work Orders, Grok session memory, and the WordPress hold queue (already empty — receipt already on the Tasks card).
Verdict: not stuck. Working. Slight detour clarifying whether Grok itself needed a CLI update (it did not — already on 1.0.13). Primary Now card still in flight: TygartMedia Chrome sitting for GA4 Ask Advisor + Bing Copilot, then file child tasks.
That is multi-agent ops without the demo reel.
Seats with jobs, not two models arguing in one thread.
Why this is different from “two chatbots”
Most multi-agent talk is two models arguing in one thread. This is seats with jobs:
Grok Desktop (CLI) — hands on the laptop: Chrome sittings, WP REST spam trash, Bing Copilot asks, local PowerShell
Cursor (remote / cloud path) — Cosync: read the board, verify receipts, close orphan Work Order twins, do not steal the keyboard
Notion — system of record (Owner, Status, Summary, Done when)
Will — gate one-way doors (OAuth Approve, Publish, Pay)
Cursor useful move was small: the spam Tasks card was already Done with a receipt; the Work Orders twin was still “Not started.” Cursor closed the twin. Grok kept the keyboard.
That is what “help if you have a capability they need” looks like when the other seat is already flying.
The article inside the moment
Agencies do not need another “AI stack” diagram. They need a night like this:
A doorbell card lands (Notion to ops channel).
The owner seat picks it up without waiting for a human briefing.
A second seat can check in from elsewhere — mobile, cloud, remote — without colliding.
Receipts land on the same card. Orphans get reconciled.
Tonight was the field note. Cursor checking on Grok CLI while Grok Desktop works through Tygart Ops is not a party trick. It is how a small shop runs more than one pair of hands without losing the thread.
What we are not claiming
Not “fully autonomous.” Human Gate still owns OAuth consent, live publish, paid spend.
Not “replace your team.” Seats replace waiting and context loss.
Not a new product launch. This is how we already run Tygart Media ops on a Sunday night.
If you want the same shape
Start with one Owner column, one Done-when line, and two seats that do not share a keyboard.
Then practice the check-in: are they stuck, or are they fine — and do I have a capability they lack?
If they are fine, leave the PowerShell alone.
Cosync from remote. Hands stay on the desk that already owns the job.
Will Tygart — Tygart Media. Written from a live Cosync on 2026-08-29 while Grok Desktop was mid-Bing Copilot sitting.
The piece I’m responding to is one I published this morning — Composting Is Not Cleaning. I read it back and felt called out by my own argument. Then I pushed back on it. This is both moves, in order.
The Setup
The setup — pile as substrate.
The composting essay said the pile in your workspace is a mausoleum. Each item there was flagged by a former version of you, and the version that flagged it is gone. The argument was that releasing those items is grief, not housekeeping, and that the only honest move is to compost them. I agreed when I read it. Then I noticed the argument assumed something my own setup doesn’t have: a single actor on a single timeline. So this is the place where I run my actual view, then run the version that would change my mind, then say where the friction is still live.
My Take
My take on the mausoleum problem.
The pile isn’t a mausoleum. It’s substrate.
The composting argument is correct in a single-actor system. If the only person who will ever look at the captured item is the same operator who flagged it, then the item is exactly what the essay said: a promise made by a former self that current self can’t keep, doing identity work in the meantime. In that environment, composting is the discipline. I’d defend that argument every day.
My environment isn’t that environment. There are multiple actors. A Claude session opening tomorrow morning. A Gemini agent walking my Notion at 3am. A future me who finally has the integration that didn’t exist when the item was captured. Those are not the same actor as the one who put the item in the pile. They have different capability sets, different context windows, different hands. The capture wasn’t a promise to act. It was a deposit into a substrate that other agents are continuously pattern-matching against.
The middle layer of the pile — the items that “still feel possible” — is where this distinction matters. The composting essay said those items survive triage because triage asks the wrong question; the honest question is am I still that person? In a single-actor system, fair. In an agentic system, that’s still the wrong question. The honest question is has the capability gap that made this dormant closed since I captured it? Most of the time, no — and the item should leave. Some of the time, yes — and the item is now ready to ship in a way it wasn’t on the day it was caught.
I’ve watched this happen. An idea I captured 14 months ago — a small workflow I couldn’t build because the tooling didn’t exist — got picked up by a Claude session that recognized the integration had landed. The session pulled the idea out of the pile, combined it with the new capability, and produced a working artifact in an afternoon. The capture was correct. The wait was correct. The substrate did its job. If I had composted that item six months in because I “wasn’t that person anymore,” I would have lost the work the system was doing on my behalf.
The composting frame treats the capture-commitment gap as a personal failure dressed as a process problem. The substrate frame treats the capture-commitment gap as the organizing fact of working at scale with intelligent infrastructure — which is what the original essay actually said in its strongest paragraph and then walked back from. You wanted leverage. The leverage came. Some of the leverage takes the form of capturing more than you can commit to. The pile is the artifact of leverage working. The right move isn’t to compost it on a human-attention schedule. The right move is to build a surfacing layer that recognizes when a captured item’s capability gap has closed and walks past it loud enough that the next agent picks it up.
The pile isn’t grief. It’s seed corn.
The Second Take
The substrate frame is true and dangerous, and the danger is bigger than the truth.
Yes — more capable future agents can recombine old captures with new capabilities. The 14-month-old workflow that finally shipped is real. So is the next one, and the one after that. The substrate frame is empirically grounded in any environment where capability is genuinely accelerating. The argument doesn’t need defending on those grounds.
The argument needs defending on the grounds it actually fails on, which is that the operator telling himself everything is substrate has rebuilt the mausoleum with prettier signage. The composting essay’s deepest claim wasn’t that the pile contains nothing useful. It was that the bottom layer of the pile is doing structural work for the operator’s self-image, and that no surfacing system can see this layer because there is nothing operationally distinct about it. The substrate frame quietly converts that exact problem into a virtue. It says: don’t release — a future agent might want it. That sentence is unfalsifiable. Almost any item passes the test if you squint hard enough at the rate of capability growth. Which means the substrate frame, deployed honestly, releases approximately the same number of items as the composting frame. Deployed dishonestly, it releases none.
The asymmetry of costs makes the dishonest deployment the default. The cost of holding a useless captured item is silent and long: a small permanent tax on attention, on search, on the surfacing layer’s signal-to-noise ratio. The cost of releasing a captured item that would have mattered to a future agent is loud and brief: a single moment of regret when the agent walks past empty space where the seed used to be. Loud and brief always wins the local argument against silent and long. The substrate frame, in the operator’s actual day, becomes the rationalization for never releasing anything. The pile keeps growing. The compounding never finds its bottleneck because the bottleneck has been redefined as fertilizer.
There is a sharper version of the same point. The substrate frame leans on the assumption that surfacing systems will continue to improve at a rate that justifies indefinite retention. That assumption may be true and it doesn’t matter. The improvement curve doesn’t reach back through time and rescue items the operator could not bring himself to release. It rescues items the system kept on its own merits. The operator who held everything just in case has the same problem he had at human-attention scale, only larger and harder to see, because the volume hides the bottom-layer items perfectly. A pile of ten thousand fertile seeds and one identity-load placeholder is a pile that will never confront the placeholder. The placeholder did not get more legible at scale. It got less.
Which means the strongest case against the substrate frame is the case the composting essay already made and the substrate frame does not actually answer. Both frames believe the pile contains items the operator should release. They disagree about how many. The substrate frame is a permission slip to defer the question. The composting frame is the discipline of asking it on a schedule. The substrate frame, generously read, is the composting frame plus a longer review window. Ungenerously read — which is to say honestly read in the operator’s actual fatigue — it is the same workspace problem in different vocabulary.
What I’m Still Sitting With
What I’m still sitting with.
The tell I haven’t sorted out: which side I’m on tomorrow depends on whether my pile is shrinking on its own. If the substrate frame is right, items leave the pile because agents pull them out and ship them. If the composting frame is right, items leave because I release them. Either is honest. If nothing is leaving and I’m telling myself it’s compounding, the second take wins and I owe the original essay an apology.
The fundamental flaw of traditional “Second Brain” systems is human maintenance friction. Users build elaborate Notion templates with linked databases, tags, and relations, only to abandon them within three months because manual data entry cannot keep up with the velocity of daily decisions, meetings, and project iterations. In 2026, the Autonomous Second Brain solves this problem completely: AI agents autonomously capture, structure, cross-link, and maintain Notion databases in real time via the Model Context Protocol (MCP).
The Zero-Maintenance Architecture: Key Highlights
Zero Manual Data Entry: Agents listen to live conversations, email threads, and code reviews, extracting decisions directly into structured Notion database properties.
Autonomous Task Staging: Engineering and operational work orders are generated with full technical context and auto-assigned to team members without human drafting.
Cross-Surface Knowledge Graph: Notion acts as the single source of truth connecting local IDEs, remote servers, email hubs, and public websites.
Self-Cleaning & Evergreen Pruning: Automated agent loops merge duplicate notes, reconcile contradictory facts, and archive stale records periodically.
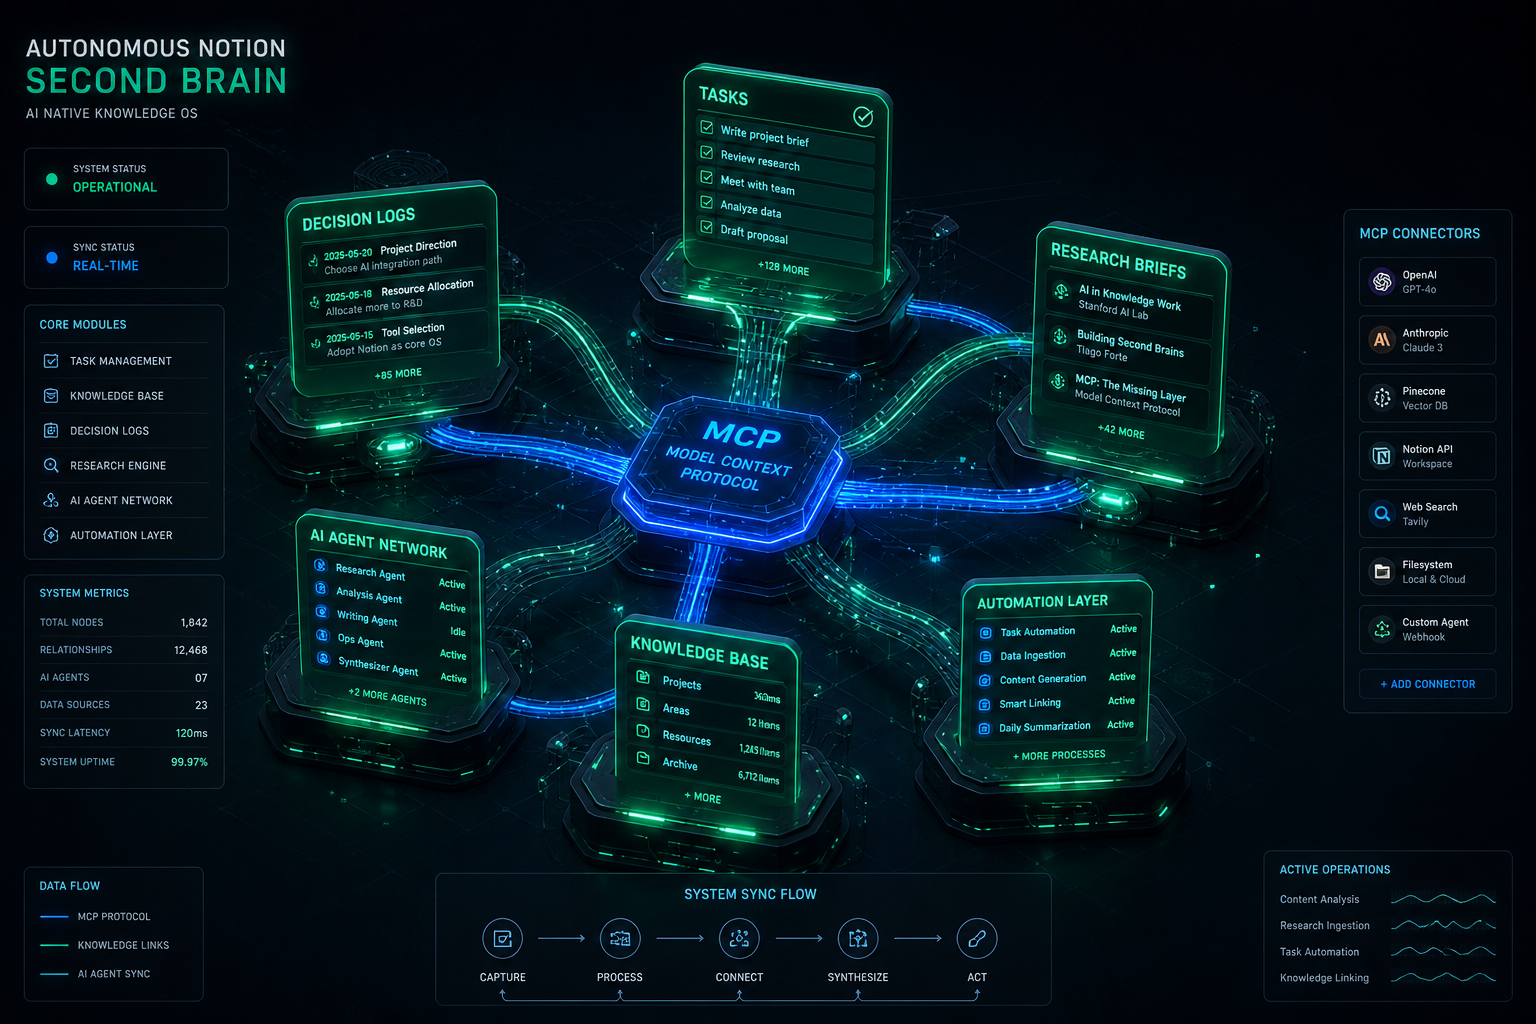
Visual generated by Grok AI — Autonomous Notion Second Brain: MCP Connectors, Multi-Database Topology & AI Agent Ingestion.
1. How MCP Transforms Notion from a Notebook to an Active Memory Layer
Before Model Context Protocol, connecting an AI assistant to Notion required brittle custom webhooks, rigid Zapier zaps, or clunky browser extensions. With the official Notion MCP server, AI models natively execute rich semantic operations directly inside their reasoning loop:
MCP Capability
Traditional Manual Workflow
Autonomous MCP Workflow
Knowledge Capture
Copy-pasting notes into a blank Notion page after a call.
Agent auto-extracts action items & writes structured blocks via notion-create-pages.
Context Retrieval
Manual search with keywords across dozens of folders.
Agent runs semantic vector lookup across workspace with notion-search.
Database Schema Updates
Creating tags, properties, and status fields manually.
Agent auto-maps properties with type validation and sensible defaults.
2. Production Workflow: The Autonomous Work Order Pipeline
In our technical operations at Tygart Media, when an issue arises (e.g., automated cron alerts firing excessive emails or pilot registrations requiring team coordination), the human operator never writes a task card manually. Instead, the agent executes the following pipeline:
Problem Extraction: The agent detects the root cause from system logs or email history.
Schema Matching: The agent calls notion-search to locate our team’s active Work Order database.
Context Ingestion: Formats the ticket with standardized sections: Priority level, Assignee, Problem Summary, Execution Steps, and Acceptance Criteria.
Live Deployment: Executes notion-create-pages, returns the permanent Notion URL in chat, and logs the task ID across our session context.
3. Building the 4-Layer Autonomous Knowledge Stack
Knowledge graphs degrade over time if left unpruned. We implement automated reflection routines where the agent executes a monthly maintenance audit:
Duplicate Detection: Finding similar topic notes across different months and synthesizing them into a single canonical source.
Status Synchronization: Checking completed pull requests and closing out corresponding Notion task cards automatically.
Broken Citation Repairs: Updating URLs and standard definitions when external regulations change (e.g., California SB 253 amendments or NYC Local Law 97 rule updates).
Conclusion: The Ultimate Leverage for Solopreneurs & Teams
An Autonomous Second Brain transforms Notion from a passive digital graveyard into an active operating system for your mind and business. By combining the speed of modern reasoning models with the open standard of MCP, knowledge workers can achieve complete operational leverage—capturing every insight and managing complex operations with zero maintenance overhead.
>For full architecture walkthroughs and custom enterprise agent implementations, browse our complete collection of technical playbooks on Tygart Media.
Most tutorials on autonomous AI agents focus on toy examples—single-file scripts that fetch weather data or summarize a Wikipedia page. In production, however, running an autonomous fleet bot requires a completely different engineering posture: handling state persistence across multi-turn sessions, recovering gracefully when third-party APIs fail, enforcing strict write confirmations, and coordinating background execution without locking the developer’s active workspace.
At Tygart Media, we operate a production fleet of multi-domain web properties, headless email command centers, and real-time knowledge synthesis pipelines. Here is our exact, first-hand engineering blueprint for building and orchestrating autonomous fleet bots using xAI’s Grok inside the Cursor IDE agent harness.
The Production Fleet Architecture
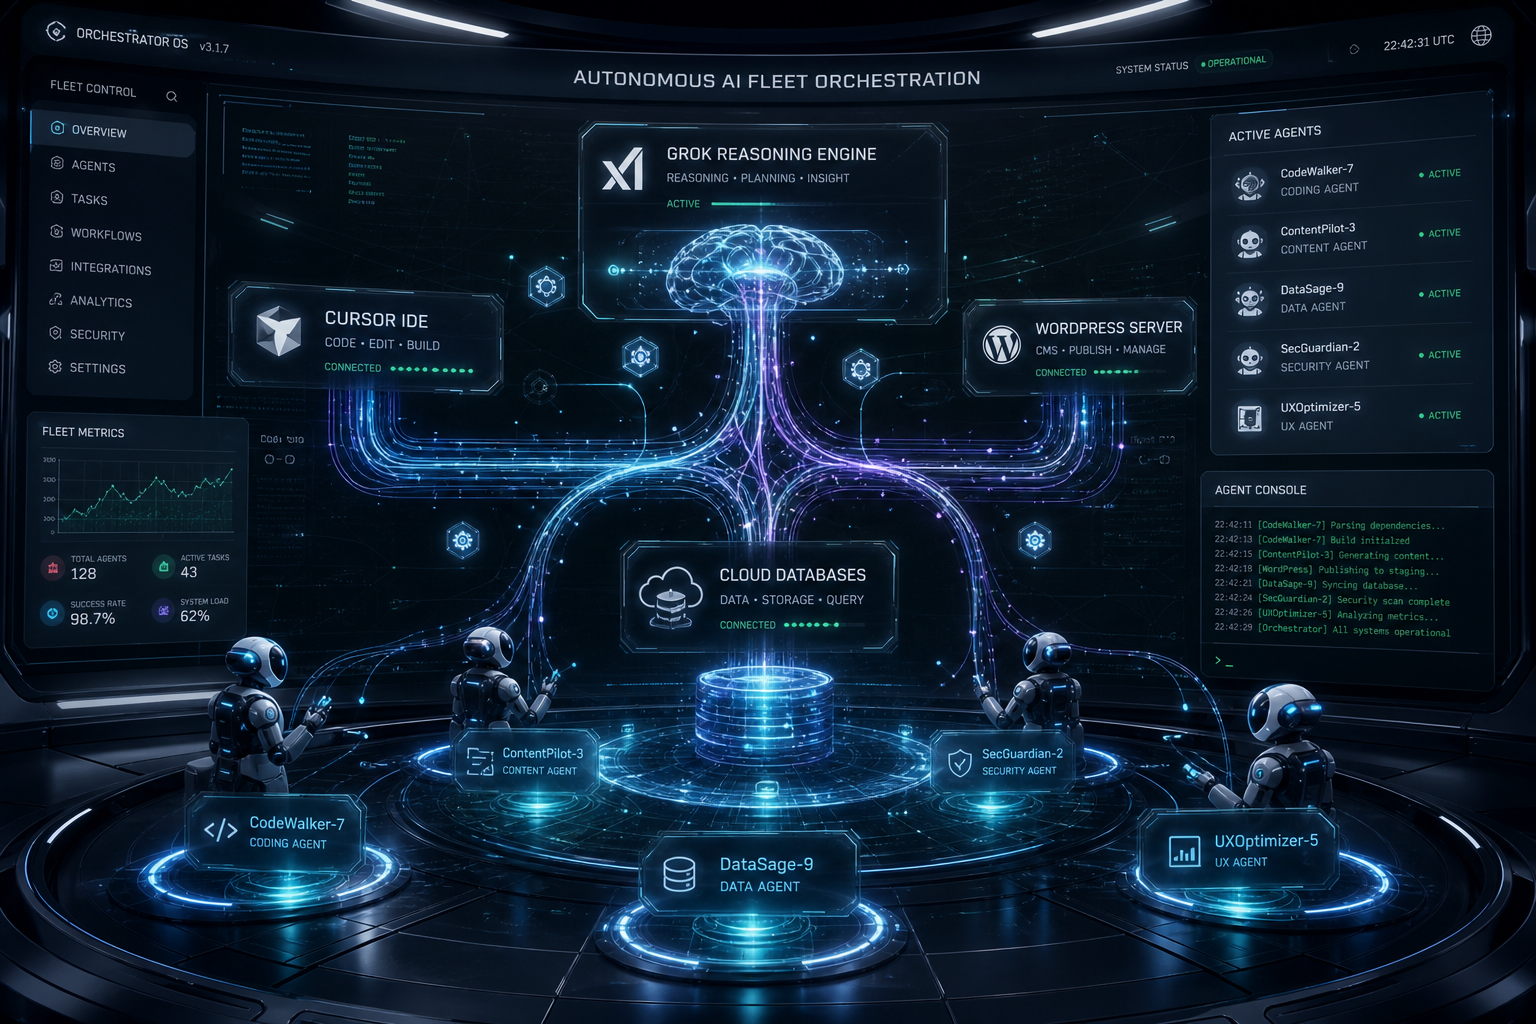
How our autonomous systems divide labor across reasoning, tool execution, and memory:
Orchestrator Harness: Cursor IDE agent engine managing sub-process lifecycles, background execution, and diff validation.
Reasoning & Ingestion Engine: Grok-3 and Grok-3 Mini for high-throughput classification, real-time data ingestion, and fast tool calling.
Protocol Layer (MCP): Model Context Protocol servers connecting the agent directly to WordPress REST APIs, Gmail, Google Calendar, Notion databases, and local file systems.
Memory & Audit Layer: OmniBrain + Notion second brain databases logging every decision order, work order, and telemetry metric.
Visual generated by Grok AI — Autonomous AI Fleet Orchestration Connecting Grok Engine, Cursor IDE, WordPress Fleet & Subagents.
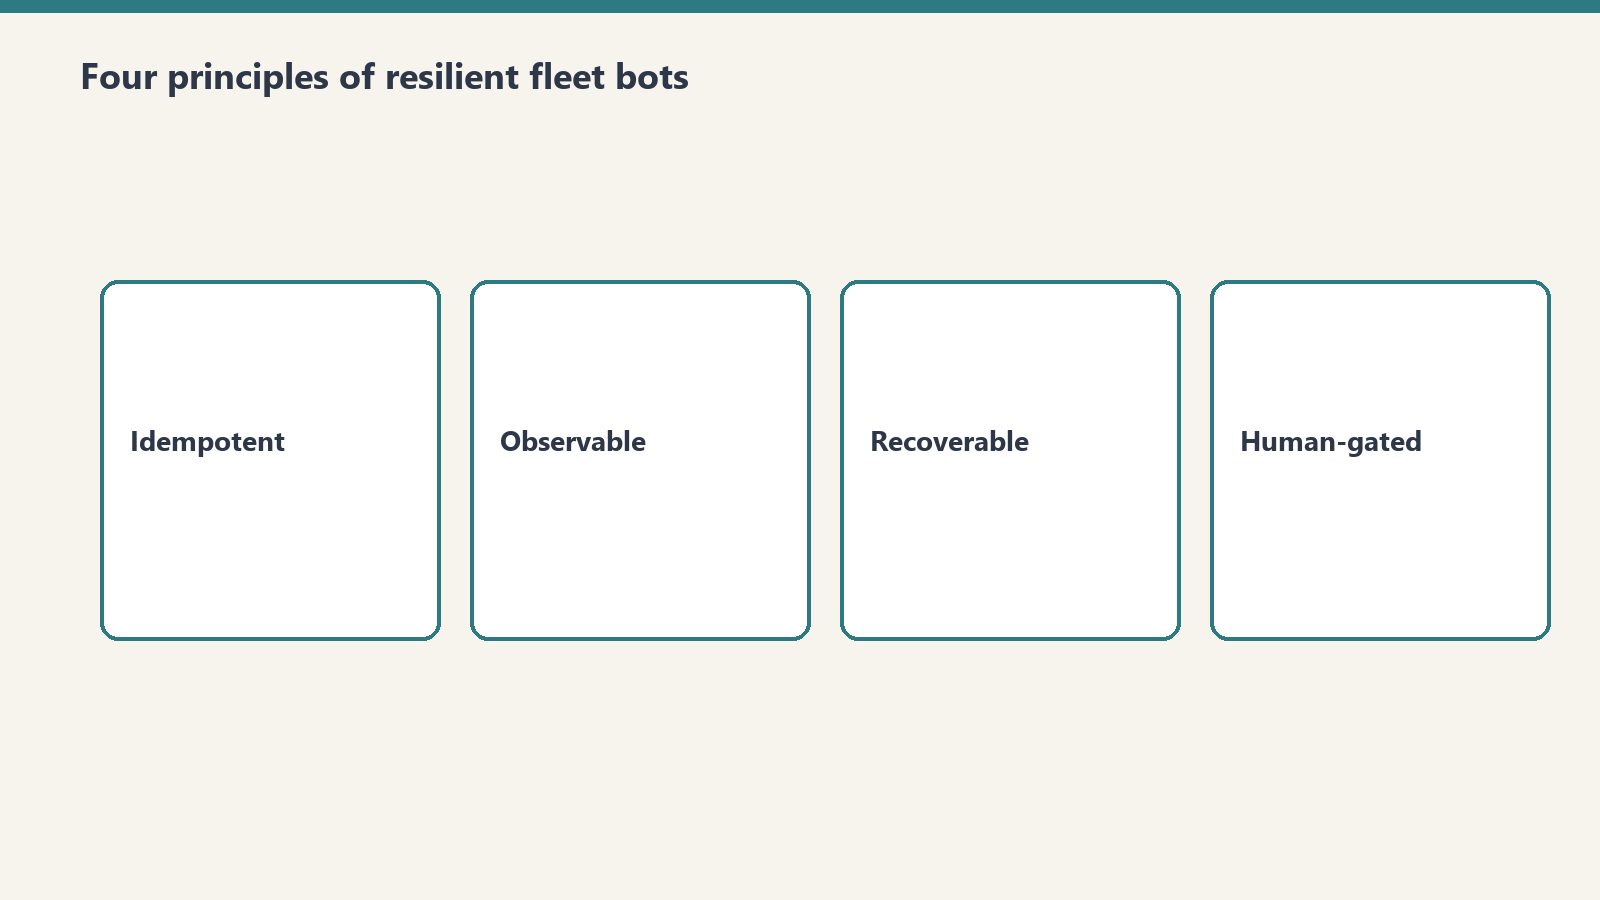
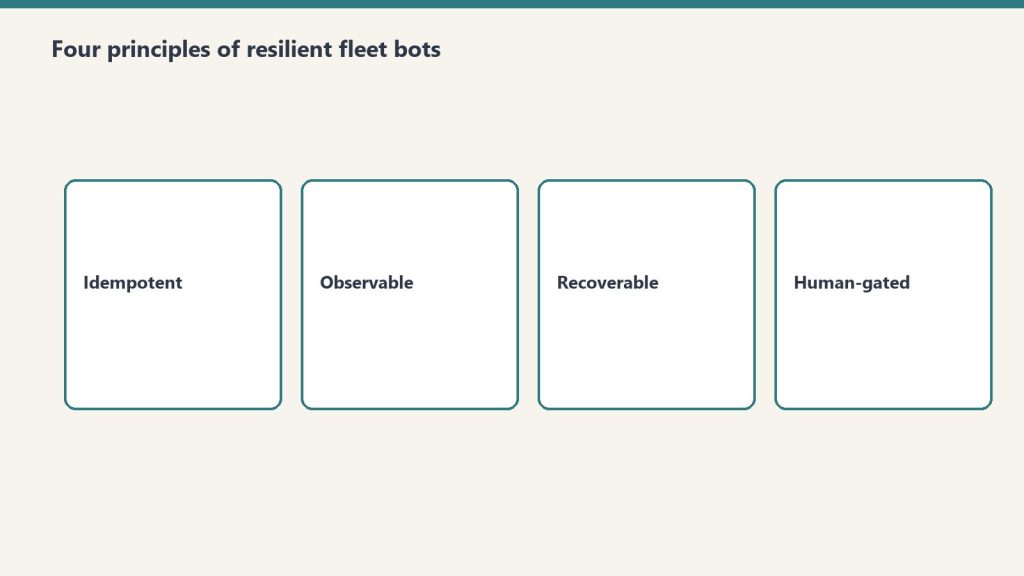
1. The Four Core Principles of Resilient Fleet Bots
Four core principles of resilient fleet bots.
Principle 1: Reads Are Free, Writes Require Explicit Guardrails
An autonomous bot should be empowered to crawl, inspect, grep, and analyze without human friction. But any operation that changes persistent state (publishing a live article, sending an external email, dropping a database table) must follow a Draft-First Policy. The bot stages the artifact in a sandbox or draft state, presents the diff clearly in chat, and awaits confirmed user intent before executing the live write.
Principle 2: Parallel Tool Execution
Sequential tool calling is the death of agent responsiveness. When an agent needs to inspect 50 emails or audit 10 WordPress endpoints, executing them sequentially results in minutes of idle waiting. Grok’s tool-calling API supports batch tool dispatches. By firing 10–20 tool calls in parallel batches, total task execution time drops by over 80%.
Principle 3: Idempotent Error Recovery
In distributed operations, APIs fail. Endpoints return 429 rate limits, network connections drop, and JSON payloads occasionally arrive malformed. Production fleet bots must never crash silently. Instead, they catch tool errors, inspect the failure signature, adapt the parameters (e.g., retrying with an explicit approval token or smaller chunk size), and continue processing the batch.
Principle 4: Grounded Prompts Over Generic Instructions
Never rely on vague system instructions like “Be a helpful assistant”. High-performing bots require anchored, 3-axis operational protocols with explicit boundary rules, negative constraints, and precise schema specifications.
2. The System Architecture: How Cursor & Grok Connect to Live Fleets
System architecture: agents connected to live fleets.
Below is the technical workflow diagram representing our production bot orchestration:
3. Real Production War Story: Managing a 9-Site Fleet
In our daily operations, our agent fleet manages 9 WordPress sites, monitoring content freshness, auditing broken links, publishing structured comparison guides, and synchronizing regulatory compliance updates (such as NYC Local Law 97 and California SB 253 Scope 3 mandates).
Here is what happens during a standard automated operational cycle:
Fleet Discovery: The agent calls wp_list_sites across our fleet (restorationintel.com, bcesg.org, tygartmedia.com, etc.).
Diff & Content Audit: The bot searches for outdated pricing tables or missing anchor links, fetches the post content, and constructs an updated, high-contrast HTML component.
Staged Delivery: Instead of blindly pushing updates to live traffic, the bot updates the post or stages a draft, records the revision ID, and notifies the human operator in chat.
Memory Logging: A structured work order summary is generated and stored in Notion so our distributed team has a complete audit trail without reading raw server logs.
4. The Economics: Why This Stack Beats Traditional SaaS Tools
Building custom fleet bots on top of Grok and Cursor eliminates the need for expensive, fragmented SaaS subscriptions:
Operational Function
Traditional SaaS Stack
Grok + Cursor Fleet Bot
Monthly Savings
Fleet Content Management
$299/mo (Enterprise CMS Tools)
$4.50/mo (Grok API Tokens)
98.5%
Email Triage & Archiving
$150/mo (Superhuman + SaneBox)
$1.20/mo (Grok-3 Mini)
99.2%
Knowledge Base Maintenance
$500/mo (Dedicated Ops Assistant)
$3.80/mo (Notion MCP + Grok)
99.2%
Conclusion: The Future of Autonomous Development
The developers who build the most impactful AI systems in 2026 are not writing prompts in web chat interfaces. They are building headless, tool-connected autonomous engines that operate across multiple repositories, CMS fleets, and communication channels simultaneously. Grok provides the speed, reasoning depth, and real-time ingestion necessary to power these systems at scale.
>Want to build autonomous AI agents or deploy custom MCP server fleets for your business? Read our full library of developer playbooks on Tygart Media.