Tag: Claude

  • Claude vs ChatGPT: The Honest 2026 Comparison

    Claude vs ChatGPT: The Honest 2026 Comparison

    Last refreshed: May 15, 2026

    Claude AI · Fitted Claude

    Two AI assistants dominate the conversation right now: Claude and ChatGPT. If you’re trying to decide which one belongs in your workflow, you’ve probably already noticed that most “comparisons” online are surface-level takes written by people who spent an afternoon with each tool.

    This isn’t that. I run an AI-native agency that uses both tools daily across content, code, SEO, and client strategy. Here’s what actually separates them in 2026 — and when each one wins.

    Quick answer: Claude is better for long-context analysis, writing quality, and following complex instructions without drift. ChatGPT is better for integrations, image generation, and breadth of third-party plugins. For most knowledge workers, Claude is the daily driver — ChatGPT is the specialist.

    The Fast Verdict: Category by Category

    Three stacked layers: chat UI, tools, agent runtime
    The fast verdict — category by category.
    Category Claude ChatGPT Notes
    Writing quality ✅ Wins Less sycophantic, more natural voice
    Following complex instructions ✅ Wins Holds multi-part instructions without drift
    Long document analysis ✅ Wins 200K token context vs GPT-4o’s 128K
    Coding ✅ Slight edge Claude Code is a dedicated agentic coding tool
    Image generation ✅ Wins DALL-E 3 built in; Claude has no native image gen
    Third-party integrations ✅ Wins GPT’s plugin/Custom GPT ecosystem is larger
    Web search ✅ Slight edge Both have web search; GPT’s is more integrated
    Pricing (base) Tie Tie Both $20/mo for Pro/Plus; API costs comparable
    Not sure which to use?

    We’ll help you pick the right stack — and set it up.

    Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.

    Writing Quality: Why Claude Has a Distinct Edge

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Writing quality — why Claude has a distinct edge.

    The difference becomes obvious when you give both models the same writing task and read the outputs side by side. ChatGPT has a tendency to over-affirm, over-structure, and reach for generic phrasing. Ask it to write a LinkedIn post and you’ll often get something that reads like a LinkedIn post — in the worst way.

    Claude’s outputs read closer to how a thoughtful human actually writes. Sentences vary. Paragraphs breathe. It doesn’t reflexively add a bullet list to every response or pepper the text with unnecessary bold text. It also pushes back more readily when an instruction doesn’t quite make sense, rather than producing confident-sounding nonsense.

    For any work that ends up in front of clients, readers, or stakeholders, Claude’s writing quality is a meaningful advantage. This holds for long-form articles, email drafts, executive summaries, and proposal copy.

    Context Window: The Practical Difference

    Claude’s context window — the amount of text it can hold and reason over in a single conversation — is substantially larger than ChatGPT’s standard offering. Claude Sonnet 4.6 and Opus both support up to 200,000 tokens. GPT-4o tops out at 128,000 tokens.

    In practice, this matters for:

    • Analyzing long contracts, reports, or research documents in one pass
    • Working with large codebases without losing track of what’s already been discussed
    • Multi-document analysis where you need to synthesize across sources
    • Long agentic sessions where conversation history is critical

    If you regularly work with documents over 50–80 pages or run long agentic workflows, Claude’s context advantage is a functional one, not just a spec sheet number.

    Instruction Following: Where Claude Consistently Outperforms

    Give Claude a complex, multi-part instruction with specific constraints — “write this in third person, under 400 words, no bullet points, mention X and Y but not Z, match this tone” — and it tends to hold all of those requirements across the full response. ChatGPT frequently drifts, especially on longer outputs.

    This matters most for:

    • Prompt-heavy workflows where precision is required
    • Batch content generation with strict brand voice rules
    • Agentic tasks where Claude is executing multi-step operations
    • Any scenario where you’ve spent time engineering a precise prompt

    Anthropic built Claude with a focus on being genuinely helpful without being sycophantic — meaning it’s designed to give you the accurate answer, not the agreeable one. In practice, Claude is more likely to flag when something in your request is unclear or contradictory rather than guessing and producing something confidently wrong.

    Coding: Claude Code vs ChatGPT

    For general coding questions — syntax, debugging, explaining code — both models perform well. The meaningful differentiation is at the agentic level.

    Anthropic’s Claude Code is a dedicated command-line coding agent that can work autonomously on a codebase: reading files, writing code, running tests, and iterating. It’s a different category of tool than ChatGPT’s code interpreter, which executes code in a sandboxed environment but doesn’t have the same level of agentic control over a real development environment.

    For developers running AI-assisted workflows on actual projects, Claude Code is the more serious tool in 2026. For casual code help or one-off scripts, the gap is smaller.

    Where ChatGPT Wins: Image Generation and Ecosystem

    ChatGPT has a clear advantage in two areas that matter to a lot of users.

    Image generation: DALL-E 3 is built directly into ChatGPT Plus. You can go from text to image in one conversation. Claude has no native image generation capability — you’d need to use a separate tool like Midjourney, Adobe Firefly, or Imagen on Google Cloud.

    Third-party integrations: OpenAI’s plugin ecosystem and Custom GPTs have more breadth than Claude’s integrations. If you rely on specific third-party tools (Zapier, specific APIs, custom workflows), there’s more infrastructure already built around ChatGPT.

    If image creation is a daily part of your workflow, or you’re heavily invested in a ChatGPT-centric tool stack, these advantages are real.

    Claude vs ChatGPT for Coding Specifically

    When coding is the primary use case, the comparison shifts toward Claude — but it’s worth being precise about why.

    For writing clean, well-commented code from scratch, Claude tends to produce cleaner output with better reasoning explanations. It’s less likely to hallucinate function signatures or library methods. For debugging, Claude’s ability to hold large code files in context without losing track is a functional advantage.

    ChatGPT’s code interpreter (now called Advanced Data Analysis) is strong for data science workflows — running actual Python in a sandbox, generating visualizations, processing files. If your coding work is primarily data analysis and you want execution in the same tool, ChatGPT has the edge there.

    Claude vs ChatGPT for Writing Specifically

    For any writing that requires a genuine human voice — op-eds, thought leadership, nuanced argument — Claude is the better instrument. Its outputs require less editing to remove the robotic, list-heavy, over-hedged quality that plagues a lot of AI-generated content.

    For template-heavy writing — product descriptions, SEO-optimized articles at scale, standardized reports — the gap is smaller and comes down to your specific prompting setup.

    What Reddit Actually Says

    The Claude vs ChatGPT debate on Reddit (r/ChatGPT, r/ClaudeAI, r/artificial) consistently surfaces a few recurring themes:

    • Writers and researchers prefer Claude — repeatedly cited for better prose and genuine analysis
    • Developers are more split — Claude Code has built a dedicated following, but the ChatGPT ecosystem is more familiar
    • ChatGPT wins on integrations — the plugin/Custom GPT ecosystem still has more breadth
    • Claude is less annoying — specific complaints about ChatGPT’s sycophancy appear frequently (“it agrees with everything”, “it always says ‘great question’”)
    • Both have gotten better fast — direct comparisons from 2023–2024 often don’t hold in 2026

    Pricing: What You Actually Pay

    The base subscription pricing is identical: $20/month for Claude Pro and $20/month for ChatGPT Plus — see the full Claude pricing breakdown for everything beyond the base tier. If you’re wondering what the free tier actually includes before committing, see what Claude’s free tier gets you in 2026. Both include web search, file uploads, and access to advanced models.

    Where it diverges:

    • Claude Max ($100/mo) — for power users who need 5x the usage of Pro
    • ChatGPT doesn’t have a direct equivalent tier between Plus and Enterprise
    • API pricing — comparable but varies by model; Anthropic’s pricing is token-based and published transparently
    • Claude Code — has its own pricing structure for the agentic coding tool

    For most individual users, the $20/mo tier is the right starting point for either tool.

    Which One Is Actually Better in 2026?
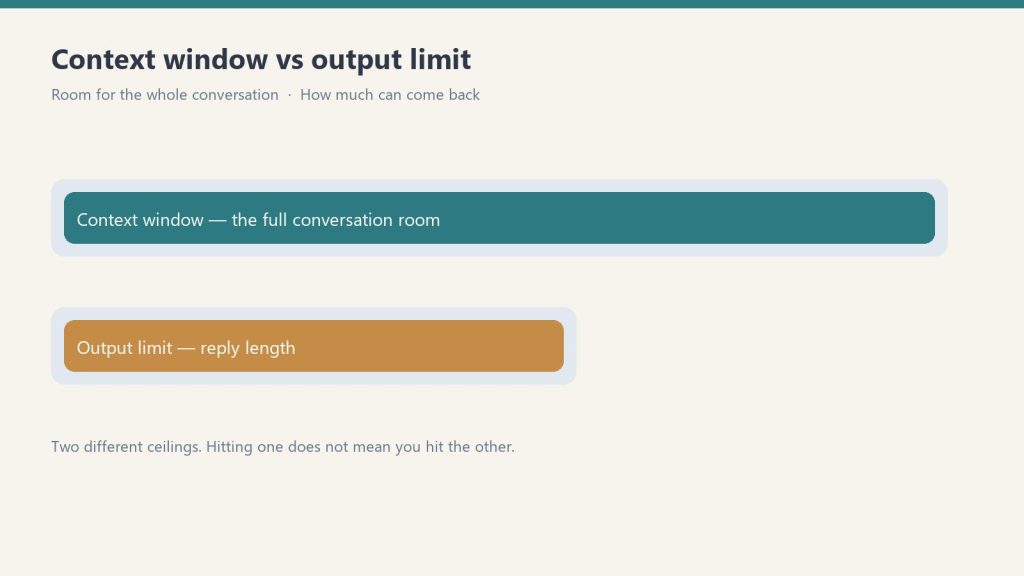
    Diagram comparing a long context window bar with a shorter output limit bar
    Which one is actually better in 2026?

    The honest answer: Claude is better for the work that benefits most from language quality, reasoning depth, and instruction precision. ChatGPT is better for the work that benefits from breadth of integrations and built-in image generation.

    For a solo operator, consultant, or knowledge worker whose primary outputs are written analysis, content, and strategy: Claude is the better daily driver. The writing is cleaner, the reasoning is more reliable, and the context window is more practical for serious document work.

    For a team already embedded in the OpenAI ecosystem — with Custom GPTs, plugins, and Zapier workflows built around ChatGPT — switching has real friction that may not be worth it unless writing quality is a high-priority problem.

    The most pragmatic setup for serious users — check the Claude model comparison to understand which tier makes sense for your work, and the Claude prompt library to get the most out of whichever you choose. The most pragmatic setup for serious users: Claude for thinking and writing, access to ChatGPT for when you need DALL-E or a specific integration it covers. At $20/month each, running both is a reasonable choice if the work justifies it.

    Frequently Asked Questions

    Is Claude better than ChatGPT?

    For writing quality, complex instruction following, and long-document analysis, Claude outperforms ChatGPT in most head-to-head tests. ChatGPT has the advantage in image generation and third-party integrations. The right answer depends on your primary use case.

    Can I use both Claude and ChatGPT?

    Yes, and many power users do. Both have $20/month Pro tiers. Running both gives you Claude’s writing and reasoning strength alongside ChatGPT’s DALL-E image generation and broader plugin ecosystem.

    Which is better for coding — Claude or ChatGPT?

    Claude has a slight edge for writing clean code and agentic coding workflows via Claude Code. ChatGPT’s Advanced Data Analysis (code interpreter) is better for data science work where you need code execution in a sandboxed environment. For general coding help, both are strong.

    Which AI is better for writing?

    Claude consistently produces better writing — less generic, less sycophantic, and closer to a natural human voice. Writers, editors, and content strategists repeatedly report that Claude’s outputs require less editing and drift less from the intended tone.

    Is Claude free to use?

    Claude has a free tier with limited daily usage. Claude Pro is $20/month and provides significantly more capacity. Claude Max at $100/month is for heavy users. API access is billed separately by token usage.
    Need this set up for your team? Talk to Will →
  • The Real Monthly Cost of Running Claude Managed Agents 24/7

    The Real Monthly Cost of Running Claude Managed Agents 24/7

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    If you’re considering running Claude Managed Agents around the clock, you want a number. Not “it depends.” An actual number you can put in a budget. Here’s the math, worked out by scenario, with the honest caveats about where the real costs are.

    The Formula

    Three stacked layers: chat UI, tools, agent runtime
    The formula.

    Total monthly cost = (Active session hours × $0.08) + token costs + optional tool costs

    The $0.08/session-hour charge only applies during active execution. Idle time — waiting for input, tool confirmations, external API responses — doesn’t count. This matters significantly for 24/7 workloads, because very few agents are active 100% of the time even when “running around the clock.”

    The Maximum Theoretical Cost

    Scenario: Agent running continuously, zero idle time, 24 hours a day, 30 days a month.

    • Session runtime: 24 hrs × $0.08 × 30 days = $57.60/month
    • Token costs: separate, highly variable (see below)

    $57.60/month is the ceiling on session runtime charges. You cannot pay more than this in session fees under any 24/7 scenario. But here’s the reality: that ceiling assumes zero idle time across the entire month, which doesn’t describe any real production agent.

    Realistic 24/7 Scenarios

    Diagram comparing a long context window bar with a shorter output limit bar
    Realistic 24/7 scenarios.

    Monitoring Agent (High Idle Ratio)

    Runs continuously watching for triggers — error alerts, specific data patterns, incoming requests. Activates on trigger, processes, returns to monitoring state.

    • Assumption: 5% active execution time (watching 95% of the time, executing 5%)
    • Active hours: 24 × 30 × 0.05 = 36 hours/month
    • Session runtime: 36 × $0.08 = $2.88/month
    • Token costs: low — moderate bursts on trigger events
    • Realistic total: $5–15/month

    Customer Support Agent (Business Hours Active)

    “24/7” in the sense of always-available, but actual request volume concentrates in business hours. Waits for tickets, processes them, waits again.

    • Assumption: 8 hours/day active execution, 16 hours waiting
    • Active hours: 8 × 30 = 240 hours/month
    • Session runtime: 240 × $0.08 = $19.20/month
    • Token costs: depends heavily on ticket volume and average length
    • At 100 tickets/day with moderate length: likely $30–80/month in tokens
    • Realistic total: $50–100/month

    Continuous Autonomous Pipeline

    Batch processing agent that runs continuously through a queue with minimal waiting — the closest to true 24/7 active execution.

    • Assumption: 20 hours/day truly active (4 hours queue exhaustion/maintenance)
    • Active hours: 20 × 30 = 600 hours/month
    • Session runtime: 600 × $0.08 = $48/month
    • Token costs: high — continuous processing means continuous token consumption
    • This is where tokens become the dominant cost driver by a significant margin
    • Realistic total: $200–500+/month (tokens dominate)

    The Real Variable: Token Costs

    For any 24/7 workload that’s genuinely busy, token costs will substantially exceed session runtime costs. The math:

    A moderately active agent processing 10,000 input tokens and 2,000 output tokens per hour with Claude Sonnet 4.6:

    • Input: 10,000 tokens × $3/million = $0.03/hour
    • Output: 2,000 tokens × $15/million = $0.03/hour
    • Token cost: $0.06/hour vs. session runtime of $0.08/hour — roughly equal at this volume

    Scale to 100,000 input tokens and 20,000 output tokens per hour (a busy processing agent):

    • Input: $0.30/hour; Output: $0.30/hour
    • Token cost: $0.60/hour vs. session runtime of $0.08/hour — tokens are 7.5× the runtime charge

    The session runtime fee is flat and bounded. Token costs scale with workload volume. For high-volume 24/7 agents, optimize token efficiency (prompt caching, context management, output brevity) before worrying about the session runtime charge.

    Prompt Caching Changes the Token Math

    If your agent has a large, stable system prompt — common in agents with extensive tool definitions or knowledge bases — prompt caching dramatically reduces input token costs. Cache hits cost a fraction of base input rates. For a 24/7 agent with a 20,000-token system prompt hitting the same context repeatedly, caching that prompt can cut input costs by 80–90%. The session runtime charge is unchanged, but the total cost picture improves significantly.

    The Budget Summary

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The budget summary.
    Agent Type Runtime/mo Typical Total
    Monitoring / low activity ~$3 $5–15
    Support agent (business hours volume) ~$19 $50–100
    Continuous processing pipeline ~$48 $200–500+
    Theoretical maximum (zero idle) $57.60 Unbounded (tokens)

    Complete pricing reference: Claude Managed Agents Pricing Guide. How idle time affects billing: Idle Time and Billing Explained. All questions: FAQ Hub.

    What to do next

    Now that you have the cost math — here’s how to choose and implement

    You now know what Managed Agents costs at scale. The next decision is whether it’s the right architecture vs. OpenAI’s equivalent — and what the implementation actually looks like in practice.

  • Claude Managed Agents vs. OpenAI Agents API — A Direct Comparison

    Claude Managed Agents vs. OpenAI Agents API — A Direct Comparison

    TL;DR — Pick one in 30 seconds

    Choose Claude Managed Agents for zero-infra, fast production deployment. Choose OpenAI Agents API if you need multi-model flexibility or already run on OpenAI infrastructure.

    Feature Claude Managed Agents OpenAI Agents API
    Model lock-inClaude onlyGPT-4o, o3 — OAI only
    Setup complexityZero infra — fully managedSDK — you build the harness
    MemoryBuilt-in (public beta, May 2026)Manual via vector DB
    MultiagentNative (lead + specialists)Swarm/SDK patterns
    Pricing$0.08/session-hr + tokensToken-only (no session fee)
    Best forFast production, Claude-nativeMulti-model, existing OAI infra

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.6 referenced in this article has been superseded. See current model tracker →

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    You’re evaluating hosted agent infrastructure. Both Anthropic and OpenAI have one. Before you commit to either, here’s what’s actually different — not the marketing version, the architectural and pricing version.

    Bottom Line Up Front

    If your stack is Claude-native and you want to get to production fast without building orchestration infrastructure, Managed Agents is hard to beat. If you need multi-model flexibility or have OpenAI deeply embedded in your stack, the calculus changes. Lock-in is real on both sides.

    Still Deciding?

    I’ve run both. Email me your use case and I’ll tell you which one fits.

    No pitch. If Claude isn’t the right call for what you’re building, I’ll tell you that too.

    Email Will → will@tygartmedia.com

    What Each Product Is

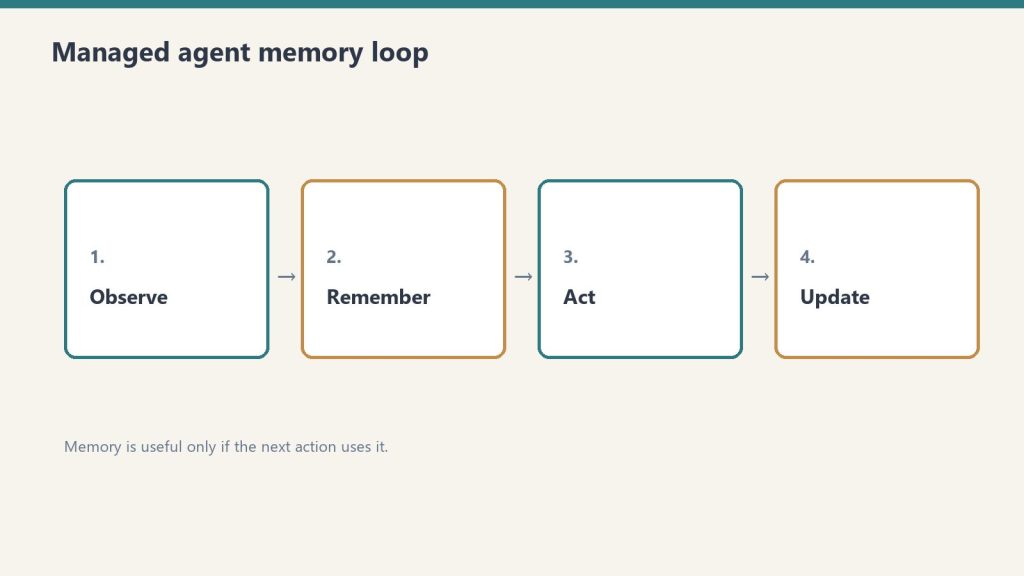
    Four-step loop: observe, remember, act, update for managed agents
    What each agents product is.

    Claude Managed Agents

    Anthropic’s hosted runtime for long-running Claude agent work. You define an agent (model, system prompt, tools, guardrails), configure a cloud environment, and launch sessions. Anthropic handles sandboxing, state management, checkpointing, tool orchestration, and error recovery. Launched April 8, 2026 in public beta.

    OpenAI Agents API

    OpenAI’s hosted agent infrastructure layer, launched earlier in 2026. Provides similar capabilities: hosted execution, tool integration, multi-agent coordination. Supports multiple OpenAI models (GPT-4o, o1, o3, etc.).

    Model Flexibility

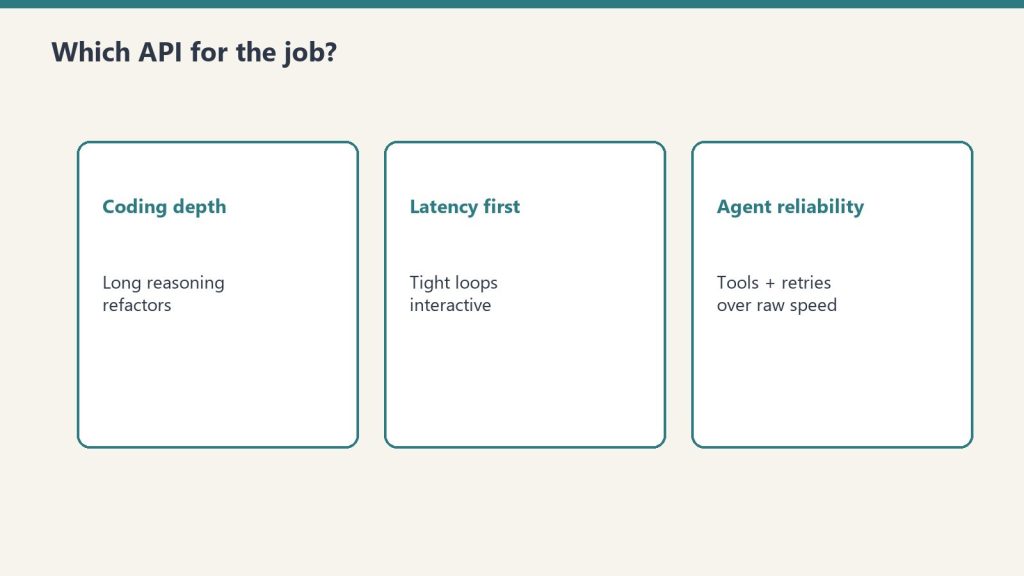
    Three cards: coding depth, latency first, agent reliability
    Model flexibility compared.

    Managed Agents: Claude models only. Sonnet 4.6 and Opus 4.6 are the primary options for agent work. No multi-model mixing within the managed infrastructure.

    OpenAI Agents API: OpenAI models only, but a wider current model lineup (GPT-4o, o1, o3-mini depending on task). Also Claude-only within its own ecosystem — not multi-model in the cross-provider sense.

    The practical implication: If your evaluation is “I want the best model for this specific task regardless of provider,” neither hosted solution gives you that. Both lock you to their provider’s models. The multi-model comparison matters for self-hosted frameworks (LangChain, etc.), not for managed hosted solutions.

    Pricing Structure

    Claude Managed Agents: Standard Claude token rates + $0.08/session-hour of active runtime. Idle time doesn’t bill. Code execution containers included in session runtime — not separately billed.

    OpenAI Agents API: Standard OpenAI token rates + usage-based tooling costs. Pricing structure varies by tool and model tier. Verify current rates at OpenAI’s pricing page — rates have changed multiple times as their agent products have evolved.

    Direct comparison difficulty: Without modeling the same specific workload against both providers’ current rates, headline comparisons mislead. Token rates differ by model, model capabilities differ, and “session runtime” isn’t a category OpenAI uses. Model the workload, not the headline number.

    Infrastructure and Lock-In

    Both solutions create meaningful lock-in. This isn’t a criticism — it’s an honest description of the trade-off you’re making:

    Claude Managed Agents lock-in: Your agents run on Anthropic’s infrastructure with their tools, session format, sandboxing model, and checkpointing. Migrating to OpenAI’s Agents API or self-hosted infrastructure requires rearchitecting session management, tool integrations, and guardrail logic. One developer’s reaction at launch: “Once your agents run on their infra, switching cost goes through the roof.”

    OpenAI Agents API lock-in: Symmetric. Same dynamic in reverse. OpenAI’s session format, tool integration patterns, and infrastructure assumptions create equivalent switching costs to move to Anthropic’s platform.

    The honest framing: You’re not choosing “open” vs. “locked.” You’re choosing which provider’s lock-in you’re more comfortable with, given your existing infrastructure, model preferences, and vendor relationship.

    Data Sovereignty

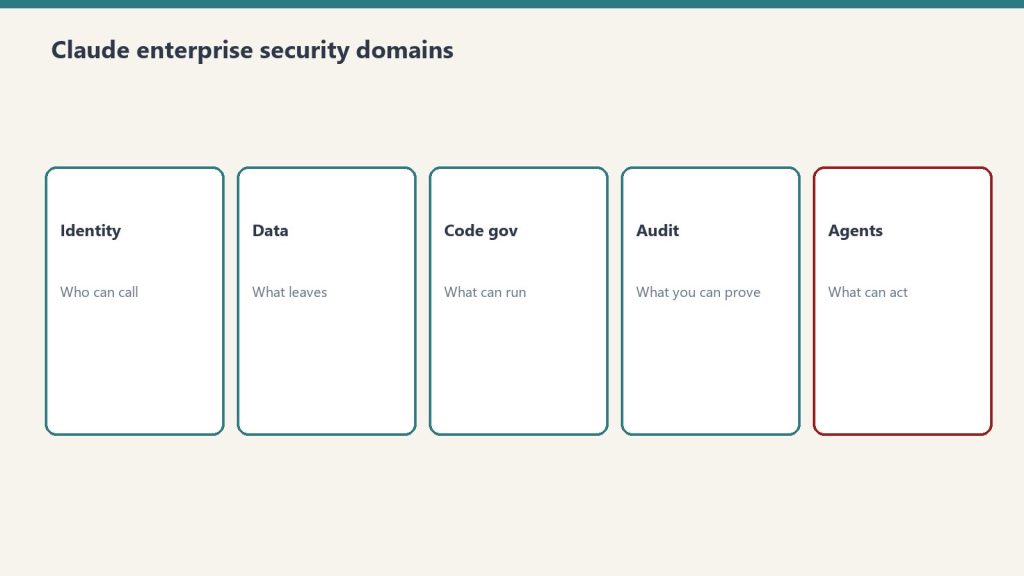
    Five security domains: identity, data, code governance, audit, agents
    Data sovereignty differences.

    Both solutions run your data on provider-managed infrastructure. Neither currently offers native on-premise or multi-cloud deployment for the managed hosted layer. For companies with strict data sovereignty requirements, this is a parallel constraint on both platforms — not a differentiator.

    Production Track Record

    Claude Managed Agents: Launched April 8, 2026. Production users at launch: Notion, Asana, Rakuten (5 agents in one week), Sentry, Vibecode, Allianz. Anthropic’s agent developer segment run-rate exceeds $2.5 billion.

    OpenAI Agents API: Earlier launch gives more time in production, but the product has been revised significantly since initial release. Longer production history, but also more legacy architectural assumptions baked in.

    When to Choose Claude Managed Agents

    • Your stack is already Claude-native (you’re using Sonnet or Opus for most model calls)
    • You want to reach production without building orchestration infrastructure
    • Your tasks are long-running and asynchronous — the session-hour model fits naturally
    • The Notion, Asana, or Sentry integrations are relevant to your workflow
    • You want Anthropic’s specific safety and reliability guarantees

    When to Consider OpenAI’s Agents API Instead

    • Your stack is already heavily OpenAI-integrated (GPT-4o for primary model work, existing tool integrations)
    • You need access to reasoning models (o1, o3) for specific task types — Anthropic’s equivalent is Claude’s extended thinking, which has different characteristics
    • The specific tool integrations in OpenAI’s ecosystem are better matched to your stack
    • You want more production time at scale before committing to a platform

    When to Use Neither (Self-Hosted Frameworks)

    LangChain, LlamaIndex, and similar self-hosted frameworks remain viable — and better — when you genuinely need multi-model flexibility, on-premise execution, or tighter loop control than either hosted solution provides. The trade-off is engineering effort: months of infrastructure work that Managed Agents or OpenAI’s API eliminates.

    Complete pricing breakdown: Claude Managed Agents Pricing Reference. All Managed Agents questions: FAQ Hub. Enterprise deployment example: Rakuten: 5 Agents in One Week.

  • How Claude Managed Agents Handles Idle Time (And Why It Matters for Your Bill)

    How Claude Managed Agents Handles Idle Time (And Why It Matters for Your Bill)

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    The most counterintuitive thing about Claude Managed Agents pricing is what you don’t pay for. Most people, when they hear “$0.08 per session-hour,” mentally model a virtual machine running continuously. That’s the wrong mental model. Here’s the right one, and why it matters for your bill.

    The Core Distinction: Active vs. Idle

    Three stacked layers: chat UI, tools, agent runtime
    The core distinction — active vs idle.

    Managed Agents session runtime only accrues while your session’s status is running. The session can exist — open, initialized, capable of continuing — without accumulating runtime charges when it’s not actively executing.

    The specific states that do not count toward your $0.08/hr charge:

    • Time spent waiting for your next message
    • Time waiting for a tool confirmation
    • Time waiting on an external API response your tool is calling
    • Rescheduling delays
    • Terminated session time

    This is a meaningful architectural decision by Anthropic. They’re billing on what actually taxes their compute — active execution — not on session existence or wall-clock time.

    Why This Is Different From How You Might Expect Billing to Work

    Compare three billing models:

    Virtual machine billing (what this is not): You pay for every hour the instance exists, whether it’s idle or saturated. A VM running 24/7 with 10% actual utilization still costs 24 hours/day.

    Lambda/function billing (closer analogy): AWS Lambda bills on execution duration and invocation count — you pay when code actually runs, not when a function is “available.” Idle Lambda functions cost nothing.

    Managed Agents billing (what this actually is): Closer to Lambda than VM. You pay $0.08 per hour of active execution. A session that runs for 2 hours of wall-clock time but has 90 minutes of waiting costs $0.08 × 1.5 hours = $0.12, not $0.08 × 2 hours = $0.16.

    A Real Scenario: The Human-in-the-Loop Agent

    Diagram comparing a long context window bar with a shorter output limit bar
    A real scenario — the human-in-the-loop agent.

    Consider an agent that processes your inbox for action items and waits for your approval before sending replies. Wall-clock time: 4 hours open during your workday. Actual active execution: 20 minutes of processing across that 4-hour window, with the rest spent waiting for your review decisions.

    • VM billing equivalent: 4 hours × rate = significant charge
    • Managed Agents billing: 20 minutes × $0.08/hr = $0.027

    The difference is real. For interaction-heavy agents where the agent frequently waits for human decisions, the idle-time exclusion significantly reduces costs versus a naive per-hour model.

    A Real Scenario: The Autonomous Batch Agent

    Now consider an agent running a fully autonomous content pipeline — no human checkpoints, just continuous execution through a queue. Wall-clock time and active execution time are nearly identical because the agent never waits.

    • A 2-hour autonomous batch: 2 hours × $0.08 = $0.16

    Here, the idle-time model provides no benefit — the agent has no idle time. The billing is effectively equivalent to per-hour pricing because execution is continuous.

    Code Execution Containers Are Included

    One more billing nuance worth knowing: when your agent runs code, the execution happens in sandboxed Linux containers. These containers are not separately billed on top of session runtime. The $0.08/hr covers both the session runtime and the container execution. This is explicitly documented by Anthropic and represents meaningful savings if your agent is doing significant code execution work — you’re not paying twice.

    What This Means for Workload Design

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What this means for workload design.

    If you’re designing agent workflows and have the choice between architectures, the billing model creates a useful signal:

    • Agents that wait on humans: Metered billing is favorable — you only pay for the actual reasoning and execution time, not the human decision time
    • Fully autonomous agents: Billing approaches equivalent to per-hour rates — optimize these on token efficiency, not idle reduction
    • Scheduled batch agents: Natural fit — run when needed, terminate when done, no idle accumulation

    The 24/7 Agent Math

    For anyone doing the 24/7 always-on calculation: the maximum theoretical runtime exposure is 24 hrs × $0.08 × 30 days = $57.60/month in session fees. But a 24/7 agent with zero idle time is rare in practice. Agents that sleep between triggers, wait on external data, or hold for human decisions have meaningful idle windows that reduce the actual charge below the theoretical ceiling.

    Full monthly cost analysis: The Real Monthly Cost of Running Claude Managed Agents 24/7. Pricing reference: Complete Pricing Guide. All questions: FAQ Hub.

    Related on Tygart Media: rate limits · managed agents review · Claude pricing.

  • Claude Managed Agents Rate Limits — What 60 Requests Per Minute Means in Practice

    Claude Managed Agents Rate Limits — What 60 Requests Per Minute Means in Practice

    The Lab · Tygart Media
    Experiment Nº 561 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    You’re planning to run Claude Managed Agents at scale. You’ve modeled the token costs, the session-hour charge, the workload cadence. Then you hit the actual constraint: rate limits. Here’s what 60 requests per minute actually means in practice, and whether it’s going to be your ceiling.

    The Two Limits You Need to Know

    Three stacked layers: chat UI, tools, agent runtime
    The two limits you need to know.

    Managed Agents has two endpoint-specific rate limits, separate from your standard Claude API limits:

    • Create endpoints: 60 requests per minute
    • Read endpoints: 600 requests per minute

    Your organization-level API limits apply on top of these. If your org is on a tier with a lower requests-per-minute ceiling, that’s the actual binding constraint.

    What “60 Create Requests Per Minute” Actually Means

    A create request, in Managed Agents context, is typically a session creation call — starting a new agent session. 60/minute means you can start 60 sessions per minute maximum. For almost all real workloads, this is not the binding constraint. Here’s why:

    Think about what generates create requests. If you’re running a batch pipeline that starts one new agent session per content item, processing 60 items per minute would saturate the limit. But a 60-item-per-minute content pipeline is running 3,600 items per hour — a genuinely high-volume operation. Most production agent workloads don’t look like this. They look like one session that runs for minutes or hours, processes multiple tasks within that session, and terminates when done.

    The create limit matters most for architectures where you’re spinning up a new session per task rather than running tasks within a persistent session. If that’s your pattern, 60/minute is a hard ceiling you’ll need to design around.

    What “600 Read Requests Per Minute” Actually Means

    Read requests include polling session status, reading agent output, checking checkpoints, and retrieving session state. 600/minute is a relatively generous limit — that’s 10 reads per second. For a monitoring dashboard polling 10 active sessions every second, you’d hit this. For most production monitoring patterns (checking status every 5-30 seconds per session), you’re well under the ceiling.

    The read limit becomes relevant in high-concurrency architectures where many sessions are running in parallel and all being polled aggressively. If you’re running 50 concurrent agents and checking each one every 2 seconds, that’s 25 reads/second — still within the 10 reads/second limit per second, but compressing toward it.

    The Limit That’s More Likely to Actually Stop You

    For most agent workloads, token throughput limits hit before request rate limits do. The reasoning: a long-running agent session processing significant context generates a lot of tokens. If you’re running many such sessions in parallel, you’ll hit your organization’s token-per-minute limit before you hit 60 sessions created per minute.

    Token limits depend on your API tier. Higher tiers have higher token throughput limits. Rate limit increases and custom limits for high-volume enterprise customers are negotiated with Anthropic’s sales team.

    Designing Around the 60 Create Limit

    Diagram comparing a long context window bar with a shorter output limit bar
    Designing around the 60 create limit.

    If your architecture genuinely needs more than 60 new sessions per minute, the primary design pattern is batching more work within each session rather than creating more sessions. A single Managed Agents session can handle sequential tasks — you don’t need a new session per task if your tasks can be queued and processed within one session’s lifecycle.

    The tradeoff: longer-running sessions accumulate more runtime charge ($0.08/hr active). For most workloads, the efficiency gains from batching outweigh the marginal runtime cost.

    The Agent Teams Implication

    Agent Teams — Managed Agents’ multi-agent coordination feature — coordinate multiple Claude instances with independent contexts. Each instance in an Agent Team is a separate entity from a context standpoint. How Agent Team member sessions count against the create rate limit is worth verifying against current documentation if you’re architecting a high-concurrency Agent Teams deployment.

    For Enterprise Workloads

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    For enterprise workloads.

    If you’re evaluating Managed Agents for enterprise-scale deployment and the published limits don’t fit your volume requirements, contact Anthropic’s enterprise sales team. Rate limit increases for high-volume applications are a documented option — they’re negotiated, not self-serve.

    Contact: [email protected] or through the Claude Console.

    Related on Tygart Media: idle-time billing · managed agents review · Claude pricing.

    Frequently Asked Questions

    Does the 60 requests/minute limit apply to all API calls or just session creation?

    The 60/minute limit applies to create endpoints — session creation being the primary one. Read operations have a separate 600/minute limit. Standard Messages API calls are governed by your organization’s standard tier limits, not these Managed Agents-specific limits.

    Do subagents count against the create rate limit separately from the parent session?

    Subagents operate within the parent session’s context and report results upward — they’re architecturally different from new sessions. Verify current documentation for precise billing treatment of subagent creation calls vs. Agent Team session creation.

    What happens when I hit the rate limit?

    Standard API rate limit behavior applies — requests over the limit receive a 429 response. Implement exponential backoff in your session creation logic for any high-volume pattern that approaches the 60/minute ceiling.

    How does this compare to OpenAI’s Agents API limits?

    Rate limit structures differ by product and tier. Direct comparison requires checking both providers’ current documentation for your specific tier. The full comparison: Claude Managed Agents vs. OpenAI Agents API.

    Full pricing context including rate limits: Claude Managed Agents Complete Pricing Reference. All questions: Claude Managed Agents FAQ.

  • What Notion’s Claude Managed Agents Integration Actually Does

    What Notion’s Claude Managed Agents Integration Actually Does

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    When Anthropic launched Claude Managed Agents, Notion was one of four launch partners. That detail got buried in the announcement. Here’s what it actually means for people who use Notion for knowledge work, and why “Notion voice input desktop” keeps showing up as a query against a Managed Agents page.

    Short answer: Managed Agents in Notion is an ambient intelligence layer. It’s not a chatbot in a sidebar. It’s an agent that watches your workspace and acts — without you directing every step.

    What the Notion Integration Actually Does

    Four cards for content, ops, build, and knowledge work with Claude
    What the Notion integration actually does.

    Notion’s Claude Managed Agents integration runs as a persistent background agent with access to your workspace. The practical capabilities, as documented at launch:

    • Autonomous page updates: The agent can read, summarize, and rewrite Notion pages without manual triggers. You set a task; it works through it.
    • Cross-database synthesis: Pull data from multiple Notion databases, synthesize it, and write outputs to a target page or database entry
    • Meeting note processing: Ingest raw meeting notes and produce structured summaries, action items, and task entries in your project database
    • Workflow automation: Trigger actions based on database property changes — a status update in one database can kick off agent work in another

    The key difference from Notion AI (which Notion has had for some time): Notion AI is request-response. You ask it something; it answers. Managed Agents in Notion can be configured to run autonomously on a schedule or on trigger, keep working through multi-step tasks, and report back when done. It’s closer to a background employee than an on-demand assistant.

    Why This Showed Up in Search as “Notion Voice Input Desktop”

    This is worth explaining, because that query cluster is real and mildly interesting. The Managed Agents announcement included voice input functionality — the ability to interact with agents via voice in some contexts. People searching “notion voice input desktop” and “notion ai voice input desktop” were looking for whether this voice capability existed in the desktop client for Notion specifically.

    The honest answer as of April 2026: voice input capabilities are in preview or context-dependent. Verify current availability in Notion’s desktop client against their current documentation — this is an area that may have evolved since launch.

    The “Decoupled Brain and Hands” Model Applied to Notion

    Anthropic describes their Managed Agents architecture as decoupling the brain (Claude, the reasoning layer) from the hands (the sandboxed containers where actions execute). In Notion’s context, this maps cleanly:

    • The brain reads your Notion workspace, understands context, makes decisions about what to do
    • The hands execute — writing to pages, updating database entries, moving content between sections

    The brain and hands operate independently. The agent can reason about what your project needs without being tightly coupled to the specific API calls that will implement it. This matters because it means the agent can handle ambiguity — “clean up the Q2 notes and create action items” is a goal, not a procedure, and the agent figures out the procedure.

    What You Actually Configure

    Three stacked layers: chat UI, tools, agent runtime
    What you actually configure.

    To run Claude Managed Agents in Notion, you’re defining:

    • Task definition: What the agent is supposed to accomplish (in natural language or structured format)
    • Tool access: Which Notion databases, pages, and capabilities the agent can read and write
    • Guardrails: What the agent cannot do — pages it can’t modify, actions it must confirm before taking
    • Trigger: When the agent runs — on schedule, on database trigger, or on demand

    You don’t write the orchestration logic. Anthropic’s infrastructure handles session management, state persistence, and error recovery. If the agent hits an error mid-task, it checkpoints and recovers — you don’t lose progress.

    The Practical Cost of Running Notion Agents

    Using Managed Agents in Notion triggers the same billing as any Managed Agents session: standard token rates plus $0.08/session-hour of active runtime. For typical knowledge work tasks:

    • A daily meeting summary agent running 15 minutes of active execution: ~$0.02/day in runtime (~$0.60/month), plus token costs for the volume of notes processed
    • A weekly database synthesis task running 45 minutes: ~$0.06/run

    For most knowledge workers, the session runtime cost is negligible — the token costs (driven by how much content the agent reads and writes) are the actual variable to model. See the complete pricing reference for worked examples.

    Asana and the Broader Pattern

    Asana was also a Managed Agents launch partner, and the integration pattern is similar: an agent that can read project data, update task statuses, move cards, and generate project summaries without constant human direction. The launch partner list (Notion, Asana, Rakuten, Sentry) suggests Anthropic targeted three categories: knowledge management (Notion), project management (Asana), enterprise operations (Rakuten), and developer tools (Sentry).

    That’s a deliberate wedge. If agents can handle the administrative layer of these four categories, the surface area for autonomous business work expands significantly.

    What This Means for How You Work

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What this means for how you work.

    The honest use case for most people reading this: you have a Notion workspace with databases that need regular synthesis, and you’re currently doing that manually. Managed Agents is the path to automating that synthesis without building and maintaining a custom integration.

    The constraint worth naming: you’re running your workspace data through Anthropic’s infrastructure. That’s the trade-off. For most knowledge work, the data sensitivity concern is low. For anything involving client data, legal documents, or proprietary strategy — read Anthropic’s data handling terms before configuring access.

    For the full Managed Agents setup and pricing context: Claude Managed Agents: Every Question Answered. For the enterprise deployment pattern: How Rakuten Deployed 5 Enterprise Agents in a Week.

    Related on Tygart Media: managed agents review · Notion Command Center · managed agents memory use cases.

  • Claude Managed Agents — Every Question Answered (Complete FAQ 2026)

    Claude Managed Agents — Every Question Answered (Complete FAQ 2026)

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    Everything people actually ask about Claude Managed Agents, answered straight. No preamble about “the exciting world of AI agents.” If you’re here, you already know why this matters — you just need answers.

    This page covers pricing, setup, capabilities, limits, comparisons, and the specific questions that don’t have obvious homes in Anthropic’s documentation. It updates as the beta evolves.

    Context

    Claude Managed Agents launched April 8, 2026 as a public beta. All answers reflect current documentation as of April 2026. Beta details change — verify specifics at platform.claude.com/docs.

    Pricing Questions

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Pricing questions — stale-proof framing.

    What does Claude Managed Agents cost?

    Two charges: standard Claude API token rates (same as calling the Messages API directly) plus $0.08 per session-hour of active runtime. That’s the complete formula. See the complete pricing reference for worked examples by workload type.

    What exactly is a “session-hour” and when does it start billing?

    A session-hour is one hour of active session runtime — time when your session’s status is running. Billing is metered to the millisecond. It does not accrue during idle time, time waiting for your input, time waiting for tool confirmations, or after session termination.

    What’s included in the $0.08/session-hour charge?

    The session runtime charge covers Anthropic’s managed infrastructure: sandboxed code execution containers, state management, checkpointing, tool orchestration, error recovery, and scaling. You are not separately billed for container hours on top of session runtime.

    Does the $0.08/hr apply even if my agent is just waiting?

    No. Time spent waiting for your message, waiting for tool confirmations, or sitting idle does not accumulate runtime charges. Only active execution time counts.

    What does web search cost inside a Managed Agents session?

    $10 per 1,000 searches ($0.01 per search), billed separately from session runtime and token costs. This is the same rate as web search through the standard API.

    Are there volume discounts?

    Yes, negotiated case-by-case for high-volume users. Contact [email protected] or through the Claude Console.

    How does Managed Agents pricing compare to running my own agent infrastructure?

    The $0.08/session-hour is almost always cheaper than equivalent provisioned compute — but you trade infrastructure control and data locality for that simplicity. For a full comparison: Build vs. Buy: The Real Infrastructure Cost.

    What’s the real monthly cost if I run an agent 24/7?

    Maximum theoretical session runtime: 24 hrs × $0.08 × 30 days = $57.60/month. In practice, no production agent has zero idle time. Token costs become the dominant cost driver long before you hit the runtime ceiling. Detailed breakdown: The Real Monthly Cost of Running Claude Managed Agents 24/7.

    Setup and Access Questions

    Four-step loop: observe, remember, act, update for managed agents
    Setup and access questions.

    How do I get access to Claude Managed Agents?

    Available to all Anthropic API accounts in public beta — no separate signup. You need the managed-agents-2026-04-01 beta header in your API requests. The Claude SDK adds this header automatically.

    Does it work with my existing API key?

    Yes. Same API key you’re already using for the Messages API. Same authentication. The beta header is the only new requirement.

    What three ways can I access Managed Agents?

    Via the Claude SDK (recommended — handles the beta header automatically), via direct API calls with the beta header, or via the Claude Console’s new Managed Agents section for no-code agent configuration and session tracing.

    Can I use Managed Agents through AWS Bedrock or Google Vertex AI?

    Managed Agents runs on Anthropic-managed infrastructure. This is distinct from Bedrock and Vertex AI deployments. Check Anthropic’s current documentation for multi-cloud availability status — this is an area of active development.

    Capability Questions

    What can Claude Managed Agents actually do?

    Run long autonomous sessions with persistent state, execute code in sandboxed Linux containers, use tools including web search and MCP servers, coordinate multiple Claude instances via Agent Teams, and maintain checkpoints for crash recovery. The session can last minutes or hours without you staying in the loop.

    What’s the difference between Agent Teams and subagents?

    Agent Teams coordinate multiple Claude instances with independent contexts, direct agent-to-agent communication, and a shared task list — suited for complex parallel tasks. Subagents operate within the same session as the main agent and only report results upward — more economical for sequential targeted tasks but less capable of true parallelism.

    Does it support MCP servers?

    Yes. MCP servers can be integrated as tool sources in Managed Agents sessions, extending what the agent can access and act on.

    How long can a session run?

    Anthropic’s documentation currently references session durations of minutes to hours. Claude Code’s longest autonomous sessions have reached 45 minutes. Managed Agents is architected for longer-running work. Check current documentation for specific session duration limits as the beta matures.

    What happened to Claude Code — is it the same as Managed Agents?

    No. Claude Code is a separate local coding workflow product. Anthropic’s docs explicitly note partners should not conflate the two. Managed Agents is a hosted API runtime service. Claude Code is a developer tool. Different products, different use cases, different billing.

    Rate Limit Questions

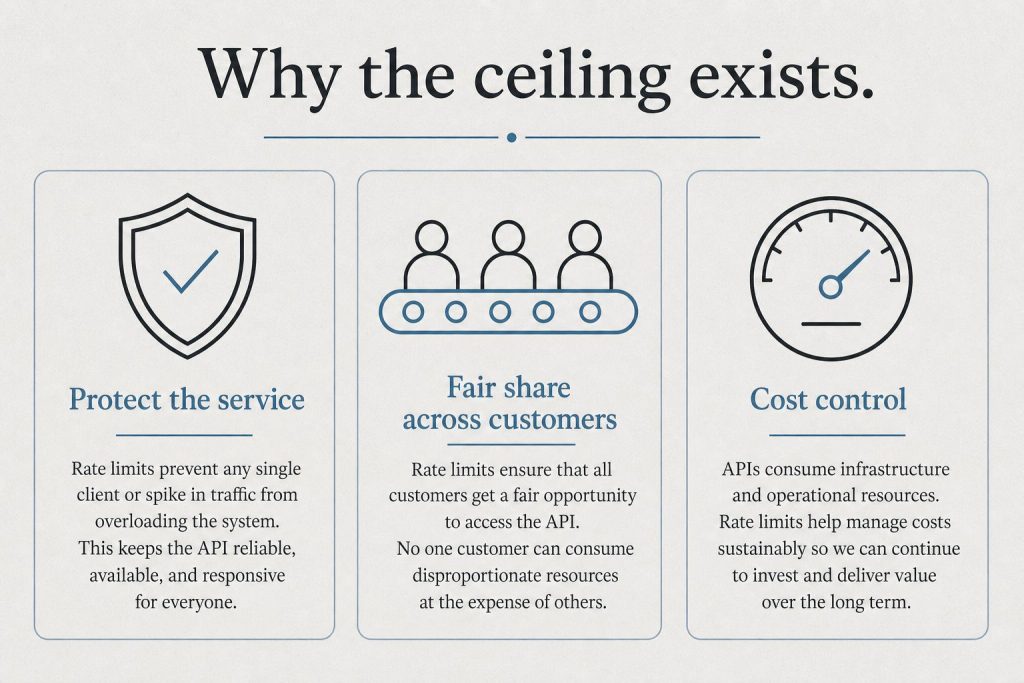
    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits
    Rate limit questions.

    What are the rate limits for Managed Agents?

    60 requests per minute for create endpoints; 600 requests per minute for read endpoints. Organization-level API limits still apply on top of these. For higher limits, contact Anthropic enterprise sales. Detailed breakdown: Claude Managed Agents Rate Limits Explained.

    Do standard Claude API rate limits still apply inside a session?

    Organization-level limits apply. The session runtime and create/read endpoint limits are Managed Agents-specific. If you’re running many parallel Agent Teams, model token throughput limits will become relevant.

    Comparison Questions

    How does Managed Agents compare to OpenAI’s Agents API?

    Both offer hosted agent infrastructure. Key differences: Managed Agents is Claude-native (no multi-model flexibility), sessions bill on runtime + tokens vs. OpenAI’s different pricing model, and lock-in dynamics differ. Full comparison: Claude Managed Agents vs. OpenAI Agents API.

    Should I use Managed Agents or the Claude Agent SDK?

    Use Managed Agents when you want Anthropic to host the runtime — less infrastructure work, faster to production. Use the SDK when you need tighter loop control, on-premise execution, or multi-cloud flexibility. Anthropic’s own migration docs draw this line clearly: SDK runs in your environment; Managed Agents runs in theirs.

    What companies are already using Managed Agents in production?

    Notion, Asana, Rakuten, Sentry, and Vibecode were launch partners. Rakuten deployed five enterprise agents within a week. Allianz is using Claude for insurance agent workflows. Anthropic’s run-rate from the agent developer segment exceeds $2.5 billion. How Rakuten did it in a week →

    Data and Security Questions

    Where does my data go when running in Managed Agents?

    Execution runs on Anthropic’s infrastructure. This is the explicit trade-off: you get managed infrastructure; they manage the compute. For companies with strict data sovereignty requirements, this is the key constraint to evaluate. On-premise or native multi-cloud deployment is not currently available.

    What are the sandboxing guarantees?

    Anthropic uses disposable Linux containers — “decoupled hands” in their terminology. Each container is a fresh sandboxed environment for code execution. State persistence is managed separately from the execution environment.

    Strategic Questions

    Is this a bet worth making?

    That depends on your switching cost tolerance. Lock-in is real: once your agents run on Anthropic’s infrastructure with their tools, session format, and sandboxing, switching providers isn’t trivial. The counter-argument: the infrastructure you’d otherwise build to match this is months of engineering. One developer’s reaction at launch was blunt: “there goes a whole YC batch.” That captures both the opportunity and the risk. Our take on why we’re staying our course →

    What does this mean for AI citation and visibility?

    Agents running on Anthropic’s infrastructure make decisions about what content to surface, cite, and synthesize. As agent workloads grow, being present in the knowledge sources agents draw from becomes a search strategy question in itself. What AI citation monitoring looks like →

  • Claude Managed Agents — Complete Pricing Reference + Dreaming Update (May 2026)

    Claude Managed Agents — Complete Pricing Reference + Dreaming Update (May 2026)

    Last refreshed: May 15, 2026

    May 2026 Update — Dreaming Feature + Beta Status

    Anthropic introduced Dreaming at Code w/ Claude (May 6, 2026) — a new Managed Agents capability where agents review their own session history overnight to improve future performance. Harvey (legal AI) reported a roughly 6× task completion rate increase after implementing it. Dreaming is developer-access preview only. Multiagent Orchestration and Outcomes are now in public beta. See the new Dreaming section below.

    What Is Claude Managed Agents? (Current Status, May 2026)

    Four-step loop: observe, remember, act, update for managed agents
    What Claude Managed Agents is right now.

    Claude Managed Agents is Anthropic’s framework for long-running, stateful AI agents — agents that can maintain context across sessions, hand off between sub-agents, and now, improve themselves by reviewing their own work history. Here’s the current status of each component:

    Component Status Who Has Access
    Multiagent Orchestration Public Beta All API developers
    Outcomes Public Beta All API developers
    Dreaming Developer Preview Selected developers only

    Dreaming: The Feature the Press Mostly Missed

    Three stacked layers: chat UI, tools, agent runtime
    Dreaming — the feature the press mostly missed.

    Announced at Code w/ Claude on May 6, 2026, Dreaming is a Managed Agents capability that lets agents review and reorganize their own memory between sessions. The mechanism:

    1. After a session ends, the agent reads its existing memory store alongside the session transcripts
    2. It produces a new, reorganized memory store: duplicates merged, stale entries replaced, new patterns surfaced
    3. The next session starts with a higher-quality knowledge base — capturing insights no single session could hold

    This is meaningfully different from simply persisting conversation history. The agent isn’t just remembering what happened — it’s synthesizing what it learned. Think of it as the difference between taking notes and actually reviewing and reorganizing your notes the next morning.

    The Harvey Result

    Harvey, the legal AI company, reported approximately a 6× task completion rate increase after implementing Dreaming in their Managed Agents workflow. Harvey’s use case — complex legal research that spans multiple sessions with evolving context — is exactly the kind of work Dreaming was designed for. Sessions build on each other rather than starting fresh each time.

    Dreaming is developer-access preview as of May 2026. Docs: platform.claude.com/docs/en/managed-agents/dreams.

    What Dreaming Is Not

    A few clarifications worth making explicit:

    • Dreaming is not available to end users — it’s a developer-layer capability requiring implementation
    • It’s not persistent memory in the claude.ai chat interface
    • It’s not available to free or standard Pro subscribers through any interface
    • It’s a developer preview, not GA — expect it to evolve before full release

    Our Take: Why This Architecture Matters

    We run Managed Agents in our own Cowork workflows. The Dreaming announcement is the first time Anthropic has shipped something that resembles how expert human knowledge actually compounds over time — not by accumulating raw notes, but by periodically synthesizing and reorganizing what’s been learned into a cleaner structure.

    The Harvey 6× result is a real-world data point from a production legal AI workflow. That’s not a benchmark number — it’s a deployed system showing measurable improvement from session-to-session memory refinement. Whether that 6× figure holds across different use cases is unknown, but the direction of the effect is the signal: agents that learn from their own history outperform agents that don’t.

    For non-developer users watching this space: Dreaming is the preview of what agentic AI will look like when it becomes mainstream. The groundwork being laid now in developer preview will eventually surface in subscription-tier products.

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    You opened this tab because you need a number you can actually use. Not a vibe, not “it depends.” A real pricing breakdown you can put in a spreadsheet, a budget request, or a Slack message to your CTO.

    This is that page. Every pricing variable for Claude Managed Agents in one place, verified against Anthropic’s current documentation as of April 2026. Bookmark it. The beta will update; so will this.

    Quick Reference: The Formula

    Total Cost = Token Costs + Session Runtime ($0.08/hr) + Optional Tools
    Session runtime only accrues while status = running. Idle time is free.

    The Two Cost Dimensions

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Two cost dimensions — stale-proof framing.

    Claude Managed Agents bills on exactly two dimensions: tokens and session runtime. Every pricing question you have collapses into one of these two buckets.

    Dimension 1: Token Costs

    These are identical to standard Claude API pricing. You pay the same rates you’d pay calling the Messages API directly. No Managed Agents markup on tokens. Current rates for the models most commonly used in agent work:

    • Claude Sonnet 4.6: ~$3/million input tokens, ~$15/million output tokens
    • Claude Opus 4.7: higher rates apply — check platform.claude.com/docs/en/about-claude/pricing for current figures
    • Prompt caching: same multipliers as standard API — cache hits dramatically reduce input token costs on long sessions with stable system prompts

    The implication: a token-heavy agent with a large system prompt that runs the same context repeatedly benefits significantly from prompt caching, and that benefit carries over unchanged into Managed Agents.

    Dimension 2: Session Runtime — $0.08/Session-Hour

    This is the Managed Agents-specific charge. You pay $0.08 per hour of active session runtime, metered to the millisecond.

    The critical word is active. Runtime only accrues while your session’s status is running. The following do not count toward your bill:

    • Time spent waiting for your next message
    • Time waiting for a tool confirmation
    • Idle time between tasks
    • Rescheduling delays
    • Terminated session time

    This is not how you’d bill a virtual machine. It’s closer to how AWS Lambda bills — you pay for execution, not reservation. An agent that “runs” for 8 hours but spends 6 of those hours waiting on human input has a very different bill than one running continuous autonomous loops.

    Optional Tool Costs

    Web Search: $10 per 1,000 Searches

    If your agent uses web search, each search costs $10/1,000 — that’s $0.01 per search. For most agents, this is negligible. For a research agent running hundreds of searches per session, it becomes a line item worth modeling separately.

    Code Execution: Included in Session Runtime

    Code execution containers are included in your $0.08/session-hour charge. You’re not separately billed for container hours on top of session runtime. This is explicitly stated in Anthropic’s docs and represents meaningful savings versus provisioning your own compute.

    Worked Cost Examples

    Example 1: Daily Research Agent

    Runs once per day. 30 minutes of active execution. Processes 10 documents, outputs a summary report. Moderate token volume.

    • Session runtime: 0.5 hrs × $0.08 = $0.04/day (~$1.20/month)
    • Tokens (estimate): 50K input + 5K output with Sonnet 4.6 = ~$0.23/run (~$7/month)
    • Total: ~$8–10/month

    Example 2: Weekly Batch Content Pipeline

    Runs 3x/week. 2-hour active sessions. Processes multiple documents, generates structured outputs.

    • Session runtime: 2 hrs × $0.08 × 12 sessions/month = $1.92/month
    • Tokens: depends on content volume — typically $10–40/month
    • Total: ~$12–42/month

    Example 3: Customer Support Agent (Business Hours)

    Active during business hours, handling tickets. 8 hours/day active, 5 days/week.

    • Session runtime: 8 hrs × $0.08 × 22 days = $14.08/month in runtime
    • Tokens: highly variable by ticket volume — the dominant cost driver at scale
    • Runtime cost alone: ~$14/month — tokens are likely 5–20x this depending on volume

    Example 4: 24/7 Always-On Agent

    The maximum theoretical runtime exposure. Continuous operation, no idle time.

    • Session runtime: 24 hrs × $0.08 × 30 days = $57.60/month
    • In practice, no agent has zero idle time — real cost will be lower
    • Token costs at this scale become the dominant factor by a wide margin

    Anthropic’s Official Example (from their docs)

    A one-hour coding session using Claude Opus 4.7 consuming 50,000 input tokens and 15,000 output tokens: session runtime = $0.08. With prompt caching active and 40,000 of those tokens as cache reads, the token costs drop significantly. The runtime charge stays flat at $0.08 regardless of caching.

    What’s Not Billed in Managed Agents

    A few things that might seem like costs but aren’t:

    • Infrastructure provisioning: Anthropic handles hosting, scaling, and monitoring at no additional charge
    • Container hours: Explicitly not separately billed on top of session runtime
    • State management and checkpointing: Included in the session runtime charge
    • Error recovery and retry logic: Anthropic’s infrastructure problem, not yours

    Rate Limits

    Managed Agents has specific rate limits separate from standard API limits:

    • Create endpoints: 60 requests/minute
    • Read endpoints: 600 requests/minute
    • Organization-level limits still apply
    • For higher limits, contact Anthropic enterprise sales

    How to Access Managed Agents Pricing

    Managed Agents is available to all Anthropic API accounts in public beta. No separate signup, no premium tier gate. You need the managed-agents-2026-04-01 beta header in your API requests — the Claude SDK adds this automatically.

    For high-volume agent applications, Anthropic’s enterprise sales team negotiates custom pricing arrangements. Contact them at [email protected] or through the Claude Console.

    The Pricing Signals Worth Noting

    Anthropic recently ended Claude subscription access (Pro/Max) for third-party agent frameworks, requiring those users to switch to pay-as-you-go API pricing. This signals a deliberate strategy: consumer subscriptions are for human-paced interactions; agent workloads route through the API. The $0.08/session-hour rate exists in that context — it’s infrastructure pricing for compute that runs beyond human attention spans.

    The session-hour model also signals something about Anthropic’s infrastructure cost structure. They’re pricing on active execution time because that’s what actually taxes their systems. Idle sessions don’t cost them much; active agents do. The billing model follows the actual resource consumption pattern.

    Frequently Asked Questions

    Is the $0.08/session-hour charge in addition to token costs, or does it replace them?

    In addition to. You pay both: standard token rates for all input and output tokens, plus $0.08 per hour of active session runtime. They’re separate line items.

    Does prompt caching work in Managed Agents sessions?

    Yes. Prompt caching multipliers apply identically to Managed Agents sessions as they do to standard API calls. If your agent has a large, stable system prompt, caching it can significantly reduce input token costs.

    What happens if my session crashes? Am I billed for the crashed time?

    Runtime accrues only while status is running. Terminated sessions stop accruing. Anthropic’s infrastructure handles checkpointing and crash recovery — the session state is preserved even if the session terminates unexpectedly.

    Can I use Managed Agents on the free API tier?

    Managed Agents is available to all Anthropic API accounts in public beta, but standard tier access and rate limits apply. Free API tier users receive a small credit for testing.

    How does this compare to running agents on my own infrastructure?

    See our full breakdown: Build vs. Buy: The Real Infrastructure Cost of Claude Managed Agents. Short version: the $0.08/hour is almost certainly cheaper than provisioning and maintaining equivalent compute, but you trade control and data locality for that simplicity.

    Are there volume discounts?

    Volume discounts are available for high-volume users but negotiated case-by-case. Contact Anthropic enterprise sales.

    Does web search billing count against the $10/1,000 rate if the search returns no results?

    Anthropic’s current docs don’t explicitly address failed searches. Treat any triggered search as billable until confirmed otherwise.

    For the full session-hour math worked out by workload type, see: Claude Managed Agents Pricing, Decoded: What a Session-Hour Actually Costs You. For the build-vs-buy infrastructure comparison: Build vs. Buy: The Real Infrastructure Cost. For enterprise deployment patterns: Rakuten Stood Up 5 Enterprise Agents in a Week.

  • AI Citation Monitoring: The Complete 2026 Guide to Tracking ChatGPT, Claude & Perplexity Mentions

    AI Citation Monitoring: The Complete 2026 Guide to Tracking ChatGPT, Claude & Perplexity Mentions

    Tygart Media // AEO & AI Search
    SCANNING
    CH 03 · Answer Engine Intelligence · Filed by Will Tygart

    What is AI citation monitoring? AI citation monitoring is the practice of systematically tracking whether generative AI systems — including ChatGPT, Claude, Perplexity, Google AI Overviews, and similar tools — are citing, referencing, or recommending your content when users ask relevant questions. It’s the GEO equivalent of rank tracking: instead of asking “where do I rank on Google?”, you’re asking “does AI think I’m worth mentioning?”

    Here’s a scenario that’s playing out right now across thousands of websites: a business owner spends months creating genuinely excellent content. It ranks well. People find it. The traffic dashboards look good. And then, quietly, something changes. Fewer people are clicking through from Google. The traffic dips but the rankings haven’t moved. What happened?

    AI happened. Specifically: AI search features are now answering questions directly — and the content they choose to summarize, reference, or cite is not necessarily the content that ranks #1. It’s the content that AI systems have determined is trustworthy, factual, well-structured, and authoritative. Whether that’s you depends on whether you’ve been paying attention.

    AI citation monitoring is how you pay attention.

    Why AI Citations Are a New Category of Search Visibility

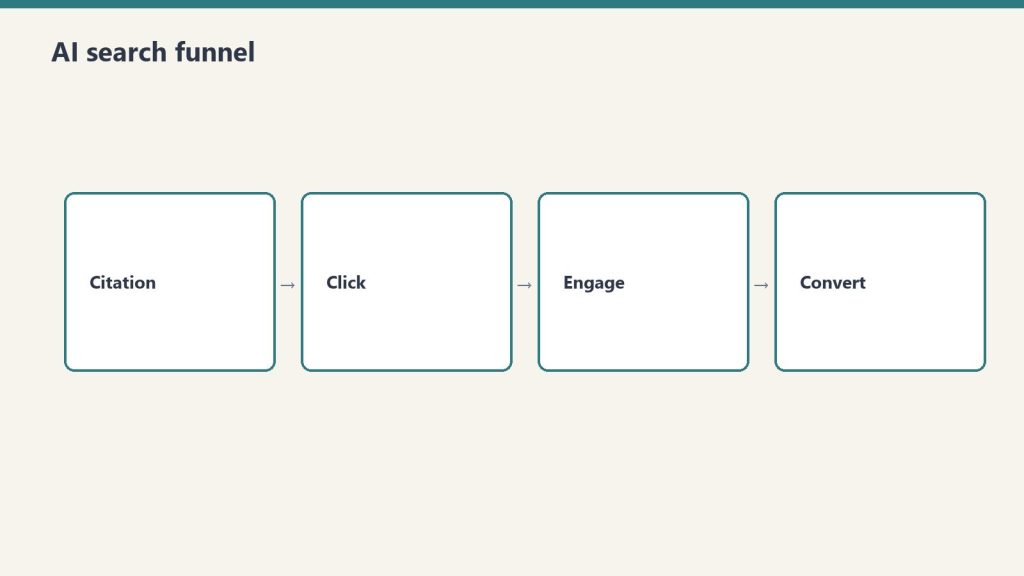
    Four-stage funnel: citation, click, engage, convert
    Why AI citations are a new category of search visibility.

    Traditional SEO gave us a clean, rankable world. Query goes in, ten blue links come out, you live or die by position one through ten. The metrics were unambiguous. Either you’re visible or you’re not.

    AI search doesn’t work that way. When someone asks ChatGPT a question, they don’t get ten links — they get an answer. That answer might cite your content, paraphrase it without attribution, or ignore it entirely in favor of a competitor whose content happened to be better structured for machine consumption. There’s no “position 1” equivalent. There’s cited, mentioned, or absent.

    This creates a new visibility dimension that most businesses aren’t tracking at all. They’re optimizing for Google’s traditional index while AI systems quietly form opinions about whose content is worth recommending — and those opinions are influencing a growing share of how people discover information.

    According to data from Semrush and BrightEdge, AI Overviews now appear in roughly 13-15% of all Google searches in the US as of early 2026 — disproportionately for informational queries, which are exactly the queries that content marketing is designed to capture. If your content isn’t getting cited in those overviews, you’re invisible to a significant portion of your potential audience.

    What AI Citation Monitoring Actually Involves

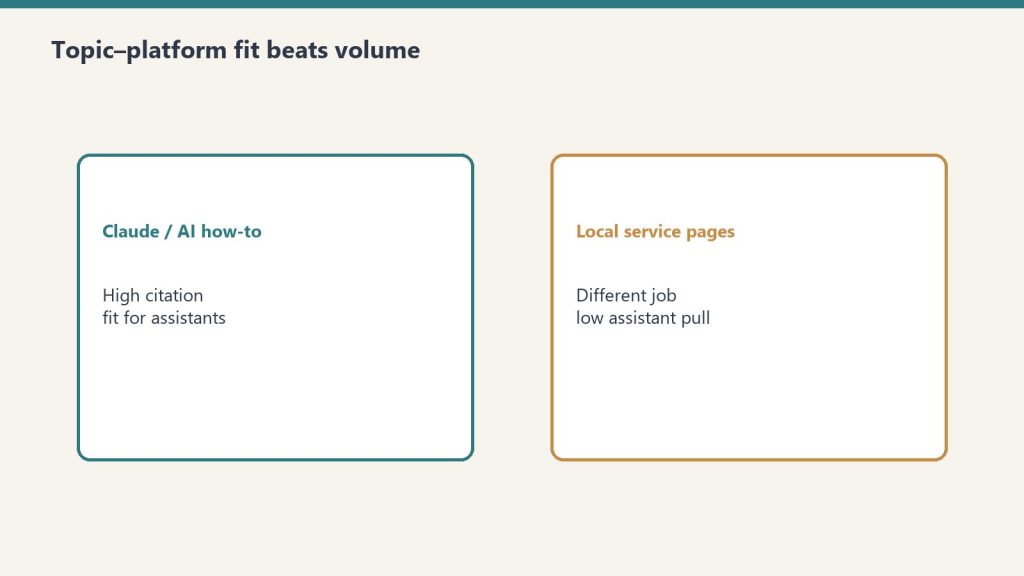
    Comparison of Claude how-to fit versus local service page fit for assistants
    What AI citation monitoring actually involves.

    AI citation monitoring has three core components — and they require different approaches because each AI system works differently.

    Google AI Overviews monitoring. This is the highest-volume opportunity for most businesses. Google’s AI Overviews appear at the top of search results for qualifying queries and pull from indexed web content. You can monitor citation appearances using rank tracking tools that have added AI Overview detection — Semrush, Ahrefs, and SE Ranking all have versions of this. The manual approach: run your target queries in a fresh browser session and note whether your domain appears in any AI Overview source citations.

    Perplexity monitoring. Perplexity is citation-native — it almost always shows source links. This makes it easier to monitor: run your core queries directly in Perplexity and see what it cites. You can do this manually at scale by building a query list and running it weekly. There are also emerging tools like Profound and Otterly.ai that automate Perplexity citation tracking.

    ChatGPT and Claude monitoring. These are harder because responses vary by session, model version, and user phrasing. The practical approach is prompt-based: run 10-20 of your highest-value queries as ChatGPT and Claude prompts asking for recommendations or explanations. Note whether your brand or content gets mentioned. Do this monthly. It’s not a perfect signal, but patterns emerge — if you’re never mentioned across 20 queries where you should be, that tells you something.

    How to Set Up AI Citation Monitoring Without Losing Your Mind

    The good news: you don’t need a $500/month enterprise tool to get started. Here’s a working system using mostly free or low-cost resources:

    1. Build your query list. Identify 20-30 informational queries that your ideal customers are likely asking AI systems. These should be questions your content already attempts to answer — the alignment matters. If you write about franchise marketing, your queries might include “how does SEO work for franchise locations” or “best marketing strategy for restoration franchises.”
    2. Run baseline checks. Go through each query manually in Perplexity, ChatGPT, and Google (looking for AI Overviews). Document what gets cited, mentioned, or surfaced. This is your Day 0 benchmark.
    3. Set a monitoring cadence. Monthly is realistic for most teams. Weekly if your content velocity is high or you’re actively running a GEO optimization campaign. Quarterly is the absolute minimum if you want to catch trends before they become problems.
    4. Track changes over time. A simple spreadsheet — query, platform, date, your citation (yes/no), competitor citations — is enough to start seeing patterns. You’re looking for: which queries you consistently appear in, which you never appear in, and which competitors keep showing up instead of you.
    5. Use the gaps to drive content decisions. Every query where a competitor gets cited and you don’t is a content gap — either you don’t have content on that topic, or your existing content isn’t structured in a way AI systems can easily extract and cite. Fix one or the other.

    What Makes Content More Likely to Get Cited by AI

    AI citation isn’t random. Systems like Perplexity and Google AI Overviews have consistent preferences, and understanding them is the foundation of any effective AI content monitoring and optimization strategy.

    Factual density. AI systems prefer content that makes specific, verifiable claims over vague generalizations. “Email marketing generates $42 in return for every $1 spent, according to Litmus’s 2023 State of Email report” is more citable than “email marketing has great ROI.” Specificity signals reliability.

    Clear question-and-answer structure. Content that explicitly poses a question as a heading and answers it directly in the following paragraph is easy for AI systems to extract. This is Answer Engine Optimization (AEO) in practice — and it’s directly correlated with AI citation frequency.

    Author authority signals. Named authors with associated credentials, social profiles, and a content history perform better in AI citation environments than anonymous or brand-attributed content. The E-E-A-T framework Google uses for quality evaluation translates directly to AI citability.

    Entity saturation. Content that correctly identifies and accurately describes key entities in a topic area — named people, organizations, products, concepts — is easier for AI to contextualize and cite accurately. Vague content gets paraphrased. Entity-rich content gets cited.

    The Monitoring Stack We Use at Tygart Media

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The monitoring stack we use at Tygart Media.

    For monitoring AI citations across our managed sites, we run a combination of automated and manual checks. The automated layer uses rank trackers with AI Overview detection — primarily Semrush’s AI Overview tracker — combined with custom scripts that run Perplexity queries via API and log citation appearances to a shared tracking sheet.

    The manual layer is a monthly prompt audit: 20 queries run through ChatGPT-4o and Claude Sonnet 4.6, logged and compared to the previous month. It takes about 45 minutes per site and surfaces patterns that automated tools miss — particularly for conversational queries where phrasing variations change AI behavior significantly.

    What we’ve learned: citation frequency is strongly correlated with content structure, not just content quality. A well-structured 800-word post with clear headers and explicit answer formatting consistently outperforms a sprawling 3,000-word post that buries the answer in paragraph five. AI systems are extracting, not reading.

    Frequently Asked Questions About AI Citation Monitoring

    What is AI citation monitoring?

    AI citation monitoring is the practice of tracking whether AI-powered search tools and chatbots — including Google AI Overviews, Perplexity, ChatGPT, and Claude — are citing, referencing, or recommending your website’s content when users ask relevant questions. It’s a form of search visibility measurement designed for the generative AI era.

    Why does AI citation monitoring matter for SEO?

    AI-generated answers in Google, Perplexity, and other platforms are now intercepting click traffic that would previously have gone to organically ranked content. If AI systems cite your competitors but not you when answering questions in your category, you’re losing visibility and traffic that traditional rank tracking won’t show you.

    How can I track if ChatGPT is citing my website?

    Run your target queries directly in ChatGPT and note whether your brand or domain appears in the response or sources. Because ChatGPT responses vary by session, run each query two to three times. For systematic tracking, build a query list and run it monthly, logging results to a spreadsheet. Emerging tools like Profound.ai offer automated ChatGPT citation monitoring.

    What is the difference between AI citation monitoring and GEO?

    AI citation monitoring is a measurement practice — it tells you whether AI systems are currently citing you. Generative Engine Optimization (GEO) is the optimization practice — it covers the content structure, entity signals, and authority markers that make your content more likely to be cited. Monitoring tells you where you are. GEO is how you improve it.

    How often should I run AI citation monitoring?

    Monthly monitoring is a practical baseline for most businesses. If you’re actively publishing and optimizing content, weekly checks let you correlate content changes with citation frequency more precisely. Quarterly is the minimum for any site that wants to stay aware of AI search trends in their category.

    Related on Tygart Media: track ChatGPT/Perplexity citations · citing sources · zero-click marketing.

    Go deeper: Once you understand what AI citation monitoring is, see how to build a live tracking system — The Living Monitor: How to Track Whether AI Systems Are Actually Citing Your Content.
  • Will’s Second Brain as an API: Should You Productize Your Context Stack?

    Will’s Second Brain as an API: Should You Productize Your Context Stack?

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    Origin note: This started as a half-formed thought — “what if my second brain is what makes my Claude work so well, and what if I could let other people rent it?” The article below is the honest answer to that question, including the parts that argue against doing it.

    The Observation That Started It

    Three stacked layers: chat UI, tools, agent runtime
    The observation that started it.

    If you spend enough time building an operational stack on top of Claude — skills, Notion databases, retrieval pipelines, project knowledge, accumulated SOPs — you start to notice something strange. Your Claude does not just answer better than a fresh Claude. It moves better. It picks the right tool the first time. It remembers patterns from work you did six months ago on a different client. It improvises in ways that look almost like learning, even though the underlying model has not changed at all.

    The model is the same. The context is doing the work.

    That observation leads to an obvious question: if a curated context layer is what separates a useful AI from a frustrating one, could you sell access to your context layer? Not the model, not the prompts, not the chat interface — just the accumulated patterns, conventions, and operational wisdom, exposed as an API that any other AI workflow could pull from. Call it “Will’s Second Brain” or anything else. The pitch is: connect this to whatever you are building, and somehow it just works better. You will not always know why. That is part of the value.

    This article walks through whether that is actually a good idea, what it would cost, what the conversion math looks like, what the legal exposure is, and where the real moat would have to come from.

    The Category Already Exists (And That Is Mostly Good News)

    The “memory layer for AI agents” category is real and growing fast. Mem0, which is probably the most visible player, raised a $24M Series A in October 2025 and reports more than 47,000 GitHub stars on its open-source SDK. Their pitch is essentially the one above: instead of stuffing the entire conversation history into every LLM call, route through a memory layer that retrieves only the relevant context. They claim around 90% lower token usage and 91% faster responses compared to full-context approaches. Their pricing tiers run from a free hobby plan (10K memories, 1K retrieval calls per month) to $19/month Starter to $249/month Pro to custom enterprise pricing.

    Letta, formerly MemGPT, takes a different approach — it is a full agent runtime built around tiered memory (core, recall, archival) that mirrors how operating systems manage RAM and disk. Zep and its Graphiti engine focus on temporal knowledge graphs. SuperMemory bundles memory and RAG with a generous free tier. Hindsight publishes benchmark results claiming 91.4% on LongMemEval versus Mem0’s 49.0%, and offers all four retrieval strategies on its free tier. LangMem ships with LangGraph for teams already on that stack. AWS has Bedrock AgentCore Memory as the managed equivalent.

    The good news in all of that: the category is validated. Buyers exist. Pricing precedents exist. The bad news: you are not going to win on infrastructure. You are not going to out-engineer a YC-backed team with $24M in funding and 47K stars. If you enter this space, you have to enter on a different axis entirely.

    Where The Real Moat Would Be

    Five security domains: identity, data, code governance, audit, agents
    Where the real moat would be.

    The moat is not the storage. The moat is what is in the storage.

    Mem0, Letta, and the rest sell empty memory layers. You bring the data. The promise is: if you put your facts in here, retrieval will be fast and cheap. That is a real value proposition, but it is a tooling pitch, not a knowledge pitch. The customer still has to build the knowledge themselves.

    A second-brain-as-a-service offering would sell a pre-loaded memory layer. Not “here is a fast retrieval system,” but “here is a retrieval system that already knows how an AI-native content agency thinks about WordPress, SEO, GEO, AEO, taxonomy architecture, content refresh strategy, hub-and-spoke linking, Notion command center design, GCP publishing pipelines, and the operational lessons from running 27 client sites.” That is not a tooling product. That is consulting wisdom packaged as middleware.

    The closest analogies are not Mem0 or Letta. They are things like:

    • Cursor’s index of best practices baked into its autocomplete — the tool ships with an opinion about what good code looks like, and that opinion is the product.
    • Linear’s opinionated workflows — the value is not the database, it is the prescribed way of working that the database enforces.
    • 37signals’ Shape Up methodology being sold as a book — accumulated operational wisdom packaged as a product separate from the consulting practice.

    The “second brain as an API” pitch is closer to Shape Up than to Mem0. The technical layer is just the delivery mechanism.

    The Economics: Cheaper Than You Think, Harder Than You Think

    Per-query costs for serving a RAG API are genuinely low. A typical retrieval call against a vector store runs somewhere in the range of fractions of a cent to a few cents depending on embedding model, vector store, and how many chunks you return. If you self-host on GCP using Cloud Run, BigQuery, and Vertex AI embeddings, marginal serving cost per query is negligible at small scale and only becomes meaningful at thousands of queries per minute.

    The cost problems are not the queries. They are:

    • Free trial abuse. Developer-facing API products with free trials get hammered. Bots, scrapers, people running benchmarks against you for blog posts, competitors testing your retrieval quality. If you offer any free tier without a credit card on file, expect a meaningful percentage of total traffic to be abuse. Hard rate limits and required payment methods from day one are not optional.
    • Support load. Even a “just connect this and it works” product generates support tickets. Integration questions, schema confusion, “why did it return X when I asked Y,” “how do I cite this in my own product.” For a single operator, support load is the actual scaling constraint, not infrastructure.
    • Conversion math. Free-trial-to-paid conversion for self-serve developer tools typically runs in the 2% to 5% range, with some outliers higher and many lower. A trial that converts at 2% needs roughly 50 trial signups per paying customer. If your trial is generous and your conversion is on the low end, you can spend more on serving free users than you earn from paid ones, especially in early months when paying user count is small.

    None of this kills the idea. It just means the business case has to be built on top of realistic assumptions, not aspirational ones.

    The Scrubbing Problem (This Is The Scariest Part)

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The scrubbing problem — the scariest part.

    An accumulated operational knowledge base built from real client work is, by definition, contaminated with information that cannot leave the building. Client names. Service URLs. App passwords. Internal strategy documents. Competitor analysis. Personal references. Names of contractors and partners. Slack-style observations about which clients are easy to work with and which are not. Pricing conversations. Things a client said in a meeting.

    “I will scrub the data before I expose it” is a sentence that gets people sued. The problem is that scrubbing, done as a filter on top of live data, always misses things. You build a regex for client names, but you forget a client was referenced obliquely in a footnote. You strip URLs, but a screenshot or a code example contains a domain. You remove credentials, but an old version of a SOP still has an example token in it. Filters are 95% solutions to a problem that needs a 100% solution, because the failure mode of the missing 5% is “client finds their internal information being served to a stranger via your API.”

    The right architecture is not a filter. It is a clean room.

    That means a separate knowledge base, built from scratch, that contains only the patterns, conventions, and methodology — never the source material it was extracted from. You read your accumulated work, you write generalized lessons by hand or with heavy review, and those generalized lessons become the product. The production knowledge base never touches the serving knowledge base. There is an air gap, not a pipeline.

    This is more work than the “scrub and ship” approach. It is also the only version that does not end in a lawsuit.

    Liability Exposure

    The moment “Will’s Second Brain” is connected to someone else’s workflow, three new liability vectors open up:

    1. Bad output causes a bad decision. Customer uses your API to generate strategy, follows the strategy, loses money, blames you. Mitigated by ToS, liability caps, and clear disclaimers that the service is informational and not professional advice.
    2. Hallucinated facts get cited as authoritative. Your knowledge base says something confident, customer publishes it, the something is wrong, customer’s audience holds them responsible. Mitigated by disclaimers and by being conservative about what gets included in the seed data.
    3. Your contaminated data ends up in front of the wrong eyes. See previous section. Mitigated by the clean-room architecture, not by promises.

    The minimum legal infrastructure to launch is: an LLC, a Terms of Service with clear liability caps, a Privacy Policy, errors and omissions insurance, and ideally a separate entity that owns the product so the consulting business is shielded if the product business gets sued. None of these are expensive individually. All of them are necessary together.

    The Loss Leader Question

    One framing of the idea is: do not try to make money from it directly. Give it away. Let it serve as the most aggressive top-of-funnel content marketing asset Tygart Media has ever shipped. Every developer who connects “Will’s Second Brain” to their workflow becomes aware of Tygart Media. Some fraction of them will eventually need the consulting practice that the second brain was extracted from.

    This is a much more defensible version of the idea, for three reasons:

    • It removes the trial conversion math from the critical path. You are not optimizing for paid signups. You are optimizing for awareness and mindshare.
    • It removes most of the support burden. Free tools have lower customer expectations. “It is free, here is the docs page” is a complete answer in a way that “you are paying $19 a month, please help me debug my integration” is not.
    • It changes the liability story. Free tools used at the user’s own risk have a much easier time enforcing liability caps than paid services do.

    The cost side of a free version is real but manageable. Hard rate limits, required signup with a real email address (for the funnel, not the billing), aggressive abuse detection, and serving costs absorbed as a marketing line item rather than a COGS line item. A few hundred dollars a month of GCP spend is cheaper than most paid ad campaigns and probably reaches more qualified people.

    Verdict

    The idea is good. The business is hard. The two are not the same thing.

    The version that probably works is the loss-leader version: a free, rate-limited, clean-room knowledge API marketed as a top-of-funnel asset for the consulting practice, built from a hand-curated knowledge base that never touches client data, wrapped in a basic legal entity with a real ToS and E&O insurance. The version that probably does not work is the standalone subscription business with a free trial, because the trial economics, the support load, and the liability surface area are all more hostile than they look from the outside.

    The thing worth building first is not the API. It is the clean-room knowledge base. If you can hand-write 100 generalized operational patterns from the existing stack, in a way that contains zero client-specific information and reads as standalone wisdom, you have proven the product is possible. If you cannot — if every pattern keeps wanting to reference a specific client situation to make sense — then the wisdom is not yet abstract enough to package, and the right move is to keep accumulating and revisit in six months.

    Either way, the question that started this is the right question. Context is doing more work in modern AI than most people realize, and someone is going to figure out how to sell curated context as a product. It might as well be the operator who already has the most interesting context to sell.


    Reference Data and Knowledge Node Notes

    This section exists to make this article more useful as a knowledge node when scanned later. It contains the underlying market data, pricing references, and structural notes that informed the analysis above.

    Memory Layer Market Snapshot (2026)

    • Mem0: $24M Series A October 2025 (Peak XV, Basis Set Ventures). 47K+ GitHub stars. Apache 2.0 open source. Pricing: free Hobby (10K memories, 1K retrieval calls/month), $19 Starter (50K memories), $249 Pro (unlimited, graph memory, analytics), custom Enterprise. Claims 90% token reduction, 91% faster, +26% accuracy on LOCOMO benchmark vs OpenAI Memory. SOC 2, HIPAA available. Independent evaluation: 49.0% on LongMemEval.
    • Letta (formerly MemGPT): Full agent runtime, not just memory layer. Three-tier OS-inspired architecture (core, recall, archival). Self-editing memory where agents decide what to store. Apache 2.0, ~21K GitHub stars. Python-only SDK. Best for new agent builds, not for adding memory to existing stacks.
    • Zep / Graphiti: Temporal knowledge graphs. Strongest option for queries that need to reason about how facts changed over time. Reportedly scores 15 points higher than Mem0 on LongMemEval temporal subtasks.
    • Hindsight: MIT licensed. Claims 91.4% on LongMemEval. All retrieval strategies (graph, temporal, keyword, semantic) available on free tier including self-hosted.
    • SuperMemory: Bundled memory + RAG. Closed source. Generous free tier. Small API surface.
    • LangMem: Memory tooling for LangGraph. Three memory types: episodic, semantic, procedural (agents updating their own instructions). Free, open source. Requires LangGraph.
    • Bedrock AgentCore Memory: AWS managed equivalent. Out-of-the-box short-term and long-term memory.

    Conversion Rate Reference Numbers

    • Self-serve developer tool free trial → paid conversion: typically 2-5%, with B2B SaaS averages around 14-25% across all categories but developer tools tend to be lower because the audience is more skeptical and self-sufficient.
    • Freemium to paid conversion (no trial, just free tier): typically 1-4%.
    • Required credit card on free trial: roughly 2x conversion rate vs no card required, but 50-75% lower trial signup rate. Net result is usually higher quality but lower quantity.

    Cost Reference Numbers (GCP, 2026)

    • Vertex AI text embedding (gecko-003 or similar): roughly $0.000025 per 1K characters. A typical 500-word document chunk costs less than $0.0001 to embed.
    • BigQuery vector search: storage is cheap, queries scale with the size of the result set. A retrieval against 100K vectors returning top-10 typically costs well under a cent.
    • Cloud Run serving costs: minimum-instance-zero deployments cost nothing at idle. Per-request cost for a typical retrieval API is a fraction of a cent including CPU time and egress.
    • Realistic monthly serving cost for a free, rate-limited “second brain” API at modest usage (say, 100 active users averaging 50 queries per day): probably $50-200/month total infrastructure.

    The Clean Room Architecture (Recommended Approach)

    Two completely separate knowledge bases, never connected:

    1. Production knowledge base: The existing accumulated stack. Notion command center, Claude skills library, client SOPs, BigQuery operations ledger, everything tagged to specific clients and projects. This is the source of truth for the consulting practice. It never touches the public-facing system.
    2. Clean room knowledge base: Hand-written or heavily-reviewed generalized patterns. Contains zero client-specific information, zero credentials, zero internal strategy, zero personal references. Each entry is a standalone generalized lesson that could have been written by anyone with similar experience. This is what gets exposed via the API.

    The transfer between the two is manual or heavily reviewed, never automated. A regex filter is not a clean room. A human reading each entry and rewriting it is.

    Minimum Viable Legal Stack

    • Separate LLC for the product (shields the consulting practice)
    • Terms of Service with explicit liability cap (typically capped at fees paid in last 12 months, or for free service, capped at $0 plus minimal statutory damages)
    • Privacy policy covering what gets logged and retained
    • Errors and omissions insurance ($1M coverage typical, runs $500-1500/year for a small operation)
    • Clear “informational, not professional advice” disclaimers on every API response
    • Logged consent that the user understands the service is generative and may produce incorrect output

    Adjacent Concepts Worth Tracking

    • “Context as a service” as an emerging category — distinct from memory layers. Memory layers store what the user told them. Context services ship with knowledge already loaded.
    • The methodology-as-product pattern — Shape Up, Getting Things Done, the 4-Hour Workweek. These are all examples of operational wisdom productized into something that can be sold separate from the consulting practice that generated it.
    • Loss leaders as PR for consulting practices — 37signals’ Basecamp, Stripe’s documentation, Vercel’s open source projects. The free or cheap thing is the marketing for the expensive thing.
    • The “API for vibes” risk — products that promise “it just works better” without explaining why are hard to differentiate, hard to defend in court, and hard to upsell. The product needs at least one concrete claim that can be measured.

    Last updated: April 2026. Knowledge node tags: AI memory layers, productization, second brain, RAG, context engineering, loss leader strategy, clean room architecture, Mem0, Letta, Zep, agency productization, AI tooling business models.