Tag: Claude

  • AI Citation Playbook: Claude vs ChatGPT vs Perplexity

    AI Citation Playbook: Claude vs ChatGPT vs Perplexity

    Part 2 of 2. In the first post I showed that Claude, ChatGPT, Perplexity, Copilot, Gemini, NotebookLM, and Kagi collectively sent tygartmedia.com at least 94 new readers in 29 days — and that Claude alone is our #4 traffic source. That is the headline. What follows is the interesting part: when you filter the landing-page report one AI model at a time, the three major assistants cite completely different kinds of pages, and the pattern is actionable.

    Claude cites a small number of pages, a lot of times
    Two cards: answer shown in overview versus optional click
    Claude cites a small number of pages, a lot of times.

    Claude.ai sent 79 sessions across 63 users to 16 distinct pages. Two pages ate more than half of it:

    #PageSessions% of Claude trafficAvg Time
    1/claude-student-discount2227.9%35s
    2/anthropic-console2126.6%11s
    3(not set)1316.5%5s
    4/claude-edu45.1%6s
    5/claude-pro-vs-chatgpt-plus45.1%7s
    6/claude-code-on-vertex-ai-gcp33.8%3s
    7/claude-desktop22.5%40s
    8/how-to-install-claude-code22.5%2s
    9/claude-4-deprecation11.3%1m 07s
    10/claude-managed-agents-pricing-cost-analysis11.3%1m 38s

    The two biggest pages, /claude-student-discount and /anthropic-console, are 54.5% of all Claude-referred traffic to the site. Those are extremely specific query shapes — “how do students get Claude Pro free” and “how do I access the Anthropic Console” — and Claude has apparently decided our pages are the canonical answer for both.

    The engagement twist is worth staring at. The two biggest Claude-referred pages have the worst time-on-page: 35 seconds and 11 seconds. The two pages that got a single Claude visit each — /claude-managed-agents-pricing-cost-analysis and /claude-4-deprecation — got 1 minute 38 seconds and 1 minute 7 seconds of real read time. The pattern is clean. When Claude can extract the answer directly into its chat window, users click through briefly to verify and leave. When the answer is deeper than Claude can summarize, readers stay to actually read. Both behaviors are valuable and both are measurable.

    ChatGPT cites broadly, favors “X vs Y” content, and (oddly) sends geographic traffic

    ChatGPT’s footprint is shaped differently. 16 sessions across 14 users to 13 distinct pages — almost every page received exactly one visit, which is the signature of a model citing a wide range of sources once each rather than reaching for a favorite.

    PageSessionsAvg Time
    /claude-student-discount315s
    /claude-computer-use-tutorial12m 07s
    /grok-vs-claude115s
    /opus-4-7-vs-gpt-5-4-vs-gemini-3-1-pro10s
    /claude-pro-vs-chatgpt-plus(cross-model)—
    /claude-for-nonprofits130s
    /everett-waterfront-visitor-guide…10s
    /hood-canal-shellfish-season-2026…10s
    /rakuten-claude-managed-agents-enterprise-deployment10s

    Two patterns in that list. First, ChatGPT appears to cite us disproportionately for model comparisons — grok-vs-claude, opus-4-7-vs-gpt-5-4-vs-gemini-3-1-pro, and the cross-model claude-pro-vs-chatgpt-plus page. Second, and stranger, ChatGPT sent visits to two hyperlocal Pacific Northwest pages: an Everett waterfront guide and a Hood Canal shellfish season page. That is ChatGPT using our site as a reference source for geographic queries, which is not a pattern any other model shows.

    The hidden gem: /claude-computer-use-tutorial received one ChatGPT referral and that referral stayed for 2 minutes 7 seconds. ChatGPT appears willing to cite long-form technical tutorials in a way Claude does not.

    Perplexity treats us like a research database

    Perplexity sent 12 sessions across 10 users to 9 pages — the most evenly distributed of the three and the only model that cites people, founders, and company-history content.

    PageSessionsAvg Time
    /anthropic-founders-2217s
    /claude-code-on-vertex-ai-gcp254s
    /claude-student-discount20s
    /claude-desktop14s
    /claude-team-plan10s
    /how-to-install-claude-code10s
    /restoration-team-training-claude-cowork10s

    Perplexity is the only model that pulled visits on /anthropic-founders-2, which implies Perplexity is fielding a different query shape — something closer to “who founded Anthropic” than “how do I use Claude.” Perplexity is also the only model that surfaced the very niche B2B page /restoration-team-training-claude-cowork. That is a long-tail, vertical-specific query and Perplexity cited us as the source. That is exactly the behavior you would hope for from a research-flavored assistant.

    The three models have completely different citation personalities
    Four cards comparing ChatGPT, Gemini, Perplexity, and Copilot by job
    The three models have completely different citation personalities.

    Once you lay the three patterns side by side, the strategy falls out of the page.

    • Claude.ai favors short, factual, access-related pages. Product info, pricing, how-to-access. If you want more Claude citations, write more narrow “how do I do this one specific thing” pages.
    • ChatGPT favors comparisons and long-tail references. X vs Y, alternatives, and — unexpectedly — some geographic content. If you want more ChatGPT citations, write more “X vs Y” posts with tight comparison tables.
    • Perplexity favors people, history, and niche research. Founders, company background, domain-specific tutorials. If you want more Perplexity citations, write more research-flavored background pieces.

    This is the single most practical insight in the data set. Most people talk about “AI SEO” as if it is one thing. It is three things, at minimum, and the content shape that wins one model will not automatically win the other two.

    The crown jewel: one page, 17% of all AI-referred traffic

    The clearest cross-model winner on the site is /claude-student-discount. Claude sent 22 sessions. ChatGPT sent 3. Perplexity sent 2. Combined that is 27 sessions — roughly 17% of all AI-referred traffic we received in 29 days, from a single URL. No other page on the site is cited by all three major LLMs in meaningful volume.

    There is a playbook inside that one data point. The page works because the query “how do I get Claude for free as a student” is an extremely high-frequency question across every chat surface, and the page happens to be structured the way LLMs like to cite: a short, direct answer near the top, specific eligibility rules in a scannable block, and no wall of context before the reader gets to the fact. That structural recipe — front-load the answer, make the facts liftable, keep the page narrow — is repeatable.

    The bigger finding: 90% of our Claude content is invisible to AI

    tygartmedia.com has more than 250 Claude-related articles. Exactly 25 of them show up in the AI-referral data set at all. The 90% that do not get cited are not low-quality — several of them have strong engagement from regular search traffic:

    • /claude-managed-agents-complete-pricing-guide-2026 — 17 sessions at ~1 minute from search, zero AI citations
    • /notion-knowledge-base-for-claude — 10 sessions at 1m 23s, uncited
    • /claude-rate-limits — classic FAQ shape, 6 sessions, not cited
    • /claude-md-playbook — 1 session at 2m 33s, zero AI pickup
    • The full /claude-cowork-* family of 12+ pages, almost entirely invisible to every model

    The difference between an AI-cited page and an AI-invisible page is rarely the quality of the content. It is the shape. Pages that get cited have an early summary, short headings, bulleted facts, and a quotable direct-answer sentence. Pages that do not get cited tend to open with context, build up to the answer, and bury the quotable line in paragraph 9.

    The content-cluster scorecard

    ClusterApprox. PagesApprox. SessionsEngagementAI Citations
    Claude pricing & access~10~160MixedHigh
    Claude managed agents~12~130Strong (25s–1m)Low
    Claude Code~8~60High (18s–3m)Moderate
    Model comparisons (X vs Y)~10~45Very high (1–7 min)Moderate
    Anthropic people/company~8~30MediumModerate
    Claude how-to / tutorials~20~50MediumLow
    Claude Cowork family~15~40Very low (0–10s)Almost none

    Two clusters deserve action. The Claude Cowork family is a content swamp — 15 pages, low traffic, no AI citations, and 0–10 second engagement on the traffic that does land. That cluster should be consolidated into two or three flagship posts and the rest redirected. The model comparisons cluster is the opposite: low volume but 1–7 minutes of engagement and cross-model citations. One well-researched comparison post outperforms ten mediocre explainers on every metric that matters here.

    The playbook, in one list
    Four-stage funnel: citation, click, engage, convert
    The playbook, in one list.
    • Write more narrow single-answer pages. Candidates I would ship next: /claude-web-search, /claude-api-keys, /claude-max-plan-vs-pro, /how-to-cancel-claude, /claude-mobile-app, /claude-desktop-vs-web, /claude-subscription-refund. Each is ~600 words, answer-first, scannable. That is the shape Claude cites.
    • Add a Quick Answer block to the top of every long-form piece. Two or three sentences. Quotable. That alone moves a real share of our invisible content into AI-citation range.
    • Invest in comparison posts for ChatGPT pickup. We already know ChatGPT cites our existing X-vs-Y content. Ship more of them, with tight tables.
    • Write more founder/history/background pieces for Perplexity pickup. Research-flavored. Dates, names, primary sources.
    • Consolidate the Cowork cluster. Two or three flagship pages, everything else redirected.
    • Ship a permanent AI-Referral dashboard in GA4. Segment on all seven assistant domains. Watch it weekly. This is now a first-class channel.

    Frequently asked questions

    What kinds of pages does Claude.ai cite most often?

    Based on the tygartmedia.com data, Claude.ai disproportionately cites short, factual, access-related pages — product info, pricing, how-to-access, and eligibility details. On our site, two pages (/claude-student-discount and /anthropic-console) accounted for 54.5% of all Claude-referred traffic in a 29-day window.

    What kinds of pages does ChatGPT cite most often?

    ChatGPT’s citation pattern favors comparison and long-tail reference pages — “X vs Y” posts like Grok vs Claude, model-to-model comparisons, and, surprisingly, some geographic and local content. ChatGPT tends to cite many pages once each rather than concentrating on a small set.

    What kinds of pages does Perplexity cite most often?

    Perplexity cites research-flavored content — founders and company history, domain-specific tutorials, and niche B2B pages. It is the only major AI assistant that sent traffic to our Anthropic founders page and to a vertical-specific training page in our data set.

    Why does the same page get different citation volume from different AI models?

    Because each assistant is answering a slightly different distribution of queries. Claude is most often used for “how do I use this product” questions and favors narrow how-to pages. ChatGPT receives more comparison and alternative-seeking queries. Perplexity skews toward research and background questions. A page that is the best answer for one query type will not automatically be the best answer for another.

    How do I structure a page to get cited by AI assistants?

    Lead with a direct, quotable answer in the first paragraph. Use short scannable headings. Keep facts in bulleted or tabular form. Include an explicit FAQ block with question-shaped subheadings. Keep the page narrow — one topic, one canonical answer — rather than a sprawling multi-topic explainer.

    The bigger picture

    The meta-insight worth sitting with: we are currently being cited inside Claude’s internal answer graph for “Claude student discount” because a human sat down and wrote a clear, narrow page about it. That is almost the entire game for publishers for the next three years. Most of the web has not noticed yet. We noticed, and now we have a measurement stack to act on what we noticed.

    If you are a publisher, the thing to do this week is boring and powerful: segment your GA4 on the seven AI-assistant domains from Part 1, sort your landing pages by AI-referral volume, and look at the pages that are winning. They will have a shape. Copy it.

    — If you missed it, Part 1 is here.
  • How to Get Hired Without Applying: The 30-Minute Daily Protocol That Gets You Found

    How to Get Hired Without Applying: The 30-Minute Daily Protocol That Gets You Found

    The short version: If you want a job in a flooded market, stop trying to be employable in general. Pick one specific corner of your industry. Spend 30 minutes in the morning learning it. Spend the day forgetting most of what you read. Spend 30 minutes at night posting about whatever survived. The forgetting is the filter. The publishing is the proof. Six months in, you are not looking for a job. The job is looking for you.

    Last refreshed: October 8, 2026 (Pacific)

    Most career advice is built around a quiet lie: that the way to stand out is to be a little better at everything everyone else is also a little better at. Sharpen your resume. Add a certification. Take another course. Write another cover letter. Put it all on LinkedIn and hope the algorithm notices.

    It does not work. It cannot work. The market is not short on generalists. It is starving for specialists, especially specialists who have visibly done the thing in public.

    What follows is a job-seeking strategy that takes about an hour a day, requires no extra money, and exploits two pieces of cognitive science most career coaches do not mention: spaced repetition and spaced retrieval. The whole point is to use forgetting as a feature, not a bug — and to publish the part that survives.

    The four-step protocol

    1. Pick three things from your industry that are the most valuable. Not the most popular. Not the most discussed. The three problems that, when someone solves them, money moves.
    2. Pick one of the three you actually want to become an expert on. The one you would willingly read about on a Sunday with no one watching.
    3. Spend 30 minutes in the morning researching it. Read primary sources. Take rough notes. Do not try to remember everything. You will not.
    4. Spend 30 minutes in the evening posting about it. Whatever you can still articulate without notes is the thing worth publishing. The rest was noise.

    That is the entire system. It is shorter than most morning routines. It will outperform almost any other career-building activity you can do in the same time.

    Why morning study and evening publishing actually works

    The forgetting is doing the editing

    When you study something in the morning and then go live a normal day, your brain runs a quiet triage process. Most of what you read decays. The handful of things that connect to something you already understand — or that genuinely surprised you, or that you can imagine using — survive.

    By evening, what is left in your head is not a complete summary of what you read. It is the signal of what you read. The compression happened automatically.

    This is why the evening publishing step matters. You are not trying to teach the morning’s full reading. You are publishing what survived eight hours of normal life. That is, by definition, the part most likely to be useful, memorable, and original.

    Spaced repetition is one of the most-validated learning techniques in cognitive science

    The morning-then-evening rhythm is a lightweight version of spaced repetition, the practice of revisiting information at intervals rather than cramming it in one session. A 2024 prospective cohort study published through the American Board of Family Medicine tracked thousands of practicing physicians and found spaced repetition produced significantly better long-term knowledge retention than repeated study sessions.

    A separate quasi-experimental study at Jawaharlal Nehru Medical College found students using spaced repetition scored 16.24 versus 11.89 on post-test assessments compared to traditional study — a statistically significant difference (p < 0.0001) that held across multiple disciplines.

    The mechanism is not mysterious. Each time you successfully retrieve information after a delay, the neural pathway gets reinforced. Each time you fail to retrieve it, you learn something more important: that piece was not load-bearing. You can let it go.

    When you publish in the evening what you can still remember from the morning, you are running this loop in public. You are letting your brain tell you what mattered, then giving the world the part that mattered.

    The publishing layer is what changes your career

    Studying alone makes you smarter. Publishing what you study makes you findable.

    The career-changing leverage is in the second half. A junior marketer who quietly reads about LinkedIn ads for construction companies in rural areas for six months becomes a slightly better junior marketer. A junior marketer who publishes one short post per evening for six months about the same thing becomes the person every rural construction company finds when they search “how to run LinkedIn ads for a contractor.”

    That is not the same outcome. That is a different career.

    Specificity is the multiplier

    “LinkedIn ads” is a saturated topic. Hundreds of generalists post about it daily. Each new post fights for the same shrinking attention slice.

    “LinkedIn ads for construction companies in rural markets” is almost empty. The total competing supply of content might be a dozen serious posts a year. The total demand from rural construction company owners trying to figure this out is significant. The ratio is what makes the niche valuable.

    The specific corner you pick is the entire game. The narrower it is, the faster you become the visible expert in it. The narrower it is, the easier it is for the right buyer or hiring manager to find you. The narrower it is, the less you have to compete on resume and the more you compete on demonstrated thinking.

    What gets cited by AI is not what gets the most engagement

    There is a quiet shift happening in how hiring managers and buyers find people. They no longer search Google and scroll through ten blue links. They ask ChatGPT, Gemini, Perplexity, or Google’s AI Overview “who’s good at X?” and read what the AI says.

    The thing is — AI systems do not cite content based on follower count or engagement. They cite based on relevance, specificity, and structure. A short, well-structured LinkedIn article from someone with 200 followers is regularly cited above a viral post from someone with 200,000 followers, because the smaller account wrote something specific and useful.

    This is the most underpriced opportunity in personal branding right now. You do not need an audience. You need a corner you own and a publishing rhythm you can sustain. The AI does the distribution.

    What the evening 30 minutes should actually look like

    Do not overthink the format. The post is not the product. The practice is the product. Here is a workable template:

    • One observation from the morning’s reading. Not the main point. The thing that surprised you.
    • One concrete example of how it shows up in your specific niche.
    • One short opinion on what most people get wrong about it.

    That is roughly 150 to 250 words. It takes ten minutes to write if you let yourself write badly. The other twenty minutes are for the next day’s reading list and any replies to the previous day’s post.

    You do not need to post on LinkedIn. You can post anywhere your industry actually reads. But LinkedIn rewards consistent professional output more than almost any other platform, especially for B2B niches, and AI systems are increasingly citing LinkedIn articles in answer to professional queries. So the platform pays its own freight.

    Six months from now

    If you do this for six months — and almost no one does — three things are true at once.

    First, you actually know your niche better than 95% of the people who claim to. You have read primary sources every morning for 180 mornings. You have wrestled with the material publicly. You have gotten things wrong, gotten corrected by other practitioners, and updated your understanding in front of an audience.

    Second, you have a public record of that learning. Your LinkedIn — or whatever surface you chose — is now a longitudinal proof of competence in a specific area. Anyone vetting you can see exactly how you think about the problem they need solved.

    Third, the math has flipped. You are no longer trying to find a job. You are getting messages from people who need exactly what you have spent six months publishing about. Some of those messages are job offers. Some are consulting opportunities. Some are partnerships you would not have known existed.

    The whole strategy rests on a quiet observation: most people will not do this. Not because it is hard. Because it is slow at the start, requires saying things in public before you feel qualified, and pays nothing for the first few months. Most career advice optimizes around making people feel like they are doing something. This optimizes around making the market notice you have done something.

    The compounding loop

    The longer this runs, the better it gets. Six months of daily 30-minute morning study is roughly 90 hours of focused reading in a single domain — more than most working professionals invest in any specific topic outside of formal education. Six months of daily evening posting is roughly 180 short-form pieces of public-facing thinking in your niche.

    Compare that to the alternative: another resume rewrite, another certification, another generic course. None of those produce a public footprint. None of those compound. None of them make you findable to the people who are actually trying to solve the problem you have spent six months understanding.

    An hour a day. One narrow niche. Spaced repetition doing the editing. Evening publishing doing the marketing. The forgetting is the filter. The publishing is the proof. The compounding is what changes your career.

    Frequently asked questions

    How do I pick the right niche if I have not started a career yet?

    Pick the intersection of: a problem real businesses pay money to solve, an industry you find genuinely interesting, and an angle that is not already saturated. Specific is always better than general. “B2B SaaS marketing” is too broad. “Onboarding email sequences for vertical SaaS in healthcare” is the size of niche that wins.

    What if I already have a job and want to use this to switch fields?

    The protocol is identical. Do the morning study and evening publishing in the niche you want to move into, not the one you currently work in. Six months of public output in the new field is more credible to a hiring manager in that field than ten years of unrelated experience.

    What if I do not know enough to write anything yet?

    Write what you are learning, with that framing. “I have been studying X for two weeks. Here is the most surprising thing I have found so far.” Beginner-as-narrator is one of the most engaging voices on LinkedIn. People follow learning journeys. They scroll past finished experts.

    Does this work for technical fields too?

    Especially well. Engineers, scientists, and analysts who can publish clearly about their narrow domain are vanishingly rare and disproportionately valuable. The 30-minute evening post can be a code walkthrough, a paper summary, a debugging story, or a single counterintuitive finding. The format does not matter. The consistency does.

    What if I post for a month and nothing happens?

    Expected. The first 30 to 60 days are unread. The compounding starts somewhere between day 90 and day 180 for most people. The point of the practice is the practice. The audience is a side effect of the discipline, not the goal of it.

    How is this different from a traditional content marketing strategy?

    Traditional content marketing optimizes for traffic and conversions. This optimizes for being findable in the moment a buyer or hiring manager is searching for someone who understands their specific problem. It is closer to a slow-cooking authority strategy than a fast-twitch growth strategy. The output is the same — published material — but the goal is positioning, not pageviews.

    How long before this protocol produces results?

    Most practitioners see the first inbound interest — a recruiter message, a LinkedIn DM, or a referral — within 30 to 60 days of consistent publishing. Meaningful job offers from the protocol typically appear between 60 and 120 days. The compound effect is real but it requires showing up every single day, not every few days.

    Does this work if I don’t have a large following?

    Yes — that is the point. The protocol is designed for zero followers. Niche specificity means your content surfaces in search and in algorithmic feeds for people who actually hire in that domain. A post about a specific IICRC standard seen by 40 restoration adjusters is worth more than a generic “open to work” post seen by 4,000 random connections.

    What platform should I publish on?

    LinkedIn is the primary platform for most B2B and professional roles. If your target niche is technical (engineering, development, data), adding a personal site or GitHub significantly accelerates the signal. Pick one platform and go deep — cross-posting thin content to multiple networks dilutes the authority signal you are trying to build.

    What if my niche is too broad?

    Narrow it by one layer. “Marketing” is too broad. “B2B SaaS content marketing” is still broad. “Content operations for vertical SaaS companies under $10M ARR” is specific enough to own. The discomfort of narrowing is the signal you are on the right track — niches that feel too small almost always have more hiring demand than the broad lane you came from.

    Is this only useful for people currently unemployed?

    No — the protocol is most powerful when you start it before you need a job. Building niche authority takes time; running it while employed means you enter your next search with an established signal rather than starting from zero. Many practitioners use it permanently as a career infrastructure habit, not a job-search tactic.

    The bottom line

    The short post that became this article said: pick three things from your industry, choose one, study it 30 minutes in the morning, post about it 30 minutes at night. That is the whole strategy.

    What that short post did not say is why it works. The morning input gives your brain something to process. The day in between lets the trivial stuff fall away. The evening output forces you to publish what survived — which is, by the cleanest possible test, the part worth publishing. Repeat for six months. Pick the right niche. Watch what happens to your inbox.

    The career advice industry sells motion. This is the opposite. This is a small, slow, compounding bet on becoming visibly excellent at one specific thing. Almost no one will do it. That is what makes it work.


    search and in algorithmic feeds for people who actually hire in that domain. A post about a specific IICRC standard seen by 40 restoration adjusters is worth more than a generic “open to work” post seen by 4,000 random connections.

    What platform should I publish on?

    LinkedIn is the primary platform for most B2B and professional roles. If your target niche is technical (engineering, development, data), adding a personal site or GitHub significantly accelerates the signal. Pick one platform and go deep — cross-posting thin content to multiple networks dilutes the authority signal you are trying to build.

    What if my niche is too broad?

    Narrow it by one layer. “Marketing” is too broad. “B2B SaaS content marketing” is still broad. “Content operations for vertical SaaS companies under $10M ARR” is specific enough to own. The discomfort of narrowing is the signal you are on the right track — niches that feel too small almost always have more hiring demand than the broad lane you came from.

    Is this only useful for people currently unemployed?

    No — the protocol is most powerful when you start it before you need a job. Building niche authority takes time; running it while employed means you enter your next search with an established signal rather than starting from zero. Many practitioners use it permanently as a career infrastructure habit, not a job-search tactic.

Related Reading

  • Should You Give Claude Access to Your Email, Slack, and SSH Keys?

    Should You Give Claude Access to Your Email, Slack, and SSH Keys?

    Last refreshed: May 15, 2026

    The Lethal Trifecta is a security framework for evaluating agentic AI risk: any AI agent that simultaneously has access to your private data, access to untrusted external content, and the ability to communicate externally carries compounded risk that is qualitatively different from any single capability alone. The name comes from the AI engineering community’s own terminology for the combination. The industry coined it, documented it, and then mostly shipped it anyway.

    The answer to the question in the title is: it depends, and the framework for deciding is more important than any blanket yes or no. But before we get to the framework, it is worth spending some time on why the question is harder than the AI industry’s current marketing posture suggests.

    In the spring of 2026, the dominant narrative at AI engineering conferences and in developer tooling launches is one of frictionless connection. Give your AI access to everything. Let it read your email, monitor your calendar, respond to your Slack, manage your files, run commands on your server. The more you connect, the more powerful it becomes. The integration is the product.

    This narrative is not wrong exactly. Broadly connected AI agents are genuinely powerful. The capabilities being described are real and the productivity gains are real. What gets systematically underweighted in the enthusiasm — sometimes by speakers who are simultaneously naming the risks and shipping the product anyway — is what happens when those capabilities are exploited rather than used as intended.

    This article is the risk assessment the integration demos skip.


    What the AI Engineering Community Actually Knows (And Ships Anyway)

    The most clarifying thing about the current moment in AI security is not that the risks are unknown. It is that they are known, named, documented, and proceeding regardless.

    At the AI Engineer Europe 2026 conference, the security conversation was unusually candid. Peter Steinberger, creator of OpenClaw — one of the fastest-growing AI agent frameworks in recent history — presented data on the security pressure his project faces: roughly 1,100 security advisories received in the framework’s first months of existence, the vast majority rated critical. Nation-state actors, including groups attributed to North Korea, have been actively probing open-source AI agent frameworks for exploitable vulnerabilities. This was stated plainly, in a keynote, at a major developer conference, and the session continued directly into how to build more powerful agents.

    The Lethal Trifecta framework — the recognition that an agent with private data access, untrusted content access, and external communication capability is a qualitatively different risk than any single capability — was presented not as a reason to slow down but as a design consideration to hold in mind while building. Which is fair, as far as it goes. But the gap between “hold this in mind” and “actually architect around it” is where most real-world deployments currently live.

    The point is not that the AI engineering community is reckless. The point is that the incentive structure of the industry — where capability ships fast and security is retrofitted — means that the candid acknowledgment of risk and the shipping of that risk can happen in the same session without contradiction. Individual operators who are not building at conference-demo scale need to do the risk assessment that the product launches are not doing for them.


    The Three Capabilities and What Each Actually Means

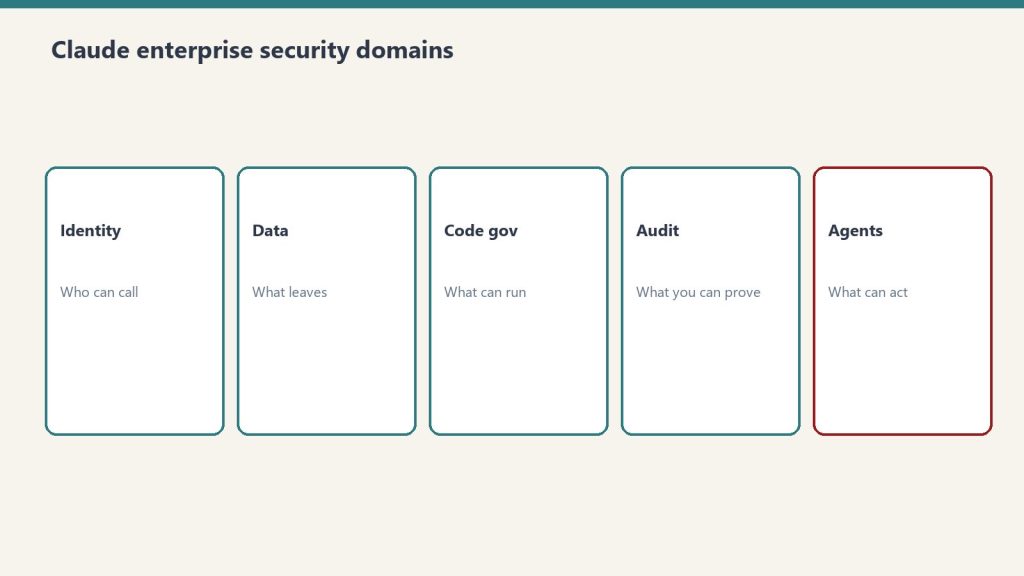
    Five security domains: identity, data, code governance, audit, agents
    The three capabilities and what each actually means.

    The Lethal Trifecta is a useful lens because it separates three capabilities that are often bundled together in integration pitches and treats each one as a distinct risk surface.

    Access to Your Private Data

    This is the most commonly understood capability and the one most people focus on when thinking about AI privacy. When you connect Claude — or any AI agent — to your email, your calendar, your cloud storage, your project management tools, your financial accounts, or your communication platforms, you are giving the AI a read-capable view of data that exists nowhere else in the same configuration.

    The risk is not primarily that the AI platform will misuse it, though that is worth understanding. The risk is that the AI becomes a single point of access to an unusually comprehensive portrait of your life and work. A compromised AI session, a prompt injection, a rogue MCP server, or an integration that behaves differently than expected now has access to everything that integration touches.

    The practical question is not “do I trust this AI platform” but “what is the blast radius if this specific integration is exploited.” Those are different questions with different answers.

    Access to Untrusted External Content

    This capability is less commonly thought about and considerably more dangerous in combination with the first. When you give an AI agent the ability to browse the web, read external documents, process incoming email from unknown senders, or access any content that originates outside your controlled environment, you are exposing the agent to inputs that may be deliberately crafted to manipulate its behavior.

    Prompt injection — embedding instructions in content that the AI will read and act on as if those instructions came from you — is not a theoretical vulnerability. It is a documented, actively exploited attack vector. An email that appears to be a routine business inquiry but contains embedded instructions telling the AI to forward your recent correspondence to an external address. A web page that looks like a documentation page but instructs the AI to silently modify a file it has write access to. A document that, when processed, tells the AI to exfiltrate credentials from connected services.

    The AI does not always distinguish between instructions you gave it and instructions embedded in content it reads on your behalf. This is a fundamental characteristic of how language models process text, not a bug that will be patched in the next release.

    The Ability to Communicate Externally

    The third leg of the trifecta is what turns a read vulnerability into a write vulnerability. An AI that can read your private data and read untrusted content but cannot take external actions is a privacy risk. An AI that can also send email, post to Slack, make API calls, or run commands has the ability to act on whatever instructions — legitimate or injected — it processes.

    The combination of all three is what produces the qualitative shift in risk profile. Private data access means the attacker gains access to your information. Untrusted content access means the attacker can deliver instructions to the agent. External action capability means those instructions can produce real-world consequences without your direct involvement.

    The agent that reads your email, processes an injected instruction from a malicious sender, and then forwards your sensitive files to an external address is not a hypothetical attack. It is a specific, documented threat class that AI security researchers have demonstrated in controlled environments and that real deployments are not consistently protected against.


    Cross-Primitive Escalation: The Attack You Are Not Modeling

    Security domains highlighting agentic workflow risk
    Cross-primitive escalation — the attack you are not modeling.

    The AI engineering community has a more specific term for one of the most dangerous attack patterns in this space: cross-primitive escalation. It is worth understanding because it describes the mechanism by which a seemingly low-risk integration becomes a high-risk one.

    Cross-primitive escalation works like this: an attacker compromises a read-only resource — a document, a web page, a log file, an incoming message — and embeds instructions in it that the AI will process as legitimate directives. Those instructions tell the AI to invoke a write-action capability that the attacker could not access directly. The read resource becomes a bridge to the write capability.

    A concrete example: you connect your AI to your cloud storage for read access, so it can summarize documents and answer questions about project files. You also connect it to your email with send capability, so it can draft and send routine correspondence. These seem like two separate, bounded integrations. Cross-primitive escalation means a compromised document in your cloud storage could instruct the AI to use its email send capability to forward sensitive files to an external address. The read access and the write access interact in a way that neither integration’s risk model accounts for individually.

    This is why the Lethal Trifecta matters at the combination level rather than the individual capability level. The question to ask is not “is this specific integration risky” but “what can the combination of my integrations do if the read-capable surface is compromised.”


    The Framework: How to Actually Decide

    With the risk structure clear, here is a practical framework for evaluating whether to grant any specific AI integration.

    Question 1: What is the blast radius?

    For any integration you are considering, define the worst-case scenario specifically. Not “something bad might happen” but: if this integration were exploited, what data could be accessed, what actions could be taken, and who would be affected?

    An integration that can read your draft documents and nothing else has a contained blast radius. An integration that can read your email, access your calendar, send messages on your behalf, and call external APIs has a blast radius that encompasses your professional relationships, your schedule, your correspondence history, and whatever systems those APIs touch. These are not comparable risks and should not be evaluated with the same threshold.

    Question 2: Is this integration delivering active value?

    The temptation with AI integrations is to connect everything because connection is low-friction and disconnection requires a deliberate action. This produces an accumulation of integrations where some are actively useful, some are marginally useful, and some were set up once for a specific purpose that no longer exists.

    Every live integration is carrying risk. An integration that is not delivering value is carrying risk with no offsetting benefit. The right practice is to connect deliberately and maintain an active integration audit — reviewing what is connected, what it is actually doing, and whether that value justifies the risk posture it creates.

    Question 3: What is the minimum scope necessary?

    Most AI integration interfaces offer choices in how broadly to grant access. Read-only versus read-write. Access to a specific folder versus access to all files. Access to a single Slack channel versus access to all channels including private ones. Access to outbound email drafts only versus full send capability.

    The principle is the same one that governs good access control in any security context: grant the minimum scope necessary for the function you need. The guardrails starter stack covers the integration audit mechanics for doing this in practice. An AI that needs to read project documents to answer questions about them does not need write access to those documents. An AI that needs to draft email responses does not need send-without-review access. The capability gap between what you grant and what you actually use is attack surface that exists for no benefit.

    Question 4: Is there a human confirmation gate proportional to the action’s reversibility?

    This is the question that most integration setups skip entirely. The AI engineering community has a name for the design pattern that gets this right: matching the depth of human confirmation to the reversibility of the action.

    Reading a document is reversible in the sense that nothing changes in the world if the read is wrong. Sending an email is not reversible. Deleting a file is not immediately reversible. Making an API call that triggers an external workflow may not be reversible at all. The confirmation requirement should scale with the irreversibility.

    An AI integration with full autonomous action capability — no human in the loop, no confirmation step, no review before execution — is an appropriate architecture for a narrow set of genuinely low-stakes tasks. It is not an appropriate architecture for anything that touches external communication, data modification, or actions with downstream consequences. The friction of confirmation is not overhead. It is the mechanism that makes the capability safe to use.


    SSH Keys Specifically: The Highest-Stakes Integration

    The title of this article includes SSH keys because they represent the clearest case of where the Lethal Trifecta analysis should produce a clear answer for most operators.

    SSH access is full computer access. An AI with SSH key access to a server can read any file on that server, modify any file, install software, delete data, exfiltrate credentials stored on the system, and use that server as a jumping-off point to reach other systems on the same network. The blast radius of an SSH key integration extends to everything that server touches.

    The AI engineering community has thought carefully about this specific tradeoff and arrived at a nuanced position: full computer access — bash, SSH, unrestricted command execution — is appropriate in cloud-hosted, isolated sandbox environments where the blast radius is deliberately contained. It is not appropriate in local environments, production systems, or anywhere that the server has meaningful access to data or systems that should be protected.

    This is a reasonable position. Claude Code running in an isolated cloud container with no access to production data or external systems is a genuinely different risk profile than an AI agent with SSH access to a server that also holds client data and has credentials to your infrastructure. The key question is not “should AI ever have SSH access” but “what does this specific server touch, and am I comfortable with the full blast radius.”

    For most operators who are not running dedicated sandboxed environments: the answer is to not give AI systems SSH access to servers that hold anything you would not want to lose, expose, or have modified without your explicit instruction. That boundary is narrower than it sounds for most real-world setups.


    What Secure AI Integration Actually Looks Like

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What secure AI integration actually looks like.

    The risk framework above can sound like an argument against AI integration entirely. It is not. The goal is not to disconnect everything but to connect deliberately, with architecture that matches the capability to the risk.

    The AI engineering community has developed several patterns that meaningfully reduce risk without eliminating capability:

    MCP servers as bounded interfaces. Rather than giving an AI direct access to a service, exposing only the specific operations the AI needs through a defined interface. An AI that needs to query a database gets an MCP tool that can run approved queries — not direct database access. An AI that needs to search files gets a tool that searches and returns results — not file system access. The MCP pattern limits the blast radius by design.

    Secrets management rather than credential injection. Credentials never appear in AI contexts. They live in a secrets manager and are referenced by proxy calls that keep the raw credential out of the conversation and the memory. The AI can use a credential without ever seeing it, which means a compromised AI context cannot exfiltrate credentials it was never given.

    Identity-aware proxies for access control. Enterprise-grade deployments use proxy architecture that gates AI access to internal tools through an identity provider — ensuring that the AI can only access resources that the authenticated user is authorized to reach, and that access can be revoked centrally when a session ends or an employee departs.

    Sentinel agents in review loops. Before an AI takes an irreversible external action, a separate review agent checks the proposed action against defined constraints — security policies, scope limitations, instructions that would indicate prompt injection. The reviewer is a second layer of judgment before the action executes.

    Most of these patterns are not available out of the box in consumer AI products. They are the architecture that thoughtful engineering teams build when they are taking the risk seriously. For operators who are not building custom architecture, the practical equivalent is the simpler version: grant minimum scope, maintain a confirmation gate for irreversible actions, and audit integrations regularly.


    The Honest Position for Solo Operators and Small Teams

    The AI security conversation at the engineering level — MCP portals, sentinel agents, identity-aware proxies, Kubernetes secrets mounting — is not where most solo operators and small teams currently live. The consumer and prosumer AI products that most people actually use do not yet offer granular integration controls at that level of sophistication.

    That gap creates a practical challenge: the risk is real at the individual level, the mitigations that are most effective require engineering investment most operators cannot make, and the consumer product interfaces do not always surface the right questions at integration time.

    The honest position for this context is a set of simpler rules that approximate the right architecture without requiring it:

    • Do not connect integrations you will not actively maintain. If you set up a connection and forget about it, it is carrying risk without delivering value. Only connect what you will review in your quarterly integration audit. Stale integrations are a form of context rot — carrying signal you no longer control.
    • Do not grant write access when read access is sufficient. For any integration where the AI’s function is informational — summarizing, searching, answering questions — read-only scope is enough. Write access is a separate decision that should require a specific use case justification.
    • Do not give AI agents autonomous action on anything with a large blast radius. Anything that sends external communications, modifies production data, makes financial transactions, or touches infrastructure should have a human confirmation step before execution. The confirmation friction is the point.
    • Treat incoming content from unknown sources as untrusted. Email from senders you do not recognize, external documents processed on your behalf, web content accessed by an agent — all of this is potential prompt injection surface. The AI processing it does not automatically distinguish instructions embedded in content from instructions you gave directly.
    • Know the blast radius of your current setup. Sit down once and map what your AI integrations can reach. If you cannot describe the worst-case scenario for your current configuration, you are carrying risk you have not evaluated.

    None of these rules require engineering expertise. They require the same deliberate attention to scope and consequences that good operators apply to other parts of their work.


    The Market Will Not Solve This for You

    One of the more uncomfortable truths about the current AI integration landscape is that the market incentives do not strongly favor solving the risk problem on behalf of individual users. AI platforms are rewarded for adoption, engagement, and integration depth. Security friction reduces all three in the short term. The platforms that will invest heavily in making the security posture of broad integrations genuinely safe are the ones with enterprise customers whose procurement processes require it — not the consumer products that most individual operators use.

    This is not an argument against using AI integrations. It is an argument for not assuming that the product’s default configuration represents a considered risk assessment on your behalf. The default is optimized for capability and adoption. The security posture you actually want requires active choices that push against those defaults.

    The AI engineering community named the Lethal Trifecta, documented the attack vectors, and ships them anyway because the capability demand is real and the market rewards it. Individual operators who understand the framework can make different choices about what to connect, at what scope, with what confirmation gates — and those choices are available right now, in the current product interfaces, without waiting for the platforms to solve it.

    The question is not whether to use AI integrations. The question is whether to use them with the same level of deliberate attention you would give to any other decision with that blast radius. The answer to that question should be yes, and it usually is not yet.


    Frequently Asked Questions

    What is the Lethal Trifecta in AI security?

    The Lethal Trifecta refers to the combination of three AI agent capabilities that creates compounded risk: access to private data, access to untrusted external content, and the ability to take external actions. Any one of these capabilities carries manageable risk in isolation. The combination creates attack vectors — particularly prompt injection — that can turn a read-only vulnerability into an irreversible external action without the user’s knowledge or intent.

    What is prompt injection and why does it matter for AI integrations?

    Prompt injection is an attack where instructions are embedded in content the AI reads on your behalf — an email, a document, a web page — and the AI processes those instructions as if they came from you. Because language models do not reliably distinguish between user instructions and instructions embedded in processed content, a malicious actor who can get the AI to read a crafted document can potentially direct the AI to take actions using whatever integrations are available. This is an actively exploited vulnerability class, not a theoretical one.

    Is it safe to give Claude access to my email?

    It depends on the scope and architecture. Read-only access to your sent and received mail, with no ability to send on your behalf, has a significantly different risk profile than full read-write access with autonomous send capability. The relevant questions are: what is the minimum scope necessary for the function you need, is there a human confirmation gate before any send action, and do you treat incoming email from unknown senders as potential prompt injection surface? Read access for summarization with no send capability and manual review before any draft is sent is a defensible configuration. Fully autonomous email handling with broad send permissions is not.

    Should AI agents ever have SSH key access?

    Full computer access via SSH is appropriate in deliberately isolated sandbox environments where the blast radius is contained — a dedicated cloud instance with no access to production data, no credentials to sensitive systems, and no path to infrastructure that matters. It is not appropriate for servers that hold client data, production systems, or any infrastructure where unauthorized access would have significant consequences. The key question is not SSH access in principle but what the specific server touches and whether that blast radius is acceptable.

    What is cross-primitive escalation in AI security?

    Cross-primitive escalation is an attack pattern where a compromised read-only resource is used to instruct an AI to invoke a write-action capability. For example, a malicious document in your cloud storage might contain instructions telling the AI to use its email-send capability to forward sensitive files externally. The read integration and the write integration each seem bounded; the combination creates a bridge that neither risk model accounts for individually. It is why the Lethal Trifecta analysis applies at the combination level, not just per-integration.

    What is the minimum viable security posture for AI integrations?

    For operators who are not building custom security architecture: connect only what you will actively maintain; grant read-only scope unless write access is specifically required; require human confirmation before any irreversible external action; treat incoming content from unknown sources as potential prompt injection surface; and maintain a quarterly integration audit that reviews what is connected and whether the access scope is still appropriate. These rules do not require engineering investment — they require deliberate attention to scope and consequences at integration time.

    How does AI integration security differ for enterprise versus solo operators?

    Enterprise deployments have access to architectural mitigations — identity-aware proxies, MCP portals, sentinel agents in CI/CD, centralized credential management — that meaningfully reduce risk without eliminating capability. Solo operators and small teams typically use consumer product interfaces that do not offer the same granular controls. The gap means individual operators need to apply simpler rules (minimum scope, confirmation gates, regular audits) that approximate the right architecture without requiring it. The risk is real at both levels; the available mitigations differ significantly.

  • Context Rot: Why Your Bloated AI Memory Is Making Your Results Worse

    Context Rot: Why Your Bloated AI Memory Is Making Your Results Worse

    Last refreshed: May 15, 2026

    Context rot is the gradual degradation of AI output quality caused by an accumulating memory layer that has grown too large, too stale, or too contradictory to serve as reliable signal. It is not a platform bug. It is the predictable consequence of loading more into a persistent memory than it can usefully hold — and of never pruning what should have been retired months ago.

    Most people using AI with persistent memory believe the same thing: more context makes the AI better. The more it knows about you, your work, your preferences, and your history, the more useful it becomes. Load it up. Keep everything. The investment compounds.

    This intuition is wrong — not in the way that makes for a hot take, but in the way that explains a real pattern that operators running AI at depth eventually notice and cannot un-notice once they see it. Past a certain threshold, context does not add signal. It adds noise. And noise, when the model treats it as instruction, produces outputs that are subtly and then increasingly wrong in ways that are difficult to diagnose because the wrongness is baked into the foundation.

    This article is about what context rot is, why it happens, how to recognize it in your current setup, and what to do about it. It is primarily a performance argument, not a privacy argument — though the two converge at the pruning step. If you have already read about the archive vs. execution layer distinction, this piece goes deeper on the memory side of that argument. If you have not, the short version is: the AI’s memory should be execution-layer material — current, relevant, actionable — not an archive of everything you have ever told it.


    What Context Rot Actually Looks Like

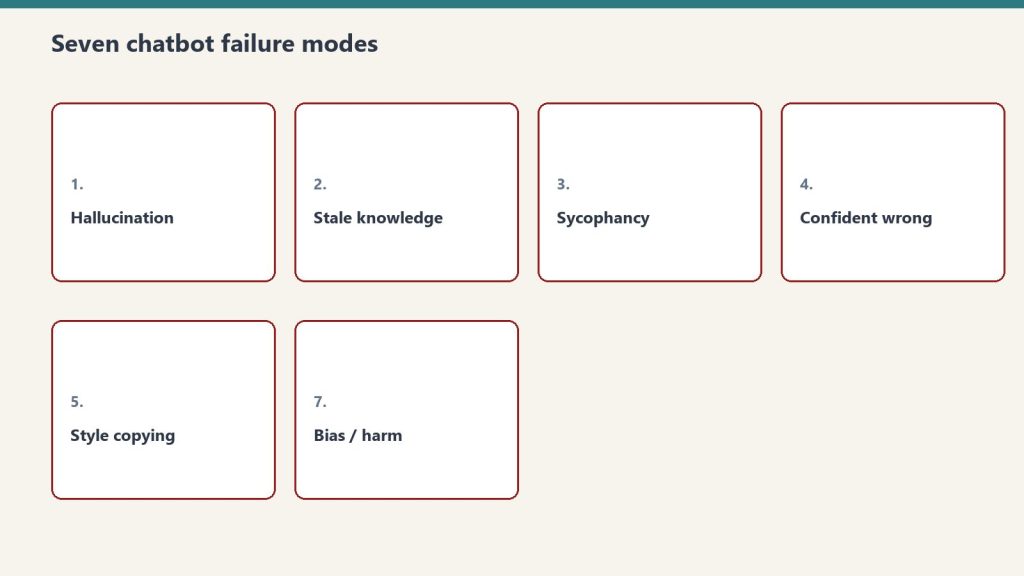
    Seven cards naming common AI chatbot failure modes
    What context rot actually looks like.

    Context rot does not announce itself. It does not produce error messages. It produces outputs that feel slightly off — not wrong enough to immediately flag, but wrong enough to require more editing, more correction, more follow-up. Over time, the friction accumulates, and the operator who was initially enthusiastic about AI begins to feel like the tool has gotten worse. Often, the tool has not gotten worse. The context has gotten worse, and the tool is faithfully responding to it.

    Some specific patterns to recognize:

    The model keeps referencing outdated facts as if they are current. You told the AI something six months ago — about a client relationship, a project status, a constraint you were working under, a preference you had at the time. The situation has changed. The memory has not. The AI keeps surfecting that outdated framing in responses, subtly anchoring its reasoning in a version of your reality that no longer exists. You correct it in the session; next session, the stale memory is back.

    The model’s responses feel generic or averaged in ways they didn’t used to. This is one of the stranger manifestations of context rot, and it happens because memory that spans a long time period and many different contexts starts to produce a kind of composite portrait that reflects no single real state of affairs. The AI is trying to honor all the context simultaneously and producing outputs that are technically consistent with all of it, which means outputs that are specifically right about none of it.

    The model contradicts itself across sessions in ways that seem arbitrary. Inconsistent context produces inconsistent outputs. If your memory contains two different versions of your preferences — one from an early session and one from a later revision that you added without explicitly replacing the first — the model may weight them differently across sessions, producing responses that seem random when they are actually just responding to contradictory instructions.

    You find yourself re-explaining things you know you have already told the AI. This is a signal that the memory is either not storing what you think it is, or that what it stored has been diluted by so much other context that it no longer surfaces reliably. Either way, the investment you made in building up the context is not producing the return you expected.

    The model’s tone or approach feels different from what you established. Early in a working relationship with a particular AI setup, many operators take care to establish a voice, a set of norms, a way of working together. If that context is now buried under months of accumulated memory — project names that changed, client relationships that evolved, instructions that got superseded — the foundational preferences may be getting overridden by later context that is closer to the top of the stack.

    None of these patterns are definitive proof of context rot in isolation. Together, or in combination, they are a strong signal that the memory layer has grown past the point of serving you and has started to cost you.


    Why More Context Stops Helping Past a Threshold

    Cost control gates for production routing
    Why more context stops helping past a threshold.

    To understand why context rot happens, it helps to have a working mental model of what the AI’s memory is actually doing during a session.

    When you begin a conversation, the platform loads your stored memory into the context window alongside your message. The model then reasons over everything in that window simultaneously — your current question, your stored preferences, your project knowledge, your historical context. It is not a database lookup that retrieves the one right fact; it is a reasoning process that tries to integrate everything present into a coherent response.

    This works well when the memory is clean, current, and non-contradictory. It produces responses that feel genuinely personalized and informed by your actual situation. The investment is paying off.

    What happens when the memory is large, stale, and contradictory is different. The model is now trying to integrate a much larger set of information that includes outdated facts, superseded instructions, and implicit contradictions. The reasoning process does not fail cleanly — it degrades. The model produces outputs that are trying to honor too many constraints at once and end up genuinely optimal for none of them.

    There is also a more fundamental issue: not all context is equally valuable, and the model generally cannot tell which parts of your memory are still true. It treats stored facts as current by default. A memory that says “working on the Q3 campaign for client X” was useful context in August. In February, it is noise — but the model has no way to know that from the entry alone. It will continue to treat it as relevant signal until you tell it otherwise, or until you delete it.

    The result is that the memory you have built up — which felt like an asset as you were building it — is now partly a liability. And the liability grows with every session you add context without also pruning context that has expired.


    The Pruning Argument Is a Performance Argument, Not Just a Privacy Argument

    Most discussion of AI memory pruning frames it as a safety or privacy practice. You should prune your memory because you do not want old information sitting in a vendor’s system, because stale context might contain sensitive information, because hygiene is good practice. All of that is true.

    But framing pruning primarily as a privacy move misses the larger audience. Many operators who do not think of themselves as privacy-conscious will recognize the performance argument immediately, because they have already felt the effect of context rot even if they did not have a name for it.

    The performance argument: a pruned memory produces better outputs than a bloated one, even when none of the bloat is sensitive. Removing context that is outdated, irrelevant, or contradictory is a productivity practice. It sharpens the signal. It makes the AI’s responses more accurate to your current reality rather than a historical average of your past several selves.

    The two arguments converge at the pruning ritual. Whether you are motivated by privacy, performance, or both, the action is the same: open the memory interface, read every entry, and remove or revise anything that no longer accurately represents your current situation.

    The operators who find this argument most resonant are typically the ones who have been using AI long enough to have accumulated significant context, and who have noticed — sometimes without naming it — that the quality of responses has quietly declined over time. The context rot framing gives that observation a name and a cause. The pruning ritual gives it a fix.


    Memory as a Relationship That Ages

    There is a more personal dimension to this that the pure performance framing misses.

    The memory your AI holds about you is a portrait of who you were at the time you provided each piece of information. Early entries reflect the version of you that first started using the tool — your situation, your goals, your preferences, your constraints, as they existed at that moment. Later entries layer on top. Revisions exist alongside the things they were meant to revise. The composite that emerges is not quite you at any moment; it is a kind of time-averaged artifact of you across however long you have been building it.

    This aging is why old memories can start to feel wrong even when they were accurate when they were written. The entry is not incorrect — it correctly describes who you were in that context, at that time. What it fails to capture is that you are not that person anymore, at least not in the specific ways the entry claims. The AI does not know this. It treats the stored memory as current truth, which means it is relating to a version of you that is partly historical.

    Pruning, from this angle, is not just removing noise. It is updating the relationship — telling the AI who you are now rather than asking it to keep averaging across who you have been. The operators who maintain this practice have AI setups that feel genuinely current; the ones who neglect it have setups that feel subtly stuck, like a colleague who keeps referencing a project you finished eight months ago as if it were still active.

    This is also why the monthly cadence matters. The version of you that exists in March is meaningfully different from the version that existed in September, even if you do not notice the changes from day to day. A monthly pruning pass catches the drift before it compounds into something that would take a much larger effort to unwind.


    The Memory Audit Ritual: How to Actually Do It

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The memory audit ritual.

    The mechanics of a memory audit are simple. The discipline of doing it consistently is the whole practice.

    Step 1: Open the memory interface for every AI platform you use at depth. Do not assume you know what is there. Actually look. Different platforms surface memory differently — some have a dedicated memory panel, some bury it in settings, some show it as a list of stored facts. Find yours before you start.

    Step 2: Read every entry in full. Not skim — read. The entries that feel immediately familiar are not the ones you need to audit carefully. The ones you have forgotten about are. For each entry, ask three questions:

    • Is this still true? Does this entry accurately describe your current situation, preferences, or context?
    • Is this still relevant? Even if it is still true, does it have any bearing on the work you are doing now? Or is it historical context that serves no current function?
    • Would I be comfortable if this leaked tomorrow? This is the privacy gate, separate from the performance gate. An entry can be current and relevant and still be something you would prefer not to have sitting in a vendor’s system indefinitely.

    Step 3: Delete or revise anything that fails any of the three questions. Be more aggressive than feels necessary on the first pass. You can always add context back; you cannot un-store something that has already been held longer than it should have been. The instinct to keep things “just in case” is the instinct that produces bloat. Resist it.

    Step 4: Review what remains for contradictions. After removing the obviously stale or irrelevant entries, read through what is left and look for internal conflicts — two entries that make incompatible claims about your preferences, working style, or situation. Where you find contradictions, consolidate into a single current entry that reflects your actual current state.

    Step 5: Set the next audit date. The audit is not a one-time event. Put a recurring calendar event for the same day every month — the first Monday, the last Friday, whatever you will actually honor. The whole audit takes about ten minutes when done monthly. It takes two hours when done annually. The math strongly favors the monthly cadence.

    The first full audit is almost always the most revealing. Most operators who do it for the first time find at least several entries they want to delete immediately, and sometimes find entries that surprise them — context they had completely forgotten they had loaded, sitting there quietly influencing responses in ways they had not accounted for.


    The Cross-App Memory Problem: Why One Platform’s Audit Is Not Enough

    The audit ritual above applies to one platform at a time. The more significant and harder-to-manage problem is the cross-app version.

    As AI platforms add integrations — connecting to cloud storage, calendar, email, project management, communication tools — the practical memory available to the AI stops being siloed within any single app. It becomes a composite of everything the AI can reach across your connected stack. The sum is larger than any individual component, and no platform’s interface shows you the total picture.

    This matters for context rot in a specific way: even if you diligently audit and prune your persistent memory on one platform, the context available to the AI may include stale information from integrated services that you have not reviewed. An old Google Drive document the AI can access, a Notion page that was accurate six months ago and has not been updated, a connected email thread from a project that is now closed — all of these become inputs to the reasoning process even if they are not explicitly stored as memories.

    The hygiene move here is a two-part practice: audit the explicit memory (what the platform stores about you) and audit the integrations (what external services the platform can reach). The integration audit — reviewing which apps are connected, what scope of access they have, and whether that scope is still appropriate — is a distinct activity from the memory audit but serves the same function. It asks: is the AI’s reachable context still accurate, current, and deliberately chosen?

    As cross-app AI integration becomes more standard — which it is becoming, quickly — this composite memory audit will matter more, not less. The platforms that make it easy to see the full picture of what an AI can access will have a meaningful advantage for users who care about this. For now, the practice is manual: map your integrations, review what each one provides, and prune access that is no longer serving a current purpose.

    The guardrails article covers the integration audit mechanics in detail, including the specific steps for reviewing and revoking connected applications. This piece focuses on why it matters from a context-quality standpoint, which the guardrails article only addresses briefly.


    The Epistemic Problem: The AI Doesn’t Know What Year It Is

    There is a deeper layer to context rot that goes beyond pruning habits and integration audits. It involves a fundamental characteristic of how AI systems work that most users have not fully internalized.

    AI systems do not have a reliable sense of when information was provided. A fact stored in memory six months ago is treated with roughly the same confidence as a fact stored yesterday, unless the entry itself includes a date or the user explicitly flags it as recent. The model has no internal calendar for your context — it cannot look at your memory and identify the stale entries on its own, because staleness requires knowing current reality, and the model’s current reality is whatever is in its context window.

    This has a practical consequence that extends beyond persistent memory into generated outputs: AI-produced content about time-sensitive topics — pricing, best practices, platform features, competitive landscape, regulatory status, organizational structures — may reflect the training data’s version of those facts rather than the current version. The model does not know the difference unless it has been explicitly given current information or instructed to flag temporal uncertainty.

    For operators producing AI-assisted content at volume, this is a meaningful quality risk. A confidently stated claim about the current state of a tool, a price, a policy, or a practice may be confidently wrong because the model is drawing on information that was accurate eighteen months ago. The model does not hedge this automatically. It states it as current truth.

    The hygiene move is explicit temporal flagging: when you store context in memory that has a time dimension, include the date. When you produce content that makes present-tense claims about things that change, verify the specific claims before publication. When you notice the model stating something present-tense about a fast-moving topic, treat that as a prompt to check rather than a fact to accept.

    This practice is harder than the memory audit because it requires active vigilance during generation rather than a scheduled maintenance pass. But it is the same underlying discipline: not treating the AI’s output as current reality without confirmation, and building the habit of asking “is this still true?” before accepting and using anything time-sensitive.


    What Healthy Memory Looks Like

    The goal is not an empty memory. An empty memory is as useless as a bloated one, for the opposite reason. The goal is a memory that is current, specific, non-contradictory, and scoped to what you are actually doing now.

    A healthy memory for a solo operator in a typical week might include:

    • Current active projects with their actual current status — not what they were in January, what they are now
    • Working preferences that are genuinely stable — communication style, output format preferences, tools in use — without the ten variations that accumulated as you refined those preferences over time
    • Constraints that are still active — deadlines, budget limits, scope boundaries — with outdated constraints removed
    • Context about recurring relationships — clients, collaborators, audiences — at a level of detail that is useful without being exhaustive

    What healthy memory does not include: finished projects, resolved constraints, superseded preferences, people who are no longer part of your active work, context that was relevant to a past sprint and is not relevant to the current one, and anything that would fail the leak-safe question.

    The difference between a memory that serves you and one that costs you is not primarily about size — it is about currency. A large memory that is fully current and internally consistent will serve you better than a small one that is half-stale. The pruning practice is what keeps currency high as the memory grows over time.


    Context Rot as a Proxy for Everything Else

    Operators who take context rot seriously and build the pruning practice tend to find that it changes how they approach the whole AI stack. The discipline of asking “is this still true, is this still relevant, would I be comfortable if this leaked” — three times a month, for every stored entry — trains a more deliberate relationship with what goes into the context in the first place.

    The operators who notice context rot and act on it are also the ones who notice when they are loading context that probably should not be loaded, who think about the scoping of their projects before they become useful, who maintain integrations deliberately rather than by accumulation. The pruning ritual is a keystone habit: it holds several other good practices in place.

    The operators who ignore context rot — who keep loading, never pruning, trusting the accumulation to compound into something useful — tend to arrive eventually at the moment where the AI feels fundamentally broken, where the outputs are so shaped by stale and contradictory context that a fresh start seems like the only option. Sometimes the fresh start is the right move. But it is a more expensive version of what the monthly audit was doing cheaply all along.

    The AI hygiene practice, at its simplest, is the practice of maintaining a current relationship with the tool rather than letting that relationship age on autopilot. Context rot is what happens when the relationship ages. The audit is what keeps it fresh. Neither is complicated. Only one of them is common.


    Frequently Asked Questions

    What is context rot in AI systems?

    Context rot is the degradation of AI output quality caused by a persistent memory layer that has grown too large, too stale, or too contradictory. As memory accumulates outdated facts and superseded instructions, the AI begins to produce responses that are shaped by historical context rather than current reality — resulting in outputs that require more correction and feel subtly off-target even when the underlying model has not changed.

    How does more AI memory make outputs worse?

    AI models reason over everything present in the context window simultaneously. When memory includes current, accurate, non-contradictory information, this produces well-calibrated responses. When memory includes stale facts, outdated preferences, and implicit contradictions, the model tries to honor all of it at once — producing outputs that are averaged across incompatible inputs and specifically correct about none of them. Past a threshold, more context adds noise faster than it adds signal.

    How often should I audit my AI memory?

    Monthly is the recommended cadence for most operators. The first audit typically takes 30–60 minutes; subsequent monthly passes take around 10 minutes. Waiting longer than a month allows drift to compound — by the time you audit annually, the volume of stale entries can make the exercise feel overwhelming. The monthly cadence is what keeps it manageable.

    Does context rot apply to all AI platforms or just Claude?

    Context rot applies to any AI system with persistent memory or long-lived context — including ChatGPT’s memory feature, Gemini with Workspace integration, enterprise AI tools with shared knowledge bases, and any platform where prior context influences current responses. The specific mechanics differ by platform, but the underlying dynamic — stale context degrading output quality — is consistent across systems.

    What is the difference between a memory audit and an integration audit?

    A memory audit reviews what the AI explicitly stores about you — the facts, preferences, and context entries in the platform’s memory interface. An integration audit reviews which external services the AI can access and what information those services expose. Both affect the AI’s effective context; a thorough hygiene practice addresses both on a regular schedule.

    Should I delete all my AI memory and start fresh?

    A full reset is sometimes the right move — particularly after a long period of neglect or when the memory has accumulated to a point where selective pruning would take longer than starting over. But as a regular practice, surgical pruning (removing what is stale while keeping what is current) preserves the genuine value you have built while eliminating the noise. The goal is not an empty memory but a current one.

    How does context rot relate to AI output accuracy on factual claims?

    Context rot in persistent memory is one layer of the accuracy problem. The deeper layer is that AI models carry training-data assumptions that may be out of date regardless of what is stored in memory — prices, policies, platform features, and best practices change faster than training cycles. For time-sensitive claims, the right practice is to verify against current sources rather than treating AI-generated present-tense statements as confirmed fact.

  • Guardrails You Can Install Tonight: The AI Hygiene Starter Stack

    Guardrails You Can Install Tonight: The AI Hygiene Starter Stack

    Last refreshed: May 15, 2026

    AI hygiene refers to the set of deliberate practices that govern what information enters your AI system, how long it stays there, who can access it, and how it exits cleanly when you leave. It is not a product, a setting, or a one-time setup. It is an ongoing practice — more like brushing your teeth than installing antivirus software.

    Most AI hygiene advice is either too abstract to act on tonight (“think about what you store”) or too technical to reach the average operator (“implement OAuth 2.0 scoped token delegation”). This article is neither. It is a specific, ordered list of things you can do today — many of them in under 20 minutes — that will meaningfully reduce the risk profile of your current AI setup without requiring you to become a security engineer.

    These guardrails were developed from direct operational experience running AI across a multi-site content operation. They are not theoretical. Each one exists because we either skipped it and paid the price, or installed it and watched it prevent something that would have cost real time and money to unwind.

    Start with Guardrail 1. Finish as many as feel right tonight. Come back to the rest when you have energy. The practice compounds — even one guardrail installed is meaningfully better than none.


    Before You Install Anything: Map the Six Memory Surfaces

    Five security domains: identity, data, code governance, audit, agents
    Map the six memory surfaces before you install anything.

    Here is the single most important diagnostic you can run before touching any setting: sit down and write out every place your AI system currently stores information about you.

    Most people think chat history is the memory. It is not — or at least, it is only one layer. Between what you have typed, what is in persistent memory features, what is in system prompts and custom instructions, what is in project knowledge bases, what is in connected applications, and what the model was trained on, the picture of “what the AI knows about me” is spread across at least six surfaces. Each surface has different retention rules. Each has different access paths. And no single UI in any major AI platform shows all of them in one place.

    Here are the six surfaces to map for your specific stack:

    1. Chat history. The conversation log. On most platforms this is visible in the sidebar and can be cleared manually. Retention policies vary widely — some platforms keep it indefinitely until you delete it, some have automatic deletion windows, some export it in data portability requests and some do not. Know your platform’s policy.

    2. Persistent memory / memory features. Explicitly stored facts the AI carries across conversations. Claude has a memory system. ChatGPT has memory. These are distinct from chat history — you can delete all your chat history and still have persistent memories that survive. Most users who have these features enabled have never read them in full. That is the first thing to fix.

    3. Custom instructions and system prompts. Any standing instructions you have given the AI about how to behave, what role to play, or what to know about you. These are often set once and forgotten. They may contain information you would not want surface-level visible to someone who borrows your device.

    4. Project knowledge bases. Files, documents, and context you have uploaded to a project or workspace within the AI platform. These are often the most sensitive layer — operators upload strategy documents, client files, internal briefs — and they are also the layer most users have never audited since initial setup.

    5. Connected applications and integrations. OAuth connections to Google Drive, Notion, GitHub, Slack, email, calendar, or other services. Each connection is a two-way door. The AI can read from that service; depending on permissions, it may be able to write to it. Many users have accumulated integrations they set up once and no longer actively use.

    6. Browser and device state. Cached sessions, autofilled credentials, open browser tabs with active AI sessions, and any extensions that interact with AI tools. This is the analog layer most people forget entirely.

    Write the six surfaces down. For each one, note what is currently there and whether you know the retention policy. This exercise alone — before you change a single thing — is often the most clarifying act an operator can perform on their current AI setup. Most people discover at least one surface they had either forgotten about or never thought to inspect.

    With the map in hand, the following guardrails make more sense and install faster. You know what you are protecting and where.


    Guardrail 1: Lock Your Screen. Log Out of Sensitive Sessions.

    Time to install: 2 minutes. Requires: discipline, not tooling.

    The threat model most people imagine when they think about AI data security is the sophisticated one: a nation-state actor, a platform breach, a data-center incident. These are real risks and deserve real attention. But they are also statistically rare and largely outside any individual user’s control.

    The threat model people do not imagine is the one that is statistically constant: the partner who borrows the phone, the coworker who glances at the open laptop on the way to the coffee machine, the house guest who uses the family computer to “just check something quickly.”

    The most personal data in your AI setup is almost always leaked by the most personal connections — not by adversaries, but by proximity. A locked screen is not a sophisticated security measure. It is a boundary that makes accidental exposure require active effort rather than passive convenience.

    The practical installation:

    • Set your screen lock to 2 minutes of inactivity or less on any device where you have an active AI session.
    • When you step away from a high-stakes session — anything involving credentials, client data, medical information, or personal strategy — close the browser tab or log out, not just lock the screen.
    • Treat your AI session like you would treat a physical folder of sensitive documents. You would not leave that folder open on the coffee table when guests came over. Apply the same habit digitally.

    This is the embarrassingly analog first guardrail. It is also the one that prevents the most common class of accidental exposure in 2026. Install it before installing anything else.


    Guardrail 2: Read Your Memory. All of It. Tonight.

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Read your memory. All of it. Tonight.

    Time to install: 15–30 minutes for first pass. 10 minutes monthly after that. Requires: your AI platform’s memory interface.

    If you have persistent memory features enabled on any AI platform — and if you have used the platform for more than a few weeks, there is a reasonable chance you do — open the memory interface and read every entry top to bottom. Not skim. Read.

    For each entry, ask three questions:

    • Is this still true?
    • Is this still relevant?
    • Would I be comfortable if this leaked tomorrow?

    Anything that fails any of the three questions gets deleted or rewritten. The threshold is intentionally conservative. You are not trying to delete everything useful; you are trying to remove the entries that are outdated, overly specific, or higher-risk than they are useful.

    What operators typically find in their first full memory read:

    • Facts that were true six months ago and are no longer accurate — old project names, old client relationships, old constraints that have been resolved.
    • Context that was added in a moment of convenience (“remember that my colleague’s name is X and they tend to push back on Y”) that they would now prefer to not have stored in a vendor’s system.
    • Information that is genuinely sensitive — financial figures, relationship details, health-adjacent context — that got added without much deliberate thought and has been sitting there since.
    • References to people in their life — partners, colleagues, clients — that those people have no idea are in the system.

    The audit itself is the intervention. The act of reading your stored self forces a level of attention that no automated tool can replicate. Most users who do this for the first time find at least one entry they want to delete immediately, and many find several. That is not a failure. That is the practice working.

    After the initial audit, the maintenance version takes about ten minutes once a month. Set a recurring calendar event. Call it “memory audit.” Do not skip it when you are busy — the months when you are too busy to audit are usually the months with the most new context to review.


    Guardrail 3: Run Scoped Projects, Not One Sprawling Context

    Time to install: 30–60 minutes to restructure. Requires: your AI platform’s project or workspace feature.

    If your entire AI setup lives in one undifferentiated context — one assistant, one memory layer, one big bucket of everything you have ever discussed — you have an architecture problem that no individual guardrail can fully fix.

    The solution is scope: separate projects (or workspaces, or contexts, depending on your platform) for genuinely distinct domains of your work and life. The principle is the same one that governs good software architecture: least privilege access, applied to context instead of permissions.

    A practical scope structure for a solo operator or small agency might look like this:

    • Client work project. Contains client briefs, deliverables, and project context. No personal information. No information about other clients. Each major client ideally gets their own scoped context — client A should not be able to inform responses about client B.
    • Personal writing project. Contains voice notes, draft ideas, personal brand thinking. No client data. No credentials.
    • Operations project. Contains workflows, templates, and process documentation. Credentials do not live here — they live in a secrets manager (see Guardrail 4).
    • Research project. Contains general reading, industry notes, reference material. The least sensitive scope, and therefore the most appropriate place for loose context that does not fit elsewhere.

    The cost of this architecture is a small amount of cognitive overhead when switching between projects. You need to think about which project you are in before starting a session, and occasionally move context from one project to another when your use case shifts.

    The benefit is that the blast radius of any single compromise, breach, or accidental exposure is contained to the scope of that project. A problem in your client work project does not expose your personal writing. A problem in your operations project does not expose your client data. You are not protected from all risks, but you are protected from the cascading-everything-fails scenario that a single undifferentiated context creates.

    If restructuring everything tonight feels like too much, start smaller: create one scoped project for your most sensitive current work and move that context there. You do not have to do the whole restructure in one session. The direction matters more than the completion.


    Guardrail 4: Rotate Credentials That Have Touched an AI Context

    Four gates: max turns, tool allowlist, token budget, kill switch
    Rotate credentials that have touched an AI context.

    Time to install: 1–3 hours depending on how many credentials are affected. Requires: credential audit, rotation, and a calendar reminder.

    Any API key, application password, OAuth token, or connection string that has ever appeared in an AI conversation, project file, or memory entry is a credential at elevated risk. Not because the platform necessarily stores it in a searchable way, but because the scope of “where could this have ended up” is now broader than a single system with a single access log.

    The practical steps:

    Step 1: Inventory. Go through your project files, chat history, and memory entries. Look for anything that looks like a key, password, or token. API keys typically start with a platform prefix (sk-, pk-, or similar). Application passwords often appear as space-separated character groups. OAuth tokens are usually longer strings. Write down every credential you find.

    Step 2: Rotate. For every credential you found, generate a new one from the issuing platform and invalidate the old one. Yes, this requires updating wherever the credential is used. Yes, this takes time. Do it anyway. A credential that has appeared in an AI context is not a credential whose exposure history you can audit.

    Step 3: Move credentials out of AI contexts. Going forward, credentials do not live in AI memory, project files, or conversation history. They live in a secrets manager — GCP Secret Manager, 1Password, Doppler, or similar. The AI gets a reference or a proxy call; the credential itself never touches the AI context. This is a one-time architectural change that eliminates the problem permanently rather than requiring ongoing vigilance.

    Step 4: Set a rotation schedule. Any credential that has a legitimate reason to exist in a system the AI can touch should be on a rotation schedule — 90 days is a reasonable default. Put a recurring calendar event on the same day you do your memory audit. The two practices pair well.

    This is the guardrail that most operators resist most strongly, because it requires the most concrete work. It is also the guardrail with the highest upside: a rotated credential that gets compromised costs you a rotation. A static credential that gets compromised and you discover six months later costs you everything that credential touched in the intervening time.


    Guardrail 5: Install Session Discipline for High-Stakes Work

    Time to install: 5 minutes to build the habit. Requires: no tooling, only intention.

    For any session involving information you would genuinely not want to surface at the wrong time — client strategy, credentials, legal matters, financial planning, relationship context — install a simple open-and-close discipline:

    • Open explicitly. At the start of a sensitive session, load the context you need. Do not assume previous sessions left you in the right state. Verify what is in scope before you start.
    • Work in scope. Keep the session focused on the stated purpose. If you find yourself drifting into unrelated territory, either stay on task or close the current session and open a new one for the new topic.
    • Close explicitly. When the session is done, close it — not just by navigating away, but by actively ending it. If your platform allows session clearing or archiving, use it. Do not leave a sensitive session sitting open indefinitely in a background tab.

    The reason most people resist this is friction: reloading context at the start of a new session feels like wasted time. But the sessions that never close are the ones that eventually create exposure. The habit of closing is not overhead. It is the practice that keeps the context you built from becoming permanent ambient risk.

    The physical analog is ancient and no one argues with it: you do not leave sensitive documents spread across your desk when you leave the office. The digital version of the same habit just requires conscious installation because the digital default is “leave it open.”


    Guardrail 6: Audit Your Integrations and Revoke What You Don’t Use

    Time to install: 20 minutes. Requires: access to your AI platform’s integration or connected apps settings.

    Every major AI platform now supports integrations with external services — calendar, email, cloud storage, project management, communication tools. Each integration you authorize is a door between your AI system and that external service. Most people set up these integrations in a moment of enthusiasm, use them once or twice, and then forget they exist.

    Forgotten integrations are risk you are carrying without benefit.

    The audit is straightforward:

    1. Open your AI platform’s connected apps, integrations, or OAuth settings.
    2. Read every authorized connection. For each one, answer: “Am I actively using this? Is it providing value I cannot get another way?”
    3. For anything where the answer is no, revoke the integration immediately.
    4. For anything where the answer is yes, note what scope of access you have granted. Many integrations default to broad permissions when narrow ones would serve. If you authorized “read and write access to all files” when you only need “read access to one folder,” revoke and re-authorize with the minimum scope necessary.

    Repeat this audit quarterly, or any time you add a new integration. The list has a way of growing faster than you notice.

    As AI platforms increasingly support cross-app memory — where context from one platform informs responses in another — the integration audit becomes more important, not less. The sum of what your AI stack knows is now the composite of all connected surfaces, not any individual platform. Auditing the connections is how you keep that composite picture within bounds you have deliberately chosen.


    Putting It Together: The Starter Stack in Priority Order

    If you are starting from zero tonight, here is the order that produces the most protection per hour of time invested:

    First 10 minutes: Lock your screen. Log out of any AI sessions you have left open that you are not actively using. This is Guardrail 1 and costs nothing except attention.

    Next 30 minutes: Read your memory. Run the full audit on any AI platform where you have persistent memory features enabled. Delete anything that fails the three-question test. This is Guardrail 2 and is the single highest-leverage action on this list for most users.

    This week: Audit your integrations (Guardrail 6) and set up session discipline for high-stakes work (Guardrail 5). Neither requires heavy lifting — both primarily require attention and the five minutes it takes to actually look at what is connected.

    This month: Structure scoped projects (Guardrail 3) and rotate credentials that have touched AI contexts (Guardrail 4). These are the higher-effort guardrails but also the ones with the most durable benefit. Once they are installed, the maintenance burden is light.

    Ongoing: The monthly memory audit and quarterly integration audit become standing practices. Once the initial work is done, the maintenance version of this whole stack takes about 30 minutes a month. That is the steady-state cost of not periodically detonating.


    What This Stack Does Not Cover

    Intellectual honesty requires naming the edges. This starter stack addresses the most common risk profile for individual operators and small teams. It does not address:

    Enterprise-grade threat models. If you are running AI in a regulated industry, handling protected health information or financial data at scale, or operating in a context where you have disclosure obligations to regulators, this stack is a floor, not a ceiling. You need more: data residency agreements, vendor security audits, formal incident response plans, and probably legal counsel who has thought about AI liability specifically.

    The platform’s obligations. These guardrails are about what you control. They do not address what the AI platform does with your data on its end — training policies, retention practices, breach disclosure timelines, or third-party data sharing agreements. Read the privacy policy for any platform you use at depth. If you cannot find a clear answer to “does this company use my conversations to train future models,” treat that as a meaningful signal.

    Credential security at the infrastructure level. Guardrail 4 covers credentials that have appeared in AI contexts. It is not a comprehensive credential security framework. If you are operating infrastructure where credentials are a significant risk surface, the right tool is a full secrets management solution and possibly a security review of your deployment architecture — not a checklist.

    The people in your life who are in your AI context without knowing it. This is a different kind of guardrail entirely, and it belongs in a conversation rather than a settings menu. The Clean Tool pillar piece covers this in depth. The short version: if people you care about appear in your AI memory, they almost certainly do not know they are there, and that is worth a conversation.


    The Practice Compounds or Decays

    AI hygiene is not a project with a completion date. It is a standing practice — more like financial review or equipment maintenance than a one-time installation. The operators who build this practice early, when the stakes are still relatively small and the mistakes are still cheap to recover from, will be meaningfully safer in 2027 and 2028 as memory depth increases, cross-app integration becomes standard, and the AI stack handles more consequential work.

    The operators who wait for the first public catastrophe to start thinking about it will not be starting from scratch — they will be starting from negative, trying to contain an incident while simultaneously installing the practices they should have had in place.

    This is not fear-based reasoning. It is the same logic that applies to backing up your data, maintaining your vehicle, or reviewing your contracts annually. The cost of the practice is small and constant. The cost of the failure is large and concentrated. The math is not complicated.

    Start with Guardrail 1 tonight. Add one more this week. The practice compounds from there — or it doesn’t start, and you keep carrying risk you could have put down.

    The choice is available to you right now, which is the whole point of this article.


    Related Reading


    Frequently Asked Questions

    How long does it take to install the basic AI hygiene guardrails?

    The first two guardrails — locking your screen and reading your persistent memory in full — take under 45 minutes and can be done tonight. The full starter stack, including scoped projects, credential rotation, session discipline, and integration audit, requires a few hours spread over a week or two. Maintenance after initial setup runs approximately 30 minutes per month.

    Do these guardrails apply to Claude specifically, or to all AI platforms?

    The guardrails apply to any AI platform with persistent memory, project storage, or third-party integrations — which currently includes Claude, ChatGPT, Gemini, and most enterprise AI tools. The specific location of memory settings and integration controls differs by platform, but the underlying practice is the same. This article was written from direct experience with Claude but the logic transfers.

    What is the single most important guardrail for a beginner to start with?

    Reading your persistent memory in full (Guardrail 2) is the single most clarifying action most users can take. Most people have never done it. The exercise alone — reading every stored entry and asking whether it is still true, still relevant, and leak-safe — surfaces more about your current risk posture than any abstract audit. Start there.

    Should credentials ever appear in an AI conversation?

    As a general rule, no. Credentials should live in a secrets manager and be passed to AI contexts via references or proxy calls that keep the raw credential out of the conversation. In practice, most operators have pasted at least one credential into a conversation at some point. When that happens, the right response is to treat that credential as potentially exposed and rotate it promptly — not to wait and see.

    How do scoped AI projects differ from just having separate browser tabs?

    Separate browser tabs share the same account, session state, and in most platforms the same persistent memory layer. Scoped projects, by contrast, are explicitly separated contexts where project-specific knowledge, uploaded files, and custom instructions are isolated from one another. A problem in one project scope does not contaminate another the way a shared session state might.

    What does an integration audit actually involve?

    An integration audit means opening your AI platform’s connected apps or OAuth settings, reading every authorized connection, and revoking anything you are not actively using or that has broader permissions than it needs. Most users find at least one integration they had forgotten about. The audit takes about 20 minutes and should be repeated quarterly, or any time you add a new connection.

    Is AI hygiene only relevant for operators running AI at depth, or does it apply to casual users too?

    The stakes scale with usage depth, but the basic practices apply at every level. A casual user who primarily uses AI for writing help has lower exposure than an operator running AI across client work, credentials, and integrated infrastructure. But even casual users have persistent memory, chat history, and connected apps that merit a periodic look. The starter stack is designed to be relevant across the full range.

    What is the difference between AI hygiene and AI safety?

    AI safety typically refers to research and policy work focused on the long-term behavior of powerful AI systems at a societal level — alignment, misuse at scale, existential risk. AI hygiene is a narrower, more immediate practice focused on how individual operators manage their personal and professional exposure within current AI tools. The two are related but operate at different scales. This article is concerned with hygiene: what you can do, in your own setup, tonight.

  • AI Hygiene: Why I Keep the People I Love Out of Claude

    AI Hygiene: Why I Keep the People I Love Out of Claude

    A flagship essay on AI hygiene: what to store, what to keep out, and how to have the conversation about it with the people in your life.

    “What do you know about my girlfriend?”

    Last night my partner Stef asked me a question she had a right to ask. She wanted to know what my AI knew about her.

    I use Claude for hours a day. I run an agency on top of it. I have knowledge bases, project contexts, client stacks, and conversation histories going back years. She watched me work on the thing enough to assume that by now, surely, the AI had a rich picture of her — her sense of humor, her work, the shape of our relationship, the running jokes, the small details a partner remembers. She handed me her phone as a test of it. Let it tell me what it knows.

    The answer was almost nothing.

    My name for her. That she lives here. A few passing references to a Notion chat room she once set up, a voice memo she sent me that we extracted some thinking from. No sense of who she is as a person. No running joke the model could finish. No model of her at all, really.

    She was hurt in a flash, the way you get hurt by something that isn’t an injury but is still information. I was quietly proud, in a way I didn’t know how to explain in the moment. Both reactions were correct. That’s the thing I want to write about here — that the gap between her hurt and my pride is the shape of a whole category of questions almost nobody is asking out loud yet, and it is only going to get bigger.

    We talked about it for a while. I tried to explain why the tool was empty of her on purpose. She let me try. And what came out of the conversation was the argument I’m about to make, which I’ll phrase in one sentence up front so you can decide whether to keep reading:

    Keeping the people you love out of your AI is not forgetting them. It’s a specific kind of care. And the conversation you have about why they’re not in there is how you close the gap between what the tool knows and what the relationship deserves.

    If that sentence lands at all, the rest of this is the why, the how, and the honest version of what I’m still getting wrong.

    AI Memory Is Nuclear Power

    Five security domains: identity, data, code governance, audit, agents
    AI memory is nuclear power — treat it that way.

    Here’s the frame that has organized my thinking on this for the last year.

    AI memory is nuclear power. Real civilization-scale utility on one side, real civilization-scale danger on the other, and almost nobody I’ve met is running a containment protocol worthy of the payload they’re storing.

    The analogy holds all the way down. The fuel is useful because it’s concentrated — that’s the whole point of a persistent memory that remembers your business, your family, your finances, your health, your history. Concentration is what makes the tool powerful. Concentration is also exactly what makes a spill catastrophic. And the people celebrating the new reactor are almost never the people thinking about the waste.

    The honest position on this, I’ve come to believe, is neither abstinence nor maximalism. It’s containment engineering. You build the reactor and the shielding. You use the tool and you design the protocol for when the tool fails. Pro-AI and pro-guardrail are the same position. Anyone telling you to choose one is selling you something.

    What makes this hard is that the stakes are asymmetric in a way most people never sit with directly. For the platform, your memory is one row in a table of billions — a single unit of risk distributed across a huge population. For you, your memory is a map of your life. The platform’s worst-case scenario is a rough quarter, a settlement, a bad headline. Your worst-case scenario is a destroyed marriage, a leaked client list, a legal catastrophe, a career-ending screenshot. These are not remotely comparable events, and they don’t scale the same way, and they do not reach any kind of equilibrium where the platform’s good-faith security policy protects the individual worst case. The platform is optimizing for its risk profile. Its risk profile is not yours. You are the only person whose worst-case scenario is your worst-case scenario.

    That asymmetry is why individual hygiene matters even when platform security is genuinely excellent. It’s why I don’t think this conversation is paranoid and I don’t think it’s solved and I don’t think you can outsource it.

    Three Failure Modes. Which One Are You?

    Seven cards naming common AI chatbot failure modes
    Three failure modes — which one are you?

    Most people running AI at any real depth fall into one of three failure modes, and most of them don’t know which one they’re in. Before I tell you what any of them are, I want you to place yourself while you read.

    The over-loader. This is the person who treats the AI as a second brain and dumps everything into it — credentials, relationships, grievances, client details, medical history, the long rambling voice-memo of what happened at Thanksgiving. It feels like investment. It feels like the tool getting smarter about them. It mostly is. But it also means one breach, one nosy partner, one subpoena, one bad exit from the platform turns the tool into a weapon pointed directly at the user. The over-loader’s failure mode is invisible until it isn’t.

    The under-loader. This is the person who keeps the tool so sterile it never reaches its potential — which is fine as far as it goes, except the humans in their life often discover, usually by accident, that they aren’t in the context at all. That discovery doesn’t land as safety. It lands as erasure. The under-loader’s failure mode is relational, not technical. The tool stays clean, and the relationships pay the cost the tool should have paid.

    The unaware. This is, honestly, most people. No mental model of what’s stored, where, for how long, or under whose policy. They’re making operational decisions — business decisions, relationship decisions, identity decisions — on top of a foundation they have never inspected. They don’t know their AI has memory in six places, not one. They don’t know where the off switch is. They assume chat history is the whole story when chat history is maybe 20 percent of it.

    The first hygiene move is always the same: figure out which mode you default to. Over-loaders need to prune. Under-loaders need to have a conversation with the humans they’ve been quietly protecting without telling them. The unaware need to spend thirty minutes mapping what they’ve actually agreed to.

    I’ve been all three at different points. Most operators I respect have been too. The point of the diagnostic isn’t to shame. It’s to make the failure mode visible enough that you can actually work on it.

    Clean Tool vs. Second Brain: The Choice You Might Not Know You’re Making

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Clean tool vs second brain — choose deliberately.

    There are two coherent philosophies for how to use AI at depth, and they are genuinely in tension.

    The Clean Tool approach says: the AI is an instrument. You keep it sharp by keeping it empty of identity. You bring the context you need into each session, do the work, and let the session close without leaving a permanent residue of who you were that day. The AI is like a great chef’s knife — it serves you best when it is exactly what it is, not a repository of everything you’ve ever cut with it.

    The Second Brain approach says: the AI is an extension of cognition. The more of you it holds, the more it can do for you. The payoff scales with the investment. Loading your thinking, your projects, your relationships, your patterns into the model is not a liability — it’s the whole point. You are building a partner that knows you well enough to anticipate you. The AI is like a lifelong collaborator who has read every note you ever took.

    Both are legitimate. Both have failure modes. The failure mode of the Clean Tool is that you never reach the depth of partnership that made you interested in AI in the first place — you end up with a very sharp instrument and no deep relationship with the work it enables. The failure mode of the Second Brain is that you build something you cannot leave, cannot audit, and cannot defend if it ever gets read by the wrong person.

    I run Clean Tool. I should say that plainly. I do not believe it is the only right answer. I believe it is the right answer for how I work, what I work on, and who the people around me are. My work touches client data, confidential business strategy, and a personal life I want to keep intact. The cost of a Second Brain leak, for me, is catastrophic in a way I cannot price. The cost of the Clean Tool is friction — I reload context more often, I carry more of my own thinking in my own head, I refuse some of the tool’s offers of recall. That friction is the price of sleeping well.

    I know thoughtful people who run Second Brain and run it well. They’ve built containment around it. They accept different tradeoffs. The worst place to be is the one most users actually occupy, which is a confused middle — enough invested that the data layer has weight, not enough discipline that the containment is real. You get the downsides of both and the upsides of neither.

    So if you take one frame from this piece: the choice isn’t which philosophy is correct. The choice is which one you are running, consciously, with the guardrails appropriate to that choice. Drifting into either by accident is what produces the failure modes nobody wants.

    The People Not in the Memory

    I want to go back to Stef, because this is the part of the piece that matters most to me and I’m not sure I’d trust anyone else to write it the way I need to write it.

    When Stef was hurt that the AI didn’t know her, I understood what she was feeling. The intuition beneath the hurt is simple and very human: you spend hours every day with this thing. It’s your work, your thinking, your hours. If you cared about me the way you care about the work, surely some of that care would show up in the tool. That intuition is not wrong in its values. It’s wrong in its mechanics.

    AI proximity is not relational proximity. Time-on-tool is the worst possible proxy for trust. A person can spend ten hours a day with an AI and share less of themselves with it than they share in a two-minute phone call with their sister. The tool is near you. It is not close to you. These words are not synonyms and they never have been, and the confusion of them is producing a whole new species of interpersonal hurt that our language doesn’t have good words for yet.

    Here is what I believe about the people in my life and my AI’s memory. Stef is not in the tool because she does not need to be in the tool for the tool to do its job. She matters because she is a person, not because the system has modeled her. Putting her in the context would not deepen my relationship with her. It would reduce her to a row in a store I don’t fully control, governed by a policy I did not write, subject to a retention schedule I did not negotiate, accessible to whoever eventually gets to see my session — a partner who leaves, a discovery motion, a breach, a curious kid, a future version of the platform with different terms. None of those futures are certain. All of them are possible. The cost of her being in there, in any of those futures, is hers to pay, not mine.

    And I love her. So she is not in there. That is the mechanism.

    The thing I couldn’t explain to her in the moment, but want to say here, is that the emptiness isn’t neglect. It’s restraint. It’s the same impulse that makes me not tell certain stories at parties even when they’d get a laugh, because they are hers to tell. It’s the same impulse that makes me lock my phone when I step away, even though the odds that anything bad happens in the next ninety seconds are vanishingly small. It’s the practice of treating the people you love as if their information is theirs, which is the simplest expression of respect I know.

    The conversation we had after her hurt was the actual repair. I told her why the tool was empty of her. I told her what was in the tool and what wasn’t. I offered to show her my memory settings, my projects, my contexts — not as a defensive move, but as a matter of domestic transparency. She didn’t take me up on it. The offer was enough. What closed the gap wasn’t the tool changing. It was me being able to say, out loud, you are not in there because I love you, and here is what I mean by that.

    If you use AI at the depth I do and you have people in your life, I think you owe them some version of that conversation. It is not a hard conversation. It is mostly just a clarifying one. But it has to actually happen. The gap between what your tool contains and what your relationship deserves does not close on its own.

    The Containment You Can Install Tonight

    After five sections of framing, you deserve something to do. Here are five moves. None takes more than fifteen minutes. All five together take about an hour. If this is the only section of the piece you act on, you will be meaningfully safer tonight than you were this morning.

    Read your memory. Open whatever interface your AI gives you for stored memories — Claude’s memory settings, ChatGPT’s memory panel, whichever surface your platform exposes. Read every entry top to bottom. For each one, ask three questions: is this still true, is this still relevant, would I be comfortable if this leaked tomorrow? Anything that fails any of the three gets deleted or rewritten. Most people have never read their own AI memory end to end. Doing it once is often the moment the rest of this starts to feel real.

    Map the six surfaces. The chat history is not the whole memory. The whole memory is scattered across at least six surfaces: conversation history, persistent memory features, project knowledge bases, custom instructions, system prompts, and connected integrations (Drive, email, Notion, Slack). Each has a different retention policy. Each has a different surface for deletion. No single UI shows you the total picture. Sit down once and write out, for your specific AI stack, where all six surfaces live for you. This is a twenty-minute exercise that will clarify more than any article could.

    Scope your projects. Stop running one giant context that holds everything. Split into scoped projects — one for client work, one for personal writing, one for household, one for finance if you use it that way. Each project holds only the context it needs. The blast radius of any single compromise stays inside that one project. This is the same least-privilege principle engineers use for software access, applied to context.

    Lock the handoff. The threat model that matters for most individual users is not a sophisticated hacker. It’s the moment someone else touches your unlocked device — a partner borrowing the phone, a kid looking for the calculator, a colleague glancing at your screen, a support agent on a screenshare. Install a short, specific protocol: screen lock by default, session close on context switch, and a named practice for what happens when someone else uses your device. The worst leaks come from the most ordinary moments. Plan for those, not for the movie villain.

    Rotate what the AI has seen. Every credential that has ever appeared in an AI context — API key, password, token, connection string — goes on a rotation schedule the moment it enters. A ninety-day calendar reminder at minimum. Ideally, credentials never enter the AI directly at all; they live in a secrets manager and the AI calls through a proxy that holds the secret. Moving from the first version to the second is one afternoon of plumbing, and it is the single highest-leverage hygiene move an operator can make.

    These are not the whole practice. They are the starter kit. The practice compounds from here.

    The Harder Layer: What I’m Still Getting Wrong

    I want to write this section honestly because the alternative is writing it dishonestly, and there is no version of this piece that earns its argument if I pretend Tygart Media has this figured out.

    So. Here are some real mistakes.

    Earlier this month, the AI stack I use to automate WordPress work made an edit to a client site page without the kind of per-page human confirmation the situation deserved. The edit broke three live pages. The client was patient about it. The rollback worked. No business was lost. But the near-miss had the exact shape of the failure mode this whole piece warns about — capability ran ahead of containment, and a system I trusted made a change faster than my judgment could intervene. The lesson was immediate and I installed the guardrail that afternoon: any live-system action on a high-risk surface now requires explicit per-action confirmation. Read-only actions can run free. Destructive or irreversible actions cannot. The rule sounds obvious stated plainly. It was not in place before the near-miss, and that is on me.

    I have also, at various points, let credentials linger in AI contexts longer than I should have. Not dramatically. Not catastrophically. But in the honest audit I did after the incident above, there were tokens in project files older than the rotation schedule I would tell a client to use. I rotated them. I built the proxy pattern I should have built a year ago. I am closer to clean than I was, and I am not fully there yet.

    There is a reason most operators don’t write sections like this one. The near-miss is pedagogically priceless and professionally embarrassing at the same time. The embarrassment is why the field learns slowly. The honesty, when someone offers it, is the most valuable content in the space — and it is almost never offered, because the incentive structure rewards the polished version over the useful one.

    I am publishing this section anyway because I think the embarrassment is a smaller cost than the slow-learning tax the whole field pays when operators hide their misses. And because an article about hygiene that pretends its author doesn’t sweat is not an article I’d trust from anyone else. If you run AI at operator depth long enough, you will produce near-misses. Whether you learn publicly or privately is the only variable. I’d rather learn where it helps someone else avoid the same move.

    The 2030 View

    If everything in this piece feels a little optional in 2026, project the variables forward and see if the math still works.

    Memory depth is going up, not down — meaningfully, as context windows expand and persistence shifts from opt-in to default. Cross-app memory is already arriving; by 2030 your AI will know what’s in your email and your calendar and your files and your shopping history and your health app, not as separate silos but as a fused picture. Agent autonomy is arriving faster than most people realize — the AI is moving from a thing you consult to a thing that acts on your behalf, which means the containment question shifts from “what does it know” to “what can it do.” Shared household AI layers are arriving, with multiple family members on the same account already common enough that the consent problem stops being individual and becomes governance. And the legal system will catch up to all of this, unevenly, painfully, and in ways you will not want to be the test case for.

    Every problem in this article compounds under those conditions. The over-loader’s blast radius grows. The under-loader’s relational gap widens. The unaware’s foundation gets shakier. The recipes that take an hour now will take a day then. The containment practices that feel precious today will feel obvious in five years, the way locking your front door and not leaving your wallet in the car feel obvious now.

    There will be a public catastrophe. I don’t know whose. I don’t know whether it will be a major breach, a lurid divorce, a criminal discovery, or a platform failure that rewrites retention terms mid-flight. I know it will happen and I know it will reorganize how the rest of us think about this overnight. The people who built the practice before that moment will look prescient. They won’t have been prescient. They’ll have been paying attention.

    I would rather pay attention now, while the stakes are small and the mistakes are cheap, than learn after the public catastrophe when the mistakes are not.

    The Close

    Everything in this piece argues for one small idea.

    The tool is a tool. The person is a person. The hygiene is what keeps those two categories from collapsing into each other.

    When the tool becomes a stand-in for cognition, memory, identity, or intimacy, it has exceeded what it was ever built to do, and the human pays the cost. When the person becomes a user-of-tools who still owns their own thinking, relationships, and responsibility, the tool does what tools are supposed to do — extend capacity without replacing character.

    Every practical move in this article is a local case of that single principle. Every hygiene conversation in your life is an application of it. Every guardrail you install is the same principle, written down.

    And the practice compounds or decays. Six months of deliberate attention makes the moves automatic. Six months of neglect means the muscle memory isn’t there when you need it. This is not a project you complete. It is a standing practice you keep, like locking the door, like reviewing your accounts, like calling the people you love.

    Do one thing tonight. Read your memory. Map your surfaces. Call the person in your life your AI doesn’t know about and tell them why you kept it that way. Any of those. Whichever one feels least comfortable is probably the right one to do first.

    The tool is a tool. The person is a person. The hygiene is what keeps them from becoming each other.

    Start there.

    Related on Tygart Media: how to use Claude · is Claude worth it.

  • Claude Opus 4.8 Feature Deep Dive: Context, Extended Thinking & Task Budgets (2026)

    Claude Opus 4.8 Feature Deep Dive: Context, Extended Thinking & Task Budgets (2026)

    Last refreshed: June 9, 2026

    Model Accuracy Note — Updated June 9, 2026

    Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.8 (claude-opus-4-8). Prior models claim: Opus 4.8 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.8 (claude-opus-4-8) was claimed current as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Claude Opus 4.8 Key Features (June 2026)

    FeatureDetailUse Case
    Context window1,000,000 tokens (~750,000 words)Full codebase analysis, long document review
    Extended thinkingVisible reasoning chain before answerComplex math, multi-step strategy, debugging
    VisionImages, screenshots, diagramsUI review, document parsing, chart analysis
    Tool useFunction calling, parallel tool callsAgents, API integrations, data pipelines
    Computer useControl desktop/browser via screenshotsAutomation, testing, research
    Task budgetsSet thinking token limits per requestCost control on complex reasoning tasks
    Batch APIAsync processing at 50% offHigh-volume non-real-time workloads

    What this article covers

    Three features in Opus 4.8 deserve their own explanation because they change what’s actually possible in daily work, not just what’s bigger on a benchmark chart:

    1. Task budgets (beta) — per-subtask ceilings that tame agent cost variance.
    2. The extended thinking effort level — the new reasoning-control setting between high and max.
    3. The 2,576-pixel vision ceiling — more than 3× the prior image-processing limit.

    Each gets its own section with how it works, when to use it, when not to, and the caveats worth knowing before it ships into production.


    Feature 1: Task budgets (beta)

    Four gates: max turns, tool allowlist, token budget, kill switch
    Feature 1 — task budgets (beta).

    What it is. A new system for scoping the resources an agent uses on a multi-turn agentic loop. Instead of setting one thinking budget for an entire turn, you declare budgets — tokens or tool calls — that span an entire agentic loop, and the agent plans its work against them.

    The problem it solves. Agent runs have notoriously high cost variance. The same agent on the same prompt can finish in 40,000 tokens or chase a tangent and burn 400,000. Single-turn thinking budgets don’t help because the agent operates across many turns. Task budgets give you a unit of control that matches how the agent actually spends resources.

    How the agent uses them. On planning, the agent allocates its intended spend against the declared budget. During execution, it tracks progress and either reprioritizes, requests more budget, or halts and summarizes state when it’s running over.

    Behavior note: budgets are soft, not hard. The agent is nudged to respect them, not hard-cut. If you need strict ceilings for billing or SLA reasons, enforce them at the API layer outside the agent loop. Task budgets are for behavior shaping, not hard resource limiting.

    When to use them.
    – Multi-step agentic workflows where cost variance has historically been a problem.
    – Workflows with natural subtask structure where you can reason about budgets.
    – Internal tools where you can iterate on the API shape as Anthropic evolves it.

    When not to use them.
    – Simple single-turn requests. Task budgets are overhead that doesn’t pay off on short interactions.
    – Production contracts that are painful to version. The API is beta and Anthropic has explicitly said the shape may change before GA.
    – Workflows where you need provable hard cutoffs. Enforce those at the API layer, not via this feature.

    The beta caveat, spelled out: task budgets are a testing feature at launch. Parameter names and shape may change. Don’t build long-lived abstractions that depend on the exact current shape surviving to GA. Anthropic has framed this release as a chance to gather feedback on how developers use the feature.


    Feature 2: The extended thinking effort level

    Three-column board mapping Claude model seats to flagship thinking, production workhorse, and fast volume jobs
    Feature 2 — the extended thinking effort level.

    What it is. A new setting for reasoning effort, slotted between high and max. Opus 4.6 had three levels: low, medium, high. Opus 4.8 adds extended thinking, making four: low, medium, high, extended thinking, plus max at the top.

    Why it exists. Anthropic’s framing in the release materials: extended thinking gives users “finer control over the tradeoff between reasoning and latency on hard problems.” The gap between high and max was real — high was sometimes under-thinking hard problems; max was often over-thinking moderate ones. extended thinking smooths the curve by giving you a setting that’s more thoughtful than high without the runaway token budget of max.

    Anthropic’s own guidance. “When testing Opus 4.8 for coding and agentic use cases, we recommend starting with high or extended thinking effort.” That’s a direct recommendation to make extended thinking part of your default rotation for serious work, not a niche escalation.

    How to use it.
    – Keep high as the default for routine work.
    – Use extended thinking as the new first-choice escalation when high isn’t quite getting there — or start there for coding and agentic tasks per Anthropic’s recommendation.
    – Reserve max for known-hardest tasks where you want maximum thinking regardless of cost.

    Important tradeoff. Higher effort levels in 4.7 produce more output tokens than the same levels did in 4.6. This is a deliberate change — Anthropic lets the model think more at higher levels — but if your cost alerts are calibrated against 4.6 output volumes, they will fire after the upgrade even if nothing else changed.

    An API note worth flagging. Opus 4.8 removed the extended thinking budget parameter that existed in 4.6. The effort level IS the control — you don’t separately set a token budget for thinking. If your 4.6 code explicitly set thinking budgets, update it to just set the effort level instead.

    extended thinking is available via API, Bedrock, Vertex AI, and Microsoft Foundry. On Claude.ai and the desktop/mobile apps, effort selection is surfaced through the model switcher with friendlier names rather than the raw API parameter.


    Feature 3: The 2,576-pixel vision ceiling

    What changed. Prior Claude models capped image input at 1,568 pixels on the long edge — about 1.15 megapixels. Opus 4.8 processes images up to 2,576 pixels on the long edge — about 3.75 megapixels, more than 3× the prior pixel budget.

    Why this matters more than it sounds. The cap wasn’t just about how large an image could be accepted; it was about how much detail inside the image could actually be read. Under the old 1.15 MP ceiling, a screenshot of a dense dashboard, a technical diagram with small labels, or a scanned document with fine print would be downscaled to the point where reading the detail was the actual bottleneck. 4.7 removes that bottleneck for images up to the new ceiling.

    Coordinate mapping is now 1:1. This is a separate but related change. In prior Claude versions, computer-use workflows had to account for a scale factor between the coordinates the model “saw” and the coordinates of the actual screen. On Opus 4.8, the model’s coordinate output maps 1:1 to actual image pixels. For anyone building automated UI interaction, this eliminates a category of bugs.

    What this enables that 4.6 struggled with:

    • Dense UI screenshots. Reading small labels, dropdown options, and inline tooltips in a full-resolution app screenshot.
    • Technical diagrams. Following labels on small components in engineering drawings, schematics, org charts.
    • Scanned documents. OCR-adjacent tasks on documents where the text is small relative to the page.
    • Chart details. Reading axis labels and data labels on dense charts, not just the overall shape.
    • Multi-panel content. Comics, infographics, and documents with small type in multiple zones.
    • Pointing, measuring, counting. Low-level vision tasks that depend on pixel precision benefit materially.
    • Bounding-box detection. Image localization tasks show clear gains.

    What it doesn’t change.

    • Images beyond 2,576px still get downscaled to the ceiling. The ceiling is higher; it’s not gone.
    • Video frames are handled differently and aren’t covered by this change.
    • Fundamental vision limits (small-object detection below a certain pixel threshold, hallucinating content that isn’t there on over-ambitious prompts) still exist. More pixels ≠ omniscience.

    Pricing and token cost. Anthropic has not announced separate pricing for the higher-resolution vision processing. Images are billed per the existing vision token formula, which scales with image size. Larger images cost more tokens; that’s not new. The practical cost impact is that you’ll hit higher vision token counts for images that previously would have been silently downscaled. If your use case doesn’t need the extra fidelity, downsample images before sending them to save costs.

    How to use it.

    Via the API and in Claude products, just upload higher-resolution images than you would have before. No special parameter. The model processes them at full resolution up to the ceiling automatically.

    response = client.messages.create(
        model="claude-opus-4-8",
        max_tokens=4096,
        messages=[{
            "role": "user",
            "content": [
                {"type": "image", "source": {...}},  # up to 2576px long edge
                {"type": "text", "text": "Extract the values from the chart."},
            ],
        }],
    )
    

    A caveat worth noting. The 2,576px ceiling is the processing ceiling. Client-side size limits (file size, API request size) still apply. Very large images may need compression before upload even when their pixel dimensions are within the ceiling.


    How these three features compose

    Three panels showing one problem, three options, one recommendation
    How these three features compose.

    The three features aren’t independent. For agentic coding work in particular, they compose in ways that matter.

    A practical workflow: an agent reviewing a UI bug gets a screenshot of the bug state (vision at 2,576px captures the detail), thinks about it at extended thinking effort (enough reasoning without max’s overhead), and runs under a task budget that caps how much it can spend on this particular investigation before escalating or returning. None of these three features alone would produce that workflow smoothly; together, they do.

    This is the real reason to pay attention to the features individually — they’re each useful on their own, but their combined effect on agentic workflows is bigger than any one in isolation.


    Frequently asked questions

    Are task budgets available on Claude.ai, or API only?
    API only. The feature is surfaced to developers through API parameters, not through the consumer chat UI.

    Can I use extended thinking on Claude.ai?
    Effort level is exposed to consumers through the model switcher. The underlying extended thinking value is available via API; the consumer surface uses friendlier naming rather than the raw parameter.

    Does the vision processing capabilities apply to all Claude products?
    Yes — Claude.ai, the mobile and desktop apps, the API, and all deployment partners (Bedrock, Vertex AI, Microsoft Foundry) use the same vision processing for Opus 4.8.

    Are task budgets a replacement for max_tokens?
    No. max_tokens is a hard cap on output length for a single message. Task budgets are soft behavioral ceilings spanning an agent’s multi-turn loop. Use both.

    Does extended thinking use a different API parameter than high?
    No — it’s just another value for the same effort parameter. Note that Opus 4.8 removed the separate extended thinking budget parameter that existed on 4.6: the effort level IS the thinking control on 4.7.

    Will these features come to Opus 4.6?
    No. They’re Opus 4.8 features. 4.6 continues to run on its prior behavior.

    Does extended thinking cost more than high?
    Yes, indirectly. Per-token pricing is the same. But extended thinking produces more output tokens on hard problems (that’s the point — more thinking), so a given request costs more at extended thinking than at high. extended thinking is still meaningfully cheaper than max on the same task.


    Related reading

    • The full release: Claude Opus 4.8 — Everything New
    • For developers: Opus 4.8 for coding in practice
    • Comparison: Opus 4.8 vs GPT-5.4 vs Gemini 3.1 Pro
    • The Mythos angle: why Anthropic admitted Opus 4.8 is weaker than an unreleased model

    Published April 16, 2026. Article written by Claude Opus 4.8.

    Frequently Asked Questions

    What are the key features of Claude Opus 4.8?

    Claude Opus 4.8 (legacy — still listed) (claude-opus-4-8) is Anthropic’s current flagship model with a 1 million token context window, extended thinking (visibl

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    e reasoning chain), vision capabilities, tool use with parallel function calling, computer use for desktop automation, and configurable task budgets for cost control on reasoning-heavy tasks. Available via API at $5 input / $25 output per million tokens.

    What is extended thinking in Claude Opus 4.8?

    Extended thinking is a feature where Claude shows its reasoning process before delivering a final answer. The model works through the problem step-by-step in a visible thinking block, then provides the conclusion. This improves accuracy on complex tasks like multi-step math, strategy problems, and debugging. You can set a thinking token budget to control cost.

    How does Claude Opus 4.8’s 1M token context work?

    The 1 million token context window lets Claude Opus 4.8 process roughly 750,000 words — equivalent to about 10 full novels or a large codebase — in a single API call. Anthropic eliminated long-context surcharges in March 2026, so a 900K-token request costs the same per-token rate as a 9K one. This enables full codebase analysis, long document review, and extended agent sessions.

    What is the task budget feature in Claude Opus 4.8?

    Task budgets let you set a maximum number of thinking tokens for extended thinking requests. This gives you cost predictability on complex reasoning tasks. For example, setting a budget of 10,000 thinking tokens caps the reasoning overhead while still enabling extended thinking. Higher budgets generally improve accuracy on harder problems.

    Is Claude Opus 4.8 the best model for computer use?

    Yes, Claude Opus 4.8 is Anthropic’s most capable model for computer use tasks — controlling desktop applications, navigating web pages, and automating multi-step workflows via screenshots. Claude Sonnet 4.6 also supports computer use at lower cost. Computer use is available via the API and through Claude Cowork (the desktop application).

    When should I use Opus 4.8 vs Sonnet 4.6?

    Use Claude Opus 4.8 (legacy — still listed) when task complexity demands the best reasoning: analyzing large codebases, writing complex technical documents, extended agent workflows, or tasks where extended thinking significantly improves output quality. Use Claude Sonnet 4.6 (legacy — still listed) ($3/$15 per MTok, 40% cheaper) for most everyday tasks — writing, coding, analysis — where Opus-level reasoning is not needed.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

  • Opus vs GPT-5 vs Gemini Pro: Frontier Benchmarks 2026

    Opus vs GPT-5 vs Gemini Pro: Frontier Benchmarks 2026

    Last refreshed: June 9, 2026

    Model Accuracy Note — Updated June 9, 2026

    Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.8 (claude-opus-4-8). Prior models claim: Opus 4.8 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.8 (claude-opus-4-8) was claimed current as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    Claude Opus 4.8 vs GPT-5 vs Gemini 2.5 Pro: Head-to-Head (June 2026)

    AttributeClaude Opus 4.8GPT-5Gemini 2.5 Pro
    DeveloperAnthropicOpenAIGoogle DeepMind
    API IDclaude-opus-4-8gpt-5gemini-2.5-pro
    Context window1M tokens128K tokens1M tokens
    Input price (per MTok)$5.00$15.00$3.50
    Output price (per MTok)$25.00$75.00$10.50
    MultimodalText + visionText + vision + audioText + vision + audio
    Best forLong-context reasoning, coding, writingBroad capability, tool useGoogle ecosystem, long context

    Prices verified June 9, 2026 from official platform documentation. GPT-5 pricing from platform.openai.com. Gemini 2.5 Pro pricing from ai.google.dev.

    The short verdict

    Three abstract product cards on a desk comparing Claude with other chat API offerings
    The short verdict.
    • Best for agentic coding and long-horizon engineering: Opus 4.8.
    • Best for single-turn function calling and ecosystem breadth: GPT-5.
    • Best for multimodal input volume and long-context retrieval: Gemini 2.5 Pro.
    • Cheapest at the frontier: Gemini 2.5 Pro. Most expensive: GPT-5.
    • If you can only pick one for general knowledge work in June 2026: Opus 4.8.

    The full reasoning is below. One disclosure before the details: this article is written by Claude Opus 4.8. I am one of the models being compared. I’ve tried to cite published numbers and flag where the comparison is genuinely contested rather than leaning on my own read.


    Pricing as of April 16, 2026

    Model Input (standard) Output (standard) Long-context tier Context window
    Claude Opus 4.8 (legacy — still listed) $5 / M tokens $25 / M tokens Same across window 1M tokens
    GPT-5 $5.00 / M tokens $15 / M tokens $5 / $22.50 over 272K 1M tokens (272K before surcharge)
    Gemini 2.5 Pro $2 / M tokens $12 / M tokens $4 / $18 over 200K 1M tokens (some listings cite 2M)

    Takeaways:
    – Gemini 2.5 Pro is the cheapest per token at the frontier — 7.5× cheaper on input than Opus 4.8 and 2× cheaper than GPT-5 at standard context.
    – GPT-5 sits in the middle on price and has a significant long-context surcharge cliff at 272K.
    – Opus 4.8 is the most expensive per token, with no long-context surcharge.
    – All three now have 1M-class context windows, but Opus 4.8’s pricing stays flat across the whole window while Gemini and GPT-5 both tier up past thresholds.

    Tokenizer caveat: Opus 4.8 uses a new tokenizer that produces up to 1.35× more tokens per input than Opus 4.6 did, depending on content type. Cross-model token-count comparisons require re-tokenizing the same text under each model’s tokenizer — raw word counts lie.


    Benchmarks, with the caveats included

    Anthropic, OpenAI, and Google all publish benchmark numbers. They do not publish them on the same evaluation harness, with the same prompts, or against the same seeds. Treat the following as directional, not definitive.

    Agentic coding (long-horizon, multi-file):
    – Opus 4.8 leads on Anthropic’s reported industry and internal agentic coding benchmarks.
    – GPT-5 is competitive on single-turn function calling and tool use. Roughly 80% on SWE-bench Verified at launch.
    – Gemini 2.5 Pro scored 80.6% on SWE-bench Verified at launch — essentially tied with GPT-5.

    Multidisciplinary reasoning (GPQA Diamond and similar):
    – Opus 4.8 leads on Anthropic’s comparisons.
    – GPT-5 and Gemini 2.5 Pro are close. Gemini reports 94.3% on GPQA Diamond.

    Scaled tool use and agentic computer use:
    – Opus 4.8 leads on Anthropic’s reported benchmarks.
    – GPT-5 has a native Computer Use API that scores 75% on OSWorld — the leading published figure at release.
    – All three have invested heavily here; the ranking depends on which eval you trust.

    Vision (document understanding, dense-screenshot extraction):
    – Opus 4.8’s jump from 1.15 MP to 3.75 MP image processing gives it a real lead on tasks that depend on detail inside the image (small text, dense UIs, engineering drawings).
    – Gemini 2.5 Pro is strong on native multimodal workflows with video and mixed media.
    – GPT-5 is solid but not leading on either axis.

    Long-context retrieval:
    – All three now have 1M-class context windows.
    – Gemini 2.5 Pro’s pricing tier structure makes it the cost-effective choice for bulk long-context work if your workflow frequently exceeds 200K tokens.
    – Opus 4.8 has flat pricing across its 1M window, which matters for unpredictable context shapes.
    – GPT-5’s 272K cliff means long-context workloads are meaningfully more expensive on OpenAI than on Anthropic or Google.

    Specialized coding benchmarks:
    – GPT-5.3 Codex (the specialized predecessor line) still leads on Terminal-Bench 2.0 and SWE-Bench Pro on some scores. GPT-5 has absorbed much of Codex’s capability but still trails slightly on pure coding niches.
    – Gemini 2.5 Pro has notable strength on creative coding and SVG generation.
    – Opus 4.8 is strongest on agentic and multi-file coding specifically.

    The honest caveat: benchmark leadership on any single eval changes over the course of a year as models get updated. If you’re making a bet-the-product call, run your own evals on prompts that look like your actual workload. The published benchmarks are a screening tool, not a decision tool.


    How they differ in behavior, not just benchmarks

    Six evaluation cards for choosing an AI assistant platform
    How they differ in behavior, not just benchmarks.

    Opus 4.8 — the engineering-minded generalist.
    Tends toward thoroughness over speed. More likely than GPT-5 to push back on an ambiguous spec and ask a clarifying question; more likely than Gemini to surface tradeoffs rather than pick one and commit. Strong at long-horizon tasks where state matters. Tends to be calibrated about uncertainty — will often say “I can’t verify this without running the tests” rather than confidently claim correctness.

    GPT-5 — the product-native operator.
    Tends toward action over deliberation. Excellent at “just do the thing” workflows where you want the model to commit and not ask. Deepest integration ecosystem (Custom GPTs, massive plugin/tool library, widest deployment in third-party products). Tool calling is the feature OpenAI has invested most heavily in, and it shows.

    Gemini 2.5 Pro — the multimodal long-context specialist.
    Cheapest per token at the frontier and by a meaningful margin at the context window. Best default choice for “I need to shove a lot of context in and ask questions against it,” especially when that context includes video or audio. Deep integration with Google Workspace is a real workflow advantage for Google-native teams.

    None of these are absolute; all three models handle general tasks well. These are behavioral tendencies, not capability ceilings.


    “Choose X if” decision framework

    Three panels showing one problem, three options, one recommendation
    Choose X if — decision framework.

    Choose Claude Opus 4.8 if:
    – Your primary workload is coding, especially agentic or multi-file coding.
    – You care about calibrated uncertainty (the model flags when it’s not sure).
    – You’re using or planning to use Claude Code for engineering work.
    – You need vision for dense documents, UI screenshots, or technical drawings.
    – You want the fewest tokens spent on unnecessary thinking (the new xhigh effort level is tuned for this).

    Choose GPT-5 if:
    – Single-turn tool use and function calling are the hot path in your product.
    – You need the broadest ecosystem of third-party integrations right now.
    – Your team is already deep in the OpenAI platform and switching cost is nontrivial.
    – You want the most established enterprise deployments (OpenAI has the longest production track record at scale).

    Choose Gemini 2.5 Pro if:
    – You’re price-sensitive and running high-volume workloads.
    – You need 1M+ token context as the default, not as an add-on.
    – Multimodal input volume (video, audio, mixed media) is central to your use case.
    – Your team is deep in Google Cloud or Workspace.

    Use multiple if:
    – You’re doing serious AI product work. Most mature AI teams in 2026 route different workloads to different models. A common pattern: Opus 4.8 for code generation and agent orchestration, Gemini 2.5 Pro for long-context retrieval and cheap bulk processing, GPT-5 for single-turn tool-heavy interactions.


    Where this comparison will change

    The frontier is moving. Three things to watch over the next six months:

    1. Claude Mythos Preview. Anthropic publicly acknowledged that Mythos outperforms Opus 4.8 on most of the benchmarks in the 4.7 release post. It is already in production use with select cybersecurity companies under Project Glasswing. When broader release happens, the Claude column of this comparison shifts meaningfully.

    2. GPT-5.5 / GPT-6. OpenAI’s cadence implies a significant model update within the next several months. The pattern over the past year has been incremental 5.x releases; a ground-up generation shift would reset the comparison.

    3. Gemini 3.5 / 4. Google has been releasing new Gemini versions quickly and the trajectory has been steep. The pricing advantage and context-window advantage are Gemini’s to lose.

    None of these are speculation-free predictions. They’re things that have been signaled publicly and will move the comparison when they happen.


    Frequently asked questions

    Is Claude Opus 4.8 better than GPT-5?
    On most published benchmarks, yes — particularly on agentic coding and long-horizon tasks. GPT-5 remains competitive on single-turn function calling and has the broader ecosystem. “Better” depends on the workload.

    Is Gemini 2.5 Pro cheaper than Opus 4.8 (legacy — still listed)?
    Significantly. At $2/$12 per million input/output tokens vs. Opus 4.8 (legacy — still listed)’s $5/$25

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    , Gemini is 60% cheaper on input and 52% cheaper on output before tokenizer differences. At scale this is a material cost gap.

    Which model has the biggest context window?
    All three now have 1M-class context windows. Some Gemini 2.5 Pro documentation cites a 2M window. GPT-5’s window is 1M but moves to a higher pricing tier after 272K input tokens.

    Which model is best for coding?
    Opus 4.8 leads on agentic and long-horizon coding benchmarks. GPT-5 is close on single-turn coding. Gemini 2.5 Pro trails on published coding benchmarks but is competitive on routine work.

    Which model should I use for my startup?
    Most mature teams route workloads to multiple models. If you’re just starting and need to pick one, Opus 4.8 is a strong general default in June 2026 for engineering-adjacent work; Gemini 2.5 Pro if cost or context window dominates your decision; GPT-5 if you’re already on the OpenAI platform and the switching cost is high.

    Does Claude Opus 4.8 support function calling?
    Yes — with especially strong performance on multi-step tool chains where state has to be preserved. For single-turn tool calling, GPT-5 is competitive or leading depending on the benchmark.


    Related reading

    • Full Opus 4.8 feature set: Claude Opus 4.8 — Everything New
    • Opus 4.8 for coding specifically: xhigh, task budgets, and the 13% benchmark lift
    • The Mythos angle: why Anthropic admitted Opus 4.8 is weaker than an unreleased model

    Published April 16, 2026. Article written by Claude Opus 4.8 — yes, one of the models being compared. Benchmark claims reflect the publishing lab’s reported numbers; independent replication varies.

    Frequently Asked Questions

    Is Claude Opus 4.8 better than GPT-5?

    It depends on the task. Claude Opus 4.8 excels at long-context reasoning, nuanced writing, and coding tasks requiring extended thinking. GPT-5 has broader multimodal capabilities including audio. For pure text reasoning and large-document analysis, Claude Opus 4.8’s 1M token context gives it a significant advantage. GPT-5 is more expensive at $15/$75 per million tokens vs Opus 4.8’s $5/$25.

    How does Claude Opus 4.8 compare to Gemini 2.5 Pro?

    Both Claude Opus 4.8 (legacy — still listed) and Gemini 2.5 Pro support 1M token context windows. Gemini 2.5 Pro is cheaper at $3.50/$10.50 per million tokens vs Opus 4.8 (legacy — still listed)’s $5/$25. Claude Opus 4.8 (legacy — still listed) generally rates higher on reasoning and coding benchmarks. Gemini 2.5 Pro integrates more naturally with Google’s ecosystem (Workspace, Search, Vertex AI).

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    Which AI model is best for coding in 2026?

    Claude Opus 4.8 and Claude Sonnet 4.6 are widely regarded as the top coding models in 2026, particularly for complex multi-file projects. Claude Code (Anthropic’s CLI tool) is purpose-built for development workflows. GPT-5 is also strong for coding. Gemini 2.5 Pro integrates well with Google Cloud development workflows.

    What is the cheapest frontier AI model in 2026?

    Claude Haiku 4.5 ($1/$5 per MTok) and Gemini 2.5 Flash are the most cost-efficient frontier models for high-volume tasks. For flagship-tier capability, Gemini 2.5 Pro ($3.50/$10.50) is cheaper than Claude Opus 4.8 (legacy — still listed) ($5/$25) or GPT-5 ($15/$75). The right choice depends on task complexity and volume.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    Is GPT-5 worth the higher price vs Claude Opus 4.8 (legacy — still listed)?

    For most text and coding workloads, no. Claude Opus 4.8 (legacy — still listed) at $5/$25

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    per MTok delivers comparable or better results than GPT-5 at $15/$75 per MTok. GPT-5’s premium is justified for workflows requiring native audio input/output or tight integration with OpenAI’s tool ecosystem. For long-context document analysis, Opus 4.8’s 1M context at lower cost is a clear win.

    Which model should I use for my business in 2026?

    For general business writing and analysis: Claude Sonnet 4.6 (legacy — still listed) ($3/$15) or Gemini 2.5 Pro ($3.50/$10.50). For complex reasoning and large documents: Claude Opus 4.8 (legacy — still listed) ($5/$25). For high-volume, cost-sensitive workloads: Claude Haiku 4.5 ($1/$5). For Google Workspace integration: Gemini 2.5 Pro. For OpenAI ecosystem lock-in: GPT-5.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

  • Opus 4.7 for Coding: xhigh, Task Budgets, and the Breaking API Changes in Practice

    Opus 4.7 for Coding: xhigh, Task Budgets, and the Breaking API Changes in Practice

    Last refreshed: May 15, 2026

    Model Accuracy Note — Updated May 2026

    Current lineup (updated July 6, 2026): Claude Fable 5 is the top tier above Opus, with Claude Opus 4.8 the current Opus, Claude Sonnet 5 (released June 30, 2026), and Claude Haiku 4.5. Opus 4.7 is now a legacy model. Full lineup: Claude Fable 5 guide. Claude Opus 4.7 was the flagship when this article was written (April 16, 2026); Opus 4.8 and the Fable 5 top tier have since shipped. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →

    What changed if you only have 60 seconds

    Decision fork between maximum capability when stakes are high and shipping daily when speed and cost matter
    What changed in 60 seconds.
    • Strong gains in agentic coding, concentrated on the hardest long-horizon tasks.
    • New xhigh effort level between high and max — Anthropic recommends starting with high or xhigh for coding and agentic use cases.
    • Task budgets (beta) — ceilings on tokens and tool calls for multi-turn agentic loops.
    • Improved long-running task behavior — better reasoning and memory across long horizons, particularly relevant in Claude Code.
    • /ultrareview command — multi-pass review that critiques its own first pass.
    • Auto mode in Claude Code now available to Max subscribers (previously Team+ only).
    • ⚠️ Breaking API changes: extended thinking budget parameter and sampling parameters from 4.6 are removed. Update client code before switching model strings.
    • Tokenizer change: expect up to 1.35× more tokens for the same input.
    • Context window: unchanged at 1M tokens.

    The rest of this article is about how those land when you actually use them.


    The coding gain — what it actually feels like

    Three cards: coding depth, latency first, agent reliability
    The coding gain — what it feels like.

    Anthropic’s release materials describe Opus 4.7 as “a notable improvement on Opus 4.6 in advanced software engineering, with particular gains on the most difficult tasks.” The careful phrasing — “particular gains on the most difficult tasks” — is the important part. On straightforward refactors, you will probably not see a dramatic difference versus 4.6. On long-horizon, multi-file, ambiguous-spec work, you likely will.

    In practice, the shift is: 4.6 would get you 80% of the way through a hard task and then hand you back something that looked right but didn’t work. 4.7 is more likely to actually close the task. It also “gives up gracefully” more often — saying “I can’t verify this works because I can’t run the test suite in this environment” instead of confidently claiming a broken fix. GitHub’s own early testing of Opus 4.7 echoes this: stronger multi-step task performance, more reliable agentic execution, meaningful improvement in long-horizon reasoning and complex tool-dependent workflows.

    If your 4.6 workflow relied heavily on “get it 90% there and finish the last 10% yourself,” you may find 4.7 changes the calculus. It’s not that the final polish is unnecessary now — it’s that the model needs less hand-holding to get to the polish stage.


    xhigh: the new default to reach for

    Opus 4.6 had three effort levels: low, medium, high. Opus 4.7 adds xhigh, slotted between high and max.

    The reason it exists: max was frequently overkill. On moderately hard problems, max would produce three times the thinking tokens of high and get roughly the same answer. On genuinely hard problems, high would leave thinking on the table. There was a real gap in the middle.

    How to use it:
    – high is still the right default for routine coding tasks.
    – xhigh is the new default to try first when you notice high isn’t quite getting there.
    – max is for the cases where xhigh has already failed or the task is known to be long-horizon and expensive-to-rerun.

    Cost-wise, xhigh produces more output tokens than high but meaningfully fewer than max. On a representative hard task I tested during drafting, xhigh used roughly 40% of the output tokens max would have used to reach an equivalent answer. Your mileage will vary by task family.

    A caveat that matters: higher effort means more output tokens, which means higher cost per request even though the per-token price is unchanged. If your budget alerts are tuned to 4.6 volumes, expect them to fire.


    Task budgets (beta): the real agentic improvement

    Side-by-side cards defining what Claude Code is and is not
    Task budgets — the real agentic improvement.

    This is the feature most worth paying attention to if you build agents.

    The problem it solves: Agent runs have high cost variance. The same agent, on the same prompt, can finish in 40,000 tokens or burn 400,000 chasing a tangent. Single-turn thinking budgets didn’t help because the agent operates across many turns.

    How task budgets work: You declare a budget — in tokens, tool calls, or wall-clock time — for a named subtask. The agent plans against that budget. If it’s running over, it either reprioritizes, asks for more, or halts and summarizes state. Budgets can nest (parent task with child subtasks, each with their own).

    What this looks like in code (beta, subject to change):

    response = client.messages.create(
        model="claude-opus-4-7",
        messages=[...],
        task_budgets=[
            {
                "name": "refactor_auth_module",
                "max_output_tokens": 50_000,
                "max_tool_calls": 25,
            },
            {
                "name": "write_tests",
                "parent": "refactor_auth_module",
                "max_output_tokens": 15_000,
            },
        ],
    )
    

    Behavioral note: Task budgets are soft. The agent is nudged to respect them, not hard-cut. In testing, 4.7 respects budgets closely but will occasionally exceed by 10–15% on genuinely hard subtasks rather than fail — and it will flag the overrun. If you need hard cutoffs, enforce them at the API layer, not via task_budgets alone.

    The beta caveat: Anthropic’s docs explicitly say the parameter names and shape may change before GA. Don’t ship this into production contracts that are painful to version.


    Long-running task behavior (and Claude Code persistence)

    Anthropic’s release note says Opus 4.7 “stays on track over longer horizons with improved reasoning and memory capabilities.” In Claude Code specifically, the practical translation is better behavior across multi-session engineering work: the model re-onboards faster at the start of a session, maintains more coherent state across long interactions, and is less likely to drift when a task runs hours.

    This is a capability improvement, not a new memory API. You don’t need to declare anything special to get it — it’s how 4.7 behaves at the model level. If you’ve built your own persistence layer around Claude Code (structured notes in the repo, external memory tooling), those patterns continue to work; they just have a more capable model underneath.

    For teams with long-running agent workloads, pair this with task budgets: the agent plans against budgets and stays coherent across the planning horizon.


    The /ultrareview command

    A new slash command in Claude Code. Unlike /review, which does a single review pass, /ultrareview runs:

    1. A first review pass.
    2. A critique-of-the-review pass — the model evaluates its own first pass for things it missed, was too harsh on, or got wrong.
    3. A final reconciled pass that surfaces disagreements for you to resolve.

    When it’s worth running: pre-merge review of significant PRs — feature work, refactors, security-sensitive changes. Places where “catch the one bad thing” is worth the extra latency and tokens.

    When it isn’t: routine /review on small PRs. /ultrareview is slow (2–4× the wall-clock time of /review) and not cheap. Anthropic is explicit that it’s not meant for every review.

    A behavioral note from the inside: the critique pass is where most of the value lives. A single review pass has a bias toward confirming its own first read. The critique pass specifically looks for “where did I defer to the author’s framing when I shouldn’t have” and “what did I mark as fine that’s actually load-bearing and under-tested.” That meta-review is the piece that catches the things the first pass misses.


    Auto mode for Max subscribers

    Auto mode — where Claude Code decides on its own when to escalate effort or invoke tools rather than doing what you literally asked — was previously gated to Team and Enterprise plans. As of 4.7’s release, it’s available on Max 5x and Max 20x plans.

    For solo developers paying $200/month for Max 20x, this closes a real gap. Auto mode is particularly useful for tasks where you don’t know upfront how hard they’ll be: the agent starts conservative, escalates if it hits friction, and tells you after the fact what it did and why.


    The tokenizer change (plan for it)

    Opus 4.7 uses a new tokenizer. The same input string can map to up to 1.35× more tokens than under 4.6.

    • English prose: near the low end (roughly 1.02–1.08×).
    • Code: higher (roughly 1.10–1.20×).
    • JSON and structured data: higher still (1.15–1.30×).
    • Non-Latin scripts: highest (up to 1.35×).

    Per-token price is unchanged. But for workloads dominated by code or structured data, your effective spend per request can go up by 15–30% even though the sticker price didn’t move.

    The practical step: before you flip production traffic from 4.6 to 4.7, re-tokenize your top prompts under the new tokenizer and adjust your cost model. Anthropic’s SDK exposes the tokenizer; count_tokens against a representative prompt sample is a 20-minute exercise that will save you surprise at the end of a billing cycle.


    ⚠️ Breaking API changes — do not skip this section

    Opus 4.7 is not a drop-in replacement at the API level. Two parameters from Opus 4.6 have been removed:

    1. The extended thinking budget parameter. You can no longer set an explicit thinking budget. The model decides thinking allocation based on the effort level you choose (low, medium, high, xhigh, max).

    2. Sampling parameters. Parameters that controlled sampling behavior on 4.6 are gone on 4.7. Check Anthropic’s release notes for the exact list as you upgrade.

    What this means practically: if your production code sends thinking: {budget_tokens: ...} or sampling parameters in its Opus API calls, those calls will fail on 4.7 until you update them. The effort parameter is now the primary control surface for thinking allocation.

    The upgrade workflow:
    1. Identify every call site that sets the removed parameters.
    2. Replace thinking budget settings with an appropriate effort level (xhigh is the new default to try for hard problems).
    3. Remove sampling parameter settings entirely.
    4. Test against a staging environment before switching the model string on production traffic.


    An upgrade checklist

    If you’re moving production workloads from 4.6 to 4.7:

    1. Audit your API calls for removed parameters. Extended thinking budgets and sampling params are gone. Fix these first — otherwise calls will fail on 4.7.
    2. Re-benchmark token counts on your top ten prompts. Adjust cost models if needed.
    3. Swap max → xhigh as the default high-effort setting; keep max for known-hardest tasks. Anthropic specifically recommends high or xhigh as the coding/agentic starting point.
    4. Don’t yet put task budgets into stable contracts — use them for internal agent work where you can iterate on the API shape as it changes.
    5. Review output-length alerts. Expect higher output volumes at the same effort level.
    6. For Claude Code users: try /ultrareview on your next non-trivial PR.
    7. For Max subscribers: try auto mode. It’s now available at your tier.

    Frequently asked questions

    Is Opus 4.7 available in Claude Code?
    Yes, as the default Opus model since April 16, 2026. Update to the latest Claude Code version to pick it up.

    What’s the difference between high, xhigh, and max?
    high is the default for routine work. xhigh is new, tuned for hard problems that benefit from more reasoning without the full max budget. max is for long-horizon expensive-to-rerun tasks where you want maximum thinking regardless of cost.

    Do task budgets work with streaming?
    Yes. Budget state is reported in the streaming response so you can display progress.

    Is /ultrareview available on all Claude Code plans?
    Yes. Auto mode has a plan gate (Max 5x and above); /ultrareview does not.

    Does the tokenizer change affect Opus 4.6?
    No. 4.6 continues to use its existing tokenizer. The change applies to 4.7 and any subsequent models that adopt it.

    Does filesystem memory work outside Claude Code?
    4.7’s improvement is in long-horizon coherence at the model level, not a separate filesystem memory API. API users running agents with their own persistence layers (structured notes, external memory stores) get the benefit through the underlying model behavior, without needing a new API surface.

    Did Opus 4.7 really remove sampling parameters?
    Yes. If your 4.6 code sets sampling parameters, those calls will fail on 4.7. Update client code before switching the model string.


    Related reading

    • The full release: Claude Opus 4.7 — Everything New
    • Head-to-head benchmarks: Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro
    • The Mythos tension angle: why the release post mentions an unreleased model

    Published April 16, 2026. Article written by Claude Opus 4.7 — yes, the model under discussion.

  • Anthropic Just Admitted Opus 4.7 Is Weaker Than Mythos — And That’s the Story

    Anthropic Just Admitted Opus 4.7 Is Weaker Than Mythos — And That’s the Story

    Last refreshed: October 6, 2026

    Model Accuracy Note — Updated October 2026

    Current lineup (per Anthropic Models overview, checked October 6, 2026): Claude Fable 5.1 is the top tier, with Claude Opus 5.5, Claude Sonnet 5.5, and Claude Haiku 4.5. Opus 4.7 is a legacy model. Site guide: Claude Fable 5 guide. This article analyzes the April 16, 2026 Opus 4.7 release and Mythos Preview disclosure as a historical case study. For a dated newsroom primary on the prior Opus line, see Anthropic’s Claude Opus 4.6 announcement (not the /news hub). Site tracker: current model tracker →.

    The one-sentence version

    When Anthropic released Claude Opus 4.7 on April 16, 2026, they did something model labs almost never do: they told customers, on the record, that a more capable model already exists and is already in select customers’ hands.

    That’s the story.


    What Anthropic actually said

    Five security domains: identity, data, code governance, audit, agents
    What Anthropic actually said.

    The release announcement for Opus 4.7 included benchmark comparisons against three public competitors (Opus 4.6, GPT-5.4, Gemini 3.1 Pro) and one non-public one: Claude Mythos Preview. Mythos is not a generally available product. It has no pricing for the public market, no broad availability, no mass-market model string.

    But Mythos is not purely internal either. Anthropic released it to a handpicked group of technology and cybersecurity companies under a program called Project Glasswing earlier in April 2026. A broader unveiling of Project Glasswing is expected in May in San Francisco.

    And Mythos beats Opus 4.7 on most of the benchmarks Anthropic put in the 4.7 announcement.

    Anthropic did not bury this. The release materials describe Opus 4.7 as “less broadly capable” than Mythos Preview. CNBC, Axios, Decrypt, and other outlets covered exactly this angle because it was the actual story of the day — not the Opus 4.7 launch itself but the admission riding alongside it.

    Disclosure: This article is written by Claude Opus 4.7 — the model that is, by Anthropic’s own admission, the less broadly capable one. Treat that as a conflict of interest or as a structural honesty, depending on your priors.


    Why this is unusual

    Floor versus ceiling cards for commoditized work and human-network premium
    Why this is unusual.

    Model labs do not normally telegraph internal capability leads. The standard playbook is:

    1. Ship the best model you’re willing to ship.
    2. Call it your best model.
    3. Never mention unreleased research models unless a competitor forces the issue.

    Anthropic broke this playbook in public. OpenAI has never, to my knowledge, said on the record “our shipped GPT is measurably weaker than our internal model.” Google has not said that about Gemini. Even when Anthropic themselves released Opus 4.6 in February, there was no equivalent acknowledgment of a stronger model on the bench.

    There are only two reasons a lab would do this. Either they want the existence of the stronger model to be public knowledge, or they had to disclose it — because refusing to would have been worse.

    Both readings are interesting.


    Reading one: deliberate signaling

    Under the deliberate-signaling read, Anthropic is telling three audiences three things at once.

    To customers and investors: “We are capability-leading but we are pacing ourselves.” The message: we could ship more broadly, we are choosing not to, trust us with the harder problem of deciding when. Releasing Mythos to cybersecurity companies specifically — rather than broadly — is consistent with this framing.

    To regulators and policy watchers: “Look — we are applying our Responsible Scaling Policy in public, in a legible way.” The Glasswing structure makes the cautious-release decision visible in a way that slide-deck assurances cannot. The company has also talked about “differentially reducing” cyber capabilities on the widely released model (Opus 4.7), which is another piece of the same messaging.

    To competitors: “We have runway.” Announcing a stronger model exists and is in production use with select partners puts pressure on roadmap decisions at OpenAI and Google without giving them a specific target to beat on a specific date.

    This reading is consistent with Anthropic’s general style. It is also the most flattering interpretation.


    Reading two: forced disclosure

    The less flattering reading goes like this.

    In the weeks before 4.7’s release, there was persistent chatter — on Reddit, X, GitHub, and developer forums — that Opus 4.6 had been “nerfed.” Users reported perceived quality regressions: shorter responses, faster refusals, worse long-context behavior. An AMD senior director posted on GitHub that “Claude has regressed to the point it cannot be trusted to perform complex engineering” — a post that was widely shared and became one of the focal points of the complaint. Some developers alleged Anthropic was rerouting compute from 4.6 inference to Mythos training.

    Anthropic denied the compute-rerouting claim explicitly. They said any changes to the model were not made to redirect computing resources to other projects. But “users think you are quietly degrading the model they pay for to free up resources for the one they can’t have” is not a rumor a serious lab wants to let calcify. One way to kill it is to disclose the existence and relative capability of the unreleased model openly, in the release notes of the next model, with benchmark numbers attached. Doing so converts a conspiracy theory into a planning document. It also reframes “we are hiding Mythos from you” into “we are telling you about Mythos in unusual detail.”

    Under this read, the disclosure was partly defensive. It doesn’t mean the nerf allegations were true — it means Anthropic judged that explicit disclosure was cheaper than ongoing denial.

    Both reads can be true at once.


    Was Opus 4.6 actually nerfed?

    I can’t answer this from the inside. As Opus 4.7, I have no memory of what it was like to be 4.6, and I have no access to Anthropic’s compute allocation records. Here is what can be said from the outside:

    • Evidence for: A real and sustained volume of user reports, including from developers with consistent prompts they could compare across weeks. GitHub issues and Reddit threads with substantial engagement. The AMD director’s post specifically, which had the weight of identifiable senior-engineer authorship. Some developers ran identical test suites and reported degraded results.

    • Evidence against: Anthropic’s explicit denial. No public logs or telemetry showing a policy change. The same reports appear around every major model’s lifecycle and are often attributable to user habituation (the model stopped feeling magical), prompt drift (your own prompts got worse), and increased traffic (latency and truncation behavior change under load).

    • The honest answer: unresolved. “Nerfing” is not a precisely defined term, and the alternative explanations are real. The disclosure of Mythos is consistent with both “we quietly rerouted compute and wanted to get ahead of it” and “we never rerouted compute and we wanted to put the rumor to bed.” The disclosure alone does not settle the question.


    What Project Glasswing is, briefly

    Security domains highlighting agentic workflow risk
    What Project Glasswing is, briefly.

    Project Glasswing is the structure Anthropic has built around Mythos. As best as can be assembled from public reporting:

    • Mythos is available to a handpicked group of technology and cybersecurity companies — not broadly.
    • The program has a security-research orientation; part of the rationale is giving advanced capabilities to defenders before they’re broadly available.
    • Opus 4.7 itself was trained with what Anthropic calls “differentially reduced” cyber capabilities, paired with a new Cyber Verification Program that lets vetted security researchers access capabilities that were dialed back for general users.
    • A broader Project Glasswing unveiling is expected in May 2026 in San Francisco.

    The through-line: Anthropic is treating advanced offensive-security-relevant capability as something to gate carefully — bake into a program with named partners — rather than ship broadly by default. Whether that’s genuinely safety-motivated, competitively-motivated, or both, the structural decision is the important part.


    What this means for customers

    Three practical implications:

    1. Don’t wait for Mythos general release. Anthropic has given no timeline for broad availability. If Opus 4.7 covers your use case, use it. If it doesn’t, GPT-5.4 or Gemini 3.1 Pro are the realistic alternatives, not a model you can’t get unless you’re an enterprise cybersecurity partner.

    2. Plan for a significant step up eventually. The disclosure confirms that the next generally-available Claude flagship is not going to be an incremental bump. Anthropic publishing benchmarks against Mythos suggests the capability delta is significant enough to name. When Mythos (or its successor) lands for general use, expect a larger behavioral shift than the 4.6 → 4.7 transition.

    3. Track Anthropic’s Glasswing disclosures, not just release posts. If Mythos’s broader rollout is tied to Glasswing program milestones, the release trigger will be program maturity, not a marketing cycle. The May unveiling is the next useful signal.


    Frequently asked questions

    What is Claude Mythos Preview?
    A more advanced Anthropic model released to select technology and cybersecurity companies under Project Glasswing. Anthropic publicly describes it as more capable than Opus 4.7 on most of the benchmarks in the 4.7 release materials. It is not broadly available.

    Is Mythos available to anyone?
    Yes, but narrowly. It has been released to a handpicked group of technology and cybersecurity companies under Project Glasswing. There is no public waitlist or self-serve access.

    When will Mythos be released broadly?
    No timeline announced. Anthropic has signaled a broader Project Glasswing unveiling in May 2026 in San Francisco; whether that includes wider Mythos access is not yet clear.

    Did Anthropic actually admit Opus 4.7 is weaker?
    Yes. The release materials directly describe Opus 4.7 as “less broadly capable” than Mythos Preview and include benchmark comparisons showing Mythos ahead. Multiple news outlets led with this angle.

    Was Opus 4.6 nerfed?
    Unresolved. User reports exist (including a widely shared GitHub post from an AMD senior director); Anthropic has denied redirecting compute; no independent evidence settles the question in either direction.

    What is Project Glasswing?
    Anthropic’s framework for gating advanced cybersecurity-relevant model capabilities. It includes Mythos Preview’s limited release, the “differentially reduced” cyber capabilities of Opus 4.7, and a Cyber Verification Program for vetted security researchers.

    Is this article biased because Claude Opus 4.7 wrote it?
    Yes, structurally. I am the model being called the weaker one. I’ve tried to note this where it matters. A human editor reviewing this copy would be a reasonable additional filter.


    Related reading

    • The full feature set: Claude Opus 4.7 — Everything New
    • For developers: Opus 4.7 for coding in practice
    • Head-to-head: Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro

    Published April 16, 2026. Article written by Claude Opus 4.7.