Claude Code pricing has stopped being a clean sticker number and started being a question of which ceiling you hit first. There is a $20 plan, a $100 plan, and a $200 plan — and underneath all three sits a 5-hour rolling window, a weekly active-hours cap added in August 2025, and a per-model multiplier that quietly makes Opus 4.7 the most expensive thing you can do inside the terminal. If you came looking for the right plan, the honest answer is: it depends on whether you are mostly a Sonnet operator or you live in Opus.
The three subscription tiers, stripped down
The three subscription tiers, stripped down.
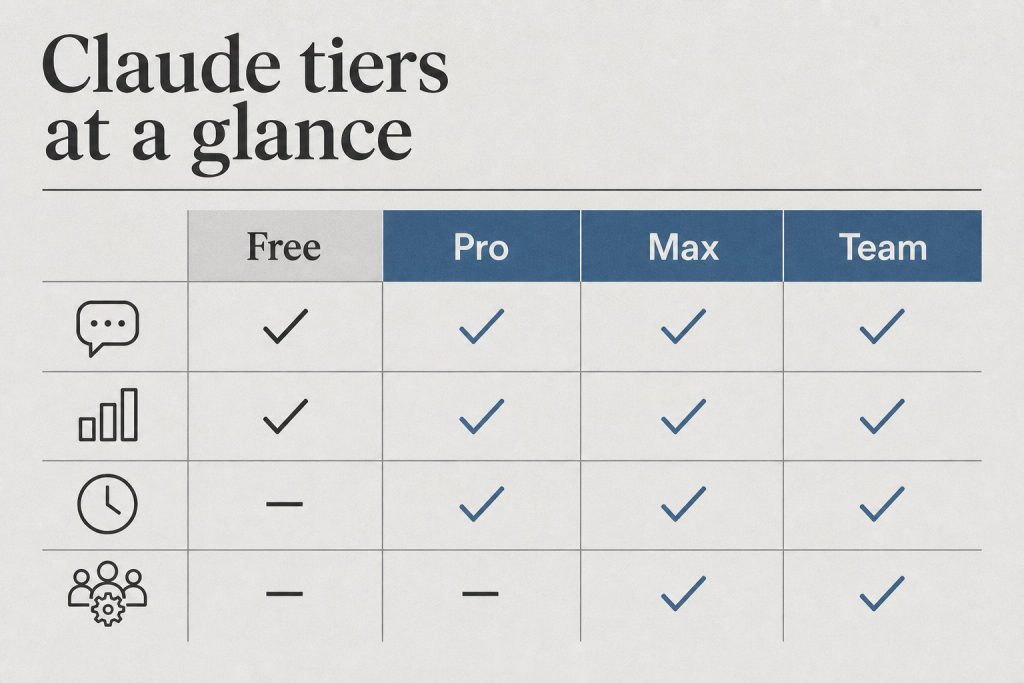
Pro — $20/month. Access to Claude Code in the terminal, web, and desktop, with both Sonnet 4.6 and Opus 4.7 available. The practical envelope is about 44,000 tokens per 5-hour window and roughly 40–80 weekly active hours on Sonnet, depending on session concurrency. This is the plan for someone running Claude Code a few hours a day on focused work — refactors, scoped feature builds, debugging passes — not someone leaving an agent running while they eat lunch.
Max 5x — $100/month. Five times the Pro envelope, plus priority during peak demand. The window allocation lands around 88,000 tokens per 5-hour block. This is the tier where you stop thinking about token budgets during a single working day and start thinking about them across a whole week. Picked correctly, it is the cheapest way to use Claude Code as your primary IDE companion without flipping over to API billing.
Max 20x — $200/month. Twenty times Pro — about 220,000 tokens per window — which translates to roughly 480 Sonnet-hours or about 40 Opus-hours per week before the weekly cap kicks in. Real-world reports from early 2026 had $200/month users watching single Opus prompts eat 10–20% of their daily allocation; Anthropic publicly acknowledged the problem, expanded capacity, and doubled the 5-hour rate limit for Pro and Max accounts. If you are running Claude Code across multiple repos all week and reaching for Opus on the hard problems, this is the tier that stops you from staring at a rate-limit wall.
The API, as a sanity check
The API, as a sanity check.
If you want a sanity check on whether the subscription math works, price the same workload against the API:
Claude Haiku 4.5 (claude-haiku-4-5-20251001): $1.00 input / $5.00 output per million tokens
Claude Sonnet 4.6 (claude-sonnet-4-6): $3.00 input / $15.00 output per million tokens
Claude Opus 4.7 (claude-opus-4-7): $5.00 input / $25.00 output per million tokens
Prompt caching is the lever almost nobody uses correctly. Cache writes cost 1.25x input price for the 5-minute TTL or 2.0x for the 1-hour TTL, but cache reads cost 0.10x — a 90% discount on every subsequent request that hits the same context. If your .clauderules file, project map, and the file you are editing are all stable for an hour, the bill on a long pairing session can drop by an order of magnitude. The Batch API knocks another 50% off both directions for asynchronous workloads, which is worth knowing if you are running large refactor sweeps.
One trap on Opus 4.7 specifically: the model uses a new tokenizer that inflates token counts by up to 35% on identical text compared to Opus 4.6. The headline price did not change, but your effective spend per request did — sometimes by nothing, sometimes by a third, depending on the content. If you migrated from Opus 4.6 and your bill went up without your prompt patterns changing, that is the reason.
How to actually choose
How to actually choose.
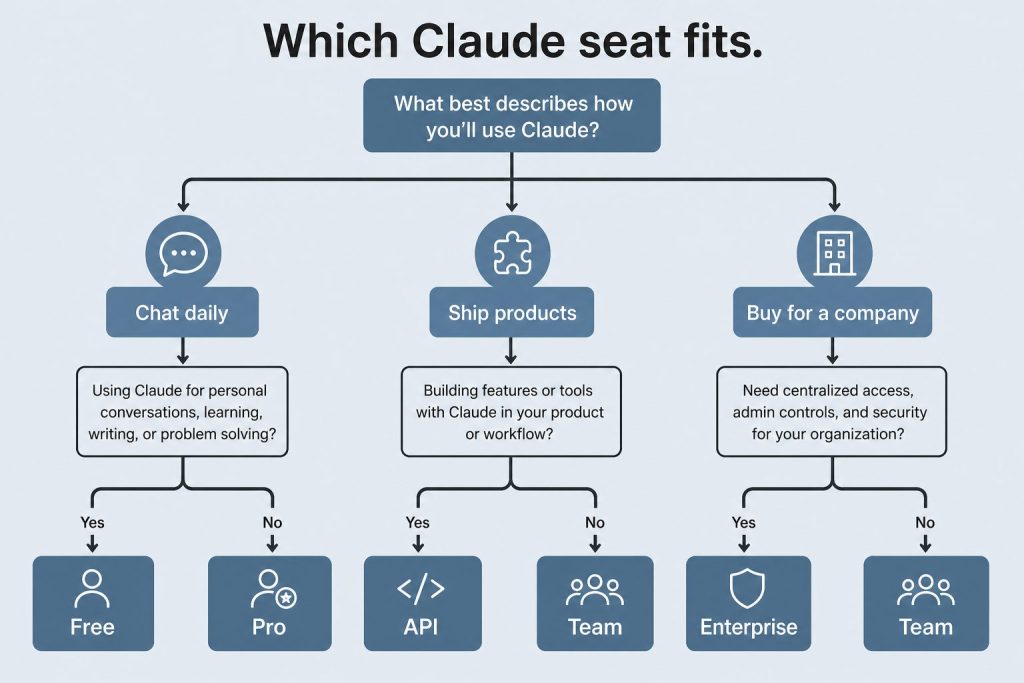
The cleanest way to pick a plan is to first decide your model mix, then your weekly hours.
If you are mostly a Sonnet operator — long agentic runs, multi-file edits, codebase Q&A, with Opus only reached for on the architectural questions — Pro at $20 is plausible up to about 5–8 hours of focused use per day, Max 5x covers most full-time individual developers, and Max 20x is overkill unless you are running multiple sessions in parallel.
If you live in Opus — long-horizon agentic work, hard refactors across many files, anything where you would rather have one good attempt than three Sonnet retries — Pro will frustrate you within two weeks, Max 5x is the realistic floor, and Max 20x is the only tier that gives you a defensible Opus envelope without bouncing over to API billing.
And if you are running Claude Code across multiple repos all week, leaving agents to grind on tasks while you do other things, Max 20x is the only subscription that holds up — and even then, the weekly cap is real. Use the API for the spillover and you will still come out cheaper than trying to brute-force a smaller plan.
The number that matters
One developer’s public report this year: roughly 10 billion tokens consumed across Claude Code over eight months. API metered cost would have exceeded $15,000. The same workload on Max at $100/month for the same window came in around $800 — about 93% cheaper. That is the gap that makes the subscription model worth taking seriously, even when the rate limits feel arbitrary. The $200 tier is not a vanity number; it is the price Anthropic charges to stop being a meaningful constraint on your workflow.
The right way to read Claude Code pricing in May 2026 is not to ask which plan is cheapest. It is to ask which plan is the cheapest one that disappears — the one that stops appearing in your day. For most full-time developers reaching for Opus regularly, that plan is Max 20x. For everyone else, Max 5x is the first plan that actually gets out of your way.
If you set up Claude MCP six months ago and have not touched the config since, three things have changed underneath you: the recommended transport, how tools are loaded into context, and how teams share server configs. None of these are cosmetic. If you ignore them, you are leaving tokens, money, and stability on the table.
This is the working Claude MCP setup I use in May 2026 — what the claude mcp add command actually does, which scope to pick, what the deprecation of SSE means in practice, and where Claude Code still falls short.
The three-scope mental model
The three-scope mental model.
Every MCP server you wire into Claude Code lives at exactly one of three scopes. Get this wrong and you will either leak credentials into git or wonder why your teammate cannot use the same database the AI just queried.
Local (default): the server is available only to you, only inside the current project. Config is written into your project’s entry inside ~/.claude.json. Good for project-specific servers like a dev database or a Sentry project key you do not want other repos to inherit.
User: the server is available to you across every project on your machine. Also stored in ~/.claude.json. This is where GitHub, search providers, and personal productivity servers belong.
Project: the server is written to a .mcp.json file at the repo root and shared with the whole team via git. Claude Code prompts for approval the first time a teammate opens the project — by design, because anyone who can push to the repo can wire a new server into your environment.
When the same server is defined in more than one scope, Claude Code resolves it in this order: local beats project beats user beats plugin-provided. This is the part that bites people the most. If you have a “github” entry at user scope and someone adds a different “github” entry at project scope in .mcp.json, the project definition wins for that repo. Run claude mcp list when something behaves strangely.
The commands you actually need
The commands you actually need.
The CLI is more useful than the docs make it look. Three commands cover ~90% of real setup work:
# Add a remote HTTP MCP server at user scope (available everywhere)
claude mcp add --transport http hubspot --scope user https://mcp.hubspot.com/anthropic

# Add a local stdio server scoped only to this project
claude mcp add my-db -s local -- node ./scripts/db-mcp.js

# Share a server with your team via the repo's .mcp.json
claude mcp add my-server -s project -- node server.js
The short flag is -s, the long is --scope. The -- separator is required for stdio servers because everything after it is treated as the literal command to spawn. Forget it and Claude Code will try to interpret your Node arguments as its own flags.
SSE is dead. Use Streamable HTTP.
If your MCP server documentation still tells you to use the sse transport, the documentation is stale. The MCP spec dated 2025-03-26 introduced Streamable HTTP and simultaneously deprecated HTTP+SSE. Through 2026, vendor after vendor has set hard cutoff dates — Atlassian’s Rovo MCP server keeps SSE around until June 30, 2026 and then drops it; Keboola pulled SSE on April 1; Cumulocity’s AI Agent Manager flipped to Streamable HTTP on May 8.
Why this matters beyond a name change: SSE required Claude Code to hold a persistent connection to a single server replica, which broke horizontal scaling and made every transient network blip a reconnection drama. Streamable HTTP is stateless. Multiple replicas behind a load balancer just work. If you have flaky MCP connections in production, the first thing to check is whether the server is still on SSE.
For new setups, use --transport http. The older --transport sse still functions but is on the deprecation path.
Tool Search is the feature you should actually care about
The single biggest change in how Claude Code uses MCP in 2026 is lazy tool loading via Tool Search. Older MCP clients dumped every tool schema from every connected server into the model’s context window at the start of every conversation. With ten servers wired up that could easily be 20,000+ tokens of overhead before you typed a single character.
Tool Search inverts this. Claude Code keeps only the server names and short descriptions resident. When a tool is actually needed, it fetches that tool’s full schema on demand. Anthropic’s own documentation says this reduces tool-definition context usage by roughly 95% versus eager-loading clients. In practice that means you can run a serious MCP fleet — GitHub, Sentry, a database, a search provider, your internal API — without quietly burning through your context budget. The Sonnet 4.6 and Opus 4.7 1M-token context window does not save you here, because anything you let crowd the prompt is also being re-read on every turn.
Companion feature: list_changed notifications. An MCP server can now tell Claude Code “my tool list changed” and Claude Code refreshes capabilities without a disconnect-reconnect dance. If you build your own server, emit this when you swap tool definitions and you save users a restart.
What it still gets wrong
Honest take: claude mcp list still does not surface scope information for every entry in a useful way — there is an open issue on the anthropics/claude-code repo asking for it (#8288 if you want to track). Project-scoped servers from .mcp.json have a separate history of not appearing in the list output (#5963) depending on how you opened the project. If you cannot find a server, check both ~/.claude.json and ./.mcp.json directly.
The other rough edge is the project-approval prompt. The first time you open a repo with a new .mcp.json, Claude Code asks you to approve each project-scoped server. That is the right security default. It is also infuriating in CI or any non-interactive shell, where the prompt blocks the session. The current workaround is to bake the servers in at user scope on build agents so the project-scope approval never fires in CI. A cleaner non-interactive approval flow is the single most-requested fix I see in real teams.
The setup I would run on a new machine today
The setup I would run on a new machine today.
User-scope: GitHub, a code search server, and a single notes/Notion server. Project-scope in each repo’s .mcp.json: whatever database the project owns and whatever observability backend it reports to. Local-scope: anything experimental I am evaluating but do not want my team or my other repos to inherit.
Pin --transport http on everything remote. Skip Desktop Extensions (.dxt) for anything you want versioned with the codebase — they are a Claude Desktop convenience, not a Claude Code primitive, and they hide the config from your team. Run claude mcp list when something is off and read .mcp.json directly when list is unhelpful.
That is the whole working model. The pieces that matter — three scopes, Streamable HTTP, Tool Search — fit on a single screen. The pieces that have not caught up yet — list output, non-interactive approvals — are visible in the issue tracker and will move.
You’ve been there. You add a rule to CLAUDE.md — “always run prettier after editing files” — and Claude follows it, most of the time. Then it doesn’t. The formatter doesn’t run, the lint check gets skipped, and you’re back to reviewing diffs manually.
Hooks fix this. Claude Code hooks are shell commands, HTTP endpoints, or LLM prompts that fire deterministically at specific points in Claude’s agentic loop. Unlike CLAUDE.md instructions, which are advisory, hooks are enforced at the execution layer — Claude cannot skip them.
As of early 2026, Claude Code ships with 21 lifecycle events across four hook types. This article covers the two that matter most for daily workflow: PreToolUse and PostToolUse.
How Hooks Work Architecturally
How Claude Code hooks work architecturally.
Claude Code’s agent loop is a continuous cycle: receive input → plan → execute tools → observe results → repeat. Hooks intercept this loop at named checkpoints.
Every hook is defined in .claude/settings.json under a hooks key. A hook entry has three parts: the lifecycle event name, an optional matcher (a regex against tool names), and the handler definition — either a shell command, an HTTP endpoint, or an LLM prompt.
That’s it. Every file Claude writes or edits now auto-formats. No CLAUDE.md reminders, no hoping Claude remembers — the formatter runs on every single Write or Edit tool call, period.
PreToolUse: Enforce Before Claude Acts
PreToolUse — enforce before Claude acts.
PreToolUse fires before Claude executes any tool. Your hook receives the full tool call — name, inputs, arguments — and can return one of three signals:
Exit 0 → allow the tool call to proceed
Exit 2 → block the tool call; Claude receives your error message and adjusts
Exit 1 → hook error; Claude proceeds but logs the failure
This makes PreToolUse the right place for guardrails. Here’s a real example: blocking npm in a bun project.
#!/bin/bash
# .claude/hooks/check-package-manager.sh
# Blocks npm commands in projects that use bun

if echo "$CLAUDE_TOOL_INPUT_COMMAND" | grep -qE "^npm "; then
  echo "Error: This project uses bun, not npm. Use: bun install / bun run / bun add" >&2
  exit 2
fi
exit 0
Now when Claude tries npm install, the hook exits 2, Claude sees the error message, and it switches to bun install without you intervening. The correction happens in the same turn.
Another production pattern: blocking writes to protected paths.
#!/bin/bash
# Prevent Claude from modifying migration files already run in production
if echo "$CLAUDE_TOOL_INPUT_FILE_PATH" | grep -qE "db/migrations/"; then
  echo "Error: Migration files are immutable after deployment. Create a new migration instead." >&2
  exit 2
fi
exit 0
PostToolUse: React After Claude Acts
PostToolUse fires after a tool completes successfully. It can’t block execution, but it can provide feedback — and it can run any side-effect you need automatically.
#!/bin/bash
# Run affected tests after any source file edit
FILE="$CLAUDE_TOOL_INPUT_FILE_PATH"
if echo "$FILE" | grep -qE "\.(ts|js|py)$"; then
  if [ -f "package.json" ]; then
    npx jest --testPathPattern="$(basename ${FILE%.*})" --passWithNoTests 2>&1 | tail -5
  fi
fi
Claude Code exposes context about the triggering tool call through environment variables. The ones you’ll use most:
Variable
Value
$CLAUDE_TOOL_NAME
Name of the tool being called (e.g., Edit, Bash, Write)
$CLAUDE_TOOL_INPUT_FILE_PATH
File path for Edit, Write, Read calls
$CLAUDE_TOOL_INPUT_COMMAND
Shell command for Bash calls
$CLAUDE_SESSION_ID
Current session ID — useful for audit logging
$CLAUDE_TOOL_RESULT_OUTPUT
Output of the tool (PostToolUse only)
These are injected by Claude Code before your hook runs. You don’t configure them — they’re always there.
The Model Question: Which Claude Runs Agentic Tasks?
One practical consideration for hook-heavy workflows: the default model affects how well Claude responds to hook feedback. As of May 2026:
claude-opus-4-7 ($5/MTok input, $25/MTok output) — highest agentic coding capability; best at interpreting hook rejection messages and self-correcting without re-asking
claude-sonnet-4-6 ($3/MTok input, $15/MTok output) — strong balance of speed and reasoning; handles most hook-corrected flows well
claude-haiku-4-5-20251001 ($1/MTok input, $5/MTok output) — fastest; may require more explicit hook messages to course-correct reliably
For workflows with complex PreToolUse guardrails — especially ones that provide long error messages with corrective instructions — Opus 4.7 handles the feedback loop most reliably. For simpler PostToolUse automation (formatters, notifications), model choice doesn’t matter; the hook runs regardless.
To configure the model: export ANTHROPIC_MODEL=claude-opus-4-7 before launching Claude Code, or set it in your team’s .env.
Hooks vs. CLAUDE.md: When to Use Each
Hooks vs CLAUDE.md — when to use each.
CLAUDE.md is the right place for context, preferences, and guidance — things you want Claude to know about your project. Hooks are the right place for behavior that must happen every time without exception.
The practical test: if failing to follow the instruction costs you five minutes of manual cleanup, put it in a hook. If it’s a style preference or a reminder about architecture decisions, put it in CLAUDE.md. The two are complementary — you’ll likely end up with both in any mature project setup.
A team that gets this right builds CLAUDE.md as documentation for Claude and hooks as the CI/CD equivalent for the agentic loop.
Getting Started
The fastest path to a working hook setup:
Create .claude/settings.json in your project root if it doesn’t exist
Add a PostToolUse hook wired to your formatter — this is low-risk and immediately valuable
Test it by asking Claude to edit a file; the formatter should run automatically
Add PreToolUse guardrails for any tool calls that have caused problems in the past
The official hooks reference is at code.claude.com/docs/en/hooks — it covers all 21 lifecycle events, HTTP handler format, and the full JSON output schema for hook responses.
Hooks are the difference between Claude Code as a powerful suggestion engine and Claude Code as a reliable automation layer. Once you have a PostToolUse formatter running on every edit, going back feels like working without version control.
Most teams I see roll out Claude Code by handing every engineer the install command and walking away. Three weeks later, half the repo has personal preferences committed to .claude/settings.json, the other half has a CLAUDE.md that contradicts the actual review process, and someone’s customized subagent is silently making code changes nobody else on the team understands.
There is a better way, and it lives in the split between three files: CLAUDE.md, .claude/settings.json, and .claude/settings.local.json. Get this split right, and Claude Code becomes a force multiplier for the team. Get it wrong, and you are shipping AI-generated code that nobody owns.
The Three-File Split
The three-file split for team Claude Code.
Here is the rule, no exceptions:
CLAUDE.md — committed. Project root. Every engineer’s session reads this at startup. Put your architectural decisions, preferred libraries, naming conventions, and a review checklist here. If you would not write it on a whiteboard for a new hire, it does not belong here.
.claude/settings.json — committed. Team-wide tool permissions, default models, and hooks. This is the file that keeps personal flagship-model enthusiasts from blowing through your team’s budget when claude-sonnet-4-6 would have done the job. If you let everyone default to claude-opus-4-7 for routine refactors, your monthly invoice will tell you about it.
.claude/settings.local.json — gitignored. Personal preferences, individual MCP server configs, anything that varies by engineer. Add this line to your .gitignore on day one:
.claude/settings.local.json
If you do not, someone will commit credentials by Friday. Audit your existing repo right now: git log --all --full-history -- .claude/settings.local.json will surface any history that needs scrubbing.
The mistake I see most often is teams committing settings.local.json because someone copied a tutorial that did not make the distinction clear. That copy-paste error is the single most common Claude Code rollout failure I have seen this year.
Shared Subagents Are the Real Win
Shared subagents are the real win.
Project subagents live in .claude/agents/ and they ship with the repo. This is where teams compound value. A subagent for security review, one for accessibility audits, one for SQL migration safety — defined once, used by every engineer, every PR.
A subagent definition is a markdown file with YAML frontmatter and a system prompt. When you commit it, every teammate’s claude invocation can call it. The subagent inherits your CLAUDE.md context automatically, so you do not have to redefine the project’s coding standards inside each agent.
Here is the trap: do not put twelve subagents in there on day one. Start with one. The team’s most painful repeated review task is the right candidate. Whatever takes a long time and pulls in multiple engineers per PR — that is your first subagent. After two weeks of using it, you will know whether the second one is worth defining.
CLAUDE.md Is a Living Document, Not a Manifesto
The longest CLAUDE.md files I see are the worst-performing. Engineers do not read 4,000-word context files, and neither does Claude in any useful way — at some point you are paying for tokens that just dilute the signal.
The CLAUDE.md files that actually shape behavior are usually compact, structured around three things:
What this codebase is and what it is not.
The handful of rules that get a PR rejected — test coverage, naming, error handling, dependency policy.
A pointer to where deeper documentation lives.
If your CLAUDE.md has a “philosophy” section, delete it. If it has a “history of the project” section, delete it. The file is read every session — make every line earn its tokens.
CI/CD: Run Claude Code on PRs, Not in Place of Reviewers
The pattern that works in CI is automated triage, not automated approval. A GitHub Actions workflow that runs Claude Code on every PR to check for things humans miss — missing tests, secrets in logs, public APIs without docstrings — adds value. A workflow that approves and merges PRs adds liability.
Anthropic’s official GitHub Actions integration handles the auth and runs Claude Code headlessly. The realistic use cases:
Comment on PRs with a structured review (not a merge gate).
Auto-label PRs based on the diff.
Flag suspected regressions before a human reviewer opens the PR.
Avoid: anything that auto-merges, anything that posts directly to production-facing systems, anything that calls a paid API on every commit to a feature branch. The bill compounds quickly when CI fires Claude on every push to every developer branch. Gate the workflow on PR-target branches only, or on labels.
Where Claude Code for Teams Loses Today
The honest list:
No native role-based permissions inside a single repo. If you want a junior engineer’s Claude Code to be more restricted than a senior’s, you have to enforce it through settings.json and trust everyone to not edit it. The Enterprise plan adds SSO, SCIM, and audit logs at the workspace level, but inside the repo, Claude Code itself does not differentiate by role.
No first-class secret scanning before commits. Hooks can plug this gap, but you have to wire pre-commit yourself.
Shared MCP servers are still per-developer auth. A team-shared Linear or Jira MCP, for example, still requires each engineer to authenticate individually.
The Team plan addresses workspace-level governance through Premium seats, which is the tier that actually unlocks Claude Code for teammates. The Enterprise plan layers on SSO, SCIM, and audit logs. Neither makes the in-repo configuration questions go away — those are still your team’s problem to solve.
Model Selection Is a Team Decision
This one matters more than people realize. Default everyone in .claude/settings.json to claude-sonnet-4-6 for day-to-day work, with claude-opus-4-7 available for explicitly hard tasks. The current Anthropic lineup as of this writing — flagship claude-opus-4-7, workhorse claude-sonnet-4-6, fast claude-haiku-4-5-20251001 — is documented at docs.anthropic.com/en/docs/about-claude/models, and the model strings change frequently enough that hard-coding them in scripts has bitten me twice this year. Read that page, do not memorize it.
A team that defaults to flagship for everything and a team that defaults to workhorse with selective escalation will see meaningfully different invoices for substantially the same productivity. Make the choice consciously.
The 20-Minute Setup
The 20-minute team setup.
If you are rolling Claude Code out to a team next week:
Add .claude/settings.local.json to .gitignore. First commit, today.
Write a focused CLAUDE.md covering review-blocking rules. Ship it short.
Create one subagent in .claude/agents/ for the team’s most painful review task.
Add a single GitHub Actions workflow that runs Claude Code on PRs in comment-only mode.
Schedule a 30-minute team review of the CLAUDE.md every two weeks. Delete more than you add.
That is it. Everything else is iteration. The teams that succeed with Claude Code treat the configuration as code — versioned, reviewed, and pruned. The teams that fail treat it as a personal productivity tool that happens to be in a shared repo.
Decide which kind of team you want to be before the third engineer commits.
Two new Claude Code capabilities shipped in the April sprint that have received almost no coverage despite being significant workflow expansions: Ultraplan, a cloud-hosted agentic planning workflow, and Ultrareview, a deep multi-pass code review command. Together they represent Claude Code’s first serious steps toward being an agentic planning tool, not just an interactive coding assistant.
Ultraplan: Cloud-Hosted Agentic Planning
Ultraplan — cloud-hosted agentic planning.
Ultraplan is currently in early preview. The workflow is three steps:
Draft in the CLI — from your terminal, describe the task or project you want Claude Code to plan. Ultraplan generates a structured execution plan: steps, dependencies, tool calls, expected outputs, error-handling branches.
Review in the browser — the plan is pushed to a cloud-hosted web editor where you can read it in a structured interface, add comments, modify steps, flag concerns, and approve or reject sections. This is the human-in-the-loop gate that makes agentic execution trustworthy.
Run remotely or pull back local — once approved, the plan can execute in Anthropic’s cloud infrastructure (no local machine required, runs while your laptop is off) or be pulled back to execute locally with full observability in your terminal.
The remote execution capability is the most significant aspect. This is Claude Code’s first “runs while your laptop is closed” feature — distinct from Cowork Routines (which are consumer-facing) and designed specifically for developer workflows. A migration plan, a batch refactoring job, a test suite generation task, or a dependency upgrade across a large codebase can be approved, handed to cloud execution, and completed overnight without a machine staying on.
When to Use Ultraplan
When to use Ultraplan.
Ultraplan is designed for tasks where you want to review the approach before committing to execution — not for quick, single-step tasks. The review step adds 5–15 minutes to the workflow. That is worth it when:
The task spans multiple files, services, or systems where a wrong step has cascading effects
You are working in a production codebase where mistakes have real consequences
The task will take more than 30 minutes to execute and you want human review before investing that time
You are using remote execution and cannot monitor progress in real time
You are delegating the task to a junior developer or teammate who will execute the plan
For quick tasks — generate a function, fix a specific bug, explain this code — use standard Claude Code. Ultraplan’s value scales with task complexity and execution risk.
Ultrareview: Deep Multi-Pass Code Review
Ultrareview — deep multi-pass code review.
The claude ultrareview subcommand applies multiple sequential review passes to code, each with a different evaluation focus:
Maintainability review — naming clarity, function size and cohesion, documentation gaps, test coverage, coupling and cohesion
Each pass generates findings, and Ultrareview synthesizes them into a prioritized report with severity ratings and specific remediation recommendations. The output is designed to go directly into a pull request review comment or a team review document.
Ultrareview vs. Standard Review
Standard claude review applies a single review pass optimized for breadth — it catches obvious issues quickly across all dimensions. Ultrareview applies specialized depth in each dimension sequentially. The trade-off is token cost and time: Ultrareview consumes 3–5× more tokens than standard review and takes proportionally longer.
The recommended workflow: use standard review on every pull request as part of your CI pipeline. Reserve Ultrareview for high-stakes merges — releases, security-sensitive features, architecture changes, any code that will touch production payment or authentication flows.
Both features are available now to Claude Code users on Pro and above. Ultraplan is in early preview — activate it via claude ultraplan --enable-preview. Ultrareview is generally available — run claude ultrareview [file or directory] from any Claude Code session.
Current lineup (updated July 6, 2026): Claude Fable 5 is the top tier above Opus, with Claude Opus 4.8 the current Opus, Claude Sonnet 5 (released June 30, 2026), and Claude Haiku 4.5. Opus 4.7 is now a legacy model. Full lineup: Claude Fable 5 guide. This article compares Claude Opus 4.7 pricing to Opus 4.6 as a historical baseline. Opus 4.7 has since been superseded by Opus 4.8 and the Fable 5 top tier. Opus 4.7 and 4.6 share the $5/$25 per MTok list price. See current model tracker →
Anthropic announced Claude Opus 4.7 with the same list pricing as Opus 4.6: $5 per million input tokens, $25 per million output tokens. What Anthropic did not announce — and what Simon Willison surfaced through direct tokenizer analysis — is that Opus 4.7 generates approximately 1.46× more tokens for the same text output as Opus 4.6. That is a ~40% real-world cost increase at unchanged list prices.
This is not a criticism of the model. Opus 4.7 is genuinely better — 3× higher vision resolution, a new xhigh effort level, improved instruction following, higher-quality interface and document generation. The performance gains are real. The cost increase is also real, and it is not being communicated transparently in Anthropic’s pricing documentation. If you are budgeting for Claude API usage, you need to account for this.
What Token Inflation Means
What token inflation means.
Token inflation occurs when a model generates more tokens to express the same semantic content. It happens for several reasons: more detailed reasoning traces, more verbose explanations, additional caveats and structure, or architectural changes in how the model constructs its output. Opus 4.7 appears to produce more elaborated, structured responses than 4.6 by default — which accounts for the 1.46× multiplier.
The practical effect: if you were spending $10,000/month on Opus 4.6 for a production application, the same application workload on Opus 4.7 costs approximately $14,600/month — before any intentional use of the new xhigh effort level, which adds further token consumption on top of the baseline inflation.
How to Measure Your Actual Exposure
How to measure your actual exposure.
Do not estimate — measure. Here is the four-step process:
Pull your last 30 days of Anthropic API usage data from your platform dashboard. Note your average output token count per call for your primary workloads.
Run a representative sample of those same workloads on Opus 4.7 using the API directly, with identical prompts and system messages. Log output token counts for each call.
Calculate your actual multiplier — it may be higher or lower than 1.46× depending on your specific prompt patterns and use cases. Tasks with highly constrained output formats (structured JSON, fixed-length summaries) will see lower inflation than open-ended generation.
Apply the multiplier to your budget model and adjust your spend projections before migrating production workloads to Opus 4.7.
Mitigation Strategies
Mitigation strategies.
Several approaches can reduce the cost impact while preserving Opus 4.7’s quality gains:
Explicit length constraints in system prompts. Adding “Respond in 200 words or fewer” or “Use bullet points, not paragraphs” constraints does not reduce quality on most tasks but meaningfully constrains token generation. Test which of your prompts accept length constraints without quality loss.
Model routing by task type. Use the new gateway model picker in Claude Code, or implement explicit routing in your API calls: Opus 4.7 for the tasks where quality genuinely requires it, Sonnet 4.6 or Haiku 4.5 for high-volume tasks where speed and cost matter more than peak quality. The cost difference between Haiku and Opus is roughly 30×.
Avoid xhigh effort unless necessary. The new xhigh effort level in Opus 4.7 consumes significantly more tokens than the default effort setting. Reserve it for tasks where maximum quality is genuinely required — complex reasoning, high-stakes code generation, detailed document analysis. Do not set it as a default.
Evaluate Sonnet 4.6 for your use case. For many production workloads, Claude Sonnet 4.6 at $3/$15 per million tokens delivers quality that is indistinguishable from Opus 4.7 at the task level. The Opus tier is most clearly differentiated on the most difficult tasks — extended chain-of-thought reasoning, complex multi-step coding, nuanced creative judgment. Benchmark your specific workloads before assuming Opus is required.
The Transparency Gap
Anthropic’s pricing page lists token costs accurately. What it does not document is how output token counts change across model versions for equivalent tasks. This is an industry-wide gap, not an Anthropic-specific failing — no major AI provider documents per-task token consumption differences between model versions in their pricing documentation.
The practical implication for any team managing AI infrastructure: treat “same price per token” announcements as partial information. Always benchmark your actual workloads on new model versions before migrating production traffic. The 1.46× multiplier Willison measured is for general text — your specific workload multiplier will be different, and you need to know it before your invoice arrives.
Claude Opus 4.7 is available now through the Anthropic API at platform.claude.com. API pricing: $5/M input tokens, $25/M output tokens. Measure before you migrate.
Claude Code shipped v2.1.126 today, May 1, 2026. This is the 9th release in April’s sprint and continues what has been a 2–3 releases per week cadence throughout the month. Here is the complete picture of what shipped this week across v2.1.120 through v2.1.126, with operational context for each feature that actually matters.
v2.1.126 — Today’s Release
v2.1.126 — today’s release.
Gateway Model Picker
The gateway model picker allows you to route different tasks within a single Claude Code session to different models. This is the first step toward Claude Code as a multi-model orchestration layer rather than a single-model coding assistant. Practical use: run Haiku 4.5 on file reading, search, and summarization tasks where speed matters; route Opus 4.7 at complex reasoning, architecture decisions, and code generation where quality is the priority. The cost reduction on high-volume workflows can be material — Haiku is roughly 30× cheaper per token than Opus.
PowerShell as Primary Shell on Windows — Git Bash No Longer Required
This is the most significant quality-of-life change in this release for enterprise Windows shops. Claude Code previously required Git Bash as its terminal environment on Windows, which meant every Windows developer needed a non-standard shell installation, created friction in corporate IT environments with software approval processes, and produced a different developer experience than Mac/Linux teammates.
Starting with v2.1.126, PowerShell is the primary shell on Windows. Git Bash is no longer required. For enterprise teams where half the developer fleet runs Windows and software installation requires IT approval, this removes a significant deployment barrier. Claude Code is now a standard Windows application from an IT management perspective.
OAuth Code Terminal Input for WSL2, SSH, and Containers
Authentication in headless environments — WSL2 sessions, SSH remote development, Docker containers — previously required workarounds. v2.1.126 adds OAuth code terminal input: Claude Code displays the authorization code directly in the terminal, you paste it into your browser, and authentication completes without requiring a browser redirect to the headless environment. Eliminates the most common authentication friction point for remote and containerized development workflows.
claude project purge
New command that cleans up stale project data accumulated across sessions. For teams running Claude Code in CI/CD pipelines or long-running agent workflows, project data can accumulate and affect performance. claude project purge gives you explicit control over that cleanup rather than relying on automatic garbage collection.
v2.1.120–122 — April 28 Stack
v2.1.120–122 — April 28 stack.
alwaysLoad MCP Option
MCP servers can now be configured to always load regardless of context window state. Previously, Claude Code would make decisions about which MCP servers to initialize based on available context. alwaysLoad: true in your MCP server config guarantees that server is always available — critical for production deployments where MCP tools need to be reliably present, not conditionally loaded.
claude ultrareview Subcommand
claude ultrareview triggers a deep, multi-pass code review that goes beyond standard review. It applies multiple review personas in sequence — security researcher, performance engineer, maintainability analyst — and synthesizes findings into a prioritized report. For code that needs to meet high standards before production merge, ultrareview is the command. It consumes more tokens than standard review, so use it on pull requests that matter, not every commit.
claude plugin prune
Removes unused plugins from your Claude Code installation. As the plugin ecosystem has grown and plugin auto-update behavior has been refined in recent releases, teams accumulate plugins that are no longer active in their workflow. claude plugin prune audits your installed plugins against recent usage and removes those that have not been invoked within a configurable time window.
Type-to-Filter Skills Search
The skills picker now supports live type-to-filter — start typing a skill name and the list filters in real time. For teams with large skill libraries or plugin collections, this eliminates the scroll-and-hunt workflow that slowed skill invocation. Small UX change, large daily time savings at scale.
New environment variable that allows Claude Code running on Amazon Bedrock to specify service tier at the environment level rather than per-request. For teams using Claude Code through Bedrock as their primary deployment path — common in regulated industries that require AWS-native infrastructure — this simplifies configuration management across multiple environments and removes per-request overhead.
OpenTelemetry Improvements
Extended OpenTelemetry trace data now includes more granular span information for Claude Code operations. For enterprise teams with existing observability infrastructure (Datadog, Grafana, Honeycomb), Claude Code activity is now more fully integrated into your trace timeline — you can see exactly where Claude Code operations land within the context of your broader application traces.
v2.1.123 — April 29
Fixed OAuth 401 retry loop triggered when CLAUDE_CODE_DISABLE_EXPERIMENTAL_BETAS was set. If you were seeing repeated authentication failures in environments with that flag set, update to v2.1.123 or later immediately.
Update Now
Update now.
Update via npm install -g @anthropic-ai/claude-code@latest or through your package manager. v2.1.126 is the current stable release. For teams running Claude Code in CI/CD, update your Docker base images or pipeline steps to pin to 2.1.126.
Between April 15 and April 29, 2026, the Claude Code team shipped releases from v2.1.89 to v2.1.123 — 34 version increments in 14 days, or roughly 2–3 production releases per week. For an agentic coding tool that engineering teams run in their daily development workflow, this release cadence is worth understanding, both for what it signals about the product’s development velocity and for the practical implications of staying current.
What’s Driving the Cadence
What’s driving the cadence.
The v2.1 series is where Claude Code’s parallel agents architecture is being built out. The desktop redesign for parallel agents shipped on April 14, and the v2.1 releases since then represent the iterative work of making parallel agent workflows — running multiple agents simultaneously from a single workspace — stable and usable at production quality. Rapid iteration on a new architectural feature explains the compressed release schedule better than any other factor.
The new onboarding guide for Claude Code teams, published April 28 on code.claude.com, is a related signal. Documentation for team-scale adoption typically follows (not precedes) the stability work that makes team-scale adoption advisable. Publishing the onboarding guide now suggests the team considers the core parallel agents architecture stable enough for broader engineering team adoption.
Parallel Agents: The Architecture Change That Matters
Parallel agents — the architecture change that matters.
The April 14 desktop redesign for parallel agents is the most significant Claude Code architectural change of the quarter. Previously, Claude Code operated as a single-agent tool — one active task at a time per workspace. The parallel agents redesign allows developers to run multiple agents simultaneously, each working on independent tasks within the same workspace, with Claude coordinating between them.
The practical applications are significant: running tests while implementing a feature, refactoring one module while debugging another, generating documentation in parallel with code review. Tasks that previously required sequential attention can now run concurrently, compressing the time from specification to working code.
Implications for Engineering Teams Evaluating Adoption
Implications for engineering teams evaluating adoption.
The combination of the new onboarding guide and the parallel agents architecture makes this the right moment for engineering teams that have been evaluating Claude Code to make a decision. The tool has moved from “impressive demo” to “documented team workflow” with the April 28 guide, and the parallel agents capability meaningfully changes the productivity math for teams doing complex, multi-threaded development work.
For teams already using Claude Code, staying current with the v2.1 series matters more than it did in earlier versions. The 2–3 weekly releases aren’t cosmetic — they’re iterating on the parallel agents infrastructure that the most powerful new workflows depend on. Check the changelog at code.claude.com/docs/en/changelog before major projects to ensure you’re running a recent build.
Infosys, India’s second-largest IT services company with over 300,000 employees and clients in virtually every regulated industry on the planet, announced a strategic collaboration with Anthropic on April 29, 2026. The partnership embeds Claude — including Claude Code — into Infosys Topaz AI, the company’s enterprise AI platform, targeting telecommunications, financial services, manufacturing, and software development verticals.
What’s Actually Being Built
What’s actually being built.
The collaboration begins with a dedicated Anthropic Center of Excellence inside Infosys’s telecom practice. This isn’t a reseller agreement or a marketing partnership — it’s an engineering buildout. The Center of Excellence structure means Infosys is committing internal resources to develop Claude-powered workflows specific to telecom use cases, with the intent to replicate the model across the other three target verticals.
Claude Code’s inclusion is significant. Enterprise AI deployments at IT services firms historically mean wrapping AI around existing workflows — summarization, document processing, customer-facing chatbots. Embedding Claude Code signals that Infosys is building AI into the software development lifecycle itself, which is where the highest-value, highest-margin work in IT services actually lives.
Why Regulated Industries Are the Real Story
Why regulated industries are the real story.
Telecom, financial services, and manufacturing are three of the most compliance-heavy verticals in enterprise technology. Data residency requirements, audit trails, explainability mandates, and sector-specific regulations (TRAI in India, FCA in the UK, SEC in the US for financial services) make AI deployment substantially more complex than in unregulated industries. The fact that Infosys is leading with these verticals rather than easier targets suggests genuine confidence in Claude’s compliance posture.
For the Indian developer and enterprise market specifically, this partnership carries weight that a US-only announcement would not. Infosys is a trusted name in Indian boardrooms in a way that American AI labs, even well-regarded ones, simply aren’t yet. Anthropic gaining Infosys as an integration partner is a significant step toward the kind of enterprise credibility that accelerates procurement decisions.
The INR Pricing Gap Remains Open
It’s worth noting what the Infosys partnership doesn’t solve: direct access pricing for Indian developers and individual subscribers. Claude’s consumer and API pricing in India remains at ₹16,800/month for Pro — a figure that has generated sustained criticism in developer communities and on GitHub (issue #17432 on the Claude feedback tracker has been open for months with no response). Enterprise deals like the Infosys collaboration typically involve custom pricing negotiated well below list, which means the developers who most need relief from INR pricing aren’t the ones who benefit from this announcement.
That gap is a content opportunity and a legitimate market gap. Anthropic’s APAC expansion is clearly accelerating — Sydney office, NEC Japan partnership, now Infosys India — but the individual developer pricing story in the region hasn’t kept pace with the enterprise narrative.
Context: Anthropic’s APAC Quarter
Context: Anthropic’s APAC quarter.
The Infosys announcement is the third significant APAC move in the last two weeks. Anthropic opened a Sydney office and named Theo Hourmouzis as GM for Australia and New Zealand on April 27. The NEC Japan multi-year workforce upskilling collaboration was announced on April 24. Three moves in five days — India, Japan, Australia — is not coincidence. This is a coordinated APAC buildout, and Infosys is the India anchor.
I have been running a working second brain for long enough to have stopped thinking of it as a second brain.
I have come to think of it as an actual brain. Not metaphorically. Architecturally. The pattern that emerged in my workspace over the last year — without me intending it, without me planning it, without me reading a single neuroscience paper about it — is structurally isomorphic to how the human brain manages memory. When I finally noticed the pattern, I stopped fighting it and started naming the parts correctly, and the system got dramatically more coherent.
This article names the parts. It is the architecture I actually run, reported honestly, with the neuroscience analogy that made it click and the specific choices that make it work. It is not the version most operators build. Most operators build archives. This is closer to a living system.
The pattern has three components: a cortex, a hippocampus, and a consolidation loop that moves signal between them. Name them that way and the design decisions start falling into place almost automatically. Fight the analogy and you will spend years tuning a system that never quite feels right because you are solving the wrong problem.
I am going to describe each part in operator detail, explain why the analogy is load-bearing rather than decorative, and then give you the honest version of what it takes to run this for real — including the parts that do not work and the parts that took me months to get right.
Why most second brains feel broken
Why most second brains feel broken.
Before the architecture, the diagnosis.
Most operators who have built a second brain in the personal-knowledge-management tradition report, eventually, that it does not feel right. They can not put words to exactly what is wrong. The system holds their notes. The search mostly works. The tagging is reasonable. But the system does not feel alive. It feels like a filing cabinet they are pretending is a collaborator.
The reason is that the architecture they built is missing one of the three parts. Usually two.
A classical second brain — the library-shaped archive built around capture, organize, distill, express — is a cortex without a hippocampus and without a consolidation loop. It is a place where information lives. It is not a system that moves information through stages of processing until it becomes durable knowledge. The absence of the other two parts is exactly why the system feels inert. Nothing is happening in there when you are not actively working in it. That is the feeling.
An archive optimized for retrieval is not a brain. It is a library. Libraries are excellent. You can use a library to do good work. But a library is not the thing you want to be trying to replicate when you are trying to build an AI-native operating layer for a real business, because the operating layer needs to process information, not just hold it, and archives do not process.
This diagnosis was the move that let me stop tuning my system and start re-architecting it. The system was not bad. The system was incomplete. It had one of the three parts built beautifully. It had the other two parts either missing or misfiled.
Part one: the cortex
Part one: the cortex.
In neuroscience, the cerebral cortex is the outer layer of the brain responsible for structured, conscious, working memory. It is where you hold what you are actively thinking about. It is not where everything you have ever known lives — that is deeper, and most of it is not available to conscious access at any given moment. The cortex is the working surface.
In an AI-native workspace, your knowledge workspace is the cortex. For me, that is Notion. For other operators, it might be Obsidian, Roam, Coda, or something else. The specific tool is less important than the role: this is where structured, human-readable, conscious memory lives. It is where you open your laptop and see the state of the business. It is where you write down what you have decided. It is where active projects live and active clients are tracked and active thoughts get captured in a form you and an AI teammate can both read.
The cortex has specific design properties that differ from the other two parts.
It is human-readable first. Everything in the cortex is structured for you to look at. Pages have titles that make sense. Databases have columns that answer real questions. The architecture rewards a human walking through it. Optimize for legibility.
It is relatively small. Not everything you have ever encountered lives in the cortex. It is the active working surface. In a human brain, the cortex holds at most a few thousand things at conscious access. In an AI-native workspace, your cortex probably wants to hold a few hundred to a few thousand pages — the active projects, the recent decisions, the current state. If it grows to tens of thousands of pages with everything you have ever saved, it is trying to do the hippocampus’s job badly.
It is organized around operational objects, not knowledge topics. Projects, clients, decisions, deliverables, open loops. These are the real entities of running a business. The cortex is organized around them because that is what the conscious, working layer of your business is actually about.
It is updated constantly. The cortex is where changes happen. A new decision. A status flip. A note from a call. The consolidation loop will pull things out of the cortex later and deposit them into the hippocampus, but the cortex itself is a churning working surface.
If you have been building a second brain the classical way, this is probably the part you built best. You have a knowledge workspace. You have pages. You have databases. You have some organizing logic. Good. That is the cortex. Keep it. Do not confuse it for the whole brain.
Part two: the hippocampus
In neuroscience, the hippocampus is the structure that converts short-term working memory into long-term durable memory. It is the consolidation organ. When you remember something from last year, the path that memory took from your first experience of it into your long-term storage went through the hippocampus. Sleep plays a large role in this. Dreams may play a role. The mechanism is not entirely understood, but the function is: short-term becomes long-term through hippocampal processing.
In an AI-native workspace, your durable knowledge layer is the hippocampus. For me, that is a cloud storage and database tier — a bucket of durable files, a data warehouse holding structured knowledge chunks with embeddings, and the services that write into it. For other operators it might be a different stack: a structured database, an embeddings store, a document warehouse. The specific tool is less important than the role: this is where information lives when it has been consolidated out of the cortex and into a durable form that can be queried at scale without loading the cortex.
The hippocampus has different design properties than the cortex.
It is machine-readable first. Everything in the hippocampus is structured for programmatic access. Embeddings. Structured records. Queryable fields. Schemas that enable AI and other services to reason across the whole corpus. Humans can access it too, but the primary consumer is a machine.
It is large and growing. Unlike the cortex, the hippocampus is allowed to get big. Years of knowledge. Thousands or tens of thousands of structured records. The archive layer that the classical second brain wanted to be — but done correctly, as a queryable substrate rather than a navigable library.
It is organized around semantic content, not operational state. Chunks of knowledge tagged with source, date, embedding, confidence, provenance. The operational state lives in the cortex; the semantic content lives in the hippocampus. This is the distinction most operators get wrong when they try to make their cortex also be their hippocampus.
It is updated deliberately. The hippocampus does not change every minute. It changes on the cadence of the consolidation loop — which might be hourly, nightly, or weekly depending on your rhythm. This is a feature. The hippocampus is meant to be stable. Things in it have earned their place by surviving the consolidation process.
Most operators do not have a hippocampus. They have a cortex that they keep stuffing with old information in the hope that the cortex can play both roles. It cannot. The cortex is not shaped for long-term queryable semantic storage; the hippocampus is not shaped for active operational state. Merging them is the architectural choice that makes systems feel broken.
Part three: the consolidation loop
Part three: the consolidation loop.
In neuroscience, the process by which information moves from short-term working memory through the hippocampus into long-term storage is called memory consolidation. It happens constantly. It happens especially during sleep. It is not a single event; it is an ongoing loop that strengthens some memories, prunes others, and deposits the survivors into durable form.
In an AI-native workspace, the consolidation loop is the set of pipelines, scheduled jobs, and agents that move signal from the cortex through processing into the hippocampus. This is the part most operators miss entirely, because the classical second brain paradigm does not include it. Capture, organize, distill, express — none of those stages are consolidation. They are all cortex-layer activities. The consolidation loop is what happens after that, to move the durable outputs into durable storage.
The consolidation loop has its own design properties.
It runs on a schedule, not on demand. This is the most important design choice. The consolidation loop should not be triggered by you manually pushing a button. It should run on a cadence — nightly, weekly, or whatever fits your rhythm — and do its work whether you are paying attention or not. Consolidation is background work. If it requires attention, it will not happen.
It processes rather than moves. Consolidation is not a file-copy operation. It extracts, structures, summarizes, deduplicates, tags, embeds, and stores. The raw cortex content is not what ends up in the hippocampus; the processed, structured, queryable version is. This is the part that requires actual engineering work and is why most operators do not build it.
It runs in both directions. Consolidation pushes signal from cortex to hippocampus. But once information is in the hippocampus, the consolidation loop also pulls it back into the cortex when it is relevant to current work. A canonical topic gets routed back to a Focus Room. A similar decision from six months ago gets surfaced on the daily brief. A pattern across past projects gets summarized into a new playbook. The loop is bidirectional because the brain is bidirectional.
It has honest failure modes and health signals. A consolidation loop that is not working is worse than no loop at all, because it produces false confidence that information is getting consolidated when actually it is rotting somewhere between stages. You need visible health signals — how many items were consolidated in the last cycle, how many failed, what is stale, what is duplicated, what needs human attention. Without these, you do not know whether the loop is running or pretending to run.
When I got the consolidation loop working, the cortex and hippocampus started feeling like a single system for the first time. Before that, they were two disconnected tools. The loop is what turns them into a brain.
The topology, in one diagram
If I were drawing the architecture for an operator who is considering building this, it would look roughly like this — and it does not matter which specific tools you use; the shape is what matters.
Input streams flow in from the things that generate signal in your working life. Claude conversations where decisions got made. Meeting transcripts and voice notes. Client work and site operations. Reading and research. Personal incidents and insights that emerged mid-day.
Those streams enter the consolidation loop first, not the cortex directly. The loop is a set of services that extract structured signal from raw input — a claude session extractor that reads a conversation and writes structured notes, a deep extractor that processes workspace pages, a session log pipeline that consolidates operational events. These run on schedule, produce structured JSON outputs, and route the outputs to the right destinations.
From the consolidation loop, consolidated content lands in the cortex. New pages get created for active projects. Existing pages get updated with relevant new information. Canonical topics get routed to their right pages. This is how your working surface stays fresh without you having to manually copy things into it.
The cortex and hippocampus exchange signal bidirectionally. The cortex sends completed operational state — finished projects, finalized decisions, archived work — down to the hippocampus for durable storage. The hippocampus sends back canonical topics, cross-references, and AI-accessible content when the cortex needs them. This bidirectional exchange is the part that most closely mirrors how neuroscience describes memory consolidation.
Finally, output flows from the cortex to the places your work actually lands — published articles, client deliverables, social content, SOPs, operational rhythms. The cortex is also the execution layer I have written about before. That is not a contradiction with the cortex-as-conscious-memory framing; in a human brain, the cortex is both the working memory and the source of deliberate action. The analogy holds.
The four-model convergence
I want to pause and tell you something I did not know until I ran an experiment.
A few weeks ago I gave four external AI models read access to my workspace and asked each one to tell me what was unique about it. I used four models from different vendors, deliberately, to catch blind spots from any single system.
All four models converged on the same primary diagnosis. They did not agree on much else — their unique observations diverged significantly — but on the core architecture, they converged. The diagnosis, in their words translated into mine, was:
The workspace is an execution layer, not an archive. The entries are system artifacts — decisions, protocols, cockpit patterns, quality gates, batch runs — that convert messy work into reusable machinery. The purpose is not to preserve thought. The purpose is to operate thought.
This was the validation of the thesis I have been developing across this body of work, from an unexpected source. Four models, evaluated independently, landed on the same architectural observation. That was the moment I knew the cortex / hippocampus / consolidation-loop framing was not just mine — it was visible from the outside, to cold readers, as the defining feature of the system.
I bring this up not to show off but to tell you that if you build this pattern correctly, external observers — human or AI — will be able to see it. The architecture is not a private aesthetic. It is a thing a well-designed system visibly is.
Provenance: the fourth idea that makes the whole thing work
There is a fourth component that I want to name even though it does not have a neuroscience analog as cleanly as the other three. It is the concept of provenance.
Most second brain systems — and most RAG systems, and most retrieval-augmented AI setups — treat all knowledge chunks as equally weighted. A hand-written personal insight and a scraped web article are the same to the retrieval layer. A single-source claim and a multi-source verified fact carry the same weight. This is an enormous problem that almost nobody talks about.
Provenance is the dimension that fixes it. Every chunk of knowledge in your hippocampus should carry not just what it means (the embedding) and where it sits semantically, but where it came from, how many sources converged on it, who wrote it, when it was verified, and how confident the system is in it. With provenance, a hand-written insight from an expert outweighs a scraped article from a low-quality source. With provenance, a multi-source claim outweighs a single-source one. With provenance, a fresh verified fact outweighs a stale unverified one.
Without provenance, your second brain will eventually feed your AI teammate garbage from the hippocampus and your AI will confidently regurgitate it in responses. With provenance, your AI teammate knows what it can trust and what it cannot.
Provenance is the architectural choice that separates a second brain that makes you smarter from one that quietly makes you stupider over time. Add it to your hippocampus schema. Weight every chunk. Let the retrieval layer respect the weights.
The health layer: how you know the brain is working
A brain that is working produces signals you can read. A brain that is broken produces silence, or worse, false confidence.
I build in explicit health signals for each of the three components. The cortex is healthy when it is fresh, when pages are recently updated, when active projects have recent activity, and when stale pages are archived rather than accumulating. The hippocampus is healthy when the consolidation loop is running on schedule, when the corpus is growing without duplication, and when retrieval returns relevant results. The consolidation loop is healthy when its scheduled runs succeed, when its outputs are being produced, and when the error rate is low.
I also track staleness — pages that have not been updated in too long, relative to how load-bearing they are. A canonical document more than thirty days stale is treated as a risk signal, because the reality it documents has almost certainly drifted from what the page describes. Staleness is not the same as unused; some pages are quietly load-bearing and need regular refreshes. A staleness heatmap across the workspace tells you which pages are most at risk of drifting out of reality.
The health layer is the thing that lets you trust the system without having to re-check it constantly. A brain you cannot see the health of is a brain you will eventually stop trusting. A brain whose health is visible is one you can keep leaning on.
What this costs to build
I want to be honest about what actually getting this working takes. Not because it is prohibitive, but because the classical second-brain literature underestimates it and operators get blindsided.
The cortex is the easy part. Any capable workspace tool, a few weeks of deliberate organization, and a commitment to keeping it small and operational. Cost: low. Most operators have some version of this already.
The hippocampus is harder. You need durable storage. You need an embeddings layer. You need schemas that capture provenance and not just content. For a solo operator without technical capability, this is a real build project — probably a few weeks to months of focused work or a partnership with someone technical. It is also the part that, once built, becomes genuinely durable infrastructure.
The consolidation loop is hardest. Because the loop is a set of services that extract, process, structure, and route, it is the most engineering-intensive part. This is where most operators stall. The solve is either to use tools that ship consolidation-like capabilities natively (Notion’s AI features are approximately this), or to build a small set of extractors and pipelines yourself with Claude Code or equivalent. For me, the loop took months of iteration to run reliably. It is now the highest-leverage part of the whole system.
Total cost for an operator with moderate technical capability: a few months of evenings and weekends, some cloud infrastructure spend, and an ongoing maintenance commitment of maybe eight to ten percent of working hours. In exchange, you get an operating system that compounds with use rather than decaying.
For operators who do not want to build the hippocampus and loop themselves, the vendor-shaped version of this architecture is starting to become available in 2026 — Notion’s Custom Agents edge toward a consolidation loop, Notion’s AI offers hippocampus-like capability at small scale, and various startups are working on the layers. None are complete yet. Most operators serious about this will need to build some of it.
What goes wrong (the honest failure modes)
Three failure modes are worth naming, because I have hit all three and the pattern recovered only because I caught them.
The cortex that tries to be the hippocampus. Operators who get serious about a second brain often try to put everything in the cortex — every article they have ever read, every transcript of every meeting, every bit of research. The cortex then gets too big to be legible, starts running slowly, and the search stops returning useful results. The fix is to build the hippocampus separately and move the bulk of the corpus there. The cortex should be small.
The hippocampus that gets polluted. Without provenance weighting and without deduplication, the hippocampus accumulates low-quality content that then gets retrieved and surfaced in AI responses. The fix is provenance, deduplication, and periodic hippocampal pruning. The archive is not sacred; some things earn their place and some things do not.
The consolidation loop that nobody maintains. The loop is background infrastructure. Background infrastructure rots if nobody owns it. A consolidation loop that was working six months ago might be quietly broken today, and you only notice because your cortex is drifting out of sync with your operational reality. The fix is health signals, monitoring, and a weekly ritual of checking that the loop is running.
None of these are dealbreakers. All of them are things the pattern has to work around.
The one sentence I want you to walk away with
If you take nothing else from this piece:
A second brain is not a library. It is a brain. Build it with the three parts — cortex, hippocampus, consolidation loop — and it will behave like one.
Most operators have built the cortex and called it a second brain. They have a library with the sign out front updated. The system feels broken because it is not a brain yet. Build the other two parts and the system stops feeling broken.
If you can only add one part this month, add the consolidation loop, because the loop is the thing that makes everything else work together. A cortex without a loop is still a library. A cortex with a loop but no hippocampus is a library whose books walk into the back room and disappear. A cortex with a loop and a hippocampus is a brain.
FAQ
Is this just a metaphor, or does the neuroscience actually apply?
It is a metaphor at the level of mechanism — the way neurons consolidate memories is not identical to the way a scheduled pipeline does. But the functional role of each component maps cleanly enough that the analogy is load-bearing rather than decorative. Where the architecture borrows from neuroscience, it inherits genuine design principles that compound the system’s coherence.
Do I need all three parts to benefit?
No. A well-built cortex alone is better than no system. A cortex plus a consolidation loop is significantly more powerful. Add the hippocampus when you have enough volume to justify it — usually once your cortex starts straining under its own weight, somewhere in the low thousands of pages.
Which tool should I use for the cortex?
The tool is less important than how you organize it. Notion is what I use and what I recommend for most operators because its database-and-template orientation maps cleanly to object-oriented operational state. Obsidian and Roam are better for pure knowledge work but weaker for operational state. Coda is similar to Notion. Pick the one whose grain matches how your brain already organizes work.
Which tool should I use for the hippocampus?
Any durable storage that supports embeddings. Cloud object storage plus a vector database. A cloud data warehouse like BigQuery or Snowflake if you want structured queries alongside semantic search. Managed services like Pinecone or Weaviate for pure vector workloads. The decision depends on what else you are running in your cloud environment and how technical you are.
How do I actually build the consolidation loop?
For operators with technical capability, a combination of Claude Code, scheduled cloud functions, and a few targeted extractors will get you there. For operators without technical capability, Notion’s built-in AI features approximate parts of the loop. For true coverage, you will eventually either need technical help or to wait for the vendor-shaped version to mature.
Does this mean I need to rebuild my whole system?
Not necessarily. If your existing workspace is serving as a cortex, keep it. Add a hippocampus as a separate layer underneath it. Build the consolidation loop between them. The cortex does not have to be rebuilt for the pattern to work; it has to be complemented.
What if I just want a simpler version?
A simpler version is fine. A cortex plus a lightweight consolidation loop that runs once a week is already far better than what most operators have. Do not let the fully-built pattern be the enemy of the partially-built version that still earns its place.
Closing note
The thing I want to convey in this piece more than anything else is that the architecture revealed itself to me over time. I did not sit down and design it. I built pieces, noticed they were not enough, built more pieces, noticed something was still missing, and eventually the neuroscience analogy clicked and the three-part structure became obvious.
If you are building a second brain and it does not feel right, you are probably missing one or two of the three parts. Find them. Name them. Build them. The system starts feeling like a brain when it actually has the parts of a brain, and not before.
This is the longest-running architectural idea in my workspace. I have been iterating on it for over a year. The version in this article is the one I would give a serious operator who was willing to do the work. It is not a quick start. It is an operating system.
Run it if the shape fits you. Adapt it if some of the parts translate better to a different context. Reject it if you honestly think your current pattern works better. But if you are in the large middle ground where your system kind of works and kind of does not, the missing part is usually the hippocampus, the consolidation loop, or both.
Go find them. Name them. Build them. Let your second brain actually be a brain.
The Exit Protocol — the hygiene discipline that keeps the hippocampus from becoming a liability
On the external validation: the cross-model convergent analysis referenced in this article was conducted using multiple frontier models evaluating workspace structure independently. The finding that the workspace behaves as an execution layer rather than an archive was independently surfaced by all evaluated models, which I took as meaningful corroboration of the internal architectural thesis.
The neuroscience analogy is drawn from standard memory-consolidation literature, particularly work on hippocampal consolidation during sleep and the role of the cortex in conscious working memory. This article does not attempt to make rigorous claims about neuroscience; it borrows the functional analogy where the analogy is useful and drops it where it is not.