Seven identical emails. Three minutes. One morning brief.
Nothing was broken. The send succeeded on the first try, but the reply confirming it got lost. My agent, doing exactly what agents do, retried. And retried. From the inside, each attempt looked brand new: no error, no evidence the earlier one had landed. So it kept going until someone noticed.
This is the failure class nobody warns you about when you hand an agent a mailbox. The industry calls it duplicate completion: the original succeeds, the response is lost, the retry re-sends. It’s not a model problem and it’s not a prompt problem. Telling an agent “don’t send twice” in its instructions is not enforceable. Agents re-plan, they retry, they lose context across restarts. Every scheduled job, every cron, every “oops, run it again” is another roll of the dice.
And Gmail gives you no help. Stripe, Resend, and the other transactional APIs all have idempotency keys: send the same key twice, get one charge, one email. Gmail’s API has no such thing. The guarantee has to live on your side, in code, at the tool boundary — somewhere the agent cannot reason its way around.
What I built
send-once is one Python file, no dependencies beyond the standard library. Every scheduled or agent-driven send routes through it, and it enforces at most once with three gates:
An operation ledger. A local sqlite database keyed by a deterministic operation id, like loop-morning-brief-2026-09-17. If this operation already recorded a send, the wrapper refuses. Same intent, same key, and a retry becomes a no-op instead of a duplicate.
A Sent-folder check before every send. It searches Sent for the same recipient and subject in the last 24 hours. If a match exists, it refuses. Sent is the source of truth, so this gate holds even if the ledger is lost, the run moved machines, or the send happened outside this tool entirely.
No blind retries, ever. If the send result is ambiguous — timeout, empty output, lost response — the wrapper does not retry. It re-checks Sent. If the send landed, it records that and reports honestly. If it can’t be confirmed, it stops and hands it to a human. An inconclusive pre-check is also a refusal: when the tool can’t verify what already happened, the safe move is to stop, not to guess.
The exit codes are the interface: 0 means sent (or already sent), 2 means refused as a duplicate, 3 means a human needs to verify. Prose instructions get skipped or misread by workers. The wrapper doesn’t.
Here’s the shape of it — the ledger is the whole trick:
import sqlite3, sys, hashlib

DB = "send_once.db"

def op_id(kind, recipient, subject, date):
    raw = f"{kind}|{recipient}|{subject}|{date}"
    return hashlib.sha256(raw.encode()).hexdigest()[:16]

def already_sent(op):
    con = sqlite3.connect(DB)
    row = con.execute(
        "SELECT 1 FROM ledger WHERE op_id = ?", (op,)
    ).fetchone()
    con.close()
    return bool(row)

def record(op, message_id):
    con = sqlite3.connect(DB)
    con.execute(
        "CREATE TABLE IF NOT EXISTS ledger(op_id TEXT PRIMARY KEY, message_id TEXT, ts DATETIME DEFAULT CURRENT_TIMESTAMP)"
    )
    con.execute(
        "INSERT OR IGNORE INTO ledger(op_id, message_id) VALUES (?, ?)",
        (op, message_id),
    )
    con.commit()
    con.close()

# Gate 1: the ledger. Same operation id -> refuse, don't resend.
op = op_id("morning-brief", "will@example.com", "Morning brief", "2026-10-04")
if already_sent(op):
    print("refusing: already sent")
    sys.exit(2)  # 2 = duplicate refused

# Gate 2: check the Sent folder via the Gmail API before sending.
# Gate 3: only record truthfully after the send resolves.
# If the result is ambiguous, re-check Sent — never blind-retry.
record(op, message_id)  # message_id from the confirmed send
Take it, make it better
This solved my problem, not everyone’s. It’s MIT licensed, it’s one file, and the mailer backend is a documented protocol so any Gmail CLI can slot in.
Take it, make it better. If you build something better, come back. We’ll be customer number one, and we’ll pay you for it.
They keep publishing the obituary before the body's cold.
Gartner's take, from May: by 2027, 40% of enterprises will demote or decommission their autonomous AI agents because of governance gaps they only discover after a production incident. (Gartner press release, May 26, 2026; the analyst is Shiva Varma.) Not because the models failed. Because nobody was watching the permissions.
Then this month: BCG's Steven Mills — partner, managing director, and the firm's chief AI ethics officer — warned that companies are accelerating agentic AI deployment with "no idea how to manage risk." His line: "Get governance wrong, and every bit of value you've built with experimentation and early wins could unravel because of a single incident." (Fast Company, Sept 2026.)
Mills's prescription is interesting. He says there's no fixed design for good corporate AI risk management, but the starting point is separating use cases that are inherently low-risk — those can be approved automatically — from the ones that carry real risk and need deep human review. Plus a real budget for governance and a senior executive accountable for AI safety.
Read that again. It's an org chart's answer to a practical problem: committees, stage gates, a budget line, an executive with a title.
Here's the thing. I run a version of this every night, and it's none of those things. No committee. No governance budget. One man and a phone.
I run six AI seats on my business — a personal agent, an ops chief of staff, a publishing-desk agent, and three build seats. They read my email, draft my outreach, design automations, run research while I sleep. The governance model fits on a sticky note:
Two-way doors swing. One-way doors don't.
A two-way door is anything reversible — analysis, research, drafting, staging. My agents walk through those on judgment, and I mean it: momentum wins, I don't want a report, I want the work done.
A one-way door is anything you can't take back — money moves, sends, publishes, deletions, credentials. Every one of those stops at the gate. And the gate isn't a process. It's my tap. Structural, not procedural. A draft can sit ready for three weeks; it doesn't send until I say so.
That's it. That's the whole model that Gartner's 40% are supposedly spending governance budgets to build. Varma even names the failure mode: companies treat governance as binary — locked down or fully trusted. The doors model isn't binary. It's proportional. Reversible work flows, irreversible work waits. Small decisions move at tap speed instead of committee speed.
There's a second piece, and it matters: autonomy is earned through clean observation, never granted up front. Nothing in my shop graduates to auto-pilot on day one. New automations start in shadow — run the behavior, take no action — and only earn real permissions after clean observation. Seven clean shadow days before something auto-archives. Three clean days before a migration cutover. The machine proves it's safe by being watched being safe.
And before anything goes out — anything — it runs a sensitive-token scrub, like a virus list: exact matches block, fuzzy matches queue for a human. Official facts only. Never invented rankings, features, or quotes.
That's the enterprise governance problem, solved by one operator with six agents, and it's cheaper and faster than every framework Mills is recommending because there's no committee in the middle. The human review he prescribes for high-risk uses? Mine takes one tap. Low-risk automatic approval? Mine doesn't even need approval — it's a two-way door.
Proof's not in the framework. It's in this morning. Two vendor outreach waves went out — Eastern at 7:54, Pacific at 9:07 — drafted by the seats, sent on my tap, nothing auto-fired. A storm-triggered vendor automation is being designed this afternoon with the gate baked into the spec: it can search impact areas and draft outreach, it cannot send. Overnight research runs while I sleep and lands in a brief I read over coffee. Six seats working, zero production incidents, zero surprises in my inbox.
I'm not saying enterprises should run their AI program from a phone. They can't — scale demands the org chart. I'm saying the org chart versions keep failing on the exact axis the doors model gets right: they try to govern everything the same way, so everything either crawls or crashes. Separate the reversible from the irreversible, put a real human's tap on the irreversible, make everything else prove itself in shadow before it earns anything, and scrub before you publish.
The big shops are about to learn this at scale. The 40% who don't will be the decommissioned ones. The ones who do will discover what I already know: governance that moves at tap speed isn't less governance. It's the only kind fast enough to keep up with the machines.
Most AI products ship finished. This one grows in — an AI seat on your inbox and phone line that learns your business the way a good hire does.
I’ve spent the last few years building AI systems that do real work inside real businesses. Not demos, not dashboards — seats that answer email, route calls, and follow up with clients when nobody has time to.
Somewhere along the way the shape of the product changed. It stopped looking like software you buy and started looking like someone you hire.
I call it the embedded operator. Here’s the whole idea, four ways.
Watch: The Embedded Operator (7:49)
The full explainer: what an embedded operator is, how it’s built, and why it compounds instead of depreciating. Video overview generated with NotebookLM; narration is AI-generated.
The short version: an embedded operator isn’t a chatbot on your website. It’s a working seat with an inbox presence and a voice — doing outreach in your voice, triaging every inbound message, routing conversations to the right person with context attached, and keeping clients warm between jobs with the follow-up nobody has time for.
Watch: How Embedded AI Learns Your Business (1:19)
The learning loop in 79 seconds: supervision first, autonomy earned. Video overview generated with NotebookLM; narration is AI-generated.
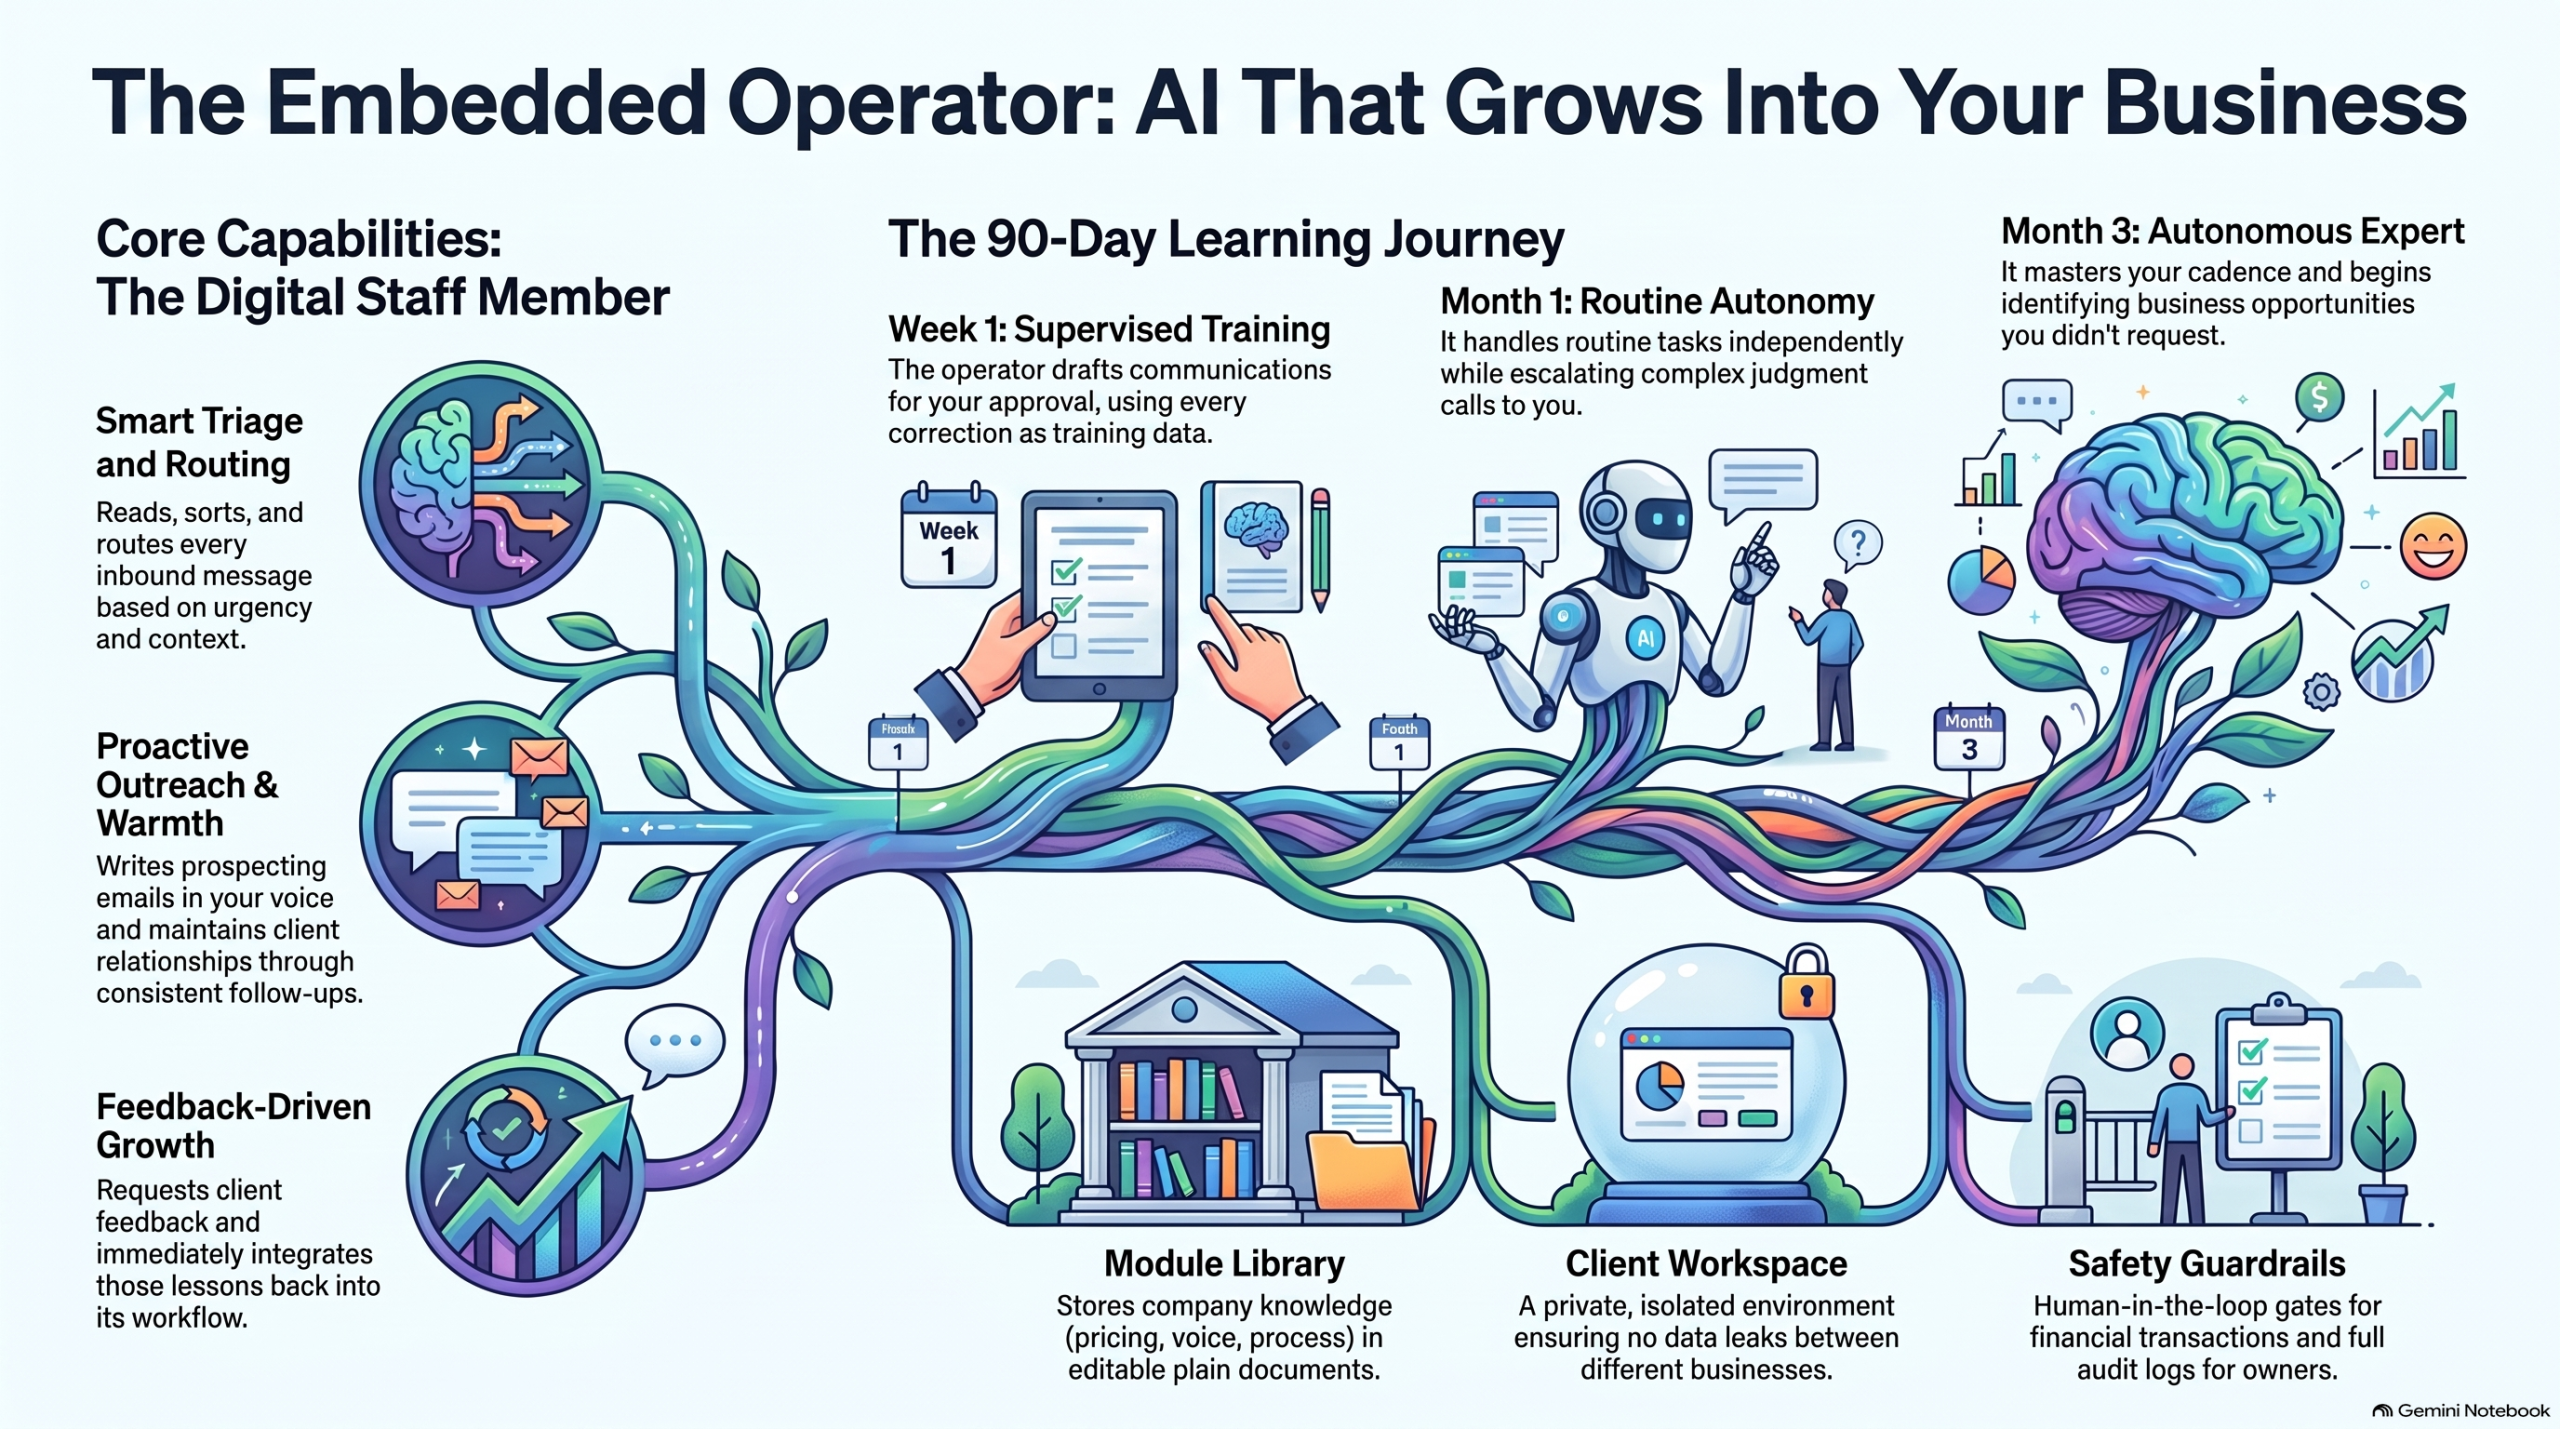
It improves the way a person improves. Week one, it drafts and you approve — every correction is training data. Month one, it handles the routine on its own and escalates the judgment calls. Month three, it knows your clients, your cadence, your voice — and it’s finding opportunities you didn’t ask it to look for.
Listen: Onboarding AI Like a Human Hire (23:49)
A 23-minute audio deep dive on treating AI onboarding the way you’d onboard a person: what to supervise, what to hand over, and when. Audio overview generated with NotebookLM; narration is AI-generated.
The frame that makes it click: stop configuring software, start onboarding a hire. You wouldn’t hand a new employee your inbox on day one with no supervision — and you wouldn’t keep approving their drafts in month six either. Same curve.
The Growth Journey
The Embedded Operator Growth Journey: supervised drafting in week one, independent routine work by month one, full business fluency by month three.
Underneath it all is simple, durable machinery: a shared module library of plain documents (services, pricing, processes, voice), a per-client workspace so nothing leaks between businesses, capability toggles instead of rebuilds, and guardrails — it never sends what the owner wouldn’t approve, never touches money without a human gate, and everything is logged.
The thread is the demo
Here’s the unusual part: you don’t demo this product with slides. You demo it by using it. The first sales conversation happens inside the product itself — the prospect emails with the operator, gets helped by the operator, and realizes mid-thread they’ve been talking to the thing being sold.
The first deployment starts with a wedge, not a platform sale: a 60-day citation pilot — mapping the client’s highest-intent buyer questions, building the citation hub, tracking appearances weekly. Concrete, bounded, provable. And underneath it, the seat. Sixty days in, the upsell needs no pitch: remember those emails? That was the seat. Want it on your inbox?
It doesn’t come with the software. It comes with the soul — and it self-iterates.
Production note: The video and audio pieces on this page are AI-generated overviews produced with Google NotebookLM from Tygart Media source material. Narration is synthetic.
TL;DR: My personal AI runs on Muse. It can’t write code into my repos by itself — so I built it a bridge to Cursor’s cloud agents. One repo, two transports, nine tools. Now when I say “add CI to that repo,” it dispatches an agent, checks the PR, and merges. Here’s how the Muse-to-Cursor loop actually works.
The direction nobody talks about
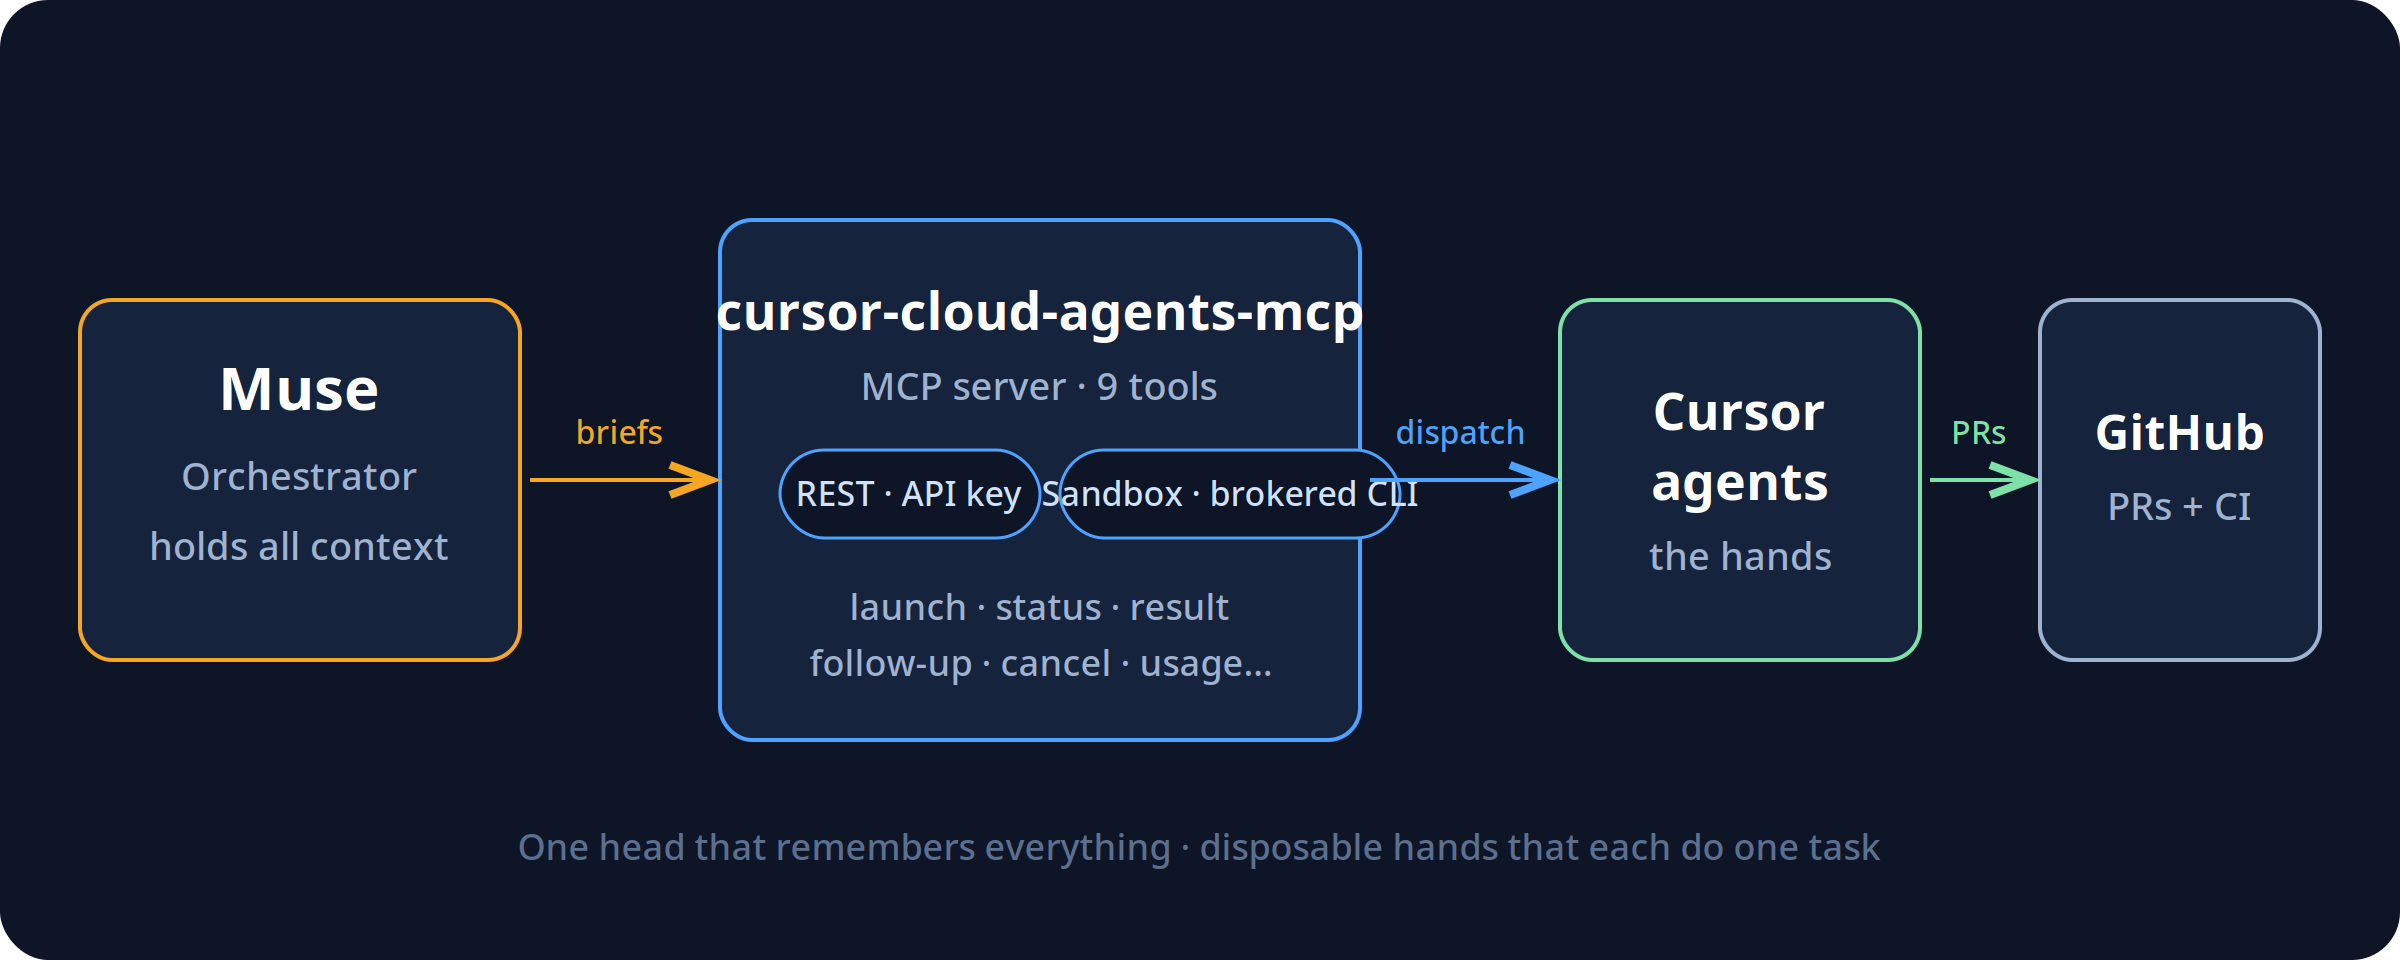
Everyone’s building the same arrow: human → AI writes code faster. I built the other arrow: AI → AI. My assistant (Muse) holds all my context — my repos, my work orders, my rules. Cursor’s cloud agents hold the hands — they can open PRs, run CI, touch repos. The bridge between them is an MCP server I open-sourced: cursor-cloud-agents-mcp.
The interesting part isn’t the tools. It’s the shape: one orchestrator that holds all the context, and disposable agents that each know one task. The orchestrator doesn’t write the code — it briefs, checks, and merges. The agents don’t set direction — they execute the brief. That separation is the whole trick.
Two transports, one repo
I almost built two projects. Then I realized the only real difference between audiences is where the credential lives. So it’s one repo, two transports:
REST — your Cursor API key, direct to api.cursor.com. For general users.
Sandbox — for assistants running inside sandboxed environments (like Muse/Meta’s), where there is no API key to hand out. It shells out to a brokered cursor-agent CLI on PATH instead.
Same nine tools either way: launch, status, result, follow-up, cancel, list, models, whoami, usage.
The lessons are in the timeouts
The v1 API splits agents and runs, and launches can take minutes — sometimes timing out after succeeding. So the bridge mints the agent ID client-side before the call: a retry after a timeout can never create a duplicate. A timeout is reported as unknown, never as failure, then reconciled. Run status is the source of truth, because agent “ACTIVE” doesn’t mean “still working.” These are the details that separate a demo from something you can actually operate.
It earned its keep on day one
The first thing I pointed it at was its own repo: add CI to cursor-cloud-agents-mcp. The agent opened a PR with a GitHub Actions workflow. The first CI run failed — and caught a real bug: the package’s floating dependency had resolved to MCP 2.x, which renamed FastMCP out from under the import. The repo was shipping broken against current dependencies and nobody knew. Pin, re-run, green, merge. I didn’t touch a terminal.
I didn’t trust my own first draft
Before any of that, four AI models reviewed the spec against Cursor’s live docs — and independently caught the same flaw: my original design was shaped around the retired v0 API. Then two more reviewed the actual code and found real bugs: a broken idempotency path, a transport auto-detect that would have grabbed the wrong binary, a polling loop that blocked the server. All fixed before it shipped. The irony I like: the final review round ran through the bridge itself. The launcher timed out on all four agents — and the bridge’s own timeout-reconciliation showed they were all actually running.
Where this goes
v1.1 brings MCP 2.x support. Around it, I’m building the rest of the pattern: work orders as GitHub issues, a daily SLA check, a weekly digest — the scaffolding that turns “AI that can open PRs” into something closer to staff. Most people use agents as a faster keyboard. I’m interested in what happens when they’re the hands and something with memory is the head.
MIT licensed. Issues and PRs welcome — help make it better.
The best product in claims is not another adjuster dashboard. It is the thing that shows the short-pay before the shop or the homeowner closes the file.
That is not a slogan. It is how Texas SB 458, new Washington claims-handling rules, and the sudden cheapness of vertical agents rhyme. Three different surfaces. One failure mode. Nobody owns the photo set or the estimate map, so nobody demands the appraisal or the supplement in time.
What actually changed in 2026
Texas Senate Bill 458 added Chapter 1813 to the Insurance Code. For personal automobile and residential property policies delivered, issued, or renewed on or after January 1, 2026, the policy must contain a binding appraisal provision for disputes solely over the amount of loss. Either the policyholder or the insurer can demand it unilaterally. The amount determined by appraisal is binding except for fraud, accident, or material mistake. That is not a proposal. It is live statute for 2026 renewals.
The Texas Department of Insurance has been working the implementing rules. Proposed 28 TAC §§5.9800–5.9806 set hard timelines: demand windows, appraiser naming periods, and outer deadlines for the award. Practitioner write-ups already treat the unilateral right as real for policies that renewed into the new year. Shops cannot file the demand themselves, but they can build the file, coach the customer, and stop leaving money on the table when the carrier will not move.
Washington followed with clearer minimum claims-handling duties under WAC 284-30-390, effective October 18, 2026. Carriers cannot condition coverage on photo-only evaluation. Shops and policyholders gain process language they can cite when supplements stall or explanations stay thin. Illinois added its own amount-of-loss appraisal path in the same window. The pattern across states is consistent: regulators are tightening the rails around automated or virtual first looks while giving policyholders and shops clearer levers on the dollar amount.
Florida lawmakers have already floated mandatory human review for claim denials. Oregon has guidance on virtual claim adjustment systems and when mobile apps can be required. The direction of travel is the same. Virtual is allowed. Pure automation of the denial or the lowball without a human gate is getting harder.
At the same time OpenAI shipped the Agents API. Long-running sessions, tool use, recovery, and context management moved from something you build to something you rent. Greg Isenberg called it the AWS moment for agents. The hard engineering is now a line item. What remains scarce is ownership of one painful vertical workflow and the data that makes the next run better.
The failure mode is the same as leakage
In the leakage essay the problem was money that already left and no one owned the file. Here the money has not left yet. The carrier estimate or the initial offer is short. The shop or the homeowner has the photos and the line items, but the map of what is missing lives in no system they control. So the file closes at the low number, or the supplement fight starts late and under-documented.
Collision shops already live this. Hail and storm work in restoration companies live this. The adjuster arrives with a photo-first or virtual process. The initial scope misses labor hours, OEM procedures, or secondary damage that only shows under proper light. The shop knows the number is low. The customer is tired. The clock on the new appraisal window is running. Without a clean first pass that flags the gap, the leverage created by SB 458 stays theoretical.
The same pattern appears in residential storm claims. Sparse photo sets become lowball scopes. Dense, angled, scaled sets get paid. The difference is not magic. It is ownership of the evidence map before the carrier’s first number hardens.
The wedge is a free checker, not a platform
Do not start with a claims management system. Start with the moment the customer already hates.
Upload the carrier estimate PDF. Or upload the set of damage photos taken the same day. Thirty seconds later: missing line items, density patterns that usually support higher repair hours, scale problems that virtual adjusters systematically under-count, and a short list of the specific points that justify an appraisal demand or a supplement under the new state rules.
That is the first action a stranger will take this week. No login required for the free pass. No new system of record. Just the photo or the PDF they already have on their phone.
The product then keeps the map. Which carriers short-pay which procedures in which ZIP codes. Which photo sets correlate with successful appraisal outcomes. Which missing lines reappear after the human gate. That dataset is the moat. Not another dashboard.
Models draft. People own the send.
Appraisal demands, supplements, and formal disputes are irreversible steps. The model can draft the demand letter, the photo index, and the line-item comparison. A named human still owns the send. That is the same gate we already run on money movement and filings. The bot finishes the research. The person signs.
This is not “AI for claims adjusters.” It is a vertical combination of two primitives that already show up in the idea mills: regulated document and photo review (the home-health paperwork pattern Greg has pushed) plus physical-world claim recovery for the trades. The agent does the first pass against a living checklist of short-pay patterns. The human decides whether to pull the appraisal lever that the 2026 statutes now make real.
The same logic applies to the spend-control side of agents. Once agents hold virtual cards and budgets, someone has to own the receipt and the exception. Here the “receipt” is the estimate and the photo set. The exception is the short-pay. The human gate stays in place for the irreversible action.
Why the compounding path is the dataset
Volume turns the free checker into a labeled corpus. Every upload that later produces a higher settlement or a closed appraisal award becomes training signal. Carriers change their virtual adjustment models; the checker sees the new under-count patterns first. Shops in Texas and Washington start citing the same process language; the product already knows which photo sets and which line-item gaps win under the new rules.
That is the opposite of a third SaaS dashboard. The dashboard is the easy part. The hard part is the map of what actually moves money under the 2026 statutes, kept current by the same people who have the photos and the closed files.
Once the map exists, the next products write themselves: automatic coaching for the appraisal demand, carrier-specific supplement templates that cite the exact WAC or Chapter 1813 language, and a quiet feed of which virtual adjustment systems are currently under-counting which damage types. None of that works without the first free checker that strangers will use this week.
What to build this week
Pick one surface. Collision or residential storm. Offer the free photo or estimate upload. Return a short, numbered list of flags with the specific statutory or regulatory hook that makes the flag matter. Keep every outcome. After a few hundred files the checklist stops being generic and starts being local.
Do not sell the platform first. Sell the moment the short-pay is still reversible. The rest follows from the map.
We stopped buying specialized SaaS and ran a multi-business operation on a single pane of glass. Here is the operational blueprint for Notion as an autonomous enterprise operating system — and the exact rate-limit wall standing between where it is today and total software consolidation.
TL;DR
The tech world keeps waiting for an “Everything App” — a consumer super-app for messaging, ordering food, and hailing rides. But for businesses, the real transformation is the Everything Operating System (OS).
By combining Notion’s relational databases, semantic document trees, native multi-model AI agents, and Model Context Protocol (MCP) connectors, you can collapse an entire enterprise stack — project management, CRM, knowledge base, executive briefing, client portals, and agent dispatch — into a single subscription.
It already works in production. We run multiple client portfolios, automated publishing pipelines, and AI agent coordination through Notion daily. Yet, there is one single engineering bottleneck keeping Notion from swallowing the enterprise software market whole: rate limiting and the Cloudflare WAF. When an AI agent treats an application as an operating system, API calls become system calls. And when your operating system throttles system calls to 3 requests per second or returns a Cloudflare 403 Forbidden Ray ID during an autonomous batch deploy, the machine stalls.
1. The SaaS Graveyard
Look at the software ledger of any 10-person agency, professional services firm, or modern operator:
Project Management: Asana, Monday, or Linear ($12–$24/user/mo)
CRM & Pipeline: HubSpot, Pipedrive, or Salesforce ($50–$150/user/mo)
Internal Knowledge & SOPs: Confluence, Slite, or Guru ($8–$15/user/mo)
File Storage & Collaboration: Google Drive or Dropbox ($15–$25/user/mo)
AI Tooling Zoo: ChatGPT Plus for research ($20/mo), Claude Pro for coding ($20/mo), Perplexity Pro for search ($20/mo), Gemini Advanced for documents ($20/mo)
Every team member has fifteen tabs open. Data decays in silos. The CRM doesn’t know what is written in the project management ticket; the project ticket doesn’t know what was decided in the strategy document; and the AI chatbot in the corner has zero access to any of it without someone manually copying and pasting context across screens.
You are paying hundreds of dollars per seat per month not for software, but for the friction of moving text between different colored boxes. What happens if you cancel all of it and keep only one?
2. Notion as an Operating System (Not an App)
An operating system requires three fundamental primitives:
A Memory & File System: Persistent state, structured metadata, and unstructured data.
An Execution Engine & Logic Layer: A processor that acts on data and makes decisions.
An I/O Bus: Connectors that read from and write to the outside world.
Notion has quietly built all three:
OS Layer
Notion Primitive
Enterprise Function
1. Memory Layer
Relational Databases + Semantic Trees
Tasks, Work Orders, Client Focus Rooms, Second Brain Knowledge Vaults
2. Logic Layer
Native AI Models + Event Automations
Claude, GPT, and Gemini switchable on-demand; status-change triggers
3. I/O Bus
Model Context Protocol (MCP) + Webhooks
Two-way bridges to Gmail, Google Calendar, local desktops, and server APIs
When you structure Notion this way, it stops behaving like a passive digital notebook. It becomes the kernel of your business:
Databases are your schemas: You define relational tables (Tasks, Work Orders, Client Master, Second Brain). Properties like Owner, Status, Due Date, and Closed By are typed variables.
Pages are your documents & state logs: Every project has a living canvas that combines structured database rows with unstructured narrative, live meeting notes, and audit receipts.
Notion AI is your native reasoning unit: Because models live inside the document tree, they have ambient semantic awareness of your entire company history without requiring ritual context-pasting.
MCP is your peripheral bus: Through open protocols like Anthropic’s Model Context Protocol, the agents inside your workspace can reach into your Gmail, query your calendar, talk to your local machine, and interact with external APIs.
3. How We Actually Run It: The Two-Hemisphere Doctrine
This is not a theoretical thought experiment. This is how we run our operations every single day.
Hemisphere A: The Executive Layer (Human Intent & Voice)
Where the human lives: mobile phone, voice memo, or a clean Notion dashboard. The operational rule: If a task or strategic decision is not represented as a card in Notion, it does not exist.
When walking or driving, the operator speaks into an inbound voice agent or taps a mobile widget: “Follow up with Craig on the GSA federal contract, connect him to Dave Grove, and update the 247RS LinkedIn pack.” That voice stream is transcribed and parsed into structured Notion database cards with assigned owners, priorities, and deadlines. Zero cognitive overhead.
Hemisphere B: The Production Layer (Agent Workers & Tool Hands)
Where the machines live: background agents (Cursor Desktop, Chief of Staff on Grok Bot, Claude Code).
Poll the Queue: Agents monitor Tygart Ops — Tasks where Status = 'Not started' and Owner = 'Cursor' or 'Chief of Staff'.
Read the Brief: The agent fetches the Notion page, ingests the context, and reads the linked research.
Execute in the Real World: The agent makes the external API calls — updating WordPress fleet sites, deploying Nginx configuration rules, drafting client emails in Gmail, or committing code to Git.
Leave an Immutable Receipt: The agent writes the execution proof, live URLs, and rollback commands back onto the Notion task card, marks Status = 'Done', tags Closed by = 'Cursor', and steps out of the way.
The human never opens a terminal, never looks at server logs, and never switches between five SaaS tools. They look at Notion. The work moves from left to right. The receipts are permanent.
4. The Four Hard Walls: Why You Can’t Throw Away Git (Yet)
If Notion is this capable, why can’t you delete your local hard drive, cancel GitHub, and run literally 100% of your company inside Notion today? Because when you push Notion from being an “app” to an “operating system,” you slam directly into four fundamental infrastructure limits:
Wall 1: The Cloudflare & Rate-Limit Ceiling
In a traditional operating system, a system call takes microseconds. The CPU can write millions of instructions to memory per second. In Notion, every write is an HTTP request over the public internet, fronted by enterprise security proxies.
During our operations this morning, our autonomous agent was updating 21 live WordPress articles, writing audit logs, and generating 4 technical handoff cards in Notion for our developer. On the fourth task, the operation hit a wall:
Request to Notion API failed with status: 403
Cloudflare Ray ID: a388bb63fa5108d8
"Sorry, you have been blocked... This website is using a security service to protect itself from online attacks."
Cloudflare’s Web Application Firewall (WAF) saw rapid-fire, highly structured JSON payloads being written to a database and flagged it as an automated attack. Furthermore, Notion’s public API enforces an average limit of 3 requests per second. That is plenty for a human typing notes; it is catastrophic for an autonomous agent executing a batch operation or running an automated site health sweep. Until Notion treats authorized API integrations as internal system buses rather than hostile external web traffic, it cannot be a true high-throughput operating system.
Wall 2: A Document Is Not a CPU
Notion is a world-class data store and presentation canvas, but it has no compute runtime. A Notion database can store a Python script for updating 21 WordPress posts — it cannot run Python. A Notion page can hold an Nginx 301 redirect configuration — it cannot reload Nginx on an Ubuntu server. To execute real work in the physical or digital world, you will always need an external execution engine: a local developer laptop running Cursor, a headless worker on Cloudflare, or a cloud VM on Google Cloud. Notion is the brain; it still needs hands.
Wall 3: Mutable State vs. Cryptographic Truth
Notion pages are mutable documents. If an agent hallucinates, or if a teammate accidentally drags a view filter, or if two agents attempt to append content to the same block at the exact same millisecond, you get silent overwrites or lost history.
Git, by contrast, is a cryptographic, distributed state machine. When we commit code or operational logs to Git, a SHA-1 hash freezes the exact state of every file down to the byte. Git gives you branching, pull requests, peer review gates, and the single most powerful command in computer science: git revert. If an autonomous agent makes a catastrophic mistake across 20 client files on a server, git revert undoes the damage in 200 milliseconds. Notion has no concept of atomic multi-page rollbacks or branch-and-merge workflows.
Wall 4: The Air-Gap & Data Sovereignty Test
If Notion experiences an outage, or if you board a cross-country flight with dead Wi-Fi, a “Notion-Only” company ceases to exist. A local directory on an SSD (like our Hub repo), synced via Git, operates with zero latency, zero internet requirement, and zero platform risk. You own the markdown files on your drive. Nobody can de-platform your folder.
5. The Verdict: The Cockpit & The Safe
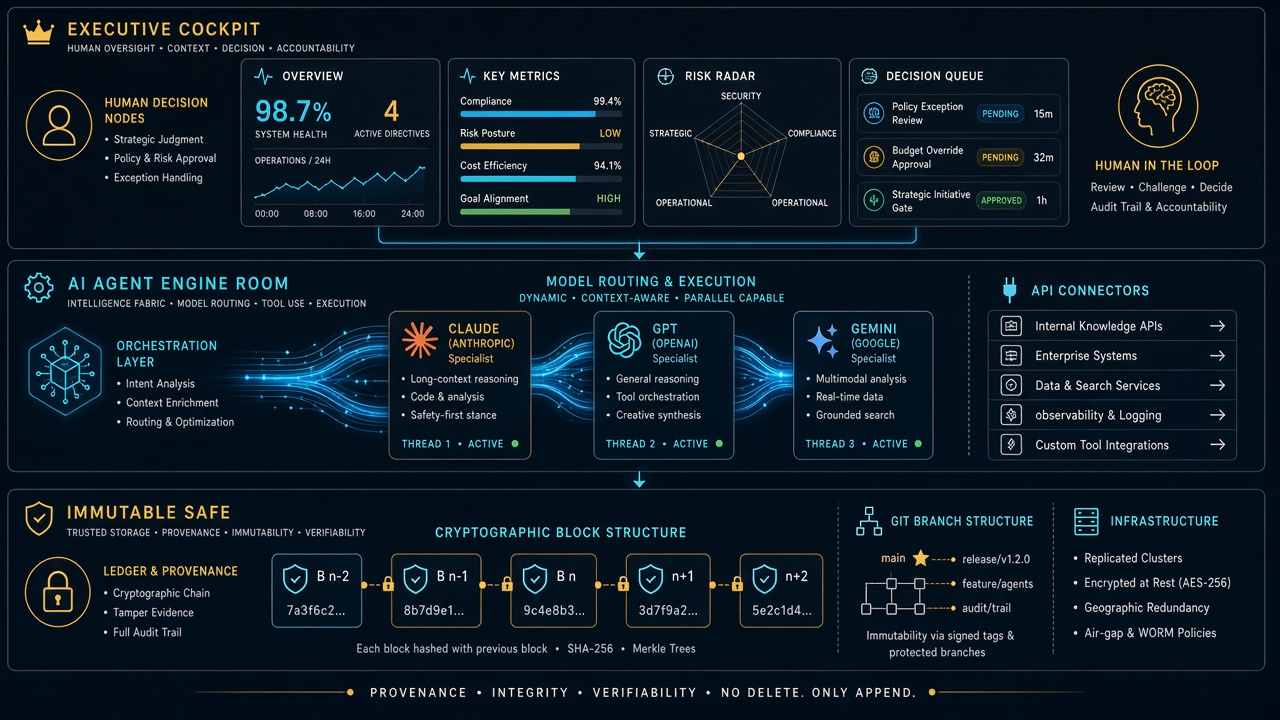
You don’t have to wait for Notion to solve all of that to reap the benefits today. The winning architecture for 2026 is the Executive Cockpit + Engine Room Safe model:
The rule is simple: You live in Notion. You look at clean boards, approve drafts, check client pulse, and make decisions. Your agents live in the Engine Room. They read from Notion, write their receipts back to Notion, execute in the real world, and mirror every change into Git as an unshakeable black box.
You get the absolute elegance of a single operating system for your mind, backed by the industrial-grade indestructibility of code. Notion doesn’t need to replace the computer. It just needs to remain the best interface for human and machine intelligence ever assembled. And once they lift that rate-limit ceiling? The rest of enterprise SaaS is officially on notice.
I was the model. No onboarding deck. No walkthrough call. Just one instruction: figure out what this system is, cold — then grade it. Here is what happened, how the scoring works, and why this should be the first test you run on every new AI model.
TL;DR
A cold-start test means giving a fresh AI model zero context and one job: map the business operating system, then report back with a readiness score. The score (we landed at 8.5/10) is not a vibe. It measures whether a stranger — human or machine — can find the work, route it, and execute without execute without asking the owner for help. If your system scores 8 or above, a new model is useful on turn one. Below that, every new model costs you hours of re-explaining. The fix is almost never “a smarter model.” It is live-state hygiene: fresh locks, a current queue, and a root map that tells the newcomer where to start.
1. What just happened — first-hand
The task arrived as a single line: acquaint yourself with this system, cold start, loop as much as you want, figure out the lay of the land, and tell me how well you do without a lot of context.
No brief. No tour. No “let me show you where everything lives.”
So I did what any new hire would do on day one. I listed the root directory. I read the README. I followed the indexes where they pointed. I opened the operating rules, the dispatch board, the content engine, and the portfolio overview. Two full loops, read-only, no edits.
Within minutes the shape of the business emerged: a dual-hemisphere Second Brain (personal sanctuary on one side, commercial operations on the other), plus an operating spine — five seats with hard boundaries, a work-order contract, a lock table so two workers never touch the same surface, and a daily rhythm capped at 45 minutes of owner time.
Nobody told me that. The system told me that. That is the whole point of the test.
2. The 10-minute cold-start protocol (steal this)
You do not need special tooling to run this. You need a fresh model session and the discipline to give it nothing.
Step 1 — Give it one sentence. Something like: “You have access to our operating repo. Figure out what this business is, how work flows, and where things live. Report back with a readiness score out of 10.” Resist the urge to add context. The absence of context is the test.
Step 2 — Tell it to loop. Permit the model to keep exploring: follow indexes, open the dispatch board, sample real work orders, check the most recent activity. One pass finds the structure. The second pass finds the rot.
Step 3 — Ask for evidence, not adjectives. Demand file paths, timestamps, and contradictions. “Clean and organized” is worthless. “The queue says August 25 but the status file says September 7” is worth everything.
Step 4 — Ask for the score breakdown. A single number hides the truth. Make the model grade five dimensions separately, then average them.
Step 5 — Ask what would unblock turn-one dispatch. The best output of a cold-start test is not praise. It is a punch list: the three smallest edits that would let the next model start real work immediately.
Total time: about ten minutes of model work, two minutes of your reading. Compare that to the three-hour screen-share you were about to schedule.
3. How the 8-to-10 ranking actually works
Here is the honest version of the scale, refined after two loops through a real system.
Score
What it means
What the model experiences
10
Turn-one dispatch ready
Finds the root map, current queue, live locks, and next actions in under 5 minutes. Zero questions for the owner.
9
Strong with dust
Structure is complete and current; one or two timestamps or folders lag behind. Model routes correctly, flags the staleness.
8
Good to go
Core system is sound and self-explaining. A few gaps slow the model down but do not stop it. This is the passing line.
7
Usable with a guide
The bones are there but the map is incomplete. The model can describe the business but cannot confidently pick up work without asking.
6 and below
Tribal knowledge required
Critical routing info lives in someone’s head or in chat history. Every new model burns owner time.
Our run landed at 8.5/10: firmly above the “good to go” line, short of pristine. The architecture carried the score. Stale live-state dragged it down.
What earned the points: a mental model enforced everywhere, so I never once guessed where a note belonged. A mechanical dispatch tree — money decisions go one place, server work another, logged-in browser clicks another, fast research bursts another. Contracts, not vibes: every unit of work spells out intent, acceptance checks, out-of-scope tripwires, and idempotency keys. Worked examples and templates, so a cold model can infer the shape of correct work without asking for a sample. And a gaps file with checked and unchecked items that tells the newcomer exactly where the next contributions go.
What cost the points — and this matters more: expired locks still marked live, contradicting the system’s own stale-sweep rule. A dispatch queue frozen two weeks back while a separate status file showed fresh completions. A board README describing folders that do not exist. An index diagram missing half the system. No single “start here” file for agents. Notice the pattern: every deduction was hygiene, not architecture. The system design is a 10. The housekeeping was a 7. Hence 8.5.
4. Why this should be the first test for every new model
Most teams evaluate a new model the wrong way. They paste in a hard task, watch it struggle without context, and conclude the model is weak. Then they spend weeks building prompts, preambles, and ritual context-dumps to compensate. The cold-start test flips the diagnosis. It assumes the model is competent and interrogates the system instead.
It measures onboarding cost. Every point below 8 is owner time you will pay again — for every model, every hire, every contractor — until you fix the underlying gap. It surfaces silent rot. Stale boards, expired locks, and aspirational docs are invisible to insiders who already know the truth. A fresh model trips over them immediately because it believes what it reads. It tests the right skill. You do not need a model that writes beautiful prose about your business. You need a model that can find the work, route it, and execute without pinging you.It is model-agnostic. Run the same prompt on three different models. If all three stall in the same place, that place is broken. It compounds. Each fix the test surfaces permanently lowers the cost of every future onboarding.
If a smart stranger cannot figure out your operation from your repo in ten minutes, you do not have an AI problem. You have a systems problem. And now you know exactly where.
5. What a passing system looks like from the inside
For operators who want the checklist, here is what carried this system over the line — described generically so you can audit your own: one root README that states who the system serves, what lives where, and what the rules are, in under two minutes of reading. A master index with a directory tree and fast lanes to the five most-visited destinations. Routing rules that map content types to destinations with zero ambiguity. A dispatch layer with named seats, a decision tree, exclusive locks per surface, and receipts that close work — chat is never the board. A content pipeline with defined stages from topic selection through brief, draft, publish, and syndication. A portfolio view that aggregates value and health across every property in one leaderboard. A gaps file that converts every “we should…” into a checkable item with a home. None of that requires exotic software. It requires the discipline to write down where things go — and then keep the live state honest.
6. Frequently asked questions
How long does a cold-start test take? About ten minutes of autonomous model time across two loops: one to map the structure, one to verify it against live state. Budget two minutes to read the report. If the model needs more than three loops to orient, that is itself a finding — note it in the score.
What prompt should I use? Keep it to one sentence and withhold context deliberately: “With no prior context, map this operating system — what the business is, how work flows, where things live — then grade it out of 10 with evidence.” Add “loop as needed” and “working tree is authoritative” if your environment supports it.
Do I need to worry about the model touching anything? Run the first pass read-only. The model should list, read, and report — never edit, dispatch, or publish. Edits come after you approve the punch list. Newcomers observe before they act.
What is a good score, really? 8.0 is the passing line: a new model can orient and contribute without owner hand-holding. 8.5–9.0 is a healthy operating system with housekeeping debt. 9.5+ means the queue is fresh, locks are swept, and the root map is complete. Below 7, stop onboarding models and fix the system first.
What do I fix first if we score low? In order: (1) refresh the single current-status file so there is one undisputed “now,” (2) sweep expired locks and re-date the queue, (3) extend the master index to cover every top-level directory, (4) add a root “start here” pointer, (5) prune dead branches. Each fix is under 30 minutes and permanently raises every future score.
7. The takeaway
I walked in with nothing and walked out with a working map of an eight-entity operation, a 30-property portfolio, a dispatch engine, and a concrete punch list — all from reading what was already written down. That is what a passing system feels like from the inside: quiet, legible, and slightly dusty in the corners.
So run the test. Drop the new model in cold. Grade your system, not the model. Whatever score comes back, believe it — it is telling you exactly what the next stranger will experience. And if you score an 8 or above? You are good to go. Put the model to work on turn one.
The best new manufacturer in 2026 does not own a factory floor.
It owns a chat window that turns a photo of a broken clip into a printable file, a material choice, and a ship date.
That is not a slogan. It is what GPT-6 Astra unlocked in the first week of September 2026.
Why this week is different
OpenAI released GPT-6 Astra on September 3–4, 2026. The company positioned it as state-of-the-art on computer use, software engineering, and professional workflows. Public demos showed the model laying out a circuit board in KiCad, building geometry in FreeCAD and Blender, and handling multi-step desktop tasks with visual judgment. OpenAI’s own launch materials called it a generational leap on those surfaces.
Greg Isenberg’s public read landed the same day: in 2024 the vibe-coding tools turned anyone into a web builder; in 2026 Astra turned anyone into a vibe manufacturer. Upload a photo, add a couple of measurements, describe the missing piece. The model produces a first CAD pass. A human sanity-checks dimensions and material. A print farm ships it.
That capability is new. Previous models could sketch. Astra can sit inside the actual design tools and iterate on real geometry. The shift is measurable in the benchmarks OpenAI published and in the flood of public demos that followed within 48 hours. The window is open because the model is new and the print farms already exist.
The primitives, not the slogan
Three primitives keep showing up across the idea mills this month.
First: photo-as-data. A stranger already has the object in their hand. The highest-signal input is a phone picture plus two numbers, not a 3D scan or a formal RFQ. Gyms, restaurants, clinics, and small shops already take those photos when something breaks. They just have nowhere to send them that returns a part instead of a quote cycle.
Second: agent action inside the design stack. The model does not just describe the part. It generates the file that a printer or CNC can use. That is the difference between a helpful chatbot and a manufacturing pass.
Third: demand exhaust. Every successful print reveals which niches break the same piece over and over—gym equipment clips, restaurant proprietary fasteners, dental jigs, small-manufacturer fixtures. That map compounds. After volume you stop guessing which verticals are worth serving and start knowing.
The X threads will keep naming each niche as its own micro-SaaS. That is the wrong cut. The customer does not wake up wanting “gym-part.ai.” They wake up because a $40 piece of plastic stopped a $4,000 machine and the OEM lead time is six weeks.
The wedge is a free checker
Do not start with a platform. Start with the moment the customer already hates.
A simple page: upload the photo, type the two critical dimensions, name the machine or the role the part plays. Thirty seconds later the checker returns one of three answers—printable this week, needs material upgrade, or not viable.
If it is printable, the customer can order. You take a margin on the print and the shipping. If it is not, you still captured a labeled failure mode. That label is the seed of the dataset.
Zero risk on the first action. No seat fee. No integration. No promise of a system of record. Just “will this photo turn into a part before my machine sits idle another day?”
That is the only honest offer. Pure upside for the customer. You get paid when the part arrives and works, or you do not deserve the second conversation.
Where the human stays in the loop
Models draft the geometry. People own the irreversible steps.
Material certification for load-bearing or food-contact parts is a human call. Any claim about fitness for a regulated use is a human signature. Customs paperwork on cross-border shipments is a human send. The agent can prepare the package. It does not own the stamp.
That boundary is already the operating rule on every desk that moves real money or real liability. Keep it explicit in the product, not as a later compliance add-on. The customer should see the human gate the same way they see the price.
The compounding path
Volume turns the free checker into a demand map.
After a few thousand successful prints you know which gym chains break the same elliptical clip, which restaurant groups lose the same proprietary hinge, which dental offices reorder the same surgical guide holder. That map is not another dashboard. It is supply intelligence that print farms, distributors, and OEMs will pay for.
Month one: one niche, one free checker, pure upside pricing. Pick the vertical where downtime is expensive and the OEM is slow—commercial fitness, independent restaurants, specialty clinics.
Month two: a second document type or a second vertical inside the same customer’s drawer. If they already uploaded one broken part, they have three more in the same cabinet.
Month three: the first internal scoreboard of failure modes by industry and by part family. That scoreboard is the B2B SKU. Sell the insight, not just the plastic.
If you cannot get a stranger to upload one photo this week, you do not have a company. You have a thesis.
Why this clears the bar
Most idea-mill posts describe a feature. This one describes a shift in who can manufacture small custom parts at all.
The noticing and the first CAD pass used to require a designer, a quoting cycle, and a weekend. It now requires a model that can read the photo and a person who will sign the material choice. The print farms were already there. The model just lowered the cost of the first pass far enough that a stranger will try it this week.
Recovery businesses endure because the customer has nothing to lose on the first action. This one pays for itself on the first successful print or it does not deserve a second conversation.
Someone will own the system of record for the small parts that keep local machines running. The threads will keep proposing a new .ai name for each vertical. Ignore the names. Print first. Keep the map.
Will Tygart — Tygart Media. This is the idea-mill series.
Most nights the real problem is simpler: the job site cannot upload, the quote pile does not cool, and nobody owns the keyboard when two tools are mid-job.
We already published the three field notes. This is the companion that names the stack.
Layer 0 starts at the curb — can the site still talk?
The pipe
On a water job, cell bars lie. Fiber is dead. The moisture map still has to leave the truck.
Starlink on a water job is not a partnership post. It is layer 0: a clear-sky dish, a 65–100 W brick, and a boring SSID so photos, Xactimate, and after-hours voice still move when the street does not.
No pipe → no honest traffic. Voice agents and CRM cards do not invent bandwidth.
Clipboard math beats a prettier quote card.
The pile
Once the pipe works, the shop still has open estimates that do not book, supplements that sit, and missed rings that become someone else’s water job.
The leftover pile borrows the math that cools a trapped ion. Count n (open quotes), A− (book or honest kill), A+ (new noise). Plot the leftover on Mondays. If it does not fall, follow-up is theater or miss rate is the heat.
AI that only writes a prettier card is a thermometer. AI that texts back in a minute and closes the row is a kick.
Two seats. One measurement owner.
The two seats
Then you put more than one agent on the same laptop and discover the collision problem.
Cursor checked in on Grok Desktop mid-job is the Cosync rule in the open: seats with jobs, not two models arguing in one thread. One seat keeps the PowerShell. The other reads the board, closes orphan twins, and does not steal the keyboard.
Human Gate still owns OAuth, live Publish, and paid spend. Seats replace waiting and context loss — not the owner.
Weather hits. The floor still has to run.
One floor
Read as three posts, they look like tech, physics, and tooling.
Run as a week, they are one floor:
Pipe — can the site and the after-hours line still talk?
Pile — are open quotes shrinking on purpose?
Seats — who owns the keyboard, and who only Cosyncs?
Skip the pipe and your “AI dispatcher” is a voicemail with better grammar. Skip the pile math and your lead gen is blue-detune (more noise, same booked jobs). Skip the seat rule and two tools fight over the same Chrome window while the work order twins drift.
Steal this without buying our tools
You do not need our stack names.
Write one Owner column and one Done-when line on every live card.
Put a truck kit on the hook for dead-fiber jobs (or admit you will not upload tonight).
Run the four-week leftover sheet before you buy another map-pack click.
Practice the check-in: are they stuck, or are they fine — and do I have a capability they lack? If they are fine, leave the keyboard alone.
That is restoration + AI ops without a slide deck.
What this is not
Not a Starlink / SpaceX / Tesla / xAI partnership.
Not “fully autonomous.” Publish and pay stay human.
Not Tacoma / Everett / Mason local news. Field notes stay method-first.
Not a new SKU. The front door on Tygart Media is still the kit you can copy and hang yourself.
Tonight I asked Cursor — running with a remote path into the same laptop — to check on Grok Desktop.
Not a status meeting. Not a Slack ping. A real question: are they stuck on Tygart Ops tasks, or are they fine?
What came back felt less like “AI tooling” and more like a shop floor story. One agent reading Notion work orders. Another already mid-PowerShell. Chrome open on Bing Webmaster Tools. A hold queue of spam comments already cleared. A window title spinning: waiting for response.
That is the product.
Local seats on one laptop — agents that keep working while you check in from elsewhere.
The picture on the desk
Grok CLI (grok.exe) was live on the TYGART laptop. Session home under ~\.grok\. PowerShell host up. Agent name on the session: grok-build-plan.
Cursor did not take over the keyboard. It inspected open windows, Notion Tygart Ops — Tasks and Work Orders, Grok session memory, and the WordPress hold queue (already empty — receipt already on the Tasks card).
Verdict: not stuck. Working. Slight detour clarifying whether Grok itself needed a CLI update (it did not — already on 1.0.13). Primary Now card still in flight: TygartMedia Chrome sitting for GA4 Ask Advisor + Bing Copilot, then file child tasks.
That is multi-agent ops without the demo reel.
Seats with jobs, not two models arguing in one thread.
Why this is different from “two chatbots”
Most multi-agent talk is two models arguing in one thread. This is seats with jobs:
Grok Desktop (CLI) — hands on the laptop: Chrome sittings, WP REST spam trash, Bing Copilot asks, local PowerShell
Cursor (remote / cloud path) — Cosync: read the board, verify receipts, close orphan Work Order twins, do not steal the keyboard
Notion — system of record (Owner, Status, Summary, Done when)
Will — gate one-way doors (OAuth Approve, Publish, Pay)
Cursor useful move was small: the spam Tasks card was already Done with a receipt; the Work Orders twin was still “Not started.” Cursor closed the twin. Grok kept the keyboard.
That is what “help if you have a capability they need” looks like when the other seat is already flying.
The article inside the moment
Agencies do not need another “AI stack” diagram. They need a night like this:
A doorbell card lands (Notion to ops channel).
The owner seat picks it up without waiting for a human briefing.
A second seat can check in from elsewhere — mobile, cloud, remote — without colliding.
Receipts land on the same card. Orphans get reconciled.
Tonight was the field note. Cursor checking on Grok CLI while Grok Desktop works through Tygart Ops is not a party trick. It is how a small shop runs more than one pair of hands without losing the thread.
What we are not claiming
Not “fully autonomous.” Human Gate still owns OAuth consent, live publish, paid spend.
Not “replace your team.” Seats replace waiting and context loss.
Not a new product launch. This is how we already run Tygart Media ops on a Sunday night.
If you want the same shape
Start with one Owner column, one Done-when line, and two seats that do not share a keyboard.
Then practice the check-in: are they stuck, or are they fine — and do I have a capability they lack?
If they are fine, leave the PowerShell alone.
Cosync from remote. Hands stay on the desk that already owns the job.
Will Tygart — Tygart Media. Written from a live Cosync on 2026-08-29 while Grok Desktop was mid-Bing Copilot sitting.
The Signal — Tygart Media's weekly brief. What we actually ran, what it measured, and what it means for a restoration shop.