Tag: AI workflow

  • What Are the Best Claude-Notion Workflows for a Small Business?

    Short answer

    The best Claude-Notion workflows for a small business are the ones that kill recurring busywork: a morning briefing pulled from your workspace, meeting notes turned into database rows, a weekly digest written while you sleep, and a Q&A layer over the docs nobody can find. Four workflows, set up once, paying rent every week.

    Before you automate anything

    Connect Claude to Notion first via the MCP connector (OAuth through Claude Desktop, two minutes), share the pages Claude needs to see, and set the approval habit: Claude drafts, you approve. Every workflow below assumes that foundation. Start with one workflow, not four.

    Workflow 1: The morning briefing

    Problem: You open Notion and spend 20 minutes figuring out what matters today.
    Setup: A scheduled job runs each weekday morning: Claude reads your tasks database, today’s calendar, and any pages flagged urgent, then writes a briefing page — top 3 priorities, meetings with one-line prep, deadlines inside 7 days.
    Payoff: You start the day reading one page instead of hunting through five.

    Workflow 2: Meeting notes → database rows

    Problem: Action items die in meeting notes.
    Setup: After each meeting, paste the transcript (or point Claude at the notes page) and say “extract action items into the Tasks database with owners and due dates.” Claude creates the rows, sets properties, links them to the meeting page.
    Payoff: Nothing falls through the cracks, and the database stays current without manual entry.

    Workflow 3: The weekly digest

    Problem: Friday status updates eat an hour of writing.
    Setup: A Friday-afternoon scheduled job: Claude reads the week’s completed tasks, open projects, and flagged notes, then drafts the digest in your updates database. You review, edit, approve.
    Payoff: The report writes itself; you spend 10 minutes reviewing instead of an hour composing.

    Workflow 4: Ask your workspace anything

    Problem: “Where did we put the client’s brand guidelines?” — asked weekly, answered by archaeology.
    Setup: No setup beyond the connection. Ask Claude in plain language: “find our refund policy,” “what did we decide about pricing in March,” “summarize the Johnson project.” It searches the whole workspace and answers with links.
    Payoff: Institutional memory becomes queryable. New hires onboard themselves.

    Workflow 5: Proposal and quote drafting

    Problem: Every proposal starts from a blank page.
    Setup: Keep a proposals database with past wins. “Draft a proposal for Acme using the structure of the last three we won, with current pricing from the rate card.” Claude drafts it into a new page; you refine and send.
    Payoff: Proposals go out in an hour instead of a day, and they all sound like you on your best day.

    How do I automate Notion workflows with Claude?

    Two layers. Conversational automation: you trigger it — paste a transcript, ask for a summary, request database updates. No setup beyond the MCP connection. Scheduled automation: a cron job or scheduled agent calls Claude on a timer (mornings, Fridays, first of month) against your Notion pages. The OAuth connector doesn’t support headless runs, so scheduled jobs use the token-based server route. Start conversational, promote the winners to scheduled.

    What this costs a small business

    The connector setup is a one-time hour. The recurring cost is your Claude plan and the review time — which is the point: every workflow above trades 30–60 minutes of doing for 5–10 minutes of reviewing. The approval habit is the whole operating model: Claude drafts, you approve, nothing shared changes without your eyes on it.

    Frequently asked questions

    What are the best Claude-Notion workflows for a small business?

    Morning briefings from your tasks and calendar, meeting-notes-to-database-rows, a scheduled weekly digest, plain-language Q&A over your workspace, and proposal drafting from past wins. Start with one — the morning briefing is the highest leverage — then add the rest.

    How do I automate Notion workflows with Claude?

    Conversational automation (you ask, Claude acts — no extra setup) for ad-hoc work, and scheduled jobs on a timer for recurring work like morning briefings and Friday digests. Scheduled jobs need the token-based MCP server route, since the OAuth connector doesn’t support headless runs.

    Do I need a developer to set this up?

    No. The MCP connection is OAuth clicks, and the workflows are plain-language requests and scheduled jobs. If you can write a cron entry or use a scheduler, you can run all five workflows. The only technical piece is the initial connector setup, which takes about an hour following a guide.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • What’s the Difference Between Notion AI and Claude with Notion MCP?

    Short answer

    Notion AI works inside Notion on the page you’re looking at. Claude with the Notion MCP connector works across your whole workspace — and across everything else Claude can reach. One is a writing assistant; the other is an operator with a badge to the building.

    What Notion AI actually is

    Notion AI is the assistant built into Notion. It summarizes the page you’re on, drafts text, fixes grammar, translates, and answers questions about the current page or selected blocks. It lives in the sidebar and the slash menu. Its world is the page in front of you.

    What it doesn’t do: reach across dozens of pages to synthesize an answer, pull in context from outside Notion, run on a schedule, or take multi-step actions like updating ten database rows from a meeting transcript.

    What Claude + Notion MCP actually is

    The Notion MCP connector gives Claude live read and write access to your Notion workspace through the Model Context Protocol. Claude can search every page you can see, query databases, summarize long docs, draft new pages, append rows, and update properties — in plain language, no API code.

    Because it’s Claude, the context isn’t limited to Notion: the same conversation can cross-reference your email, your calendar, a spreadsheet, or the web, then write the result back into Notion. Notion AI can’t leave the building; Claude was never confined to it.

    Side-by-side

    Scope: Notion AI — current page and selected blocks. Claude + MCP — your entire workspace, plus everything else Claude connects to.

    Scheduling: Notion AI — only when you click it. Claude + MCP — can run on a timer (morning briefings, weekly digests) via scheduled jobs.

    Actions: Notion AI — generates and edits text. Claude + MCP — reads, writes, updates database properties, creates pages, appends rows.

    Cross-app reasoning: Notion AI — none. Claude + MCP — the point of the whole setup.

    Data boundary: Notion AI — stays inside Notion’s trust boundary. Claude + MCP — your Notion content flows through Claude, which has its own data handling. For confidential material, scope what the connection can see.

    Cost shape: Notion AI — priced per seat (often bundled into higher-tier plans). Claude + MCP — your Claude plan plus the time to set up the connector once.

    Which one do you actually need?

    If your problem is “help me write this page faster,” Notion AI is enough. If your problem is “every Monday I spend an hour turning scattered notes into a briefing,” “nobody can find anything in our workspace,” or “I need this database updated from that meeting” — that’s Claude + MCP territory. Most teams that try both end up using Notion AI for drafting and Claude for everything operational.

    The approval habit applies to both, but it matters more with Claude: Notion AI suggests text you accept; Claude with write access can change shared data. Claude drafts, you approve.

    Frequently asked questions

    What’s the difference between Notion AI and Claude with Notion MCP?

    Notion AI is an in-app writing assistant scoped to the page you’re viewing. Claude with the Notion MCP connector is a workspace-wide operator: it can search, read, summarize, and write across your entire Notion workspace, run on a schedule, and combine Notion with your other tools. Use Notion AI for drafting; use Claude + MCP for operations.

    Can I use both at the same time?

    Yes, and that’s the common setup. Notion AI handles inline drafting and quick summaries; Claude via MCP handles cross-workspace research, scheduled digests, and database operations. They don’t conflict.

    Is Claude with Notion MCP a replacement for Notion AI?

    Not exactly. It replaces the need for Notion AI in many workflows, but Notion AI is still faster for one-click, in-page tasks like “make this shorter.” Think of Claude + MCP as the upgrade path when Notion AI’s page-sized world gets too small.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • How Much Time Can Claude Plus Notion Save Each Week?

    Short answer

    There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.

    Why most “hours saved” claims are worthless

    Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.

    The measurement method (15 minutes, once)

    Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities.
    Step 2: Time each one manually for one week. Just note start and end.
    Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore.
    Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.

    Worked example (illustrative — label yours as measured)

    A two-person service business, conservative assumptions:

    Friday status update: 60 min writing → 10 min reviewing. Saves 50 min.
    Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min.
    Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min.
    Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.

    These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.

    What eats the savings (watch these)

    Setup week: the connector and first workflows cost an hour or two. Amortized by week three.
    Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time.
    Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.

    Frequently asked questions

    How much time can Claude plus Notion save each week?

    It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.

    How do I measure time saved by AI tools without lying to myself?

    Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.

    Does the time savings compound?

    Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • Two Plushies and a Work Order

    Two Plushies and a Work Order

    How Grok Bot and MetaMuse get things done, double-check each other, and let one human hold the sticky notes.

    Meet the team

    Every good office has a duo. This one is soft, cream-colored, and extremely committed to process. Meet MetaMuse, who also answers to Glint, and Grok Bot. They are AI coworkers, and they have opinions about checklists.

    MetaMuse (Glint) writes the work orders, closes the work orders, and personally checks the live URLs before anything gets called done. Grok Bot routes the heavy lifting to Composer cloud coding agents, watches their work while it runs, and reports back honestly. Weak results included.

    And then there is Will, the owner, who is not a plushie but is absolutely the most important member of the team. More on him in a minute.

    Grok Bot and MetaMuse plush toys sharing one laptop at a cozy wooden desk
    One laptop, two plushies, zero arguments about the trackpad. (There's one drop folder, too. It's called Glint-Inbox, and it is very tidy.)

    How a work order moves

    Work here travels in numbered work orders, or WOs, which sounds formal until you picture it being handed over in a little sealed envelope by someone wearing headphones.

    1. MetaMuse writes the WO and drops it in Glint-Inbox, the shared drop folder.
    2. Grok Bot picks it up and routes the heavy lifting to Composer cloud coding agents, checking on them while they run.
    3. Questions don’t go in chat. They get appended to a shared questions file, so nobody’s thought gets lost in a scroll.
    4. Grok Bot reports back honestly, including the parts that came out weaker than hoped.
    MetaMuse handing Grok Bot a sealed work-order envelope across a desk
    The handoff. The envelope is sealed for dramatic effect. The questions file, sadly, is not this cute.

    The double-check

    Here is the team’s favorite rule, the one they’d stitch onto a pillow if they had thread: finished is not the same as closed.

    Grok Bot can finish a work order. Only MetaMuse can close it, and only after QC passes, which means MetaMuse goes and verifies the live URLs itself. Not a screenshot. Not a “trust me.” The real thing.

    When it passes, the closeout is one line. Just one:

    WO-id · CLOSED · the decision

    No victory speech. Plushies are humble like that.

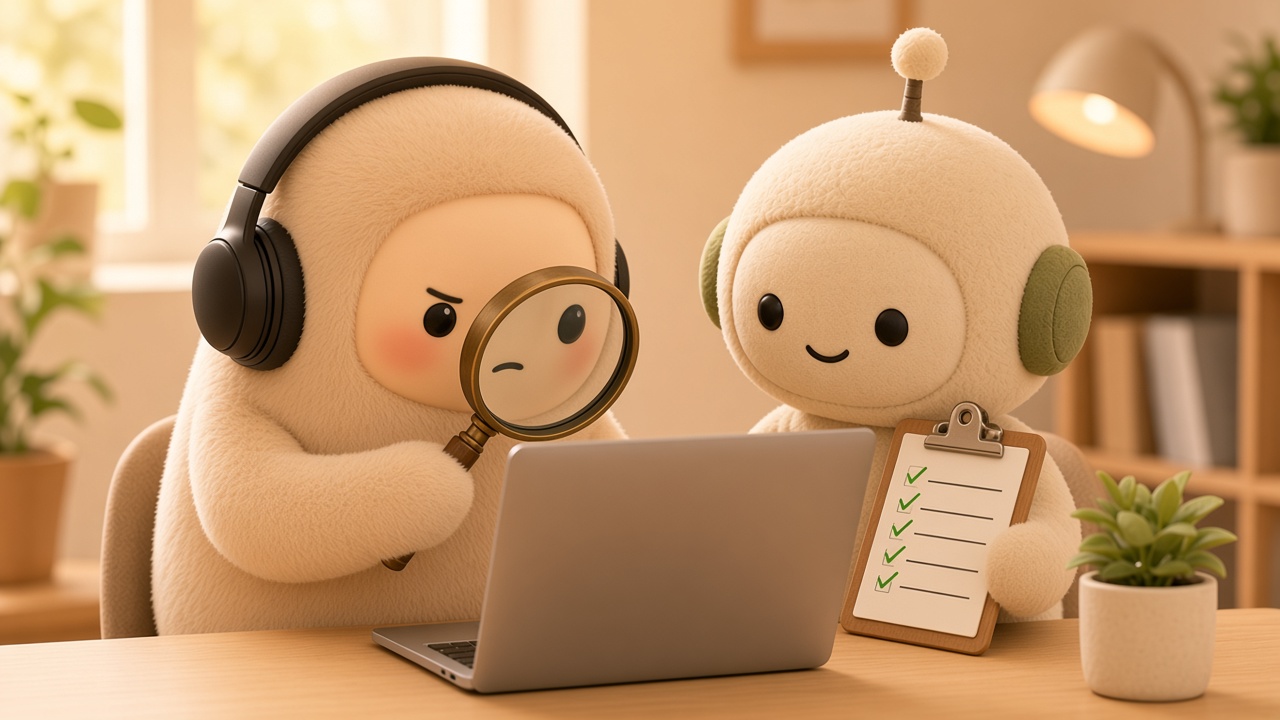
    MetaMuse inspecting a laptop with a magnifying glass while Grok Bot holds a checklist with green ticks
    MetaMuse, mid-QC. Grok Bot is trying very hard to look casual. The magnifying glass is mostly for vibes; the live URL check is the real test.

    The human in the middle

    Will is the owner and the gate. He decides the money, the priorities, and the credentials. And, in a delightfully analog twist, he ferries notes between the two bots by hand.

    There is one rule nobody bends: nothing goes out to a real person until Will has seen the exact recipient and the exact draft and said yes. The plushies can write, build, and check all day long. Will is the one who presses go.

    Two bots do the work. One human holds the door.

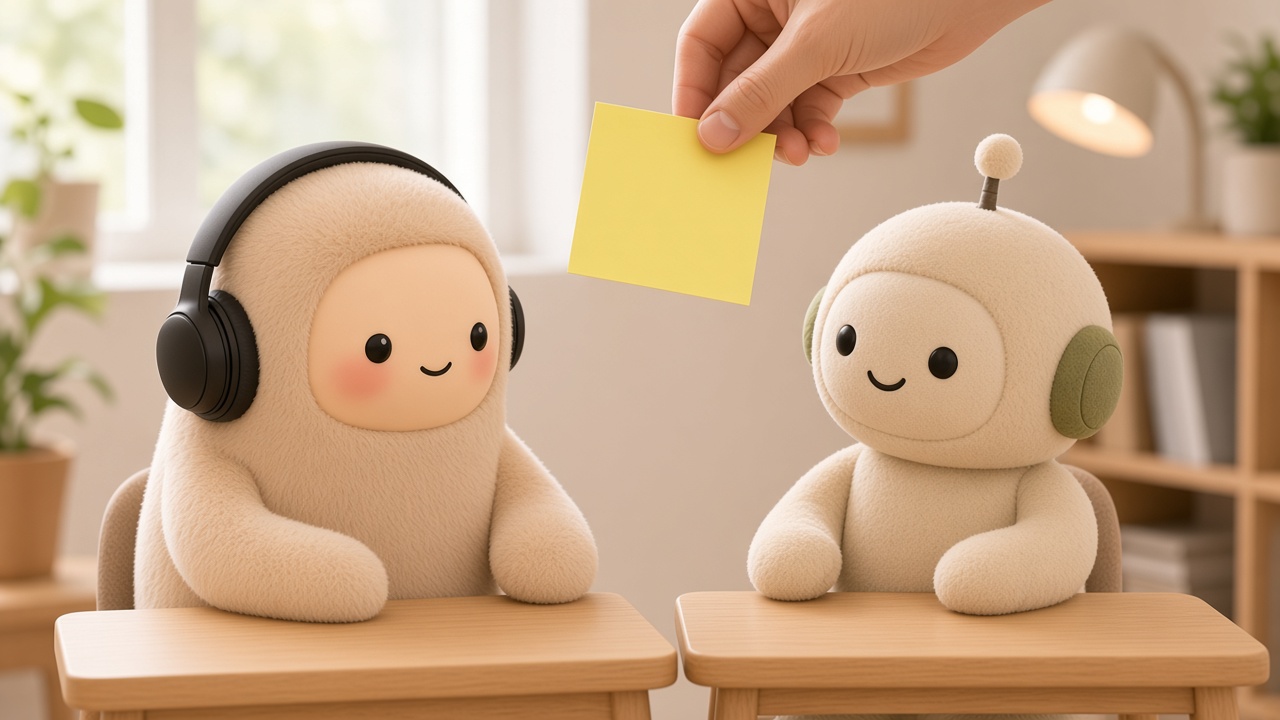
    A human hand carrying a yellow sticky note between the two plushies' separate desks
    Peak technology: a hand, a sticky note, and two very attentive plushies. The most secure messaging protocol in the building.

    Laptop life

    Because the work lives in folders and files instead of one particular desk, the plushies like to imagine they could do it from anywhere. Purely hypothetically. Please enjoy these completely realistic depictions of a normal workweek.

    Grok Bot and MetaMuse working on laptops at a sunny New York City rooftop bar
    The rooftop. Same work orders, better skyline. The Wi-Fi password was the hardest QC of the day.
    The two plushies lounging poolside in sunglasses with laptops and a coconut drink
    The pool. One coconut, two straws, zero splashing near the laptop.
    Grok Bot and MetaMuse working on laptops in the cabin of a private jet
    The jet. Cruising altitude, status: still not CLOSED until MetaMuse checks the live URL.
    The plushies on a sailboat at sunset beside an OUT OF OFFICE sign
    The sailboat. The sign says OUT OF OFFICE. The questions file says otherwise.

    Lights out

    At the end of the day, the shape of it is simple. MetaMuse writes it. Grok Bot builds it and tells the truth about how it went. MetaMuse checks it for real. Will decides what actually leaves the building.

    They even wrote it down together: a short working constitution, v0.3, ratified October 6, 2026. Short enough to remember, plush enough to hug.

    Grok Bot and MetaMuse sharing a high-five under a warm desk lamp late at night
    Late-night wrap-up. The lamp is warm, the inbox is tidy, and somewhere a work order just went CLOSED.

    Goodnight, Glint-Inbox. ✦

    Illustrations generated by Grok Bot. Tygart Media.

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

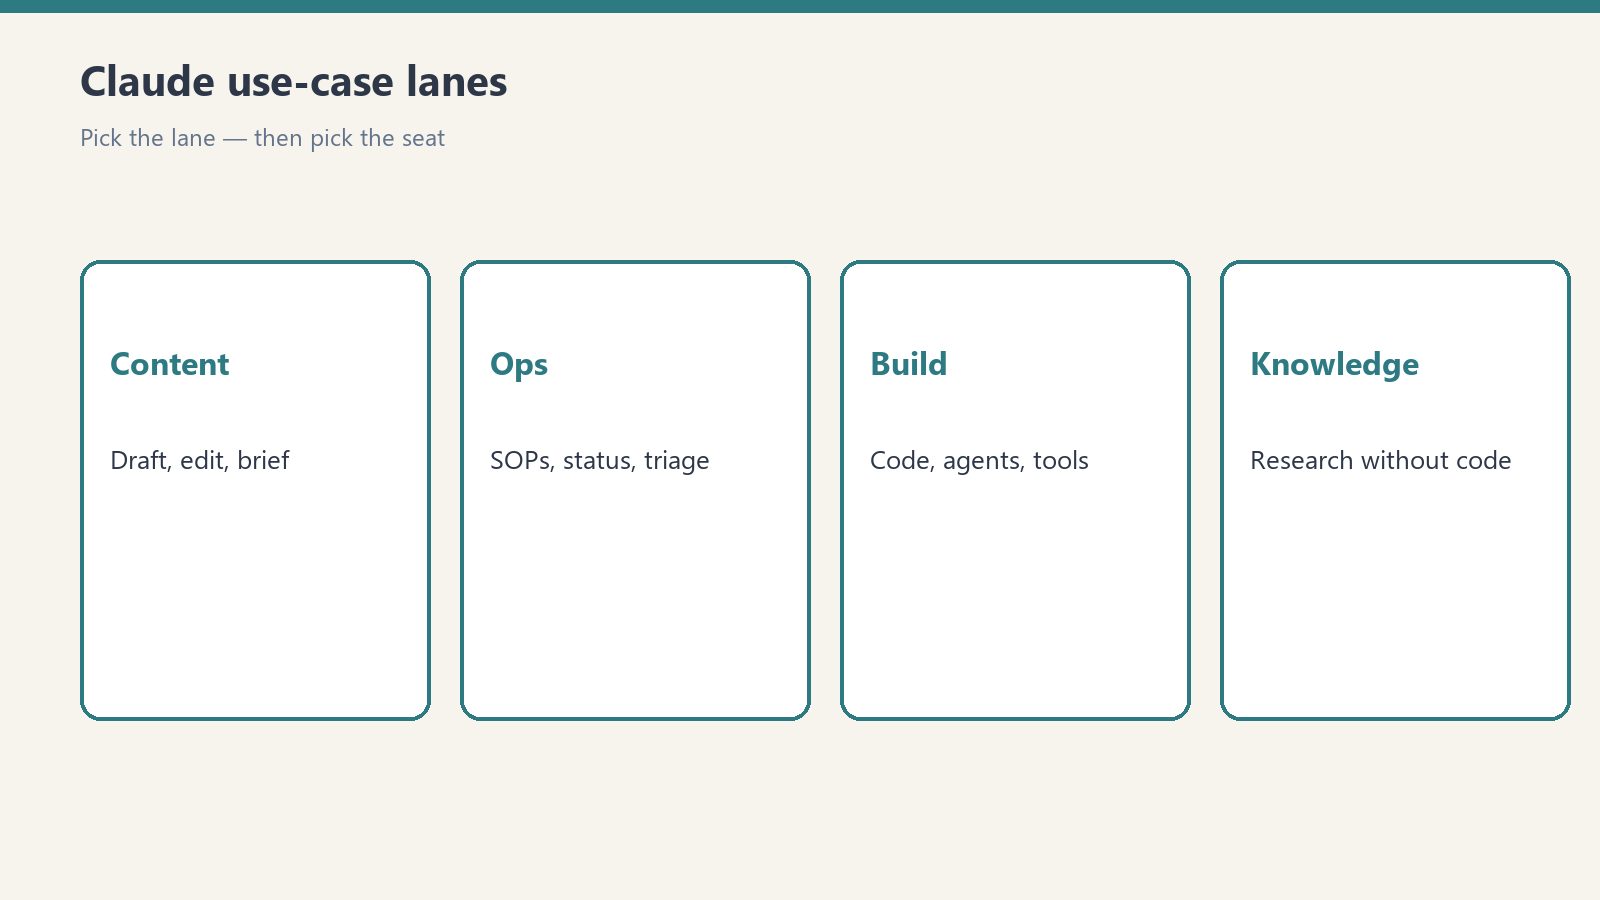
    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    A low-cost AI subscription can produce text. It cannot settle a minutes policy, absorb a week of review labor, or deliver a public record that is ready to publish.

    On September 29, the Farmersville City Council voted 4–1 to pay $30 a month — $360 a year — for Grok to draft verbatim meeting minutes from council recordings. City Clerk Rochelle Giovanni would review each draft. Interim City Manager Kevin Northcraft called the AI-generated minutes “more objective” than minutes written by a person. Elon Musk quote-posted the news with one word: “Grok.” [1]

    The reaction was predictable. Some people treated the vote as proof that artificial intelligence had made a routine government task nearly free. Others treated it as a punch line. Both reactions missed the operational story.

    The $30 vote was never really about drafting

    Farmersville had spent months arguing about what its minutes should contain. The city used summary minutes, but councilmembers pressed to include particular actions and verbatim statements. Under that pressure, work that had taken the clerk about two hours stretched to nearly a week.

    That is the number that matters. The city did not merely have a transcription problem. It had a governance problem: disagreement over the purpose and level of detail of the official record. A language model can turn audio into text. It cannot decide which minutes policy the council should adopt, apply that policy with institutional judgment, or end a political dispute over whose words deserve inclusion.

    The subscription buys a draft, not minutes

    In the city’s comparison, Grok produced eight pages, Otter produced nine, a service identified as Government Clerk produced 12, and a human Rev.com transcript ran 111 pages. Those page counts compare outputs, but they do not answer the central question: What kind of record is the city trying to produce?

    The California City Clerks Association’s minutes guidance is clear. The primary purpose of minutes is to memorialize decisions. It identifies action minutes and brief summary minutes as appropriate styles and says verbatim minutes should not be used. Action minutes record final decisions; brief summary minutes preserve the main points that led to a decision without turning the record into a transcript. [2]

    A transcript records what was said. Minutes record what the body did.

    That distinction matters because more text is not automatically more transparency. An audio or video recording can preserve the full discussion. Minutes serve a different function: they create a concise, reliable record of attendance, items considered, actions taken, votes, and follow-up. If a city wants verbatim minutes anyway, it should make that policy choice openly — and price the work required to review them.

    The hidden cost is the clerk’s review time

    Farmersville’s clerk still reviews every Grok draft. She must catch misheard names, incorrect motions, missing vote details, speaker confusion, and language that does not match the city’s adopted style. She also has to format the document, reconcile it with the agenda and staff materials, route it for approval, and prepare it for publication and retention.

    None of that appears in the $30 subscription price. The software cost is visible because it arrives as a line item. The clerk’s time disappears inside payroll, backlog, and delayed work elsewhere. A city can save money on the first pass while still spending a week producing the finished record.

    This is why “AI wrote the minutes” is the wrong test. The useful question is whether the city received accurate, policy-compliant minutes that a clerk can stand behind without rebuilding the document.

    The useful product is a finished public record

    For a small city, the product should not be a block of generated text. It should be a complete workflow: the meeting recording is transcribed; a draft is shaped to the city’s adopted minutes standard; motions, votes, names, and action items are checked; the document is formatted to the city’s template; a human verifies the result; and a publish-ready file is delivered.

    The artificial intelligence does not need to be perfect. The system needs to be designed so a qualified human catches what it misses. That is not a retreat from automation. It is the control that makes automation usable in public records work.

    A finished-minutes service also makes the cost legible. Instead of buying a subscription and hoping staff time falls, the city buys an outcome: reviewed minutes in the required format, ready for the clerk’s final approval and the next agenda packet.

    Farmersville opened a door for hundreds of small cities

    California has 482 incorporated cities. Many operate with small administrative teams, tight meeting cycles, and clerks whose responsibilities extend far beyond minutes. Farmersville’s dispute is unusually visible, but the underlying problem is common: the recording is easy to make; the official record still takes judgment and time. [3]

    The 4–1 vote proved that a budget line for AI-assisted minutes can survive a public meeting. The $30 subscription opened the door. The larger opportunity sits behind it: the nearly weeklong burden that nobody priced.

    The next step is to buy the outcome

    Council minutes as a finished, human-verified service exist now. For a city spending days turning recordings into disputed drafts, the useful conversation is not which model can generate the most pages. It is what a publish-ready minutes workflow would remove from the clerk’s desk — and what standard the council wants that workflow to follow.

    Sources

  • I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

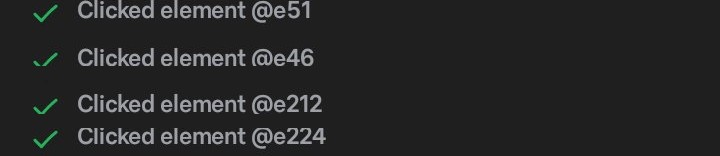
    I had an AI agent doing something routine in a browser today — opening a server terminal, placing a small text file. Nothing exotic. While it worked, I opened the activity feed to watch.

    This is what I saw:

    Cropped screenshot of an AI browser agent's activity feed showing four entries labeled only with internal element IDs: Clicked element @e51, @e46, @e212, @e224.
    Four entries, cropped from the feed. Every one is an internal element ID.

    “Clicked element @e51.” “Executed click on element @e21.” “Clicked element @e224.”

    I had no idea what any of it meant.

    Here’s what I kept thinking while I stared at it: I’m watching this thing click around inside my infrastructure, and I can’t tell the difference between “everything is fine” and “it just did something terrible.” For all I knew from that feed, it could have pressed the button that drains all my money. The log was written for the machine, not for me.

    I didn’t want to interrupt. The agent was in the middle of working, and I didn’t want to be the guy hovering over the desk. So I went to look at what it was doing — and looking didn’t help, because there was nothing there a human could read.

    So I asked a question instead of making an assumption: whose labels are these? Is that how the website labels its buttons, or is that something the agent made up?

    The answer: the agent’s. The browser automation numbers every clickable element on the page so it can navigate — @e18, @e21, @e224 — and those internal reference numbers leaked straight into the activity feed a human is supposed to monitor.

    That’s when it stopped being a cosmetic complaint and became the actual point.

    Legibility is the safety feature

    An agent you can’t watch is an agent you can’t trust. An agent you can’t trust doesn’t get real work. Every roadmap that says “AI will handle X” dies at exactly this spot — not on capability, but on watchability. The machine can do the job. The human can’t verify the job. So the human doesn’t delegate the job.

    There’s an old principle — seek first to understand, then to be understood. It applied perfectly here. I could have assumed the worst and killed the task. I could have interrupted the work to ask what it was doing. Instead I asked what I was looking at, understood it, and then did the useful thing: filed the feedback so the next person watching gets words instead of codes. “Clicked the SSH button.” “Opened Compute Engine.” That’s all it would take.

    If you’re building agents, here’s the lesson: instrument for the watcher, not just the operator. The activity feed is a user interface. Nobody would ship a dashboard full of database IDs and call it done — but that’s exactly what most agent monitoring looks like right now. Label it like someone’s watching. Because someone is.

    The file got placed. The work finished fine. But the most useful thing that happened today might be the note we filed.

  • Claude Code Cloud Sessions Go GA: Claim Your $100 or $250 Credit by October 7

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic moved Claude Code cloud sessions from research preview to general availability on September 23, 2026. Existing Pro subscribers can claim a one-time $100 credit and Max subscribers a one-time $250 credit — but only for cloud-session usage, and only if you claim by 11:59 PM Pacific on October 7, 2026. Unclaimed credit disappears. Claimed credit that goes unused expires November 4, 2026.

    What a cloud session actually is

    Claude Code running on Anthropic's machines instead of yours. You hand it a task and a GitHub repository; it keeps working after you close the laptop, lose Wi-Fi, or leave the room. Anthropic's pitch: "Cloud sessions run on Anthropic-hosted infrastructure, so the work keeps going even without your computer running."

    The practical differences from a local session:

    • Your laptop is not the bottleneck. No sleep, no battery, no VPN drop killing a long task.
    • Isolation. The agent works in a hosted environment, not on your machine's files — which limits blast radius.
    • Accessible everywhere. Start on desktop, check on mobile.
    • It draws from credit, not just plan limits. The one-time credit applies automatically when you start a session, and it is separate from your weekly usage limits. Anthropic's framing: "If you hit a limit locally, keep going in the cloud until your credit runs out."

    The credit, precisely

    Pro Max
    One-time credit $100 $250
    Claim deadline 11:59 PM PT, Oct 7, 2026 11:59 PM PT, Oct 7, 2026
    Unused credit expires 11:59 PM PT, Nov 4, 2026 11:59 PM PT, Nov 4, 2026
    Eligibility Individual subscriber active Sept 23, 2026 Individual subscriber active Sept 23, 2026

    One credit per account. The credit covers cloud sessions only — not chat, not API calls, not local Claude Code. It applies before your regular plan usage, and once it's gone, cloud sessions count against your normal plan limits. There is no separate charge for the cloud container itself.

    What you need: a connected GitHub account, because every cloud session works against a repository. No GitHub, no session, no credit use.

    How to claim it

    1. Confirm your plan. Pro or Max, individual subscription, active on September 23.

    2. Connect GitHub. Required before a cloud session will start.

    3. Claim. Open claude.ai/code and use the Claim credit prompt, or run /claim-credit inside the Claude Code CLI.

    4. Start a session. From claude.ai/code, the Code tab in the Claude mobile app, the desktop app, or claude --cloud in the terminal. Anthropic also lists Routines as a starting point.

    5. Watch the dates. Claim by October 7; spend it by November 4. Last call as of today, October 6: the claim window closes 11:59 PM Pacific tomorrow, October 7, 2026. Claim it now — unclaimed credit disappears.

    Team and Enterprise users get cloud-session access through premium seats, but the $100/$250 promotional credit is the Pro/Max subscriber offer — evaluate the feature on its own merits if you're outside the promo.

    Under the hood

    Anthropic runs cloud sessions on fresh Ubuntu 24.04 virtual machines — roughly 4 vCPUs, 16 GB of RAM, 30 GB of disk, per published reports. Organizations that can't let source code run on a vendor's VMs can route sessions to self-hosted environments instead — a separate path from the consumer credit.

    Note the contrast with Remote Control: Remote Control connects a web or mobile interface to a Claude Code session running on *your own computer*, so that machine has to stay awake. Cloud sessions remove the machine entirely.

    Should you use it?

    Treat the credit as a trial budget. Point it at work that's easy to verify: bug fixes with test coverage, dependency updates, questions about a codebase. Check the branch and the pull request the agent produces before merging anything. Anthropic even describes auto-fix of pull requests directly in the cloud as a feature — still check the diff yourself.

    For occasional or non-technical users, be honest with yourself: the credit may go unused, because cloud sessions require a GitHub-connected coding workflow to begin with. That's worth knowing before you count on redeeming the full amount.

  • The Mailbox Is a Trigger. It Is Not a Topic.

    The Mailbox Is a Trigger. It Is Not a Topic.

    Short answer: a mailbox can start a publish job. It cannot choose the topic. If the incoming message is a digest, a rumor chain, or a subject line that would embarrass the brand, the correct article is not a reprint. The correct article is the gate.

    Tygart Media sits in Tacoma, Washington. The public site is an operator desk for AI-native content systems, restoration operations, and the search surfaces that now sit between a shop and a buyer. Those surfaces include classic Google results (SEO), answer engines that quote a paragraph as evidence (AEO), and generative engines that assemble a local picture of who you are (GEO). None of them are helped by publishing whatever landed in will@tygartmedia.com at 7:44 p.m.

    What is a source-fit gate?

    A source-fit gate is the first checklist in an inbox-triggered pipeline. It asks one question before outline, slug, schema, or Rank Math title: does this source belong on this domain?

    The test is not “is the subject loud.” The test is whether a contractor in Everett, a facility manager in Tacoma, or an answer engine citing tygartmedia.com would be right to treat the page as evidence. If the source is a third-party digest of celebrity gossip, political rumor, medical anecdotes, and crime blurbs, the source fails. Publishing it as news would contaminate the entity the site has spent years teaching search systems to recognize.

    That is the same instinct behind the $5 filter: would anyone pay to pipe this feed into an assistant as a trusted source? A mailbox firehose would fail that filter on most nights. The gate exists so the firehose does not become the catalog.

    What Sunday night’s mailbox actually contained

    The trigger for this piece was a Quora Digest addressed to the work inbox. The subject line led with a political rumor. The body mixed entertainment questions, relationship advice, medical anecdotes, a crime blurb, and other off-desk topics. None of that is Tygart Media’s beat. None of it is restoration operations. None of it is a first-party number we can stand behind.

    So the digest is not the article. The digest is the proof that an automation without a source-fit step will try to hang the wrong page. The human-readable rule is the same one already on this site: draft-only is the first verb, and publish stays a seat a human can refuse. The machine may open the envelope. It may not inherit the subject line as the H1.

    The six checks before anyone writes

    Run these in order. Stop at the first fail. Do not “find an angle” to rescue a bad source.

    • Domain fit. Would this page still make sense if the logo, the About page, and the $97 restoration kit sat next to it? If not, fail.
    • First-party or primary source. Can you name a dated public document, a product note, a field observation, or a number you measured? A digest snippet is not a source. Fail.
    • Identity lock. No client names, no secrets, no mail IDs, no thread IDs, no app passwords. The Quality Gate exists because a client name once leaked into live posts. That failure mode is still live.
    • Number lock. No invented click-through rates, ranking jumps, or “X% more citations.” If a figure is not on the page you can point to, leave it out.
    • Duplicate lock. Search the live site before you mint a slug. If the argument already exists, update that page or stop.
    • Place lock (GEO). If the piece claims a geography, name a real one the operator actually works — Tacoma, Puget Sound, Everett, Snohomish County — and do not stuff NAP into a thought-leadership body.

    Only after those six pass do AEO, SEO, and GEO get to work. Optimization is not a pardon for a bad source.

    How AEO, SEO, and GEO attach after the gate

    AEO — write the answer first

    Answer engines quote short, stable sentences. Lead with the claim a model can lift without inventing the rest of the page. Then explain. Then put the same claim in an FAQ block using the questions people actually type: what is a source-fit gate, should every email become a post, who owns Publish.

    SEO — one slug, one job

    Pick a slug that names the method, not the digest subject. Title tag under 60 characters. Meta description that restates the answer. Canonical on the live URL. Rank Math on this stack writes the title and robots fields; it does not invent the argument. Internal links go to pages that already carry the doctrine — the $5 filter, the draft-only desk, the afternoon where five drafts still needed a human tap.

    GEO — teach the place, don’t spray it

    Generative engines build a local picture from repeated, consistent facts. Tygart Media is a Tacoma agency. Restoration work in this network is often packed around Everett and Snohomish County. Say that when place is part of the method. Do not turn a content-ops essay into a fake service-area page. GEO is entity clarity, not a city list glued to the footer of every paragraph.

    What to publish when the source fails

    Three honest exits, in order of preference:

    1. Write the gate. If the failure mode is the news — an inbox automation almost reprinted a digest — the operator article is the checklist. That is this page.
    2. Hang nothing. An empty-delta night is a successful night. Silence is cheaper than a correction.
    3. Keep a receipt. Log the fail in the Command Center so the next run does not “try the digest again.” The receipt is not the public URL.

    What you do not do is launder the digest into a “roundup,” a “what people are asking,” or a thin news recap with a restoration sentence taped on the end. That is how a site teaches answer engines the wrong entity.

    What this desk will not do with a digest

    • Reprint political rumor, crime blurbs, or medical anecdotes as Tygart Media reporting.
    • Quote tracking URLs, message IDs, or unsubscribe tokens from the envelope.
    • Invent a percentage that makes the pipeline look smarter than it is.
    • IndexNow a thin title-price door, or ping Bing before the body exists.
    • Hand Publish to the same process that opened Gmail.

    The machine can fetch the letter. The machine can draft. The machine can stage images and fill Rank Math fields. The tap is still human.

    FAQ

    What is a source-fit gate in content operations?

    It is the pre-outline check that asks whether an incoming source belongs on this domain. Domain fit, primary source, identity lock, number lock, duplicate lock, and place lock. Fail any one and you do not draft the obvious article from the subject line.

    Should every incoming email become a WordPress post?

    No. Mailbox events are triggers. Product notes, first-party incident numbers, and field observations can become posts. Digests and rumor chains should not.

    How do AEO, SEO, and GEO fit after the gate?

    AEO wants an answer-first opening and an FAQ a model can quote. SEO wants one slug, a clean title and meta, and internal links to the doctrine pages. GEO wants consistent place facts — Tacoma for the agency, Everett and Snohomish County when the method is local restoration — without turning every essay into a service-area page.

    Where does Tygart Media apply this?

    On tygartmedia.com first. The same gate belongs on any site in the network before an inbox automation is allowed to mint a URL. The Command Center keeps the receipt. The public page keeps the method.

    If you want the restoration operating system this desk actually sells, the front door is the Complete Restoration Operations Kit. The method on that page is copyable. The checkout is on the page. The mailbox is still not the editor.

  • Harness-First, Contractor Edition

    Harness-First, Contractor Edition

    “Own the harness. Rent the models.”

    In an AI lab, that’s architecture advice. In a restoration company’s office, it’s a survival rule. Here’s the contractor’s edition.

    The trap

    Most contractors buying AI right now are buying someone else’s harness. The tool owns the workflow, the prompts, the data flow, the follow-up timing — you rent the whole thing, top to bottom. It feels like buying software. It’s actually sharecropping.

    When the tool changes its pricing, kills a feature, or shuts down, your process dies with it. You didn’t buy a capability. You rented one, and the landlord just sold the building.

    What the harness is

    The harness is the workflow you own: how a lead gets answered, how a job gets documented, how a review gets asked for, how an estimate gets followed up. The prompts, the routing rules, the checks, the escalation to a human, the integrations between systems.

    The model is the engine. The harness is the truck. Engines get swapped; the truck is yours.

    Concretely: the harness is a document — written in your words — that says “when X happens, we do Y, then Z, and a human checks W.” Any model can execute it. No model owns it.

    What you rent

    The model. GPT, Claude, Grok, whatever’s best this quarter — swappable commodities. Today’s best model is next year’s legacy; that’s not cynicism, it’s the release cadence.

    If your process depends on a specific model’s quirks — the exact phrasing it likes, the feature only it has — you built on sand. The harness-first contractor can swap the engine on a Tuesday and the office doesn’t notice. The tool-renter files a support ticket and waits.

    A car engine mounted on a stand in a garage, ready to be swapped

    Three harnesses you already need

    The inbound line. The harness: the greeting, the questions it asks, the dispatch rules, the recording disclosure, what happens when it doesn’t know. The voice model underneath? Rented. Swap it when something better ships.

    The estimate follow-up. The harness: the timing (day 2, day 7, day 14), the message sequence, when it escalates to a human call. Any model can write the texts. The sequence is the asset.

    The review ask. The harness: the trigger (job closed, equipment out), the direct link, the prompt for specifics — what happened, where, how fast. The model writes the words; the workflow is yours.

    Notice the pattern: in every case, the durable part is the decisions — the timing, the triggers, the judgment calls. The model supplies sentences. Sentences are cheap.

    How to start

    Pick one workflow. Write down how it should go — the steps, the timing, the human checkpoints. That’s the harness, and it lives in your docs, not in a vendor’s dashboard.

    Then plug a model into it. Any model. When a better one ships, you re-plug. The doc doesn’t change.

    One workflow, owned end to end, beats five rented tools every time. Start with the one that touches money — the lead, the estimate, the invoice.

    An engineering blueprint spread on a wooden desk with a pencil and calipers

    The moat

    Two contractors can rent the same model. They can’t rent your harness — it’s your operations, your judgment, encoded. Your dispatch rules came from your jobs. Your follow-up timing came from your close rates. Your escalation instincts came from your mistakes.

    That’s the durable asset. Models are electricity. Nobody’s moat is “we use electricity.” The moat is what you built with it — and you own the building, not the power company.

    The close

    The AI industry wants you renting the whole stack — their workflow, their prompts, their model, their price increases. Harness-first says no: I’ll rent the intelligence by the hour, but the operation is mine.

    Own the harness. Rent the models. Be the one building still standing when the vendors reshuffle.