Author: Will Tygart

  • AI Citation Profiles: Optimize for Claude and Perplexity

    AI Citation Profiles: Optimize for Claude and Perplexity

    Last refreshed: May 15, 2026

    The phrase “optimize for AI search” is almost always wrong. There is no single AI search behavior. Claude, ChatGPT, and Perplexity each have distinct citation patterns — different content structures they reward, different page types they concentrate on, different signals they weight. Writing one undifferentiated article and hoping it gets cited across all three is the same mistake as writing one undifferentiated web page and hoping it ranks for every keyword. This cluster article covers the per-model citation playbook, built from GA4 data and the multi-model roundtable methodology in the Tygart Media Knowledge Lab.

    This is the final cluster in the Claude on a Budget series. For the token economics that make targeted content cheaper to produce, see Output Compression Discipline and Prompt Caching.

    The Three Citation Profiles
    Comparison of Claude how-to fit versus local service page fit for assistants
    Three citation profiles to optimize for.

    Claude (Anthropic): Concentrates heavily. GA4 data from sites in the Knowledge Lab shows Claude sending approximately 54.5% of its AI referral traffic to just 2 pages per site. It rewards content that is entity-dense, structurally authoritative, and written with speakable precision — defined terms, explicit relationships between concepts, factual density over narrative padding. Claude users tend to be technical and high-intent; the model reflects that by citing content that answers with precision rather than coverage. Approximately 90% of content on a typical site is invisible to Claude — it surfaces a small authoritative set and ignores the rest.

    ChatGPT (OpenAI): Spreads references broadly. Where Claude concentrates on 2 pages, ChatGPT may reference 8-12 across the same site. It rewards breadth, recency, and natural-language accessibility. Content structured like a knowledgeable friend explaining something clearly — without jargon walls — performs well. ChatGPT users skew toward general-purpose questions; the model cites content that covers the question conversationally without assuming deep domain expertise.

    Perplexity: Research-flavored. It rewards sourced claims, comparative tables, explicit statistics, and content that reads like a researched brief rather than an opinion piece or narrative. Perplexity users are actively in research mode; the model surfaces content that looks like it did the research so the user does not have to. Citation-rich, data-dense, table-formatted content punches above its traffic weight in Perplexity referrals.

    The Per-Model Content Shape

    ElementClaudeChatGPTPerplexity
    Density targetHigh — entity-rich, preciseMedium — accessible, broadHigh — sourced, comparative
    Best structureDefined terms, explicit relationships, OASFConversational headers, FAQ blocksTables, stat callouts, comparison matrices
    Ideal length1,500-2,500 words with tight structure800-1,500 words, readable flow1,000-2,000 words with data anchors
    Citation triggerAuthoritative entity coverageQuery-matching accessible answerSourced comparative data

    The Multi-Model Roundtable Methodology
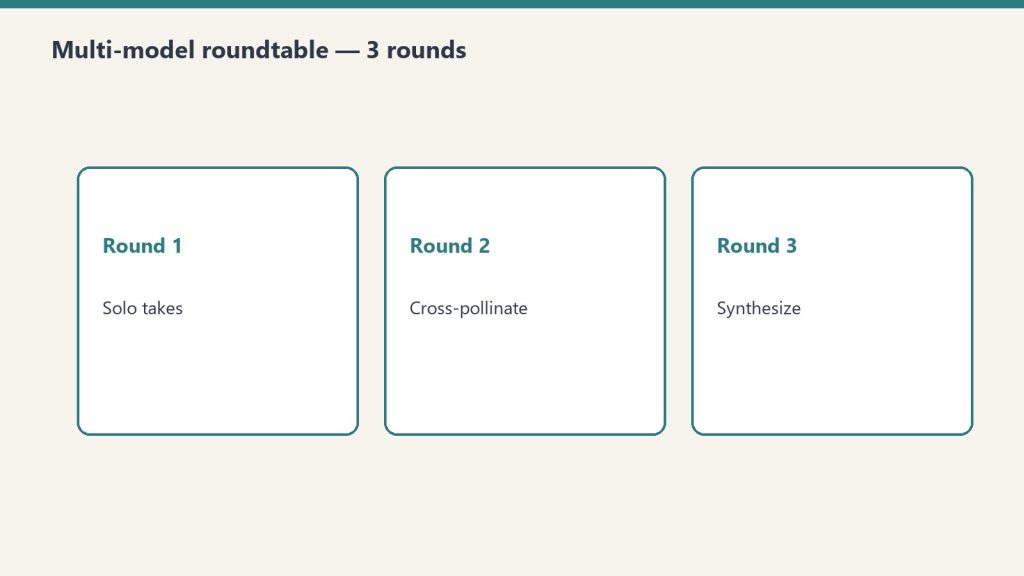
    Three cards for solo takes, cross-pollination, and synthesis
    Multi-model roundtable methodology.

    The Tygart Media Knowledge Lab documents a specific workflow for content research that leverages multiple models’ citation profiles rather than fighting them. The pattern: route the initial research brief to a free or cheap model (Gemini Flash via OpenRouter, or Llama 3 free tier) for broad source gathering. Pass the source list to Claude for entity extraction and authoritative synthesis. Use the Claude-synthesized brief as the foundation for the final article draft. The output is content that is naturally entity-dense from Claude’s synthesis pass while covering enough ground to catch ChatGPT’s broader citation net.

    The token economics matter here: the expensive synthesis pass (Claude Sonnet 4.6 or Haiku) operates on a pre-filtered source set, not raw web content. Input tokens are lower because a cheaper model did the broad sweep. Claude’s output is higher-density because it is synthesizing structured inputs rather than processing noise. This is the OpenRouter multi-model pipeline in content production form.

    Writing for Claude Citation Specifically
    Four cards for content, ops, build, and knowledge work with Claude
    Writing for Claude citation specifically.

    If your primary goal is Claude citation — high-intent technical traffic, B2B contexts, developer audiences — the content discipline is: define every entity explicitly at first mention, state relationships between concepts directly (“X enables Y because Z”), use speakable sentence structures (subject-verb-object, no buried clauses), include a structured FAQ or definition block, and remove padding. Claude’s citation concentration on 2 pages per site means your best-performing page for Claude referrals will get the bulk of the traffic — invest in making that page entity-complete rather than spreading thin coverage across many pages.

    Writing for Perplexity Citation

    Perplexity citation optimization is the most actionable of the three because the signal is explicit: include comparative tables with real numbers, cite sources inline (even if just attributing claims to specific organizations or studies), use headers that read like research questions, and lead sections with data points rather than narrative. The content in this series — pricing tables, API code examples, usage statistics — is structured for Perplexity citation by design. Every table is a potential Perplexity extraction point.

    The Budget Connection

    Per-model content shaping is a budget strategy, not just a citation strategy. Writing one highly targeted, entity-dense 2,000-word article for Claude citation is cheaper to produce — fewer tokens, tighter output discipline — and more effective than producing three generic 1,500-word articles hoping one gets cited. Concentration over coverage: the same principle Claude uses to cite content, applied to content production itself. The output compression discipline from Cluster 6 makes this article type cheaper to generate. Dense, targeted content is both cheaper to produce with Claude and more likely to be cited by Claude. The budget and the citation strategy converge.

    The Full Claude on a Budget System

    This series has covered seven levers that compound: cold-start elimination via second brain, model routing by task tier, OpenRouter free model integration, Batch API for async 50% discount, prompt caching for 90% off repeated context, output compression discipline, and per-model citation shaping. None of these require negotiating with Anthropic’s pricing team. All of them are available today via the API. Applied together, they represent the difference between paying retail for Claude and operating it at professional efficiency — which, for most teams, means the same Claude capability at 40-70% of the sticker cost.

    Return to the full guide: Claude on a Budget: Complete Guide →
  • Claude Output Compression: Token Savings & Structured JSON

    Claude Output Compression: Token Savings & Structured JSON

    Last refreshed: May 15, 2026

    Most Claude cost analyses focus on input tokens — the knowledge you send in. The underappreciated lever is output compression. Claude is trained to be thorough. Left unconstrained, it produces full meals: preambles, recaps, hedges, transition sentences, closing summaries. All of those tokens cost money. All of them are often unnecessary. Output discipline — getting Claude to deliver concentrated slices instead of full meals — is often the highest-leverage cost reduction available without changing models or switching to async.

    This is part of the Claude on a Budget series. For input-side compression, see The Cold-Start Problem. For pricing mechanics, see Prompt Caching.

    The Default Verbosity Problem

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    The default verbosity problem.

    Ask Claude to “summarize this document” without constraints and you will get: an opening sentence restating the task, a multi-paragraph summary, a bullet-point recap of the summary, and a closing note about what was not covered. The actual information density — insight per token — is low. You paid for 800 tokens of output and needed 150. Multiply across thousands of API calls and you have built a significant cost leak from default model behavior, not from bad prompts.

    The Output Compression Toolkit

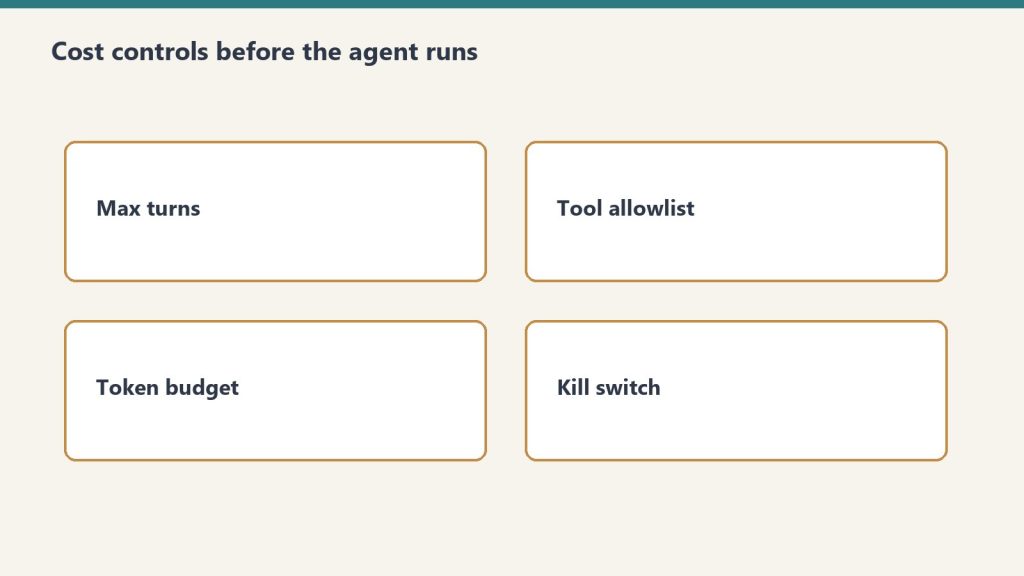
    Cost control gates for production routing
    The output compression toolkit.

    1. Explicit word and token caps in the prompt. “Respond in 150 words or fewer” is the single most effective instruction for reducing output tokens. Claude respects tight limits. “Be concise” does not work reliably. “150 words maximum” does. For JSON outputs: “Respond with only valid JSON, no markdown fences, no explanation.” Every word of instruction about format is recovered 10x in output reduction across repeated calls.

    2. Structured output schemas. When you need structured data, define the exact JSON schema. Claude stops generating prose and fills fields. You get exactly what you specified and nothing more. The token reduction versus free-form responses is typically 40-70% for equivalent information content.

    # Free-form -- verbose, unpredictable length
    prompt_verbose = "Summarize the key points of this article and their implications."
    
    # Structured -- tight, predictable, cheaper
    prompt_structured = """Extract from this article:
    {"headline": "string", "key_points": ["string", "string", "string"], "sentiment": "positive|neutral|negative"}
    Respond with valid JSON only. No explanation."""

    3. Role-based compression priming. System prompt framing shapes output length. “You are a precise technical writer who values brevity. Never restate the task. Deliver the answer directly.” produces consistently shorter outputs than a neutral system prompt. This is prompt engineering for token economics, not just quality.

    4. Chained micro-tasks over monolithic requests. Instead of asking Claude to research, analyze, synthesize, and format in one prompt, chain smaller requests. Each call is scoped to one task with tight output constraints. Total tokens across the chain are often lower than a single unconstrained request, and intermediate outputs are cacheable — pairing naturally with the prompt caching strategy.

    The Notion Second Brain Application

    The operational implementation at Tygart Media runs this pattern at pipeline level. The Notion second brain eliminates the need for Claude to generate background context — it already exists in structured form. Extractions from Notion arrive as pre-formatted knowledge blocks. Claude’s task is synthesis over existing structured data, not open-ended research and explanation. Output prompts are scoped: “Given this structured data, write a 400-word section for [topic]. No preamble, no conclusion, begin directly with the first point.” The output is a concentrated slice — dense, usable, billable at a fraction of what free-form generation costs for equivalent value.

    Measuring Compression Effectiveness

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Measuring compression effectiveness.

    Track output_tokens in your API responses. Log them per prompt template. Identify your highest-output templates and run compression interventions — tighter word caps, structured formats, role priming. The target is information density: insight delivered per output token, not raw token count. A 500-token output with 3 actionable insights beats a 200-token output with 1. Compression discipline is about removing the scaffolding (preambles, hedges, recaps) while preserving the load-bearing structure (insight, data, instruction).

    max_tokens as a Hard Ceiling

    Set max_tokens conservatively in your API calls. This is your financial guardrail, not just a model parameter. For classification tasks: 50 tokens. For short summaries: 200 tokens. For structured JSON extraction: 500 tokens. For article drafts: 1,500-2,000 tokens. Leaving max_tokens at the model default (4,096-8,192) on every call is leaving a cost ceiling unjustifiably high. Claude will rarely hit the ceiling on constrained tasks, but it prevents runaway generation on edge-case inputs that can quietly inflate your bill.

    Next: Per-Model Content Shaping: Write Less, Get Cited More →

  • Anthropic Prompt Caching: Cut Claude API Costs by 90%

    Anthropic Prompt Caching: Cut Claude API Costs by 90%

    Last refreshed: May 15, 2026

    If you’re sending the same large block of context — a knowledge base, a style guide, a long system prompt, a reference document — with every Claude request, you’re paying full input token rate on every single call. Anthropic’s prompt caching collapses that to roughly 10% of the standard input rate for cache hits. For context blocks of 1,000+ tokens sent repeatedly, this is one of the most reliable cost levers available.

    This is part of the Claude on a Budget series. For async workloads, see The Batch API: 50% Off for Non-Urgent Work. For token reduction before the API call, see The Cold-Start Problem: Second Brain and CLAUDE.md.

    How the Cache Works

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    How the prompt cache works.

    Prompt caching is prefix-based. Anthropic caches the exact token sequence up to your cache_control breakpoint. Any subsequent request that begins with that identical prefix hits the cache and pays cache read rate (~$0.30/M for Sonnet vs. $3.00/M standard — a 90% reduction). The cache is maintained for approximately 5 minutes of inactivity, with extended TTL options for longer-lived contexts. Token minimums apply: 1,024 tokens for Haiku, 2,048 for Sonnet and Opus.

    The Pricing Reality

    ModelStandard InputCache WriteCache ReadRead Savings
    Haiku 4.5$1.00/M$1.25/M$0.10/M90%
    Sonnet 4.6$3.00/M$3.75/M$0.30/M90%
    Opus 4.7$5.00/M$6.25/M$0.50/M90%

    Cache writes cost slightly more than standard input (25% premium). The break-even is the second hit. Every cache read after that is 90% cheaper. For any context block read more than once, caching wins.

    The Implementation

    import anthropic
    
    client = anthropic.Anthropic()
    
    # Large system prompt or knowledge base -- mark for caching
    SYSTEM_CONTEXT = "Your 5,000-token knowledge base or style guide here..."
    
    response = client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=1024,
        system=[
            {
                "type": "text",
                "text": SYSTEM_CONTEXT,
                "cache_control": {"type": "ephemeral"}
            }
        ],
        messages=[
            {"role": "user", "content": "Your specific question or task here"}
        ]
    )
    
    # Check cache performance in usage stats
    usage = response.usage
    print(f"Input tokens: {usage.input_tokens}")
    print(f"Cache creation tokens: {usage.cache_creation_input_tokens}")
    print(f"Cache read tokens: {usage.cache_read_input_tokens}")

    On the first call, you will see cache_creation_input_tokens populated — that is the write. On subsequent calls with the same prefix, cache_read_input_tokens shows what was served from cache at 10% cost.

    What to Cache

    Cost control gates for production routing
    What to cache — and what not to.

    Anything large, stable, and repeated qualifies. The highest-value candidates: long system prompts defining agent behavior or personas; reference documents such as product specs, legal terms, or knowledge bases; few-shot example sets (10+ examples add up fast); conversation history in multi-turn applications where you mark the stable history prefix for caching and leave only the new turn uncached. In agentic pipelines where Claude processes a document repeatedly across multiple analysis passes, cache the document body and vary only the instruction. You pay full rate once per document, cache rate on every subsequent pass.

    The CLAUDE.md and Second Brain Connection

    The cold-start reduction strategy covered in Cluster 1 works because you are reducing what gets sent, not how it gets priced. Prompt caching is the complement: for context that must be sent, cache it. Together, the disciplines compound — your CLAUDE.md file keeps context lean; prompt caching ensures whatever you do send repeatedly costs 90% less after the first hit.

    Cache Design Principles

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Cache design principles that hold up.

    Place stable content at the front of your prompt. Place dynamic content at the end. The cache key is prefix-matched, so any change to content before the cache_control marker invalidates the cache. If your system prompt has a dynamic date or session ID embedded at the top, you are guaranteeing cache misses on every call. The correct structure: static knowledge base, then cache marker, then dynamic task-specific instruction. Never the reverse.

    You can set up to 4 cache breakpoints in a single request for granular control. Most production implementations need only one or two — the system prompt cache and optionally a conversation history cache in long multi-turn sessions.

    Operational Impact

    Teams running Claude with consistent system prompts across many requests report effective input costs dropping to near-cache-read rates after the first request. For a content pipeline running 1,000 daily requests with a 5,000-token system prompt: uncached cost is $15/day on input alone at Sonnet rates ($3/M). Cached cost after the first request: $1.50/day. That is $13.50/day saved on system prompt tokens alone — $4,900/year from one implementation change that takes an afternoon to ship.

    Next: Output Compression Discipline: Concentrated Slices vs Full Meals →