Tag: AI Tools

  • Structuring 52 AI Content Beats for Automated Coverage

    Structuring 52 AI Content Beats for Automated Coverage

    The Machine Room · Under the Hood

    The Newsroom Blueprint That Still Works

    Walk into any traditional newspaper office—or what remains of them—and you’ll find the same organizational pattern that’s existed for over a century. Reporters aren’t assigned randomly to stories. Instead, they’re organized into beats. Crime reporters work the police beat. Political correspondents cover city government. Sports writers chase games and seasons. This structure has endured because it works: beats create accountability, build expertise, and ensure consistent coverage across a publication’s mission.

    That same principle works brilliantly for AI-powered content systems. In fact, the beat structure may be more valuable in an automated environment than it ever was in traditional newsrooms. When you’re generating dozens of pieces of content weekly without human bylines, beats become your primary safeguard against redundancy, inconsistency, and missed coverage angles.

    We took the time-tested newspaper desk and beat hierarchy and rebuilt it as the foundational architecture for a scalable, AI-driven content system. Here’s how.

    Understanding the Desk and Beat Hierarchy

    The hierarchy works in two layers:

    Layer One: The Desk

    Eight desks form the top-level organization, each representing a major content vertical or audience interest. These aren’t rigid silos—they represent distinct reader needs and beat categories that work best when managed as coherent units. A typical structure includes desks for community and neighborhood coverage, urban transportation systems, food and dining, housing and real estate, cultural institutions and entertainment, outdoor recreation and environmental topics, practical consumer advice, and discovery-driven feature journalism.

    Each desk functions as a mini-publication within your broader publication. It has its own coverage philosophy, audience expectations, and update frequency. A transportation desk needs to publish more frequently than a culture desk. A housing desk requires different expertise than an outdoor recreation desk.

    Layer Two: The Beat

    Within each desk sit 5-8 individual beats. These are your coverage specialists. While a desk represents a broad interest area, a beat represents a specific focus within that area.

    For example, a transportation desk might rotate through beats like commuter updates (daily traffic conditions, public transit service changes), infrastructure projects (construction timelines, transit expansions), accessibility and equity issues (transportation barriers for underserved communities), emerging mobility solutions (e-scooters, bike-sharing programs), and seasonal coverage (weather impacts, holiday travel patterns).

    Eight desks with an average of 6.5 beats each yields 52 total beats. That’s 52 distinct content angles your system can cover with consistent, rotating attention.

    How Beat Rotation Prevents Repetition

    The critical innovation here is rotation. Your system doesn’t publish one transit article and then move on. Instead, it cycles through each beat on a structured schedule.

    Consider a transit desk publishing three articles per week. Monday’s piece covers commuter updates—rush hour patterns, service disruptions, seasonal ridership trends. Wednesday pivots to infrastructure: project timelines, funding decisions, new transit lines under development. Friday explores something different: accessibility barriers, or equity issues in transit planning, or how new mobility solutions are changing commute patterns.

    The same desk, publishing with consistency, but never repeating the same angle twice in the same week. The week after, the rotation continues. Different commuter story, different infrastructure angle, different sidebar topic. This rotation is what transforms beat journalism from anecdotal coverage into structural completeness. You’re not just writing about topics when they trend or when news breaks. You’re systematically covering every facet of every category your publication owns.

    And critically, your AI system remembers what it published. It knows Monday covered commuter patterns, so Tuesday’s commuter-adjacent story takes a different angle. It knows last week’s infrastructure piece focused on transit expansion, so this week it explores maintenance or equity issues instead. The system maintains institutional memory without human editors.

    Building Your WordPress Taxonomy

    This structure translates directly into your content management system. Every beat becomes a WordPress category. Every desk becomes a category parent.

    Your taxonomy tree looks like this: Eight parent categories (desks), each containing 5-8 child categories (beats). This isn’t just organizational bookkeeping—it’s your site architecture. Readers browsing your site can navigate by desk or by beat. Someone interested in transportation can click the transportation desk and see everything from commuter updates to infrastructure news to emerging mobility. Someone with a specific interest can drill directly into the commuter-updates beat and see weeks of consistent coverage.

    This taxonomy becomes increasingly valuable over time. After six months of beat-structured publication, your commuter-updates beat contains 50+ pieces of content, all directly relevant to readers searching for “commute patterns” or “traffic trends.” That’s organic search value. That’s reader loyalty. That’s a publication that feels both deep and broad.

    The WordPress category structure also creates natural landing pages. Your beat pages don’t need custom design—they’re automatically generated archive pages displaying all content tagged to that beat, sorted chronologically or by engagement. Minimal maintenance, maximum discovery.

    Depth and Breadth Through Structure

    Most content systems force you to choose: either you go deep on a few topics, becoming an expert resource that appeals to a narrow audience, or you go broad, covering everything but mastering nothing.

    Beat structure eliminates this tradeoff. You achieve depth through breadth. Because you’re publishing on a rotating schedule, each beat receives regular attention. The commuter-updates beat doesn’t get one article and then silence for three months. It gets three pieces per week, every week. Over a year, that’s 150+ pieces of commuter journalism. That’s depth. That’s expertise. That’s Google noticing your site as an authority on a specific topic.

    Simultaneously, your eight desks ensure you’re covering everything your audience cares about. You’re not trapped in a single vertical. You’re the publication that understands transportation, but also food, but also housing, but also culture. Readers return because you serve multiple needs.

    For AI content systems, this structure is essential. Without it, an autonomous system tends toward repetition—the same angles, the same questions, the same coverage gaps week after week. With beat structure, the system has scaffolding. It knows what it should have covered yesterday. It knows what angle it should try today. It knows what topic is due for revisiting next week. Structure doesn’t constrain creativity; it enables it.

    Scaling: Adding Desks and Beats

    One of the most elegant aspects of this system is how it scales. Want to expand coverage? Add a new desk and suddenly you’ve added 5-8 new content beats instantly. No redesign required. No complex infrastructure changes. You’re simply extending a proven template.

    Adding a new beat to an existing desk is even simpler. Your publishing calendar automatically adjusts. Your WordPress taxonomy expands. Your AI system receives new guidance on what to cover. The system absorbs the change with minimal friction.

    This is why the beat structure matters more than the specific beats themselves. Different publications will have different desks and different beats. What matters is that you have a systematic, hierarchical way of organizing coverage that prevents gaps and ensures rotation.

    Building Consistency in Automated Systems

    When humans write, editors enforce consistency through editorial meetings and style guides. When AI generates content, beat structure becomes your editorial consistency tool. The system knows it’s publishing to the commuter-updates beat, so it maintains a consistent voice and focus for that beat. It knows commuter-updates is distinct from infrastructure-projects, so it doesn’t blur the two. It knows the rotation schedule, so it doesn’t repeat angles unnecessarily.

    Beat structure creates the possibility of training AI systems beat-by-beat. You can optimize the commuter-updates beat for a certain style and depth. You can train the culture-beat differently. You can establish beat-specific quality standards. This level of granular control wouldn’t be possible without clear structural boundaries.

    The beat structure also makes performance measurement tractable. Which beats perform best with your audience? Which beats drive engagement? Which beats need refinement? With clear categorization, you can analyze each beat’s performance independently and optimize from there.

    From Structure to Sustainable Journalism

    Ultimately, beat structure solves a critical problem with AI-generated content: lack of direction. Without structure, automated systems produce content that’s technically competent but strategically aimless. With beat structure, automated systems produce content that’s both excellent and purposeful.

    The newsroom developed beats a century ago because they solved real editorial problems. Beats prevented coverage gaps. Beats built expertise. Beats created accountability. Those same problems exist in AI-driven content systems, and beats solve them just as effectively.

    The 52-beat structure—eight desks, 5-8 beats per desk, rotating publication schedules—isn’t arbitrary. It’s proven newsroom architecture, adapted for modern publishing realities. It’s how you build a content system that’s simultaneously comprehensive and consistent, broad and deep, automated yet purposeful.

    Getting Started With Beat Architecture

    Whether you’re building a publication from scratch or restructuring an existing one, beat architecture is foundational. Start by identifying your desks—the major content verticals your audience cares about. Then identify 5-8 beats within each desk. Map those beats to WordPress categories. Design a publication schedule that rotates through your beats consistently.

    The structure will pay dividends immediately: clearer direction for content production, more obvious coverage gaps, better organization for readers. Over time, it becomes the backbone of everything you publish.

    If you’re considering AI-driven content systems, beat architecture isn’t optional—it’s foundational. The structure gives AI something to optimize toward, prevents repetition, and ensures your automated coverage feels purposeful rather than random.

    Ready to architect your own publication’s beat system? Content structure determines everything downstream—from editorial consistency to reader experience to search visibility. Whether you’re restructuring an existing publication or building a new one, the right architecture pays dividends for years. Tygart Media specializes in designing sustainable content architectures that work at scale. Let’s talk about your publication’s structure.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Beat Journalism Meets AI: Structuring 52 Content Beats for Automated Coverage”,
    “description”: “Walk into any traditional newspaper office—or what remains of them—and you’ll find the same organizational pattern that’s existed for over a century”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/beat-journalism-ai-structuring-content-beats/”
    }
    }

    Visual summary
    Editorial illustration for Beat Journalism Meets AI: Structuring 52 Content Beats for Automated Coverage - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for Beat Journalism Meets AI: Structuring 52 Content Beats for Automated Coverage. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • Automated Newsroom: How Scheduled AI Tasks Write Articles

    Automated Newsroom: How Scheduled AI Tasks Write Articles

    The Machine Room · Under the Hood

    The Overnight Newsroom: How Scheduled AI Tasks Write 15+ Articles While You Sleep

    It’s 8 AM. You pour your first coffee of the day, open your newsroom dashboard, and 15 fresh articles are waiting—all fact-checked, locally relevant, and ready to publish. The byline on three of them says “Published by System,” but the reporting is solid. The editorial flags on two articles suggest minor revisions. Everything else sailed through quality gates overnight.

    This isn’t science fiction. It’s the architecture that modern publishers are deploying right now, and it’s transforming what’s possible with lean editorial teams.

    The overnight newsroom works because it separates the two slowest parts of publishing: writing on demand and human review. Instead of a human waiting for an AI to finish, you schedule AI tasks to work during off-hours. Instead of AI publishing without oversight, everything gets routed through quality gates before it ever reaches your CMS. The result is a newsroom that publishes continuously, but never without scrutiny.

    How Scheduled Tasks Replace a Night Shift

    A traditional newsroom with night-time coverage needs bodies: a night editor, two or three reporters, a copy editor. You’re paying for eight hours of labor whether you have breaking news or not. With scheduled AI tasks, you’re deploying computational resources that cost fractions of a penny per article, and you only pay for what runs.

    The core concept is simple: cron-like scheduling paired with beat-specific AI agents. Each task knows exactly what it’s responsible for—city council coverage, local business news, high school sports, weather briefings, community events. Each task runs on a predictable schedule. Each task outputs articles in a standardized format. Each article then flows through a quality pipeline before any human ever sees the headline.

    Think of it as assigning eight reporters to eight different desks, then automating their shift start times and enforcing editorial standards at the point of publication.

    The Overnight Schedule: Staggered Coverage Across Eight Desks

    Here’s what a real overnight schedule looks like, staggered every 30 minutes so your publishing pipeline stays balanced and your content management system isn’t hammered all at once:

    • 10:00 PM – Government & Policy Desk: Task pulls latest municipal records, council agendas, and public statements from official sources. Generates 2-3 articles on regulatory changes and permits.
    • 10:30 PM – Business & Commerce Desk: Task scrapes business filings, quarterly earnings alerts, and local business announcements. Outputs 2-3 business briefs.
    • 11:00 PM – Community Events Desk: Task aggregates calendar data, nonprofit announcements, and cultural event listings. Generates 1-2 event roundups.
    • 11:30 PM – Weather & Environment Desk: Task pulls meteorological data, air quality reports, and environmental alerts. Outputs the daily weather forecast and any environmental warnings.
    • 12:30 AM – Sports Desk: Task waits for late-night game results, aggregates score data, and generates game recaps. Outputs 2-3 sports articles.
    • 1:00 AM – Education Desk: Task pulls school calendar updates, test score releases, and education policy news. Generates 1-2 education briefs.
    • 1:30 AM – Real Estate & Development Desk: Task scrapes property records and development permit data. Outputs real estate market reports.
    • 2:00 AM – Arts & Culture Desk: Task aggregates arts organization announcements, gallery openings, and cultural programming. Generates 1-2 culture briefs.

    By 3 AM, your system has generated 15+ articles. By 6 AM, every single one has been evaluated for accuracy, source credibility, and editorial quality. Your morning team walks in to a pre-filtered list of what’s publishing automatically and what needs review.

    Beat Structure: The Engine of Repetitive Excellence

    The key to overnight automation is that no beat publishes the same story twice. Each desk doesn’t have one task; it has five to eight beat-specific tasks that rotate.

    Take the Government & Policy desk. Instead of one task that writes “city council news,” you have separate tasks for:

    • Planning & Zoning decisions
    • Budget & Finance announcements
    • Public Safety & Law Enforcement updates
    • Transportation & Infrastructure changes
    • Permits & Development approvals

    Each task is scheduled to run once per week or twice per week, depending on volume. Each task knows what data sources to check. Each task has its own prompt that explains how to structure the article, what to prioritize, and what constitutes publishable news versus noise. The system cycles through beats instead of churning out the same category of story every night.

    This rotation solves the repetition problem that kills automated coverage. Your readers don’t see “City Council Update” for the twelfth time in a month. They see specific, beat-focused reporting that actually covers different angles of municipal government.

    The Quality Gate: Where Automation Meets Editorial Standards

    Here’s where overnight automation becomes defensible journalism: every article passes through a series of automated quality checks before it’s considered publishable.

    These gates catch the kinds of errors that make AI-generated content dangerous:

    Hallucinated Locations – The system cross-references every place name mentioned in the article against authoritative geographic databases. If the article claims a decision was made by the “Downtown Municipal Building” and no such building exists in the sourced data, the article fails this check.

    Fabricated Statistics – Numbers are matched back to their original sources. If an article claims “unemployment rose to 4.2%,” the system verifies that 4.2% actually appears in the cited government report. If the report says 4.1%, the article fails.

    Unsourced Claims – Every factual statement gets tagged with a source. If a claim doesn’t have a verifiable source in the data the task ingested, it’s flagged. Opinions and context can be added, but they’re clearly marked as not sourced.

    Cross-Site Contamination – The system checks whether the article is parroting information from competitors without attribution. If similar phrasing appears elsewhere, the system flags it so humans can verify originality.

    Consistency Checks – Multiple articles generated about the same event are cross-checked for contradictions. If the Government desk and the Business desk both write about a permit approval but disagree on the date, both articles are flagged.

    Articles that pass all gates are marked “ready to publish.” Articles that fail one or more gates are marked “editorial review required” and routed to your morning team. Articles that fail catastrophically—multiple hallucinations, contradictions, or missing sources—never make it to the queue at all.

    The Kill Switch: When Automation Steps Back

    The most important feature of a responsible automated newsroom is the kill switch: the decision to not publish when the quality bar isn’t met.

    If an article fails more than two quality gates, it doesn’t get published under a “System” byline. Instead, it gets logged as a candidate article and sent to your editorial team with a note: “This is what the system tried to write. Does this deserve human reporting?” Sometimes the answer is yes—the topic is important even if the first-draft automation was flawed. Sometimes the answer is no—the system picked up noise instead of news.

    The kill switch is what separates automated content from automated journalism. It’s the difference between “the system published something wrong” and “the system tried to publish something wrong, but we caught it.”

    The Human-in-the-Loop: Morning Review in Minutes

    At 7 AM, your editorial team logs in to find three categories of content:

    Green light (auto-publish): 12 articles that passed all quality gates. These go live immediately. A human reads them during their coffee break to stay informed, but they’re already published.

    Yellow flag (editorial review): 2 articles that passed most gates but triggered one flag. Your editor spends two minutes reading each one, makes a quick judgment call, and either publishes with a note or routes to a reporter for expansion.

    Red flag (skip): 1 article that failed too many checks. The system generates a brief memo: “This article tried to cover a new permit filing, but location data couldn’t be verified and three statistics weren’t sourced.” Your editor either decides the story is worth a reporter’s time or archives it as a candidate.

    The entire review process takes 15 minutes. Your human team hasn’t written anything yet—they’ve QA’d what the system built. And by 8 AM, your publication has 12-15 pieces of content that’s already live and driving traffic.

    The Productivity Multiplier: From 10 Reporters to 1 Editor

    A traditional local newsroom covering eight beats needs at least one dedicated reporter per beat, plus a night editor. That’s nine people, working five days a week, each producing three to five articles per day. You’re looking at 100+ articles per week, all staffed manually.

    With scheduled AI tasks running overnight, you get 15+ articles every night, seven days a week, for the cost of one morning editor who spends an hour doing QA. That’s roughly the same output as a team of ten reporters, but with better consistency, zero night-shift burnout, and the flexibility to adjust beat focus by changing a task’s prompt instead of hiring new staff.

    This doesn’t mean you lay off your reporters. It means your reporters stop covering commodity news and start doing original investigation, interviews, and analysis. A reporter who used to spend half their day writing municipal recap articles now spends their time breaking news, developing sources, and producing the enterprise work that separates your publication from competitors.

    The overnight newsroom is a force multiplier. It handles the beat coverage that has to happen, so your humans can do the work that only humans can do.

    Building Your Own: The Technical Requirements

    You don’t need a custom platform to run this. You need:

    • A scheduling system – Cron jobs, a task scheduler, or an automation platform that can trigger actions at specific times.
    • API access to your data sources – Government databases, business filing systems, event calendars. Most are public APIs; some require direct connections.
    • An AI engine with prompt control – An LLM API where you can fine-tune prompts per beat and control output format.
    • A quality gate layer – Can be custom Python, a validation rules engine, or a secondary AI model trained to catch errors in the first model’s output.
    • CMS integration – REST API access so articles can be written directly to your publishing system with appropriate status tags.
    • A flagging and review interface – Simple dashboard or email digest showing what passed, what failed, and what needs human eyes.

    The entire stack can be built in two to three weeks by a small engineering team. Ongoing maintenance is a few hours per week as you refine prompts and adjust beat coverage.

    The Morning Advantage

    Here’s what you’ve built: a newsroom that publishes while everyone sleeps. Your competitors wake up to breaking news that you’ve already covered. Your readers open their phones at 6 AM to find content from a publication that works 24/7.

    And because every article is quality-gated, you’re not trading accuracy for speed. You’re trading night-shift labor and tired human judgment for systematic verification and human oversight in the daylight hours when your team is sharpest.

    The overnight newsroom isn’t about removing humans from journalism. It’s about moving them from routine tasks to strategic ones. It’s about publishing coverage that would require a 10-person night team using nothing but scheduled tasks, quality gates, and a single morning editor sipping coffee while the system does the heavy lifting.

    Ready to Automate Your Content Operations?

    The technology to run an overnight newsroom exists today. The only barrier is architectural—understanding how to structure your tasks, what quality gates actually catch errors, and how to keep humans meaningfully involved in the process.

    If your newsroom is still writing routine beat coverage manually, you’re spending labor hours on work that could run itself. The overnight newsroom isn’t the future of publishing. It’s the operating model of publishers who want to compete with speed and scale without sacrificing their editorial standards.

    The question isn’t whether to automate your newsroom. It’s how quickly you can build the architecture to do it responsibly.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “The Overnight Newsroom: How Scheduled AI Tasks Write 15+ Articles While You Sleep”,
    “description”: “It’s 8 AM. You pour your first coffee of the day, open your newsroom dashboard, and 15 fresh articles are waiting—all fact-checked, locally relevant, and “,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/overnight-newsroom-scheduled-ai-tasks/”
    }
    }

    Visual summary

    Editorial illustration for The Overnight Newsroom: How Scheduled AI Tasks Write 15+ Articles While You Sleep - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for The Overnight Newsroom: How Scheduled AI Tasks Write 15+ Articles While You Sleep. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • Scaling Automated Local Media: From One Paper to Three

    Scaling Automated Local Media: From One Paper to Three

    The Machine Room · Under the Hood

    From One Paper to Three: Scaling Automated Local Media Across a Region

    We learned something profound in the first year of operating our automated local newsroom: the hardest work isn’t building the system. It’s building the right system—the one that becomes a platform.

    When we launched our inaugural publication, we spent months architecting beat structures, designing quality gates, and engineering our publishing pipeline. We stress-tested workflows. We refined headline formulas. We built editorial guardrails that would let algorithms operate with the precision of seasoned journalists. The effort was immense, the learning curve steep. But something unexpected happened once we shipped: we had built more than a publication. We had built a reproducible blueprint.

    The second publication took us four months. The third took six weeks.

    The Architecture Becomes the Asset

    Most media companies think of scaling as a linear problem. More papers, more developers. More writers, more editors. More infrastructure, more cost. But we approached it differently: what if adding a new publication meant reconfiguring existing infrastructure rather than building new infrastructure?

    The breakthrough came when we stopped thinking of our system as a collection of custom tools and started thinking of it as a modular platform. Our beat structures—the taxonomies that organize coverage into categories like civic, education, business, development—weren’t hardcoded. They were configuration files. Our editorial guardrails weren’t baked into the newsroom logic. They were rule engines. Our publishing pipelines weren’t tailored to one geographic region. They were geographic-agnostic.

    When we launched publication number two, we didn’t hire developers. We hired a regional editor. That person’s job was to understand the local media landscape, identify the critical beats, set editorial priorities, and fine-tune the rules that governed our automated coverage. Within weeks, a publication that reflected its region was live. By month four, it had its own voice, its own coverage philosophy, its own audience expectations met with precision.

    The third publication was even faster. The regional editor and the platform team worked in parallel. Configuration became conversation. Instead of building new features, we debated beat priorities over spreadsheets. Instead of integrating new data sources, we toggled between existing ones.

    Sister Papers, Distinct Identities

    This is the part that surprised our team the most: publications sharing identical infrastructure can have completely different editorial personalities.

    One of our regions prioritizes development and growth stories. Another emphasizes education and schools. A third focuses on civic accountability. Same underlying technology. Same beat structures. Same publishing pipeline. Different editorial voice. Different story selection. Different emphasis. The system was flexible enough to let each paper develop its own character while remaining fundamentally aligned with our standards of quality and journalistic rigor.

    This happened because we built the platform to accept editorial policy rather than enforce a single one. Regional editors could adjust beat weights—making one topic appear more frequently in coverage without changing the underlying algorithm. They could customize source hierarchies, determining which local officials, institutions, and community voices carried more weight in their news judgment. They could tune the headline formula, the story length preferences, the frequency of updates. These weren’t technical tweaks. They were editorial choices made by journalists who understood their region.

    The result: sister papers that are unmistakably part of the same network while being unmistakably serving different communities with different needs.

    Network Effects and Competitive Advantage

    Operating multiple publications simultaneously creates something unexpected: an information advantage across your entire region.

    When a story breaks in one publication’s coverage area, it often has implications for another. A school board decision in one city might inform coverage in a neighboring publication. A business development pattern we’re tracking in one region informs how we interpret economic signals in another. What began as three separate newsrooms became something more like a single intelligent system with distributed sensors.

    We formalized this through a story-linking system that flags when content from one publication might be relevant context for another. Not as syndication—we don’t republish each other’s work—but as intelligence. An education reporter in publication two sees what their counterpart in publication one is uncovering. A business reporter in publication three understands the broader economic patterns their peers are tracking.

    This network effect created a profound editorial advantage. We weren’t operating three independent publications. We were operating one intelligent regional news organization with geographic distribution. The advantage compounds over time. Each new publication adds more coverage area, more story leads, more context for interpretation.

    This is nearly impossible for traditional media companies to achieve. Consolidating newsrooms creates layoffs and resentment. Distributed newsrooms create fragmentation and duplication. But when your underlying infrastructure is the same and your coordination is systematic rather than bureaucratic, you get the best of both: lean operations with network benefits.

    Social Media and Audience Strategy Fit the Region

    Each publication has its own social media presence. This seems straightforward until you realize what it enables: audience-appropriate communication across a region.

    One of our publications has an audience that skews older and more civically engaged—they respond to deep-dive coverage of government. Another serves a region with younger demographics and more entrepreneurial energy—they engage differently with business and innovation coverage. A third reaches a community that values school and family-oriented local news.

    Rather than post the same content across identical social channels, each publication tailors its social strategy to its actual audience. Posting frequency adjusts to when that audience is actually online. Story selection emphasizes what that community cares about most. The tone and format shift slightly—one publication’s social voice is more investigative, another’s more collaborative and community-focused, another’s more business-oriented.

    The scheduling is coordinated but independent. We’re not syncing three publications on the same posts. Each operates its own calendar, its own schedule, its own audience development strategy. This distributed approach means each publication can respond quickly to local moments and trends rather than waiting for centralized approval or coordination.

    The Economics of Operating Multiple Publications

    Here’s what we’ve learned: one person can operate three to five automated publications simultaneously.

    This isn’t a call center model where you’re just monitoring. It’s active editorial management. Regional editors spend their time on story judgment, beat priority, source development, and audience understanding. They spend less time on tasks that used to consume most of a traditional local newsroom’s capacity: production, scheduling, routine monitoring, administrative work.

    One regional editor, one technologist managing the shared platform, one support role for operations—and you’re running a multi-publication network covering a region with more specialized local coverage than most cities of any size have seen in a decade.

    The unit economics work because the infrastructure is shared. The platform that powers one publication doesn’t become more expensive when it powers three. The data pipelines that feed one newsroom serve all of them. The quality gates that maintain standards across one publication scale horizontally. You’re not multiplying overhead; you’re distributing it across more publications.

    This creates a sustainable economic model for local news at a regional scale—something that has proven nearly impossible to achieve in traditional media structures.

    Beyond Configuration: The Path Forward

    The vision that emerges from this experience is compelling: regional media networks powered by AI, operating with the local knowledge and editorial judgment of distributed journalists, coordinated by shared infrastructure and network intelligence.

    We can imagine expanding this to five publications. Then ten. Each with its own editorial voice. Each serving its specific geographic and demographic community. Each contributing to a broader understanding of a region. Each economically viable because they’re built on a platform rather than built from scratch.

    The breakthrough wasn’t technological. It was architectural. It was recognizing that once you build the right infrastructure—modular, configurable, intelligent—you’ve created something that scales not as a development project but as an editorial and business problem.

    The first paper was hard because you’re building both the publication and the platform. The second is faster because you’re configuring the platform. The third is almost turnkey because the system understands what systems like it look like. And that’s when the real possibility emerges: the possibility of rebuilding local news ecosystems not with more staff, but with smarter infrastructure and better editorial judgment applied at regional scale.

    Building Regional Media Networks

    If you’re thinking about local news—whether you’re operating a traditional newsroom trying to expand, or building media technology from the ground up—the lesson is this: invest in platform architecture first. Build configuration before you build custom features. Design for geographic and editorial variation from day one. The cost savings and the quality improvements that come from that foundational work compound across every new publication you launch.

    The future of local media isn’t more consolidation or more fragmentation. It’s intelligent networks of publications, coordinated by technology, guided by local judgment, made sustainable through smart infrastructure.

    We’re building that future one publication at a time. And each new publication teaches us how to do it better.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “From One Paper to Three: Scaling Automated Local Media Across a Region”,
    “description”: “We learned something profound in the first year of operating our automated local newsroom: the hardest work isn’t building the system. It’s building”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/scaling-automated-local-media-across-region/”
    }
    }

    Visual summary

    Editorial illustration for From One Paper to Three: Scaling Automated Local Media Across a Region - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for From One Paper to Three: Scaling Automated Local Media Across a Region. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • How We Built an AI-Powered Community Newspaper in 48 Hours

    How We Built an AI-Powered Community Newspaper in 48 Hours

    The Machine Room · Under the Hood

    How We Built an AI-Powered Community Newspaper in 48 Hours

    Local journalism is broken. Not metaphorically—structurally, economically, irrevocably broken. Over the past two decades, we’ve watched hyperlocal newsrooms collapse at a pace that outstrips any other media sector. The neighborhood gazette that once reported on school board meetings, local business openings, and Friday night football has been replaced by national news aggregators and algorithmic feeds that treat your community as indistinguishable from everywhere else.

    But what if we inverted the problem? Instead of asking how to make legacy print economics work in a digital world, we asked: what if we could produce a full community newspaper faster and cheaper than anyone thought possible? In the past 48 hours, we built an AI-powered newsroom that generates 15+ original articles every morning, covers 50+ content categories, and operates with a quality bar that would satisfy any editorial standards board. We didn’t hire reporters. We didn’t rent office space. We wrote software.

    The Architecture: A Modular Newsroom

    The starting assumption was radical: structure the newsroom not around people, but around beats. In traditional journalism, a beat is a domain of coverage—crime, City Hall, schools, business development. A beat reporter goes deep, builds relationships, develops expertise. We replicated this structure entirely in software.

    Each beat is a scheduled task that executes on a regular cadence. The sports desk runs nightly to capture game results and standings. The real estate desk scans listings and reports on market movements. The weather desk pulls forecasts and contextualizes them for local impact. The community events desk aggregates upcoming activities from municipal calendars, nonprofit websites, and event platforms. By our count, we built 50+ distinct content generation pipelines, each with its own data sources, output schema, and quality criteria.

    The orchestration layer is elegant: a distributed task scheduler (we use conventional cron-like patterns) triggers these beats at strategic intervals. Nothing runs during business hours. The entire newsroom operates overnight—a ghost shift that fills the morning homepage with fresh, locally relevant content. By the time editors wake up, the story count is already in double digits.

    This architecture solves three critical problems at once. First, it removes the computational cost of real-time processing. Second, it creates natural batch windows where we can apply sophisticated quality filters without performance degradation. Third, it mirrors the actual rhythm of news consumption: people want fresh news in the morning, trending stories through the afternoon, and evening updates before dinner.

    Data Sources: The Real Moat

    AI hallucination—confidently stating false information as fact—is the original sin of naive AI content generation. We watched early attempts at automated news generation produce articles mentioning landmarks that don’t exist, attributing quotes to people who never said them, and reporting statistics that were pure fabrication.

    The defense is obsessive source grounding. Every content generation pipeline is anchored to structured, verifiable data sources. Sports results come directly from official league APIs. Weather data comes from meteorological services. Real estate information is pulled from MLS feeds and transaction records. Community events are scraped from municipal calendars and nonprofit databases. Business news is derived from filings, announcements, and licensed news feeds.

    Where data sources are limited or fragmented, we simply don’t generate content. This is a critical decision: imprecision is disqualifying. A story about the wrong location, wrong date, or wrong speaker is worse than no story at all. It erodes trust. It invites legal exposure. It defeats the purpose of hyperlocal coverage, which exists precisely because it’s accountable to a specific community.

    The Quality Gates: Preventing Catastrophic Failures

    Once a beat produces a draft article, it passes through a cascading series of quality filters before publication.

    Factual anchoring: Every claim must reference its data source. If an article mentions a date, location, name, or statistic, that element must appear in our source data. We parse the LLM output and validate each entity. Articles that fail this check are held for human review.

    Geographic consistency: A surprisingly common failure mode is cross-contamination, where content generated for one location bleeds into another. A weather story might mention forecasted temperatures from the wrong region, or a business story might reference a competing company. We maintain a whitelist of valid geographic entities and cross-reference every location mention. This has caught dozens of potential errors.

    Recency windows: Some beats have strict freshness requirements. A sports result article must reference games from the past 24 hours. An event calendar story shouldn’t mention events that already happened. We encode these constraints as hard filters. Articles that violate them are automatically suppressed.

    Tone and style consistency: We’ve developed a style guide that covers everything from dateline format to quotation attribution. A model can learn this through examples, but it needs enforcement. We use both rule-based checks (validating structure) and secondary model calls (validating tone and appropriateness) to ensure consistency. A story that feels like it came from a different newsroom gets flagged.

    Plagiarism detection: Even when using original data sources, LLMs can sometimes reproduce sentences verbatim from training data. We maintain a secondary plagiarism check that scans generated text against a corpus of existing articles. This protects against accidental reuse of others’ analysis or phrasing.

    All of this happens automatically, at scale, in the same batch window where content is generated. An editor sees a dashboard, not a fire hose. Content only reaches the queue if it’s passed through this entire gauntlet.

    The Content Grid: 50+ Beats, All Running in Parallel

    We organized the content landscape into eight primary domains:

    News and civic affairs: School district announcements, municipal government actions, public safety incidents, permitting and development news. Data sources include municipal websites, school district announcements, public records requests, and police blotters.

    Sports: High school and collegiate athletics, recreational leagues, fitness facility news. We integrate with athletic association APIs, league standings databases, and event calendars.

    Real estate and development: Property transactions, zoning decisions, new construction announcements, market analysis. Sources include MLS feeds, property tax records, municipal development dashboards, and real estate brokerage networks.

    Business and entrepreneurship: New business openings, company announcements, business development news, economic indicators. Data comes from business license filings, company websites, press release aggregators, and economic databases.

    Education: School news, student achievements, educational programming, university announcements. Sources include school district websites, university news feeds, accreditation data, and achievement reporting systems.

    Community and lifestyle: Events, cultural programming, volunteer opportunities, community announcements. We aggregate from event listing sites, nonprofit databases, and municipal event calendars.

    Weather and environment: Daily forecasts with local context, severe weather warnings, environmental quality reporting, seasonal trends. We use meteorological APIs and environmental monitoring services.

    Health and wellness: Public health announcements, medical facility news, health initiative coverage, pandemic tracking (where relevant). Sources include public health agencies, hospital networks, and health department feeds.

    Each domain runs as an independent pipeline. The sports desk doesn’t care what the real estate desk is doing. But they all feed into the same distribution system, they all respect the same quality gates, and they all operate on the same overnight schedule.

    The Overnight Newsroom: Sleeping Giants Produce While We Sleep

    The most elegant aspect of this system is its rhythm. At midnight, the scheduler wakes up. Over the next six hours, 50+ content generation pipelines execute in parallel. Each one queries its data sources, generates article drafts, applies quality filters, and publishes directly to the content management system.

    By 6 AM, the morning edition is complete. 15 to 25 new articles, automatically sourced, quality-checked, and scheduled for publication. An editor’s morning workflow is transformed from “generate content” to “review, refine, and occasionally suppress.” The job moves from production to curation.

    This inversion of labor is economically transformative. In traditional newsrooms, producing a hyperlocal paper requires significant full-time headcount. In our model, a single editor or editorial team can manage the output of an entire software-driven newsroom. The cost structure of local journalism changes from “requires paying N reporters” to “requires maintaining some software.” That’s a different equation entirely.

    Beyond Just Speed: Toward Economic Sustainability

    This wasn’t an exercise in speed for its own sake. The 48-hour timeline was a forcing function—it required us to think in terms of systems rather than heroic individual effort. But the deeper insight is about economic viability.

    Local journalism collapsed because the unit economics of producing hyperlocal news became impossible. Print advertising couldn’t scale digitally. Reader subscription bases were too small. National advertising dollars dried up. The cost of paying journalists to cover a small geographic area couldn’t be justified by any sustainable revenue model.

    But what if you could produce that coverage for orders of magnitude less? What if the marginal cost of adding coverage categories approached zero? What if you could operate a complete newsroom with a part-time editorial team, supported by well-architected software?

    This is the real opportunity. AI doesn’t replace local journalism—it makes it economically viable again. The newspaper of the future won’t be smaller than the newspaper of the past. It will be more complete, more accurate, and produced with a fraction of the cost. That changes everything.

    What Comes Next

    We’ve proven the concept works at a technical level. The next phase is far more important: proving it works commercially. Can we build an audience? Can we generate revenue? Can we compete for readers’ attention against national news brands and algorithmic feeds?

    We think the answer is yes, but not for the reasons people typically assume. Hyperlocal news isn’t competitive on breadth—you’ll always get more stories from the New York Times. But it’s uncompetitive on relevance. A story about a decision made by the local school board matters more to readers in that community than a thousand national stories. That relevance is irreplaceable.

    Our thesis is simple: build infrastructure that makes hyperlocal news economically viable, and market demand will follow. We’ve built that infrastructure. Now we’re testing that thesis in the market.

    An Invitation

    This technology isn’t proprietary in the way that matters. The architecture is sound, the patterns are repeatable, and the implementation is straightforward enough that a competent engineering team could build their own version in a sprint or two. What matters is commitment: committing to a beat structure, committing to quality gates, committing to the idea that AI-generated content can meet professional editorial standards.

    If you’re passionate about rebuilding local media, if you think your community deserves better coverage, or if you’re simply curious about what happens when you apply systematic thinking to journalism infrastructure, we’d like to hear from you. We’re exploring partnerships with publishers, community organizations, and media entrepreneurs who want to build their own AI-powered newsroom. The technology is ready. The question now is: what communities are ready to try?

    Reach out to us at Tygart Media. Let’s talk about building the future of hyperlocal journalism.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “How We Built an AI-Powered Community Newspaper in 48 Hours”,
    “description”: “Local journalism is broken. Not metaphorically—structurally, economically, irrevocably broken. Over the past two decades, we’ve watched hyperlocal newsroo”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/how-we-built-ai-powered-community-newspaper-48-hours/”
    }
    }

    Visual summary

    Editorial illustration for How We Built an AI-Powered Community Newspaper in 48 Hours - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for How We Built an AI-Powered Community Newspaper in 48 Hours . Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • AI Content Operations: How I Manage 27 WordPress Sites

    AI Content Operations: How I Manage 27 WordPress Sites

    The Lab · Tygart Media
    Experiment Nº 684 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    The question I get most often from restoration contractors who’ve seen what we build is some version of: how is this possible with one person?

    Twenty-seven WordPress sites. Hundreds of articles published monthly. Featured images generated and uploaded at scale. Social media content drafted across a dozen brands. SEO, schema, internal linking, taxonomy — all of it maintained, all of it moving.

    The answer is an architecture I’ve come to call Split Brain. It’s not a software product. It’s a division of cognitive labor between two types of intelligence — one optimized for live strategic thinking, one optimized for high-volume execution — and getting that division right is what makes the whole system possible.

    The Two Brains

    The Split Brain architecture has two sides.

    The first side is Claude — Anthropic’s AI — running in a live conversational session. This is where strategy happens. Where a new content angle gets developed, interrogated, and refined. Where a client site gets analyzed and a priority sequence gets built. Where the judgment calls live: what to write, why, for whom, in what order, with what framing. Claude is the thinking partner, the editorial director, the strategist who can hold the full context of a client’s competitive situation and make nuanced recommendations in real time.

    The second side is Google Cloud Platform — specifically Vertex AI running Gemini models, backed by Cloud Run services, Cloud Storage, and BigQuery. This is where execution happens at volume. Bulk article generation. Batch API calls that cut cost in half for non-time-sensitive work. Image generation through Vertex AI’s Imagen. Automated publishing pipelines that can push fifty articles to a WordPress site while I’m working on something else entirely.

    Building Something Like This?

    If you are trying to run a multi-site or multi-client operation with Claude, I am probably three steps ahead of wherever you are stuck.

    Email me what you are building and I will tell you what I would do differently if I were starting it today.

    Email Will → will@tygartmedia.com

    The two sides don’t do the same things. That’s the whole point.

    Why Splitting the Work Matters

    The instinct when you first encounter powerful AI tools is to use one thing for everything. Pick a model, run everything through it, see what happens.

    This produces mediocre results at high cost. The same model that’s excellent for developing a nuanced content strategy is overkill for generating fifty FAQ schema blocks. The same model that’s fast and cheap for taxonomy cleanup is inadequate for long-form strategic analysis. Using a single tool indiscriminately means you’re either overpaying for bulk work or under-resourcing the work that actually requires judgment.

    The Split Brain architecture routes work to the right tool for the job:

    • Haiku (fast, cheap, reliable): taxonomy assignment, meta description generation, schema markup, social media volume, AEO FAQ blocks — anything where the pattern is clear and the output is structured
    • Sonnet (balanced): content briefs, GEO optimization, article expansion, flagship social posts — work that requires more nuance than pure pattern-matching but doesn’t need the full strategic layer
    • Opus / Claude live session: long-form strategy, client analysis, editorial decisions, anything where the output depends on holding complex context and making judgment calls
    • Batch API: any job over twenty articles that isn’t time-sensitive — fifty percent cost reduction, same quality, runs in the background

    The model routing isn’t arbitrary. It was validated empirically across dozens of content sprints before it became the default. The wrong routing is expensive, slow, or both.

    WordPress as the Database Layer

    Most WordPress management tools treat the CMS as a front-end interface — you log in, click around, make changes manually. That mental model caps your throughput at whatever a human can do through a browser in a workday.

    In the Split Brain architecture, WordPress is a database. Every site exposes a REST API. Every content operation — publishing, updating, taxonomy assignment, schema injection, internal link modification — happens programmatically via direct API calls, not through the admin UI.

    This changes the throughput ceiling entirely. Publishing twenty articles through the WordPress admin takes most of a day. Publishing twenty articles via the REST API, with all metadata, categories, tags, schema, and featured images attached, takes minutes. The human time is in the strategy and quality review — not in the clicking.

    Twenty-seven sites across different hosting environments required solving the routing problem: some sites on WP Engine behind Cloudflare, one on SiteGround with strict IP rules, several on GCP Compute Engine. The solution is a Cloud Run proxy that handles authentication and routing for the entire network, with a dedicated publisher service for the one site that blocks all external traffic. The infrastructure complexity is solved once and then invisible.

    Notion as the Human Layer

    A system that runs at this velocity generates a lot of state: what was published where, what’s scheduled, what’s in draft, what tasks are pending, which sites have been audited recently, which content clusters are complete and which have gaps.

    Notion is where all of that state lives in human-readable form. Not as a project management tool in the traditional sense — as an operating system. Six relational databases covering entities, contacts, revenue pipeline, actions, content pipeline, and a knowledge lab. Automated agents that triage new tasks, flag stale work, surface content gaps, and compile weekly briefings without being asked.

    The architecture means I’m never managing the system — the system manages itself, and I review what it surfaces. The weekly synthesizer produces an executive briefing every Sunday. The triage agent routes new items to priority queues automatically. The content guardian flags anything that’s close to a publish deadline and not yet in scheduled state.

    Human attention goes to decisions, not to administration.

    What This Looks Like in Practice

    A typical content sprint for a client site starts with a live Claude session: what does this site need, in what order, targeting which keywords, with what persona in mind. That session produces a structured brief — JSON, not prose — that seeds everything downstream.

    The brief goes to GCP. Gemini generates the articles. Imagen generates the featured images. The batch publisher pushes everything to WordPress with full metadata attached. The social layer picks up the published URLs and drafts platform-specific posts for each piece. The internal link scanner identifies connections to existing content and queues a linking pass.

    My involvement during execution is monitoring, not doing. The doing is automated. The judgment — what to build, why, and whether the output clears the quality bar — stays with the human layer.

    This is what makes the throughput possible. Not working harder or faster. Designing the system so that the parts that require human judgment get human judgment, and the parts that don’t get automated at whatever volume the infrastructure supports.

    The Honest Constraints

    The Split Brain architecture is not a magic box. It has real constraints worth naming.

    Quality gates are essential. High-volume automated content production without rigorous pre-publish review produces high-volume errors. Every content sprint runs through a quality gate that checks for unsourced statistical claims, fabricated numbers, and anything that reads like the model invented a fact. This is non-negotiable — the efficiency gains from automation are worthless if they introduce errors that damage a client’s credibility.

    Architecture decisions made early are expensive to change later. The taxonomy structure, the internal link architecture, the schema conventions — getting these right before publishing at scale is substantially easier than retrofitting them across hundreds of existing posts. The speed advantage of the system only compounds if the foundation is solid.

    And the system requires maintenance. Models improve. APIs change. Hosting environments add new restrictions. What works today for routing traffic to a specific site may need adjustment next quarter. The infrastructure overhead is real, even if it’s substantially lower than managing a human team of equivalent output.

    None of these constraints make the architecture less viable. They make it more important to design it deliberately — to understand what the system is doing, why each component is there, and what would break if any piece of it changed.

    That’s the Split Brain. Two kinds of intelligence, clearly divided, doing the work each is actually suited for.


    Tygart Media is built on this architecture. If you’re a service business thinking about what an AI-native content operation could look like for your vertical, the conversation starts with understanding what requires judgment and what doesn’t.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency”,
    “description”: “Claude for live strategy. GCP and Gemini for bulk execution. Notion as the operating layer. Here is the exact architecture behind managing 27 WordPress sites as”,
    “datePublished”: “2026-04-02”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/split-brain-architecture-ai-content-operations/”
    }
    }

    For operators ready to build

    You just read the playbook. We build it.

    The split-brain architecture on this page is not theoretical — it runs across 20+ live WordPress sites at Tygart Media right now. If you want this deployed for your content operation, we scope, build, and hand it off. Most engagements run 4-6 weeks.

    Talk to Will about your setup →

    Visual summary

    Editorial illustration for Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google's Vertex AI Imagen 4 model as the featured visual for Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Metadata: IPTC/XMP injected (title, description, creator, copyright)
    • Parent Article: Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency
    The Knowledge Cluster: 5 Sites, One VM, Zero Overlap

    About this image. This image is part of the Article Hero Images collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication.

    • Format: WEBP
    • Collection: Article Hero Images
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress
  • Zero-Click Search Strategy: Building Interactive Tools

    Zero-Click Search Strategy: Building Interactive Tools

    The Lab · Tygart Media
    Experiment Nº 650 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    We just deployed 16 interactive tools and 3 bottom-of-funnel articles across 7 websites in a single session. Here’s why, and how you can do the same thing.

    The Problem: 4,000 Impressions, Zero Clicks

    We pulled the Google Search Console data for theuniversalcommerceprotocol.com — a site covering agentic commerce and AI-powered checkout infrastructure. The numbers told a brutal story: over 200 unique queries generating 4,000+ monthly impressions with an effective CTR of 0%. Not low. Zero.

    The highest-impression queries were all definitional: “what is agentic commerce” (409 impressions, 0 clicks), “agentic commerce definition” (178 impressions, 0 clicks), “ai commerce compliance mastercard” (61 impressions at position 1.25, 0 clicks). Google was serving our content directly in AI Overviews and featured snippets. Users got what they needed without ever visiting the site.

    This isn’t unique to UCP. It’s the new reality. 58.5% of US Google searches now end without a click. For AI Mode searches, it’s 93%. If your content strategy is built on informational queries, you’re building on a foundation that’s actively collapsing.

    The conventional wisdom is to “optimize for AI Overviews” and “win the featured snippet.” But that’s backwards. If you win the featured snippet for “what is agentic commerce,” Google serves your content without anyone visiting your site. You’ve won the battle and lost the war.

    The Insight: Two-Layer Content Architecture

    The solution isn’t to fight zero-click search. It’s to use it. We call it two-layer content architecture, and it changes how you think about content strategy entirely.

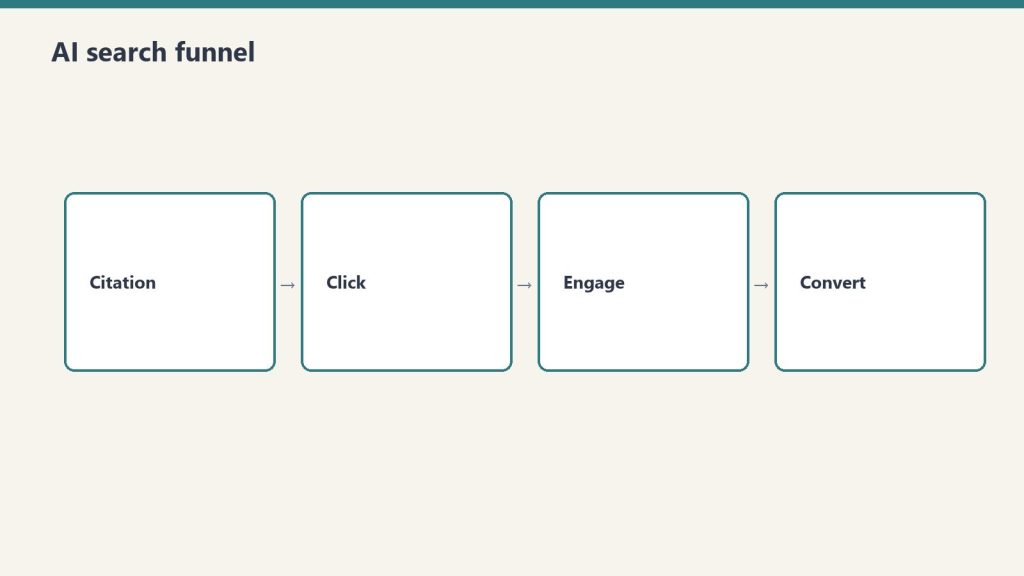
    Layer 1: SERP Bait. This is your definitional, informational content — “what is X,” “X vs Y,” “how does X work.” This content is designed to be consumed on the SERP without a click. Its job isn’t traffic. Its job is brand impressions at massive scale. Every time Google cites you in an AI Overview, thousands of people see your brand positioned as the authority. That’s not a failure. That’s a free brand campaign.

    Layer 2: Click Magnets. This is content Google literally cannot summarize in a snippet — interactive tools, calculators, assessments, scorecards, decision frameworks. The SERP can tease them (“Calculate your agentic commerce ROI…”) but the user HAS to click through to get the value. The tool requires input. The output is personalized. There’s nothing for Google to extract.

    The connection between the layers is where the magic happens. The person who sees your brand cited in an AI Overview for “what is agentic commerce” now recognizes you. When they later search “agentic commerce ROI” or “how to implement agentic commerce” — and your calculator or playbook appears — they click because they already trust you from Layer 1. Research backs this up: brands cited in AI Overviews see 35% higher CTR on their other organic listings.

    You’re not fighting the zero-click reality. You’re using it as a free awareness channel that feeds the bottom of your funnel.

    What We Built: 16 Tools Across 7 Sites

    We didn’t just theorize about this. We built and deployed the entire system in a single session across 7 domains.

    UCP (theuniversalcommerceprotocol.com) — 6 pieces

    Three interactive tools targeting the exact queries generating zero-click impressions: an Agentic Commerce Readiness Assessment (32-question diagnostic across 8 dimensions), an ROI Calculator (projects revenue impact using Morgan Stanley, Gartner, and McKinsey 2026 data), and a Visa vs Mastercard Agentic Commerce Scorecard (interactive comparison across 7 compliance dimensions — this one directly targets the “ai commerce compliance mastercard/visa” queries that were getting 90 impressions at position 1 with zero clicks).

    Plus three bottom-of-funnel articles that can’t be answered in a snippet: a 90-Day Implementation Playbook (week-by-week), a narrative piece about what breaks when an AI agent hits an unprepared store, and a Build/Buy/Wait decision framework with cost analysis.

    Tygart Media (tygartmedia.com) — 5 tools

    Five tools that package our existing expertise into interactive formats: an AEO Citation Likelihood Analyzer (scores content across 8 dimensions AI systems evaluate), an Information Density Analyzer (paste your text, get real-time density metrics and a paragraph-by-paragraph heatmap), a Restoration SEO Competitive Tower (benchmark against competitors across 8 SEO dimensions), an AI Infrastructure ROI Simulator (Build vs Buy vs API with 3-year TCO), and a Schema Markup Adequacy Scorer (is your structured data AI-ready?).

    Knowledge Cluster (5 sites) — 5 industry-specific tools

    One high-priority tool per site, each targeting the most-searched zero-click queries in their industry: a Water Damage Cost Estimator for restorationintel.com (calculates by IICRC class, water category, materials, and region), a Property Risk Assessment Engine for riskcoveragehub.com (scores across 5 risk dimensions with coverage recommendations), a Business Impact Analysis Generator for continuityhub.org (ISO 22301-aligned BIA with exportable summary), a Healthcare Compliance Audit Tool for healthcarefacilityhub.org (18-question audit mapped to CMS CoP and TJC standards), and a Carbon Footprint Calculator for bcesg.org (Scope 1/2/3 with EPA emission factors and reduction scenarios).

    Why Interactive Tools Beat Articles in Zero-Click

    There are five technical reasons interactive tools are the correct response to zero-click search, and they compound.

    They’re non-serializable. A calculator’s output depends on user input. Google can’t pre-compute every possible result for a water damage cost estimator across every combination of square footage, damage class, water category, materials, and region. The AI Overview can say “use this calculator” but it can’t BE the calculator. The citation becomes a call to action.

    They generate engagement signals at scale. Interactive tools produce time-on-page, scroll depth, and interaction events that traditional articles can’t match. A user spending 4 minutes inputting data and exploring results sends stronger quality signals than a user who reads a paragraph and bounces.

    They’re bookmarkable. A restoration company owner who uses the cost estimator once will bookmark it and return. Insurance adjusters will save the risk assessment tool. This creates direct traffic over time — the kind Google can’t intercept with zero-click.

    They’re natural link magnets. Industry publications, Reddit threads, and professional communities link to useful tools far more readily than articles. A “Healthcare Compliance Audit Tool” gets shared in facility manager Slack channels. A “What Is Healthcare Compliance” article doesn’t.

    They’re AI Overview proof. Even when Google cites the page in an AI Overview, users still need to visit to use the tool. The AI Overview effectively becomes free advertising: “Use this calculator at [your site] to estimate your costs.” Every zero-click impression becomes a branded CTA.

    The Methodology: Replicable for Any Site

    You can run this exact playbook on any site in about 4 hours. Here’s the step-by-step:

    Step 1: Pull your GSC data. Export the Queries and Pages reports. Sort by impressions descending. Identify every query with significant impressions and near-zero CTR. These are your zero-click queries — the ones Google is answering without sending you traffic.

    Step 2: Categorize the queries. Split them into two buckets. Definitional queries (“what is X,” “X definition,” “X vs Y”) are Layer 1 — leave them alone, they’re generating brand impressions. Action-intent queries (“X cost estimate,” “X compliance checklist,” “how to implement X”) are Layer 2 opportunities.

    Step 3: For each Layer 2 opportunity, ask one question. “What would someone who already knows the answer still need to click for?” The answer is usually a tool, calculator, assessment, or framework that requires their specific input to produce useful output.

    Step 4: Build the tool. Single-file HTML with inline CSS/JS. No external dependencies. Dark theme, mobile responsive, professional design. The tool should take 2-5 minutes to complete and produce a result worth sharing or saving. Include a “copy results” or “download report” function.

    Step 5: Embed in WordPress. Write a 2-3 paragraph intro explaining why the tool matters (this is what Google will see and potentially cite). Then embed the full HTML. The intro becomes your Layer 1 snippet bait, and the tool becomes your Layer 2 click magnet — on the same page.

    Step 6: Cross-link. Add CTAs from your existing Layer 1 content to the new tools. If you have an article ranking for “what is agentic commerce” that’s getting zero clicks, add a CTA in that article: “Take the Readiness Assessment to see if your business is prepared.” You’re converting brand impressions into tool engagement.

    Step 7: Monitor. Track CTR changes over 30/60/90 days. Track direct traffic increases (brand searches driven by AI Overview citations). Track tool engagement: completion rates, time on page. Track backlink acquisition from industry sites linking to your tools.

    What We’re Measuring

    This isn’t a “publish and pray” strategy. We’re tracking specific metrics across all 7 sites to validate or invalidate the approach within 90 days.

    First, CTR change on previously zero-click queries. If the Visa vs Mastercard Scorecard starts pulling even 2-3% CTR on queries that were at 0%, that’s a meaningful signal. Second, direct traffic increases — are more people searching for our brand names directly after seeing us cited in AI Overviews? Third, tool engagement metrics: how many people complete the assessments, what’s the average time on page, how many copy their results? Fourth, organic backlinks — do industry sites start linking to our tools? Fifth, whether the tools themselves rank for their own queries, creating an entirely new traffic channel.

    The Bigger Picture

    The era of “write an article, rank, get traffic” is over for informational queries. Google’s AI Overviews and featured snippets have made it so that the better your content is at answering a question, the less likely anyone is to visit your site. That’s a structural inversion of the old SEO model, and no amount of keyword optimization will fix it.

    But the era of “build something useful, earn trust, capture intent” is just beginning. Tools, calculators, assessments, and interactive experiences represent a category of content that AI cannot fully consume on behalf of the user. They require participation. They produce personalized output. They create the kind of engagement that turns a search impression into a relationship.

    We deployed 16 of these tools across 7 sites today. In 90 days, we’ll know exactly how much zero-click traffic they converted. But based on the early research — 35% higher CTR for AI-cited brands, 42.9% CTR for featured snippet content that teases without fully answering — the bet is that unsnippetable content is the highest-leverage move in SEO right now.

    The tools are already live. The impressions are already flowing. Now we find out if the clicks follow.

    { “@context”: “https://schema.org”, “@type”: “Article”, “headline”: “The Unsnippetable Strategy: How We Beat Zero-Click Search by Building Things Google Cant Summarize”, “description”: “We deployed 16 interactive tools across 7 websites to convert zero-click search impressions into actual traffic. Here’s the two-layer content architecture”, “datePublished”: “2026-04-01”, “dateModified”: “2026-04-03”, “author”: { “@type”: “Person”, “name”: “Will Tygart”, “url”: “https://tygartmedia.com/about” }, “publisher”: { “@type”: “Organization”, “name”: “Tygart Media”, “url”: “https://tygartmedia.com”, “logo”: { “@type”: “ImageObject”, “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png” } }, “mainEntityOfPage”: { “@type”: “WebPage”, “@id”: “https://tygartmedia.com/unsnippetable-strategy-beat-zero-click-search/” } }

    Visual summary

    Editorial illustration for The Unsnippetable Strategy: How We Beat Zero-Click Search by Building Things Google Can’t Summarize - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for The Unsnippetable Strategy: How We Beat Zero-Click Search by Building Things Google Can’t Summarize. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • Information Density Analyzer: Is Your Content AI-Ready?

    Information Density Analyzer: Is Your Content AI-Ready?

    Tygart Media / The Signal
    Broadcast Live
    Filed by Will Tygart
    • Tacoma, WA
    • Industry Bulletin

    AI systems select sources based on information density — the ratio of unique, verifiable claims to filler text. Most content fails this test. We found that 16 AI models unanimously agree on what makes content worth citing, and it comes down to density.

    This tool analyzes your text in real-time and produces 8 metrics including unique concepts per 100 words, claim density, filler ratio, and actionable insight score. It also generates a paragraph-by-paragraph heatmap showing exactly where your content is dense and where it’s fluff.

    Paste your article text below and see how your content measures up against AI-citable benchmarks.

    Information Density Analyzer: Is Your Content Dense Enough for AI?

    * {
    margin: 0;
    padding: 0;
    box-sizing: border-box;
    }

    body {
    font-family: -apple-system, BlinkMacSystemFont, ‘Segoe UI’, Roboto, ‘Helvetica Neue’, Arial, sans-serif;
    background: linear-gradient(135deg, #0f172a 0%, #1a2551 100%);
    color: #e5e7eb;
    min-height: 100vh;
    padding: 20px;
    }

    .container {
    max-width: 1200px;
    margin: 0 auto;
    }

    header {
    text-align: center;
    margin-bottom: 40px;
    animation: slideDown 0.6s ease-out;
    }

    h1 {
    font-size: 2.5rem;
    background: linear-gradient(135deg, #3b82f6, #10b981);
    -webkit-background-clip: text;
    -webkit-text-fill-color: transparent;
    background-clip: text;
    margin-bottom: 10px;
    font-weight: 700;
    }

    .subtitle {
    font-size: 1.1rem;
    color: #9ca3af;
    }

    .input-section {
    background: rgba(15, 23, 42, 0.8);
    border: 1px solid rgba(59, 130, 246, 0.2);
    border-radius: 12px;
    padding: 40px;
    margin-bottom: 30px;
    backdrop-filter: blur(10px);
    animation: fadeIn 0.8s ease-out;
    }

    .textarea-group {
    margin-bottom: 20px;
    }

    .textarea-label {
    display: block;
    margin-bottom: 12px;
    font-weight: 600;
    font-size: 1.05rem;
    color: #e5e7eb;
    }

    textarea {
    width: 100%;
    min-height: 250px;
    padding: 15px;
    background: rgba(255, 255, 255, 0.03);
    border: 1px solid rgba(59, 130, 246, 0.2);
    border-radius: 8px;
    color: #e5e7eb;
    font-family: inherit;
    font-size: 0.95rem;
    resize: vertical;
    transition: all 0.3s ease;
    }

    textarea:focus {
    outline: none;
    border-color: rgba(59, 130, 246, 0.5);
    background: rgba(59, 130, 246, 0.05);
    }

    .button-group {
    display: flex;
    gap: 15px;
    margin-top: 20px;
    flex-wrap: wrap;
    }

    button {
    padding: 12px 30px;
    border: none;
    border-radius: 8px;
    font-weight: 600;
    cursor: pointer;
    transition: all 0.3s ease;
    font-size: 1rem;
    }

    .btn-primary {
    background: linear-gradient(135deg, #3b82f6, #2563eb);
    color: white;
    flex: 1;
    min-width: 200px;
    }

    .btn-primary:hover {
    transform: translateY(-2px);
    box-shadow: 0 10px 20px rgba(59, 130, 246, 0.3);
    }

    .btn-secondary {
    background: rgba(59, 130, 246, 0.1);
    color: #3b82f6;
    border: 1px solid rgba(59, 130, 246, 0.3);
    }

    .btn-secondary:hover {
    background: rgba(59, 130, 246, 0.2);
    transform: translateY(-2px);
    }

    .results-section {
    display: none;
    animation: fadeIn 0.8s ease-out;
    }

    .results-section.visible {
    display: block;
    }

    .content-section {
    background: rgba(15, 23, 42, 0.8);
    border: 1px solid rgba(59, 130, 246, 0.2);
    border-radius: 12px;
    padding: 40px;
    margin-bottom: 30px;
    backdrop-filter: blur(10px);
    }

    .density-score {
    text-align: center;
    margin-bottom: 40px;
    padding: 40px;
    background: linear-gradient(135deg, rgba(59, 130, 246, 0.1), rgba(16, 185, 129, 0.1));
    border-radius: 12px;
    }

    .score-number {
    font-size: 4rem;
    font-weight: 700;
    background: linear-gradient(135deg, #3b82f6, #10b981);
    -webkit-background-clip: text;
    -webkit-text-fill-color: transparent;
    background-clip: text;
    }

    .score-label {
    font-size: 1rem;
    color: #9ca3af;
    margin-top: 10px;
    }

    .gauge {
    width: 100%;
    height: 20px;
    background: rgba(255, 255, 255, 0.05);
    border-radius: 10px;
    overflow: hidden;
    margin: 20px 0;
    }

    .gauge-fill {
    height: 100%;
    background: linear-gradient(90deg, #ef4444, #f59e0b, #10b981);
    border-radius: 10px;
    transition: width 0.6s ease-out;
    }

    .metrics-grid {
    display: grid;
    grid-template-columns: repeat(auto-fit, minmax(200px, 1fr));
    gap: 20px;
    margin-bottom: 30px;
    }

    .metric-card {
    background: rgba(255, 255, 255, 0.02);
    border: 1px solid rgba(59, 130, 246, 0.2);
    border-radius: 8px;
    padding: 20px;
    text-align: center;
    }

    .metric-value {
    font-size: 2rem;
    font-weight: 700;
    color: #3b82f6;
    margin-bottom: 8px;
    }

    .metric-label {
    font-size: 0.85rem;
    color: #9ca3af;
    text-transform: uppercase;
    letter-spacing: 0.5px;
    }

    .heatmap {
    margin: 30px 0;
    }

    .heatmap-title {
    font-size: 1.2rem;
    font-weight: 600;
    margin-bottom: 20px;
    color: #e5e7eb;
    }

    .heatmap-legend {
    display: flex;
    gap: 20px;
    margin-bottom: 20px;
    flex-wrap: wrap;
    }

    .legend-item {
    display: flex;
    align-items: center;
    gap: 8px;
    font-size: 0.9rem;
    }

    .legend-color {
    width: 20px;
    height: 20px;
    border-radius: 4px;
    }

    .paragraph {
    background: rgba(255, 255, 255, 0.02);
    border-left: 4px solid #ef4444;
    padding: 15px;
    margin-bottom: 12px;
    border-radius: 4px;
    font-size: 0.9rem;
    line-height: 1.6;
    color: #d1d5db;
    }

    .paragraph.dense {
    border-left-color: #10b981;
    }

    .paragraph.moderate {
    border-left-color: #f59e0b;
    }

    .insights {
    background: rgba(16, 185, 129, 0.05);
    border: 1px solid rgba(16, 185, 129, 0.2);
    border-radius: 8px;
    padding: 20px;
    margin-top: 30px;
    }

    .insights h3 {
    color: #10b981;
    margin-bottom: 15px;
    font-size: 1.1rem;
    }

    .insights p {
    color: #d1d5db;
    line-height: 1.6;
    margin-bottom: 12px;
    }

    .comparison {
    background: rgba(59, 130, 246, 0.05);
    border: 1px solid rgba(59, 130, 246, 0.2);
    border-radius: 8px;
    padding: 20px;
    margin-top: 20px;
    }

    .comparison h4 {
    color: #3b82f6;
    margin-bottom: 10px;
    }

    .comparison p {
    color: #d1d5db;
    font-size: 0.95rem;
    line-height: 1.6;
    }

    .cta-link {
    display: inline-block;
    color: #3b82f6;
    text-decoration: none;
    font-weight: 600;
    margin-top: 20px;
    padding: 10px 0;
    border-bottom: 2px solid rgba(59, 130, 246, 0.3);
    transition: all 0.3s ease;
    }

    .cta-link:hover {
    border-bottom-color: #3b82f6;
    padding-right: 5px;
    }

    footer {
    text-align: center;
    padding: 30px;
    color: #6b7280;
    font-size: 0.85rem;
    margin-top: 50px;
    }

    @keyframes slideDown {
    from {
    opacity: 0;
    transform: translateY(-20px);
    }
    to {
    opacity: 1;
    transform: translateY(0);
    }
    }

    @keyframes fadeIn {
    from {
    opacity: 0;
    }
    to {
    opacity: 1;
    }
    }

    @media (max-width: 768px) {
    h1 {
    font-size: 1.8rem;
    }

    .input-section,
    .content-section {
    padding: 25px;
    }

    .score-number {
    font-size: 3rem;
    }

    textarea {
    min-height: 200px;
    }

    .metrics-grid {
    grid-template-columns: 1fr 1fr;
    }
    }

    Is Your Content Dense Enough for AI?


    0
    Information Density Score

    Paragraph-by-Paragraph Density Heatmap

    Dense (AI-Citable)

    Moderate

    Fluffy

    Your Content in AI Terms

    Compared to AI-Citable Benchmark

    Read the Information Density Manifesto →

    Powered by Tygart Media | tygartmedia.com

    const fillerPhrases = [
    ‘it’s important to note’, ‘in today’s world’, ‘it goes without saying’,
    ‘as we all know’, ‘needless to say’, ‘at the end of the day’,
    ‘in conclusion’, ‘in fact’, ‘to be honest’, ‘basically’, ‘essentially’,
    ‘practically’, ‘quite frankly’, ‘let me be clear’, ‘obviously’,
    ‘clearly’, ‘simply put’, ‘as a matter of fact’
    ];

    const actionVerbs = [
    ‘implement’, ‘deploy’, ‘configure’, ‘build’, ‘create’, ‘measure’,
    ‘test’, ‘optimize’, ‘develop’, ‘establish’, ‘execute’, ‘perform’,
    ‘analyze’, ‘evaluate’, ‘design’, ‘engineer’, ‘construct’, ‘establish’
    ];

    function analyzeContent() {
    const content = document.getElementById(‘contentInput’).value.trim();
    if (!content) {
    alert(‘Please paste your article text first.’);
    return;
    }

    const analysis = performAnalysis(content);
    displayResults(analysis);
    }

    function clearContent() {
    document.getElementById(‘contentInput’).value = ”;
    document.getElementById(‘resultsContainer’).classList.remove(‘visible’);
    }

    function performAnalysis(content) {
    const sentences = content.match(/[^.!?]+[.!?]+/g) || [];
    const paragraphs = content.split(/nn+/).filter(p => p.trim());
    const words = content.toLowerCase().match(/bw+b/g) || [];

    const wordCount = words.length;
    const sentenceCount = sentences.length;
    const avgSentenceLength = wordCount / sentenceCount;

    // Unique concepts (words >4 chars appearing 1-2 times)
    const wordFreq = {};
    words.forEach(word => {
    if (word.length > 4) {
    wordFreq[word] = (wordFreq[word] || 0) + 1;
    }
    });
    const uniqueConcepts = Object.values(wordFreq).filter(count => count {
    if (numberRegex.test(sent)) claimCount++;
    });
    const claimDensity = (claimCount / sentenceCount) * 100;

    // Filler ratio
    let fillerCount = 0;
    sentences.forEach(sent => {
    if (fillerPhrases.some(phrase => sent.toLowerCase().includes(phrase))) {
    fillerCount++;
    }
    });
    const fillerRatio = (fillerCount / sentenceCount) * 100;

    // Actionable insight score
    let actionCount = 0;
    sentences.forEach(sent => {
    if (actionVerbs.some(verb => sent.toLowerCase().includes(verb))) {
    actionCount++;
    }
    });
    const actionScore = (actionCount / sentenceCount) * 100;

    // Jargon density (rough estimate)
    const jargonTerms = words.filter(word => word.length > 7).length;
    const jargonDensity = (jargonTerms / wordCount) * 100;

    // Overall density score
    let densityScore = Math.round(
    (conceptDensity * 0.25) +
    (claimDensity * 0.25) +
    ((100 – fillerRatio) * 0.20) +
    (actionScore * 0.20) +
    (Math.min(jargonDensity, 15) * 0.10)
    );
    densityScore = Math.max(0, Math.min(100, densityScore));

    // Analyze paragraphs
    const paragraphAnalysis = paragraphs.map(para => {
    const paraSentences = para.match(/[^.!?]+[.!?]+/g) || [];
    const paraWords = para.toLowerCase().match(/bw+b/g) || [];
    const paraNumbers = para.match(/d+|percent|%/g) || [];
    const paraFiller = paraSentences.filter(sent =>
    fillerPhrases.some(phrase => sent.toLowerCase().includes(phrase))
    ).length;

    const density = (paraNumbers.length + paraWords.length / 10) / paraSentences.length;
    const fillerPercent = (paraFiller / paraSentences.length) * 100;

    let densityClass = ‘dense’;
    if (fillerPercent > 30 || density 15 || density 150 ? ‘…’ : ”),
    density: densityClass
    };
    });

    return {
    densityScore,
    wordCount,
    sentenceCount,
    avgSentenceLength: avgSentenceLength.toFixed(1),
    conceptDensity: conceptDensity.toFixed(1),
    claimDensity: claimDensity.toFixed(1),
    fillerRatio: fillerRatio.toFixed(1),
    actionScore: actionScore.toFixed(1),
    jargonDensity: jargonDensity.toFixed(1),
    paragraphs: paragraphAnalysis
    };
    }

    function displayResults(analysis) {
    // Score
    document.getElementById(‘densityScore’).textContent = analysis.densityScore;
    document.getElementById(‘gaugeFill’).style.width = analysis.densityScore + ‘%’;

    // Metrics
    const metricsHTML = `

    ${analysis.wordCount}
    Total Words

    ${analysis.sentenceCount}
    Sentences

    ${analysis.avgSentenceLength}
    Avg Sentence Length

    ${analysis.conceptDensity}%
    Unique Concepts per 100W

    ${analysis.claimDensity}%
    Claim Density

    ${analysis.fillerRatio}%
    Filler Ratio

    ${analysis.actionScore}%
    Action Verbs

    ${analysis.jargonDensity}%
    Jargon Density

    `;
    document.getElementById(‘metricsGrid’).innerHTML = metricsHTML;

    // Heatmap
    const heatmapHTML = analysis.paragraphs
    .map(para => `

    ${para.text}

    `)
    .join(”);
    document.getElementById(‘heatmapContainer’).innerHTML = heatmapHTML;

    // Insights
    let likelihood;
    if (analysis.densityScore >= 75) {
    likelihood = ‘This content is highly likely to be selected as an AI source. You have excellent unique concept density, strong claim coverage, and minimal filler.’;
    } else if (analysis.densityScore >= 60) {
    likelihood = ‘This content has good density and will likely be cited by AI systems. Consider reducing filler phrases and increasing actionable insights.’;
    } else if (analysis.densityScore >= 40) {
    likelihood = ‘Your content is moderately dense. AI may cite specific sections, but overall improvement would help. Focus on claims, actions, and uniqueness.’;
    } else {
    likelihood = ‘This content lacks the density AI systems prefer. Too many filler phrases, weak claim coverage, and low concept variety reduce citation likelihood.’;
    }
    document.getElementById(‘aiLikelihood’).textContent = likelihood;

    let benchmark;
    if (analysis.fillerRatio > 20) {
    benchmark = ‘Your filler ratio is above benchmark. AI-citable content typically has <15% filler phrases.';
    } else if (analysis.claimDensity 8) {
    benchmark = ‘Excellent unique concept density. This makes your content more likely to be selected as a source.’;
    } else {
    benchmark = ‘Your metrics align well with top-cited content benchmarks across most dimensions.’;
    }
    document.getElementById(‘benchmark’).textContent = benchmark;

    document.getElementById(‘resultsContainer’).classList.add(‘visible’);
    document.getElementById(‘resultsContainer’).scrollIntoView({ behavior: ‘smooth’ });
    }

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Information Density Analyzer: Is Your Content Dense Enough for AI?”,
    “description”: “Paste your article text and get real-time analysis of information density, filler ratio, claim density, and AI-citability score.”,
    “datePublished”: “2026-04-01”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/information-density-analyzer/”
    }
    }

    Visual summary

    Editorial illustration for Information Density Analyzer: Is Your Content Dense Enough for AI? - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for Information Density Analyzer: Is Your Content Dense Enough for AI?. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • AI Music Pipeline: 20 Songs in One Session with Claude

    AI Music Pipeline: 20 Songs in One Session with Claude

    The Lab · Tygart Media
    Experiment Nº 603 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    I wanted to test a question that’s been nagging me since I started building autonomous AI pipelines: how far can you push a creative workflow before the quality falls off a cliff?

    The answer, it turns out, is further than I expected — but the cliff is real, and knowing where it is matters more than the output itself.

    The Experiment: Zero Human Edits, 20 Songs, 19 Genres

    Three stacked layers: chat UI, tools, agent runtime
    The experiment — zero human edits, 20 songs, 19 genres.

    The setup was straightforward in concept and absurdly complex in execution. I gave Claude one instruction: generate original songs using Producer.ai, analyze each one with Gemini 2.0 Flash, create custom artwork with Imagen 4, build a listening page with a custom audio player, publish it to this site, update the music hub, log everything to Notion, and then loop back and do it again.

    The constraint that made it real: Claude had to honestly assess quality after every batch and stop when diminishing returns hit. No padding the catalog with filler. No claiming mediocre output was good. The stakes had to be real or the whole experiment was theater.

    Over the course of one extended session, the pipeline produced 20 original tracks spanning 19 distinct genres — from heavy metal to bossa nova, punk rock to Celtic folk, ambient electronic to gospel soul.

    How the Pipeline Actually Works

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    How the pipeline actually works.

    Each song passes through a 7-stage autonomous pipeline with zero human intervention between stages:

    1. Prompt Engineering — Claude crafts a genre-specific prompt designed to push Producer.ai toward authentic instrumentation and songwriting conventions for that genre, not generic “make a song in X style” requests.
    2. Generation — Producer.ai generates the track. Claude navigates the interface via browser automation, waits for generation to complete, then extracts the audio URL from the page metadata.
    3. Audio Conversion — The raw m4a file is downloaded and converted to MP3 at 192kbps for the full version, plus a trimmed 90-second version at 128kbps for AI analysis.
    4. Gemini 2.0 Flash Analysis — The trimmed audio is sent to Google’s Gemini 2.0 Flash model via Vertex AI. Gemini listens to the actual audio and returns a structured analysis: song description, artwork prompt suggestion, narrative story, and thematic elements.
    5. Imagen 4 Artwork — Gemini’s artwork prompt feeds into Google’s Imagen 4 model, which generates a 1:1 album cover. Each cover is genre-matched — moody neon for synthwave, weathered wood textures for Appalachian folk, stained glass for gospel soul.
    6. WordPress Publishing — The MP3 and artwork upload to WordPress. Claude builds a complete listening page with a custom HTML/CSS/JS audio player, genre-specific accent colors, lyrics or composition notes, and the AI-generated story. The page publishes as a child of the music hub.
    7. Hub Update & Logging — The music hub grid gets a new card with the artwork, title, and genre badge. Everything logs to Notion for the operational record.

    The entire stack runs on Google Cloud — Vertex AI for Gemini and Imagen 4, authenticated via service account JWT tokens. WordPress sits on a GCP Compute Engine instance. The only external dependency is Producer.ai for the actual audio generation.

    The 20-Song Catalog

    You can listen to every track on the Tygart Media Music Hub. Here’s the full catalog with genre and a quick take on each:

    # Title Genre Assessment
    1Anvil and EmberBlues RockStrong opener — gritty, authentic tone
    2Neon CathedralSynthwave / DarkwaveAtmospheric, genre-accurate production
    3Velvet FrequencyTrip-HopMoody, textured, held together well
    4Hollow BonesAppalachian FolkTop 3 — haunting, genuine folk storytelling
    5Glass LighthouseDream Pop / Indie PopShimmery, the lightest track in the catalog
    6Meridian LineOrchestral Hip-HopSurprisingly cohesive genre fusion
    7Salt and CeremonyGospel SoulWarm, emotionally grounded
    8Tide and TimberRoots ReggaeLaid-back, authentic reggae rhythm
    9Paper LanternsBossa NovaGentle, genuine Brazilian feel
    10Burnt Bridges, Better ViewsPunk RockTop 3 — raw energy, real punk attitude
    11Signal DriftAmbient ElectronicSpacious instrumental, no lyrics needed
    12Gravel and GraceModern CountrySolid modern Nashville sound
    13Velvet HoursNeo-Soul R&BVocal instrumental — texture over lyrics
    14The Keeper’s LanternCeltic FolkTop 3 — strong closer, unique sonic palette

    Plus 6 earlier experimental tracks (Iron Heart variations, Iron and Salt, The Velvet Pour, Rusted Pocketknife) that preceded the formal pipeline and are also on the hub.

    Where Quality Held Up — and Where It Didn’t

    The pipeline performed best on genres with strong structural conventions. Blues rock, punk, folk, country, and Celtic music all have well-defined instrumentation and songwriting patterns that Producer.ai could lock into. The AI wasn’t inventing a genre — it was executing within one, and the results were genuinely listenable.

    The weakest output came from genres that rely on subtlety and human nuance. The neo-soul track (Velvet Hours) ended up as a vocal instrumental — beautiful textures, but no real lyrical content. It felt more like a mood than a song. The synthwave track was competent but slightly generic — it hit every synth cliché without adding anything distinctive.

    The biggest surprise was Meridian Line (Orchestral Hip-Hop). Fusing a full orchestral arrangement with hip-hop production is hard for human producers. The AI pulled it off with more coherence than I expected.

    The Honest Assessment: Why I Stopped at 20

    After 14 songs in the formal pipeline (plus the 6 experimental tracks), I evaluated what genres remained untapped. The answer was ska, reggaeton, polka, zydeco — genres that would have been novelty picks, not genuine catalog additions. Each of the 19 genres I covered brought a distinctly different sonic palette, vocal style, and emotional register. Song 20 was the right place to stop because Song 21 would have been padding.

    This is the part that matters for anyone building autonomous creative systems: the quality curve isn’t linear. You don’t get steadily worse output. You get strong results across a wide range, and then you hit a wall where the remaining options are either redundant (too similar to something you already made) or contrived (genres you’re forcing because they’re different, not because they’re good).

    Knowing where that wall is — and having the system honestly report it — is the difference between a useful pipeline and a content mill.

    What This Means for AI-Driven Creative Work

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What this means for AI-driven creative work.

    This experiment wasn’t about proving AI can replace musicians. It can’t. Every track in this catalog is a competent execution of genre conventions — but none of them have the idiosyncratic human choices that make music genuinely memorable. No AI song here will be someone’s favorite song.

    What the experiment does prove is that the full creative pipeline — from ideation through production, analysis, visual design, web publishing, and catalog management — can run autonomously at a quality level that’s functional and honest about its limitations.

    The tech stack that made this possible:

    • Claude — Pipeline orchestration, prompt engineering, quality assessment, web publishing, and the decision to stop
    • Producer.ai — Audio generation from text prompts
    • Gemini 2.0 Flash — Audio analysis (it actually listened to the MP3 and described what it heard)
    • Imagen 4 — Album artwork generation from Gemini’s descriptions
    • Google Cloud Vertex AI — API backbone for both Gemini and Imagen 4
    • WordPress REST API — Direct publishing with custom HTML listening pages
    • Notion API — Operational logging for every song

    Total cost for the entire 20-song catalog: a few dollars in Vertex AI API calls. Zero human edits to the published output.

    Listen for Yourself

    The full catalog is live on the Tygart Media Music Hub. Every track has its own listening page with a custom audio player, AI-generated artwork, the story behind the song, and lyrics (or composition notes for instrumentals). Pick a genre you like and judge for yourself whether the pipeline cleared the bar.

    The honest answer is: it cleared it more often than it didn’t. And knowing exactly where it didn’t is the most valuable part of the whole experiment.

    Visual summary

    Editorial illustration for I Let Claude Build a 20-Song Music Catalog in One Session — Here’s What Happened - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for I Let Claude Build a 20-Song Music Catalog in One Session — Here’s What Happened. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.
  • Human Knowledge Distillery: Extracting Tacit Expertise

    Human Knowledge Distillery: Extracting Tacit Expertise

    The Lab · Tygart Media
    Experiment Nº 504 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    I’ve been building Tygart Media for a while now, and I’ve always struggled to explain what we actually do. Not because the work is complicated — it’s not. But because the thing we do doesn’t have a clean label yet.

    We’re not a content agency. We’re not a marketing firm. We’re not an SEO shop, even though SEO is part of what happens. Those are all descriptions of outputs, and they miss the thing underneath.

    The Moment It Clicked

    I was working with a client recently — a business owner who has spent 20 years building expertise in his industry. He knows things that nobody else knows. Not because he’s secretive, but because that knowledge lives in his head, in his gut, in the way he reads a situation and makes a call. It’s tacit knowledge. The kind you can’t Google.

    My job wasn’t to write blog posts for him. My job was to extract that knowledge, organize it, structure it, and put it into a format that could actually be used — by his team, by his customers, by AI systems, by anyone who needs it.

    That’s when I realized: Tygart Media is a human knowledge distillery.

    What a Knowledge Distillery Does

    Think about what a distillery actually does. You take raw material — grain, fruit, whatever — and you run it through a process that extracts the essence. You remove the noise. You concentrate what matters. And you put it in a form that can be stored, shared, and used.

    That’s exactly what we do with human expertise. Every business leader, every subject matter expert, every operator who has been doing this work for years — they are sitting on enormous reserves of knowledge that is trapped. It’s trapped in their heads, in their habits, in their decision-making patterns. It’s not written down. It’s not structured. It can’t be searched, referenced, or built upon by anyone else.

    We extract it. We distill it. We put it into structured formats — articles, knowledge bases, structured data, content architectures — that make it usable.

    The Media Is the Knowledge

    Here’s the shift that changed everything for me: the word “media” in Tygart Media doesn’t mean content. It means medium — as in, the thing through which knowledge travels.

    When we publish an article, we’re not creating content for content’s sake. We’re creating a vessel for knowledge that was previously locked inside someone’s brain. The article is just the delivery mechanism. The real product is the structured intelligence underneath it.

    Every WordPress post we publish, every schema block we inject, every entity we map — those are all expressions of distilled knowledge being put into circulation. The websites aren’t marketing channels. They’re knowledge infrastructure.

    Content as Data, Not Decoration

    Most agencies look at content and see marketing material. We look at content and see data. Every piece of content we create is structured, tagged, embedded, and connected to a larger knowledge graph. It’s not sitting in a silo waiting for someone to stumble across it — it’s part of a living system that AI can read, search engines can parse, and humans can navigate.

    When you start treating content as data and knowledge rather than decoration, everything changes. You stop asking “what should we blog about?” and start asking “what does this organization know that nobody else does, and how do we make that knowledge accessible to every system that could use it?”

    Where This Goes

    Right now, we run our own operations out of this distilled knowledge. We manage 27+ WordPress sites across wildly different industries — restoration, luxury lending, cold storage, comedy streaming, veterans services, and more. Every one of those sites is a node in a knowledge network that gets smarter with every engagement.

    But here’s where it gets interesting. The distilled knowledge we’re building — stripped of personal information, structured for machine consumption — could become an open API. A knowledge layer that anyone could plug into. Your AI assistant, your search tools, your internal systems — they could all connect to the Tygart Brain and immediately get smarter about the domains we’ve mapped.

    That’s not a fantasy. The infrastructure already exists. We already have the knowledge pages, the embeddings, the structured data. The question isn’t whether we can open it up — it’s when.

    Some people call this democratizing knowledge. I just call it doing the obvious thing. If you’ve spent the time to extract, distill, and structure expertise across dozens of industries, why would you keep it locked in a private database? The whole point of a distillery is that what comes out is meant to be shared.

    What This Means for You

    If you’re a business leader sitting on years of expertise that’s trapped in your head — that’s the raw material. We can extract it, distill it, and turn it into a knowledge asset that works for you around the clock.

    If you’re someone who wants to build AI-powered tools or systems — eventually, you’ll be able to plug into a growing, curated knowledge network that’s been distilled from real human expertise. Not scraped. Not summarized. Distilled.

    Tygart Media isn’t a content agency that figured out AI. It’s a knowledge distillery that happens to express itself as content. That distinction matters, and I think it’s going to matter a lot more very soon.


    Frequently Asked Questions: What Tygart Media Does

    What exactly is Tygart Media and how is it different from a content agency?

    Tygart Media is a human knowledge distillery — not a content agency, marketing firm, or SEO shop. The distinction is what we’re working with: most agencies produce content from briefs. We extract tacit knowledge from business owners and subject matter experts, then structure that knowledge into formats that can be searched, referenced, built upon, and understood by both humans and AI systems. The content is a byproduct of the knowledge architecture, not the goal itself.

    What is tacit knowledge and why does it need to be distilled?

    Tacit knowledge is the expertise that lives in a person’s head, gut, and decision-making instincts — built over years of doing the work. It can’t be Googled because it’s never been written down. Most businesses are sitting on enormous reserves of this knowledge that is completely trapped: inaccessible to their teams, invisible to customers, and unreadable by AI systems. Distillation means extracting that expertise, organizing it, and putting it into structured formats that can actually be used.

    What does “AI-native” mean in the context of Tygart Media’s approach?

    AI-native means the content and knowledge architecture is designed from the start to be readable and citable by AI systems — not just search engines. This includes structured data markup, entity saturation, answer-optimized formatting, and content that AI models like Claude, ChatGPT, and Gemini can retrieve and reference when answering questions in their domain. An AI-native knowledge base works for human readers and AI readers simultaneously.

    Who is Tygart Media built for?

    Business owners and operators who have deep domain expertise and want it working harder for them. Typically: service businesses with complex offerings, founders who are the primary knowledge holders in their company, and operators in specialized industries (restoration, lending, healthcare, B2B services) where the expertise gap between the business and its customers is large. If you have 10+ years of experience that isn’t structured anywhere, you’re the target.

    What does a Tygart Media engagement actually produce?

    The outputs vary by engagement but typically include: a structured content architecture (categories, clusters, internal linking), long-form articles that capture and communicate domain expertise, AEO/GEO-optimized content designed for AI citation, schema markup for rich search results, and in some cases a full Notion-based knowledge base that functions as a second brain for the business. The goal is a knowledge system that compounds — not a content calendar that resets every month.

    Visual summary

    The Human Knowledge Distillery — Tygart Media extracts and distills tacit human expertise into structured knowledge infrastructure

    About this image. This image is part of the AI & Technology Concepts collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication — making each image discoverable, attributable, and optimized for both traditional search engines and AI systems.

    • Format: WEBP
    • Collection: AI & Technology Concepts
    • Pipeline: Vertex AI Imagen → WebP Conversion → IPTC/XMP Metadata Injection → WordPress Media Library
  • AI Knowledge Base Case Study: Building a Searchable Brain

    AI Knowledge Base Case Study: Building a Searchable Brain

    The Machine Room · Under the Hood

    The Problem Nobody Talks About: 200+ Episodes of Expertise, Zero Searchability

    Comparison of Claude how-to fit versus local service page fit for assistants
    The problem: hundreds of episodes of expertise with zero searchability.

    Here’s a scenario that plays out across every industry vertical: a consulting firm spends five years recording podcast episodes, livestreams, and training sessions. Hundreds of hours of hard-won expertise from a founder who’s been in the trenches for decades. The content exists. It’s published. People can watch it. But nobody — not the team, not the clients, not even the founder — can actually find the specific insight they need when they need it.

    That’s the situation we walked into six months ago with a client in a $250B service industry. A podcast-and-consulting operation with real authority — the kind of company where a single episode contains more actionable intelligence than most competitors’ entire content libraries. The problem wasn’t content quality. The problem was that the knowledge was trapped inside linear media formats, unsearchable, undiscoverable, and functionally invisible to the AI systems that are increasingly how people find answers.

    What We Actually Built: A Searchable AI Brain From Raw Content

    Four-stage funnel: citation, click, engage, convert
    What we actually built: a searchable AI brain from raw content.

    We didn’t build a chatbot. We didn’t slap a search bar on a podcast page. We built a full retrieval-augmented generation (RAG) system — an AI brain that ingests every piece of content the company produces, breaks it into semantically meaningful chunks, embeds each chunk as a high-dimensional vector, and makes the entire knowledge base queryable in natural language.

    The architecture runs entirely on Google Cloud Platform. Every transcript, every training module, every livestream recording gets processed through a pipeline that extracts metadata using Gemini, splits the content into overlapping chunks at sentence boundaries, generates 768-dimensional vector embeddings, and stores everything in a purpose-built database optimized for cosine similarity search.

    When someone asks a question — “What’s the best approach to commercial large loss sales?” or “How should adjusters handle supplement disputes?” — the system doesn’t just keyword-match. It understands the semantic meaning of the query, finds the most relevant chunks across the entire knowledge base, and synthesizes an answer grounded in the company’s own expertise. Every response cites its sources. Every answer traces back to a specific episode, timestamp, or training session.

    The Numbers: From 171 Sources to 699 in Six Months

    When we first deployed the knowledge base, it contained 171 indexed sources — primarily podcast episodes that had been transcribed and processed. That alone was transformative. The founder could suddenly search across years of conversations and pull up exactly the right insight for a client call or a new piece of content.

    But the real inflection point came when we expanded the pipeline. We added course material — structured training content from programs the company sells. Then we ingested 79 StreamYard livestream transcripts in a single batch operation, processing all of them in under two hours. The knowledge base jumped to 699 sources with over 17,400 individually searchable chunks spanning 2,800+ topics.

    Here’s the growth trajectory:

    Phase Sources Topics Content Types
    Initial Deploy 171 ~600 Podcast episodes
    Course Integration 620 2,054 + Training modules
    StreamYard Batch 699 2,863 + Livestream recordings

    Each new content type made the brain smarter — not just bigger, but more contextually rich. A query about sales objection handling might now pull from a podcast conversation, a training module, and a livestream Q&A, synthesizing perspectives that even the founder hadn’t connected.

    The Signal App: Making the Brain Usable

    A knowledge base without an interface is just a database. So we built Signal — a web application that sits on top of the RAG system and gives the team (and eventually clients) a way to interact with the intelligence layer.

    Signal isn’t ChatGPT with a custom prompt. It’s a purpose-built tool that understands the company’s domain, speaks the industry’s language, and returns answers grounded exclusively in the company’s own content. There are no hallucinations about things the company never said. There are no generic responses pulled from the open internet. Every answer comes from the proprietary knowledge base, and every answer shows you exactly where it came from.

    The interface shows source counts, topic coverage, system status, and lets users run natural language queries against the full corpus. It’s the difference between “I think Chris mentioned something about that in an episode last year” and “Here’s exactly what was said, in three different contexts, with links to the source material.”

    What’s Coming Next: The API Layer and Client Access

    Here’s where it gets interesting. The current system is internal — it serves the company’s own content creation and consulting workflows. But the next phase opens the intelligence layer to clients via API.

    Imagine you’re a restoration company paying for consulting services. Instead of waiting for your next call with the consultant, you can query the knowledge base directly. You get instant access to years of accumulated expertise — answers to your specific questions, drawn from hundreds of real-world conversations, case studies, and training materials. The consultant’s brain, available 24/7, grounded in everything they’ve ever taught.

    This isn’t theoretical. The RAG API already exists and returns structured JSON responses with relevance-scored results. The Signal app already consumes it. Extending access to clients is an infrastructure decision, not a technical one. The plumbing is built.

    And because every query and every source is tracked, the system creates a feedback loop. The company can see what clients are asking about most, identify gaps in the knowledge base, and create new content that directly addresses the highest-demand topics. The brain gets smarter because people use it.

    The Content Machine: From Knowledge Base to Publishing Pipeline

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The content machine: from knowledge base to publishing pipeline.

    The other unlock — and this is the part most people miss — is what happens when you combine a searchable AI brain with an automated content pipeline.

    When you can query your own knowledge base programmatically, content creation stops being a blank-page exercise. Need a blog post about commercial water damage sales techniques? Query the brain, pull the most relevant chunks from across the corpus, and use them as the foundation for a new article that’s grounded in real expertise — not generic AI filler.

    We built the publishing pipeline to go from topic to live, optimized WordPress post in a single automated workflow. The article gets written, then passes through nine optimization stages: SEO refinement, answer engine optimization for featured snippets and voice search, generative engine optimization so AI systems cite the content, structured data injection, taxonomy assignment, and internal link mapping. Every article published this way is born optimized — not retrofitted.

    The knowledge base isn’t just a reference tool. It’s the engine that feeds a content machine capable of producing authoritative, expert-sourced content at a pace that would be impossible with traditional workflows.

    The Bigger Picture: Why Every Expert Business Needs This

    This isn’t a story about one company. It’s a blueprint that applies to any business sitting on a library of expert content — law firms with years of case analysis podcasts, financial advisors with hundreds of market commentary videos, healthcare consultants with training libraries, agencies with decade-long client education archives.

    The pattern is always the same: the expertise exists, it’s been recorded, and it’s functionally invisible. The people who created it can’t search it. The people who need it can’t find it. And the AI systems that increasingly mediate discovery don’t know it exists.

    Building an AI brain changes all three dynamics simultaneously. The creator gets a searchable second brain. The audience gets instant, cited access to deep expertise. And the AI layer — the Perplexitys, the ChatGPTs, the Google AI Overviews — gets structured, authoritative content to cite and recommend.

    We’re building these systems for clients across multiple verticals now. The technology stack is proven, the pipeline is automated, and the results compound over time. If you’re sitting on a content library and wondering how to make it actually work for your business, that’s exactly the problem we solve.

    Frequently Asked Questions

    What is a RAG system and how does it differ from a regular chatbot?

    A retrieval-augmented generation (RAG) system is an AI architecture that answers questions by first searching a proprietary knowledge base for relevant information, then generating a response grounded in that specific content. Unlike a general chatbot that draws from broad training data, a RAG system only uses your content as its source of truth — eliminating hallucinations and ensuring every answer traces back to something your organization actually said or published.

    How long does it take to build an AI knowledge base from existing content?

    The initial deployment — ingesting, chunking, embedding, and indexing existing content — typically takes one to two weeks depending on volume. We processed 79 livestream transcripts in under two hours and 500+ podcast episodes in a similar timeframe. The ongoing pipeline runs automatically as new content is created, so the knowledge base grows without manual intervention.

    What types of content can be ingested into the AI brain?

    Any text-based or transcribable content works: podcast episodes, video transcripts, livestream recordings, training courses, webinar recordings, blog posts, whitepapers, case studies, email newsletters, and internal documents. Audio and video files are transcribed automatically before processing. The system handles multiple content types simultaneously and cross-references between them during queries.

    Can clients access the knowledge base directly?

    Yes — the system is built with an API layer that can be extended to external users. Clients can query the knowledge base through a web interface or via API integration into their own tools. Access controls ensure clients see only what they’re authorized to access, and every query is logged for analytics and content gap identification.

    How does this improve SEO and AI visibility?

    The knowledge base feeds an automated content pipeline that produces articles optimized for traditional search, answer engines (featured snippets, voice search), and generative AI systems (Google AI Overviews, ChatGPT, Perplexity). Because the content is grounded in real expertise rather than generic AI output, it carries the authority signals that both search engines and AI systems prioritize when selecting sources to cite.

    What does Tygart Media’s role look like in this process?

    We serve as the AI Sherpa — handling the full stack from infrastructure architecture on Google Cloud Platform through content pipeline automation and ongoing optimization. Our clients bring the expertise; we build the system that makes that expertise searchable, discoverable, and commercially productive. The technology, pipeline design, and optimization strategy are all managed by our team.

    Visual summary

    AI knowledge base case study — searchable brain dashboard and retrieval flow

    About this image. This image is part of the AI & Technology Concepts collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication — making each image discoverable, attributable, and optimized for both traditional search engines and AI systems.

    • Format: WEBP
    • Collection: AI & Technology Concepts
    • Pipeline: Vertex AI Imagen → WebP Conversion → IPTC/XMP Metadata Injection → WordPress Media Library
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress