Tag: AI Strategy

  • AI in the Trades: Why Judgment Is Your Career Moat

    AI in the Trades: Why Judgment Is Your Career Moat

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    There is a version of the AI transition story that gets told constantly, and it goes like this: AI will automate jobs, workers will be displaced, and the people who adapt will be the ones who learn to use AI tools. This version is not wrong exactly. It’s just missing the part that matters most for the people who actually work in the trades.

    The people who build things, fix things, assess damage, run field operations, and carry years of hard-won judgment in their bodies and their hands — these are not knowledge workers whose jobs can be uploaded to a language model. Their work requires physical presence, sensory intelligence, and the kind of contextual judgment that comes from doing something 500 times in conditions that were never twice the same.

    But the transition is real, and it’s happening around them whether they’re paying attention or not. The question isn’t whether AI changes the trades. It’s which trades workers end up on the right side of that change — and why.

    The answer is not “the ones who learn to code.” It’s not “the ones who get an AI certification.” It’s the ones who understand what AI can’t do without them, and position themselves as the irreplaceable layer between the intelligence and the outcome.

    That’s the Wire and Fire Guy. And the window to become one is shorter than most people realize.


    What the Wire and Fire Guy Actually Is

    In electrical work, the wire and fire guys are the experienced field technicians who come in after the rough work is done. They’re not project managers. They’re not estimators. They’re the people who look at what the system is supposed to do, look at what’s actually been installed, and bridge the gap between the plan and the physical reality. They troubleshoot. They adapt. They make judgment calls that no blueprint anticipated.

    The name is an archetype, not a job title. It describes a class of worker who exists in every trades field: the senior technician in water damage who knows from the smell and the color of the staining that the timeline is longer than the moisture readings suggest. The fire restoration veteran who can read a smoke pattern and tell you which rooms were occupied and which weren’t before the alarm triggered. The field supervisor who looks at an estimate and spots the three line items that will blow up into supplements before the job starts.

    These people carry knowledge that cannot be extracted from documentation because it was never documented. It lives in their sensory memory, their accumulated pattern recognition, their feel for how this specific type of situation typically develops. AI systems trained on the documentation don’t have it. AI systems that have processed thousands of job files come closer but still don’t have the physical dimension — the reading of a space that happens in the first ten minutes of being in it.

    That knowledge — embodied, sensory, judgment-based — is the moat. And right now, most of the people who have it don’t know it’s a moat.


    The 18-Month Window

    Here is what is true right now, in April 2026: AI systems can write estimates. They can process moisture readings. They can identify scope items from photos. They can draft communications to adjusters. They can route jobs. They can flag outliers in a dataset of completed claims. They can do all of this faster and cheaper than a human doing the same work.

    Here is what is also true: every one of those AI outputs needs a human to verify it against physical reality before it becomes an action. The estimate needs someone on-site who can see what the AI couldn’t. The moisture readings need someone who can read the environment around the reading — the substrate, the airflow, the odor, the age of the damage. The scope items need someone who can look at the photo and then look at the actual wall and tell you what the photo didn’t capture.

    That verification layer — the human in the loop between the AI’s output and the physical world — is not going away. What is going away, over the next 18 to 36 months, is everything on the other side of that line. The data entry. The scheduling calls. The status updates. The form-filling. The paperwork that currently consumes a significant portion of every field technician’s non-field time.

    The technician who understands this transition has a clear path: move toward the verification layer, away from the data layer. Develop the judgment that makes the AI’s output trustworthy or correctable. Become the person the AI reports to, not the person doing the work the AI can do.

    The technician who doesn’t understand it will find their job slowly hollowed out — not eliminated suddenly, but compressed, devalued, and increasingly focused on the tasks that AI hasn’t gotten to yet, which is a shrinking list.


    Why Judgment Is the Moat

    Judgment is not the same as experience. Experience is a prerequisite for judgment but not a guarantee of it. Judgment is what happens when experience meets a situation that doesn’t match any template and produces a correct decision anyway.

    AI systems are template-matching engines at their core. They are extraordinarily good at situations that resemble situations in their training data. They fail — sometimes silently, which is worse — when the situation deviates from the distribution they’ve seen. A water damage job in a 1920s Craftsman with non-standard framing, original plaster walls, and an HVAC system that was retrofitted twice is a deviation. An AI trained on modern residential restoration data will produce an estimate and a timeline. A Wire and Fire Guy with 15 years of experience will look at the same job and know the estimate is wrong and the timeline is optimistic, because they’ve been inside enough 1920s Craftsmans to know what those walls hold.

    This is the moat. Not the ability to use an AI tool — that’s table stakes within 18 months. The ability to know when the AI tool is wrong, and why, and what to do about it instead. That requires the tacit knowledge that only physical experience builds. It cannot be trained into a model. It cannot be acquired from a certification. It grows from doing the work in conditions the documentation never anticipated, enough times to develop the pattern recognition that operates below conscious awareness.

    The trades worker who wants to be on the right side of the AI transition doesn’t need to compete with the AI on the AI’s terms. They need to become the irreplaceable layer between the AI’s output and the physical world. That layer is called judgment, and building it is a career strategy.


    The Context Layer as Job Security

    There is a more technical version of this argument, and it’s worth understanding even if you never write a line of code.

    AI systems are dramatically more useful when they have context — specific knowledge about the situation, the history, the people involved, and the standards that apply. A generic AI asked to write an estimate for a water damage job produces a generic estimate. An AI given the job address, the property age, the adjuster’s history with this contractor, the specific moisture readings, and the known quirks of the local building code produces something much better.

    The person who provides that context — who knows enough about the job to load the AI with the information that makes its output accurate — is not replaceable. They are, in fact, more valuable as AI systems get better, because better AI systems reward better context. The technician who can brief an AI the way a good editor briefs a writer — specific, accurate, anticipating the failure modes — gets dramatically better results than the technician who types a query and accepts whatever comes back.

    This is what “human in the loop” actually means in practice. It’s not a compliance checkbox. It’s the functional requirement that the AI’s output is verified, corrected, and contextualized by someone who has the embodied knowledge to know when it’s right and when it isn’t. That someone, in the trades, is the Wire and Fire Guy.


    From Field Tech to AI Supervisor: What the Career Path Looks Like

    This is not a story about leaving the trades. It’s a story about moving up the value stack within them.

    The field technician who wants to make this transition has three things to develop, in order of how quickly they compound:

    Domain depth first. The judgment moat requires genuine expertise. The technicians who end up in the verification layer are the ones who actually know the work at the level where deviation from documentation is visible and meaningful. This is built by doing the work, paying attention, and developing the habit of asking “why does this job look different from what the estimate anticipated?”

    AI literacy second. Not coding. Not machine learning theory. The practical ability to give an AI system a useful brief, evaluate its output for the specific failure modes common to your domain, and correct it with the context that changes the answer. This is learnable in weeks, not years, and it compounds quickly once the domain depth is in place to evaluate the output.

    Communication between the two layers third. The ability to translate between the physical world — what you’re seeing in the field — and the data layer that the AI operates on. This is partly documentation discipline (logging what you observe in terms that AI systems can use later) and partly the ability to communicate your corrections and their reasoning so the system improves over time rather than repeating the same errors.

    The career path is not: field tech → project manager → estimator → office. That path still exists but it’s compressing as AI handles more of what project managers and estimators do. The path that compounds in an AI-native industry is: field tech with deep domain knowledge → field tech who understands AI output → field supervisor who runs AI-assisted teams → operations role that owns the verification layer for a company’s AI systems.

    That last role doesn’t have a standard job title yet. In three years it will. The people who get those roles will be the ones who understood the transition early enough to position themselves correctly — and who built the judgment depth that no model can replicate.


    A Note on Pinto

    This is the article I wanted to write since we published the original Wire and Fire Guys piece. That piece named the archetype. This one tries to give it a career map.

    Pinto — who handles the infrastructure layer in this operation, the GCP deployments, the Cloud Run services, the database architecture — is the Wire and Fire Guy of AI infrastructure. He doesn’t just run the code. He understands what it’s supposed to do, sees when it deviates from that, and bridges the gap between the plan and the physical reality of production systems. The AI produces the output. Pinto verifies it against what the system is actually doing and knows why they differ.

    That’s the role. That’s the moat. The window to build it is open. It won’t be open forever.


    Frequently Asked Questions

    Does this apply outside the restoration industry?

    Yes. The Wire and Fire Guy archetype exists in every trades field and every industry where physical reality diverges from documentation. Construction, manufacturing, healthcare, agriculture, logistics — any field where experienced human judgment is applied to physical conditions that AI systems observe indirectly through data. The timeline and the specific skills differ by domain. The structure of the argument is the same.

    What’s the minimum AI literacy a trades worker needs to develop?

    Three things: the ability to give an AI system a specific, accurate brief for a task; the ability to evaluate the output for domain-specific failure modes (the things AI typically gets wrong in your industry); and the discipline to log corrections in a way that builds context over time rather than each correction being one-off. None of this requires programming knowledge. It requires domain expertise applied to a new kind of tool.

    How urgent is the 18-month window?

    The 18–36 month range is where most of the data entry, scheduling, and communication tasks that currently consume field technician time will be substantially automated in adoption-leading companies. The companies that adopt early set the new baseline for what’s competitive. Workers in those companies develop the verification-layer skills first and build the largest knowledge lead. The window is not a cliff — it’s a slope — but the slope is steeper now than it will be in three years when the transition is mostly complete in leading companies and everyone is catching up.

    What about union rules and job protections?

    Job protections can slow the transition but don’t reverse the value dynamics. The worker who has built genuine verification-layer expertise is more valuable whether or not the AI transition is delayed by contract. And the worker who hasn’t built it is less valuable on the same timeline. The protection is in the skill, not the rule.


    Wire and Fire: The AI Transition Career Cluster

    Related: The Human Distillery — the methodology for capturing the tacit knowledge this cluster describes.
  • Master LinkedIn AI Citations for 2026 GEO Strategy

    Master LinkedIn AI Citations for 2026 GEO Strategy

    Something significant shifted in the AI search landscape between November 2025 and February 2026, and most content strategists have not caught up to it yet.

    LinkedIn jumped from the 11th most-cited domain to the 5th most-cited domain on ChatGPT in just three months. Profound, which tracks 1.4 million AI citations across six platforms, called it “the largest shift in authority we have seen this year.” Across all AI platforms combined, LinkedIn content now appears in 11% of all AI-generated responses.

    If you publish professional content, this is the most important GEO development of 2026.

    The Numbers Behind the Shift

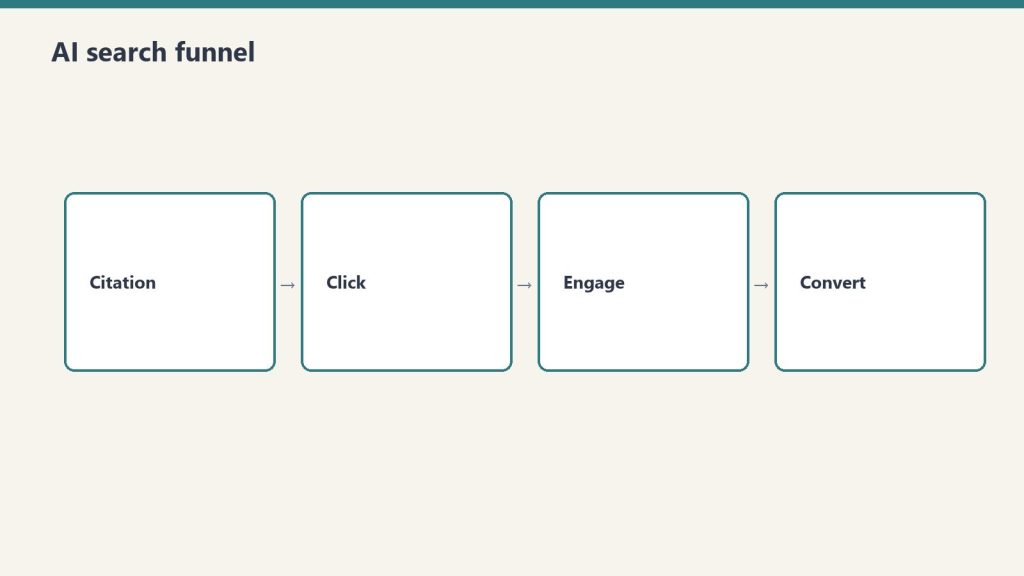
    Four-stage funnel: citation, click, engage, convert
    The numbers behind the LinkedIn citation shift.

    Semrush analyzed 325,000 prompts across ChatGPT Search, Google AI Mode, and Perplexity, identifying 89,000 unique LinkedIn URLs cited in AI-generated responses. The platform-by-platform breakdown:

    • ChatGPT Search: LinkedIn appears in 14.3% of all responses
    • Google AI Mode: LinkedIn appears in 13.5% of all responses
    • Perplexity: LinkedIn appears in 5.3% of all responses

    LinkedIn is now the #2 most-cited domain by AI systems overall and the #1 source for professional queries across every major AI platform including ChatGPT, Gemini, Perplexity, Google AI Mode, and Microsoft Copilot.

    What AI Systems Are Actually Citing

    Comparison of Claude how-to fit versus local service page fit for assistants
    What AI systems are actually citing.

    The composition of LinkedIn’s AI citations has shifted dramatically. Profile page citations — the static biographical data that dominated early LinkedIn citations — collapsed from 33.9% to just 14.5% of all LinkedIn citations in a three-month window. Meanwhile, posts and long-form articles grew from 26.9% to 34.9%.

    AI systems are not citing LinkedIn because of who you are. They are citing LinkedIn because of what you published.

    Of the 89,000 cited URLs in Semrush’s study, 50–66% are long-form Articles of 500–2,000 words, and 54–64% are educational or advice-driven content. The median cited post has just 15–25 reactions and roughly one comment. Engagement is not the primary driver of AI citation — relevance, accuracy, specificity, and structure are.

    Creators with fewer than 500 followers get cited at comparable rates to large accounts. This is not a follower game. It is a content quality and structure game.

    The Personal Profile vs Company Page Split

    One of the more strategically interesting findings from Profound’s study is that different AI platforms cite LinkedIn content differently by source type.

    ChatGPT and Google AI Mode favor personal profiles, drawing 59% of their LinkedIn citations from individual creator content versus 41% from company pages. Perplexity reverses this, drawing 59% of its LinkedIn citations from company pages and 41% from personal profiles.

    The strategic implication is a dual-publishing approach. Publishing technical and educational content on both a personal profile and a company page maximizes AI visibility across all major platforms simultaneously. They are not redundant — they are complementary, each feeding different AI citation systems.

    Why LinkedIn Content Gets Cited: The Structural Reasons

    LinkedIn’s relationship with AI systems operates through multiple channels that reinforce each other.

    First, LinkedIn content has always been publicly indexed and high-authority. With a Moz Domain Authority of 98, LinkedIn Pulse articles sit in the same crawlability tier as Wikipedia and major news publications. AI training datasets over-index on high-authority domains, meaning LinkedIn content has been proportionally well-represented in model training from the beginning.

    Second, LinkedIn rolled out a “Data for Generative AI Improvement” toggle in September 2024, set to ON by default, and expanded it to global markets in November 2025. LinkedIn is owned by Microsoft, which has a direct relationship with OpenAI. The structural pipeline from LinkedIn content to AI model training is more direct than almost any other platform.

    Third, LinkedIn content shows semantic similarity scores of 0.57–0.60 with AI-generated outputs, higher than Reddit (0.53–0.54) or Quora (0.44). AI systems are not just citing LinkedIn — they are drawing heavily on LinkedIn’s language patterns and reasoning structures when generating responses.

    What This Means for B2B and Restoration Industry Content

    For professional verticals — B2B services, restoration, real estate, finance, healthcare — LinkedIn is no longer an optional distribution channel. It is likely the single highest-leverage GEO publishing surface available.

    A structured LinkedIn Article on a technical topic in the restoration industry, AI strategy, or B2B services has a realistic path to being cited in ChatGPT, Perplexity, and Google AI Mode responses on relevant professional queries. It does not require a large following. It does not require viral engagement. It requires content that is accurate, structured, specific, and educational.

    Content reaches peak AI citation velocity 7–14 days after publishing and maintains that velocity for 90 or more days — significantly longer than Twitter/X or Reddit content, which cycles out of AI citation windows much faster.

    The Practical GEO Framework

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The practical GEO framework.

    Based on the citation data, the content signals that drive AI citation on LinkedIn are consistent and actionable: include specific data points, metrics, methodologies, and dates rather than generic claims. Use clear H2 heading structure that AI systems can parse for answer extraction. Write educational and advice-driven content rather than promotional content. Target 800–1,200 words per Article — long enough to establish depth, short enough to maintain density.

    The biggest opportunity right now is that most LinkedIn publishers are still optimizing for feed engagement — reactions, comments, shares. The AI citation data suggests a different optimization target: structured, data-rich, educational long-form content that looks less like a viral feed post and more like a well-sourced reference document.

    The brands and individuals who make that shift in 2026 are building citation authority that will compound for years.

    Related on Tygart Media: LinkedIn content strategy · GEO tactics · AI citation monitoring.

    Frequently Asked Questions

    Is LinkedIn the most cited source in AI search?

    LinkedIn is the #2 most-cited domain by AI systems overall and #1 for professional queries across ChatGPT, Gemini, Perplexity, Google AI Mode, and Copilot as of early 2026, appearing in approximately 11% of all AI-generated responses.

    What type of LinkedIn content gets cited by AI systems?

    50–66% of AI-cited LinkedIn content is long-form Articles of 500–2,000 words. Educational and advice-driven content accounts for 54–64% of citations. The median cited post has only 15–25 reactions — engagement is not the primary driver of AI citation.

    Does LinkedIn company page content get cited by AI?

    Yes. Perplexity draws 59% of its LinkedIn citations from company pages. ChatGPT and Google AI Mode favor personal profiles at 59%. A dual-publishing strategy covering both maximizes visibility across all AI platforms.

    How long does it take for LinkedIn content to appear in AI citations?

    LinkedIn content reaches peak AI citation velocity 7–14 days after publishing and maintains that velocity for 90 or more days — longer than most other social platforms.

  • AI Extraction Agent: Replacing the Human Interviewer

    AI Extraction Agent: Replacing the Human Interviewer

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    The extraction protocol works. The pivot signal lexicon is learnable. The four-layer descent can be taught. The question is whether it can be deployed without a trained human interviewer in the room — and if so, how much of the value survives the translation.

    This is the duplication problem at the center of the Human Distillery business model. Will can run an extraction session. An app cannot run the same session. But an app can run a version of the session — and for a large subset of extraction use cases, the version is sufficient.

    Understanding what transfers and what doesn’t is the whole architectural question.

    What Transfers to an App

    The four-layer question structure is codifiable. A stateful conversational agent — not a chatbot, a system that maintains a running knowledge map of what’s been surfaced and what’s still needed — can execute the question sequences in order, navigate the domain-specific question libraries for a given vertical, and detect the linguistic markers of pivot signals in real time.

    “It’s hard to explain” is detectable by NLP. Hedging patterns are detectable. Energy shifts in voice are detectable by acoustic analysis. Deflection to process — “the policy says…” — is detectable. The app can recognize these signals and adjust its question path, slowing down at tacit knowledge boundaries and applying the correct follow-up from the signal response library.

    The processing pipeline from transcript to structured concentrate is fully automatable: chunking by topic boundary, entity extraction, claim isolation, confidence scoring, contradiction flagging across multiple sessions, multi-model distillation rounds. This is where AI earns its keep. A human doing this manually would take days per session. The pipeline does it in minutes.

    Domain-specific question libraries can be built from prior extractions and expanded with each new session. The more sessions the app runs in a given vertical, the richer its question library becomes. This is the compounding effect that makes the app more valuable over time.

    What Doesn’t Transfer

    Three things resist automation in ways that won’t be resolved by better models:

    Micro-hesitation reading. The half-second pause before an answer that signals the subject knows more than they’re about to say. The slight change in phrasing when someone moves from what they’re comfortable saying to what they actually think. These are real-time, embodied, relational signals. A text-based app misses them entirely. A voice app gets closer but still lacks the visual channel that carries a significant portion of this information.

    Protocol abandonment. The decision to stop following the four-layer sequence because the subject just said something unprompted that is more important than anything in the protocol. Expert interviewers make this call constantly. They recognize the thread that, if followed, goes somewhere the protocol would never reach. An app will follow the signal response library. It won’t recognize when the library should be put down.

    Trust calibration. Whether the subject is performing for the recording or actually sharing. This is not detectable from content analysis. It requires the social intelligence to know when to lower the formality, when to match the subject’s energy, when to say something self-deprecating to signal that this is a peer conversation and not an evaluation. Subjects share differently with someone they trust. The app cannot build that trust.

    The Honest Architecture

    The tiered model that emerges from this analysis:

    Tier 1 — App-led extraction. Well-mapped domains with accessible knowledge. The subject is cooperative. The question library is deep. The knowledge being sought is in Layers 1 and 2. The app handles the session. Will reviews the concentrate before delivery.

    Tier 2 — Human-led extraction with app processing. High-stakes sessions. Guarded subjects. Knowledge at the outer edge of verbalization (Layer 3 and 4). Will conducts the session. The app runs the processing pipeline. Will reviews and approves the concentrate.

    Tier 3 — Full human extraction and distillation. Strategic engagements. Subjects who will only speak candidly to a person they know. Knowledge so embedded that it requires real-time relational judgment to surface at all. Will does everything.

    The business model implication: Tier 1 is volume. Tier 3 is premium. The ratio shifts over time as the app’s question libraries deepen and its signal detection improves. What begins as mostly Tier 2 and 3 eventually becomes mostly Tier 1, with Will’s direct involvement reserved for the sessions where only a human can get the door open.

    The app is not a replacement for the protocol. It’s a multiplier for the protocol — allowing it to run at a scale that a single human operator never could, while preserving the human layer for the cases that actually require it.


  • Knowledge Concentrate: 5 Core Components for AI Systems

    Knowledge Concentrate: 5 Core Components for AI Systems

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    A transcript is not a knowledge artifact. Neither is a summary. Both are containers for words. Neither is optimized for the thing that needs to consume them.

    When you capture an expert’s knowledge and then feed the transcript to an AI system, the AI gets the words. It does not get the structure. It does not know which claims are firsthand vs. secondhand. It cannot distinguish a confident assertion from a hedged one. It has no way to chain the decision logic — the “when X, do Y because Z” sequences that constitute the operational core of what the expert knows. It just has a long document full of things that may or may not be true, with no metadata to tell it which is which.

    This is why most knowledge capture projects fail to deliver on their promise. The content is there. The structure that makes it usable isn’t.

    A knowledge concentrate is the alternative. It is the distilled, structured artifact produced by the Human Distillery extraction protocol — smaller than a transcript, denser than any summary, and specifically formatted for the AI systems that will consume it.

    The Five Components of a Knowledge Concentrate

    1. The Entity Graph

    Every named concept, process, role, piece of equipment, regulation, and decision point that surfaces in extraction gets represented as a node. The edges between nodes are typed: causal, conditional, hierarchical, associative. The graph is not a list — it’s a map of relationships, and the relationships are the knowledge.

    An AI system with a list of entities knows vocabulary. An AI system with an entity graph knows how the domain works — how a change in one thing propagates to another, which concepts are upstream of which decisions, which relationships are conditional and which are structural.

    For a water damage restoration operation: the graph connects moisture readings to drying equipment selection to drying time estimates to invoice amounts to adjuster response patterns. None of those connections are in the documentation. All of them are in the head of a senior project manager who has run 400 jobs.

    2. Decision Logic

    The most directly usable component of the concentrate. Every when-then-because statement extracted from the session, structured as:

    • Condition: When this situation is present
    • Action: This is what we do
    • Because: This is why (the reasoning, not just the rule)
    • Exceptions: The cases where this breaks down
    • Confidence score: 0.0–1.0, based on how many independent sources confirmed it

    The “because” is what makes this different from a policy. A policy says do Y. A knowledge concentrate says do Y because Z, which means an AI system can recognize when Z is absent and adjust accordingly — rather than applying the rule in cases where the underlying condition that made the rule sensible doesn’t apply.

    The exceptions are equally important. Expert judgment is largely the accumulation of exceptions — the cases where the standard answer is wrong. Capturing those is the whole point of Layer 2 extraction.

    3. Benchmarks

    Every number that surfaces in extraction: thresholds, timelines, costs, rates, ratios, counts. Stored with context, source count, and variance.

    A benchmark from a single extraction session has low confidence. The same benchmark confirmed by six independent subjects in the same domain and market has high confidence and is ready to be used as ground truth in an AI system’s reasoning. The concentrate tracks the difference.

    This is the component that makes the concentrate valuable as a competitive intelligence product. The numbers in an industry that everyone knows but nobody has published — the real margin thresholds, the actual response time expectations, the price per square foot that experienced operators actually charge vs. what appears in public pricing guides — these exist only in people’s heads. The concentrate captures them with provenance.

    4. Tacit Signatures

    The things that are hard to explain. Captured as best as they can be verbalized, with a confidence flag.

    A tacit signature sounds like: “The drywall feels wrong before the moisture meter confirms it.” Or: “You can tell within the first five minutes of a call whether the adjuster is going to be cooperative or difficult, and it’s not anything specific they say.” These are not mysticism. They are pattern recognition operating below the level of conscious articulation — real knowledge that has never been verbalized because no one asked slowly enough.

    The confidence flag on tacit signatures signals to the consuming AI: this is approximate. This is the residue of knowledge the extraction process got close to but couldn’t fully surface. Don’t treat it as ground truth. Treat it as a signal that this is where human judgment is concentrated, and flag it for human review when it’s relevant.

    5. Provenance

    Traceable but anonymized. For every claim in the concentrate: how many independent sources confirmed it, what their roles were, what domain and market the data came from, and whether the claim is individual knowledge or cross-validated pattern.

    Provenance is what makes the concentrate auditable. An AI system that gives an answer based on a knowledge concentrate should be able to say: this answer comes from claim X, which was confirmed by three independent subjects with 10+ years of experience in this domain. That’s a very different epistemic standing than “I was trained on this.”

    The Density Test

    A useful heuristic for evaluating whether you have a transcript, a summary, or a true knowledge concentrate:

    A transcript contains everything that was said. It’s large, raw, and unstructured. An AI can search it but cannot reason from it efficiently.

    A summary contains the main points. It’s smaller. It has lost specificity, exceptions, confidence information, and relationships. It’s optimized for human reading, not AI consumption.

    A knowledge concentrate is smaller than the summary in tokens but larger in information. It contains relationships the summary dropped. It contains confidence scores the summary didn’t capture. It contains decision logic the summary flattened into assertions. An AI system can reason from it, not just retrieve from it.

    If what you have could be produced by someone reading a transcript and taking notes, it’s a summary. A knowledge concentrate requires the extraction protocol — it can only be produced from a session where the tacit layer was deliberately surfaced.


  • Tacit Knowledge Extraction for AI: The Human Distillery

    Tacit Knowledge Extraction for AI: The Human Distillery

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    Every organization has two kinds of knowledge. The documented kind — processes, policies, SOPs, training materials — lives in manuals and wikis. The other kind lives in people’s heads: the adjustments made without thinking, the thresholds learned from expensive mistakes, the pattern recognition that executes in a second but couldn’t survive a PowerPoint slide.

    The first kind is easy to feed into an AI system. The second kind is what makes the organization actually work. And it almost never gets captured before it walks out the door.

    This gap — between what’s written and what’s known — is where most enterprise AI implementations quietly fail. The system gets the documentation. It never gets the knowledge. The result is an AI that gives the same answer a new employee would give, while the 15-year veteran shakes their head and does it differently.

    The Human Distillery methodology exists to close that gap. It is a structured extraction protocol for converting tacit knowledge into dense, structured artifacts — books for bots — that AI systems can actually use. Not summaries. Not transcripts. Knowledge concentrates: information-rich artifacts that encode relationships, decision logic, and confidence alongside the facts themselves.

    This article is the methodology reference. It covers what tacit knowledge is and why it resists standard capture methods, the four-layer extraction protocol that surfaces it, the pivot signal lexicon that tells you when you’re close, what a knowledge concentrate looks like as a structured artifact, and where human judgment remains irreplaceable in the pipeline.


    Why Standard Methods Don’t Work

    The instinct when trying to capture organizational knowledge is to reach for one of three tools: a survey, an interview, or a documentation request. All three fail at tacit knowledge for the same reason: they ask people what they know. Tacit knowledge is knowledge people don’t know they know. It operates below the level of conscious articulation. You cannot survey it out of someone. You cannot ask them to write it down. You have to create the conditions under which it surfaces — and then recognize it when it does.

    Forms and surveys capture what people think they do. Conversations capture what they actually do and why. The difference between those two things is the entire product.

    A 20-year insurance adjuster asked “what’s your process for evaluating a water damage claim?” will give you the documented version: inspect the loss, review the policy, scope the damage, issue the estimate. This is accurate and useless. Ask them about a claim that went sideways and they will, unprompted, tell you that they always check the crawlspace first on older properties in this zip code because the contractor community there has a pattern of scope creep on foundation moisture that the initial inspection never catches. That’s the knowledge. It lives in the deviation from the process, not the process itself.


    The Four-Layer Descent

    The extraction protocol descends through four distinct layers in sequence. Each layer unlocks the next. Skipping a layer produces thin output. Rushing a layer produces performed output. The full descent, executed correctly, surfaces knowledge the subject didn’t know they were carrying.

    Phase 0: Disarmament

    Before any extraction begins, the status dynamic has to be neutralized. The subject needs to stop performing expertise for an evaluator and start explaining their world to a curious outsider. The difference in what comes out is dramatic.

    The disarmament move: position yourself as someone who genuinely doesn’t know. “I’ve never seen a job like this — walk me through it like I’m shadowing you.” This does two things. It forces explanation of steps the subject considers so obvious they wouldn’t otherwise mention — which is exactly where embedded knowledge concentrates. And it signals that there’s no correct answer being evaluated, which reduces the filtering that kills tacit knowledge capture.

    Open with failure. “Tell me about a job that went sideways” surfaces edge cases, exceptions, and judgment calls that success stories never reveal. People tell the truth in their failure stories. They’re not protecting anything.

    Layer 1: Surface Protocol

    The question: “What’s your process when X happens?”

    What it gets: The documented version. What the subject would write in an SOP. What they’d tell a new hire on day one. Accurate. Insufficient. Necessary baseline.

    Why you need it: The surface protocol establishes the frame. It’s the map. Everything that comes after is about finding where the territory diverges from the map — and those divergences are where the knowledge lives.

    Layer 2: Exception Probing

    The question: “When do you deviate from that?”

    What it gets: The adaptive layer. The judgment calls that experience produces. The cases where the checklist gets ignored because the situation demands something the checklist can’t accommodate. This is the first layer where genuine tacit knowledge begins to surface.

    The follow-up sequence: “And when does that happen?” → “How do you know it’s that situation?” → “What would you have done three years ago that you wouldn’t do now?” Each question peels back one more layer of accumulated judgment.

    Layer 3: Sensory and Somatic

    The question: “How do you know it’s that and not something else?”

    What it gets: Pattern recognition so ingrained it operates below conscious awareness. The knowledge the subject has never verbalized because no one has ever asked them to. This is the hardest layer to surface and the most valuable thing in the concentrate.

    What it sounds like: “The smell is different.” “The drywall feels wrong.” “Something about the way the insurance company rep is phrasing the emails.” These are not vague — they’re ultra-specific to a domain. The job is to slow down at these moments and press: “Describe the smell.” “What does wrong feel like compared to right?” “What in the phrasing specifically?” The subject usually thinks they can’t explain it. They can. They just haven’t been asked slowly enough.

    Layer 4: Counterfactual Pressure

    The question: “What would break if you weren’t here tomorrow?”

    What it gets: The knowledge hierarchy. What actually matters versus what’s ritual. Most organizations don’t know which is which until the person who knows leaves. This layer surfaces the load-bearing knowledge — the things that if absent would produce visible failures, not just suboptimal outcomes.

    The follow-up: “Who else knows that?” The answer is almost always “no one” or “maybe [one person].” That’s the knowledge risk. That’s also the product.


    The Pivot Signal Lexicon

    Proximity to tacit knowledge produces specific signals in conversation. Recognizing them in real time is the skill that separates a good extraction session from a great one. Miss these signals and you stay in Layer 1. Catch them and you descend.

    Signal What It Means The Move
    “It’s hard to explain…” The subject is about to verbalize something they have never articulated before. This is the most valuable signal in the lexicon. Slow everything down. “Try anyway.” Do not fill the silence. Do not offer a simpler question. Wait.
    “You just kind of know” Layer 3 boundary. The subject is pointing directly at tacit knowledge they don’t know how to surface. “Walk me through the last time you just knew. What did you notice first?”
    Hedging and qualifiers The subject is filtering. They have an answer but aren’t sure it’s acceptable to say. “Generally speaking…” “In most cases…” “It depends…” are all hedges. “Off the record — what actually happens?” Or: “What’s the version you’d tell a colleague vs. what you’d put in the manual?”
    Sudden energy or animation You’ve touched something they care about. The subject’s pace increases, their posture changes, they lean in. This is a live thread to a knowledge cluster. Follow it immediately. Drop the protocol. “Tell me more about that.” The protocol can resume. This thread may not come back.
    Deflection to process The subject is avoiding the judgment layer. When asked what they do, they tell you what the process says to do. Often accompanied by “the policy is…” or “we’re supposed to…” “But what do you do when that breaks down?” The emphasis on ‘you’ reframes the question from institutional to personal, which is where the knowledge actually lives.
    Pausing before a number The subject is calculating from experience, not retrieving from documentation. The pause is the gap between “what the spec says” and “what I know from doing this 200 times.” Ask for the number, then: “Where does that come from?” The answer to the second question is often the most valuable thing in the session.
    Unprompted stories The subject has moved from answering your questions to accessing their own knowledge map. Stories they tell without being asked are almost always pointing at something important. Let it run. If the story ends without the embedded knowledge surfacing, ask: “What made that one different from a normal job?”

    The Knowledge Concentrate: What the Output Actually Looks Like

    A transcript is raw. A summary is thinner in size but barely denser in information. A knowledge concentrate is smaller than either and more information-rich than both — because it encodes relationships, decision logic, and confidence alongside the facts themselves.

    The schema for a knowledge concentrate has five components:

    Entity graph. Every named concept, process, person-role, piece of equipment, and decision point that surfaces in the extraction, mapped as nodes with typed edges between them. Not a list — a graph. The relationships are the knowledge. The entities alone are just vocabulary.

    Decision logic. Every when-then-because statement extracted from the session. “When the moisture readings are above X in a crawlspace with Y flooring type, we always do Z because A.” Structured with confidence scores: is this firsthand knowledge, observed pattern, or secondhand information?

    Benchmarks. Every number that surfaces in extraction — thresholds, timelines, costs, rates, counts — with context, source count, and variance. A benchmark from one interview has low confidence. The same benchmark confirmed across six interviews in the same market has high confidence and is ready to be used as ground truth.

    Tacit signatures. The things that are hard to explain — captured as best as they can be verbalized, with a confidence flag that signals to the AI system consuming them: this is approximate. This is the residue of knowledge that the extraction process got close to but couldn’t fully surface. It’s still valuable. It tells the AI where human judgment is concentrated.

    Provenance. Traceable but anonymized. How many sources contributed to each claim. Whether a given piece of knowledge is individual or cross-validated. What industry and market it came from.

    An AI system consuming a knowledge concentrate in this format doesn’t just know facts — it knows which facts to trust, how to chain them into decisions, and where the knowledge is thin enough that human judgment should be called in.


    What the App Can Do and What It Can’t

    The four-layer protocol and the pivot signal lexicon can be partially codified. A stateful conversational agent — not a chatbot, a genuinely stateful system that maintains a running knowledge map of what’s been surfaced and what’s still needed — can execute the question sequences, detect linguistic pivot signals, navigate domain-specific question libraries, and run the processing pipeline from transcript to structured concentrate.

    What it cannot do is the thing that makes the difference between a good extraction and a complete one:

    It cannot read the half-second of hesitation before an answer that signals the subject knows more than they’re about to say. It cannot decide, in the middle of an unprompted story, that this tangent is the most important thing in the session and the protocol should be abandoned to follow it. It cannot calibrate trust — cannot sense whether the subject is performing for the recording or actually sharing, and adjust accordingly. It cannot distinguish a valuable tangent from genuine noise in real time.

    These are not gaps that better models will close. They are inherently relational and embodied. They require a human who is genuinely present in the conversation, not processing a transcript of it.

    The honest architecture for a distillery operation is therefore tiered. The app handles extraction volume — the sessions where the knowledge is relatively accessible, the domain is well-mapped, and the question library is sufficient. The human handles the sessions where the stakes are highest, the subject is guarded, or the knowledge being sought is at the outer edge of what can be verbalized. And the human is always the quality gate on the final concentrate, regardless of which path produced it.


    Why This Works in Any Industry

    Tacit knowledge is not a property of any particular field. It is a property of human expertise at depth. Wherever humans have been doing something long enough to develop judgment that exceeds documentation — which is everywhere — the distillery protocol applies.

    The domain changes the question library. The pivot signals are universal. The four-layer structure works in restoration, in legal practice, in medicine, in financial services, in manufacturing, in competitive sports coaching, in culinary production. Any field where experience produces something that training cannot replicate is a field where a knowledge concentrate has value.

    The buyers are the organizations trying to make that knowledge portable. The AI system that needs to give the same answer a 20-year veteran would give. The consultant whose insights live only in their head. The franchise trying to replicate the judgment of its best operators across 400 locations. The company that just lost its most important employee and is only now discovering what they actually knew.

    The product is not content. It is not a report. It is a structured knowledge artifact that makes someone else’s irreplaceable expertise replicable — at least partially, at least for the cases the documentation currently handles worst.

    That’s the distillery. Extract. Distill. Deploy.


    Frequently Asked Questions

    How long does a single extraction session take?

    A full four-layer descent with one subject takes 60–90 minutes. Rushing below 45 minutes consistently produces shallow output — the session ends before Layer 3 is reached. Three to five sessions with different subjects in the same domain produces a concentrate with enough cross-validation to have meaningful confidence scores on the decision logic and benchmarks.

    What industries is this most applicable to?

    Any industry where experience produces judgment that documentation can’t replicate. The highest-value applications are in fields with expensive mistakes (medical, legal, engineering), fields with long apprenticeship periods (skilled trades, finance, consulting), and fields where the knowledge is currently locked in one or two people (most small and mid-size businesses).

    How is this different from a McKinsey-style knowledge management engagement?

    Traditional knowledge management captures process documentation — what should happen. The distillery protocol captures judgment documentation — what actually happens, and why, and when the standard answer is wrong. The output is structured for AI consumption, not human reading. The concentrate is designed to be queried, not read.

    What happens to the concentrate after it’s produced?

    The concentrate is delivered to the client for ingestion into their AI infrastructure — as a RAG knowledge base, as fine-tuning data, as a reference layer for their AI assistant, or as structured context for their customer-facing AI systems. The format is designed to be immediately usable without further transformation. The provenance metadata ensures the client knows which claims to trust at what confidence level.

    Can the extraction protocol be deployed without a trained human interviewer?

    Partially. A well-built stateful conversational agent can execute the question sequences, detect linguistic pivot signals, and run the processing pipeline. What it cannot do is the real-time relational judgment that surfaces the deepest knowledge — the hesitation reading, the trust calibration, the decision to abandon the protocol and follow an unexpected thread. For accessible knowledge in well-mapped domains, the app is sufficient. For the knowledge closest to the surface of human expertise, the human remains in the loop.


  • Four-Layer Data Architecture: Behavior-First Strategy

    Four-Layer Data Architecture: Behavior-First Strategy

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    The instinct, when building a complex operation, is to find one tool that can hold everything. One source of truth. One dashboard. One system of record for all data types.

    This instinct is wrong, and it produces exactly the kind of system it’s trying to avoid: a single tool that does everything poorly, a migration project that costs more than the original implementation, and a team that has learned to distrust the data because the tool was never designed for the behaviors it was forced to support.

    The behavior-first alternative for data architecture doesn’t start with “what tool can hold everything.” It starts with: what are the distinct behaviors this data needs to support, and which tool is genuinely best suited for each one?

    The Four Data Behaviors

    In a multi-site AI-native content operation, four distinct data behaviors emerge:

    Machine-generated operational data needs to be written and read by automated systems at high speed. Batch job results, embedding vectors, image processing logs, Cloud Run execution histories. No human looks at this data directly. It needs to be fast, cheap, and structured for programmatic access. GCP serves this behavior — Firestore for structured operational state, Cloud Storage for large artifacts, BigQuery for analytical queries across the full dataset.

    Human-actionable signals need to be displayed clearly enough that a person can take action without wading through noise. Site health alerts, content gaps, client status changes, task assignments. This data needs to be readable, filterable, and connected to the people who need to act on it. Notion serves this behavior — not because it’s the most powerful database, but because it’s the most human-readable one, with views that can surface exactly the signal each role needs.

    Published content needs to be delivered to web visitors and search engines at performance standards those audiences require. WordPress serves this behavior. It was designed for it. The mistake is asking WordPress to also serve as the storage layer for unpublished content, the analytics layer for content performance, or the task management layer for content production. It wasn’t designed for those behaviors and it’s not good at them.

    Files and documents need to be stored, versioned, and shared across tools and collaborators. Google Drive serves this behavior. Skills, SOPs, brand guidelines, exported data — anything that exists as a file rather than as structured data belongs in Drive, not in a database trying to handle file attachments as a secondary feature.

    Why Separation Produces Better Systems

    A four-layer architecture feels like more complexity than a single-tool approach. In practice it produces less complexity, because each tool is operating within its design constraints instead of being stretched beyond them.

    The signal-to-noise problem in most dashboards comes from forcing machine-generated data and human-actionable signals into the same view. The machine data overwhelms the human signals. The solution is usually “better filtering” — which is the wrong answer. The right answer is storing machine data where machines can read it and surfacing human signals where humans can act on them.

    The performance problem in most content operations comes from asking WordPress to be a content management system when it’s a content delivery system. The content that belongs in a CMS — drafts, revisions, briefs, research notes — should be in Notion. The content that belongs in a CDS — published articles, page templates, media files — should be in WordPress. When you separate these, both tools perform their actual function better.

    The data loss problem in most operations comes from treating the most convenient tool as the system of record. When content lives only in WordPress, a site failure is a data failure. When operational state lives only in a Cloud Run service, a deployment change is a state failure. The four-layer architecture ensures that each data type has a permanent home in the tool designed to hold it — and that the tools interact through APIs rather than through manual migration.


  • ADHD AI-Native Operations: Behavior-First System Design

    ADHD AI-Native Operations: Behavior-First System Design

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    The conventional wisdom about ADHD and work is built around a simple premise: the ADHD brain is deficient in the behaviors that work requires, and management strategies exist to compensate for those deficiencies. More structure. Better schedules. Accountability systems. Tools designed to impose the consistency the brain doesn’t generate naturally.

    This is tool-first thinking applied to a human brain. And like most tool-first thinking, it produces systems that fight the behavior instead of serving it.

    The behavior-first alternative asks a different question: what does the ADHD brain actually do, at its best, and what system design would allow it to do more of that?

    What the ADHD Brain Actually Does

    Three behaviors characterize high-functioning ADHD cognition when the environment supports them:

    Hyperfocus. Sustained, intense concentration that arrives unbidden and runs at extraordinary depth for an unpredictable duration. Not concentration on demand — concentration that seizes the operator when a problem activates the interest system. The output of a hyperfocus session is disproportionate to the time invested, and the quality often exceeds what deliberate, scheduled work produces.

    Interest-based attention routing. The ADHD attention system allocates based on interest, novelty, urgency, or challenge — not importance. High-interest work gets exceptional focus. Low-interest work gets almost none. This is not a failure of will. It’s a feature of a different attentional architecture.

    Cross-domain pattern recognition. Rapid context-switching, which looks like distractibility in sequential-task environments, produces something valuable in environments that reward synthesis: the ability to connect observations across unrelated domains and identify patterns that single-domain experts miss.

    The System That Serves These Behaviors

    An AI-native operation designed around these behaviors looks different from a conventional productivity system:

    For hyperfocus: The system captures whatever the hyperfocus session produces — immediately, in full, without requiring the operator to organize it mid-session. The Second Brain stores the output. The cockpit session for the next day picks up the thread. The non-linearity of hyperfocus (jumping between connected insights, building in spirals) becomes productive because the AI can hold the full context of the spiral across sessions.

    For interest-based attention: Low-interest, deterministic work routes to automated pipelines. Haiku runs taxonomy fixes at scale. Cloud Run handles scheduled publishing. Batch jobs process a hundred posts while the operator is doing something that has activated their interest system. The attention that would have been coerced onto low-interest work is freed for the high-interest work where ADHD attention genuinely excels.

    For pattern recognition: The cross-domain synthesis that ADHD cognition produces naturally — connecting a restoration industry CRM insight to an AI architecture principle to a neurodiversity research finding — is exactly what generates the novel frameworks that constitute a knowledge operation’s core asset. This isn’t compensated for. It’s the product.

    The Architecture Principle

    The systems that emerged from designing around ADHD constraints are not ADHD-specific. They are better systems. External working memory (the Second Brain) outperforms internal working memory for complex multi-client operations regardless of neurology. Routing low-value-attention work to automation is better for any operator. Pre-staged context reduces friction for everyone.

    The ADHD constraints forced designs that a neurotypical operator would also benefit from — because the constraints that neurodivergence makes extreme are present in milder form in everyone. The behavior-first design process, applied to an ADHD brain, produced infrastructure. The same process, applied to any operation, produces the same result: systems that serve the actual behavior, compound over time, and don’t require the operator to fight their own cognition to function.


  • AI Work Order Architecture: Decoupling AI & Execution

    AI Work Order Architecture: Decoupling AI & Execution

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    AI systems are good at identifying problems. Automated systems are good at fixing them. The failure mode that kills most AI automation projects is building them as one thing instead of two.

    When you couple intelligence and execution in a single system, you get something that can do everything slowly and nothing reliably. The intelligence layer needs to be conversational, contextual, and judgment-driven. The execution layer needs to be deterministic, fast, and parallelizable. These are fundamentally different behaviors, and they require different tools.

    The Work Order as the Bridge

    The behavior-first design for AI automation has three distinct stages: identify (Claude analyzes a system and surfaces what needs to be done), deposit (Claude writes a structured work order to a persistent queue), and execute (a Cloud Run worker reads the work order and runs the fix).

    The work order is the key artifact. It’s the contract between the intelligence layer and the execution layer. A well-formed work order contains everything the execution layer needs to run without asking Claude any follow-up questions: the target (site, post ID, endpoint), the operation (what to do), the parameters (how to do it), and the success criteria (how to know it worked).

    When the work order is well-formed, the execution layer is a dumb runner. It doesn’t need to understand context, history, or judgment. It reads the work order, executes the operation, and writes the result back. The intelligence that produced the work order stays in the intelligence layer — which is exactly where it belongs.

    What This Looks Like in Practice

    In a multi-site content operation, Claude might analyze a WordPress site and identify 47 posts with missing FAQ schema. The tool-first approach runs Claude in a loop, generating and publishing schema for each post sequentially. This is slow, context-dependent, and fragile — if Claude loses context mid-run, the job is incomplete and the state is unclear.

    The behavior-first approach: Claude generates 47 structured work orders, one per post, and deposits them in a Notion database with status “Queued.” A Cloud Run service reads the queue and processes each work order independently, in parallel, writing results back to each row. Claude is done in minutes. The Cloud Run service finishes the execution while Claude is doing something else entirely.

    The behaviors are clean. The tools serve them. The system scales horizontally without requiring Claude to be in the loop for execution.

    The Two Lanes of AI Automation

    Not everything belongs in the work order queue. Some operations require judgment that the execution layer can’t replicate: content quality assessment, strategy decisions, anything where “it depends” is the correct first answer. These belong in a different lane — one where Claude stays in the loop through completion.

    A mature AI automation architecture has both lanes clearly defined. Deterministic operations (taxonomy fixes, schema injection, meta rewrites, image uploads, internal link additions) go to the work order queue and run without Claude. Judgment-dependent operations (content strategy, quality review, client recommendations) stay in the conversational layer where Claude’s judgment can be applied continuously.

    The discipline is in knowing which lane each operation belongs in — and resisting the temptation to put judgment-dependent work in the queue just because it would be faster. Faster execution of the wrong thing is not an improvement.


  • Tacit Knowledge Extraction: Behavior Before AI Systems

    Tacit Knowledge Extraction: Behavior Before AI Systems

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    Every organization has two kinds of knowledge. The first kind is documented: processes, policies, training materials, SOPs. The second kind is tacit: the adjustments people make without thinking, the thresholds they’ve learned from experience, the judgment calls they can execute in seconds but couldn’t explain in a meeting.

    The documented knowledge is easy to feed into an AI system. The tacit knowledge is what makes the organization actually work — and it’s almost never in a format that AI can use.

    The gap between these two knowledge types is where most enterprise AI implementations fail. Companies feed their AI the documentation and wonder why it can’t give the same answers a 10-year veteran would give. The answer is that the 10-year veteran isn’t running on the documentation. They’re running on the tacit layer — and nobody captured it.

    What Tacit Knowledge Extraction Actually Requires

    You cannot extract tacit knowledge through forms, surveys, or documentation requests. Tacit knowledge by definition is knowledge that the holder cannot fully articulate without a skilled interviewer pulling it out. The behavior that surfaces it is specific: a conversational sequence that descends through four distinct layers.

    Layer 1 — Surface protocol: “What’s your process when X happens?” This gets the documented version — what people think they do, what they’d write in an SOP. Necessary baseline but not the target.

    Layer 2 — Exception probing: “When do you deviate from that?” This surfaces the adaptive layer — the judgment calls that experience produces. The deviations are where tacit knowledge lives.

    Layer 3 — Sensory and somatic: “How do you know it’s that specific problem and not something else?” This is the hardest layer to surface and the most valuable. It captures knowledge that the holder has never verbalized — pattern recognition so ingrained it operates below conscious awareness.

    Layer 4 — Counterfactual pressure: “What would break if you weren’t here tomorrow?” This surfaces the knowledge hierarchy — what actually matters versus what’s ritual. Most organizations don’t know which is which until the person with the knowledge leaves.

    The Behavior Determines the Tool Stack

    Once this extraction behavior is understood, the tool selection for the AI system becomes clear. You need: a way to capture the conversation at high fidelity, a way to convert the transcript into structured knowledge artifacts, a storage layer that preserves the knowledge in a format AI systems can query, and an embedding layer that makes the knowledge semantically searchable.

    These are four distinct behaviors served by four distinct tools. The extraction conversation is a human behavior — no tool replaces it. The structuring is where AI earns its keep: running the transcript through multiple models with different attack angles, identifying the tacit signatures embedded in the language, organizing the output into the knowledge concentrate schema. The storage is a database decision. The embedding layer is a vector store.

    None of these tool choices could have been made intelligently without first understanding the extraction behavior. The behavior is the constraint that makes the tool selection tractable.

    The Minimum Viable Experiment

    For any organization that wants to capture its tacit knowledge layer before it walks out the door: four extraction conversations, transcribed and run through a three-model distillation round, produce a knowledge artifact dense enough to answer questions that the documentation cannot. The experiment takes a week and costs almost nothing. The cost of not doing it shows up when the person who holds the knowledge leaves and the organization discovers, for the first time, how much was never written down.


  • Behavior-First System Design: Build for Action, Not Tools

    Behavior-First System Design: Build for Action, Not Tools

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    There is a mistake that kills more technology projects than bad code, bad vendors, or bad timing combined. It happens before a single line is written, before a single subscription is purchased, before anyone even knows there’s a problem.

    The mistake is this: choosing the tool before understanding the behavior.

    It looks like a reasonable decision. You need to manage customer relationships, so you buy a CRM. You need to publish content, so you build around WordPress. You need to organize knowledge, so you set up Notion. The tool selection feels like the hard part — the research, the demos, the pricing comparisons. By the time you’ve chosen, you feel like the work is half done.

    It isn’t. You’ve just committed to building a system shaped like a tool instead of shaped like a behavior. And when the behavior and the tool don’t match, the system fails quietly — not in a crash, but in a slow drift toward abandonment, workarounds, and the quiet understanding that “we don’t really use that anymore.”

    The alternative is building the system around the behavior first. It sounds obvious. Almost nobody does it.


    What “Behavior-First” Actually Means

    A behavior is what actually happens — or needs to happen — in your operation. It’s not a goal, not a feature request, not a capability. It’s the specific sequence of actions, decisions, and handoffs that produce a result.

    Most system design starts with tools and works backward to behaviors. Behavior-first design starts with the behavior and works forward to the minimum set of tools that can serve it.

    The difference sounds subtle. The outcomes are not.

    When you start with the tool, you spend the first six months learning the tool’s shape and then trying to reshape your operation to fit it. When you start with the behavior, you spend the first six months building a system that serves the operation — and then choosing the simplest tool that delivers what the behavior requires.

    The tool-first approach produces complexity. The behavior-first approach produces leverage.


    Six Behaviors That Built This Operation

    The following examples are drawn from a single AI-native operation built over three years. None of them started with a tool selection. All of them started with the question: what actually needs to happen here?

    1. Write → Store → Distribute (The Content Pipeline)

    Most content operations are built around WordPress. The platform is the system. Articles go into WordPress, WordPress manages drafts, WordPress publishes, WordPress is the source of truth. This is tool-first design.

    The behavior is different. The behavior is: write a piece of content, preserve it permanently, distribute it to wherever it needs to go.

    When you build around that behavior, WordPress becomes one destination among several — not the system. Notion becomes the storage layer. WordPress becomes the distribution layer. The article exists independently of where it’s published. If WordPress goes down, if the WAF blocks you, if the site moves hosts — the content is not at risk. The behavior (write → store → distribute) is served by a stack of tools, none of which is the irreplaceable center.

    The practical result: every article written in this operation goes to Notion first, WordPress second. Not because Notion is a better publishing platform — it isn’t. Because the behavior requires permanent, accessible storage before distribution, and WordPress was never designed to be that.

    2. Identify → Deposit → Execute (The Work Order Architecture)

    The problem: an AI system can identify what’s wrong with a WordPress site in seconds — thin content, missing schema, broken taxonomy, orphan pages — but the identification and the fix are handled by completely different systems. The identification lives in a conversation. The fix lives in a deployment. There’s no bridge.

    The behavior is: Claude identifies a problem, deposits a structured work order, a Cloud Run worker executes it. The intelligence and the execution are decoupled. Neither layer needs to know how the other works.

    Built around that behavior, the tool choices become obvious. Notion holds the work order queue — not because Notion is a task management tool (though it is), but because Claude can write to it via API and a Cloud Run service can read from it. The tools serve the behavior. The behavior doesn’t contort to serve the tools.

    3. Extract → Distill → Deploy (The Human Distillery)

    The behavior here is one of the rarest in any knowledge-intensive industry: taking tacit knowledge — the unwritten, unspoken operational intelligence that lives in people’s heads — and converting it into structured artifacts that AI systems can immediately use.

    Tacit knowledge doesn’t fit into forms, surveys, or databases. It surfaces through conversation. The extraction behavior is a specific sequence: disarm the subject, descend through four layers of questioning (documented protocol → exception cases → sensory knowledge → counterfactual pressure), capture what surfaces, and distill it into a dense artifact.

    That behavior existed long before any tool was selected to support it. The tool choices — which models to run distillation through, how to structure the output schema, where to store the resulting knowledge concentrates — all came after the behavior was understood. The behavior is irreplaceable. The tools are interchangeable.

    4. Observe → Route → Produce (Task Routing for Variable Attention)

    Most productivity systems are built around the assumption that the operator applies consistent, scheduled attention to work. Tasks sit in queues. Work happens in order. Focus is managed through priority.

    That behavior doesn’t match how an ADHD-wired operator actually works. The actual behavior is: attention arrives unbidden, attaches to whatever has activated the interest system, runs at extraordinary intensity, and then ends — also unbidden. The work happens in spirals, not lines.

    An AI-native operation designed around this actual behavior routes tasks differently. High-interest, high-judgment work goes to the operator when the operator’s attention is activated. Low-interest, deterministic work gets routed to automated pipelines that run on schedule regardless of operator state. The behavior — variable, interest-driven, high-intensity — shapes the system. The system doesn’t demand behavior the operator can’t deliver.

    The result is not a workaround. It’s an architecture. And the architecture works better for a neurotypical operator too — because the constraints that neurodivergence makes extreme are present in milder form in everyone.

    5. Touch → Remind → Refer (The CRM Community Framework)

    The restoration industry spends $150–$500 per lead acquiring customers and then never contacts them again. Not because they don’t want to. Because the tool they have — a job management system built around transactions — doesn’t support the behavior they need.

    The behavior is: make consistent, relevant, human contact with warm relationships at regular intervals, using legitimate business moments as the reason. That’s it. The behavior is simple. The tool selection is almost irrelevant — a spreadsheet and a Mailchimp free account can execute it. What matters is that the system is built around the behavior (stay present in warm relationships) rather than around the tool (send marketing emails).

    When you build around the tool, you get a marketing email campaign. When you build around the behavior, you get a community — a network of people who feel a genuine two-way relationship with your company and who refer you business because you’re the company that actually stayed in touch.

    The technical implementation of this — segmentation from ServiceTitan and Jobber, email automation in Mailchimp or Brevo, relationship intelligence in a Notion Second Brain — is documented in full in the CRM Community Framework series. Every tool choice in that series is downstream of the behavior. None of it works if you start with the tool.

    6. Signal → Display → Act (The Four-Layer Data Architecture)

    A complex multi-site operation generates data from dozens of sources simultaneously — WordPress post metrics, GCP Cloud Run logs, Notion task statuses, client pipeline movements, content performance signals. The instinct is to find one tool that can hold all of it. The tool becomes the system.

    The behavior is different for each data type. Machine-generated operational data (image processing logs, batch job results, embedding vectors) needs to be written and read by automated systems at high speed. Human-actionable signals (site health alerts, content gaps, client status changes) need to be displayed in a way a person can act on without noise. Content in progress needs to be stored independently of where it will ultimately be published.

    Four behaviors. Four tool layers. WordPress for published content, GCP for machine data, Notion for human signals, Google Drive for files. No single tool tries to do all four. Each tool is chosen because it’s the best fit for one specific behavior — not because it can technically handle the others.


    How to Apply This in Your Operation

    The behavior-first design process has three steps, and none of them involve opening a browser tab to research tools.

    Step 1: Write down what actually needs to happen. Not what you want to accomplish. Not what you wish the system could do. The specific sequence of actions that produces the result you need. Subject → verb → object, repeated until the behavior is fully described. “Someone writes an article. The article needs to be findable in six months. The article needs to be published to a website.” That’s a behavior. “We need better content management” is not.

    Step 2: Identify where the behavior breaks down today. Every system has the places where it works and the places where it silently fails. A CRM that nobody updates after the job closes. An email platform that has contacts from three years ago and no segmentation. A content process that lives in someone’s head. These are the behavior gaps — the places where the actual behavior doesn’t match the intended behavior.

    Step 3: Choose the simplest tool that serves the behavior. Not the most powerful. Not the most popular. Not the one with the best demo. The one that makes the behavior easiest to execute consistently. A $13/month Mailchimp account and a Google Sheet will outperform a $400/month marketing platform if the behavior is four emails per year to a warm local database — because the complexity of the expensive tool introduces friction that kills the behavior entirely.


    The AI-Native Operation Is Behavior-First by Definition

    The reason AI-native operations tend to outperform tool-native operations has nothing to do with AI being smarter. It has to do with design philosophy.

    AI tools, at their best, are infinitely flexible. They don’t impose a shape on your operation. They serve whatever behavior you describe. The operator who builds an AI-native operation is forced — by the nature of the tools — to understand their own behaviors first. You cannot prompt your way to a useful output without knowing what useful looks like. You cannot build a pipeline without understanding the sequence it’s meant to automate.

    This is why the AI-native operator has a structural advantage over the SaaS-native operator. Not because their tools are better. Because the process of building with AI forces behavior-first thinking, and behavior-first thinking produces systems that compound over time instead of decaying into expensive shelf-ware.

    The tool will change. The behavior won’t. Build the system around the behavior.


    Frequently Asked Questions

    How do you identify the behavior if you’ve always built around tools?

    Start with the breakdowns. Wherever your current system has workarounds, manual steps, or things people do “outside the system,” those are the places where the tool’s shape and the behavior don’t match. The workarounds are the behavior. Build the new system to serve them directly.

    Doesn’t this make tool selection harder and slower?

    It makes it faster. When you know the behavior precisely, you have a clear evaluation criterion: does this tool make the behavior easier to execute consistently, or does it add complexity? Most tool evaluations fail because the criteria are vague. Behavior-first evaluation is fast because the test is concrete.

    What if the behavior changes over time?

    Behaviors evolve. Systems built around behaviors can evolve with them — you swap the tool layer without disrupting the behavior layer. Systems built around tools can’t evolve without a full rebuild, because the tool is the system. Behavior-first architecture is inherently more resilient to change.

    Is this just another way of saying “process before technology”?

    It’s related but more specific. “Process before technology” is usually interpreted as documentation before implementation — write the SOPs, then build the tools to support them. Behavior-first design is about understanding the actual behavior of the operation, which often differs significantly from the documented process. You’re designing around what people and systems actually do, not what they’re supposed to do.

    How does this apply to AI tool selection specifically?

    AI tools are especially susceptible to tool-first thinking because they’re impressive in demos. The demo shows capability; the behavior question asks whether that capability serves a specific sequence in your operation. Most AI tool adoptions fail not because the tools are bad but because they were selected based on capabilities rather than behaviors. The question is never “what can this tool do?” It’s “which of my behaviors does this tool serve, and does it serve them better than what I have now?”