Tag: AI Agents

  • Restoration AI Economics: The Agent-Assisted Cost Shift

    Restoration AI Economics: The Agent-Assisted Cost Shift

    This is the fourth article in the AI in Restoration Operations cluster under The Restoration Operator’s Playbook. It builds on why most projects fail, what to build first, and the source code frame.

    The conversation no one in restoration is having yet
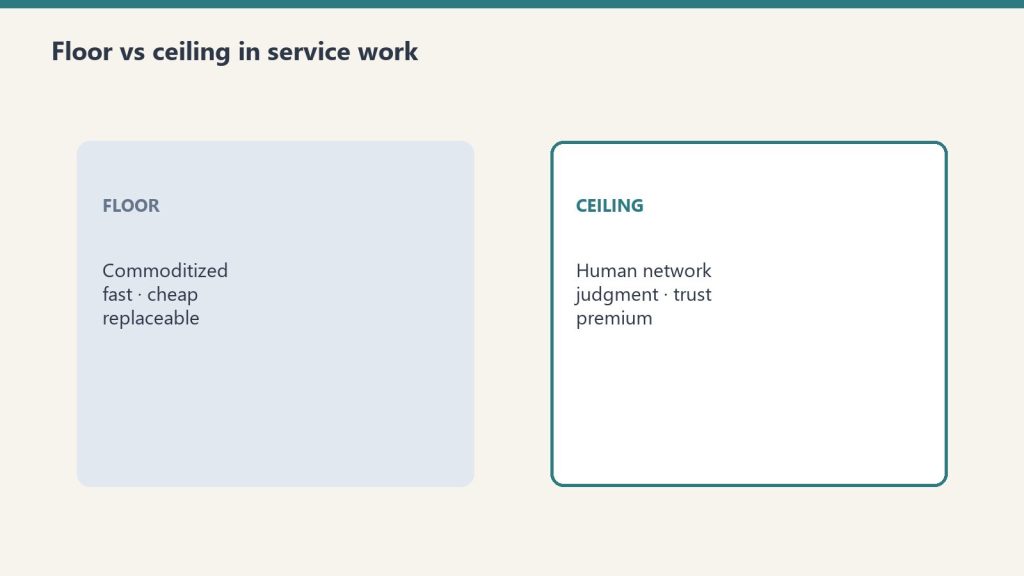
    Floor versus ceiling cards for commoditized work and human-network premium
    The conversation no one in restoration is having yet.

    The most consequential shift in restoration economics over the next thirty-six months is also the topic that almost no one in the industry is discussing in any operational depth. The shift is the cost structure that emerges when a meaningful share of a restoration company’s operational work is done by AI agents running on managed infrastructure rather than by human staff or by traditional software.

    The shift is not coming. It is here. The early-adopter companies have been operating in this cost structure for the last twelve months, and the second wave is coming online now. By the end of 2026, a competitive baseline will exist for what an AI-augmented restoration company looks like financially, and companies operating outside that baseline will start to feel the difference in their bid competitiveness, their margin profile, and their ability to take on growth.

    This article is about the economics of that shift. The math is not complicated. The implications are large.

    What an agent-assisted operation actually costs

    Three stacked layers: chat UI, tools, agent runtime
    What an agent-assisted operation actually costs.

    Start with the cost of running a meaningful AI agent capability inside a restoration company in 2026. The cost has three components.

    The first is the model usage cost. This is what gets paid to the AI provider for the actual inference — the tokens consumed, the requests made, the work the model does on the company’s behalf. For most restoration use cases, model usage cost runs in the range of a few cents per significant operation. A handoff briefing generation. A scope review pass. A photo organization run. A communication draft. Each of these costs pennies.

    The second is the runtime cost when agents are executing autonomously rather than producing single outputs on demand. An agent that runs a multi-step task — pulling a file, organizing the documentation, generating the briefing, packaging it for the rebuild team — incurs runtime cost for the duration of its session. For restoration use cases, even complex agent sessions tend to cost low single digits of dollars at most.

    The third is the operational cost of the human owners and reviewers. The senior operator who owns the AI capability. The person who reviews the outputs and feeds back corrections. The person who maintains the prompts and configurations. This is the largest of the three components by a wide margin and is often the only one that owners explicitly account for, because it is the one that shows up on payroll rather than on a separate line item.

    The total cost per operation, when honestly accounted for, is meaningful but small. The economic significance comes not from the per-operation cost but from the volume.

    The volume changes everything

    A traditional restoration operation has a defined operational throughput per senior operator. A senior project manager can credibly run a certain number of jobs per month. A senior estimator can scope a certain number of files per week. A senior dispatcher can coordinate a certain number of mitigation responses per day. These throughput numbers are determined by the human operator’s working capacity and have not meaningfully changed in decades.

    An agent-assisted operation has fundamentally different throughput characteristics for the work the agents handle. A handoff briefing generation that takes a human operator twenty minutes can be produced by an agent in under a minute. A scope review pass that takes a human estimator forty-five minutes can be produced by an agent in three minutes. A photo organization that takes a human technician thirty minutes can be done by an agent in ninety seconds. The human is still in the loop — reviewing, validating, correcting — but the operator is reviewing the agent’s output rather than producing the original work.

    The economic implication is that a senior operator’s throughput on documentation and review work expands by a multiple. Not by ten percent or twenty percent. By a multiple. A senior estimator who previously could handle thirty files per week can, with appropriate agent assistance and a working review workflow, handle eighty or a hundred files per week, with comparable or improved quality, depending on the file mix and the maturity of the agent capability.

    The cost of the agent capability supporting that estimator runs in the range of a few hundred dollars per month. The value of the additional throughput is in the tens of thousands of dollars per month at typical estimator productivity rates. The ratio is severe enough that the economics dominate the conversation about whether to invest, regardless of how the implementation cost is amortized.

    What this does to bid competitiveness

    The cost structure shift has direct implications for what restoration companies can afford to bid on competitive work.

    A company running on traditional throughput economics has a certain unavoidable cost per job that includes the senior operator time required to produce the documentation, scope, communication, and review work the job requires. That cost sets a floor on the bid. Below that floor, the company loses money.

    A company running on agent-assisted throughput economics has a meaningfully lower floor on the senior operator time required per job. The same senior team can be spread across more jobs without quality degradation, because the routine work has been compressed by orders of magnitude. The floor on what the company can profitably bid drops.

    For the company doing the bidding, this looks like the ability to win more work at price points that previously would have been unprofitable. For the company being out-bid, this looks like an inexplicable competitive pressure where peers are taking work at numbers that should not pencil. The traditional company looks at the same numbers and assumes the competitor is buying market share unprofitably or providing inferior service. In the early days of the shift, that assumption is sometimes true. Within twelve to eighteen months it stops being true. The competitor is not buying market share. Their cost structure has shifted.

    Companies that have not made the shift cannot match the bid without unacceptable margin compression. They start losing work at the margins of their territory, and the lost work is the most price-sensitive work, which means the work they are still winning is increasingly the high-touch, complex, strategically important work — which sounds fine until they realize they have lost the volume layer that used to fund their fixed overhead.

    What this does to growth capacity

    The same shift changes what growth looks like for a restoration company.

    In a traditional operation, growth is gated by the company’s ability to add senior operational capacity. New service lines, new geographies, new account relationships, new program placements all require senior operators with the bandwidth and judgment to execute. Senior operational hiring is slow, expensive, and constrained by labor market availability. The company’s growth rate is essentially capped by its hiring capacity at the senior layer.

    In an agent-assisted operation, growth is gated by a different constraint. The company’s existing senior operators can absorb significantly more operational throughput because the routine documentation and review work has been compressed. The constraint shifts from senior labor capacity to the speed at which the company can extend its captured operational standards into new contexts and the speed at which the senior team can review and validate the expanded throughput.

    This does not mean growth becomes unconstrained. It means the constraint moves to a layer that the company has more direct control over than the labor market. A company that can extend its prep standard to a new geography can extend its operations to that geography faster than a company that has to hire and train senior operators in the new location. A company that can apply its captured judgment to a new service line can launch that service line faster than a company that has to recruit operators with the requisite experience.

    The companies that have begun operating in this mode are growing in ways that competitors cannot easily explain. The growth is not coming from a marketing breakthrough or a particularly successful acquisition. It is coming from a structural change in how senior operational capacity scales.

    What this does to margin profile

    Three panels showing one problem, three options, one recommendation
    What this does to margin profile.

    The clearest economic effect of the shift, at the company level, is the change in the long-run margin profile.

    A traditional restoration company has a margin structure dominated by labor cost in the production of operational work. Senior operator time is the largest input on most jobs and the least compressible cost line. Margin improvements at the company level are primarily achieved through volume increases, pricing power, or supply chain optimization. The margin ceiling is structurally constrained.

    An agent-assisted restoration company has a margin structure where senior operator time has been redirected from routine production to higher-value work. The senior team is doing more strategic activity per hour worked. The routine work that used to consume their time is being done at a fractional cost. The margin per job improves not because the company is cutting corners but because the per-job cost of producing the operational substrate has dropped.

    Over a twenty-four to thirty-six month period, the margin profile of an agent-assisted operation pulls visibly ahead of the margin profile of a traditional operation in the same market. The pull-ahead is gradual but durable. By the time it becomes obvious in the financials, the gap is large enough that catching up requires more than a single-year investment program.

    The honest risk picture

    The economic shift is not without risk. The companies operating well in this new mode are managing several specific risks that owners considering the transition need to understand.

    The first risk is over-reliance on the AI capability. A company that lets the agent handle a function entirely without continued human oversight will eventually experience a quality failure that costs more than all the throughput gains combined. The senior operator review workflow is not optional. The economics work because the human is still in the loop. Companies that try to push the human out of the loop in pursuit of further cost savings learn the lesson the expensive way.

    The second risk is the brittleness of the captured judgment. The agent is only as good as the standard it is operating against. As conditions change — new construction styles, new carrier dynamics, new regulatory environments — the standard has to evolve, and the evolution requires continued investment. Companies that build the agent capability and then stop investing in the underlying standard see the agent quality drift over time.

    The third risk is vendor concentration. Companies that build their entire operational substrate against a single AI provider’s specific platform are exposed to vendor pricing changes, capability changes, and continuity risk. The companies operating well in this mode tend to keep their captured standards in vendor-neutral form, so that the underlying judgment can be moved to a different runtime if the original vendor relationship deteriorates.

    The fourth risk is the team’s relationship with the technology. A senior operator who has been told the AI is going to make their job easier will be disappointed if it makes their job different rather than easier. The framing of the transition with the team has to be honest about what is changing and what is not. Companies that mishandle this framing experience attrition at the senior layer that can wipe out the operational gains entirely, as discussed in the source code piece.

    What owners should be doing about this in 2026

    If you run a restoration company and you have not yet begun the transition to agent-assisted operations, the practical implication of the economic shift is that the cost of starting now is significantly lower than the cost of starting in eighteen months and the value of starting now is significantly higher.

    The cost is lower because the infrastructure is mature, the patterns are documented, and the early-adopter mistakes have been made by other people. A company starting in 2026 can move faster and avoid more pitfalls than a company that started in 2024.

    The value is higher because the bid competitiveness, growth capacity, and margin implications of the shift are now beginning to manifest in real markets. A company that begins building the capability now will start producing measurable economic effect within twelve to eighteen months. A company that waits will be entering the work at the same time competitors are starting to convert the capability into market position.

    The starting point is the documentation acceleration work described in the previous article. The economic implications described here flow from the operational substrate that documentation work creates. Without the substrate, none of the economics materialize. With the substrate, all of them do.

    The owners who recognize this and act on it now will be running a different kind of business in 2028. The owners who do not will be looking at their numbers in 2028 and trying to figure out what changed in the market. What changed will not be the market. What changed will be the cost structure of the companies they are competing against.

    Next in this cluster: how to evaluate AI tools without getting fooled — the practical buyer’s framework for cutting through vendor noise and making decisions that hold up over time.
  • Restoration Talent: The AI Bottleneck You Must Fix Now

    Restoration Talent: The AI Bottleneck You Must Fix Now

    Last refreshed: May 15, 2026

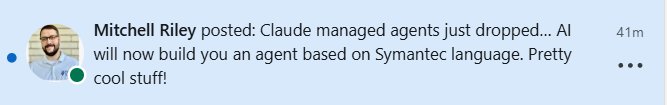
    A LinkedIn post from a restoration recruiter in Houston tipped me off this morning. He’s right — but the timeline is shorter than most people in the industry realize.

    Mitchell Riley LinkedIn post about Claude Managed Agents announcement
    Mitchell Riley’s LinkedIn post that started this train of thought.

    This article is part of The Restoration Operator’s Playbook — Tygart Media’s body of work on how the industry’s best restoration companies are actually thinking in 2026. Start with the pillar piece if this is your first read.

    The post that got me thinking

    This morning I logged into LinkedIn and saw a post from Mitchell Riley — a restoration industry recruiter in Houston who places PMs, GMs, and business development leaders for restoration contractors across the country. Mitchell flagged Anthropic’s Claude Managed Agents launch with the kind of casual enthusiasm only people who actually use this stuff every day can manage. He called it “pretty cool” and noted that Claude will now build you an agent based on natural language.

    He’s right. He’s also pointing at something most of the restoration industry hasn’t fully processed yet.

    What Anthropic actually shipped

    On April 8, 2026, Anthropic launched Claude Managed Agents in public beta. The short version: the infrastructure work that used to take three to six months of engineering — sandboxed code execution, credential management, long-running session persistence, error recovery, observability — is now a managed service. You define what the agent should do. Anthropic runs it.

    The companies already shipping production agents on it: Notion, Asana, Rakuten, and Sentry. Notion lets teams delegate coding, slides, and spreadsheets to Claude without leaving the workspace. Rakuten deployed specialist agents across product, sales, marketing, finance, and HR — each live in under a week. Sentry built an agent that goes from flagged bug to open pull request, fully autonomous.

    Internal Anthropic testing showed up to a 10-point improvement in task success on structured generation work versus a standard prompting loop, with the largest gains on the hardest problems.

    That’s the announcement. Here’s why it matters for restoration.

    The bottleneck just moved

    For the last two years, the question every restoration owner asked about AI was some version of: “Can it actually do the work?” The honest answer was usually “not yet, not without a developer team you don’t have.”

    That’s no longer the question. The infrastructure gap closed on April 8. The new bottleneck is not “can you build the agent” — it’s “do you have the human operators who know what the agent should be doing in the first place.”

    Restoration is an industry where the real intelligence lives in people. A senior PM who has worked five hundred losses knows things that have never been written down anywhere. How a Cat 3 storm response actually sequences when the carrier is dragging on TPA approvals. The difference between a contents pack-out that closes clean and one that becomes a six-month dispute. Which mitigation decisions buy you a profitable job and which ones bury you on the reconstruction side. None of that lives in a textbook. It lives in the heads of people who have been doing the work for fifteen or twenty years.

    That tribal knowledge is now the constraint. The companies that win the next three years will be the ones who pair Managed Agents (or something like it) with senior operators who can tell the agent what good looks like. The companies that try to skip that step — that try to hire generalists and teach them restoration on the fly while their competitors are distilling twenty-year veterans into operational systems — are going to get lapped.

    Buy the talent now

    This is where the recruiting angle gets interesting. Senior restoration talent has always been hard to find. It’s about to get much harder, for a reason most owners haven’t priced in yet: the value of a senior PM is no longer just the work that PM does directly. It’s the work an entire AI system does in their image once their judgment has been encoded into the workflow.

    Right now, that arbitrage is open. The market hasn’t repriced senior operators for what they’re actually worth in an AI-augmented restoration company. In twelve to twenty-four months, it will. The owners who hire the best PMs, GMs, and BD leaders now — and who pair them with someone like Mitchell who actually understands the placement game — are going to look like geniuses in 2027.

    Mitchell is one of the people who gets this from the inside. He uses the AI tools himself. He builds workflows. He analyzes things in dimensions and context that most recruiters never touch — most recruiters in this industry are still working from a spreadsheet of resumes and a cell phone. Mitchell is the kind of recruiter who notices when Anthropic ships something that’s going to change the value of every senior hire he places, and posts about it on a Wednesday morning. That’s the level of operator the smart restoration owners are going to want in their corner.

    What to actually do this quarter

    If you run a restoration company and you read this far, three concrete things:

    One. Identify your two or three most senior operators — the people whose judgment is load-bearing for the business. Start documenting how they think, not just what they do. The documentation is the raw material every future AI workflow will run on.

    Two. Open one or two senior hires you’ve been putting off. The talent market is going to tighten. Get in front of it.

    Three. Stop treating AI as an IT project. It’s an operational capability. The companies that figure this out are not waiting for their tech vendor to sell them an “AI feature.” They’re hiring the operators, capturing the judgment, and pointing the tooling at the result.

    Mitchell’s post was three sentences. The full version of what he was pointing at takes about a thousand words. This is that version.

    If you’re a restoration owner thinking about senior placements in the next two quarters, you should be talking to Mitchell. And if you’re thinking about how to operationalize AI inside your company — distilling senior judgment into systems your whole team can run — that’s the conversation we have at Tygart Media.

    Read next: The New Restoration Operator: How the Industry’s Best Companies Are Thinking in 2026 — the pillar piece this article belongs to.

  • Node Pricing Strategy: Eliminating SaaS Conversion Friction

    Node Pricing Strategy: Eliminating SaaS Conversion Friction

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    Most SaaS pricing pages are designed to justify a price. The best ones are designed to eliminate a reason not to buy. That sounds like the same thing. It isn’t. Justifying a price assumes the customer already wants what you’re selling and just needs to feel okay about the number. Eliminating friction assumes the customer wants it but has found a reason to wait — and your job is to remove that reason before they close the tab.

    Node pricing is the second kind of pricing. It’s not a discount strategy. It’s not a freemium ladder. It’s a structural acknowledgment that your product contains more than one thing of value, and not every customer needs all of it. The $9/node model — where a customer pays $9 per knowledge sub-vertical per month, with a minimum of three nodes — does something that flat subscription tiers almost never do: it makes the product accessible at the exact scope the customer actually wants, rather than at the scope you’ve decided they should want.

    This matters more than it sounds. The gap between what a customer wants to pay for and what your pricing page forces them to pay for is where most SaaS revenue quietly dies.

    The Friction Taxonomy

    Before you can eliminate friction, you have to know which kind you’re dealing with. There are three distinct friction types that kill knowledge product conversions, and they require different solutions.

    Price friction is the most obvious and the least interesting. The customer looks at the number and thinks it’s too high relative to what they’re getting. The standard response is discounts, trials, and annual pricing incentives. These work, but they’re universally available to competitors and therefore not a strategic advantage.

    Scope friction is more interesting and more solvable. The customer looks at what’s included and thinks: I need the mold section. I don’t need water damage, fire, or insurance. But the only way to get mold is to buy the whole restoration corpus at $149/month. That’s not a price objection — they might genuinely be willing to pay $40 for mold-only access. The friction is architectural. The pricing structure forces them to buy more than they want, so they buy nothing.

    Identity friction is the least discussed and often the most decisive. The customer looks at your Growth tier at $149/month and thinks: that’s a serious software subscription. It implies a level of commitment and organizational buy-in that I’m not ready to make. Even if $149 is financially trivial to them, the psychological weight of a $149 line item on a budget is different from three $9 charges that collectively total $27. The first feels like a decision. The second feels like a purchase. That distinction is not rational. It is real.

    Node pricing at $9/node addresses all three friction types simultaneously — and that’s why it’s a more interesting pricing philosophy than it appears to be on first read.

    Why $9 Is Not Arbitrary

    The $9 price point is doing several things at once. It’s below the threshold where most individuals and small business operators feel they need approval from anyone else to make a purchase. It’s above the threshold that signals “this is a real product with real value” rather than a free tier with artificial limits. And it creates an obvious natural upsell path: the customer who starts with one node at $9 and finds it useful adds a second, then a third. At three nodes they’re at $27/month. At five they’re at $45. Somewhere between five and ten nodes, the Growth tier at $149 starts looking like a better deal than individual nodes — and the customer has already been educated on why they want more coverage, by their own experience of adding nodes one at a time.

    This is not an accident. It’s a funnel architecture disguised as a pricing structure. The customer who would never have clicked “Start Trial” on a $149 product clicked “Add mold node” at $9, found out the corpus is actually good, added two more nodes, and is now a much warmer prospect for the Growth tier than any free trial would have produced — because they’ve already been paying, which means they’ve already decided the product is worth money.

    Paying, even a small amount, is a qualitatively different commitment than trialing for free. The psychology of sunk cost works in your favor when the cost is real. Free trial users can walk away feeling nothing. A customer who has paid three months of $27/month has a relationship with the product that is fundamentally stickier, even before the node count justifies an upgrade.

    The Scope Signal

    There is a second thing node pricing does that is easy to overlook: it collects enormously useful intelligence about what customers actually value.

    A flat subscription tier tells you how many people bought. It tells you almost nothing about why, or which part of the product they’re using. Node pricing tells you exactly which knowledge sub-verticals customers are willing to pay for, in what combinations, at what rate of adoption. That is product market fit data at a granularity that flat pricing can never produce.

    If 70% of customers add the mold node first, that tells you something about where to invest in corpus depth. If almost nobody adds the insurance and claims node despite it being objectively one of the most technically complex verticals in the corpus, that tells you something about either the quality of that content or the demand signal for it among your current customer base. If customers consistently add three nodes and stop, that tells you something about the natural scope of what most buyers want — and it should inform where you set the minimum bundle threshold for the Growth tier conversion.

    This is market research that runs continuously and costs nothing beyond what you were already building. It requires only that you look at the data.

    The Minimum Bundle Logic

    Node pricing works best with a thoughtfully designed minimum. Three nodes at $9/month means $27 minimum — low enough to feel like a purchase, high enough to produce real revenue and signal real intent. But the choice of three is not purely arbitrary.

    Below a certain node count, the knowledge base isn’t useful enough to demonstrate value. A single mold node in isolation tells a contractor something. Three nodes — mold, water damage, and drying science — tells them enough to use the product meaningfully in a real job situation. The minimum bundle is designed to get the customer past the “is this actually good?” threshold before they’ve made a large enough commitment to feel burned if the answer is no.

    The minimum also creates a natural comparison point with the next tier up. Three nodes at $27 versus the Growth tier at $149 is a stark difference. But eight nodes at $72 versus $149 starts to narrow. The minimum bundle pushes customers to a price point where the comparison becomes interesting — and interesting comparisons produce upgrades.

    What This Has to Do With Content Strategy

    Node pricing is a product architecture decision. But the philosophy behind it — that friction is the real barrier, not price — applies directly to how content products should be built and sequenced.

    The content equivalent of scope friction is the pillar article problem. You write a comprehensive 3,000-word guide on a topic and wonder why the conversion rate is lower than expected. The reason is often that the reader wanted one specific section — the part about how to document moisture readings for an insurance claim — and had to work through 2,000 words of context they already knew to get there. The scope of the article exceeded the scope of their need. They left.

    The content equivalent of node pricing is granular entry points. Instead of one comprehensive guide, you publish the moisture documentation section as a standalone piece, linked from the comprehensive guide but findable independently. The reader who needs exactly that finds it, gets the answer, and converts at a higher rate than the reader who had to excavate it from a wall of text. The comprehensive guide still exists for the reader who wants full coverage. Both types of readers are served at their own scope.

    The underlying insight is the same in both cases: matching the scope of what you offer to the scope of what each specific customer wants is more powerful than optimizing within a fixed scope. The customer who wants mold-only is not a lesser customer than the one who wants the full corpus. They’re a customer at the beginning of a different path that, if you’ve designed correctly, leads to the same destination.

    The $1 First Month Isn’t a Trick

    One pricing mechanic worth calling out specifically is the $1 first month offer — available on any single corpus, unlimited queries, 30 days, one dollar. No catch.

    This is not a trick and should not be presented as one. It is a philosophical statement about where conversion friction lives. If the product is good, the barrier isn’t price — it’s the activation energy required to start. Most people don’t try things because they haven’t gotten around to it, not because the price is wrong. A dollar removes the “is it worth the money to find out?” calculation entirely and replaces it with: the only reason not to try this is inertia.

    The customers who try it and stay are the ones who found value. The ones who don’t renew weren’t going to stay at any price, and the dollar was a better use of that lead than a free trial that never converts because free things feel optional.

    Priced at $1, the first month is a commitment. Priced at $0, it’s a maybe. That difference in psychological framing shows up in activation rates, usage depth during the trial period, and ultimately in renewal rates. Free is not always better than cheap. Sometimes cheap is better than free because cheap requires a decision, and a decision creates an owner.

    Frequently Asked Questions

    What is node pricing in a knowledge API product?

    Node pricing is a model where customers pay per knowledge sub-vertical — called a node — rather than for access to the entire corpus at a flat tier price. At $9/node with a three-node minimum, customers pay only for the specific knowledge domains they need, reducing scope friction and creating a natural upgrade path to higher tiers as they add more nodes.

    Why is friction the real barrier rather than price in knowledge products?

    Most knowledge product prospects aren’t declining because the price is objectively too high — they’re declining because the pricing structure forces them to commit to more scope than they currently need. Node pricing addresses scope friction (buying only what you want) and identity friction (avoiding the psychological weight of a large monthly commitment) in ways that discounting alone cannot.

    How does node pricing create an upgrade path to higher tiers?

    Customers who start with three nodes at $27/month add nodes as they discover value. As the node count climbs toward eight or ten, the per-node cost of the Growth tier at $149 becomes more attractive than continuing to add individual nodes. The customer has also been paying throughout this process — establishing a payment relationship and demonstrating intent that makes the tier upgrade a natural next step rather than a new decision.

    What intelligence does node pricing generate about customer demand?

    Node-level purchase data reveals which knowledge sub-verticals customers value enough to pay for, in what order, and in what combinations. This is granular product-market fit data that flat subscription tiers can’t produce. It informs corpus investment priorities, identifies underperforming verticals, and reveals natural scope limits in the customer base — all without additional research spending.

    Why is a $1 first month more effective than a free trial?

    Free trials feel optional because they require no commitment. A $1 first month requires a purchasing decision — the customer has decided this is worth trying rather than just started a free account. This small financial commitment increases activation rates, usage depth, and renewal conversion because customers who pay, even minimally, have already decided the product is worth their attention.

  • Corpus Contributor Model: Build an AI Knowledge Flywheel

    Corpus Contributor Model: Build an AI Knowledge Flywheel

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    The most interesting business models don’t just sell to customers. They turn customers into the product’s engine. There’s a version of this in every category — the marketplace that gets better as more buyers and sellers join, the review platform that gets more useful as more people leave reviews, the map that gets more accurate as more drivers report conditions. Network effects are well understood. But there’s a quieter version of this dynamic that almost nobody is building yet, and it may be more valuable than the classic network effect in the AI era.

    Call it the corpus contributor model. The customer who pays for access to your knowledge base also happens to be a practitioner in the exact domain your knowledge base covers. They use the product. They notice what it gets wrong. They have opinions about what’s missing. And if you build the right mechanic, they can feed those observations back into the corpus — making it more accurate, more complete, and more current than you could ever make it by yourself.

    This is not a theoretical model. It’s a specific architectural decision with specific business implications. And most AI knowledge product builders are missing it entirely.

    What the Corpus Contributor Flip Actually Is

    Floor versus ceiling cards for commoditized work and human-network premium
    What the corpus contributor flip actually is.

    The standard model for a knowledge API product looks like this: you extract knowledge from practitioners, structure it, and sell access to it. The customer is a buyer. The knowledge flows one direction — from your corpus into their AI system. You maintain the corpus. They consume it. Revenue comes from subscriptions.

    The corpus contributor model adds a second flow. The customer — who is themselves a practitioner — also has the option to contribute validated knowledge back into the corpus. Their contribution improves the product for every other customer. In exchange, they get something: a lower subscription rate, a named credit in the corpus, early access to new verticals, or simply a better product faster than the passive subscriber would get it.

    The word “flip” matters here. You are not just adding a feature. You are reframing who the customer is. They are not only a consumer of knowledge. They are simultaneously a source of it. The relationship is bilateral. That changes the economics, the product roadmap, the sales conversation, and the defensibility of the whole business in ways that compound over time.

    Why This Is Different From Crowdsourcing

    The immediate objection is that this sounds like crowdsourcing, which has a complicated track record. Wikipedia works. Most other crowdsourced knowledge projects don’t. The reason Wikipedia works at scale and most others don’t comes down to one thing: intrinsic motivation. Wikipedia contributors edit because they care about the topic. There’s no transaction.

    The corpus contributor model is not crowdsourcing and should not be designed like it. The distinction is selection and validation.

    Selection: You are not asking the general public to contribute. You are asking paying subscribers who have already demonstrated that they operate in this domain by the fact of their subscription. A restoration contractor who pays $149 a month for access to a restoration knowledge API has self-selected into a group with genuine domain expertise and a financial stake in the quality of the product. That is a fundamentally different contributor pool than an open wiki.

    Validation: Contributor submissions don’t go directly into the corpus. They go into a validation queue. Every submission is reviewed against existing knowledge, cross-referenced against standards where they exist, and flagged for expert review when there’s conflict. The contributor model doesn’t replace the extraction and validation process — it feeds it. Contributors surface what’s missing or wrong. The validation layer decides what actually enters the corpus.

    This is closer to the model used by high-quality technical reference databases than to Wikipedia. The contributors are domain insiders with a stake in accuracy. The editorial layer maintains quality. The corpus improves faster than it could with internal extraction alone.

    The Flywheel

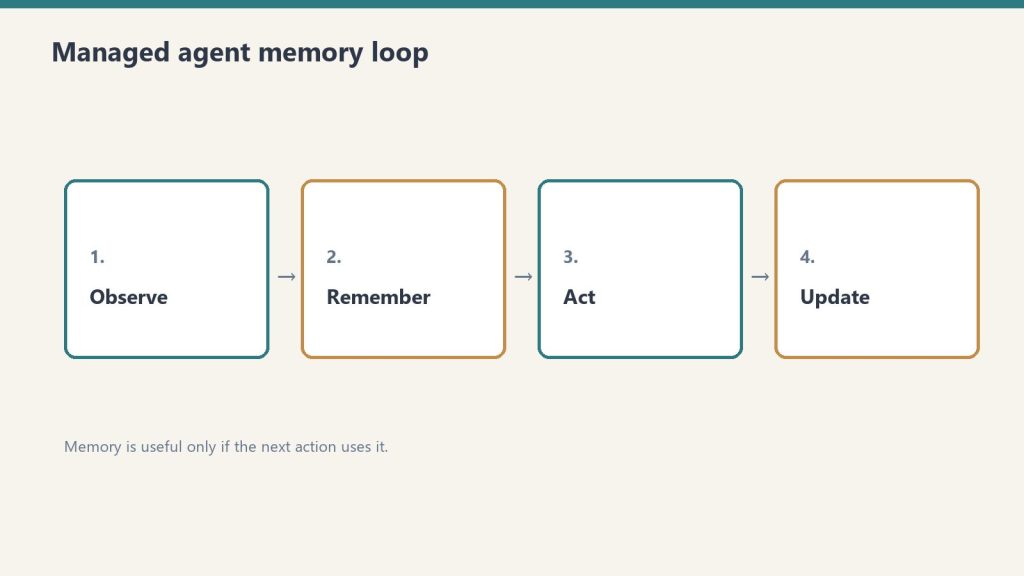
    Four-step loop: observe, remember, act, update for managed agents
    The flywheel.

    Here is where the model gets genuinely interesting. Every traditional subscription business has a churn problem. The customer pays monthly. They evaluate monthly whether the product is worth it. If nothing changes, their willingness to pay is roughly static. The product has to justify itself again and again against a customer whose needs are evolving.

    The corpus contributor model changes this dynamic in two ways that reinforce each other.

    First, contributors have a personal stake in the corpus that passive subscribers don’t. If you submitted three validated knowledge chunks about LGR dehumidification performance in high-humidity climates, and those chunks are now in the corpus being used by other contractors and by AI systems that serve your industry, you have a relationship with that corpus that is qualitatively different from someone who just queries it. You built part of it. Your churn rate is lower because leaving the product means leaving something you helped create.

    Second, the corpus gets better as contributors engage. A better corpus is worth more to new subscribers, which brings in more potential contributors, which improves the corpus further. This is a flywheel, not just a retention mechanic. The passive subscriber benefits from the contributor’s work. The contributor gets a better product to work with. New subscribers join a product that is measurably more accurate and complete than it was six months ago. The value proposition strengthens over time without requiring proportional increases in internal extraction cost.

    Compare this to a standard knowledge API where the corpus is maintained entirely internally. The corpus improves at the rate of your internal extraction capacity. If you can run four extraction sessions a month, you add roughly four sessions’ worth of new knowledge per month. With contributors, that rate is multiplied by however many qualified practitioners are actively engaged. The internal team still controls quality through the validation layer. But the input volume grows with the customer base rather than with internal headcount.

    The Enterprise Version

    Individual contributors are valuable. Enterprise contributors are transformative.

    Consider a restoration software company that builds job management tools for contractors. They have access to millions of completed job records — real-world data on what drying protocols were used on what loss categories in what climate conditions, with what outcomes. That data, properly structured and validated, is worth dramatically more to a restoration knowledge corpus than anything extractable from individual interviews.

    The standard sales conversation with that company is: “Pay us $499 a month for API access.” That’s fine. It’s a transaction.

    The corpus contributor conversation is different: “We want to build the knowledge infrastructure that makes your product’s AI features better. You have data we need. We have a structured corpus and a validation layer you’d spend years building. Let’s make the corpus jointly better and share the value.” That’s a partnership conversation. It changes the deal size, the relationship depth, and the defensibility of the resulting product — because the enterprise contributor’s data is now embedded in a corpus they can’t easily replicate by going to a competitor.

    Enterprise corpus contributors also create a named knowledge layer opportunity. The restoration software company’s contributed data doesn’t disappear into an anonymous corpus — it’s credited, tracked, and potentially sold as a named vertical: “Job outcome data layer, contributed by [Partner].” That attribution has marketing value for the contributor and validation signal for the subscribers who use it. Everyone’s incentives align.

    What the Sales Conversation Becomes

    The corpus contributor model changes the initial sales conversation in a way that most knowledge product builders miss because they’re too focused on the subscription tier.

    The standard pitch leads with access: “Here’s what you can query. Here’s the price.” That’s a cost-benefit conversation. The prospect weighs whether the knowledge is worth the fee.

    The contributor pitch leads with participation: “You know things we need. We have infrastructure you’d spend years building. Join as a contributor and help shape the corpus your AI stack runs on.” That’s a different conversation entirely. It’s not about whether the existing product justifies its price — it’s about whether the prospect wants to have a role in what the product becomes.

    For practitioners who care about their industry’s AI infrastructure — and in most verticals, there are a meaningful number of these people — the contributor framing is more compelling than the subscriber framing. It gives them agency. It makes them a participant in something larger than a software subscription. That is a qualitatively different reason to write a check, and it is stickier than feature value alone.

    The Validation Layer Is the Business

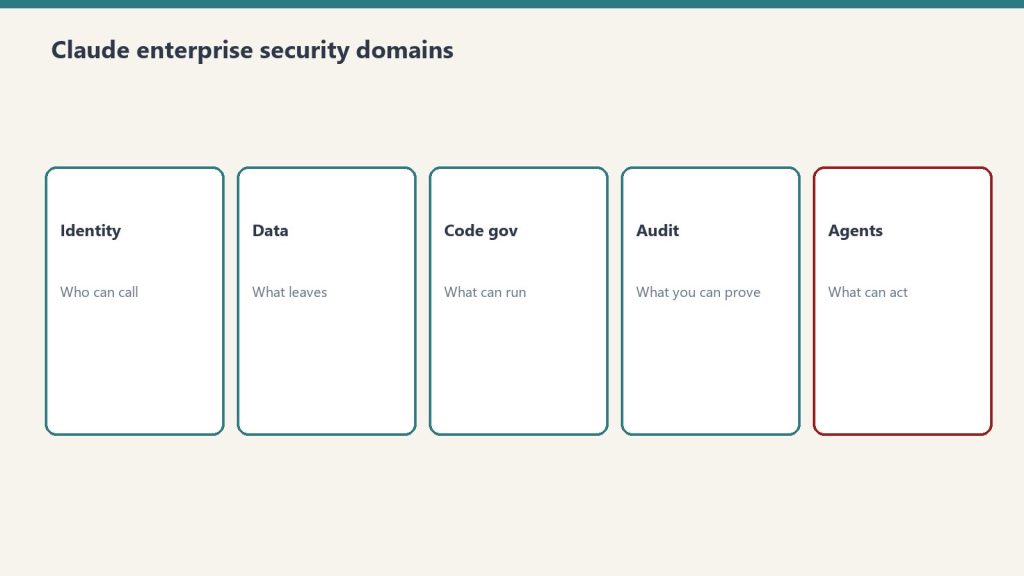
    Five security domains: identity, data, code governance, audit, agents
    The validation layer is the business.

    Everything described above depends on one thing working correctly: the validation layer. If contributors can inject bad knowledge into the corpus, the product becomes unreliable. If the validation layer is so restrictive that nothing gets through, the contributor mechanic produces no value. The design of the validation layer is where the real intellectual work of the corpus contributor model lives.

    A well-designed validation layer has three properties. It is domain-aware — it knows enough about the field to evaluate whether a contribution is plausible, consistent with existing knowledge, and meaningfully different from what’s already there. It is conflict-surfacing — when a contribution contradicts existing corpus entries, it flags the conflict for expert review rather than silently accepting or rejecting either. And it is contributor-transparent — contributors can see the status of their submissions, understand why something was accepted or rejected, and engage in a dialogue about contested points.

    The validation layer is also the moat that a competitor can’t easily replicate. Building a corpus takes time. Building relationships with contributors takes time. But building the domain expertise required to run a validation layer that practitioners trust — that takes the longest. It’s the part of the business that scales slowest and defends best.

    Who Should Build This First

    The corpus contributor model is available to any knowledge product company that has, or can develop, three things: a practitioner customer base with genuine domain expertise, an extraction and validation infrastructure that can process contributions at volume, and the product design capability to build a contribution mechanic that practitioners actually use.

    In the restoration industry, the conditions are nearly ideal. The customer base — contractors, adjusters, estimators, project managers — has deep domain knowledge and a direct financial interest in AI tools that work correctly. The knowledge gaps are enormous and well-understood. And the trust infrastructure, built through trade associations, peer networks, and industry events, already exists as a substrate for the kind of relationship-based contributor model that works at scale.

    The first knowledge product company in any vertical to implement the corpus contributor model well will have an advantage that is very difficult to replicate. Not because their technology is better. Because they turned their customers into co-authors of the most defensible asset in vertical AI.

    Related on Tygart Media: jobs as knowledge base · information density · GEO tactics.

    Frequently Asked Questions

    What is the corpus contributor model in AI knowledge products?

    The corpus contributor model is a product architecture where paying customers — who are domain practitioners — also have the option to contribute validated knowledge back into the product’s knowledge base. This creates a bilateral relationship where the customer is both a consumer and a source of knowledge, improving the corpus faster than internal extraction alone could achieve.

    How is this different from crowdsourcing?

    The corpus contributor model differs from crowdsourcing in two critical ways: selection and validation. Contributors are self-selected domain practitioners who pay for access, not anonymous volunteers. And contributions pass through a structured validation layer before entering the corpus — they don’t go in automatically. This makes it closer to a high-quality technical reference database model than an open wiki.

    Why does the corpus contributor model reduce churn?

    Contributors develop a personal stake in the corpus that passive subscribers don’t have. Having built part of the product, contributors are less likely to cancel because leaving means leaving something they helped create. Additionally, active contributors see the corpus improving in response to their input, which reinforces the value they’re receiving beyond passive access.

    What makes enterprise corpus contributors particularly valuable?

    Enterprise contributors — such as software companies with large volumes of structured job outcome data — can contribute knowledge at a scale and quality that individual extraction sessions can’t match. Their data also creates a named knowledge layer opportunity: credited, tracked contributions that signal validation quality to other subscribers and create a partnership relationship that is significantly stickier than a standard subscription.

    What is the validation layer and why does it matter?

    The validation layer is the quality control system that evaluates contributor submissions before they enter the corpus. It must be domain-aware enough to assess plausibility, conflict-surfacing when contributions contradict existing knowledge, and transparent enough that contributors understand how their submissions are evaluated. The validation layer is also the hardest component to replicate, making it the deepest competitive moat in the model.

  • AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    AI Extraction Layer: The Most Valuable Asset AI Can’t Build

    Tygart Media Strategy
    Volume Ⅰ · Issue 04 Quarterly Position
    By Will Tygart Long-form Position Practitioner-grade

    The extraction layer is the part of the AI economy that doesn’t exist yet — and it’s the only part that can’t be automated into existence. Every vertical AI product, every industry-specific chatbot, every AI assistant that actually knows what it’s talking about requires one thing that nobody has figured out how to manufacture at scale: the deep, tacit, hard-won knowledge that lives inside experienced human practitioners.

    This is not a gap that will close on its own. It is a structural feature of how expertise works. And for the businesses and individuals who understand it clearly, it is the single most durable competitive advantage available in the current AI era.

    What the Extraction Layer Actually Is

    Floor versus ceiling cards for commoditized work and human-network premium
    What the extraction layer actually is.

    When people talk about AI knowledge gaps, they usually mean one of two things: either the model hasn’t been trained on recent data, or the model lacks access to proprietary databases. Both of those are real problems. Neither of them is the extraction layer problem.

    The extraction layer problem is different. It’s the gap between what an experienced practitioner knows and what has ever been written down in a form that any AI system — regardless of its training data or database access — can actually use.

    A 30-year restoration contractor who has dried 2,000 structures knows things that have never been documented anywhere. Not because they were keeping secrets. Because the knowledge is embedded in judgment calls, pattern recognition, and muscle memory that wasn’t worth writing down at the time. They know which psychrometric conditions in a basement after a Category 2 loss require an LGR versus a conventional dehumidifier, and why. They know the exact moment a water damage job transitions from “drying” to “reconstruction” based on a combination of readings and smells and wall flex that no textbook captures. They know which insurance adjusters will fight a mold scope and which ones will approve it without a second look.

    None of that knowledge is in any training dataset. None of it will be in any training dataset until someone does the hard, slow, relationship-dependent work of pulling it out of people’s heads and putting it into structured form.

    That is the extraction layer. And it requires humans.

    Why AI Cannot Close This Gap By Itself

    Three stacked layers: chat UI, tools, agent runtime
    Why AI cannot close this gap by itself.

    The reflex response to any knowledge gap problem in 2026 is to propose an AI solution. Train a bigger model. Scrape more data. Use retrieval-augmented generation with a larger corpus. There is genuine value in all of those approaches. None of them solves the extraction layer problem.

    The issue is not volume or recency. The issue is source availability. Training data and RAG systems can only work with knowledge that has been externalized — written, recorded, structured, published somewhere that a crawler or an ingestion pipeline can reach. Tacit expertise, by definition, hasn’t been externalized. It exists as neural patterns in someone’s head, not as tokens in a document.

    There are things AI can do well that partially address this. AI can synthesize patterns from large volumes of existing text. It can identify gaps in documented knowledge by mapping what questions get asked versus what answers exist. It can transcribe and structure interviews once they’ve been recorded. But AI cannot conduct the interview. It cannot build the relationship that earns the trust required to get a 25-year adjuster to walk through their actual decision logic on a contested mold claim. It cannot recognize, in the middle of a conversation, that the contractor just said something technically significant that they treated as throwaway context.

    The extraction process requires a human who understands the domain well enough to know what they’re hearing, has the relationship to access the right people, and has the patience to do this work over months and years rather than in a single API call. That is not a temporary limitation of current AI systems. It is a structural property of how tacit knowledge works.

    The Pre-Ingestion Positioning

    There is a second reason the extraction layer matters beyond the knowledge itself: where in the AI stack you sit determines your liability exposure, your defensibility, and your pricing power.

    Most businesses that try to participate in the AI economy position themselves downstream of AI processing — they modify outputs, review generated content, add a human approval layer on top of AI decisions. That positioning puts them in the output chain. When something goes wrong, they are implicated. The AI said it, but they delivered it.

    The extraction layer positions you upstream — before the AI processes anything. You are the raw data source. The same category as a web search result, a database query, a regulatory filing. The AI system that consumes your knowledge is responsible for what it does with it. You are responsible for the quality of the knowledge itself.

    This is how every B2B data vendor in the world operates. DataForSEO does not guarantee your search rankings. Bloomberg does not guarantee your trades. They guarantee the accuracy and quality of the data they provide. What downstream systems do with that data is those systems’ problem. The pre-ingestion positioning applies the same logic to industry knowledge: guarantee the knowledge, not the outputs built on top of it.

    This single reframe changes the risk profile of being in the knowledge business entirely.

    What Makes Extraction Layer Knowledge Defensible

    Three panels showing one problem, three options, one recommendation
    What makes extraction-layer knowledge defensible.

    In a market where AI can write a competent 1,500-word blog post about mold remediation in 45 seconds, content is not a moat. But the knowledge that makes a 1,500-word blog post about mold remediation actually correct — the kind of correct that a working contractor or an insurance adjuster would recognize as coming from someone who has actually done this — that is a moat.

    There are four properties that make extraction layer knowledge genuinely defensible:

    Relationship dependency. The best knowledge comes from people who trust you enough to share their actual mental models, not their public-facing summaries. That trust is earned over time through consistent contact, demonstrated competence, and reciprocal value. It cannot be purchased or automated. A competitor who wants to build a comparable restoration knowledge corpus doesn’t start by writing code — they start by spending three years attending trade events and building relationships with people who know things. The time cost is the moat.

    Validation depth. Anyone can collect statements from practitioners. Collecting statements that have been cross-validated against field outcomes, regulatory standards, and peer review is a different operation entirely. A knowledge chunk that says “humidity levels above 60% RH for more than 72 hours in a structure with cellulose materials creates conditions for mold amplification” is only valuable if it’s been validated against IICRC S520 and corroborated by practitioners in multiple climate zones. The validation work is slow, expensive, and domain-specific. That’s what makes it valuable.

    Structural format. Raw interview transcripts are not an API. The extraction work includes converting practitioner knowledge into machine-readable, consistently structured formats that AI systems can actually consume without hallucinating context. This requires both domain knowledge and technical architecture. Most domain experts don’t have the technical skills. Most technical people don’t have the domain knowledge. The people who have both, or who have built teams that combine both, have a significant advantage.

    Maintenance obligation. Industry knowledge changes. Regulatory standards update. Best practices evolve as new equipment enters the market. A static knowledge corpus becomes a liability as it ages. The commitment to maintaining knowledge over time — keeping relationships active, re-validating chunks, incorporating new field evidence — is itself a barrier that competitors can’t easily replicate.

    The Compound Effect

    Here is what makes the extraction layer position genuinely interesting over a long time horizon: it compounds.

    Every extraction session adds to the corpus. Every validation pass improves accuracy. Every new practitioner relationship opens access to adjacent knowledge that wouldn’t have been reachable without the trust built in the previous relationship. The corpus that exists after three years of sustained extraction work is not three times as valuable as the corpus after year one — it’s potentially ten or twenty times as valuable, because the knowledge chunks have been cross-validated against each other, the gaps have been identified and filled, and the relationships that generate ongoing updates are deep enough to provide real-time field intelligence.

    Meanwhile, the barrier to entry for a new competitor grows with every passing month. They are not three years behind on code — they are three years behind on relationships, validation work, and corpus structure. Those things don’t accelerate with more investment the way software development does. You can hire ten engineers and ship in months what one engineer would take years to build. You cannot hire ten field relationships and develop in months what one relationship would take years to earn.

    Where This Is Going

    The most valuable AI products of the next decade will not be the ones with the most parameters or the most compute. They will be the ones with access to the best knowledge. In most industries, that knowledge hasn’t been extracted yet. It’s still sitting in the heads of practitioners, waiting for someone to do the patient, human-intensive work of getting it out and into machine-readable form.

    The businesses that move on this now — while the extraction layer is still largely empty — will have a significant and durable advantage over those who wait. The technical infrastructure to build with extracted knowledge exists today. The AI systems that can consume and deliver it exist today. The market that wants vertical AI products with genuine domain expertise exists today.

    The only scarce input is the knowledge itself. And the only way to get it is to do the work.

    The Practical Question

    Every industry has an extraction layer problem. The question is who is going to solve it.

    In restoration, the practitioners who have seen thousands of losses, negotiated thousands of claims, and developed the judgment that comes from being wrong in expensive ways and learning from it — that knowledge base exists. It’s distributed across individual careers and company histories, mostly undocumented, largely inaccessible to the AI systems that restoration companies are increasingly building or buying.

    The same is true in radon mitigation, luxury asset appraisal, cold chain logistics, medical triage, and every other field where the difference between a good decision and a bad one depends on knowledge that was never worth writing down at the time it was learned.

    The extraction layer is not a technical problem. It is a knowledge infrastructure problem. And the first movers who build that infrastructure — who do the relationship work, run the extraction sessions, structure the knowledge, and maintain it over time — will be sitting on the most defensible position in vertical AI.

    Not because they built a better model. Because they did the work AI can’t.

    Frequently Asked Questions

    What is the extraction layer in AI?

    The extraction layer refers to the process of converting tacit, practitioner-held knowledge into structured, machine-readable formats that AI systems can consume. It sits upstream of AI processing and requires human relationship-building, domain expertise, and sustained extraction effort that cannot be automated.

    Why can’t AI build its own knowledge base from existing content?

    AI training and retrieval systems can only work with externalized knowledge — content that has been written, recorded, and published somewhere accessible. Tacit expertise exists as judgment and pattern recognition in practitioners’ minds, not as tokens in any document. It requires active extraction through interviews, observation, and validation before it can enter any AI system.

    What makes extraction layer knowledge defensible as a business asset?

    Four properties make it defensible: relationship dependency (earning practitioner trust takes years and cannot be purchased), validation depth (cross-referencing against standards and field outcomes is slow and domain-specific), structural format (converting raw knowledge to structured AI-consumable formats requires both domain and technical expertise), and maintenance obligation (keeping knowledge current requires sustained investment that most competitors won’t make).

    How does pre-ingestion positioning reduce AI liability?

    By positioning as an upstream data source rather than a downstream output modifier, knowledge providers follow the same model as all major B2B data vendors: they guarantee the quality of the knowledge itself, not what downstream AI systems do with it. This is structurally different from businesses that modify or deliver AI outputs, which puts them in the output liability chain.

    What industries have the largest extraction layer gaps?

    Any industry where expert judgment is built through years of practice rather than documented procedure has significant extraction layer gaps. Restoration contracting, radon mitigation, luxury asset appraisal, insurance claims adjustment, cold chain logistics, and specialized medical triage are examples where practitioner knowledge vastly exceeds what has ever been formally documented.

  • AI Extraction Agent: Replacing the Human Interviewer

    AI Extraction Agent: Replacing the Human Interviewer

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    The extraction protocol works. The pivot signal lexicon is learnable. The four-layer descent can be taught. The question is whether it can be deployed without a trained human interviewer in the room — and if so, how much of the value survives the translation.

    This is the duplication problem at the center of the Human Distillery business model. Will can run an extraction session. An app cannot run the same session. But an app can run a version of the session — and for a large subset of extraction use cases, the version is sufficient.

    Understanding what transfers and what doesn’t is the whole architectural question.

    What Transfers to an App

    The four-layer question structure is codifiable. A stateful conversational agent — not a chatbot, a system that maintains a running knowledge map of what’s been surfaced and what’s still needed — can execute the question sequences in order, navigate the domain-specific question libraries for a given vertical, and detect the linguistic markers of pivot signals in real time.

    “It’s hard to explain” is detectable by NLP. Hedging patterns are detectable. Energy shifts in voice are detectable by acoustic analysis. Deflection to process — “the policy says…” — is detectable. The app can recognize these signals and adjust its question path, slowing down at tacit knowledge boundaries and applying the correct follow-up from the signal response library.

    The processing pipeline from transcript to structured concentrate is fully automatable: chunking by topic boundary, entity extraction, claim isolation, confidence scoring, contradiction flagging across multiple sessions, multi-model distillation rounds. This is where AI earns its keep. A human doing this manually would take days per session. The pipeline does it in minutes.

    Domain-specific question libraries can be built from prior extractions and expanded with each new session. The more sessions the app runs in a given vertical, the richer its question library becomes. This is the compounding effect that makes the app more valuable over time.

    What Doesn’t Transfer

    Three things resist automation in ways that won’t be resolved by better models:

    Micro-hesitation reading. The half-second pause before an answer that signals the subject knows more than they’re about to say. The slight change in phrasing when someone moves from what they’re comfortable saying to what they actually think. These are real-time, embodied, relational signals. A text-based app misses them entirely. A voice app gets closer but still lacks the visual channel that carries a significant portion of this information.

    Protocol abandonment. The decision to stop following the four-layer sequence because the subject just said something unprompted that is more important than anything in the protocol. Expert interviewers make this call constantly. They recognize the thread that, if followed, goes somewhere the protocol would never reach. An app will follow the signal response library. It won’t recognize when the library should be put down.

    Trust calibration. Whether the subject is performing for the recording or actually sharing. This is not detectable from content analysis. It requires the social intelligence to know when to lower the formality, when to match the subject’s energy, when to say something self-deprecating to signal that this is a peer conversation and not an evaluation. Subjects share differently with someone they trust. The app cannot build that trust.

    The Honest Architecture

    The tiered model that emerges from this analysis:

    Tier 1 — App-led extraction. Well-mapped domains with accessible knowledge. The subject is cooperative. The question library is deep. The knowledge being sought is in Layers 1 and 2. The app handles the session. Will reviews the concentrate before delivery.

    Tier 2 — Human-led extraction with app processing. High-stakes sessions. Guarded subjects. Knowledge at the outer edge of verbalization (Layer 3 and 4). Will conducts the session. The app runs the processing pipeline. Will reviews and approves the concentrate.

    Tier 3 — Full human extraction and distillation. Strategic engagements. Subjects who will only speak candidly to a person they know. Knowledge so embedded that it requires real-time relational judgment to surface at all. Will does everything.

    The business model implication: Tier 1 is volume. Tier 3 is premium. The ratio shifts over time as the app’s question libraries deepen and its signal detection improves. What begins as mostly Tier 2 and 3 eventually becomes mostly Tier 1, with Will’s direct involvement reserved for the sessions where only a human can get the door open.

    The app is not a replacement for the protocol. It’s a multiplier for the protocol — allowing it to run at a scale that a single human operator never could, while preserving the human layer for the cases that actually require it.


  • AI Work Order Architecture: Decoupling AI & Execution

    AI Work Order Architecture: Decoupling AI & Execution

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    AI systems are good at identifying problems. Automated systems are good at fixing them. The failure mode that kills most AI automation projects is building them as one thing instead of two.

    When you couple intelligence and execution in a single system, you get something that can do everything slowly and nothing reliably. The intelligence layer needs to be conversational, contextual, and judgment-driven. The execution layer needs to be deterministic, fast, and parallelizable. These are fundamentally different behaviors, and they require different tools.

    The Work Order as the Bridge

    The behavior-first design for AI automation has three distinct stages: identify (Claude analyzes a system and surfaces what needs to be done), deposit (Claude writes a structured work order to a persistent queue), and execute (a Cloud Run worker reads the work order and runs the fix).

    The work order is the key artifact. It’s the contract between the intelligence layer and the execution layer. A well-formed work order contains everything the execution layer needs to run without asking Claude any follow-up questions: the target (site, post ID, endpoint), the operation (what to do), the parameters (how to do it), and the success criteria (how to know it worked).

    When the work order is well-formed, the execution layer is a dumb runner. It doesn’t need to understand context, history, or judgment. It reads the work order, executes the operation, and writes the result back. The intelligence that produced the work order stays in the intelligence layer — which is exactly where it belongs.

    What This Looks Like in Practice

    In a multi-site content operation, Claude might analyze a WordPress site and identify 47 posts with missing FAQ schema. The tool-first approach runs Claude in a loop, generating and publishing schema for each post sequentially. This is slow, context-dependent, and fragile — if Claude loses context mid-run, the job is incomplete and the state is unclear.

    The behavior-first approach: Claude generates 47 structured work orders, one per post, and deposits them in a Notion database with status “Queued.” A Cloud Run service reads the queue and processes each work order independently, in parallel, writing results back to each row. Claude is done in minutes. The Cloud Run service finishes the execution while Claude is doing something else entirely.

    The behaviors are clean. The tools serve them. The system scales horizontally without requiring Claude to be in the loop for execution.

    The Two Lanes of AI Automation

    Not everything belongs in the work order queue. Some operations require judgment that the execution layer can’t replicate: content quality assessment, strategy decisions, anything where “it depends” is the correct first answer. These belong in a different lane — one where Claude stays in the loop through completion.

    A mature AI automation architecture has both lanes clearly defined. Deterministic operations (taxonomy fixes, schema injection, meta rewrites, image uploads, internal link additions) go to the work order queue and run without Claude. Judgment-dependent operations (content strategy, quality review, client recommendations) stay in the conversational layer where Claude’s judgment can be applied continuously.

    The discipline is in knowing which lane each operation belongs in — and resisting the temptation to put judgment-dependent work in the queue just because it would be faster. Faster execution of the wrong thing is not an improvement.


  • Notion Claude Memory: Setup Guide for Persistent Context

    Notion Claude Memory: Setup Guide for Persistent Context

    Last refreshed: May 15, 2026

    Update — May 15, 2026: On May 13, 2026, Notion shipped the Notion Developer Platform (version 3.5), with Claude as a launch partner. The platform adds Workers, database sync, an External Agents API, and a Notion CLI. The patterns described in this article still work, but there is now a native, sanctioned alternative for some of what previously required custom MCP wiring or third-party automation. For the full breakdown of what changed and what it means for the Notion + Claude stack, see Notion Developer Platform Launch (May 13, 2026). For the underlying operating philosophy, see The Three-Legged Stack.

    Claude AI · Fitted Claude

    Claude doesn’t remember anything between sessions by default. Every conversation starts from zero. For casual use, that’s fine. For an operator running a complex business across multiple clients, projects, and entities, that reset is a real problem — and the solution is architectural, not a workaround.

    Here’s how to set up Notion so Claude has the context it needs at the start of every session, without you manually rebuilding it every time.

    How do you set up Notion so Claude remembers everything? You don’t make Claude remember — you make the relevant context retrievable. A Claude-ready Notion setup has three components: a metadata standard that makes key pages machine-readable, a master index Claude fetches at session start to know what exists, and a session logging practice that captures what was decided so the next session can pick up where the last one ended. Together these create functional persistence without relying on Claude’s native memory.

    What “Remembering” Actually Means

    Four cards for content, ops, build, and knowledge work with Claude
    What remembering actually means.

    It’s worth being precise about what we’re solving for. Claude’s context window — the information it has access to during a session — is large. The problem is that it resets between sessions. Information from Monday’s session isn’t available in Tuesday’s session unless it’s either in the system prompt or retrieved during the new session.

    The goal isn’t to give Claude a persistent memory in the biological sense. The goal is to ensure that any context Claude would need to operate effectively in a new session is stored somewhere Claude can retrieve it, and that Claude knows to retrieve it before starting work.

    That’s a knowledge management problem, not an AI problem. Solve the knowledge management problem and the memory problem resolves itself.

    Step 1: The Metadata Standard

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Step 1 — the metadata standard.

    Every key Notion page needs a brief structured metadata block at the top — before any human-readable content. The metadata block makes the page machine-readable: Claude can read the summary and understand the page’s purpose and key constraints without reading the full content.

    The minimum viable metadata block for each page includes: what type of document this is (SOP, reference, project brief, decision log), its current status (active, evergreen, draft), a two-to-three sentence plain-language summary of what the page contains and when to use it, and a resume instruction — the single most important thing to know before acting on this page’s content.

    With this block in place, Claude can orient itself to any page in seconds. Without it, Claude has to read the full page to understand whether it’s relevant — which is slow and impractical at scale.

    Step 2: The Master Index

    The master index is a single Notion page that lists every key knowledge page in the workspace: its title, Notion page ID, type, status, and one-line summary. Claude fetches this page at the start of any session that involves the knowledge base.

    The index answers the question Claude needs answered before it can retrieve anything: what exists and where is it? Without the index, Claude would need to search for relevant pages by keyword — imprecise and dependent on the page having the right words. With the index, Claude can scan the full list of what exists and identify exactly which pages are relevant to the current task.

    Keep the index current. Add a row whenever a significant new page is created. Archive rows when pages are deprecated. The index is only useful if it accurately represents what’s in the knowledge base.

    Step 3: Session Logging

    The session log is the practice that creates true continuity across sessions. At the end of any significant working session, a brief log entry captures what was decided, what was done, and what the next step is. That log entry lives in the Knowledge Lab as a dated record.

    The next session starts by reading the most recent session log for the relevant project or client. Claude picks up with full awareness of what the previous session decided and where the work stands — not because it remembered, but because the information was captured and is retrievable.

    Session logs don’t need to be long. Three to five sentences covering the key decisions and the next step is sufficient. The goal is continuity, not comprehensive documentation. A session log that takes two minutes to write saves ten minutes of context reconstruction at the start of the next session.

    The Start-of-Session Protocol

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The start-of-session protocol.

    With the metadata standard, master index, and session logging in place, every session starts the same way: “Read the Claude Context Index and the most recent session log for [project/client], then let’s work on [task].”

    Claude fetches the index, identifies the relevant pages, fetches those pages and reads their metadata blocks, reads the most recent session log, and begins work with genuine operational context. The context transfer that used to require ten minutes of manual explanation happens in under a minute of automated retrieval.

    This protocol works because the setup work was done upfront. The metadata blocks were written. The index was created and maintained. The session logs were captured. The session start protocol is fast because the knowledge management discipline that makes it fast was already in place.

    What This Doesn’t Replace

    This architecture doesn’t replace judgment about what’s worth capturing. Not every session produces information worth logging. Not every Notion page needs a metadata block. The discipline of the system is knowing what deserves to be in the knowledge base and what doesn’t — and being honest about the maintenance overhead that every addition creates.

    A knowledge base that captures everything becomes a knowledge base that surfaces nothing useful. The curation decision — what goes in, what stays out — is as important as the architecture that stores it.

    Want this set up correctly?

    We configure the Notion + Claude memory architecture — the metadata standard, the Context Index, the session logging practice, and the start-of-session protocol — as a done-for-you implementation.

    Tygart Media runs this system in daily operation. We know what makes it work and what breaks it.

    See what we build →

    Frequently Asked Questions

    Does Claude have a memory feature that makes this unnecessary?

    Claude has a memory system in claude.ai that captures information from conversations and surfaces it in future sessions. This is useful for personal context — preferences, background, recurring topics. For operational context in a business setting — current project status, client-specific constraints, recent decisions — the Notion-based architecture described here is more reliable, more comprehensive, and more controllable. The two approaches complement each other rather than competing.

    How often should session logs be written?

    For sessions that produce significant decisions, complete meaningful work, or advance a project to a new stage — write a log entry. For sessions that are purely exploratory or produce nothing durable — skip it. The rule of thumb: if the next session on this topic would benefit from knowing what happened in this session, write the log. If not, don’t. Logging every session creates overhead without value; logging selectively keeps the knowledge base signal-dense.

    What’s the difference between a session log and a Notion page?

    A session log is a dated record of what happened in a specific working session — decisions made, work completed, next steps identified. A Notion knowledge page is a durable reference document — an SOP, an architecture decision, a client reference — that’s meant to be read and used repeatedly. Session logs are ephemeral and time-stamped. Knowledge pages are evergreen and maintained. Both are in the Knowledge Lab database, distinguished by the Type property.

    Can this setup work for a team, not just a solo operator?

    Yes, with additional structure. The metadata standard and master index work the same for a team. Session logging becomes more important with multiple people working on the same projects — the log creates a shared record of what was decided so team members don’t reconstruct it for each other. The additional requirement for a team is clarity about who owns the knowledge base maintenance — who updates the index, who reviews pages for currency, who writes the session logs. Without that ownership, the system degrades quickly in a team setting.

  • AI-Native Business: Building on GCP, Notion, and Claude

    AI-Native Business: Building on GCP, Notion, and Claude

    Last refreshed: May 15, 2026

    Claude AI · Fitted Claude

    Running an AI-native business in 2026 means making a decision about infrastructure that most operators don’t realize they’re making. You can run AI operations reactively — open Claude, do the work, close the session, repeat — or you can build an infrastructure layer that makes every session faster, more consistent, and more capable than the last.

    We chose the second path. The stack is Google Cloud Platform for compute and data infrastructure, Notion for operational knowledge, and Claude as the AI intelligence layer. Here’s what that combination looks like in practice and why each piece is there.

    What does it mean to run an AI-native business on GCP and Notion? An AI-native business on GCP and Notion uses Google Cloud Platform for infrastructure — compute, storage, data, and AI APIs — and Notion as the operational knowledge layer, with Claude connecting the two as the intelligence and orchestration layer. Content publishing, image generation, knowledge retrieval, and operational logging all run through this stack. The business is not just using AI tools; it’s built on AI infrastructure.

    Why GCP

    Google Cloud Platform provides three things that matter for an AI-native content operation: scalable compute via Cloud Run, AI APIs via Vertex AI, and data infrastructure via BigQuery. All three integrate cleanly with each other and with external services through standard APIs.

    Cloud Run handles the services that need to run continuously or on demand without managing servers: the WordPress publishing proxy that routes content to client sites, the image generation service that produces and injects featured images, the knowledge sync service that keeps BigQuery current with Notion changes. These services run when triggered and cost nothing when idle — the right economics for an operation that doesn’t need 24/7 uptime but does need reliable on-demand availability.

    Vertex AI provides access to Google’s image generation models for featured image production, with costs that scale predictably with usage. For an operation producing hundreds of featured images per month across client sites, the per-image cost at scale is significantly lower than commercial image generation alternatives.

    BigQuery provides the data layer described in the persistent memory architecture: the operational ledger, the embedded knowledge chunks, the publishing history. SQL queries against BigQuery return results in seconds for datasets that would be unwieldy in Notion.

    Why Notion

    Four cards for content, ops, build, and knowledge work with Claude
    Why Notion sits at the center of an AI-native business stack.

    Notion is the human-readable operational layer — the place where knowledge lives in a form that both people and Claude can navigate. The GCP infrastructure handles compute and data. Notion handles knowledge and workflow. The division of responsibility is clean: GCP for machine-scale operations, Notion for human-scale understanding.

    The Notion Command Center — six interconnected databases covering tasks, content, revenue, relationships, knowledge, and the daily dashboard — is the operational OS for the business. Every piece of work that matters is tracked here. Every procedure that repeats is documented here. Every decision that shouldn’t be made twice is logged here.

    The Notion MCP integration is what makes Claude a genuine participant in that system rather than an external tool. Claude reads the Notion knowledge base, writes new records, updates status, and logs session outputs — all directly, without requiring a manual transfer step between Claude and Notion.

    Where Claude Sits in the Stack

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Where Claude sits in the stack.

    Claude is the intelligence and orchestration layer. It doesn’t replace the GCP infrastructure or the Notion knowledge base — it uses them. A content production session starts with Claude reading the relevant Notion context, proceeds with Claude drafting and optimizing content, and ends with Claude publishing to WordPress via the GCP proxy and logging the output to both Notion and BigQuery.

    The session is not just Claude doing a task and returning a result. It’s Claude operating within a system that provides it with context going in and captures its outputs coming out. The infrastructure is what makes that possible at scale.

    What This Stack Enables

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What this stack enables day to day.

    The combination of GCP infrastructure and Notion knowledge unlocks operational capabilities that neither provides alone. Content can be generated, optimized, image-enriched, and published to multiple WordPress sites in a single Claude session — because the GCP services handle the technical distribution and the Notion context provides the client-specific constraints that govern each site. Knowledge produced in one session is immediately available in the next — because BigQuery captures it and Notion stores the human-readable version. The operation runs at a scale that one person couldn’t manage manually — because the infrastructure handles the mechanical work while Claude handles the intelligence work.

    What This Stack Costs

    The honest cost picture: GCP infrastructure at our operating scale runs modest monthly costs, primarily driven by Cloud Run service invocations and Vertex AI image generation. Notion Plus for one member is around ten dollars per month. Claude API usage for content operations varies with session volume. The total monthly infrastructure cost for the stack is a small fraction of what equivalent human labor would cost for the same output volume — which is the point of building infrastructure rather than hiring for scale.

    Interested in building this infrastructure?

    The GCP + Notion + Claude stack is advanced infrastructure. We consult on the architecture and can help design the right version for your operation’s scale and requirements.

    Tygart Media built and runs this stack live. We know what the implementation actually requires and where the complexity is.

    See what we build →

    Related on Tygart Media: Notion Command Center · OpenRouter field manual · Claude pricing.

    Frequently Asked Questions

    Do you need GCP to run an AI-native content operation?

    No — GCP is one infrastructure option among several. The core stack (Claude + Notion) works without any cloud infrastructure for smaller operations. GCP becomes valuable when you need reliable service infrastructure for publishing automation, image generation at scale, or data infrastructure for persistent memory. Operators starting out don’t need GCP; operators scaling up often find it the right addition.

    How does Claude connect to GCP services?

    Claude connects to GCP services through standard REST APIs and the MCP (Model Context Protocol) integration layer. Cloud Run services expose HTTP endpoints that Claude calls during sessions. BigQuery is queried via the BigQuery API. Vertex AI image generation is called via the Vertex AI REST API. Claude orchestrates these calls as part of a session workflow — fetching context, generating content, calling publishing APIs, logging results.

    Is this architecture HIPAA or SOC 2 compliant?

    GCP offers HIPAA-eligible services and SOC 2 certification. A “fortress architecture” — content operations running entirely within a GCP Virtual Private Cloud with appropriate data handling controls — can be configured to meet healthcare and enterprise compliance requirements. This is an advanced implementation beyond the standard stack described here, but it’s achievable within the GCP environment for organizations with those requirements.

  • Persistent AI Memory Layer: BigQuery & Notion Architecture

    Persistent AI Memory Layer: BigQuery & Notion Architecture

    Last refreshed: May 15, 2026

    Claude AI · Fitted Claude

    The hardest problem in running an AI-native operation is not the AI — it’s the memory. Claude’s context window is large but finite. It resets between sessions. Every conversation starts from zero unless you engineer something that prevents it.

    For a solo operator running a complex business across multiple clients and entities, that reset is a real operational problem. The solution we built combines Notion as the human-readable knowledge layer with BigQuery as the machine-readable operational history — a persistent memory infrastructure that means Claude never truly starts from scratch.

    Here’s how the architecture works and why each layer exists.

    What is a BigQuery + Notion AI memory layer? A BigQuery and Notion AI memory layer is a two-tier persistent knowledge infrastructure where Notion stores human-readable operational knowledge — SOPs, decisions, project context — and BigQuery stores machine-readable operational history — publishing records, session logs, embedded knowledge chunks — that Claude can query during a live session. Together they provide Claude with both the institutional knowledge of the operation and the operational history of what has been done.

    Why Two Layers

    Four cards for content, ops, build, and knowledge work with Claude
    Why two layers.

    Notion and BigQuery solve different parts of the memory problem.

    Notion is optimized for human-readable, structured documents. An SOP in Notion is readable by a person and fetchable by Claude. But Notion isn’t a database in the traditional sense — it doesn’t support the kind of programmatic queries that make large-scale operational history navigable. Searching five hundred knowledge pages for a specific historical data point is slow and imprecise in Notion.

    BigQuery is optimized for exactly that: large-scale structured data that needs to be queried programmatically. Operational history — every piece of content published, every session’s decisions, every architectural change — lives in BigQuery as structured records that can be queried precisely and quickly. But BigQuery records aren’t human-readable documents. They’re rows in tables, useful for lookup and retrieval but not for the kind of contextual understanding that Notion pages provide.

    Together they cover the full memory requirement: Notion for what the operation knows and how things are done, BigQuery for what the operation has done and when.

    The Notion Layer: Structured Knowledge

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The Notion layer — structured knowledge.

    The Notion knowledge layer is the Knowledge Lab database — SOPs, architecture decisions, client references, project briefs, and session logs. Every page carries the claude_delta metadata block that makes it machine-readable: page type, status, summary, entities, dependencies, and a resume instruction.

    The Claude Context Index — a master registry page listing every key knowledge page with its ID, type, status, and one-line summary — is the entry point. At the start of any session touching the knowledge base, Claude fetches the index and identifies the relevant pages for the current task. The index-then-fetch pattern keeps context loading fast and targeted.

    What the Notion layer provides: the institutional knowledge of how the operation works, what has been decided, and what the constraints are for any given client or project. This is the layer that makes Claude operate consistently across sessions — not by remembering the previous session, but by reading the same underlying knowledge base that governed it.

    The BigQuery Layer: Operational History

    The BigQuery operations ledger is a dataset in Google Cloud that holds the operational history of the business: every content piece published with its metadata, every significant session’s decisions and outputs, every architectural change to the systems, and — most importantly — the embedded knowledge chunks that enable semantic search across the entire knowledge base.

    The knowledge pages from Notion are chunked into segments and embedded using a text embedding model. Those embedded chunks live in BigQuery alongside their source page IDs and metadata. When a session needs to find relevant knowledge that isn’t covered by the Context Index, a semantic search against the embedded chunks surfaces the right pages without requiring a manual search.

    What the BigQuery layer provides: operational history that’s too large and too structured for Notion pages, semantic search across the full knowledge base, and a machine-readable record of everything that has been done — which pieces of content exist, what was changed, what decisions were made and when.

    How Sessions Use Both Layers

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How sessions use both layers.

    A typical session that requires deep operational context follows a pattern. Claude reads the Claude Context Index from Notion and identifies relevant knowledge pages. It fetches those pages and reads their metadata blocks. For operational history — “what has been published for this client in the last thirty days?” — it queries the BigQuery ledger directly. For knowledge gaps not covered by the index, it runs a semantic search against the embedded chunks.

    The result is a session that starts with genuine institutional context rather than a blank slate. Claude knows how the operation works, what the relevant constraints are, and what has happened recently — not because it remembers the previous session, but because all of that information is accessible in structured, retrievable form.

    The Maintenance Requirement

    Persistent memory infrastructure requires persistent maintenance. The Notion knowledge layer stays current through the regular SOP review cycle and the practice of documenting decisions as they’re made. The BigQuery layer stays current through automated sync processes that push new content records and session logs as they’re created.

    The sync isn’t fully automated in a set-and-forget sense — it requires periodic verification that records are being captured correctly and that the embedding model is processing new chunks accurately. But the maintenance overhead is modest: a few minutes of verification per week, and occasional manual intervention when a sync process fails silently.

    The system degrades if the maintenance lapses. A knowledge base that’s three months stale is worse than no knowledge base — it provides false confidence that Claude has current context when it doesn’t. The maintenance discipline is as important as the architecture.

    Interested in building this for your operation?

    The Notion + BigQuery memory architecture is advanced infrastructure. We build and configure it for operations that are ready for it — not as a first Notion project, but as the next layer on top of a working system.

    Tygart Media runs this infrastructure live. We know what the build and maintenance actually requires.

    See what we build →

    Related on Tygart Media: Command Center · AI-native business stack · Notion-deep, surface-simple.

    Frequently Asked Questions

    Why use BigQuery instead of just storing everything in Notion?

    Notion is optimized for human-readable structured documents, not for large-scale programmatic data queries. Storing thousands of operational history records — content publishing logs, session outputs, embedded knowledge chunks — in Notion creates performance problems and makes precise programmatic queries slow. BigQuery handles that scale trivially and supports the SQL queries and vector similarity searches that make the operational history actually useful. Notion and BigQuery do different things well; the architecture uses each for what it’s good at.

    Is this architecture accessible to non-engineers?

    The Notion layer is. The BigQuery layer requires comfort with Google Cloud infrastructure, SQL, and API integration. Building and maintaining the BigQuery ledger is an engineering task. For operators without that background, the Notion layer alone — the Knowledge Lab, the claude_delta metadata standard, the Context Index — provides significant value and is fully accessible without engineering support. The BigQuery layer is the advanced extension, not the foundation.

    What does “semantic search over embedded knowledge chunks” mean in practice?

    When knowledge pages are embedded, each page (or section of a page) is converted into a numerical vector that represents its meaning. Semantic search finds pages with vectors close to the query vector — pages that are conceptually similar to what you’re looking for, even if they don’t use the same words. In practice this means Claude can find relevant knowledge pages by describing what it needs rather than knowing the exact title or keyword. It’s significantly more reliable than keyword search for knowledge retrieval across a large, varied knowledge base.