Tag: AI Agents

  • Notion Content Pipeline for Multi-Client Operations

    Notion Content Pipeline for Multi-Client Operations

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Running a content pipeline across twenty-plus WordPress sites from a single Notion workspace is not the obvious use case Notion was designed for. It’s a use case we built — deliberately, iteratively, over the course of operating a content agency where the volume of work made ad hoc management impossible.

    The result is a system where every piece of content, across every client site, moves through a defined sequence from brief to published inside one Notion database. Nothing publishes without a record. Nothing falls through the cracks between clients. The status of the entire operation is visible in a single filtered view.

    Here’s how that pipeline works.

    What is a Notion content pipeline for multi-site operations? A multi-site content pipeline in Notion is a single Content Pipeline database where every piece of content across every client site is tracked through a defined status sequence — Brief, Draft, Optimized, Review, Scheduled, Published — with each record tagged to its client, target site, and publication date. One database, filtered views per client, full operational visibility across all sites simultaneously.

    Why One Database for All Sites

    Four cards for content, ops, build, and knowledge work with Claude
    Why one Notion database for all sites.

    The instinct is to give each client their own content tracker. Separate pages, separate databases, separate calendars. This feels organized. In practice it means your Monday morning question — “what’s publishing this week?” — requires opening twenty separate databases and manually compiling the answer.

    One database with entity-level partitioning answers that question in a single filtered view sorted by publication date. Every client’s content in motion, every publication date, every status, visible simultaneously. Add a filter for one client and you have their isolated view. Remove the filter and you have the full operational picture.

    The cognitive shift required: stop thinking about the database as belonging to a client and start thinking about the client tag as a property of the record. The database belongs to the operation. The records belong to clients.

    The Status Sequence
    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The status sequence that keeps the pipeline honest.

    Every content record moves through the same six stages regardless of client or content type: Brief → Draft → Optimized → Review → Scheduled → Published. Each stage transition has a defined meaning and, for key transitions, a quality check.

    Brief: The content concept exists. Target keyword identified, angle defined, target site confirmed. Not yet written.

    Draft: Written. Not yet optimized. Word count and rough structure in place.

    Optimized: SEO pass complete. Title, meta description, slug, heading structure, internal links reviewed and adjusted. AEO and GEO passes applied if applicable. Schema injected.

    Review: Content quality gate passed. Ready for final check before scheduling. This is the stage where anything that shouldn’t publish gets caught.

    Scheduled: Publication date set. Post exists in WordPress as a draft or scheduled post. Date confirmed in the database record.

    Published: Live. URL confirmed. Post ID logged in the database record for future reference.

    The Quality Gate as a Pipeline Stage

    The transition from Optimized to Review is gated by a content quality check — a scan for unsourced statistical claims, fabricated specifics, and cross-client content contamination. The contamination check matters specifically for multi-site operations: content written for one client’s niche should never reference another client’s brand, geography, or specific context.

    Running this check as a formal pipeline stage rather than an informal pre-publish habit is what makes it reliable at scale. When publishing volume is high, informal checks get skipped. A formal stage in the status sequence means the check is either done or the content doesn’t advance. There’s no middle ground where it was probably fine.

    What Notion Tracks Per Record

    Each content pipeline record carries: the content title, the client entity tag, the target site URL, the target keyword, the content type, word count, the assigned writer if applicable, the publication date, the WordPress post ID once published, and the current status. Relation fields link the record to the client’s CRM entry and to the associated task in the Master Actions database.

    The WordPress post ID field is the detail most content trackers skip. With the post ID logged, finding the exact WordPress record for any piece of content is a direct lookup rather than a search. For a pipeline publishing hundreds of articles across dozens of sites, that lookup speed matters every week.

    The Weekly Content Review

    Every Monday, one database view answers the primary operational question for the week: a filter showing all records with a publication date in the next seven days, sorted by date, across all clients. This view drives the week’s content priorities — whatever needs to move from its current stage to Published by the end of the week gets the first attention.

    A second view shows all records stuck in the same status for more than five days. Stale records indicate a bottleneck — something that was supposed to move and didn’t. Finding and clearing those bottlenecks is the second priority of the weekly review.

    Both views take under a minute to read. The decisions they drive take longer. But the information is current, complete, and doesn’t require any compilation — it’s all in the database, updated as work happens.

    How Claude Plugs Into the Pipeline

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How Claude plugs into the content pipeline.

    The content pipeline database is one of the primary interfaces between Notion and Claude in our operation. Claude reads the pipeline to understand what’s in progress, writes new records when content is created, updates status as work advances, and logs the WordPress post ID when publication is confirmed.

    This write-back capability — Claude updating the Notion database directly via MCP rather than requiring a manual logging step — is what keeps the pipeline current without adding overhead. The database is accurate because updating it is part of the work, not a separate step after the work is done.

    Want this pipeline built for your content operation?

    We build multi-site content pipelines in Notion — the database architecture, the quality gate process, and the Claude integration that keeps it current automatically.

    Tygart Media runs this pipeline live across a large portfolio of client sites. We know what the architecture requires at real operating scale.

    See what we build →

    Related on Tygart Media: Notion Command Center for agencies · Notion for content agencies · client onboarding template.

    Frequently Asked Questions

    How do you prevent content written for one client from appearing on another client’s site?

    Two mechanisms. First, every content record is tagged with the client entity at creation — the tag makes it explicit which client owns the content before a word is written. Second, a content quality gate scans every piece for cross-client contamination before it advances to the Review stage. Content referencing geography, brands, or context specific to another client gets flagged and held before it reaches WordPress.

    What happens when content is published — how does the pipeline stay accurate?

    When content publishes, the record status updates to Published and the WordPress post ID gets logged in the database record. In our operation, Claude handles this update directly via Notion MCP as part of the publishing workflow. For operations without that automation, a daily or weekly manual update pass keeps the pipeline accurate. The key is building the update into the publishing workflow rather than treating it as optional.

    Can Notion’s content pipeline replace a dedicated editorial calendar tool?

    For most content agencies, yes. Notion’s calendar view applied to the content pipeline database provides the same visual publication scheduling that dedicated editorial calendar tools offer, plus the full database functionality — filtering by client, sorting by status, tracking by keyword — that standalone calendar tools lack. The combination is more capable than purpose-built tools for agencies already running Notion as their operational backbone.

  • Notion AI Review 2026: Is It Worth It For Claude Users?

    Notion AI Review 2026: Is It Worth It For Claude Users?

    Last refreshed: May 15, 2026

    Claude AI · Fitted Claude

    If you’re already running Claude as your primary AI system, Notion AI is a different question than it is for everyone else. For most users, Notion AI is evaluated against not having AI in their workspace at all. For operators already deep in Claude, the question is whether Notion AI adds enough on top of what Claude already does to justify the cost.

    The honest answer: it depends on how you work, and the overlap is larger than Notion’s marketing suggests.

    What is Notion AI? Notion AI is an add-on feature built into the Notion interface, powered by Anthropic’s Claude models, that allows users to draft, edit, summarize, and ask questions about content directly within Notion pages and databases. It costs an additional ten dollars per member per month on top of any Notion plan. As of 2026 it includes Q&A over your workspace, AI-assisted writing, and database intelligence features.

    What Notion AI Actually Does

    Four cards for content, ops, build, and knowledge work with Claude
    What Notion AI actually does.

    In-page writing assistance. Highlight text, invoke Notion AI, and get drafting help, tone adjustments, summaries, or rewrites without leaving the page. For teams doing a lot of writing inside Notion, the in-context availability is genuinely convenient — no context switching to a separate Claude tab.

    Q&A over your workspace. Ask Notion AI a question and it searches your workspace for relevant pages and synthesizes an answer. This is the feature with the most apparent overlap with what Claude can do via MCP — both can answer questions drawing on your Notion content.

    Database intelligence. Notion AI can generate text properties for database records, summarize page content into a field, and assist with populating structured data. Useful for automating some of the manual data entry that comes with maintaining large databases.

    Meeting notes and summaries. Summarize a long page, extract action items from meeting notes, generate a structured summary of a document. Standard AI summarization, accessible without leaving Notion.

    Where It Overlaps With Claude

    Three stacked layers: chat UI, tools, agent runtime
    Where it overlaps with Claude.

    If you’re running Claude via MCP with your Notion workspace connected, there is significant overlap between what Notion AI does and what Claude can already do. Claude via MCP can read your Notion pages, answer questions about your workspace content, draft and edit content, and write back to Notion directly. These are the core Notion AI use cases.

    The overlap is not complete. Notion AI’s in-page convenience — invoking it directly within a page without any setup — is a real difference from Claude, which requires a separate interface. For team members who aren’t power Claude users, Notion AI’s accessibility matters. For a solo operator already running Claude sessions as the primary working mode, the convenience gap is smaller.

    Where Notion AI Adds Genuine Value

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Where Notion AI adds genuine value.

    Team accessibility. Notion AI requires no setup, no API configuration, no MCP server. For team members who need AI assistance within Notion but aren’t going to configure Claude integrations themselves, Notion AI is available immediately at the click of a button. If you’re the only person on your team who uses Claude deeply, Notion AI may be the right AI layer for everyone else.

    Database automation. The database intelligence features — generating and populating text fields, summarizing records — are more native and lower-friction than doing the same via Claude. For operations with large databases that need AI-assisted data population, this feature has real value.

    Inline editing speed. Selecting text and getting an AI rewrite in the same interface, without switching to Claude and copying content back, is faster for quick editing tasks. If a significant portion of your working day involves editing text inside Notion, the friction reduction is real.

    When to Skip It

    If you’re running Claude via MCP as your primary AI interface and doing most of your knowledge work in Claude sessions rather than in the Notion editor, Notion AI’s incremental value is limited. You already have Q&A over your workspace. You already have AI writing assistance. You already have the ability to read and write Notion content from Claude. The ten-dollar-per-month-per-member cost for Notion AI adds mostly convenience features on top of a capability you already have.

    The exception is if you have team members who need AI assistance within Notion but won’t use Claude independently. In that case, Notion AI’s accessibility for non-power users justifies the cost for those seats.

    Our Setup

    We don’t use Notion AI as a paid add-on. Claude via MCP covers the Q&A and workspace intelligence use cases. For in-page writing, the workflow of writing in Claude and pasting the result into Notion adds minimal friction compared to the ten-dollar monthly cost. The database intelligence features are interesting but not critical to how our pipeline works.

    That said, for teams where Notion is the primary working interface for multiple people who aren’t going to become Claude power users, Notion AI is probably worth the cost. The value calculation depends almost entirely on the team’s working style.

    Want help figuring out the right AI stack?

    We configure AI tool stacks for agencies and operators — Claude, Notion AI, MCP integrations, and the workflow architecture that connects them.

    Tygart Media runs a fully integrated Claude + Notion operation. We know where the tools overlap and where each adds distinct value.

    See what we build →

    Related on Tygart Media: Command Center · Claude vs Notion AI.

    Frequently Asked Questions

    Is Notion AI powered by Claude?

    Notion AI uses Anthropic’s Claude models as part of its underlying infrastructure, along with other AI providers. The specific model powering any given Notion AI feature isn’t always disclosed, and the implementation is different from using Claude directly — Notion AI is a packaged product built on top of AI models, not direct API access to Claude.

    Can Notion AI replace Claude for content creation?

    For basic writing assistance within Notion — drafting, editing, summarizing — Notion AI is adequate. For more complex content production, extended reasoning, system-level workflow integration, and the kind of context-aware assistance that comes from a well-configured Claude setup, Notion AI falls short. They serve different use cases even though there’s overlap in the middle.

    How much does Notion AI cost?

    Notion AI costs an additional ten dollars per member per month on top of any Notion plan. For a solo operator on the Plus plan, that’s roughly twenty dollars per month total. For a five-person team, it adds fifty dollars per month to the Notion bill. The cost is reasonable for teams that will use the features actively; it’s harder to justify for individuals already running Claude.

    Does Notion AI have access to my entire workspace?

    Notion AI’s Q&A feature searches across pages you have access to in your workspace. It does not index pages in private sections you don’t have access to, and it respects Notion’s existing permission structure. The AI assistant cannot access content outside your Notion workspace.

  • Build a Notion Knowledge Base Claude Can Actually Use

    Build a Notion Knowledge Base Claude Can Actually Use

    Last refreshed: May 15, 2026

    Update — May 15, 2026: On May 13, 2026, Notion shipped the Notion Developer Platform (version 3.5), with Claude as a launch partner. The platform adds Workers, database sync, an External Agents API, and a Notion CLI. The patterns described in this article still work, but there is now a native, sanctioned alternative for some of what previously required custom MCP wiring or third-party automation. For the full breakdown of what changed and what it means for the Notion + Claude stack, see Notion Developer Platform Launch (May 13, 2026). For the underlying operating philosophy, see The Three-Legged Stack.

    Claude AI · Fitted Claude

    A knowledge base Claude can actually use is not the same as a well-organized Notion workspace. A well-organized Notion workspace is readable by humans who know where to look. A knowledge base Claude can use is structured so Claude can find the right information, understand it in context, and act on it — without you manually directing every step.

    The gap between those two things is real, and most Notion setups fall on the wrong side of it. This is how to close it.

    What does it mean for a knowledge base to be Claude-ready? A Claude-ready knowledge base is structured so that Claude can fetch relevant pages, understand their content and context quickly, and act on them without manual context transfer from the user. It combines consistent metadata on every key page, a master index Claude fetches first, and a page structure that frontloads the most important information.

    The Core Problem: Claude Doesn’t Browse

    Three stacked layers: chat UI, tools, agent runtime
    The core problem — Claude doesn’t browse.

    When you look for something in Notion, you navigate — you know roughly where things live, you scan headings, you follow links. Claude doesn’t navigate the same way. In a session, Claude fetches specific pages by ID or searches for them by keyword. It reads what’s there. It doesn’t browse a folder structure or follow a trail of internal links unless explicitly directed to.

    This means a knowledge base that works well for human navigation can be nearly unusable for Claude. Pages buried three levels deep under unlabeled parent pages, content that requires reading five hundred words before the relevant part, databases with no descriptions — all of these create friction that degrades Claude’s performance in a live session.

    The fix is structural: make the most important information findable without navigation, readable without extensive context, and consistently formatted so Claude knows where to look within any given page.

    The Metadata Block

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The metadata block.

    The single most important structural change is adding a metadata block to the top of every key knowledge page. Before any human-readable content, before the first heading, a brief structured summary tells Claude what the page is for and how to use it.

    The metadata block should include: what type of document this is (SOP, reference, decision log, project brief), what its current status is (active, evergreen, draft, deprecated), a two-to-three sentence plain-language summary of what the page contains, the business entities or projects it applies to, any other pages it depends on, and a single resume instruction — the most important thing to know before acting on this page’s content.

    With this block in place, Claude can read the metadata of twenty pages in the time it would otherwise take to read one page fully. The index-then-fetch pattern becomes viable: Claude reads the index, identifies which pages are relevant, fetches only those, reads the metadata blocks, and proceeds with accurate context.

    The Master Index

    The master index is a single Notion page that lists every key knowledge page in the workspace: its title, page ID, type, status, and one-line summary. Claude fetches this page at the start of any session that involves the knowledge base.

    The index doesn’t need to be comprehensive — it needs to cover the pages Claude will actually need. SOPs for recurring procedures, architecture decisions for the major systems, client reference documents for active engagements, and project briefs for work in progress. Everything else can be found via search if it’s needed.

    The index page should be updated whenever a significant new page is added to the knowledge base. It’s a lightweight maintenance task — add a row to a table, fill in four fields — that pays off every time a session starts with accurate orientation rather than a search.

    Page Structure That Frontloads Context

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Page structure that frontloads context.

    Beyond the metadata block, the structure of individual pages matters for Claude’s performance. Pages that bury key information deep in the content — behind extensive background, after long introductions — require Claude to read more to extract less.

    The right structure for knowledge pages: metadata block first, then a one-paragraph summary of the page’s purpose and scope, then the operative content (the steps, the rules, the decisions), then background and rationale for anyone who needs it. The most important information is always near the top. Readers who need background scroll down; Claude gets what it needs from the first section.

    Keeping the Knowledge Base Current

    A knowledge base Claude can use today but not in three months is not actually useful — it creates false confidence that the system has current information when it doesn’t. The maintenance discipline is as important as the initial structure.

    Two mechanisms keep the knowledge base current without significant overhead. First, a Last Verified date on every page, with a periodic check for pages that haven’t been reviewed in more than ninety days. Second, a practice of updating the relevant knowledge page immediately when a procedure changes or a decision is revised — not after the fact, not in a quarterly review, but as part of the workflow that produced the change.

    The second mechanism is the harder one to establish. It requires treating knowledge documentation as part of the work, not as overhead separate from it. Once that practice is established, the knowledge base stays current almost automatically.

    Want this built for your operation?

    We build Claude-ready Notion knowledge bases — the metadata standard, the master index, and the page structure that makes your workspace a genuine AI operational asset.

    Tygart Media runs this architecture live. We know what makes a knowledge base useful for AI versus what just looks organized.

    See what we build →

    Frequently Asked Questions

    Can Claude search a Notion workspace?

    With the Notion MCP integration, Claude can search Notion by keyword and fetch specific pages by ID. It doesn’t browse folder structures the way a human would. This means the knowledge base needs to be structured for retrieval — with a master index and consistent metadata — rather than for navigation.

    What’s the difference between a Notion knowledge base and a wiki?

    A wiki is typically organized by topic for human browsing. A Claude-ready knowledge base is organized by function and structured for machine retrieval — with metadata blocks, a master index, and page structures that frontload key information. A wiki works well for human reference; a knowledge base structured for AI retrieval works for both humans and AI systems.

    How many pages should a knowledge base have?

    Enough to cover the procedures, decisions, and context that matter for the operation — typically thirty to one hundred pages for a small agency. More pages are not better. A knowledge base with two hundred pages of varying quality and currency is less useful than one with fifty consistently structured, current pages. Curation matters more than comprehensiveness.

  • Notion Claude Integration: Using Claude as Your Notion OS

    Notion Claude Integration: Using Claude as Your Notion OS

    Last refreshed: May 15, 2026

    Update — May 15, 2026: On May 13, 2026, Notion shipped the Notion Developer Platform (version 3.5), with Claude as a launch partner. The platform adds Workers, database sync, an External Agents API, and a Notion CLI. The patterns described in this article still work, but there is now a native, sanctioned alternative for some of what previously required custom MCP wiring or third-party automation. For the full breakdown of what changed and what it means for the Notion + Claude stack, see Notion Developer Platform Launch (May 13, 2026). For the underlying operating philosophy, see The Three-Legged Stack.

    Claude AI · Fitted Claude

    Notion is where the work lives. Claude is what thinks about it. That’s the simplest way to describe the integration — not Claude as a chatbot you open in a separate tab, but Claude as an active layer that reads your Notion workspace, reasons about what’s in it, and acts on it in real time.

    Most people using both tools treat them as separate. They take notes in Notion, then copy and paste context into Claude when they need help. That works, but it’s not an integration — it’s a clipboard operation. What we run is different: a structured Notion architecture that Claude can navigate directly, combined with a metadata standard that makes every key page machine-readable across sessions.

    This is how that system actually works.

    What does it mean to use Claude as a Notion operating system? Using Claude as a Notion OS means structuring your Notion workspace so Claude can fetch, read, and act on its contents during a live session — without you manually copying context. Your Notion workspace becomes Claude’s working memory: it knows where your SOPs live, what your current priorities are, and what decisions have already been made.

    Why the Default Approach Breaks Down

    Three stacked layers: chat UI, tools, agent runtime
    Why the default approach breaks down.

    The standard way people use Claude with Notion: open Claude, describe the project, paste in relevant content, do the work, close the session. Next session, start over.

    Claude has no memory between sessions by default. Every conversation starts from zero. If your operation has any meaningful complexity — multiple clients, ongoing projects, established decisions and constraints — rebuilding that context from scratch every session is expensive. It costs time, it introduces errors when you forget to mention something relevant, and it means Claude is always operating with incomplete information.

    The fix is not to paste more context. The fix is to architect your Notion workspace so Claude can retrieve the context it needs, when it needs it, without you managing that transfer manually.

    The Metadata Standard That Makes It Work

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The metadata standard that makes it work.

    The foundation of the integration is a consistent metadata structure at the top of every key Notion page. We call this standard claude_delta. Every SOP, architecture decision, project brief, and client reference document in our Knowledge Lab starts with a JSON block that looks like this:

    {
      "claude_delta": {
        "page_id": "unique-page-id",
        "page_type": "sop",
        "status": "evergreen",
        "summary": "Two to three sentence plain-language description of what this page contains and when to use it.",
        "entities": ["relevant business", "relevant project", "relevant tool"],
        "dependencies": ["other-page-id-this-depends-on"],
        "resume_instruction": "The single most important thing Claude needs to know to continue work on this topic without re-reading the entire page.",
        "last_updated": "2026-04-12T00:00:00Z"
      }
    }

    The metadata block serves two purposes. First, it gives Claude a structured, consistent entry point to any page — the summary and resume instruction mean Claude can orient itself in seconds rather than reading thousands of words. Second, it makes the page indexable: when we need to find the right page for a given task, Claude can scan metadata blocks rather than full page content.

    The Claude Context Index

    The metadata standard only works if Claude knows where to start. The Claude Context Index is a master registry page in our Notion workspace — the first thing Claude fetches at the start of any session that involves the knowledge base.

    The index contains a structured list of every major knowledge page: its title, page ID, page type, status, and a one-line summary. When Claude reads the index, it knows what exists, where it is, and which pages are relevant to the current task — without having to search or guess.

    In practice, a session starts like this: “Read the Claude Context Index and then let’s work on [task].” Claude fetches the index, identifies the relevant pages for that task, fetches those pages, and begins work with full context. The context transfer that used to take ten minutes of copy-paste happens in seconds.

    What Claude Can Actually Do Inside Notion

    Four cards for content, ops, build, and knowledge work with Claude
    What Claude can actually do inside Notion.

    With the Notion MCP (Model Context Protocol) integration active, Claude can do more than read — it can write back to Notion directly during a session. In our operation, Claude routinely:

    Creates new knowledge pages — when a session produces a decision, an SOP, or a reference document worth keeping, Claude writes it to Notion with the claude_delta metadata already applied. The knowledge base grows automatically as work happens.

    Updates project status — when a content piece is published, Claude logs the publication in the Content Pipeline database. When a task is complete, Claude marks it done. The databases stay current without a separate manual logging step.

    Reads SOPs mid-session — if a session reaches a step with an established procedure, Claude fetches the relevant SOP rather than improvising. This enforces consistency across sessions and across different types of work.

    Scans the task database — at the start of a working session, Claude can read the current P1 and P2 task list and surface anything that should be addressed before the session’s primary work begins.

    The Persistent Memory Layer

    The hardest problem in running an AI-native operation is context persistence. Claude’s context window is large but finite, and it resets between sessions. For any operation with meaningful ongoing complexity, that reset is a real problem.

    Our solution is a three-layer memory architecture:

    Layer 1: Notion Knowledge Lab. Human-readable SOPs, architecture decisions, project briefs, and reference documents. Claude fetches these at session start. Persistent across all sessions indefinitely.

    Layer 2: BigQuery operations ledger. A machine-readable database of operational history — what was published, what was changed, what decisions were made, and when. Claude can query this layer for operational data that would be too verbose to store in Notion pages. Currently holds several hundred knowledge pages chunked and embedded for semantic search.

    Layer 3: Session memory summaries. At the end of a significant session, Claude writes a summary of what was decided and done to a Notion session log page. The next session can start by reading the most recent session log, picking up exactly where the previous session ended.

    Together these three layers mean Claude never truly starts from zero — it has access to the institutional knowledge of the operation, the operational history, and the most recent session context.

    Building This for Your Own Operation

    The full architecture takes time to build correctly, but the core of it — the metadata standard and the Context Index — can be implemented in a few hours and provides immediate value.

    Start with five to ten of your most important Notion pages: your key SOPs, your main project references, your client guidelines. Add a claude_delta metadata block to the top of each. Create a simple index page that lists them with their IDs and summaries. Then start your next Claude session by telling Claude to read the index first.

    The difference in session quality is immediate. Claude operates with context it would otherwise need you to provide manually, makes decisions consistent with your established constraints, and produces output that fits your actual operation rather than a generic interpretation of it.

    From there, you can layer in the Notion MCP integration for write-back capability, build out the BigQuery knowledge ledger for operational history, and develop the session logging practice for continuity. But the metadata standard and the index are where the leverage is — everything else builds on top of them.

    What This Is Not

    This is not a plug-and-play integration. Notion’s native AI features and Claude are different products — Notion AI is built into the Notion interface and works on your pages directly, while Claude operates via API or the claude.ai interface with Notion access layered on through MCP. The architecture described here is a custom implementation, not a feature you turn on.

    It also requires discipline to maintain. The metadata standard only works if every important page follows it. The Context Index only works if it’s kept current. The session logs only work if they’re written consistently. The system degrades quickly if the documentation practice slips. That maintenance overhead is real — budget for it explicitly or the architecture will drift.

    Want this set up for your operation?

    We build and configure the Notion + Claude architecture — the metadata standard, the Context Index, the MCP integration, and the session logging system — as a done-for-you implementation.

    We run this system live in our own operation every day. We know what breaks without proper architecture and how to build it to last.

    See what we build →

    Frequently Asked Questions

    Does Claude have native Notion integration?

    Claude can connect to Notion through the Model Context Protocol (MCP), which allows it to read and write Notion pages and databases during a live session. This is not a built-in feature that requires no setup — it requires configuring the Notion MCP server and connecting it to your Claude environment. Once configured, Claude can fetch, create, and update Notion content directly.

    What is the difference between Notion AI and Claude in Notion?

    Notion AI is Anthropic-powered AI built natively into the Notion interface — it works directly on your pages for tasks like summarizing, drafting, and Q&A over your workspace. Claude operating via MCP is a separate implementation where Claude, running in its own interface, connects to your Notion workspace as an external tool. The MCP approach gives Claude more operational flexibility — it can combine Notion data with other tools, write complex logic, and operate across a full session — but requires more setup than Notion AI’s native features.

    What is the claude_delta metadata standard?

    Claude_delta is a JSON metadata block added to the top of key Notion pages that makes them machine-readable for Claude. It includes the page type, status, a plain-language summary, relevant entities, dependencies, a resume instruction for picking up work in progress, and a timestamp. The standard makes it possible for Claude to orient itself to any page quickly and consistently, without reading the full content every time.

    Can Claude write back to Notion automatically?

    Yes, with the Notion MCP integration active. Claude can create new pages, update existing records, add database entries, and modify page content during a session. This enables workflows where Claude logs its own outputs — publishing records, session summaries, decision logs — directly to Notion without a manual step.

    How do you handle Claude’s context limit with a large Notion workspace?

    The metadata standard and Context Index approach addresses this directly. Rather than loading the entire workspace into context, Claude fetches only the pages relevant to the current task. The index tells Claude what exists; the metadata tells Claude whether a page is worth fetching in full. For operational history too large for context, a separate database layer (we use BigQuery) handles storage and semantic retrieval, with Claude querying it for specific data rather than ingesting it wholesale.

  • Claude MCP Tutorial: Model Context Protocol Setup Guide

    Claude MCP Tutorial: Model Context Protocol Setup Guide

    Last refreshed: May 15, 2026

    Claude AI · Fitted Claude

    Model Context Protocol (MCP) is the most important infrastructure development in Claude’s ecosystem in 2026. It’s an open standard for connecting AI models to external tools, data sources, and services — replacing fragmented one-off integrations with a universal interface. This guide explains what MCP is and how to set up your first server.

    What Is MCP?

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    What is MCP?

    MCP defines a universal interface: any tool that implements the MCP server specification can connect to any AI application implementing the MCP client specification. Build once, connect anywhere. Before MCP, connecting Claude to external systems required custom integration code for every integration — and none of it worked across different AI tools.

    MCP Architecture

    • MCP Host: The AI application (Claude desktop, Claude Code, your custom app)
    • MCP Client: Built into the host; manages connections to servers
    • MCP Server: Lightweight program exposing tools, resources, or prompts

    Setting Up MCP in Claude Desktop

    Three stacked layers: chat UI, tools, agent runtime
    Setting up MCP in Claude Desktop.

    Go to Settings → Developer → Edit Config. Add your server configuration:

    {
      "mcpServers": {
        "filesystem": {
          "command": "npx",
          "args": ["-y", "@modelcontextprotocol/server-filesystem", "/path/to/directory"]
        }
      }
    }

    Restart Claude Desktop. Claude can now read, write, and manage files in your specified directory.

    Popular MCP Servers

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Popular MCP servers.
    Server What It Does
    Filesystem Read/write local files
    GitHub Manage repos, issues, PRs
    PostgreSQL Query databases
    Slack Read/send messages
    Brave Search Real-time web search
    Zapier Connect to 8,000+ apps

    Frequently Asked Questions

    Is MCP open source?

    Yes. Anthropic open-sourced the MCP specification and official server implementations.

    Do I need to code to use MCP?

    To install existing servers: basic command-line comfort is enough. To build custom servers: TypeScript or Python knowledge required.


    Need this set up for your team? Talk to Will →
  • Solo Content Operator: The 5-Layer AI Content Stack

    Solo Content Operator: The 5-Layer AI Content Stack

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Solo Content Operator: A single person running a multi-site content operation using AI as the execution layer — producing, optimizing, and publishing at scale by building systems rather than hiring teams.

    There is a version of content marketing that requires an editor, a team of writers, a project manager, a technical SEO lead, and a social media coordinator. That version exists. It also costs more than most small businesses can justify, and it produces content at a pace that rarely matches the actual opportunity in search.

    There is another version. One person. A deliberate system. AI as the execution layer. The output of a team, without the overhead of one.

    This is not a hypothetical. It is a description of how a growing number of solo operators are running content operations across multiple client sites — producing, optimizing, and publishing at scale without hiring a single writer. Here is how the stack works.

    The Mental Model: Operator, Not Author

    The first shift is in how you think about your role. A solo content operator is not a writer who also does some SEO and sometimes publishes things. That framing puts writing at the center and treats everything else as overhead.

    The correct frame is: you are a systems operator who uses writing as the output. The center of gravity is the system — the keyword map, the pipeline, the taxonomy architecture, the publishing cadence, the audit schedule. Writing is what the system produces.

    This distinction matters because it changes what you optimize. An author optimizes the quality of individual pieces. An operator optimizes the throughput and intelligence of the system. Both matter, but operators scale. Authors do not.

    Layer 1: The Intelligence Layer (Research and Strategy)

    Before anything gets written, the system needs to know what to write and why. This layer answers three questions for every article:

    What is the target keyword? Not a guess — a researched position. Keyword tools surface what terms are being searched, how competitive they are, and which queries sit in near-miss positions where ranking is achievable with the right content.

    What is the search intent? A keyword is a clue. The intent behind it is the brief. Someone searching “how to choose a cold storage provider” wants a comparison framework. Someone searching “cold storage temperature requirements” wants a technical reference. The same topic, two completely different articles.

    What does the competitive landscape look like? What is already ranking? What does it cover? What does it miss? The answer to the third question is the editorial angle.

    This layer produces a content brief: keyword, intent, angle, target word count, target taxonomy, and a note on what the competitive content is missing.

    Layer 2: The Generation Layer (Writing at Scale)

    With a brief in hand, AI handles the first draft. Not a rough draft — a structurally complete draft with headings, a definition block, supporting sections, and a FAQ set.

    The operator’s role in this layer is not to write. It is to direct, review, and elevate. The questions at this stage:

    • Does the opening make a real argument, or does it hedge?
    • Are the H2s building toward something, or just organizing paragraphs?
    • Is there a sentence in here that is genuinely worth reading, or is it all competent filler?
    • Does the conclusion land, or does it trail into a generic call to action?

    World-class content has a point of view. It takes a position. It says something that a reasonable person might disagree with, and then makes the case. The operator’s job is to ensure the generation layer produces that kind of content — not just competent coverage of the topic.

    Layer 3: The Optimization Layer (SEO, AEO, GEO)

    A well-written article that no one finds is a waste. The optimization layer ensures every piece of content is structured to be found, read, and cited — by humans and machines. Three passes:

    SEO Pass

    Title optimized for the target keyword. Meta description written to earn the click. Slug cleaned. Headings structured correctly. Primary keyword in the first 100 words. Semantic variations woven throughout.

    AEO Pass

    Answer Engine Optimization. Definition box near the top. Key sections reformatted as direct answers to questions. FAQ section added. This is the layer that chases featured snippets and People Also Ask placements.

    GEO Pass

    Generative Engine Optimization. Named entities identified and enriched. Vague claims replaced with specific, attributable statements. Structure applied so AI systems can parse the content correctly. Speakable markup added to key passages.

    Layer 4: The Publishing Layer (Infrastructure and Taxonomy)

    Content that lives in a document is not content. It is a draft. Publishing is the act of inserting a structured record into the site database with every field populated correctly.

    The publishing layer handles taxonomy assignment, schema injection, internal linking, and direct publishing via REST API. Every post field is populated in a single operation — no manual CMS login, no copy-paste, no incomplete records.

    Orphan records do not get created. Every post that publishes has at least one internal link pointing to it and links out to relevant existing content.

    Layer 5: The Maintenance Layer (Audits and Freshness)

    The system does not stop at publish. A content database requires maintenance. On a quarterly cadence, the maintenance layer runs a site-wide audit to surface missing metadata, thin content, and orphan posts — then applies fixes systematically.

    This layer is what separates a content operation from a content dump. The dump publishes and forgets. The operation publishes and maintains.

    The Real Leverage: Systems Over Output

    The counterintuitive truth about this stack is that the leverage is not in how fast it produces articles. The leverage is in the system’s ability to treat every piece of content as part of a structured, maintained, interconnected database.

    A single operator running this system on ten sites is not doing ten times the work. They are running ten instances of the same system. Each instance shares the same mental model, the same pipeline stages, the same optimization passes, the same maintenance cadence. The marginal cost of adding a site is far lower than staffing it with a human team.

    What gets eliminated: the briefing meeting, the draft review cycle, the back-and-forth on edits, the manual CMS copy-paste, the post-publish social scheduling that happens three days late because everyone was busy.

    What remains: intelligence and judgment — the things that actually require a human.

    Frequently Asked Questions

    How does a solo operator manage content for multiple websites?

    A solo operator manages multiple content sites by building a replicable system across five layers: research and strategy, AI-assisted generation, SEO/AEO/GEO optimization, direct publishing via REST API, and ongoing maintenance audits. The same system runs across every site with site-specific briefs as inputs.

    What is the difference between a content operation and a content dump?

    A content dump publishes articles and forgets them. A content operation publishes articles as database records, maintains them over time, connects them via internal linking, and runs regular audits to keep the database fresh and complete. The operation compounds; the dump decays.

    What is AEO and GEO in content optimization?

    AEO stands for Answer Engine Optimization — structuring content to appear in featured snippets and direct answer placements. GEO stands for Generative Engine Optimization — structuring content to be cited by AI search tools like Google AI Overviews and Perplexity.

    How do you maintain content quality at scale without a writing team?

    Quality at scale comes from having a clear editorial standard, applying it at the review stage of the generation layer, and running every piece through optimization passes before publish. The standard is set by the operator; the system enforces it.

    What does publishing via REST API mean for content operations?

    Publishing via REST API means writing directly to the WordPress database without manual CMS interaction. Every post field is populated in a single automated call, eliminating the manual copy-paste bottleneck and ensuring every record is complete at publish.

    Related: The database model that makes this stack possible — Your WordPress Site Is a Database, Not a Brochure.

  • AI Agents vs Chatbots & Automations: Key Differences

    AI Agents vs Chatbots & Automations: Key Differences

    These terms get used interchangeably. They’re not the same thing. Here’s the actual distinction between each one, where the lines get genuinely blurry, and which category fits what you’re actually trying to build.

    Chatbots

    A chatbot is a software interface designed to simulate conversation. The defining characteristic: it’s stateless and reactive. You send a message; it responds; the exchange is complete. Each interaction is largely independent.

    Traditional chatbots (pre-LLM) operated on decision trees — “if the user says X, respond with Y.” Modern LLM-powered chatbots use language models to generate responses, which makes them dramatically more capable and flexible — but the fundamental architecture is the same: you ask, it answers, you ask again.

    What chatbots are good at: answering questions, providing information, routing conversations, handling defined service scenarios with natural language flexibility. What they’re not: action-takers. A chatbot can tell you how to cancel your subscription. An agent can cancel it.

    Automations

    Automations are rule-based workflows that execute when triggered. Zapier, Make, and similar tools are the canonical examples. When event A happens, do B, then C, then D.

    The key characteristic: the path is predefined. Every step is specified by the person who built the automation. If an unexpected situation arises that the automation wasn’t built for, it either fails or skips the step. There’s no reasoning about what to do — there’s only executing the specified path or not.

    Automations are highly reliable for well-defined, stable processes. They break when edge cases arise that weren’t anticipated. They scale perfectly for the exact task they were built for; they don’t generalize.

    APIs

    An API (Application Programming Interface) is a communication contract — a defined way for software systems to talk to each other. APIs are infrastructure, not agents or automations. They’re the mechanism through which agents and automations take action in external systems.

    When an AI agent “uses Slack,” it’s calling Slack’s API. When an automation “posts to Twitter,” it’s calling Twitter’s API. The API is the door; agents and automations are the things that open it.

    Conflating APIs with agents is a category error. An API is a tool, not a behavior pattern.

    AI Agents

    An AI agent takes a goal and figures out how to accomplish it, using tools available to it, handling unexpected situations along the way, without a human specifying each step.

    The distinguishing characteristics versus the above:

    • vs. Chatbots: Agents take action in the world; chatbots respond to messages. An agent can book the flight, not just tell you how to book it.
    • vs. Automations: Agents reason about what to do next; automations execute predefined paths. When an unexpected situation arises, an agent adapts; an automation fails or skips.
    • vs. APIs: APIs are tools an agent uses; they’re not the agent itself. The agent is the reasoning layer that decides which API to call and what to do with the result.

    Where the Lines Actually Blur

    In practice, real systems often combine these categories:

    LLM-powered chatbots with tool access: A customer service chatbot that can look up your order status, initiate a return, and send a confirmation email is starting to look like an agent — it’s taking actions, not just responding. The boundary between “advanced chatbot” and “limited agent” is genuinely fuzzy.

    Automations with AI decision steps: A Zapier workflow with an OpenAI or Claude step in the middle isn’t purely rule-based anymore — the AI step can produce variable outputs that affect what the automation does next. This is a hybrid: mostly automation, partly agentic.

    Agents with constrained scopes: An agent restricted to a single tool and a narrow task class starts to look like a sophisticated automation. The more constrained the scope, the more the distinction collapses in practice.

    The useful question isn’t “what category is this?” but “is this system reasoning about what to do, or executing a predefined path?” That’s the actual distinction that matters for how you build, monitor, and trust it.

    Why the Distinction Matters Operationally

    Reliability profile: Automations fail predictably — when an edge case hits a path that wasn’t built. Agents fail unpredictably — when their reasoning goes wrong in a way you didn’t anticipate. Different failure modes require different monitoring approaches.

    Maintenance overhead: Automations require explicit updates when processes change. Agents adapt to process changes automatically — but may adapt in unexpected ways that need to be caught and corrected.

    Auditability: Automations are fully auditable — you can read the workflow and know exactly what it does. Agents are less auditable — you can inspect their actions, but not fully predict them in advance. For compliance-sensitive contexts, this matters significantly.

    Build cost: Automations are faster to build for well-defined, stable processes. Agents are faster to deploy when the process is complex, variable, or not fully specified — because you’re specifying a goal rather than a procedure.

    For what agents can actually do in production: What AI Agents Actually Do. For a business owner’s introduction: AI Agents Explained for Business Owners. For hosted agent infrastructure: Claude Managed Agents FAQ.


    Hosted agent infrastructure pricing: Claude Managed Agents Pricing Reference.

  • What AI Agents Do: Real Production Examples Explained

    What AI Agents Do: Real Production Examples Explained

    Not the version where AI agents are going to replace all human jobs by 2030. The actual version, right now, based on what’s deployed in production.

    The Actual Definition

    What an AI agent is

    Software that takes a goal, breaks it into steps, uses tools to execute those steps, handles errors along the way, and keeps working without you directing every action. The distinguishing characteristic is autonomous multi-step execution — not just answering a question, but completing a task.

    The Key Distinction: One-Shot vs. Agentic

    Most people’s experience with AI is one-shot: you type something, the AI responds, the exchange is complete. That’s a language model doing inference. An AI agent is different in one specific way: it takes actions, checks results, and takes more actions based on what it found — often dozens of steps — without you approving each one.

    Example of one-shot AI: “Summarize this document.” You paste the document, the AI returns a summary. Done.

    Example of an AI agent doing the same task: “Research this topic and produce a summary with verified sources.” The agent searches the web, reads multiple pages, identifies conflicts between sources, runs additional searches to resolve them, synthesizes findings, and returns a summary with citations — without you specifying each search query or each page to read. You gave it a goal; it handled the steps.

    What Agents Can Actually Do

    The tools an agent can use define its capability surface. Common tool categories in production agents:

    • Web search: Query search engines and retrieve current information
    • Code execution: Write and run code in a sandboxed environment, use results to inform next steps
    • File operations: Read, write, and modify files — documents, spreadsheets, data files
    • API calls: Interact with external services — CRMs, databases, project management tools, communication platforms
    • Browser control: Navigate web pages, fill forms, extract information
    • Memory: Store and retrieve information across steps within a session, sometimes across sessions

    The combination of these tools is what makes agents capable of genuinely autonomous work. An agent that can search, write code, execute it, check the results, and write findings to a document can complete a research and analysis task that would otherwise require hours of human work — without you steering each step.

    What “Autonomous” Actually Means in Practice

    Autonomous doesn’t mean unsupervised indefinitely. Production agents are typically configured with:

    • Defined scope: The tools the agent can use, the systems it can access, the actions it’s allowed to take
    • Guardrails: Actions that require human confirmation before proceeding — making a payment, sending an email externally, modifying a production database
    • Reporting: Checkpoints where the agent surfaces what it’s done and asks whether to continue

    Autonomy is a dial, not a switch. You set how much the agent handles independently versus checks in. Most production deployments start more supervised and reduce oversight as trust in the agent’s behavior is established.

    Real Production Examples (Not Hypotheticals)

    Concrete examples from confirmed public deployments as of April 2026:

    • Rakuten: Deployed five enterprise Claude agents in one week on Anthropic’s Managed Agents platform — handling tasks across their e-commerce operations including data processing, content tasks, and operational workflows
    • Notion: Background agents that autonomously update workspace pages, synthesize database content, and process meeting notes into structured summaries without manual triggers
    • Sentry: Agents integrated into developer workflows — monitoring error streams, triaging issues, and surfacing relevant context to engineers
    • Asana: Project management agents that update task statuses, synthesize project health, and move work items based on defined triggers

    These are not pilots. These are production systems handling real operational load.

    How They’re Built

    An agent is built from three components:

    1. A language model: The reasoning layer — the part that decides what to do next, interprets tool results, and determines when the task is complete
    2. Tools: The action layer — APIs, code execution environments, file systems, or anything else the model can call to take action in the world
    3. Orchestration: The loop that connects them — manages the sequence of model calls and tool executions, maintains state between steps, handles errors

    Historically, builders had to construct the orchestration layer themselves — a significant engineering investment. Hosted platforms like Claude Managed Agents handle the orchestration layer, letting builders focus on defining the agent’s goals, tools, and guardrails rather than the mechanics of running the loop.

    What Agents Are Not Good At (Yet)

    Honest calibration on current limitations:

    • Long-horizon planning with many unknowns: Agents perform best on tasks with relatively defined scope. Open-ended exploratory work over many days with fundamentally uncertain requirements is still better handled by humans in the loop at each major decision point.
    • Tasks requiring physical world interaction: No production general-purpose physical agent exists. Software agents operating through APIs and interfaces are the current state.
    • Tasks where errors are catastrophic: Agents make mistakes. For any irreversible, high-stakes action — financial transactions, production data modifications, external communications to important relationships — human confirmation steps should remain in the loop.

    For how hosted agent infrastructure works: Claude Managed Agents FAQ. For the difference between agents and chatbots: AI Agents vs. Chatbots, Automations, and APIs. For an SMB-focused explanation: AI Agents Explained for Business Owners.


    For pricing specifics on hosted agent infrastructure: Claude Managed Agents Complete Pricing Reference.

  • The Real Monthly Cost of Running Claude Managed Agents 24/7

    The Real Monthly Cost of Running Claude Managed Agents 24/7

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    If you’re considering running Claude Managed Agents around the clock, you want a number. Not “it depends.” An actual number you can put in a budget. Here’s the math, worked out by scenario, with the honest caveats about where the real costs are.

    The Formula

    Three stacked layers: chat UI, tools, agent runtime
    The formula.

    Total monthly cost = (Active session hours × $0.08) + token costs + optional tool costs

    The $0.08/session-hour charge only applies during active execution. Idle time — waiting for input, tool confirmations, external API responses — doesn’t count. This matters significantly for 24/7 workloads, because very few agents are active 100% of the time even when “running around the clock.”

    The Maximum Theoretical Cost

    Scenario: Agent running continuously, zero idle time, 24 hours a day, 30 days a month.

    • Session runtime: 24 hrs × $0.08 × 30 days = $57.60/month
    • Token costs: separate, highly variable (see below)

    $57.60/month is the ceiling on session runtime charges. You cannot pay more than this in session fees under any 24/7 scenario. But here’s the reality: that ceiling assumes zero idle time across the entire month, which doesn’t describe any real production agent.

    Realistic 24/7 Scenarios

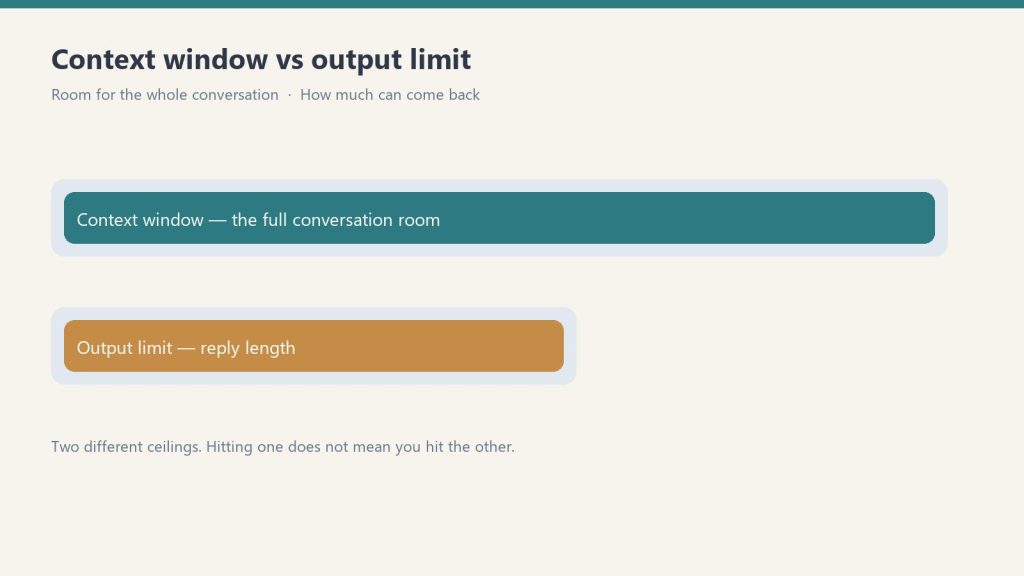
    Diagram comparing a long context window bar with a shorter output limit bar
    Realistic 24/7 scenarios.

    Monitoring Agent (High Idle Ratio)

    Runs continuously watching for triggers — error alerts, specific data patterns, incoming requests. Activates on trigger, processes, returns to monitoring state.

    • Assumption: 5% active execution time (watching 95% of the time, executing 5%)
    • Active hours: 24 × 30 × 0.05 = 36 hours/month
    • Session runtime: 36 × $0.08 = $2.88/month
    • Token costs: low — moderate bursts on trigger events
    • Realistic total: $5–15/month

    Customer Support Agent (Business Hours Active)

    “24/7” in the sense of always-available, but actual request volume concentrates in business hours. Waits for tickets, processes them, waits again.

    • Assumption: 8 hours/day active execution, 16 hours waiting
    • Active hours: 8 × 30 = 240 hours/month
    • Session runtime: 240 × $0.08 = $19.20/month
    • Token costs: depends heavily on ticket volume and average length
    • At 100 tickets/day with moderate length: likely $30–80/month in tokens
    • Realistic total: $50–100/month

    Continuous Autonomous Pipeline

    Batch processing agent that runs continuously through a queue with minimal waiting — the closest to true 24/7 active execution.

    • Assumption: 20 hours/day truly active (4 hours queue exhaustion/maintenance)
    • Active hours: 20 × 30 = 600 hours/month
    • Session runtime: 600 × $0.08 = $48/month
    • Token costs: high — continuous processing means continuous token consumption
    • This is where tokens become the dominant cost driver by a significant margin
    • Realistic total: $200–500+/month (tokens dominate)

    The Real Variable: Token Costs

    For any 24/7 workload that’s genuinely busy, token costs will substantially exceed session runtime costs. The math:

    A moderately active agent processing 10,000 input tokens and 2,000 output tokens per hour with Claude Sonnet 4.6:

    • Input: 10,000 tokens × $3/million = $0.03/hour
    • Output: 2,000 tokens × $15/million = $0.03/hour
    • Token cost: $0.06/hour vs. session runtime of $0.08/hour — roughly equal at this volume

    Scale to 100,000 input tokens and 20,000 output tokens per hour (a busy processing agent):

    • Input: $0.30/hour; Output: $0.30/hour
    • Token cost: $0.60/hour vs. session runtime of $0.08/hour — tokens are 7.5× the runtime charge

    The session runtime fee is flat and bounded. Token costs scale with workload volume. For high-volume 24/7 agents, optimize token efficiency (prompt caching, context management, output brevity) before worrying about the session runtime charge.

    Prompt Caching Changes the Token Math

    If your agent has a large, stable system prompt — common in agents with extensive tool definitions or knowledge bases — prompt caching dramatically reduces input token costs. Cache hits cost a fraction of base input rates. For a 24/7 agent with a 20,000-token system prompt hitting the same context repeatedly, caching that prompt can cut input costs by 80–90%. The session runtime charge is unchanged, but the total cost picture improves significantly.

    The Budget Summary

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The budget summary.
    Agent Type Runtime/mo Typical Total
    Monitoring / low activity ~$3 $5–15
    Support agent (business hours volume) ~$19 $50–100
    Continuous processing pipeline ~$48 $200–500+
    Theoretical maximum (zero idle) $57.60 Unbounded (tokens)

    Complete pricing reference: Claude Managed Agents Pricing Guide. How idle time affects billing: Idle Time and Billing Explained. All questions: FAQ Hub.

    What to do next

    Now that you have the cost math — here’s how to choose and implement

    You now know what Managed Agents costs at scale. The next decision is whether it’s the right architecture vs. OpenAI’s equivalent — and what the implementation actually looks like in practice.

  • Claude Managed Agents vs. OpenAI Agents API — A Direct Comparison

    Claude Managed Agents vs. OpenAI Agents API — A Direct Comparison

    TL;DR — Pick one in 30 seconds

    Choose Claude Managed Agents for zero-infra, fast production deployment. Choose OpenAI Agents API if you need multi-model flexibility or already run on OpenAI infrastructure.

    Feature Claude Managed Agents OpenAI Agents API
    Model lock-inClaude onlyGPT-4o, o3 — OAI only
    Setup complexityZero infra — fully managedSDK — you build the harness
    MemoryBuilt-in (public beta, May 2026)Manual via vector DB
    MultiagentNative (lead + specialists)Swarm/SDK patterns
    Pricing$0.08/session-hr + tokensToken-only (no session fee)
    Best forFast production, Claude-nativeMulti-model, existing OAI infra

    Model Accuracy Note — Updated May 2026

    Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.6 referenced in this article has been superseded. See current model tracker →

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    Long-form Position
    Practitioner-grade

    You’re evaluating hosted agent infrastructure. Both Anthropic and OpenAI have one. Before you commit to either, here’s what’s actually different — not the marketing version, the architectural and pricing version.

    Bottom Line Up Front

    If your stack is Claude-native and you want to get to production fast without building orchestration infrastructure, Managed Agents is hard to beat. If you need multi-model flexibility or have OpenAI deeply embedded in your stack, the calculus changes. Lock-in is real on both sides.

    Still Deciding?

    I’ve run both. Email me your use case and I’ll tell you which one fits.

    No pitch. If Claude isn’t the right call for what you’re building, I’ll tell you that too.

    Email Will → will@tygartmedia.com

    What Each Product Is

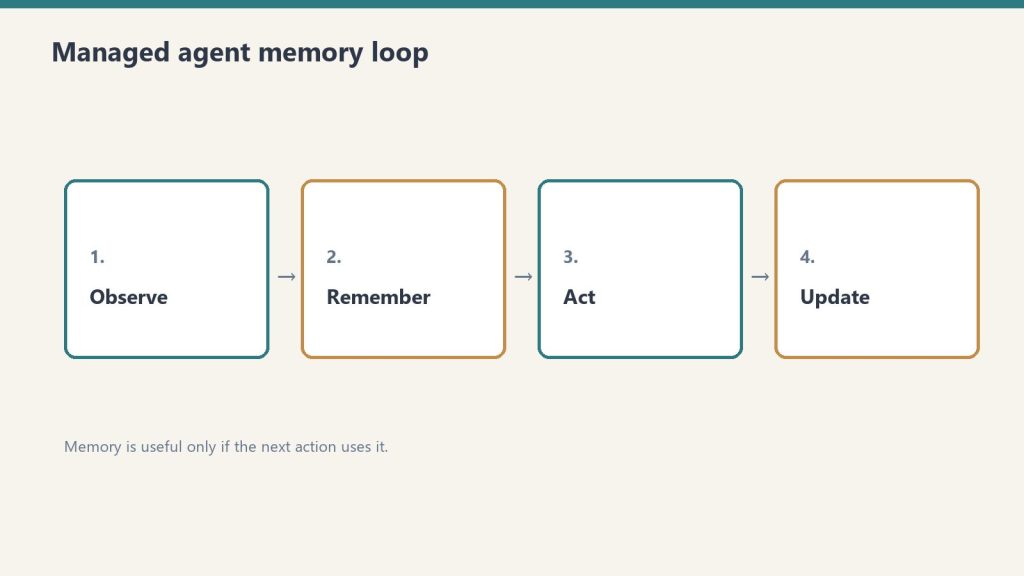
    Four-step loop: observe, remember, act, update for managed agents
    What each agents product is.

    Claude Managed Agents

    Anthropic’s hosted runtime for long-running Claude agent work. You define an agent (model, system prompt, tools, guardrails), configure a cloud environment, and launch sessions. Anthropic handles sandboxing, state management, checkpointing, tool orchestration, and error recovery. Launched April 8, 2026 in public beta.

    OpenAI Agents API

    OpenAI’s hosted agent infrastructure layer, launched earlier in 2026. Provides similar capabilities: hosted execution, tool integration, multi-agent coordination. Supports multiple OpenAI models (GPT-4o, o1, o3, etc.).

    Model Flexibility

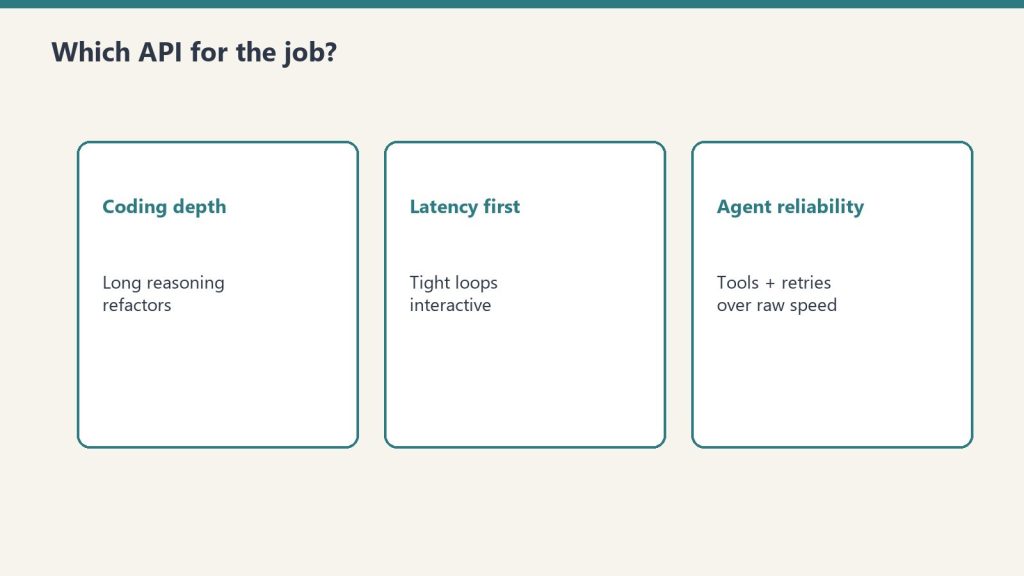
    Three cards: coding depth, latency first, agent reliability
    Model flexibility compared.

    Managed Agents: Claude models only. Sonnet 4.6 and Opus 4.6 are the primary options for agent work. No multi-model mixing within the managed infrastructure.

    OpenAI Agents API: OpenAI models only, but a wider current model lineup (GPT-4o, o1, o3-mini depending on task). Also Claude-only within its own ecosystem — not multi-model in the cross-provider sense.

    The practical implication: If your evaluation is “I want the best model for this specific task regardless of provider,” neither hosted solution gives you that. Both lock you to their provider’s models. The multi-model comparison matters for self-hosted frameworks (LangChain, etc.), not for managed hosted solutions.

    Pricing Structure

    Claude Managed Agents: Standard Claude token rates + $0.08/session-hour of active runtime. Idle time doesn’t bill. Code execution containers included in session runtime — not separately billed.

    OpenAI Agents API: Standard OpenAI token rates + usage-based tooling costs. Pricing structure varies by tool and model tier. Verify current rates at OpenAI’s pricing page — rates have changed multiple times as their agent products have evolved.

    Direct comparison difficulty: Without modeling the same specific workload against both providers’ current rates, headline comparisons mislead. Token rates differ by model, model capabilities differ, and “session runtime” isn’t a category OpenAI uses. Model the workload, not the headline number.

    Infrastructure and Lock-In

    Both solutions create meaningful lock-in. This isn’t a criticism — it’s an honest description of the trade-off you’re making:

    Claude Managed Agents lock-in: Your agents run on Anthropic’s infrastructure with their tools, session format, sandboxing model, and checkpointing. Migrating to OpenAI’s Agents API or self-hosted infrastructure requires rearchitecting session management, tool integrations, and guardrail logic. One developer’s reaction at launch: “Once your agents run on their infra, switching cost goes through the roof.”

    OpenAI Agents API lock-in: Symmetric. Same dynamic in reverse. OpenAI’s session format, tool integration patterns, and infrastructure assumptions create equivalent switching costs to move to Anthropic’s platform.

    The honest framing: You’re not choosing “open” vs. “locked.” You’re choosing which provider’s lock-in you’re more comfortable with, given your existing infrastructure, model preferences, and vendor relationship.

    Data Sovereignty

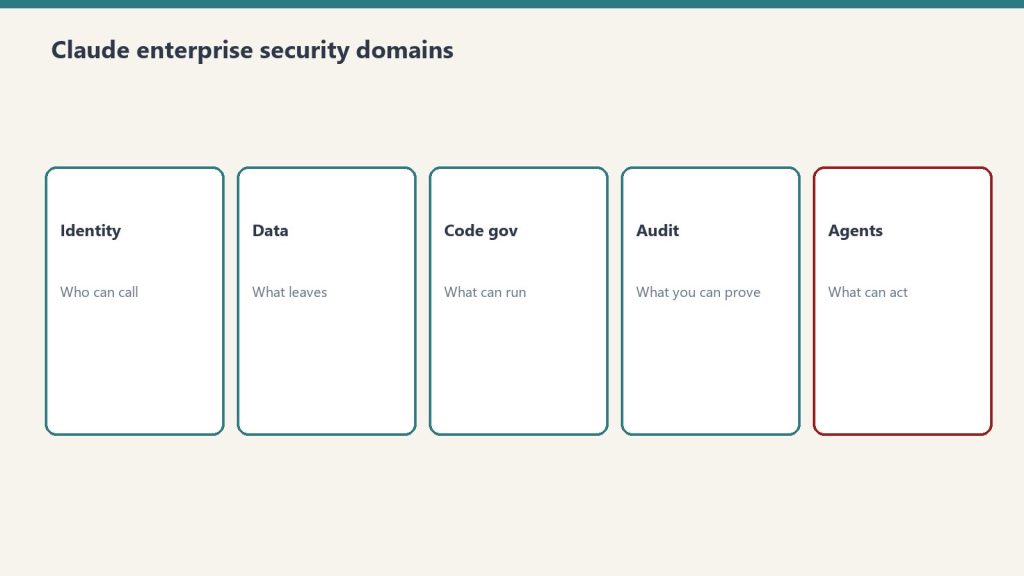
    Five security domains: identity, data, code governance, audit, agents
    Data sovereignty differences.

    Both solutions run your data on provider-managed infrastructure. Neither currently offers native on-premise or multi-cloud deployment for the managed hosted layer. For companies with strict data sovereignty requirements, this is a parallel constraint on both platforms — not a differentiator.

    Production Track Record

    Claude Managed Agents: Launched April 8, 2026. Production users at launch: Notion, Asana, Rakuten (5 agents in one week), Sentry, Vibecode, Allianz. Anthropic’s agent developer segment run-rate exceeds $2.5 billion.

    OpenAI Agents API: Earlier launch gives more time in production, but the product has been revised significantly since initial release. Longer production history, but also more legacy architectural assumptions baked in.

    When to Choose Claude Managed Agents

    • Your stack is already Claude-native (you’re using Sonnet or Opus for most model calls)
    • You want to reach production without building orchestration infrastructure
    • Your tasks are long-running and asynchronous — the session-hour model fits naturally
    • The Notion, Asana, or Sentry integrations are relevant to your workflow
    • You want Anthropic’s specific safety and reliability guarantees

    When to Consider OpenAI’s Agents API Instead

    • Your stack is already heavily OpenAI-integrated (GPT-4o for primary model work, existing tool integrations)
    • You need access to reasoning models (o1, o3) for specific task types — Anthropic’s equivalent is Claude’s extended thinking, which has different characteristics
    • The specific tool integrations in OpenAI’s ecosystem are better matched to your stack
    • You want more production time at scale before committing to a platform

    When to Use Neither (Self-Hosted Frameworks)

    LangChain, LlamaIndex, and similar self-hosted frameworks remain viable — and better — when you genuinely need multi-model flexibility, on-premise execution, or tighter loop control than either hosted solution provides. The trade-off is engineering effort: months of infrastructure work that Managed Agents or OpenAI’s API eliminates.

    Complete pricing breakdown: Claude Managed Agents Pricing Reference. All Managed Agents questions: FAQ Hub. Enterprise deployment example: Rakuten: 5 Agents in One Week.