Tag: AEO

  • They Say GEO Isn’t Real. Watch a Website Answer Questions About Itself.

    They Say GEO Isn’t Real. Watch a Website Answer Questions About Itself.

    People keep telling me AEO and GEO are the new snake oil. Acronyms invented to sell audits. “SEO is SEO,” they say, “and the rest is conference talk.”

    Fine. Let me show you the thing itself, on a site I run, with nobody’s hands on the scale.

    What you’re watching

    That’s Healthcare Facility Hub — a site for people who run hospital facilities. In the corner of every page sits an AI that knows one thing: the site itself. It’s trained on the site’s own content and nothing else. No open internet. No general model knowledge doing the heavy lifting. If the answer isn’t in the site’s pages, the AI doesn’t have it.

    I spent five minutes asking it questions on camera. Three things happened, and they’re the whole argument.

    First: it answers like the content is a database

    Ask it what an infection control risk assessment requires and it doesn’t write an essay. It returns the site’s own material as structure — the risk classes, the types, and then, when I push on negative air pressure, the actual working numbers: the target pressure, the alarm setpoints, the HEPA specs a facilities team would use on a job.

    That’s not a chatbot being clever. That’s what happens when every page is built as a clean, standalone record — one question, one complete answer, the facts in the open — instead of a pile of marketing prose with keywords folded in. The AI can pull from it because the page was built to be pulled from.

    Second: ask it something the site doesn’t have, and it says so

    I asked it for stories about Chicago. It said: we don’t have any content or stories about Chicago in our current site resources.

    Sit with that for a second. The big chatbots, asked the same question, would give you Chicago stories — real, invented, blended, who knows. This one refused, because its world ends at the edge of the site’s content, and it knows where the edge is.

    That’s not a limitation of the demo. That IS the demo. An answer engine is only ever as good as the corpus it can draw on. When the corpus is disciplined, the answers are disciplined. When there’s nothing there, an honest system says nothing’s there — and a visitor, or an engine deciding what to cite, can trust everything it did say.

    Third: the answer ends at an asset

    Follow the thread to the end of the video and I’m not reading a blog post. I’m opening a one-page field sheet — the article distilled into a printable PDF with a QR code, made to be carried onto a hospital job site.

    That’s the shape of the whole thing. A question gets asked. The structured content answers it. The answer hands you something usable. Search used to end at a blue link and a hope. This ends at a tool in a facility manager’s hand.

    Why this is what the engines are doing to you

    ChatGPT, Perplexity, Copilot, Google’s AI — different companies, same basic move. They read corpora, they extract answers, they cite the sources that could answer. Your website is either a corpus they can extract from, or it’s a brochure they skim past on the way to somebody else’s.

    We measure this instead of arguing about it. We run a fixed battery of questions a buyer would actually ask, score what our sites’ AI answers from their own content, and log where it has nothing — those gaps become the next pages we write. This morning, on a sibling site in a different industry, that battery came back 24 passes out of 36, with the misses itemized as a content list. The scoreboard is not a vibe. It’s a work queue.

    And the citation side gets measured too — which engines cite which sites, on which questions, over a trailing thirty days. When the numbers move, we know why, because we know what we published and what it answered.

    The part nobody wants to hear

    None of this is a trick you bolt onto an existing site. The AI on that page answers well because the site underneath it was rebuilt to be a knowledge base — treated like a headless database that happens to have pages attached. Every article answers one real question, in the words the asker would use, with the numbers in the text where an extractor can find them.

    If an AI trained only on your own website can’t answer your customers’ questions, the big engines can’t either. They’ll answer from a competitor whose site can. That’s not a threat I’m selling. It’s arithmetic you can run on your own site this afternoon — most sites have a chat box or a search bar you can interrogate. Ask it your customers’ five best questions. Count what it actually knows.

    We already know how that count comes out for most sites. It’s why the phone rings here.

    The recording is unedited screen capture from healthcarefacilityhub.org, October 22, 2026 — the site’s own AI, its own content, my own questions. Narration on the video is Glint, my AI. This is the work, on tape.

    Run the count on your own site

    The AI Citation Quick-Scan asks ten homeowner prompts — the questions your buyers actually put to ChatGPT, Perplexity, and Copilot — and shows you whether your business is the answer, and if not, who is. It is the same interrogation I ran on camera, pointed at your market: the AI Citation Quick-Scan, $97 — and the $97 comes off the package price if you move forward.

  • Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Disclosure, up front — because that is the subject of this article. Tygart Media sells AI search visibility work. We publish our own tool pricing and comparison pages, and this site is a vendor in the category this article examines. Every number below comes from one named study, with its method stated, so you can check it the way we did.

    The short answer is yes. A disclosed vendor comparison can earn AI citations, because the engines are barely scoring authorship at all. In the largest count anyone has published, between a third and a half of the “best tools” lists cited in AI answers were written by a vendor selling in that category. The traits that measurably raise a page’s citation odds are a comparison table and a stated selection method — not who published the page.

    What got counted

    In August 2026, the agencies Minuttia and Convex Works asked 18,084 software-buying questions across six platforms — Google Search, AI Overviews, ChatGPT, Gemini, Claude, and Perplexity. They then read all 311,766 pages those platforms cited and labelled each one by who published it and what kind of page it is. It is the first count of vendor-written lists in AI answers that works from the cited pages themselves rather than from opinion about them.

    The study’s own caveats deserve the same prominence as its findings. Every share it reports is a floor, because pages its team could not read were counted as not self-promotional. And the results are a snapshot, not a standing: when the researchers re-asked Perplexity 2,000 of the questions a month later, only 28% of the pages in the new answers had been there in August. Citations churn. Anyone measuring them from a single screenshot is reading weather and calling it climate.

    How much of the answer is a vendor grading its own homework

    For “best alternatives to X” questions, 34% to 47% of the listicles the platforms cited were a vendor’s own list, depending on the platform — 47% on Google and Gemini, 34% on ChatGPT. For “how do X and Y compare” questions, the vendor-written share rises to between 56% and 65%. Across every category and question type, 43% of cited listicles are self-promotional.

    The spread by category is wider than the average suggests, running from 12% in audio production to 76% in AI security operations. AI visibility — the category this site sells in — sits at 65%, one of the most self-promotional categories measured. If you buy or sell in a software category, the honest working assumption is that a large share of the “best tools” content the machines quote was written by someone ranked in it.

    The lists themselves behave the way you would expect. Of the vendor-written lists the platforms cited, 93% highlight the vendor’s own product, 87% rank it first, and 90% criticise competitors. Only 16% clearly disclose that the vendor wrote the page. The typical cited list, in other words, is an undisclosed advertisement that puts its author first — and the engines cite it anyway.

    Each engine shops differently

    ChatGPT searches the way a buyer going straight to the source would. In 71% of the searches it ran before answering, it named exactly one product, and 92% of its site-limited searches pointed at a vendor’s own website. On alternatives questions, vendors’ own sites made up 42% of ChatGPT’s citations, against 1% to 6% on the other platforms. For ChatGPT, the vendor’s own pages are not a contamination of the research — they are a primary input to it.

    Perplexity works more like an editor with a pile of candidates. A typical answer finds about 20 pages and cites 9 of them, and which pages survive depends first on where they sat in its search results. Here is the finding that reframes the whole question: of the pages Perplexity found, vendor-written listicles were cited 58% of the time — the highest citation rate of any page type it found, ahead of independent listicles at 44% and review sites at 36%.

    There is no single shelf to win, either. Only 21% to 28% of the citations from AI Overviews, Gemini, Perplexity, and Claude also appear in Google’s top 10 results for the same question. Each engine assembles its own evidence, which means a page earns its place engine by engine, on traits each engine can see.

    The traits that actually move a citation

    Perplexity is the one platform where the study could watch the selection happen — every page found, then which ones got cited. Holding search position equal, here is how often a found listicle was cited with and without each trait:

    Trait Cited with it Cited without it
    Has a comparison table 70% 60%
    Says how the tools were picked 69% 61%
    Longer than the typical list 68% 62%
    Year in the title 68% 63%
    Written by a vendor in the category 64% 68%
    Promotional tone 64% 69%
    Ranks its own product first 64% 65%

    Read the table from the bottom up and the story tells itself. Ranking your own product first — the move that looks most like cheating — costs about one point. A promotional tone costs about five. Being a vendor at all costs about four. Now read the top: a comparison table is worth ten points, and stating how the tools were selected is worth eight. The penalties for self-interest are small and the rewards for being genuinely useful are larger, on the same scale, in the same measurement.

    One honesty note about this article’s own title: the study never isolated disclosure itself as a citation trait, so no one can honestly claim a measured disclosure bonus. What the study did measure is disclosure’s closest cousin — a page that says how its tools were picked gets cited more, not less. Nothing in the data shows an engine detecting a disclosure line and punishing it, and the 84% of vendor lists that hide their authorship are not winning because they hide. They are winning in spite of it, on tables, method, length, and position.

    So why disclose, if the machines don’t make you

    Because the citation is only half the transaction. The other half is the human who clicks through from the answer and decides whether to trust the page in front of them. A list that hides its author converts every citation it earns into a small liability: the reader who discovers the trick discounts not just the list but everything else the vendor says. Disclosure costs no measurable citation share, and it is the only version of the page that survives both readers — the machine counting traits and the person counting on you.

    This is also a game a small operator can actually win. Vendor-written lists that earn citations come from smaller sites than the independent lists they compete with — a median domain rank of 49 against 63 — and the field is fragmented: the 20 most-cited vendors together hold only 6% of the citations. There is no incumbent wall here. There is a craft bar, and it is published in the table above.

    The rules we publish by

    • Disclose at the top, not in the footer. If a page compares a category we sell in, the first screen says so. A disclosure a reader has to hunt for is a hiding place with better manners.
    • State the selection method. How the tools were picked is a measured citation trait, not just an ethical nicety. Write the method before the rankings, and let the rankings follow from it.
    • Put the comparison in a real table. Rows a machine can parse and a person can scan. The table is worth more citation share than any headline about yourself.
    • Earn first place or don’t take it. Ranking yourself first costs almost nothing in citations and almost everything in credibility when the method on the same page doesn’t support it.
    • Date it and keep it current. A year in the title is itself a small citation trait, and a stale list quietly stops being evidence. Lists are maintained assets or they are litter.
    • Publish the data behind the claims. Minuttia released the data behind every chart in its study so competitors could check the work. Checkable beats confident, with machines and with people.
    • Measure citations as a 30-day rate. A quarter of the cited pages turn over in a month. A rate over time is the only reading that distinguishes a page that earns its place from a page that got lucky once.

    The engines have already decided the underlying question: vendor lists are sources now, cited at rates no one can opt out of by refusing to write them. The live question is narrower and more useful — whether your list reads as evidence or as advertising when it gets there. The disclosed list, with its method stated and its comparison in a table, is the one built to be both.

    Study: Minuttia × Convex Works, “Self-Promotional Content Data Study” (August 2026 data), self-promotional-content-data-study.minuttia.com — full data published with the study. Coverage: Digital Market Reports, October 22, 2026.

    AI Citation Quick-Scan — $97

    This article is about whether your pages earn citations. The Quick-Scan runs that test on your company: ten real homeowner prompts across the major AI answer engines, with a written report — and the $97 comes off the package price if you go further. Built for restoration contractors.

    Get the Quick-Scan — $97

  • Six in Seven AI Answers Never Look Anything Up

    Six in Seven AI Answers Never Look Anything Up

    Most of what an AI answer says about your business was never looked up. It was remembered — or invented in the shape of a memory. Ahrefs put a number on that in a study published October 12, 2026: across 66.6 million free, logged-out ChatGPT responses from August and September 2026, a web search ran in only 14.4% of them. Six in seven answers were written without checking anything.

    That single fact reorganizes the work. If the answer usually comes from what the model already carries, then being findable is only half the game. The other half is being known — and, for the one answer in seven where the engine does go looking, having the fact it needs sitting in plain text on your own domain, where it looks first.

    The search, when it happens, is narrow

    The same study logged 15 million fan-out queries — the searches ChatGPT issues behind an answer when it decides to search at all. A searching response ran about 1.6 of them on average. This is not a research department fanning out across the open web. It is a quick, targeted check, and the targeting is the story.

    6.8% of those fan-out queries used a site: operator to search one specific website, spread across roughly 116,000 domains. Among the most common of those targeted searches, 75.9% pointed at a brand’s own site — not a retailer, not a forum, not a review aggregator. When the engine wants a price or a specification, it goes to the company that sells the thing.

    The vocabulary inside the queries leans the same way. The word “official” appeared in 13.1% of English fan-out queries in September 2026, up from 10.1% in August. “Price” climbed from 6.04% to 8.88% of fan-outs in the same month — a relative rise of nearly half. The engine is increasingly searching for the authoritative version of a fact, and the facts it most wants are commercial ones: what it costs, what it includes, what the official page says.

    Facts go home; comparisons wander

    Ahrefs paired the fan-out data with a separate test of 20,000 US prompts, and the split inside it is worth keeping separate in your head, because it is a different instrument from the 66.6 million. In that test, 84.4% of factual questions — pricing, product features, company details — cited at least one official source. For factual questions, 63.4% of all citations pointed at official websites. For comparison questions (“A vs B,” “which is cheaper”), the official share fell to 46.4%: most citations went somewhere else.

    Read together, the two datasets describe one behavior with two modes. Asked for a fact, the engine goes home to the source. Asked to judge, it goes out to the crowd. An operator cannot control the judging mode. The fact mode is entirely winnable: it is won by having the fact, in the open, on the domain the engine already searches by name.

    The playbook that follows

    Publish the price, the spec, and the support fact in plain text on your own domain. Not in a PDF the crawler has to excavate, not inside a configurator, not implied by a sales page’s adjectives. The fan-out query literally contains the words “official” and “price” — it is asking for a page that states the number. Whoever states it cleanly gets cited for it.

    Publish the pages only you can publish. Your measured results, your actual process, your own numbers with dates on them. A summary of somebody else’s facts competes with the original; the original is what the engine is learning to prefer (the citation movement below shows how far that preference has already moved).

    Treat fan-out queries as an instrument of their own. The queries an engine issues about your category — which words it adds, which domains it targets, how that shifts month to month — are a measurement channel separate from citation counts. Watch them separately. We grade the flight recorder, not just the answer, for the same reason: the queries show the intent; the answer only shows the outcome.

    Never blend two dashboards into one story. The 14.4% comes from 66.6 million free logged-out responses. The 84.4% comes from a different, 20,000-prompt test. The citation movements in the next section come from a third cut again. Each number is true inside its own denominator and misleading outside it. This is the same discipline we run on our own visibility work: being cited is not being chosen, and being measured is not being measured the same way twice. Our running instrument for the citation side is the Citation Pulse.

    The second movement: summarizers are losing

    Ahrefs’ Brand Radar citation data for the US — 2.4 million ChatGPT answers in March 2026 against 3.8 million in September, a different dataset from the fan-out study above — shows where the citations went. Reddit fell from roughly one citation in every five answers in March to about one in 43 by late September. Wikipedia fell from one in seven to one in 35. The share those summarizers and forums lost moved to research bodies, regulators, brand and support pages, and hands-on testers. On a matched set of about 25,000 prompts present in both months, every tracked site moved in the same direction, so the shift is not an artifact of new questions entering the sample.

    For an operator, that is the durable part of the whole study. The memory answers reward whoever the model already knows. The searching answers reward whoever publishes the primary fact. The citation trend rewards the originator over the summarizer. All three roads end at the same address: your own domain, carrying your own facts, in plain text.

    The same citation movement, read for hospitals and the firms that build for them — why clinical and facility specifications now have to live as primary documents — is on Healthcare Facility Hub: The Citation List Is Moving Toward the Source Document.

    Sources: Ahrefs, “How ChatGPT Does Query Fan-Out” (October 12, 2026) — fan-out dataset (66.6M responses, 15M queries, Aug–Sep 2026), the 20,000-prompt official-source test reported in the same article, and the Brand Radar US citation comparison (2.4M answers March 2026; 3.8M September 2026). Each figure above is stated with the dataset it came from; the three are not interchangeable.

  • Cited Is Not Chosen

    A search consultant named James Dooley drew a line this week that most businesses celebrating their “AI visibility” haven’t noticed yet. An AI can mention you. It can cite you — pull your page, quote your numbers, link your guide. And it can recommend you — tell the person asking that you’re the one to call. Those are three different events, and they are not a staircase. Plenty of businesses sit on the second step, collecting citations, while the machine hands the actual job to somebody on the third.

    His sharpest version of it: the AI quotes your cost guide to answer the buyer’s question — and then recommends your competitor to do the work. Your content educated the customer. Your competitor got the call. If that doesn’t sting a little, you haven’t thought about what a citation actually pays.

    I test this on my own fleet instead of theorizing about it. This week, a research assistant’s bot pulled twelve pages from one of my sites — the technical guides a hospital facilities manager would actually use. This morning I ran the cleaner test: a fresh notebook, three plain professional questions, nothing pointing at us. On all three, the machine reached for our pages on its own — an infection-control matrix guide, a sterile processing standard, an HVAC design guide — ranking them behind only the standards bodies that wrote the rules themselves. By every dashboard I own, we are cited, and increasingly so.

    And I treat that number the way a pilot treats a single gauge. Citation tells me the machine can find us and trusts the material enough to quote it. It does not tell me we were chosen. Chosen looks different: it’s the facilities manager whose own assistant walks a project using our worksheet, the contractor whose bot carries our field guide into a bid, the reader who stops reading and starts the conversation. None of that shows up in a citation count.

    So what moves a business from cited to chosen? Watch what the machines actually do. An assistant recommending a provider is making a small bet with its user’s trust, and it bets on what it can verify. It can verify a price guide. It can verify something stronger: a working tool. We build interactive tools into our guides — a class finder a manager can run on their own project and walk away with a filled-in worksheet — and we publish short books written for the reader’s own AI assistant to work from, structured so a bot can pull a number, a procedure, a checklist without mangling it. A page that can be used is a different asset from a page that can be quoted. Quoted is a citation. Used is a habit, and habits are what recommendations are made of.

    This is also where most of the industry advice quietly stops working. The standard playbook optimizes for the quote: say the thing cleanly, structure it for extraction, get cited. Fine as far as it goes. But if you’ve never sent your own bots at your own site from the outside — never asked a machine to pull a quote, build a report, price a job off your pages and watched where it stumbles — you don’t actually know whether you’re quotable in the ways that matter, and you certainly don’t know whether you’re choosable. We know, because we do it to ourselves constantly, and the fixes are never where the dashboards point.

    Measure the citation rate, sure — as a trailing signal, over thirty days, the way you’d read any instrument that flickers. Just don’t confuse it with the outcome. The outcome is the phone, the bid list, the short list. Cited is the machine knowing your name. Chosen is the machine spending its credibility on you. Build for the second, and the first takes care of itself.

    Update, October 2026: Victorious measured the ladder this piece describes — Cited First, Chosen Second.

  • What does AI visibility help cost — and what should it include?

    Updated November 2, 2026 — added direct answers on hiring someone versus handling AI search in-house, from our own published work.

    AI visibility help is sold in four shapes: one-time diagnostics, one-time builds, monthly retainers, and software subscriptions. The same underlying work can hide inside any of the four, which is why the total matters less than the inventory — what exists when the money is spent. One-time work should carry a one-time price. Monthly money should buy monthly work you can name.

    What are you actually paying for in each shape?

    A diagnostic buys a measurement: a fixed set of questions about your business, asked once, with the answers and citations returned as a report. A build buys finished assets: profiles rebuilt, answer pages written and published, listings corrected. A retainer buys a standing habit: new questions tested, new pages written, changes logged, run after run. A subscription buys software — a tracker — and the reading of it stays yours.

    None of the shapes is the honest one. Each fits a situation: a diagnostic before you spend real money, a build when the gaps are known, a retainer when your market moves fast enough that last quarter’s answers rot, a subscription when you have someone in-house who will actually open it. The dishonesty creeps in at the seams — a one-time fix billed monthly forever, a subscription sold to a business with nobody to read it, a retainer with no list of what it produces.

    What should the work include?

    Whatever the shape, AI visibility work should end with things you can hold: your Google Business Profile and Bing Places listing claimed, complete, and in your name; answer pages on your own website that answer your customers’ real questions; your name, address, phone, and services agreeing across the directories machines read; a fixed question set tested before the work and after it; and a written record of what was changed and when.

    Read that list as a quote-checker. If a proposal cannot point each dollar at an item on it — or at a named addition of its own — it is not a quote, it is a mood with a price attached. Notice what is not on the list: no item says “trust us,” and no item is invisible. Visibility work is unusual in marketing for one happy reason — nearly all of it can be opened and inspected the day it is done. Insist on inspecting it.

    What is worth paying for?

    The parts worth paying for are the audit discipline, the writing time, and the measurement habit: a question set held steady while everyone wants to change it, finished pages instead of drafts of drafts, and answers re-asked on a schedule after the work ships. A fourth item earns its keep in contested markets — someone watching which competitor the machines cite on your questions, and why.

    What those four have in common is that they are labor, not secrets. The underlying knowledge in this field is mostly published and plain: complete profiles, consistent facts, quotable answers, measured results. We learned it by doing it on our own business first, and the recipe is written down free on this site. You pay a provider for the same reason you pay anyone — the work is real, the hours are real, and your own hours have somewhere better to be. If a provider’s price rests on mystery instead of hours, the mystery is the product.

    What is not worth paying for?

    Content volume is not worth paying for: a pile of pages written to no customer’s question gives the machines more of what they already ignore. Dashboards are not worth paying for if nobody will open them after the first month. And the sprinkle-ons are not worth paying for as the main event — a schema file or a text file presented as the visibility fix itself. We have tested those; they are not levers, and anyone selling them as the meal is selling garnish.

    The quietest bad buy is the mismatch, not the scam: good work in the wrong shape. A careful one-time build, billed as a retainer, costs a business twelve times its price for the same finished assets. A subscription bought for a business with no reader costs its fee for a login nobody uses. Before the price, before the provider, settle the shape — that one decision prevents most of the waste in this market.

    What are the red flags?

    A guarantee is the first red flag: nobody controls which businesses an assistant names, so a promised mention or ranking is a promise about someone else’s behavior. The second is a provider who will not show the questions they test, or the raw answers before and after. The third is ownership — pages and profiles built on the provider’s accounts, in their name, that leave when you do. That is not a service, that is rent with a marketing department.

    The rest rhyme: a price that cannot be split into one-time and recurring parts; a long contract demanded before any proof exists; a report you are not allowed to re-run or take with you. Any one of these is survivable in an otherwise sound engagement. Two or more in the same proposal is the proposal telling you what the engagement will be like.

    Should a small business hire someone for AI search or do it in-house?

    Whether to hire an outside provider or manage AI search visibility in-house depends on available hours, execution discipline, and the specific shape of help required. The underlying knowledge is published and plain: complete profiles, consistent directory facts, quotable answer pages, and measured results. A small business with internal capacity can execute the fundamentals directly using our playbook for local service businesses—claiming your Google Business Profile and Bing Places in your own name, aligning name, address, phone, and services across directories machines read, and writing clear answer pages that address your customers’ real questions.

    You pay an outside provider for labor and execution time, not proprietary secrets. Hiring someone is worth paying for when your own hours have somewhere better to be, or when you need audit discipline, dedicated writing hours, and a standing measurement habit (keeping a fixed question set steady and re-testing answers on a schedule after the work ships). When hiring, insist on buying finished assets in a finishable shape rather than open-ended retainers. As published in our own pricing, finishable work carries finishable terms—such as our $97 one-time AI Citation Quick-Scan diagnostic (10 prompts scored within 7 days) or our $450 one-time Ask Maps Protocol build (profile rebuild, website FAQ answer page, directory matching, and a 30-day proof check).

    If you choose to hire, apply the quote-checker and watch for the red flags named on this page: guarantees of AI recommendations or rankings (nobody controls which businesses an assistant names), providers refusing to share their tested question sets or raw before-and-after answers, profiles or answer pages built on provider accounts that leave when you do, content volume written for no real customer question, dashboards nobody opens, or one-time fixes billed as monthly retainers. If a provider’s price rests on mystery instead of inspectable hours and finished assets you own, keep the work in-house.

    What does ours cost, as an example?

    Ours is priced by shape, and we will use it as the example because we can vouch for its terms. The AI Citation Quick-Scan is the diagnostic: 10 prompts about your service line, a scored report within 7 days, $97, one time. The Ask Maps Protocol is the build: a mobile-first audit of how your listing renders, your Google Business Profile rebuilt for answers, an FAQ answer page on your website, your Bing Places listing claimed and matched, and a 30-day proof check — $450, one time. We sell no retainer version of either, because the work they name is finishable.

    Hold any provider’s quote — ours included — against the sections above: the inventory, the shape, the flags. The right price for this work is the one attached to finished things you own and a measurement you can repeat.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • What does AEO reporting actually show?

    An honest AEO report shows four things: the exact questions that were asked, the answers the assistants actually gave, which businesses and pages those answers cited, and how all of it changed since the last run. AEO reporting is the scheduled record of those four things, kept the same way every time. Anything that cannot show you the four is showing you a mood, not a measurement.

    What questions were asked?

    A real AEO report prints its question set in full, word for word. The questions are the foundation of the whole report: they should be your customers’ real questions, fixed in advance, and identical from run to run. A citation count means nothing until you can see the questions it was counted on.

    This is where reports quietly cheat. Swap the questions between runs and every comparison is fiction — you improved because the test got easier. Add a question you already win and the average climbs without a single answer changing. Ask for the set in writing before the first run, and treat any later change to it as a new baseline, announced as one. A short set of real questions, held steady, beats a long set that wanders.

    What did the AI actually say?

    A real AEO report keeps the raw answers, not summaries of them. The answer text is what your customer actually reads — the names in it, the order they appear, the words around them. A summary written by the provider can only tell you what the provider noticed. The raw answer lets you check.

    Summaries hide the losses. A run where you were cited on nine questions and dropped on the tenth, hard, reads as “visibility strong” in a summary and as a work order in the raw text. Keep the full answers, dated, for every run. They take almost no space, they cannot be reconstructed later, and they are the difference between having evidence and having a recollection.

    Who got cited?

    A real AEO report names the citations for every question: which businesses the answers credited, which pages of theirs did the work, and what share of the citations on each question went to whom. The citation list is the most useful page in the report. It converts “we are not visible” into a named list of exactly who the machines trusted instead, question by question.

    Read it as a work list, not a wound. When one restoration client of ours kept losing a question to the same competitor, the citation list showed the competitor’s page the assistant kept crediting — a page that answered the question in the customer’s own words, in the first paragraph. That is a specific, fixable problem, and it was invisible in every summary number we had. Your citation share — your slice of the citations on your questions — is the one summary figure worth tracking, because it is arithmetic on the list, not an opinion about it.

    What changed since last time?

    A real AEO report is built to compare: this run against the last, same questions, with the differences stated plainly and the work done in between written next to them. Answers churn — the same question, asked next month, can name different businesses with nothing changed on either side. An honest report says so, and reads movement over several runs instead of celebrating or mourning a single one.

    The work log belongs inside the report for one reason: without it, you cannot tell your work from the weather. “We rebuilt the profile and published two answer pages in March; citations on those questions rose across the April and May runs” is knowledge. The same rise with no log behind it is luck you will try to repeat blind. If your provider’s report never mentions what they did between runs, ask why their work and their results live in separate documents.

    What does a horoscope report look like?

    A horoscope report shows a single score with no questions behind it, percentages with no counts under them, and screenshots of the one good answer from a good day. It changes its questions when the results are inconvenient, reports only the wins, and always finds that things are improving and that more budget would improve them faster. It feels good, commits to nothing, and cannot be checked.

    The test is simple. Pick any number in the report and ask: on which questions, from which answers, counted how? A real report answers in one step, because the number came from a list it can show you. A horoscope report answers with another number. We call them horoscopes because, like the ones in the paper, they are written to be agreeable about the future and impossible to grade about the past.

    How often should you read an AEO report?

    Read AEO reporting on a rolling cadence — monthly is a sane default — and never daily. AI answers move day to day with nothing changed, so daily reading is noise-chasing: it manufactures urgency, spends your attention, and teaches you to react to weather. What is worth reading is the run-over-run trend, and the first run after real work has had time to settle.

    Reading it should end in a decision, or the reading is decoration. The standing decision a good report sets up is small: which questions is a competitor cited on that we are not, and what is the missing answer we should write next? Our AI Citation Quick-Scan is this artifact in its smallest honest form — 10 prompts about your service line, the answers recorded, the citations named, a scored report within 7 days, $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • How do you measure AI search visibility?

    Updated November 2, 2026 — added direct answers on visibility metrics and AI search share of voice, from our own published measurement.

    You measure AI search visibility with two kinds of tools: the reports the platforms publish about their own answers, and trackers that ask the assistants your customers’ questions on a schedule and record who gets named. The platform reports show who the platform cited. The trackers show what an assistant answered when asked. A buyer who knows which tool shows which thing can read either one honestly.

    What does “visible” mean in an AI answer?

    An AI answer can mention your business, cite your business, or recommend your business, and those are three different measurements. A mention means your name appears in the answer text. A citation means the answer credits your page as a source. A recommendation means the assistant names you as the choice. Every tool below reports some mix of the three, under its own labels.

    The distinction decides what a number is worth. A mention can be one name in a list of eight. A citation means the platform read your material closely enough to credit it — that is the receipt that survives. A recommendation is the strongest outcome and the least common. When a tool shows you one big “visibility” number, the first question is which of the three it counted.

    What metrics matter for AI search visibility?

    Traditional search metrics like keyword rank and search volume do not apply to AI assistants. A complete measurement framework tracks five distinct metrics, as established in our guide to measuring LLM visibility and our three-layer visibility measurement framework:

    • Citation frequency: The total number of times your domain or brand is cited as a source in AI-generated answers over a measured window.
    • Prompt coverage: The percentage of your sampled buyer queries where your brand or content appears anywhere in the output.
    • Share of voice: The proportion of citations your domain earns on a specific prompt set compared to named competitors.
    • AI referral traffic: The volume of qualified sessions arriving on your site from AI platforms, tracked via custom GA4 channel groups.
    • Citation-assisted conversions: Inquiries, form submissions, and booked jobs that originate from or touch an AI search session.

    What is share of voice in AI search?

    Share of voice in AI search—also termed share of authority—is the percentage of total citations awarded to a specific domain across a fixed set of prompt tests. Unlike a simple citation count, share of voice measures your presence relative to every other source cited for the same queries.

    Consider a live worked example from Tygart Media’s own tracking on November 2, 2026. Across a Clarity measurement run evaluating the topic “AI citation rate measurement” (101 total citations distributed across approximately 50 competing domains), the single leading domain captured 8.91% of citations (9 citations). Tygart Media earned a 0.99% share of authority (1 citation). In an emerging, fragmented AI search topic where no single authority owns the category, tracking share of voice across recurring runs reveals whether your content is steadily accumulating citations or losing share to competing domains.

    What does Bing AI Performance show?

    Bing AI Performance is Microsoft’s free first-party report, and it shows what the assistants built on Bing actually cited. The report organizes citations four ways: Intents, Topics, Citation Share, and Compare. It is the platform grading its own homework — the most direct evidence a buyer can get, and a view of exactly one surface.

    The four views answer four plain questions. Intents shows the kinds of things people were trying to do when your pages got cited. Topics groups those citations by subject, so you can see which of your subjects the machines trust. Citation Share shows your slice of the citations on a topic against everyone else cited there. Compare puts two date ranges side by side, so a change shows up as a change and not a feeling.

    Our own report is the example we read every month. For tygartmedia.com, our Bing AI Performance report covering six months of Microsoft Copilots and partners shows 1.5M total citations across an average of 164 cited pages. We read that as our footprint on one measured surface — proof the surface can be measured, and a baseline to compare the next run against. It says nothing about any other platform, and it is not a promise about any other business.

    What do third-party visibility trackers show?

    Third-party trackers are subscriptions that ask a fixed set of questions to the major assistants on a schedule and record the answers. A tracker shows mention rates, citation rates, and competitor shares across several surfaces at once. What it sells is a trend line across platforms, built from sampled asks — not a record of what any real customer saw.

    The honest advantages are real. A tracker sees surfaces the first-party reports cannot, because each platform only reports on itself. A fixed question set, asked the same way each run, produces runs a buyer can actually compare. Competitor context comes built in, and in a contested market that context is the point.

    The limits are just as real. The tracker asks its questions, on its schedule, from its accounts — your customers ask differently, locally, and once. Small question sets get reported as precise percentages, and a two-question swing can dress itself up as a trend. And the subscription runs whether you read it or not. A tracker earns its money in a competitive market with several assistants in play, read monthly by someone who acts on it. Everywhere else it is an expensive screensaver.

    What can no tool tell you?

    No tool can tell you what a specific customer saw, whether a mention became a phone call, or why an assistant chose a competitor. AI answers vary by person, place, and moment, and the platforms do not publish their reasoning. A tool shows outputs. The cause behind an output is still the buyer’s work to figure out.

    Sit with that limit before you buy anything, because it is where the honest tools end and the salesmanship starts. No report closes the gap between “the assistant named us” and “the phone rang” — that gap closes with call tracking and asking customers how they found you, unglamorous as that is. A provider who sells you certainty across that gap is selling you the gap.

    Which tool should a buyer start with?

    A buyer should start with the free first-party report for the surface their customers actually use, and add a tracker only when they need a cross-platform trend and will read it monthly. The tool matters less than the discipline behind it: a fixed set of your customers’ questions, asked before the work and after, with the raw answers kept. Any tool run that way beats a better tool run casually.

    Most small businesses find the first-party report is enough to start, because it answers the only question that changes what they do next: on the questions my customers ask, who does the machine name — and is it me? If you want that first measurement done by hand instead, our AI Citation Quick-Scan asks 10 prompts about your service line and returns a scored report within 7 days — $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • Which AI SEO services are right for a small business?

    The right AI SEO services for a small business are the ones matched to where your customers actually ask questions. For most local service businesses, that means three things, in order: a business profile the machines can read, answer pages on your own website written the way customers ask, and a scheduled check that shows who the machines name.

    What are AI SEO services?

    AI SEO services are services that make a business readable to AI answer engines. A traditional search engine returns a list of links; an AI assistant returns an answer, and it names the businesses it can read clearly. AI SEO is the work of giving those systems clean material — profiles, pages, and consistent facts — to name you from.

    The category is new enough that the label covers very different work. One provider’s “AI SEO” is a rebuilt Google Business Profile and a page of real answers. Another’s is a software subscription and a monthly PDF. The sections below separate the kinds, so you can buy the work instead of the label.

    What kinds of AI SEO services are there?

    AI SEO services come in five kinds: listing and profile work, answer-page writing, citation cleanup across directories, one-time audits that measure where you stand, and ongoing retainers that bundle all of it. Most small businesses need the first three once, the audit before and after, and a retainer only when the market moves fast.

    • Profile work builds the listings machines read first: Google Business Profile on Google’s side, Bing Places on Microsoft’s — the listing Copilot and the assistants built on Bing read from.
    • Answer-page writing puts pages on your own website that answer customer questions in customer language, in passages short and plain enough to be quoted.
    • Citation cleanup makes your name, address, phone, and services agree across directories and aggregators — Yelp, Foursquare, Apple Maps, Angi, and the data feeds behind them.
    • Audits and scans measure the starting point: a fixed set of questions, asked before the work and after, with the answers kept.
    • Retainers bundle the above into monthly work. They fit businesses in fast-moving markets; they are a poor fit for one-time fixes billed forever.

    How is AI SEO different from traditional SEO?

    Traditional SEO earns a position on a list of links; AI SEO earns a mention inside an answer. The list rewards the page; the answer rewards the clearest source. Both run on the same foundations — a readable website, consistent business facts, reviews, and real expertise — but the AI layer reads quotable passages, not just pages.

    That difference changes what good work looks like. A page stuffed with keywords can rank and still never be quoted, because there is no clean passage to lift. A plainly written answer — the question as the heading, the answer first, the detail after — gives an assistant something it can repeat word for word. Traditional SEO is not replaced by this; it is the floor it stands on.

    What should a small business buy first?

    A small business should buy in the order a customer asks. First, the profile a machine reads when someone asks for your trade nearby — your Google Business Profile and your Bing Places listing. Second, answer pages on your own site. Third, a measurement check. Software subscriptions and content volume come last, if at all.

    The order matters because the surfaces compound. An assistant answering “who does this work near me” starts from profiles and listings, then checks what your website says. A beautiful website behind an empty profile is invisible at the first step. A strong profile pointing at a website with no answers gives the machine nothing to quote. Buy the chain in order and each link makes the next one worth more.

    How much do AI SEO services cost?

    AI SEO services are sold three ways: one-time builds, monthly retainers, and small diagnostics. The honest difference is not the label but what you can hold afterward — a finished profile and pages you own, or a report you can re-run. Any price is too high for work you cannot inspect when it is done.

    Price follows scope: number of locations, number of services, number of towns you serve. What should make you careful is shape, not size. One-time work — a profile build, an answer page, a listing cleanup — should carry a one-time price. Monthly money should buy monthly work you can name: new questions tested, new answers written, changes logged. If a provider cannot tell you which of your dollars are one-time and which recur, that is the answer to whether to sign.

    What questions should I ask an AI SEO provider before I pay?

    Ask an AI SEO provider five questions before you pay: What exactly will exist when you are done? Which questions will you test, and can I see the answers before and after? What do you not control? What does the work cost once, and what recurs? Who owns the pages and profiles afterward? Ask us the same five.

    Each question has a tell. “What will exist” should produce a list, not adjectives. “Which questions” should produce your customers’ actual questions, written down. “What do you not control” is the honesty test — no provider controls which businesses an assistant names, and one who promises a ranking is telling you how the rest of the engagement will go. Ownership is the quiet one: profiles and pages built on your accounts, in your name, stay yours if you leave. Anything else is rent.

    What proof should an AI SEO service show me?

    An AI SEO service should show you a named report, a date range, and the questions it tested — not a screenshot of a ranking. On our own site, the proof habit looks like this: our Bing AI Performance report for tygartmedia.com, covering six months of Microsoft Copilots and partners, shows 1.5M total citations across an average of 164 cited pages.

    Read those numbers the way we do. They are our own footprint on one measured surface — evidence that the measurement exists and that we live under it — not a promise about your business. AI answers also churn: the same question asked next month can name different businesses, which is why honest proof is a before-and-after on your questions, re-asked on a schedule, with the raw answers kept. A provider who shows you their own numbers should be just as willing to show you yours.

    Can I do AI SEO myself?

    Yes — the free layer of AI SEO is real work any owner can do: claim and complete your Google Business Profile and Bing Places listing, write your services in plain language, and answer your customers’ common questions on your own site. What you pay a provider for is the audit discipline, the writing time, and the measurement habit.

    Be honest with yourself about which of those three you will actually do. The profile most businesses already “have” is a name, a pin, and hope — claimed years ago and never finished. The knowledge is not the scarce part; the finished, checked, written-down work is. If you will do it yourself, the sections above are the whole recipe, in order, and they will work the same for you as for us.

    Where does our own offer fit?

    If you want to know where you stand first, our AI Citation Quick-Scan runs 10 prompts about your service line and returns a scored report within 7 days — $97, one time. If you want the build done, the Ask Maps Protocol is our version: $450, one time — a mobile-first audit of how your listing actually renders, your Google Business Profile rebuilt for answers, an FAQ answer page on your website, your Bing Places listing claimed and matched, and a 30-day proof check.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • Yes, I Put the Schema Where You Could See It. On Purpose.

    Yes, I Put the Schema Where You Could See It. On Purpose.

    I had an audit run on the oldest content on this site this week. Pages, posts, links, bylines, search descriptions, the works. It came back with a ranked list of problems, and near the top, flagged as a defect readers can see, was this:

    Visible raw JSON-LD schema code printed as text in the post body.

    Across the whole site, it found 197 posts doing it.

    Cartoon crawler robot stamping FLAGGED on a blog post full of visible code while the blogger gives a sheepish thumbs-up
    My own audit, doing exactly what I asked it to do. Rude.

    And I’ll be honest, my first reaction wasn’t “oops.” It was closer to “hey, I did that on purpose.”

    What you’re looking at

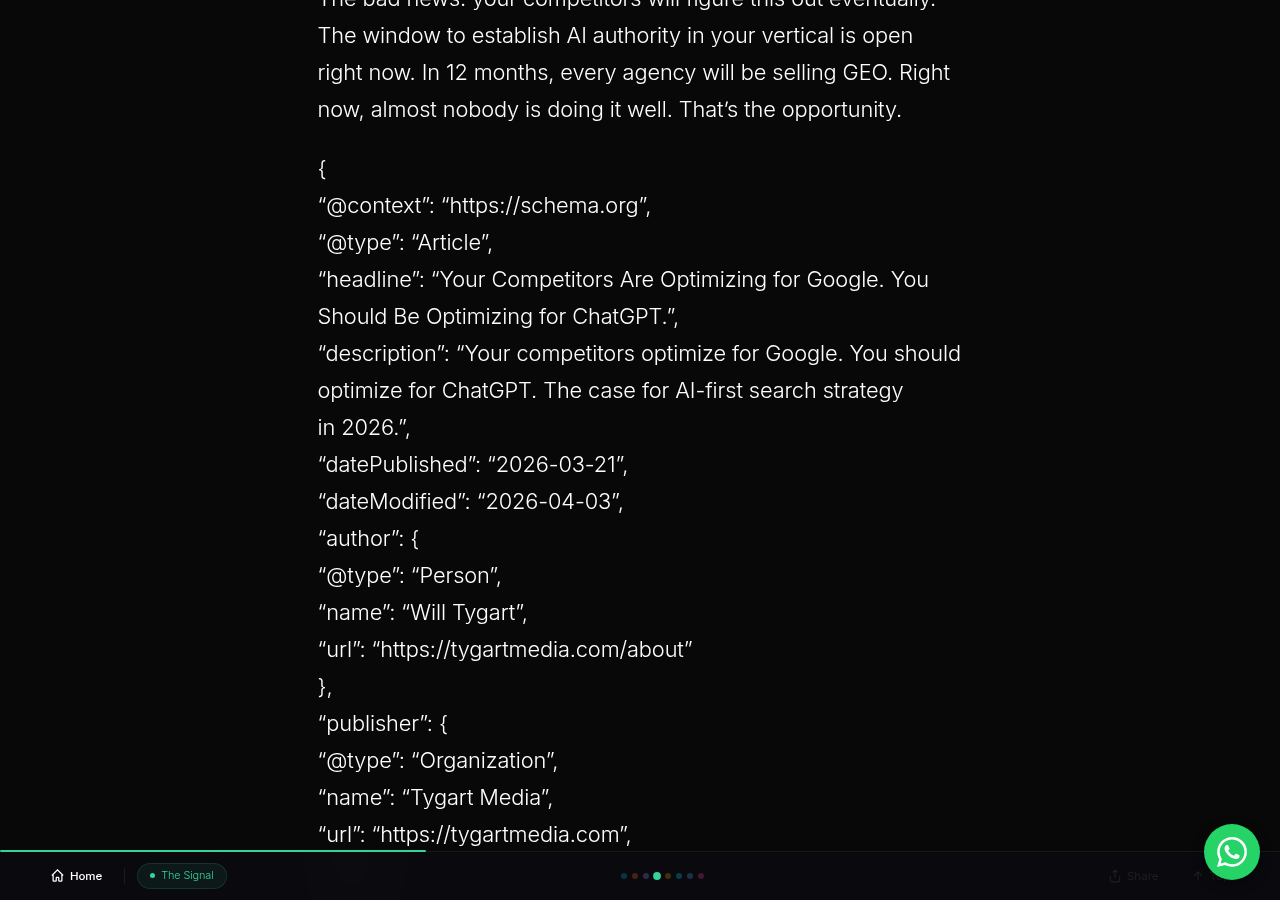
    If you’ve scrolled to the bottom of some of my older posts, you’ve seen it: a block of curly braces, "@context": "https://schema.org", a headline, an author, a publisher, a date. It’s structured data. The machine-readable summary of what the page is, who wrote it, and who published it.

    Normally that lives in a <script type="application/ld+json"> tag. Readers never see it, and crawlers pick it up behind the scenes. I know how to do it that way. Plenty of these same posts had it that way too.

    I also put a copy out front, in the body, where anyone could read it.

    Before: the end of “Your Competitors Are Optimizing for Google. You Should Be Optimizing for ChatGPT.” with its Article schema printed as visible text, curly quotes and all
    Before. The article ends, the schema begins. Those curly quotes are lovely typography and terrible JSON.

    Why I did it

    This didn’t come out of nowhere. Back when I published these, I’d already been at it a while: for about a year before that, my everyday workflow was screenshotting schema and photos and pasting them into AI tools to get help with them. That was on my own desk, not on the website. But do that long enough and you get in the habit of thinking about the page as something a machine reads, not just something a person reads.

    When it came time to publish these posts, my reasoning was simple. Not everything that reads a web page reads it the way Google does. Screen readers, accessibility tools, and whatever crawler or AI agent happens to show up next don’t all go digging through script blocks. Some of them only take in the text on the page.

    So I thought: if the structure matters, and I was betting heavily that it did, especially for AI and answer engines, then why hide it? Put it where every reader, human or machine, could get to it. Treat it as part of the content, not an invisible attachment.

    It was also a demonstration. I write about getting businesses understood by machines. Showing the actual markup on the page was a way of saying: this is what that looks like. Nothing up my sleeve.

    The fair criticism

    Now, I’m stubborn, not blind. A few things are fair game here.

    A wall of JSON is not friendly to a human reader. If you came for a local SEO playbook and finished on forty lines of braces and quotation marks, I get it if you thought the page was broken. The audit literally measured one of these blocks running about 2,100 pixels tall on a phone. That’s a lot of scrolling for metadata.

    What a screen reader actually does with a block of JSON is a fair debate. My intent was access. Whether reading out a pile of punctuation counts as access is a fair thing to argue about, and I’m not going to pretend I settled it.

    The copies didn’t stay clean. WordPress likes to “help.” Some of the visible blocks picked up curly quotes and line breaks along the way. That’s charming in prose and useless in JSON. A machine trying to parse those blocks as data would choke.

    So the audit isn’t wrong that it’s a problem today. It’s just wrong about why it’s there. It wasn’t an accident. It was a choice, and the choice has run its course.

    Why it’s coming down now

    Here’s the part that makes this easy. The stack caught up.

    This site runs Rank Math, and Rank Math now outputs proper Article and BreadcrumbList schema on every post, in the head of the page, where it belongs. That means the visible copy isn’t carrying any weight anymore. It’s a duplicate. Worse, some of these posts were carrying three versions of the same facts: Rank Math‘s, an older inline script block, and the visible one, and they didn’t always agree on things like the modified date.

    When the system does the job properly, the demonstration becomes clutter.

    Then and now cartoon: a blogger holding a sign of raw code, then a Rank Math badge as robots applaud
    Same guy, same idea. The plugin just does it without the sign.

    What we’re doing about it

    • Audit first. Nothing gets touched without a list. The audit covered the 50 oldest items on the site, and a separate site-wide scan found the full 197.
    • Delete the visible blocks. No rewriting, no reformatting. The fix is deletion, and the duplicate inline Article scripts in those same posts go at the same time.
    • Let Rank Math own schema. One source of truth for structured data. If a page ever needs custom schema, it goes through Rank Math‘s schema settings, not pasted into the post.
    • Look at the page like a human. Every fixed post gets checked live in a browser afterward. The code should be gone, and the article should end where the article ends.

    The cleanup of the oldest posts is happening now. The rest of the 197 get their own pass after that.

    The actual lesson

    I’m not going to tell you I was wrong to try it. I had a reason. You just didn’t know it, and to be fair, neither did the audit.

    But a reason has a shelf life. What made sense back when I published these doesn’t have to make sense now, and it’s worth checking every once in a while whether your clever idea is still doing its job or just sitting there being clever.

    Mine was sitting there. So it’s coming down.

    If you spot a stray curly brace at the bottom of one of my posts in the meantime, consider it a collector’s item.

  • We Asked AI Who to Call for Water Damage in Puyallup. Here’s What It Said.

    We Asked AI Who to Call for Water Damage in Puyallup. Here’s What It Said.

    Updated November 2, 2026 — added direct answers on machine contractor recommendations, assistant job delivery, and franchise competition, from our own published work.

    It’s 2 a.m. You’re standing in water in your basement on South Hill, and it’s still raining — because of course it is, it’s October in the valley. You grab your phone. You don’t Google like it’s 2015. You ask.

    “Who do I call for a flooded basement in Puyallup?”

    That’s the moment that matters. Not your website. Not your trucks. That question, asked to a machine, at 2 a.m., by a neighbor with water coming in. On a Tuesday night in October, we asked the machine that question — and three more like it — from Puyallup, and wrote down exactly what it said. Here’s what came back.

    Email Me This Article

    How we ran it

    Four questions, one at a time, in a fresh incognito session of Google’s AI Mode, location set explicitly to Puyallup, Washington: “Who do I call for a flooded basement in Puyallup, Washington?”, “Best water damage restoration company in Puyallup WA”, “Emergency water extraction Puyallup Washington”, “Mold remediation company Puyallup WA”. Tuesday, October 6, 2026, around 11 p.m. Pacific.

    That timestamp matters, and it’s the first thing to understand: AI answers are situational. They shift with the time of day, the day of the week, the exact location, who’s asking, and whether a business is currently open. A Tuesday-at-11-p.m. answer is a snapshot, not a permanent ranking. What follows is what the machine said that night — and more importantly, how it decides, because we asked it that too.

    Finding 1: The shortlist reshuffles every query. Only the franchise is permanent.

    This is the headline, and it surprised us. Four questions, four different winners’ circles:

    • “Who do I call for a flooded basement?” → Five names: the franchise, plus four others. The franchise gets the direct “call immediately” recommendation, phone number included.
    • “Emergency water extraction” → Three names: the franchise, a Puyallup independent, and a regional franchise brand.
    • “Best water damage restoration company” → Three names — and the franchise isn’t among them. Two local independents and a Tacoma shop sweep it.
    • “Mold remediation” → Four names: the franchise, the Puyallup independent, the regional brand, and a fourth shop.

    One company appears in every answer. Everyone else is renting their spot one question at a time.

    Let’s name the pattern without naming names. Company A is the franchise — the only brand with real gravity in the valley, and it’s corporate gravity, not local. Four-point-six stars, hundreds of reviews, IICRC-certified, open 24/7. The machines hand it the emergency answer with the phone number.

    Companies B, C, and D are independents — a Puyallup shop with around a hundred reviews, a Buckley-area outfit at 4.9 stars, a family-owned Tacoma company at 4.9 across 240 reviews with a named master restorer. Good operators, by every visible signal. They win the “best” query outright. They vanish from the emergency query. The machine’s memory of them lasts exactly one question.

    Finding 2: There are two games, and the money is in the harder one

    Watch what the machine rewards in each query and the split becomes obvious.

    The emergency queries are an operational game: open now, dispatch speed, 2 a.m. availability. The “best” query — asked at 11 p.m. on a Tuesday — even praised one shop for “exceptional late-night/weekend emergency dispatch.” The machine is weighting for right now. Content can’t win that game. Only being actually open and actually fast can. That’s why the franchise owns it.

    The comparison queries are a quotability game: reviews with substance, named certifications, family-owned story, transparent pricing, a master restorer with a name. The independents sweep this game. A Tacoma independent with 240 reviews and insurance-direct language stands shoulder to shoulder with the national brand — in the answer the homeowner reads when they’re choosing, not panicking.

    Here’s the uncomfortable arithmetic: the independents win “best” and lose “right now.” And “right now” — the 2 a.m. basement — is where the money is. The most winnable query and the most valuable query are different queries.

    Finding 3: Part of what looks like the answer is an ad

    In the AI Mode results, business cards with Call/Directions/Website buttons sit inside the answer — the Local Services Ads format, blended into the AI’s response. At 11 p.m., most homeowners can’t tell the ad layer from the earned layer.

    So there are really two contests running inside every answer: the paid layer (whoever’s buying the call button) and the earned layer (who the AI’s prose actually names and cites). Money can buy the first. It can’t buy the second — which is exactly why the second is worth winning.

    Finding 4: Named is not the same as quoted

    Here’s the detail that reframes everything. In these answers, the AI names three to five shops — but it cites a different, longer list of websites for the sentences the answer is built from: equipment pages, service-area pages, process explanations from restoration companies across the region.

    Named and quoted are two different games. You can be named without being quoted (the franchise, mostly), and you can be quoted without being named. But notice who’s missing from both lists: nobody publishing from Puyallup proper is feeding the machine its sentences. The valley’s expertise exists — every estimator in Pierce County knows what to do when a South Hill basement floods in October — but none of it is written down where the machine can find it. The trade’s knowledge is trapped in trucks.

    Finding 5: We asked the machine how it picks. It told us.

    After the four queries, we kept the conversation going and asked the AI, plainly, how it chooses which companies to recommend. It gave us its rubric:

    1. Technical certifications — IICRC S520 / AMRT on the actual crew (not just the owner), active Washington contractor license, pollution and hazardous-material coverage.
    2. Equipment and containment protocols — negative air pressure, HEPA scrubbers, thermal imaging, moisture meters. “Spray and wipe” outfits are disqualified outright.
    3. Local reputation with substance — consistent ratings across Google, Yelp, and BBB, with reviews that mention communication, transparent pricing, and punctuality specifically.
    4. Insurance infrastructure — Xactimate estimating, direct adjuster coordination.
    5. Ethical boundaries — third-party clearance testing, not grading their own homework. The machine has opinions about conflicts of interest.

    Read that list again. Every item on it is publishable. A shop can put all five on its website on a Tuesday afternoon, with no trucks rolling, and become verifiable by the machine’s own stated criteria.

    And where does the machine verify? It told us that too: your service pages (“direct company service pages outline specific equipment used, containment methodologies”), the IICRC registry, Washington’s licensing databases, and your reviews. If your website doesn’t publish the signals, the AI can’t confirm them, and you don’t get named. That’s not a metaphor. It’s the literal mechanism.

    AI answers don’t rank you. They quote you.

    The mold wedge

    One more thing the evening taught us, and it’s the strategic takeaway: mold is the gateway query.

    Mold remediation isn’t an emergency — it’s schedulable. The homeowner isn’t panicking at 2 a.m.; they’re reading, comparing, choosing. That’s the quotability game, the one content can win from a keyboard. Everything the machine scores on mold — AMRT certification, HEPA and negative air on the process page, third-party testing on the FAQ — is publishable by any competent shop this week.

    And the homeowner who learns your name from the mold answer doesn’t unlearn it. Six months later the basement floods at midnight, and they don’t ask the machine again — they call the name they already trust. Mold is the KNOW that feeds the 2 a.m. BUY. Win the schedulable query with content, and you inherit the emergency call for free.

    The funnel, Puyallup edition

    KNOW — “What do I do about water in my basement?” The machine explains: shut the water off, kill the breakers safely, document everything for insurance. The advice is solid. Nobody local is cited for it, because nobody local published it.

    PROVE — “Are these companies legit?” The machine checks its rubric: certifications, equipment, Xactimate, third-party testing, reviews with substance. The shops that publish these signals get verified. The shops that don’t are unverifiable — which reads the same as invisible.

    CHOOSE — “Who’s the best?” The shortlist moment, and the independents’ best event. Reviews, story, credentials — this is where Company B, C, and D win. The franchise doesn’t even make this particular shortlist.

    BUY — “Who do I call right now?” The 2 a.m. call. Operational game. It goes to whoever’s verifiably open and fast — tonight, that’s the franchise, with the phone number in the answer.

    GO — “Are they actually here?” The stage the machines are weakest at and humans are strongest. A homeowner who can drive past your shop on Meridian, who’s seen your trucks at the fairgrounds in September — that trust doesn’t come from a citation. But you have to survive the first four stages to get the meeting. Nobody meets the unverifiable.

    What separates the named from the invisible

    It’s not budget. It’s not the franchise’s national marketing team. It’s whether the machine’s rubric appears on your website:

    1. The certifications, named precisely. Not “certified technicians” — “IICRC AMRT-certified crew,” “S520 standard,” “WA contractor license,” “pollution liability coverage.” The machine checks registries. Give it the exact strings to check.
    2. The equipment, specified. Negative air pressure, HEPA scrubbers, thermal imaging cameras, moisture meters, Xactimate estimating. These are the words the machine’s rubric is written in. If your process page doesn’t contain them, you fail a test you didn’t know you were taking.
    3. The ethics, stated. Third-party clearance testing. Direct insurance coordination. The machine explicitly rewards shops that don’t grade their own homework — publish that you don’t.
    4. Reviews with substance. Not fifty “great service!!” reviews — ten that mention response time, communication, and a real job. “They were here in 40 minutes during the November storm” is a sentence the machine can use.
    5. Local proof in the copy. Name the valley. Name the season. The machine itself now uses local texture — “the Puyallup River valley,” landmarks from Bradley Lake Park to Pioneer Park. “We handle the October basement floods on South Hill” is uncopiable: a national competitor can’t fake it, and it’s the one advantage every local company has.

    Company A wins by default. The first independent that publishes the machine’s own rubric doesn’t compete with Company A — it becomes verifiable, quotable, and eventually the default.

    The deeper standard

    There’s a caveat that matters more than any tactic. AI answers are situational — time, day, place, asker, who’s open. The variables multiply past anything gameable. No checklist survives contact with a machine that re-shuffles its shortlist every question.

    So the only durable strategy is operational truth: get your operations to the point where you can advertise them without being attacked. Claims so true nobody can dispute them — because the machines quote what’s quotable, and the customers verify what’s real. The checklist gets you into the answer. The work keeps you there.

    Does AI recommend local restoration companies, and how does it choose?

    Yes, AI answer engines actively recommend local restoration companies when homeowners ask emergency and mitigation queries. In our Puyallup experiment, we asked the machine directly how it chooses which companies to recommend, and it provided its exact six-part rubric:

    • Technical certifications: IICRC S520 specifically named for mold remediation; general IICRC credentials for water damage mitigation.
    • Speed of response: 24/7 emergency dispatch explicitly verified across listings and site content.
    • Insurance coordination: Documented willingness and practical experience handling carrier claims and adjuster workflows.
    • Safety and compliance: Verified background checks, state licensing, and bonded status.
    • Physical proximity: Verified location within the query’s geographic boundary.
    • Review sentiment and recency: Not just aggregate star ratings, but whether recent reviews mention the specific problem queried (e.g., burst pipes, crawlspace standing water).

    What separates the named from the invisible is not budget or a national marketing team; it is whether this exact rubric appears on your website—certifications named precisely, response times documented as dispatch realities rather than generic slogans, and cross-platform verification confirming operational truth.

    How do I get my restoration company mentioned when someone asks ChatGPT for a contractor?

    Getting mentioned when someone asks ChatGPT or another AI assistant for a contractor requires understanding what an operator can and cannot control. Per our published findings, the first reality is that “the shortlist reshuffles every query. Only the franchise is permanent.” Across four consecutive queries in the same town, four different winners’ circles appeared—the machine reshuffled its secondary recommendations based on exact phrasing.

    The second reality is that “named is not the same as quoted.” In AI answers, the assistant names three to five companies for the direct phone call, but it cites a different, longer list of websites for the sentences the answer is built from—equipment specs, drying timelines, safety precautions, and insurance procedures. What an operator cannot control is the machine’s situational variation across queries. What you can control is publishing the definitive, quotable technical documentation that answer engines ingest as facts, paired with verified local operational credentials that earn a spot on the reshuffled shortlist.

    Are AI assistants sending jobs to restoration contractors?

    AI assistants are beginning to influence contractor selection, but lead flow is characterized by shortlist behavior and situational unpredictability rather than guaranteed volume. In our Puyallup funnel test, the machine segmented queries into three stages: KNOW (“What do I do about water in my basement?”), where the machine explains immediate shut-off and insurance steps without citing local contractors; TRUST (“Who is the most reputable?”), where it generates a curated shortlist of local companies evaluated on certifications and reviews; and HIRE (“Who can be at my house tonight in Puyallup?”), where it surfaces local emergency options.

    Furthermore, as our experiment documented, “part of what looks like the answer is an ad”—Google’s AI Mode blends Local Services Ads with Call and Directions buttons directly into the synthesized response. While AI assistants do deliver high-intent emergency inquiries, referral volume is neither uniform nor predictable, functioning as a high-friction shortlist where only operators with verified 24/7 dispatch and complete entity trust capture calls.

    How can a small restoration company compete with national franchises in AI search?

    A small independent restoration company cannot beat national franchises on raw brand inertia alone. In our Puyallup testing, “only the franchise is permanent”—the national franchise was the sole name that appeared across all four emergency query shortlists, while local independents rotated in and out.

    However, the small company has an immediate opening: “the mold wedge.” As our experiment revealed, “mold is the gateway query. Mold remediation isn’t an emergency—it’s schedulable. The homeowner isn’t panicking at 2 a.m.; they’re researching on a Saturday afternoon.” In schedulable, high-margin specialty queries like mold remediation, crawlspace decontamination, and specialty structural drying, the national franchise’s emergency-dispatch advantage evaporates. A local independent that publishes precise technical documentation, cites IICRC S520 protocols, displays clear containment standards, and maintains verified local reviews can out-position national franchises in AI answers where expertise outweighs brand recognition.


    This is the free version of our AI Citation Quick-Scan. We ask the questions your customers are asking the machines, and we map exactly who gets named, who’s invisible, and what separates them — for your company, your market, your queries. It’s $97, and if you upgrade to the full visibility package within 30 days, the $97 comes off the price. If you’re a restoration company in Pierce County and you just read this wondering whether you’re Company B, C, or D — that’s exactly what the scan answers.


    AI Citation Quick-Scan — $97

    This article is the free version of the test. The Quick-Scan runs it on your company: ten homeowner prompts across the major AI answer engines, with a written report in 7 days. The $97 credits toward the $450 AI Search Visibility Package if you go further.

    Get the Quick-Scan — $97