Related on Tygart Media: AI operator’s stack · conversations as code · owner freedom kit.
Blog
-
Claude Code Limits: Permanent +25% Weekly After the Sep 13 Promo (September 2026)
Last verified: September 15, 2026 (Pacific). Sources: Anthropic Help Center — Claude Code May–August 2026 weekly limits promotion (updated; permanent +25% now official) and Fable-on-plan article. Exact token counts are not published — check Settings → Usage or
/usagein the CLI.Direct answer: Claude Code has two meters. A rolling 5-hour session limit that the May 2026 doubling made permanent, and a weekly usage limit. The temporary +50% weekly promotion ended September 13, 2026 at 11:59 PM PT — do not claim +50% as live. Starting September 14, 2026, Anthropic Help Center states weekly limits in Claude Code are permanently 25% higher than the pre-promotion baseline for Pro, Max, Team, and seat-based Enterprise. That is lower than the promo week (1.5×) and higher than the old baseline (1.25×). The 5-hour window did not change. Fable 5 and Fable 5.1 are included only on Max, Team Premium, and seat-based Enterprise Premium, and they may use at most 50% of the weekly pool.
The two clocks
People treat “I hit my limit” as one event. It is two.
- 5-hour session. Rolling window. Burns when the model is working, not when you are idle. Anthropic doubled this across paid plans on May 6, 2026 and removed the old peak-hour throttle for Pro and Max. Neither the +50% weekly promo nor the permanent +25% weekly change raised or lowered this clock.
- Weekly bucket. Fixed reset time on your account (Settings → Usage). This is the one that ends a Friday on Max after a Fable week. The May–September 2026 +50% promotion applied to Claude Code only — CLI, IDE, desktop, and web Code — not to Claude chat or Cowork. That temporary bump is over. What remains: the permanent +25% over the pre-promo weekly baseline (Help Center).
Eligible for the promo and the permanent +25%: Pro, Max, Team, and legacy seat-based Enterprise. Not eligible: Free and consumption-based Enterprise.
The September 13–14 change
Official Help Center timeline:
- May 13 – Sep 13, 2026 11:59 PM PT: Claude Code weekly limits were 50% higher than the pre-promotion baseline. 5-hour limits were not affected.
- Starting Sep 14, 2026: weekly limits in Claude Code are permanently 25% higher than they were before the promotion for Pro, Max, Team, and seat-based Enterprise. Plan price unchanged.
- 5-hour limits stay at the May doubled level.
Cite: support.claude.com/en/articles/15910845.
Compared to last week’s promo, you have less weekly headroom than 1.5×. Compared to the old baseline, you have more: 1.25×. Exact quotas are still unpublished — read your live number in Settings → Usage.
Who gets Fable 5.1 on the subscription
Official: Claude Fable models on your plan. Fable 5 and Fable 5.1 follow the same plan rules.
Plan Fable 5 / 5.1 on the subscription Free Not included Pro ($20) Not in plan limits. Usage credits from the first Fable token. Team Standard Same as Pro: credits, not included. Max 5x / Max 20x Included, capped at 50% of weekly limits. Same pool as Sonnet and Opus. Team Premium / Enterprise Premium seats Same 50% included cap as Max. Enterprise Standard seats Only if the org enables usage credits. API / usage-based Enterprise List rates. See Fable pricing. The July 2026 one-time $100 credit for Pro / Team Standard applied to the Fable 5 plan change. Help Center says there is no matching credit for Fable 5.1.
Practical read: Pro can still open Fable. It just bills. Max can spend half the week on Fable before the included cap trips, then it is credits or switch to Opus 5 / Sonnet 5. Fable burns the shared weekly bar faster than Sonnet — plan against the permanent +25% weekly bar, not the old promo week.
What still burns quota
- Long agent loops and multi-agent fan-out (each worker keeps its own context).
- Dumping a whole repo when one file would do.
- MCP tool output that stays in context for the rest of the session.
- Leaving
ANTHROPIC_API_KEYset so the CLI bills API rates and ignores the subscription.
What to do now
- If you are on Pro and need Fable all week, budget credits or move the hard jobs to Max. The subscription does not include Fable on Pro.
- If you are on Max, treat weekly headroom as permanent +25% over the old baseline — not the temporary +50% promo week. Route cheap loops to Sonnet 5; save Fable for the jobs that need it. Check Settings → Usage /
/usagefor your real number. - Do not upgrade from Pro to Max only because the 5-hour window feels tight on Friday. Check which clock you hit. Session vs week is a different purchase.
-
Restoration Google LSA Changes: Verified Badge & Disputes
If you have been running Google Local Services Ads (LSAs) for your restoration company for more than a year, the platform you’re managing today is not the one you signed up for. Two changes that landed in late 2025 quietly rewrote the economics of LSAs for restoration contractors — and most owners I talk to are still operating on outdated assumptions. The badge you bragged about is gone. The dispute process you relied on to claw back bad leads is gone. And the insurance trap that can silently kill your campaign is bigger than ever. Here is what actually changed and what you should do about it.
The badge consolidation: “Google Guaranteed” is now “Google Verified”
Badge renamed — ops discipline did not get easier. Effective October 20, 2025, Google folded its three trust badges — “Google Guaranteed,” “Google Screened,” and “License Verified by Google” — into a single unified “Google Verified” blue checkmark. For restoration owners who spent months getting the green Google Guaranteed badge and then put it on their trucks and websites, this matters. The badge you earned still exists, it just looks different and means something slightly different now.
The verification requirements themselves haven’t loosened. You still pass a background check (Google runs this free through its partner Evident), and Google still verifies your license and insurance. Reported approval timelines run roughly three to four weeks once your documents are submitted — budget for that lag if you’re launching into a busy season.
The money-back guarantee is dead — and that changes your pitch
Here’s the change almost nobody talks about: the consumer money-back guarantee that was the whole point of the “Google Guaranteed” name was discontinued on November 7, 2025. Under the old program, if a customer was unhappy with a job booked through LSAs, Google would reimburse them up to a lifetime cap. That backstop is gone.
Why should a restoration owner care? Because if your sales process or your website copy still leans on “we’re backed by Google’s money-back guarantee,” you are now making a claim that is no longer true. Audit your marketing materials. The badge now signals verification — that you are who you say you are, licensed and insured — not a satisfaction guarantee. That’s a meaningful difference in how you should position it to a homeowner who just had a pipe burst.
The bigger story: manual lead disputes are gone
This is the change that hits your wallet directly. For years, the LSA model let restoration contractors manually dispute junk leads — wrong number, spam, a caller looking for a service you don’t offer, a job outside your service area — and recover a meaningful share of those charges. Reports from contractors who worked the old system suggest manual disputes recovered credits on a solid majority of flagged bad leads when documented well.
Google removed manual disputes in 2024 and replaced them with an automated credit system. Here’s how it works now: Google’s machine learning reviews leads, typically within about 72 hours of being charged, and automatically applies credits for leads it deems invalid, with credits generally appearing within roughly 30 days. You no longer build a case and submit it. The algorithm decides.
Two limitations matter enormously for restoration:
- “Job type not serviced” and “geo not serviced” leads are no longer creditable. If a caller wants mold remediation and you only do water mitigation, or the job is two counties away, Google will not credit that charge anymore. Restoration owners across the home-services space have reported receiving out-of-area and out-of-category leads with no recourse — and that’s now baked into the system, not a glitch.
- The automated system is reportedly less generous. Practitioner estimates put the current automated credit rate well below what manual disputes used to recover. You will eat more bad-lead cost than you used to. Plan your cost-per-acquisition math accordingly.
The one lever you still have: rate every lead
The one lever you still have: rate every lead honestly. The “Rate this lead” feedback tool in your LSA dashboard is not a customer-satisfaction survey — it’s the primary input the automated credit engine uses. Marking a lead as “Very dissatisfied” with a specific, accurate reason is reportedly the most reliable way to nudge a credit. The discipline here is operational: whoever answers your LSA calls needs a standing instruction to rate every single lead the same day, with notes. If you’re not rating leads, you’ve handed the algorithm zero signal and you’re leaving credits on the table.
The silent campaign-killer: your insurance certificate
Here is the trap that takes down more restoration LSA accounts than bad creative ever will. Google periodically re-checks the license and insurance on file in your LSA account. When your general liability policy renews and you don’t upload the new certificate, Google can pause your ads automatically — no warning email that most owners notice, no grace period you can count on. For a restoration company, an unexplained pause during storm season is real revenue walking out the door.
The fix is trivial and free: set a calendar reminder for two weeks before your GL policy renews each year to upload the fresh certificate of insurance into your LSA account. This single recurring task prevents the most common avoidable outage in the channel.
What this costs you in restoration
For context on the stakes: water damage restoration sits at the expensive end of LSAs because the jobs are big and contractors bid the channel up. Reported cost-per-lead figures for water damage restoration commonly land in roughly the $75–$200 range depending on market competition, with some sources citing $300+ per call in the most aggressive markets. Cost per acquired job is reported in the rough range of $200–$800. With restoration margins what they are, those numbers can still pencil out — but only if you’re not silently absorbing uncreditable junk leads and only if your account never goes dark over a lapsed insurance cert. The platform changes above all push in the same direction: the margin of error on LSA management got thinner in late 2025.
The bottom line
Bottom line: LSA is a system, not a set-and-forget badge. If you run LSAs for a restoration company, do three things this week. First, scrub any “money-back guarantee” language from your marketing — it’s no longer accurate. Second, make daily lead-rating a non-negotiable task for whoever fields your LSA calls, because rating is now your only real influence over credits. Third, put a recurring two-weeks-before-renewal reminder on the calendar to update your insurance certificate. None of these cost a dollar, and together they protect the most expensive lead channel in your marketing budget from the changes Google made while you weren’t watching.
📖 Recommended Reading in Restoration Intelligence
- 🎯 Pillar Guide: Does Homeowners Insurance Cover Radon Mitigation?
- 🔗 Next Topic: Radon Mitigation System Installation in New Construction
-
Verify llms.txt: How to Check Server Logs for AI Crawlers
You shipped an
llms.txtfile. You curated the links, you paired it withrobots.txt, you validated the format. Now answer the only question that matters: is anything actually requesting it? Most site owners never check — and the data from 2026 suggests the honest answer, for most domains, is “almost nothing.” This is the verification step that turnsllms.txtfrom an act of faith into a measurable signal. Here is how to read your own server logs and find out exactly what is fetching the file you published.Why verification matters more than the file itself
Why verification matters more than the file itself. The uncomfortable finding of the last year is that publishing
llms.txtand benefiting fromllms.txtare two different things. In OtterlyAI’s 90-day crawler study, only 0.1% of AI crawler requests touched/llms.txtat all — 84 requests out of 62,100 total AI bot visits — and the file received far fewer visits than the average content page (OtterlyAI GEO study). As of Q1 2026, no major AI company — OpenAI, Google, Anthropic, Meta, or Mistral — has publicly committed to reading or acting onllms.txtin production systems, though GPTBot does fetch the file occasionally (AEO Engine).That does not make the file worthless. It makes measurement the whole game. If you cannot tell whether a crawler ever requested the file, you cannot tell whether your time was wasted, whether a platform quietly started honoring it, or whether your file is returning a silent 404. Verification is the difference between strategy and superstition.
The five-minute server-log check
Five-minute server-log check. Every fetch of your
llms.txtfile leaves a row in your access log. The job is to isolate requests to that path, then filter by the user-agents that belong to AI systems. On any server with standard combined-format Apache or Nginx logs, this one-liner does the first pass:grep -E "/llms(-full)?\.txt" /var/log/nginx/access.log | \ grep -E -i "GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|Claude-User|Claude-SearchBot|PerplexityBot|Perplexity-User|Google-Extended|Google-CloudVertexBot|Amazonbot|CCBot|Applebot|meta-externalagent|MistralAI-User|bingbot"The first
grepnarrows to requests forllms.txtorllms-full.txt. The second filters to the known AI crawler user-agent strings documented across 2026 reference work (No Hacks AI User-Agent Landscape 2026; Momentic crawler list). Each surviving line tells you three things: which bot, what time, and the HTTP status code it received.That status code is the part people skip. A
200means the bot got your file. A404means you have been congratulating yourself over a file the crawler never actually reached — a misconfigured path, a redirect loop, or a build step that drops the file on deploy. A301or302means it is being redirected, and not every crawler follows redirects for this path. Read the status column before you read anything else.Turn the raw hits into a monthly cadence table
One grep tells you whether the file is reachable. To know whether anything is changing, you need the same query run on a schedule and counted by bot. Extend the pipeline to a count:
grep -E "/llms(-full)?\.txt" /var/log/nginx/access.log* | \
  grep -E -i -o "GPTBot|ClaudeBot|PerplexityBot|Google-Extended|bingbot|Amazonbot|CCBot|Applebot" | \
  sort | uniq -c | sort -rn
This produces a leaderboard of which AI user-agents requested your
llms.txtacross all retained logs. Capture that number on the first of each month and you have a cadence series. The signal you are watching for is not the absolute count — it will be small — but the direction: a bot that appears for the first time, a bot whose hit count jumps, or a bot that goes silent. Those inflection points are the leading indicators that a platform has changed how it treats the file.What you see in the log What it means Action No requests to /llms.txtat allFile may be unreachable, or simply not yet fetched — both are common Request the URL yourself; confirm a clean 200 before assuming neglect 200from GPTBot, low frequencyConsistent with reported behavior — GPTBot fetches occasionally Log the cadence; treat as baseline, not a ranking signal 404or301on the pathCrawler is not getting the file you think you published Fix the path/redirect today — this is a silent failure A new bot appears month-over-month A platform may have started fetching the file Note the date; correlate with any citation or referral changes Cross-check against your content fetches
The
llms.txthit count means little in isolation. Compare it against how often the same bots fetch your actual content pages. If GPTBot pulls forty content URLs a day and never touchesllms.txt, the file is not part of how that crawler discovers you — your content’s own structure and internal linking are doing the work. The practical monitoring approach documented for 2026 is exactly this: a server-log dashboard built against the major user-agents, watching cadence and path-preference shifts month over month (Digital Applied 30-day log study). The same study notes distinct personalities worth knowing — GPTBot crawls more aggressively than most assume, ClaudeBot is more patient than its volume suggests, and PerplexityBot is quieter than its share-of-voice would predict.What to do with the answer

What to do with the answer. If your logs show the file is reachable and occasionally fetched, you are in the normal range for 2026 — keep the file current and keep measuring. If they show a
404, you found a real bug that no amount of curation would have fixed. And if they show a brand-new bot starting to request the path, you have spotted a platform behavior change before the blog posts catch up to it. That last case is the entire payoff: the practitioners who read their own logs will know the standard started mattering weeks before the ones who only read about it. Verification is not the boring final step of anllms.txtrollout. On a standard that nobody has formally committed to honoring yet, it is the only step that produces evidence instead of hope.Related on Tygart Media: AI crawler experiment · GEO tactics · Bing Webmaster AI tab.
-
Legacy Systems: Why Deprecated Tools Outlive Their Reason
Related on Tygart Media: AI operator’s stack · redundant AI tasks · most replaceable thing.
-
Claude Code MCP Scopes: Mastering the –scope Flag
Everyone teaches you how to add an MCP server to Claude Code. Almost nobody teaches you where to add it — and that one decision, the scope flag, is the difference between a clean team setup and three engineers debugging why the same server works on one machine and not another. I’ve watched it happen. The fix is always the same: someone added a server at the wrong scope.
If you run
claude mcp addwithout thinking about scope, Claude Code makes the choice for you. It defaults to local. That’s fine for a throwaway experiment and wrong for almost everything else.The three scopes, and what each one actually controls
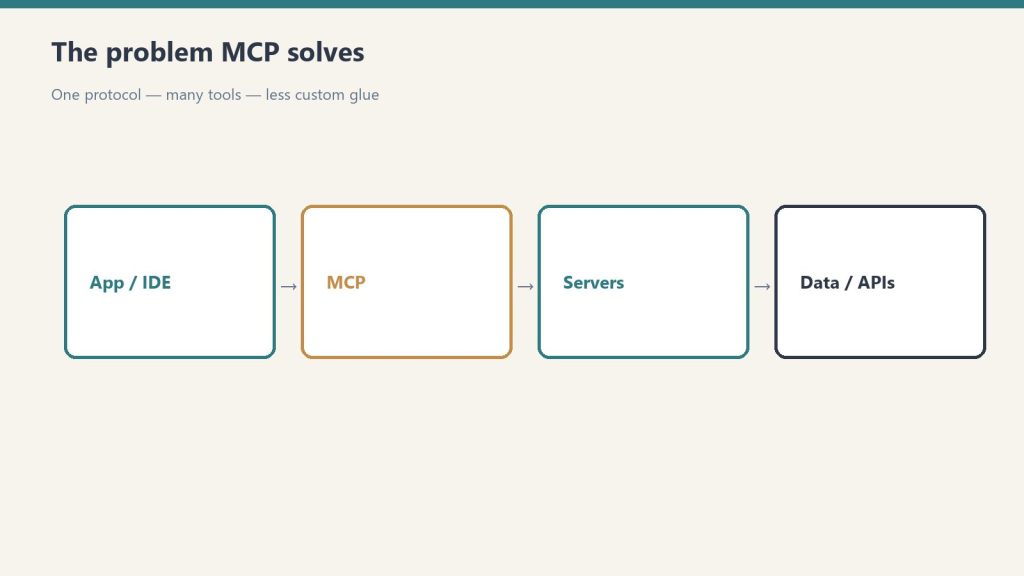
The three scopes, and what each one actually controls. Claude Code stores MCP server configurations in three places, and the
--scopeflag decides which one you’re writing to.Local scope (the default) writes the server config into your personal settings, keyed to the current project path, inside
~/.claude.json. Nobody else sees it. It doesn’t get committed. Open the same repo on your laptop at home and the server isn’t there. This is the scope you want for a one-off — a database you’re poking at this afternoon, a server you’re still deciding whether to keep.Project scope writes to a
.mcp.jsonfile at the root of the repository. You commit that file to git. Everyone who clones the repo gets the same servers, configured the same way. This is the scope that makes MCP a team decision instead of a personal one — and it’s the one most people skip because the default never points them at it.User scope writes to your global config so the server is available in every project you open, regardless of which repo you’re in. This is for the handful of servers you genuinely use everywhere — a documentation search server, a personal notes tool — not for anything project-specific.
The mental model I use: local is “me, here, now.” Project is “anyone on this repo.” User is “me, everywhere.” If you can articulate which of those three sentences describes the server, you know the flag.
The command, written three ways
The command, written three ways. Same server, three scopes. The only thing that changes is the flag.
# Local — default, personal, not committed
claude mcp add --transport stdio my-db -- npx -y @some/db-mcp-server

# Project — shared via .mcp.json, commit to git
claude mcp add --scope project --transport stdio my-db -- npx -y @some/db-mcp-server

# User — available in every project you open
claude mcp add --scope user --transport stdio my-db -- npx -y @some/db-mcp-server
Verify what’s connected and where it came from with
claude mcp list. If a teammate reports a server “isn’t working” and yours is fine, this is the first command to run on both machines — the discrepancy is almost always a scope mismatch, not a broken server.The .mcp.json pattern that actually pays off
The .mcp.json pattern that actually pays off. Here’s the workflow that turns this from trivia into leverage. When you onboard a repo that the whole team uses, you decide once which MCP servers belong to that codebase — the Postgres server pointed at the dev database, the issue tracker, whatever the repo’s daily work requires — and you add them all at project scope. The resulting
.mcp.jsonlooks like this:{ "mcpServers": { "postgres": { "command": "npx", "args": ["-y", "@some/postgres-mcp-server", "postgresql://localhost/devdb"] }, "linear": { "type": "http", "url": "https://mcp.linear.app/mcp" } } }Commit it. Now a new hire clones the repo, opens Claude Code, and the agent already knows how to query the dev database and read tickets — no setup doc, no Slack thread asking “wait, how do I connect the database again.” The repo carries its own integration surface.
One safety detail worth knowing: when Claude Code encounters project-scoped servers from a
.mcp.jsonit didn’t write, it asks you to approve them before they run. That prompt exists because a committed config file is, technically, code other people can put on your machine. Read what you’re approving — the same way you’d read apackage.jsonscript before running it.Where this bites people
Three failure modes I see repeatedly. First: adding a server at local scope, then wondering why it vanished on a different machine — local is path-and-machine specific, that’s the design. Second: putting a secret directly into
.mcp.jsonand committing it to a public repo. Don’t. Reference an environment variable in the config and keep the actual token out of git. Third: piling everything into user scope so every project loads servers it doesn’t need, which bloats the context the agent has to reason over and slows routing when you have many tools connected.The cost angle, since it’s a fair question: scoping itself costs nothing. But every connected MCP server adds its tool definitions to the model’s context on each turn. With Sonnet 4.6 as the workhorse model, a lean per-project tool set is faster and cheaper than a kitchen-sink user-scope config you never pruned. Scope discipline is, indirectly, token discipline.
The rule that replaces all of this
Before you run
claude mcp add, finish this sentence: “This server should be available to ___.” If the answer is “just me, just here” — local. If it’s “anyone working in this repo” — project, commit the file. If it’s “me, in everything I do” — user. The flag follows from the sentence. Get that habit, and the entire class of “works on my machine” MCP bugs disappears from your team’s life.📖 Recommended Reading in Claude Code Insider
-
Project Glasswing: Securing Global Critical Software
Following its initial launch, Anthropic has released an update on Project Glasswing, an ambitious initiative aimed at securing the world’s most critical software infrastructure. The project represents a monumental collaborative effort between Anthropic and tech giants including Amazon Web Services, Apple, Broadcom, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, NVIDIA, and Palo Alto Networks.
As the digital landscape faces increasingly sophisticated threats, securing foundational open-source software and critical infrastructure is a massive undertaking. Project Glasswing seeks to leverage advanced AI—specifically the capabilities of models like Claude—to analyze, patch, and reinforce the software that powers our global economy.
The Future of AI-Powered Security
The latest update indicates significant momentum for the project. By bringing competitors and industry leaders to the same table, Anthropic is demonstrating the unique role AI can play not just in automation, but in global cybersecurity defense. For businesses relying on digital infrastructure, this initiative promises a more secure and resilient future.
Related on Tygart Media: Anthropic safety · is Claude safe · invisible agent layer.
-
Anthropic AI Ethics: Response to Pope Leo XIV Encyclical
In a fascinating intersection of global philosophy and artificial intelligence development, Anthropic co-founder Chris Olah recently provided remarks on Pope Leo XIV’s encyclical, “Magnifica humanitas.” The encyclical, which addresses the moral and ethical responsibilities humanity holds toward emerging technologies, has prompted deep reflection across the tech industry.
Anthropic, known for its focus on AI safety and alignment, has consistently emphasized the importance of building reliable, interpretable, and steerable AI systems. Olah’s response highlights how the company’s mission aligns with the ethical frameworks proposed in the encyclical. This dialogue represents a crucial step in ensuring that frontier AI models like Claude are developed with profound consideration for their broader societal impact.
Why This Matters
As AI becomes deeply integrated into our daily lives and enterprise workflows, the alignment of technology with fundamental human values is paramount. The response from Anthropic showcases a willingness from AI leaders to engage with moral authorities, bridging the gap between Silicon Valley and global ethical discourse.
Related on Tygart Media: Anthropic safety · Dario Amodei · Claude restraint & trust.
-
AI Site Auditing: Catching Silent Failures in Workflows
There is a class of problem in an AI-native operation that is invisible to every individual surface and obvious to the audit layer that sits across them. The site looks healthy. The dashboard is green. And the body of work has stopped compounding.
The Green Dashboard Trap
The green dashboard trap. In modern serverless architectures and agentic pipelines, we are trained to monitor local execution outputs. We build alerts for 500 errors, set up uptime pings, and watch cron job completions. If the terminal or console returns a successful exit code, we assume the system is functioning.
But in generative workflows, a script can run perfectly, parse without throwing syntax errors, make successful API calls, and still produce completely empty pages or silent failures (such as duplicating pages with
-2slugs). The surface looks pristine, but the structural value is eroding.Why Isolated Auditing is Essential
Why isolated auditing is essential. Individual execution environments (like a Claude Code terminal instance or an Antigravity background task) only know what is in their immediate input context. They do not know if the overall sitemap is bloated, if search engine canonical flags are misconfigured, or if previous runs created redundant resources. They check the box for their specific task and exit.
An audit plane sits above these execution agents. It doesn’t write code or publish content. Instead, it continuously queries the outputs of the entire operation, testing for anomalies like:
- Thin Content: Published pages that lack text bodies.
- Taxonomy Decay: Articles published without tags or nested in default categories.
- Asset Duplication: Identical titles or slugs created due to syncing conflicts.
Implementing a Two-Plane Architecture

Implementing a two-plane architecture. To prevent silent failure in portfolio management, operators must separate the Execution Plane from the Control & Auditing Plane. Notion or similar databases act as the control plane where human instructions and data states live. Google Cloud Run or local CLI tools act as compute. But a third independent auditor loop must actively crawl, assert, and report on the final state of the live web asset.
“When trust is earned in evidence rather than asserted by success logs, you stop running broken systems that look perfectly healthy.”
The audit sees what the site cannot, because the site only knows what it is, not what it has repeatedly become.
Related on Tygart Media: verify llms.txt in logs · AI crawler experiment · WordPress SEO audit.
-
Claude Code vs Cursor: Token Efficiency & Agent Teams
I’ve been running both Claude Code and Cursor on the same codebases for the last eight months. Not as a reviewer — as someone who has to actually ship features in both tools and watch the credit meter tick. Here is what the comparison actually looks like in May 2026, after Cursor’s credit overhaul, after Claude Opus 4.7, and after Claude Code’s agent teams went GA.
The Real Pricing Picture
The real pricing picture — stale-proof. The headline subscription numbers are nearly identical: Claude Pro at $20/month, Cursor Pro at $20/month. That’s where the similarity ends.
Cursor’s Pro tier in 2026 ships with unlimited “Auto” mode requests plus a $20 credit pool for premium models. Pro+ is $60/month with roughly 3x credits and background agents. Ultra is $200/month at 20x usage. Hobby is still free with limited requests. Teams is $40/user/month.
Claude Code on the Pro plan gets you Sonnet-tier usage with quota limits. Max at $100/month unlocks Opus access and 5x the usage envelope. The team plan for Claude Code is where the real spread shows: Anthropic’s team pricing on Claude Code lands materially higher than Cursor Teams for a comparable seat count. If you’re a 10-person team buying the most generous tier of each, you’re looking at roughly 3x more for Claude Code.
For solo developers, the cost is a wash at the entry tier. The decision is not about money — it’s about how each tool burns tokens.
Token Efficiency Is the Hidden Variable
This is the number I wish I had known a year ago: independent benchmarking through 2026 has Claude Code using roughly 5.5x fewer tokens than Cursor on identical tasks. Not 5.5% — five and a half times fewer.
The why matters. Cursor’s agent loop tends to re-read files, re-include context, and verify intermediate steps by stuffing prior turns back into the prompt. Claude Code’s CLI architecture leans on a tighter context budget by default, and on Opus 4.7 the model itself is doing more work per token. When you’re paying by credit (Cursor) and your power-user-hours start adding up, that ratio is the difference between a $60 month and a $200 month.
The honest counterpoint: Cursor’s median completion time on simple, single-file edits is roughly 12% faster than Claude Code. If you live in the find-and-fix-a-typo loop, Cursor’s IDE integration genuinely wins.
Where Claude Code Wins
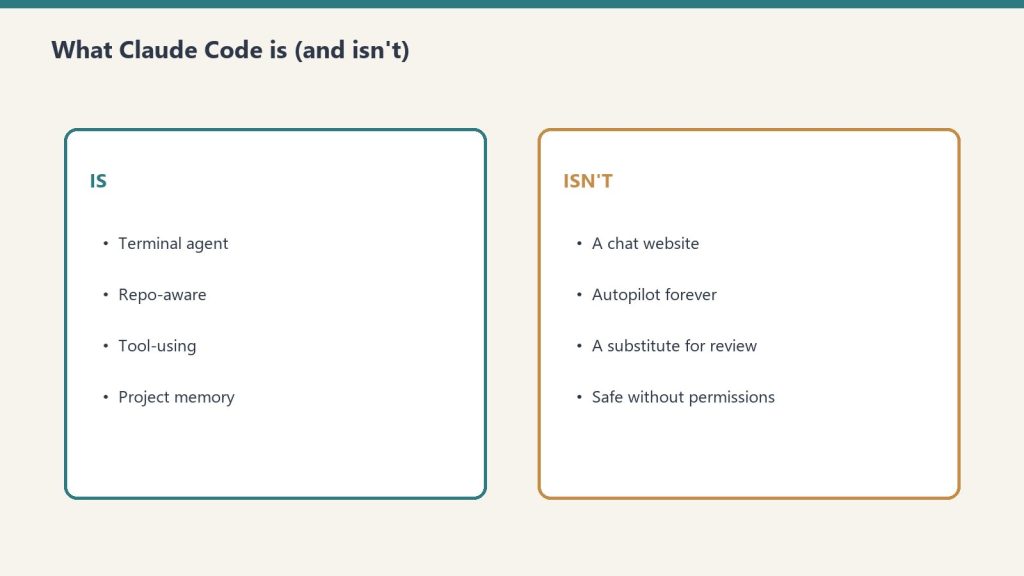
Where Claude Code wins. The 1M token context window is now generally available on Claude Opus 4.6, Opus 4.7, and Sonnet 4.6, at standard per-token pricing with no long-context surcharge. A 900,000-token request costs the same per-token rate as a 9,000-token one. For codebases that need to be understood holistically — monorepos, large migrations, anything where “ctrl-F across 200 files” is part of the problem — this is the single most consequential capability difference in 2026.
Agent teams went past experimental in 2026 with Claude Code v2.1.32 and the CLAUDE_CODE_EXPERIMENTAL_AGENT_TEAMS=1 flag. The team-lead pattern — one Claude session coordinating teammates who can message each other, share a task list with dependencies, and lock files — is a genuinely different primitive than Cursor’s background agents. The cost is real: agent teams use approximately 7x the tokens of a single session in plan mode. The benefit is also real: the work that previously needed a human program manager now runs unattended.
On full-feature implementation tasks — the kind where a benchmark measures end-to-end PR shipment, not single edits — Claude Code was roughly 18% faster on median wall-clock time. Opus 4.7 specifically lifted resolution on a 93-task coding benchmark by 13% over Opus 4.6, including four tasks that neither Opus 4.6 nor Sonnet 4.6 could solve.
Where Cursor Wins
Where Cursor wins. The editor. This is not a small thing. Cursor is still a VS Code fork that evolved into an agent workbench. The integrated diff view, the multi-file edit preview, the in-line ghost text completions, the model picker in the corner — none of that exists in Claude Code, which lives in a terminal pane. If you have a strong opinion about your IDE and you want AI features welded inside it, Cursor is the answer.
Cloud agents on Cursor Pro and above run AI tasks in isolated cloud VMs with no access to your local machine. The use case — fire off a refactor and walk away from your laptop — is well-served. The catch: background agents always use MAX mode, which adds a 20% surcharge on credit cost, and a single agent run on a 50,000-line codebase can consume around 22.5% of a Pro plan’s monthly credits. One bad day of agent runs eats your month.
Model variety is also a Cursor advantage. You can route a task to a non-Anthropic model when the situation calls for it. Claude Code is Claude all the way down.
What I Actually Run
Both. For $40/month at the Pro tier on each, I get the most powerful AI coding setup available in 2026. Claude Code handles the long-context architectural work, the cross-cutting refactors, the agent-team orchestration where one Claude is doing program management and three teammates are touching different services. Cursor handles the IDE work — the small-bore edits, the in-line completions, the moments where I want to see a diff hover above the line I just changed.
If forced to pick one, the answer depends on the work. Heavy backend, large codebases, multi-agent workflows: Claude Code. UI-heavy, single-file iteration, “I just want my editor to be smarter”: Cursor.
The Honest Limitation
Claude Code on a team plan is genuinely expensive at scale. A 10-person team running Claude Code at the team-equivalent tier is roughly 3x the Cursor Teams equivalent. If you’re cost-sensitive at headcount, that math may decide the question regardless of capability. The token-efficiency advantage helps Claude Code claw back some of that on per-task economics, but the subscription line item is the line item.
The other honest limitation: model versions move fast. As of May 26, 2026, the current Anthropic lineup is Claude Opus 4.7 (flagship), Claude Sonnet 4.6 (workhorse), and Claude Haiku 4.5. Any comparison written more than a quarter ago is already partially wrong on the model column. Read pricing pages, not blog posts, when you’re committing budget.
The Bottom Line
Cursor wins on editor experience, model variety, and team subscription cost. Claude Code wins on token efficiency, context window economics, agent-team primitives, and Opus 4.7’s raw coding capability on hard tasks. If you’re optimizing for one tool, pick the one that matches the bulk of your work. If you can afford $40/month, run both — and pay attention to which one you actually open first in the morning. That’s your real answer.
📖 Recommended Reading in Claude Code Insider