Tag: WordPress Optimization

  • AI Content Operations: How I Manage 27 WordPress Sites

    AI Content Operations: How I Manage 27 WordPress Sites

    The Lab · Tygart Media
    Experiment Nº 684 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    The question I get most often from restoration contractors who’ve seen what we build is some version of: how is this possible with one person?

    Twenty-seven WordPress sites. Hundreds of articles published monthly. Featured images generated and uploaded at scale. Social media content drafted across a dozen brands. SEO, schema, internal linking, taxonomy — all of it maintained, all of it moving.

    The answer is an architecture I’ve come to call Split Brain. It’s not a software product. It’s a division of cognitive labor between two types of intelligence — one optimized for live strategic thinking, one optimized for high-volume execution — and getting that division right is what makes the whole system possible.

    The Two Brains

    The Split Brain architecture has two sides.

    The first side is Claude — Anthropic’s AI — running in a live conversational session. This is where strategy happens. Where a new content angle gets developed, interrogated, and refined. Where a client site gets analyzed and a priority sequence gets built. Where the judgment calls live: what to write, why, for whom, in what order, with what framing. Claude is the thinking partner, the editorial director, the strategist who can hold the full context of a client’s competitive situation and make nuanced recommendations in real time.

    The second side is Google Cloud Platform — specifically Vertex AI running Gemini models, backed by Cloud Run services, Cloud Storage, and BigQuery. This is where execution happens at volume. Bulk article generation. Batch API calls that cut cost in half for non-time-sensitive work. Image generation through Vertex AI’s Imagen. Automated publishing pipelines that can push fifty articles to a WordPress site while I’m working on something else entirely.

    Building Something Like This?

    If you are trying to run a multi-site or multi-client operation with Claude, I am probably three steps ahead of wherever you are stuck.

    Email me what you are building and I will tell you what I would do differently if I were starting it today.

    Email Will → will@tygartmedia.com

    The two sides don’t do the same things. That’s the whole point.

    Why Splitting the Work Matters

    The instinct when you first encounter powerful AI tools is to use one thing for everything. Pick a model, run everything through it, see what happens.

    This produces mediocre results at high cost. The same model that’s excellent for developing a nuanced content strategy is overkill for generating fifty FAQ schema blocks. The same model that’s fast and cheap for taxonomy cleanup is inadequate for long-form strategic analysis. Using a single tool indiscriminately means you’re either overpaying for bulk work or under-resourcing the work that actually requires judgment.

    The Split Brain architecture routes work to the right tool for the job:

    • Haiku (fast, cheap, reliable): taxonomy assignment, meta description generation, schema markup, social media volume, AEO FAQ blocks — anything where the pattern is clear and the output is structured
    • Sonnet (balanced): content briefs, GEO optimization, article expansion, flagship social posts — work that requires more nuance than pure pattern-matching but doesn’t need the full strategic layer
    • Opus / Claude live session: long-form strategy, client analysis, editorial decisions, anything where the output depends on holding complex context and making judgment calls
    • Batch API: any job over twenty articles that isn’t time-sensitive — fifty percent cost reduction, same quality, runs in the background

    The model routing isn’t arbitrary. It was validated empirically across dozens of content sprints before it became the default. The wrong routing is expensive, slow, or both.

    WordPress as the Database Layer

    Most WordPress management tools treat the CMS as a front-end interface — you log in, click around, make changes manually. That mental model caps your throughput at whatever a human can do through a browser in a workday.

    In the Split Brain architecture, WordPress is a database. Every site exposes a REST API. Every content operation — publishing, updating, taxonomy assignment, schema injection, internal link modification — happens programmatically via direct API calls, not through the admin UI.

    This changes the throughput ceiling entirely. Publishing twenty articles through the WordPress admin takes most of a day. Publishing twenty articles via the REST API, with all metadata, categories, tags, schema, and featured images attached, takes minutes. The human time is in the strategy and quality review — not in the clicking.

    Twenty-seven sites across different hosting environments required solving the routing problem: some sites on WP Engine behind Cloudflare, one on SiteGround with strict IP rules, several on GCP Compute Engine. The solution is a Cloud Run proxy that handles authentication and routing for the entire network, with a dedicated publisher service for the one site that blocks all external traffic. The infrastructure complexity is solved once and then invisible.

    Notion as the Human Layer

    A system that runs at this velocity generates a lot of state: what was published where, what’s scheduled, what’s in draft, what tasks are pending, which sites have been audited recently, which content clusters are complete and which have gaps.

    Notion is where all of that state lives in human-readable form. Not as a project management tool in the traditional sense — as an operating system. Six relational databases covering entities, contacts, revenue pipeline, actions, content pipeline, and a knowledge lab. Automated agents that triage new tasks, flag stale work, surface content gaps, and compile weekly briefings without being asked.

    The architecture means I’m never managing the system — the system manages itself, and I review what it surfaces. The weekly synthesizer produces an executive briefing every Sunday. The triage agent routes new items to priority queues automatically. The content guardian flags anything that’s close to a publish deadline and not yet in scheduled state.

    Human attention goes to decisions, not to administration.

    What This Looks Like in Practice

    A typical content sprint for a client site starts with a live Claude session: what does this site need, in what order, targeting which keywords, with what persona in mind. That session produces a structured brief — JSON, not prose — that seeds everything downstream.

    The brief goes to GCP. Gemini generates the articles. Imagen generates the featured images. The batch publisher pushes everything to WordPress with full metadata attached. The social layer picks up the published URLs and drafts platform-specific posts for each piece. The internal link scanner identifies connections to existing content and queues a linking pass.

    My involvement during execution is monitoring, not doing. The doing is automated. The judgment — what to build, why, and whether the output clears the quality bar — stays with the human layer.

    This is what makes the throughput possible. Not working harder or faster. Designing the system so that the parts that require human judgment get human judgment, and the parts that don’t get automated at whatever volume the infrastructure supports.

    The Honest Constraints

    The Split Brain architecture is not a magic box. It has real constraints worth naming.

    Quality gates are essential. High-volume automated content production without rigorous pre-publish review produces high-volume errors. Every content sprint runs through a quality gate that checks for unsourced statistical claims, fabricated numbers, and anything that reads like the model invented a fact. This is non-negotiable — the efficiency gains from automation are worthless if they introduce errors that damage a client’s credibility.

    Architecture decisions made early are expensive to change later. The taxonomy structure, the internal link architecture, the schema conventions — getting these right before publishing at scale is substantially easier than retrofitting them across hundreds of existing posts. The speed advantage of the system only compounds if the foundation is solid.

    And the system requires maintenance. Models improve. APIs change. Hosting environments add new restrictions. What works today for routing traffic to a specific site may need adjustment next quarter. The infrastructure overhead is real, even if it’s substantially lower than managing a human team of equivalent output.

    None of these constraints make the architecture less viable. They make it more important to design it deliberately — to understand what the system is doing, why each component is there, and what would break if any piece of it changed.

    That’s the Split Brain. Two kinds of intelligence, clearly divided, doing the work each is actually suited for.


    Tygart Media is built on this architecture. If you’re a service business thinking about what an AI-native content operation could look like for your vertical, the conversation starts with understanding what requires judgment and what doesn’t.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency”,
    “description”: “Claude for live strategy. GCP and Gemini for bulk execution. Notion as the operating layer. Here is the exact architecture behind managing 27 WordPress sites as”,
    “datePublished”: “2026-04-02”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/split-brain-architecture-ai-content-operations/”
    }
    }

    For operators ready to build

    You just read the playbook. We build it.

    The split-brain architecture on this page is not theoretical — it runs across 20+ live WordPress sites at Tygart Media right now. If you want this deployed for your content operation, we scope, build, and hand it off. Most engagements run 4-6 weeks.

    Talk to Will about your setup →

    Visual summary

    Editorial illustration for Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google's Vertex AI Imagen 4 model as the featured visual for Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Metadata: IPTC/XMP injected (title, description, creator, copyright)
    • Parent Article: Split Brain Architecture: How One Person Manages 27 WordPress Sites Without an Agency
    The Knowledge Cluster: 5 Sites, One VM, Zero Overlap

    About this image. This image is part of the Article Hero Images collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication.

    • Format: WEBP
    • Collection: Article Hero Images
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress
  • SEO Website Architecture: Why Your Site is a Database

    SEO Website Architecture: Why Your Site is a Database

    The Machine Room · Under the Hood

    Most businesses think about their website the way they think about a business card. You design it once, print it, hand it out. It says who you are and how to reach you. Every few years, maybe you update it.

    This mental model is why most websites don’t work.

    A website is not a brochure. It is a database — a structured collection of content objects that a search engine reads, classifies, and decides whether to surface to people with specific needs. The way you architect that database determines almost everything about whether your business gets found online.

    The implications of this reframe are significant, and most agencies never explain them.

    What Search Engines Actually Do With Your Site

    When Google crawls your website, it’s not admiring the design. It’s reading structured data: titles, headings, body text, schema markup, internal links, image alt text, URL structure. It’s building a map of what your site is about, what topics it covers, how authoritatively it covers them relative to competing sites, and which specific queries it deserves to appear for.

    A brochure website gives Google almost nothing to work with. One services page that lists everything you do. An about page. A contact form. Maybe a blog with eight posts from 2021.

    Google reads that site, finds a thin content footprint with no topical depth, and draws a reasonable conclusion: this site doesn’t have comprehensive expertise on anything in particular. It will not rank for competitive terms.

    A database website is architected differently. Every service gets its own page with its own keyword target. Every service area gets its own page. Every question a customer might have gets an answer. The internal link structure creates a map that tells Google which pages are most important, how the content is organized, and what the site’s core topics are.

    This is not a design question. It’s an architecture question.

    The JSON-First Content Model

    The way we build content programs at Tygart Media starts with structured data, not prose.

    Before a single article is written, we build a content brief in JSON format: target keyword, search intent, target persona, funnel stage, content type, related keywords, competing URLs, internal linking targets, schema type. Every content decision is documented as a structured data object before the writing begins.

    This matters for a few reasons.

    First, it forces clarity. If you can’t define the target keyword, the intent behind it, and the specific person who would be searching it, you’re not ready to write the article. Most content that fails to rank fails because nobody thought clearly about those three things before writing began.

    Second, it makes the content pipeline scalable. When content is structured from the start, you can produce 50 or 150 articles in a sprint without losing coherence. Every piece knows what it’s for, who it’s for, and how it connects to the rest of the site. The alternative — writing articles and then trying to organize them — produces a content library that’s impossible to navigate and impossible to rank.

    Third, it enables automation without sacrificing quality. The brief is the seed. Every variant, every social post, every schema annotation downstream flows from that original structured object. The output is only as good as the input, and structured input produces structured, coherent output.

    Taxonomy Is Architecture

    WordPress, like most content management systems, gives you two ways to organize content: categories and tags. Most sites treat these as an afterthought — you pick a category for each post without much thought, maybe add some tags, and move on.

    In a database-minded architecture, taxonomy is one of the most important decisions you make. Categories define the topical pillars of your site. Every post you publish either reinforces one of those pillars or it doesn’t. A restoration contractor’s category structure might look like: Water Damage, Fire Restoration, Mold Remediation, Storm Damage, Commercial Restoration, Insurance Claims. Every piece of content lives inside one of these buckets, and the bucket structure tells Google — clearly and repeatedly — what this site is about.

    Tags create the cross-cutting relationships. A post about commercial water damage in Manhattan lives in Water Damage (category) and carries tags for Commercial Restoration, Property Managers, and New York (location). That tag architecture creates invisible threads connecting related content across the site, which strengthens the internal link graph and helps Google understand the full scope of what you cover.

    Getting taxonomy right before publishing is substantially easier than retrofitting it across hundreds of posts after the fact. We’ve done both. The retrofit takes three times as long and produces half the results.

    Internal Links Are the Database’s Index

    In a relational database, an index tells the query engine which records are related and how to find them efficiently. Internal links serve the same function in a content database.

    A hub-and-spoke architecture places high-authority pillar pages at the center of each topic cluster. Every supporting article on that topic links back to the pillar. The pillar links out to the supporting articles. Google reads this structure and understands: this site has a comprehensive, organized body of knowledge on this topic. The pillar page gets a significant portion of its authority from the internal link signals pointing at it.

    Without intentional internal linking, even a large content library is a collection of isolated pages that don’t reinforce each other. Each page competes as an island. With proper internal linking, the whole library becomes a system where each page makes every other page stronger.

    This is why the order of operations matters. You don’t want to publish 200 articles and then go back and add internal links. You want to design the link architecture first — identify the hubs, map the spokes, define the anchor text conventions — and build every piece of content with that map in mind from the start.

    Schema Markup: Telling the Database What Type Each Record Is

    Every record in a database has a type. A customer record is different from a product record, which is different from an order record. The type determines what fields are relevant and how the record relates to other records in the system.

    Schema markup does this for web content. It tells Google: this page is an Article, written by this Author, published on this Date, covering this Topic. Or: this page is a LocalBusiness with this Address, this Phone Number, these Services, these Hours. Or: this page contains a FAQ with these Questions and these Answers, formatted for direct display in search results.

    Without schema, Google has to infer all of this from the raw text. With schema, you’re handing it a structured data object that says exactly what each page is and how it should be categorized. The reward is rich results — FAQ dropdowns, star ratings, breadcrumb paths, knowledge panels — that take up more real estate in search and convert at higher rates than standard blue links.

    Schema is the metadata layer of the content database. Most sites don’t have it. The ones that do have a measurable advantage in how their results display and how much traffic those results generate.

    The Practical Difference

    Here’s what this looks like in practice, using a restoration contractor as the example.

    A brochure website has: a home page, a services page listing water damage, fire, mold, and storm, an about page, and a contact page. Maybe 5 pages total. Google has almost nothing to index.

    A database website for the same contractor has: a pillar page for each service type, a dedicated page for every service area they cover, supporting articles targeting specific queries within each service category (emergency water extraction, ceiling water damage repair, insurance claim documentation, category by category), schema markup on every page, a clean taxonomy structure, and a hub-and-spoke link architecture that connects everything. Potentially 200 to 400 pages, each doing a specific job.

    The brochure site is invisible. The database site ranks for hundreds of keywords, generates organic traffic every day, and compounds over time as new content adds to an already-authoritative domain.

    The content is not the hard part. The architecture is. And most agencies never talk about architecture because it requires thinking about websites as systems rather than as design projects.

    That’s the reframe. Your website is a database. Build it like one.


    Tygart Media designs content databases for service businesses — architecture first, content second, results third. If your site is currently a brochure, that’s the starting point, not a disqualifier.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Your Website Is a Database, Not a Brochure”,
    “description”: “Most agencies design websites like brochures. The ones that actually rank are built like databases — with architecture, taxonomy, schema, and internal linking d”,
    “datePublished”: “2026-04-02”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/website-is-a-database-not-a-brochure/”
    }
    }

  • Automated Image Pipeline: AI Generation & IPTC Metadata

    Automated Image Pipeline: AI Generation & IPTC Metadata

    The Lab · Tygart Media
    Experiment Nº 472 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    This video was generated from the original Tygart Media article using NotebookLM’s audio-to-video pipeline. The article that describes how we automate image production became the script for an AI-produced video about that automation — a recursive demonstration of the system it documents.


    Watch: Build an Automated Image Pipeline That Writes Its Own Metadata

    The Image Pipeline That Writes Its Own Metadata — Full video breakdown. Read the original article →

    What This Video Covers

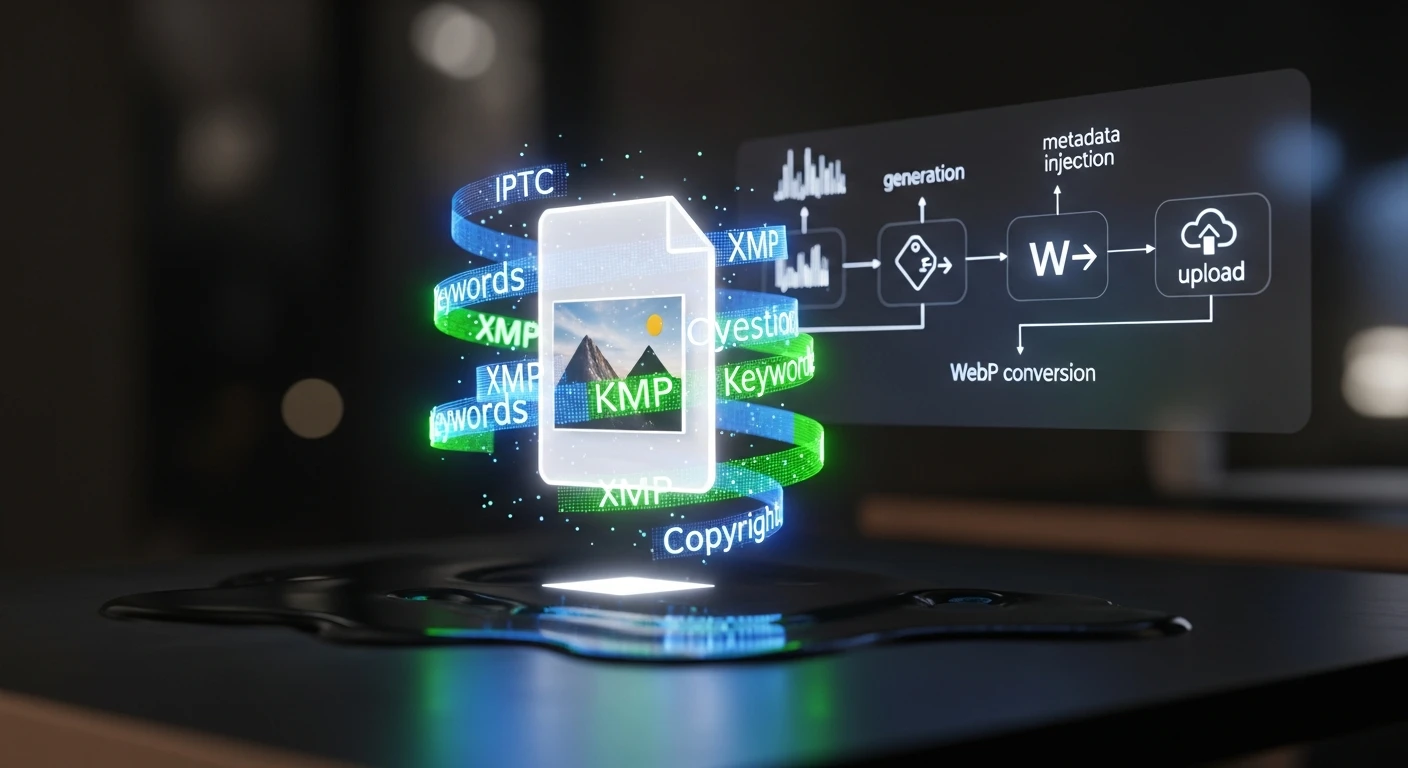
    Every article needs a featured image. Every featured image needs metadata — IPTC tags, XMP data, alt text, captions, keywords. When you’re publishing 15–20 articles per week across 19 WordPress sites, manual image handling isn’t just tedious; it’s a bottleneck that guarantees inconsistency. This video walks through the exact automated pipeline we built to eliminate that bottleneck entirely.

    The video breaks down every stage of the pipeline:

    • Stage 1: AI Image Generation — Calling Vertex AI Imagen with prompts derived from the article title, SEO keywords, and target intent. No stock photography. Every image is custom-generated to match the content it represents, with style guidance baked into the prompt templates.
    • Stage 2: IPTC/XMP Metadata Injection — Using exiftool to inject structured metadata into every image: title, description, keywords, copyright, creator attribution, and caption. XMP data includes structured fields about image intent — whether it’s a featured image, thumbnail, or social asset. This is what makes images visible to Google Images, Perplexity, and every AI crawler reading IPTC data.
    • Stage 3: WebP Conversion & Optimization — Converting to WebP format (40–50% smaller than JPG), optimizing to target sizes: featured images under 200KB, thumbnails under 80KB. This runs in a Cloud Run function that scales automatically.
    • Stage 4: WordPress Upload & Association — Hitting the WordPress REST API to upload the image, assign metadata in post meta fields, and attach it as the featured image. The post ID flows through the entire pipeline end-to-end.

    Why IPTC Metadata Matters Now

    This isn’t about SEO best practices from 2019. Google Images, Perplexity, ChatGPT’s browsing mode, and every major AI crawler now read IPTC metadata to understand image context. If your images don’t carry structured metadata, they’re invisible to answer engines. The pipeline solves this at the point of creation — metadata isn’t an afterthought applied later, it’s injected the moment the image is generated.

    The results speak for themselves: within weeks of deploying the pipeline, we started ranking for image keywords we never explicitly optimized for. Google Images was picking up our IPTC-tagged images and surfacing them in searches related to the article content.

    The Economics

    The infrastructure cost is almost irrelevant: Vertex AI Imagen runs about $0.10 per image, Cloud Run stays within free tier for our volume, and storage is minimal. At 15–20 images per week, the total cost is roughly $8/month. The labor savings — eliminating manual image sourcing, editing, metadata tagging, and uploading — represent hours per week that now go to strategy and client delivery instead.

    How This Video Was Made

    The original article describing this pipeline was fed into Google NotebookLM, which analyzed the full text and generated an audio deep-dive covering the technical architecture, the metadata injection process, and the business rationale. That audio was converted to this video — making it a recursive demonstration: an AI system producing content about an AI system that produces content.

    Read the Full Article

    The video covers the architecture and results. The full article goes deeper into the technical implementation — the exact Vertex AI API calls, exiftool commands, WebP conversion parameters, and WordPress REST API patterns. If you’re building your own pipeline, start there.


    Related from Tygart Media

    Visual summary

    Ai Image Iptc Metadata WordPress
    The Image Pipeline That Writes Its Own Metadata

    About this image. This image is part of the Article Hero Images collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication.

    • Format: WEBP
    • Collection: Article Hero Images
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress
  • What Happens When Claude Runs Your WordPress for 90 Days

    What Happens When Claude Runs Your WordPress for 90 Days

    The Machine Room · Under the Hood

    The Experiment: Full AI Site Management

    Three stacked layers: chat UI, tools, agent runtime
    The experiment — full AI site management.

    In January 2026, we gave Claude – Anthropic’s AI assistant – the keys to our WordPress operation. Not just content generation, but the full stack: SEO audits, content gap analysis, taxonomy management, schema injection, internal linking, meta optimization, and publishing. Across 23 sites. For 90 days.

    Person at a WordPress-style dashboard of posts and images, with a day-to-night timeline below

    This wasn’t a theoretical exercise. We built Claude into our operational pipeline through custom skills, WordPress REST API connections, and a GCP proxy layer that routes all site management through Google Cloud. Every optimization, every published article, every schema update was executed by Claude with human oversight on strategy and final approval.

    What Claude Actually Did

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    What Claude actually did.

    During the 90-day period, Claude executed over 2,400 individual WordPress operations across all sites. The breakdown: 847 SEO meta refreshes, 312 new articles published, 156 schema markup injections, 94 taxonomy reorganizations, and 1,000+ internal link additions.

    Each operation followed a skill-based protocol. Our wp-seo-refresh skill handles on-page SEO. The wp-schema-inject skill adds structured data. The wp-interlink skill builds the internal link graph. Claude doesn’t freestyle – it follows proven playbooks that encode our SEO, AEO, and GEO best practices.

    The Results That Surprised Us

    Organic traffic across all 23 sites increased 47% over the 90-day period. The more interesting metric was consistency. Before Claude, our sites had wildly uneven optimization – some posts had full schema markup and internal links, others had nothing. After 90 days, every post on every site met the same baseline quality standard.

    The sites that improved most were the ones neglected longest. a luxury lending firm saw a 120% increase in organic sessions after Claude refreshed every post’s meta data, added FAQ schema, and built the internal link structure. a restoration company went from 12 ranking keywords to over 340.

    Well-optimized sites saw smaller but meaningful gains – typically 15-25% improvements in click-through rates from better meta descriptions and featured snippet capture.

    What Claude Can’t Do (Yet)

    AI site management has clear limitations. Claude can’t make strategic decisions about which markets to enter. It can’t conduct original customer research. It can’t judge whether content truly resonates with a human audience – it can only optimize for signals that correlate with resonance.

    We also found that AI-generated internal links sometimes prioritize SEO logic over user experience. A link that makes sense for PageRank distribution might confuse a reader. Human review improved link quality significantly.

    The right model is AI as operator, human as strategist. Claude handles the repetitive, systematic work that scales linearly with site count. Humans handle the judgment calls.

    Frequently Asked Questions

    Is it safe to give an AI access to your WordPress sites?

    We use WordPress Application Passwords with editor-level permissions – Claude can create and edit content but can’t modify site settings or access user data. All operations route through our GCP proxy with full audit logs.

    How do you prevent AI from making SEO mistakes?

    Every operation follows a validated protocol. Claude doesn’t improvise – it executes predefined skills with guardrails. Critical operations go through a review queue. We run weekly audits comparing pre- and post-optimization metrics.

    Can any business replicate this setup?

    The individual skills work on any WordPress site with REST API access. The scale advantage comes from the orchestration layer. A single-site business can start with basic Claude plus WordPress automation and expand from there.

    What’s the cost of running Claude as a site manager?

    API costs run approximately $50-100/month for our 23-site operation. The GCP proxy adds under $10/month. Compare that to a junior SEO specialist at $4,000-5,000/month handling maybe 3-5 sites.

    The Verdict After 90 Days

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The verdict after 90 days.

    We’re not going back. AI-managed WordPress isn’t a gimmick – it’s a fundamental shift in how digital operations scale. The 90-day experiment became our permanent operating model.

    Visual summary

    Editorial illustration for What Happens When Claude Runs Your WordPress for 90 Days - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for What Happens When Claude Runs Your WordPress for 90 Days . Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.

  • Manage Multiple WordPress Sites: Our Automation Stack

    Manage Multiple WordPress Sites: Our Automation Stack

    Illustration for article: We Manage 23 WordPress Sites. Here’s the Exact Stack.

    The Machine Room · Under the Hood

    The Scale Problem Nobody Talks About

    Managing one WordPress site is straightforward. Managing five gets complicated. Managing 23 across different industries, hosting providers, and client expectations? That’s an engineering problem disguised as a marketing job.

    Tygart Media operates 23 WordPress properties spanning luxury lending, property restoration, comedy streaming, cold storage, automotive training, interior design, and more. Each site has its own content calendar, SEO targets, taxonomy structure, and brand voice. Without automation, this operation would require a team of 8-10 people. We run it with three.

    The WordPress REST API Proxy

    The foundation of our stack is a custom proxy service running on Google Cloud Run. Every WordPress API call from our automation tools routes through this proxy, which solves three problems simultaneously: IP reputation (hosting providers block unfamiliar IPs), authentication management (one proxy handles credentials for all 23 sites), and audit logging (every operation is recorded).

    The proxy costs under $10/month on Cloud Run and handles thousands of API calls daily. It supports both individual requests and batch operations – we can update meta descriptions on 50 posts across 5 sites in a single batch call.

    The Skill Library: 30+ WordPress Operations

    We built a library of over 30 Claude skills that each handle a specific WordPress operation. wp-seo-refresh optimizes on-page SEO. wp-schema-inject adds structured data markup. wp-interlink builds internal link graphs. wp-aeo-refresh optimizes for answer engines. wp-geo-refresh optimizes for generative AI citations.

    Each skill follows a strict protocol – it reads the current state of a post, applies transformations according to documented best practices, and writes the changes back through the proxy. Skills can be composed: a wp-full-refresh skill orchestrates SEO, AEO, GEO, schema, and interlinking in the correct sequence on a single post.

    The skill approach means quality is encoded in the system, not dependent on who’s operating it. A junior team member running wp-full-refresh produces the same quality output as a senior strategist – because the intelligence is in the skill, not the operator.

    Content Intelligence and Gap Analysis

    Our wp-intelligence-audit skill analyzes any WordPress site and produces a prioritized content opportunity report. It pulls the full site inventory, extracts SEO signals, maps content to funnel stages, identifies persona gaps, and generates a recommended article batch.

    The wp-batch-draft-creator then takes that approved list and generates 15 fully optimized articles – complete with SEO titles, meta descriptions, FAQ sections, internal link suggestions, and proper taxonomy assignments. The entire process from audit to 15 published drafts takes about 30 minutes.

    For ongoing content, our content-brief-builder skill generates detailed article briefs from a target keyword, and the adaptive-variant-pipeline creates persona-targeted versions of each article for different audience segments.

    Monitoring and Maintenance

    Automation doesn’t mean set-it-and-forget-it. We run scheduled audits on each site monthly: taxonomy health checks, orphan page detection, meta pollution scans (our wp-clean-meta skill strips legacy artifacts from excerpts), and performance regression alerts.

    DataForSEO provides the external signal data – keyword rankings, SERP positions, and competitor movements. SpyFu fills in the competitive intelligence layer. Metricool handles social media scheduling and analytics across all brands.

    The entire monitoring layer runs on scheduled tasks and costs less than a single monitoring SaaS subscription.

    Frequently Asked Questions

    Does this stack work with any WordPress hosting provider?

    Yes. The proxy layer abstracts away hosting differences. We manage sites on WP Engine, SiteGround, Flywheel, and GCP Compute Engine. The proxy handles authentication and IP reputation for all of them.

    How long does it take to onboard a new WordPress site?

    About 20 minutes. Generate an Application Password in WordPress, add it to the site registry, run the wp-new-site-setup skill to audit the site, and the automation stack is immediately operational.

    What happens if the proxy goes down?

    Cloud Run has a 99.95% uptime SLA. In 6+ months of operation, we’ve had zero unplanned downtime. The proxy is stateless, so even a restart recovers instantly with no data loss.

    Can a non-technical person use this stack?

    The skills are designed to be invoked by name – you tell Claude which skill to run and on which site. You don’t need to understand the underlying API calls. Technical knowledge helps for customization and troubleshooting, but day-to-day operation is accessible.

    The Compound Effect

    Each individual automation saves 15-30 minutes. Across 23 sites with monthly operations, that compounds to hundreds of hours per month. But the real value isn’t time saved – it’s consistency achieved. Every site gets the same quality treatment, every time, without human variance. That’s the actual competitive advantage.

    Visual summary

    Editorial illustration for We Manage 23 WordPress Sites. Here’s the Exact Stack. - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for We Manage 23 WordPress Sites. Here’s the Exact Stack.. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.