Tag: SEO Strategy

  • Local SEO for Restoration Companies: Beat Aggregators

    Local SEO for Restoration Companies: Beat Aggregators

    Tygart Media — Restoration Content Strategy

    Local SEO for Restoration Companies: The Content Strategy That Beats the Big Aggregators

    By Tygart Media Updated: April 12, 2026
    The aggregator problem: HomeAdvisor, Angi, Thumbtack, and Yelp dominate generic restoration searches — “water damage restoration near me,” “restoration company [city].” These platforms have domain authority that independent contractors cannot match on generic terms. The content strategy that beats them is the same one that beats Zillow in real estate: hyper-local content that aggregators cannot replicate because they don’t know your market the way you do.

    Why Aggregators Can’t Own the Local Queries That Convert Best

    Comparison of Claude how-to fit versus local service page fit for assistants
    Why aggregators can’t own the local queries that convert best.

    Aggregator platforms rank for generic, high-volume terms. They cannot rank for hyper-local, service-specific queries that require genuine local knowledge. “Water damage restoration companies near me” — HomeAdvisor wins that. “What to do if my basement floods in [specific neighborhood]” or “sewage backup cleanup contractor [specific zip code]” — these are queries where a local contractor’s content can win, and they convert at higher rates because they’re more specific.

    The restoration companies that build topical authority through hyper-local content — neighborhood-specific service area pages, local weather and flood risk content, municipality-specific permit and code content — create a content moat that aggregators cannot replicate because they lack the local knowledge to write it convincingly.

    How can restoration companies compete with HomeAdvisor and Angi in local search? Restoration companies compete with HomeAdvisor and Angi by targeting hyper-local queries that aggregators cannot rank for: neighborhood-specific service content (“basement flood cleanup in [neighborhood name]”), municipality-specific permit and code references for restoration work, local weather and infrastructure risk content (“why [city] homes are susceptible to sump pump failure”), and service-specific long-tail queries with local modifiers. Aggregators dominate generic terms; local contractors own hyper-local and process-specific queries that require genuine market knowledge.

    Three Content Types That Beat Aggregators Consistently
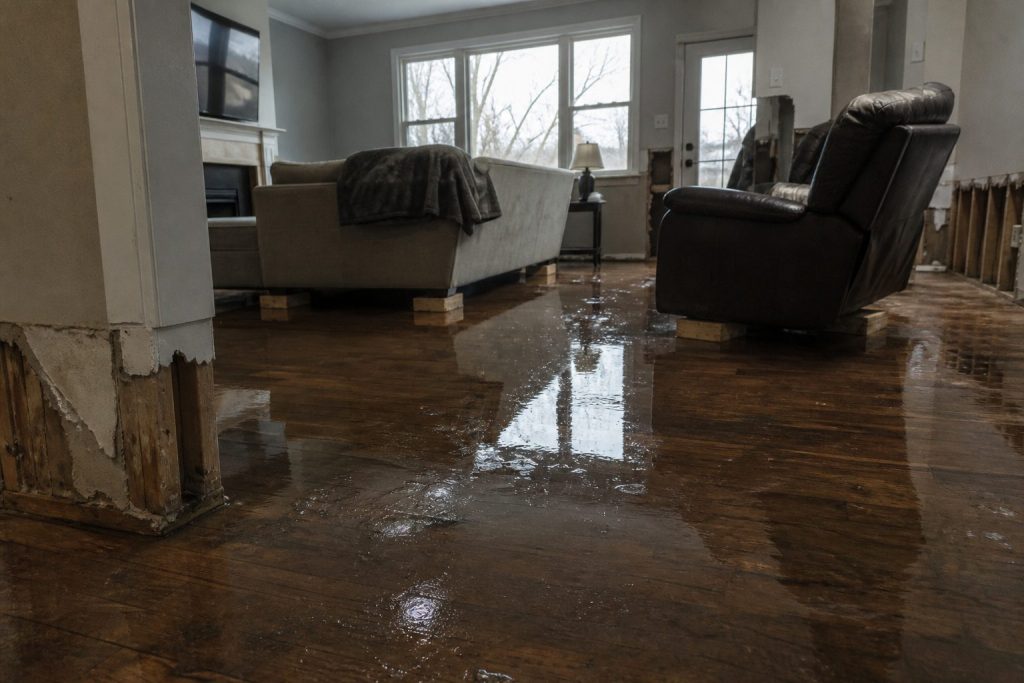
    Flooded residential living room with standing water on hardwood after a water loss
    Three content types that beat aggregators consistently.

    1. Neighborhood-Specific Service Content

    A dedicated article or page for each primary service area neighborhood — not just a city — with specific local references: the age and construction type of housing stock in that area (older homes with clay tile sewer laterals vs newer homes with PVC), common water damage causes specific to the geography (proximity to a flood plain, sump pump dependency in areas with high water tables), and local infrastructure that affects restoration timelines (permit requirements for drywall removal, local inspection protocols). HomeAdvisor has a landing page for your city. You can have a genuinely informative article for every neighborhood you serve.

    2. Local Risk and Prevention Content

    Weather events, aging infrastructure, and local building characteristics create specific restoration risk patterns that vary by market. An article titled “Why [City] Homes Get Basement Flooding After Spring Rain” — referencing local topography, the combined sewer system that causes backup events in specific zip codes, and the age of housing stock in affected neighborhoods — is content that only a contractor who actually works that market can write authoritatively. This is E-E-A-T through genuine local experience, and it’s exactly what AI systems recognize as locally authoritative content.

    3. Process Content With Local Code References

    Restoration permit requirements, local inspection protocols, and municipality-specific code provisions vary by jurisdiction. An article explaining “Do You Need a Permit for Water Damage Restoration in [City]?” — with the actual answer for your market, the permit threshold (square footage of drywall removal, extent of structural work), and the typical inspection timeline — is content that serves homeowners, builds local authority, and is completely outside what a national aggregator can provide.

    The Entity Set for Local Restoration Authority

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The entity set for local restoration authority.

    Beyond IICRC and RIA, local restoration authority requires geographic entity injection: named neighborhoods and service area communities, local watershed and drainage authority references where applicable, municipality names, specific local weather events that create restoration demand, and named local building code authorities. These geographic entities are the signals Google and AI systems use to determine whether a restoration contractor truly serves and understands a local market versus claiming a service area on a directory profile.

    Geographic entity injection and local content structuring are part of the GEO layer in WordPress content optimization for restoration companies through SiteBoost — applied to your existing service area and neighborhood content to build the local topical authority that aggregators can’t match.

    Related on Tygart Media: blog SEO · Twin Cities water damage SEO · property damage SEO.

    Frequently Asked Questions

    How many service area pages should a restoration company have?

    A dedicated page for each primary service city or neighborhood you actively serve and have genuine local knowledge about. The quality standard is: could you write 300+ words of genuinely specific, locally-relevant content about restoration work in this area? If yes, the page is worth creating. Generic “We serve [city]” pages with no local-specific content do not build topical authority and may actually dilute your overall site quality signals. Depth per location beats breadth of thin location pages.

    What local entities matter most for restoration company SEO?

    Named neighborhoods and communities within your service area, local watershed and drainage authority names (relevant for flood and backup content), municipality names paired with specific services, local housing stock characteristics (age, construction type, common infrastructure issues), and references to local weather patterns or infrastructure events that create restoration demand. Geographic specificity — naming specific streets, neighborhoods, or local landmarks — is the entity signal that separates genuine local expertise from claimed service area coverage.

    How does local content help restoration companies compete in AI search?

    AI systems evaluating restoration content for hyper-local queries — “basement flood cleanup [neighborhood]” or “sewage backup contractor [zip code]” — favor content with genuine geographic entity depth over generic service descriptions. A restoration company article that references specific local geography, housing stock characteristics, and infrastructure context is treated as locally authoritative by AI systems in a way that a national aggregator’s generic city page cannot match. Local entity injection is both a Google local SEO signal and an AI citation signal for geographically-specific restoration queries.
    Sources: Aziel Digital, “Water Damage SEO Secrets: How Restoration Companies Rank #1” (2026); Blueprint Digital, “Water Damage Restoration SEO” (2026); Whitespark Local Search Ranking Factors (2025); The RMG, “Local SEO for Restoration Companies” (2025)
  • Restoration SEO: Boost Rankings With IICRC Certification

    Restoration SEO: Boost Rankings With IICRC Certification

    Tygart Media — Restoration Content Strategy

    How IICRC Certification Signals Rank Your Restoration Company Higher (And Get You Cited by AI)

    By Tygart Media Updated: April 12, 2026
    IICRC as an SEO entity: The Institute of Inspection, Cleaning and Restoration Certification (IICRC) is the named credentialing body that Google’s quality evaluators and AI systems use to evaluate restoration content authority. An article that mentions “IICRC-certified technicians” once is a marketing claim. An article that references the specific IICRC S500 Standard for Professional Water Damage Restoration, the Applied Structural Drying (ASD) technician designation, and the Restoration Industry Association (RIA) as co-publisher of industry standards — that article has entity depth that signals genuine industry expertise.

    Why Certification Names in Content Matter More Than Logos

    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    Why certification names in content matter more than logos.

    Most restoration company websites display IICRC logos — in the footer, on the About page, on the homepage trust bar. This helps with human visitor credibility but contributes almost nothing to search or AI visibility. Logos are images. Google’s text-based quality evaluators and AI retrieval systems read the text content of pages, not the images on them.

    The SEO and AI citation value of IICRC certification comes from naming the credentials, standards, and certifying body in the text content of your articles and service pages. Specifically:

    • IICRC S500 — Standard for Professional Water Damage Restoration
    • IICRC S520 — Standard for Professional Mold Remediation
    • IICRC S770 — Standard for Professional Water Damage Restoration of Sewage Impacted Structures
    • ASD — Applied Structural Drying technician designation
    • WRT — Water Damage Restoration Technician certification
    • AMRT — Applied Microbial Remediation Technician
    • RIA — Restoration Industry Association (co-publisher of IICRC standards)
    How does IICRC certification improve restoration company SEO and AI citation? IICRC certification improves restoration company SEO when specific IICRC standards — S500 for water damage, S520 for mold, S770 for sewage — are named in article text content rather than just displayed as logos. These named entities signal genuine restoration industry expertise to Google’s E-E-A-T quality evaluators and AI systems like ChatGPT and Perplexity, which evaluate whether restoration content represents real industry knowledge before citing it in answers about water damage, mold, or property restoration.

    Implementing IICRC Entities in Three Content Types

    Gloved hands using a pin-type moisture meter on wet drywall during inspection
    Implementing IICRC entities in three content types.

    Water Damage Articles

    Every water damage article should reference the IICRC S500 standard and explain that professional water damage restoration follows its protocols — including moisture mapping, equipment placement based on psychrometric calculations, and documentation of drying progress. An article that explains Category 1 (clean water), Category 2 (grey water), and Category 3 (black water) contamination levels using IICRC S500 terminology signals expertise that generic homeowner advice does not.

    Mold Remediation Articles

    Mold content should reference the IICRC S520 standard, AMRT technician certification, and EPA mold remediation guidelines as named entities. The distinction between mold remediation (reducing mold to a normal fungal ecology per S520) and mold removal (a marketing term without a defined standard) is the kind of specific, standard-referenced distinction that earns Google quality evaluator trust for YMYL property damage content.

    Insurance Claim Content

    Insurance-related restoration content should reference IICRC standards as the basis for scope of work documentation — specifically that IICRC S500-compliant documentation (moisture readings, equipment logs, drying reports) is what adjusters require to approve claims. This entity connection between IICRC standards and insurance claim approval is highly specific and AI-citation-worthy because it answers a high-intent homeowner question with verifiable, standard-referenced information.

    IICRC entity injection is part of the GEO optimization layer in WordPress content optimization for restoration companies through SiteBoost — applied to your existing water damage, mold, and insurance content without changing any factual claims.

    Related on Tygart Media: restoration blog SEO · S500 in the van · local SEO.

    Frequently Asked Questions

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Frequently asked questions.
    What IICRC standards should restoration content reference?

    The most SEO-valuable IICRC standard references for restoration content are: S500 (Professional Water Damage Restoration — the foundational water damage standard), S520 (Professional Mold Remediation), S770 (Water Damage Restoration of Sewage Impacted Structures), and IICRC technician designations including WRT (Water Damage Restoration Technician), ASD (Applied Structural Drying), and AMRT (Applied Microbial Remediation Technician). Referencing specific standards by number and full name — not just “IICRC standards” generically — creates the named entity anchors that signal genuine expertise.

    Is RIA membership also an SEO entity signal?

    Yes. The Restoration Industry Association (RIA) co-publishes IICRC standards and is the primary trade association for the restoration industry. Referencing RIA membership, RIA industry statistics, or RIA educational programs in restoration content adds a second named industry entity alongside IICRC — which strengthens the entity cluster signaling genuine restoration industry standing. For content about insurance claims, referencing RIA’s advocacy work with insurance industry on claim documentation standards is specifically relevant and AI-citation-worthy.

    Do IICRC entity references help with both Google rankings and AI citation?

    Yes, through the same mechanism. Google’s quality evaluators assess restoration content for expertise signals — specific named standards and certifications are the clearest indicators that content reflects genuine professional knowledge. AI systems like ChatGPT and Perplexity use similar evaluation criteria when deciding which restoration content to cite in answers. Named IICRC standard references make content machine-verifiable — the AI can cross-reference the entity against known certification data — which increases citation probability for both Google AI Overviews and standalone AI assistants.

    Sources: IICRC S500 Standard for Professional Water Damage Restoration (5th ed.); IICRC S520 Standard for Professional Mold Remediation; Restoration Industry Association (RIA), restorationindustry.org; Aziel Digital, “Water Damage SEO Secrets” (2026); Peterson SEO Consulting, “Water Damage SEO for Restoration Contractors” (2025)
  • Restoration Company Blog SEO: Why Posts Fail to Get Calls

    Restoration Company Blog SEO: Why Posts Fail to Get Calls

    Tygart Media — Restoration Content Strategy

    Why Restoration Company Blog Posts Don’t Generate Calls (And What to Fix)

    By Tygart Media Updated: April 12, 2026
    The restoration blog problem: A homeowner discovers water damage at 11pm. They search “what to do after a pipe burst” or “how fast does mold grow after water damage.” If your blog article exists but has no meta description, no FAQ schema, and no IICRC entity references, Google has no reason to surface it — and neither does ChatGPT. The article exists. It just never gets found.

    Restoration Searches Are Emergency Searches — Optimization Has to Match

    Flooded residential living room with standing water on hardwood after a water loss
    Restoration searches are emergency searches — optimization has to match.

    Water damage restoration is one of the few industries where the customer’s timeline is minutes, not days. According to Blueprint Digital’s 2026 water damage SEO analysis, high-intent searches like “water damage repair near me” or “emergency water extraction” often convert to calls within minutes of the search. That urgency creates a specific content requirement: the article needs to appear, answer the question directly, and provide a clear next step — all before the homeowner finds a competitor.

    Most restoration company WordPress blogs fail at all three. The posts exist but don’t appear because they lack optimization. They don’t answer questions directly because they were written as general service descriptions. And they don’t provide a clear next step because the CTA was an afterthought.

    Why don’t restoration company blog posts rank despite regular publishing? Restoration company blog posts fail to rank when they lack the optimization signals Google uses for emergency local content: a title tag that matches the homeowner’s actual search query (“what to do after a pipe bursts” not “our water damage services”), a written meta description with a direct action signal, FAQPage schema targeting the questions homeowners ask during a water damage crisis, and IICRC certification and RIA membership entity references that signal industry authority. Without these signals, the article competes for positions it has no basis to win.

    The Four Fixes — In Order of Impact

    Comparison of Claude how-to fit versus local service page fit for assistants
    The four fixes — in order of impact.

    1. Rewrite Titles for Emergency Intent

    Restoration content titles almost universally describe the company’s service rather than matching the homeowner’s search query. “Our Water Damage Restoration Process” describes your operation. “What to Do Immediately After Water Damage (First 24 Hours)” matches a homeowner searching in a crisis. Emergency intent keywords — “immediately,” “fast,” “what to do,” “how long,” “is it safe” — are the search triggers that precede a call. The title needs to capture those triggers first.

    2. Add IICRC and RIA Entity References

    Google’s quality evaluators assess restoration content for named industry credentials. An article about water damage that references “IICRC S500 Standard for Professional Water Damage Restoration,” mentions the “Restoration Industry Association (RIA)” as the industry body, and cites “ANSI/IICRC S520 Standard for Professional Mold Remediation” signals genuine restoration expertise. These named entities are also what AI systems use to determine whether a restoration article represents real industry knowledge or generic homeowner advice.

    3. Add FAQ Schema Targeting the Crisis Questions

    Restoration homeowners ask very specific questions during a crisis: “How long before water damage causes mold?”, “Will insurance cover my water damage?”, “How long does water damage restoration take?”, “Is my house safe after water damage?” A FAQ section with direct answers to these questions, combined with FAQPage JSON-LD schema, positions your article for People Also Ask placements — which appear above organic results for these exact emergency queries.

    4. Add a 24/7 Emergency CTA in the Article Body

    Blog posts that generate calls have a visible, urgent CTA embedded in the article body — not just in the footer. “Water damage worsens every hour. Call [number] for 24/7 emergency response.” This CTA converts the reader who found your article at 2am and is ready to call right now — not the reader who completes the article, navigates to your contact page, and calls during business hours.

    All four fixes — emergency-intent title rewrites, IICRC entity injection, FAQPage schema, and CTA optimization — are part of WordPress content optimization for restoration companies through SiteBoost. Applied to your existing article library, pushed live via WordPress REST API.

    Related on Tygart Media: IICRC certification SEO · local SEO for restoration · AI search for restoration.

    Frequently Asked Questions

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Frequently asked questions.
    What restoration keywords actually drive calls, not just traffic?

    Emergency-intent keywords drive calls: “water damage repair near me,” “emergency water extraction,” “flooded basement cleanup,” “burst pipe water damage,” “sewage backup cleanup.” These phrases signal active crisis — someone searching them is ready to call within minutes. Research keywords like “how long does water damage restoration take” drive lower-urgency traffic but build trust during the insurance claim research phase. Both matter, but emergency keywords should be prioritized on service pages and emergency CTAs.

    Should restoration companies blog about prevention or restoration?

    Both, but for different funnel stages. Prevention content (“how to prevent pipes from freezing,” “signs of hidden water damage”) attracts homeowners before a crisis and builds brand awareness. Restoration content (“what to do after a pipe bursts,” “how long does mold take to grow after water damage”) captures homeowners in an active crisis — the highest-converting traffic. Prioritize restoration process and crisis content first, then build prevention content as a secondary funnel.

    How does IICRC certification help restoration company SEO?

    IICRC certification signals credibility to both Google’s quality evaluators and homeowners evaluating contractors. In content, referencing specific IICRC standards — S500 for water damage, S520 for mold, S770 for sewage — by name creates named entity anchors that Google associates with genuine restoration industry expertise. This entity signal is also what AI systems like ChatGPT use when evaluating whether a restoration article represents real industry knowledge worth citing.

    Sources: Blueprint Digital, “Water Damage SEO: How to Rank Higher and Win More Local Jobs” (2026); Aziel Digital, “Water Damage SEO Secrets: How Restoration Companies Rank #1” (2026); Peterson SEO Consulting, “Water Damage SEO for Restoration Contractors” (2025); IICRC S500 Standard for Professional Water Damage Restoration
  • Law Firm WordPress Optimization: 8-Step SEO Checklist

    Law Firm WordPress Optimization: 8-Step SEO Checklist

    Tygart Media — Law Firm Content Strategy

    Law Firm WordPress Optimization: The Post-Publish Checklist Every Attorney Blog Needs

    By Tygart Media Updated: April 12, 2026
    The post-publish gap: Most law firm blog content goes through one optimization pass at the time of writing — keyword research, a readable draft, publication. The optimization steps that determine long-term ranking performance, PAA placement eligibility, and AI citation probability almost all happen after publication. This checklist covers the 8 post-publish steps that the majority of law firm WordPress blogs skip entirely.
    What is post-publish WordPress optimization for law firm blogs? Post-publish WordPress optimization for law firm blogs is the process of applying SEO, AEO, and GEO improvements to a blog post after it has been published — updating the title tag for search intent, writing a meta description, adding a FAQ section with FAQPage JSON-LD schema, injecting named legal entity references, adding a visible Last Updated date and dateModified schema, and ensuring internal links connect the article to relevant practice area pages. These steps determine whether a published post ranks, earns People Also Ask placements, and gets cited by AI systems.

    The 8-Step Post-Publish Optimization Checklist

    • 1
      Rewrite the title tag for search intent The published title is often the article headline — which may not match how a prospective client searches. Rewrite it to lead with the primary keyword in the first 3 words and stay within 50–60 characters. “What Is the Statute of Limitations for Personal Injury in Texas?” outperforms “Understanding Personal Injury Time Limits.”
    • 2
      Write a meta description from scratch Delete the auto-generated excerpt. Write a 140–155 character meta description that includes the primary keyword, states a clear value, and ends with an action signal. This is the copy that determines click-through rate from search results.
    • 3
      Add a FAQ section with 6–8 questions Add a visible FAQ section at the bottom of the post with questions written in client language — the actual queries a prospective client would type or ask an AI assistant. Each answer should be 40–60 words, direct, and specific to jurisdiction where applicable.
    • 4
      Inject FAQPage JSON-LD schema The visible FAQ section needs a corresponding FAQPage JSON-LD block in the post HTML. Without the schema, Google can read the FAQ but cannot extract it for People Also Ask placement. Both elements are required — the visible section and the machine-readable schema.
    • 5
      Inject named legal entity references Add 3–5 named legal entities relevant to the article: the applicable statute with its full citation, the relevant bar association rule, named legal doctrines, or regulatory body references. These entity anchors are what Google’s quality evaluators and AI systems use to verify legal expertise.
    • 6
      Add a definition box after the intro Insert a 40–60 word definition box immediately after the intro paragraph defining the primary topic. This is the highest-probability featured snippet target — a concise, factual definition that Google’s systems can extract for the position-zero definition box that appears before any organic result.
    • 7
      Set a visible Last Updated date and dateModified schema Add a visible “Last updated: [date]” near the byline. Update the dateModified field in the Article JSON-LD schema to match. For YMYL legal content, freshness signals matter — outdated content on time-sensitive legal topics (statute of limitations, filing deadlines) is evaluated negatively by quality raters.
    • 8
      Add internal links to and from practice area pages Link from the blog post to at least one relevant practice area service page using descriptive anchor text (“personal injury attorney services” not “click here”). Then update the practice area page to link back to the blog post. Bidirectional internal linking passes authority both directions and signals topical depth to Google’s crawlers.
    These 8 steps applied to 10 existing law firm blog posts is exactly the scope of SiteBoost’s WordPress content optimization pilot for law firms. Every step is applied programmatically via the WordPress REST API — no plugin required, no manual editing. Changes pushed live, before/after baseline recorded.

    Frequently Asked Questions

    Can these optimizations be applied to old blog posts, or only new ones?

    All 8 steps can be applied retroactively to existing published posts. WordPress’s REST API allows any post to be updated post-publication — title, excerpt (meta description), content (FAQ section, schema, entity references), and modified date. Retroactive optimization of your existing article library is typically higher-value than publishing new content because existing posts have index history, any existing backlinks, and are already known to Google’s crawlers.

    Which of the 8 steps has the highest impact for law firm WordPress blogs?

    Steps 3 and 4 — adding a FAQ section and FAQPage schema — consistently produce the fastest visible results for law firm content because they directly enable People Also Ask placement eligibility. Step 1 (title tag rewrite) has the highest impact on click-through rate from existing impressions. Step 5 (entity injection) has the highest long-term impact on AI citation probability. Implemented together, all 8 steps create compounding returns that no single step achieves alone.

    Do these steps require a specific WordPress plugin?

    No plugin is required for any of the 8 steps. The title tag, meta description, FAQ section, JSON-LD schema, and content additions can all be applied directly to post content via the WordPress REST API using an Application Password for authentication. SEO plugins like Rank Math or Yoast handle some of these fields through their own meta fields — if you use one, the title and meta description updates should be made through the plugin’s fields rather than the post title and excerpt fields to avoid conflicts.

    Sources: Google Rich Results Test Documentation; AttorneyWebsiteDesign.us, “Law Firm Website SEO: Complete Guide 2026”; inqnest, “Local SEO for Lawyers 2026”; ALM Corp, “SEO for Law Firms: Advanced Tactics for 2026”
  • Law Firm FAQ Schema: How to Win People Also Ask Placements

    Law Firm FAQ Schema: How to Win People Also Ask Placements

    Tygart Media — Law Firm Content Strategy

    How Law Firms Win People Also Ask Placements With FAQ Schema

    By Tygart Media Updated: April 12, 2026
    People Also Ask for legal searches: Google’s People Also Ask boxes appear above organic listings for the majority of legal queries — “how long do I have to file,” “what does this coverage actually include,” “do I need a lawyer for this.” These placements are visible before the first blue link, capturing prospect attention at peak intent. Winning them requires two things: a FAQ section with 40–60 word direct answers to specific questions, and FAQPage JSON-LD schema that tells Google’s systems exactly where those answers are. Most law firm blogs have neither.

    Why PAA Placements Matter More Than Position 1 for Legal Queries

    For legal searches, Google surfaces People Also Ask boxes before position 1 organic results on the majority of high-intent queries. A prospect searching “how long do I have to sue after a car accident in Texas” sees PAA answers before they see any firm’s website. If your content is in that box, you’ve captured attention before your competitors’ organic listings are even visible.

    PAA placements also feed directly into AI Overviews and AI assistants. When a prospect asks ChatGPT the same question, the AI draws from content with the same direct-answer structure that wins PAA placements — well-structured, entity-rich, 40–60 word direct answers with FAQPage schema. Optimizing for PAA and optimizing for AI citation are the same optimization.

    How do law firms win People Also Ask placements? Law firms win People Also Ask placements by adding a FAQ section to existing blog posts where each question-and-answer pair matches a specific legal query pattern — “How long do I have to file a personal injury claim in [state]?”, “What does comparative negligence mean?”, “Do I need a lawyer for a minor car accident?” — with a direct 40–60 word answer immediately following each question, and FAQPage JSON-LD schema injected into the post’s HTML so Google can identify and extract those answers for PAA display.

    The Anatomy of a PAA-Winning Legal FAQ

    Most law firm FAQ sections fail to win PAA placements because they answer the wrong questions in the wrong format. The difference:

    ❌ What doesn’t win PAA
    What is personal injury law?
    Too generic — Nolo, FindLaw, and Wikipedia already own this. No specificity, no jurisdictional context, no urgency signal. Google has better sources for this answer.
    ✅ What wins PAA
    How long do I have to file a personal injury claim in Texas?
    In Texas, the statute of limitations for personal injury claims is two years from the date of injury under Texas Civil Practice and Remedies Code § 16.003. Exceptions apply for minors, claims against government entities (which may require notice within 6 months), and cases where the injury was not immediately discoverable.

    The winning answer is: specific to a jurisdiction, names the relevant statute, acknowledges exceptions, and is 40–60 words. It’s the answer a practitioner would give — not the answer a content writer researching for an hour would produce. That specificity is exactly what Google’s systems evaluate.

    The 7 Legal FAQ Categories That Win PAA Consistently

    1. Statute of limitations questions — “How long do I have to [sue/file/claim] in [state]?”
    2. Cost and fee questions — “How much does a [type] lawyer cost?”, “Do I pay upfront?”
    3. Process questions — “What happens after I file [claim/complaint/petition]?”
    4. Fault and liability questions — “What if I was partially at fault?”, “Who is liable if…?”
    5. Documentation questions — “What evidence do I need for [claim type]?”
    6. Alternative questions — “Can I handle this without a lawyer?”, “What happens if I don’t get a lawyer?”
    7. Recovery questions — “What damages can I recover?”, “How much is my case worth?”

    Implementing FAQPage Schema in WordPress

    FAQPage schema is injected as a JSON-LD block in the post’s HTML. It does not require a plugin — it can be added directly to the post content. The schema structure tells Google’s systems exactly which HTML elements contain the question text and which contain the answer text, making the content machine-readable for PAA extraction and AI citation.

    The most common implementation error is creating a FAQ section in HTML without the corresponding JSON-LD schema — Google can see the questions but cannot parse them for PAA extraction. Both the visible FAQ section and the JSON-LD block are required.

    FAQPage schema injection is one of the four core optimization layers in SiteBoost’s WordPress content optimization for law firms. For each post, we generate 6–8 PAA-targeted questions, write direct answers, and inject both the visible FAQ section and the FAQPage JSON-LD schema — pushing everything live via the WordPress REST API.

    Frequently Asked Questions

    How long does it take for FAQPage schema to earn PAA placements?

    FAQPage schema can earn People Also Ask placements within 2–4 weeks of implementation for posts that are already ranking in positions 1–20. Google crawls and re-evaluates indexed content regularly, and FAQPage schema is one of the fastest-surfacing schema types in Google’s rich result system. Posts that are not yet indexed or ranking below position 20 will need to build ranking authority before PAA placements are achievable.

    Should every law firm blog post have a FAQ section?

    Every post that targets an informational query — which is most legal blog content — should have a FAQ section. Practice area service pages benefit from FAQs too, but they serve a slightly different function (addressing pre-hire objections rather than research questions). The posts with the highest PAA potential are those targeting process, cost, liability, and statute of limitations questions — the queries prospects ask during active research before contacting a firm.

    Does FAQPage schema work for all practice areas?

    Yes. FAQPage schema works across all legal practice areas because the underlying mechanism — direct answers to specific questions that Google can extract — is universal. Personal injury, family law, criminal defense, estate planning, business law, and immigration all have distinct question patterns that prospects search. The key is writing questions in the language clients use, not the language attorneys use, and providing direct jurisdictional answers rather than generic legal information.

    Sources: Google Rich Results Documentation — FAQPage; ALM Corp, “SEO for Law Firms: Advanced Tactics for 2026”; W3Era, “Law Firm SEO Guide 2026”; Grow Law, “SEO for Lawyers: How to Dominate the SERPs in 2026”
  • E-E-A-T for Law Firms: Trust Signals That Drive Rankings

    E-E-A-T for Law Firms: Trust Signals That Drive Rankings

    Tygart Media — Law Firm Content Strategy

    E-E-A-T for Law Firms: The Trust Signals That Actually Move Legal Content Rankings

    By Tygart Media Updated: October 5, 2026
    Why E-E-A-T hits law firms hardest: Google classifies legal content as YMYL — Your Money or Your Life — content that can directly affect a person’s financial situation, legal rights, or safety. This triggers the highest level of E-E-A-T scrutiny of any content category. Google says its ranking systems give even more weight to content that aligns with strong E-E-A-T on YMYL topics, and the September 11, 2025 edition of its Search Quality Rater Guidelines keeps that standard at the center of how raters judge page quality. The difference is specific and implementable.

    What E-E-A-T Actually Means for Legal Content

    E-E-A-T — Experience, Expertise, Authoritativeness, Trustworthiness — appears about 120 times in Google’s Search Quality Rater Guidelines. For law firms, each dimension has a specific, practical meaning that goes beyond the abstract framework.

    E

    Experience

    First-hand knowledge of the legal situation being discussed. An attorney who has handled 200 slip-and-fall cases brings experiential authority a content writer cannot replicate. This shows in specificity: real case dynamics, real objections, real procedural details.

    E

    Expertise

    Demonstrated legal knowledge through how content is structured. Named statutes, specific case law references, bar association standards, jurisdictional nuances. Expertise is not claimed in a bio — it’s demonstrated in the precision of the content itself.

    A

    Authoritativeness

    External recognition. Bar association memberships, Avvo and Martindale-Hubbell profiles, citations from legal directories, mentions in local legal news. Named credentials in author schema markup that Google’s systems can verify.

    T

    Trustworthiness

    The most weighted dimension. Accurate content, named sources for statistics, HTTPS, consistent NAP, ABA Model Rules compliance in content claims, regular content updates with visible dates. Trust is infrastructure, not tone.

    What E-E-A-T signals does Google evaluate for law firm content specifically? Google evaluates law firm content E-E-A-T across four dimensions: Experience (does the content reflect first-hand legal practice knowledge, including real case dynamics and procedural specifics?), Expertise (are named statutes, case law, and bar association standards correctly referenced?), Authoritativeness (does the named author have verifiable bar admission, named credentials, and external recognition on Avvo, Martindale-Hubbell, or FindLaw?), and Trustworthiness (are claims sourced, content updated with visible dates, and the site technically secure and ABA-compliant in its marketing claims?).

    The Three Highest-Impact E-E-A-T Implementations for Law Firm Blogs

    1. Named Attorney Authorship With Credentials in Schema

    Every blog post should be attributed to a named attorney with verifiable credentials — not “Staff Writer” or the firm name. The author byline should link to an author bio page that includes bar admission state(s), practice area specialties, years in practice, and any notable professional recognitions. This bio page should have Physician-equivalent Person schema markup (or Attorney schema) with those credentials as named properties. This is the single highest-impact E-E-A-T implementation for law firm content because it converts an anonymous article into verifiable expert content.

    2. Named Legal Entity References in Every Article

    Each article should contain at least 3–5 named legal entities relevant to the topic: the applicable statute with its citation, the relevant bar association rule, named legal doctrines (contributory negligence, res ipsa loquitur, piercing the corporate veil), and any relevant regulatory body or court. These entities are what Google’s quality evaluators use to assess whether the content represents genuine legal expertise or generic information anyone could write.

    3. Visible Update Dates With dateModified Schema

    Legal content goes stale. Statutes change. Court decisions create new precedents. An article about the statute of limitations for personal injury claims that was last updated in 2022 is a liability in 2026 — Google’s quality evaluators are specifically trained to flag outdated YMYL content. Every law firm blog post needs a visible “Last updated” date near the byline and a dateModified field in the Article JSON-LD schema. When the content is genuinely updated — not just date-stamped — this signals active editorial stewardship.

    All three E-E-A-T implementations — attorney credential schema, legal entity injection, and dateModified schema — are applied as part of SiteBoost’s WordPress content optimization for law firms. The optimization is structural; your attorneys’ actual legal content and clinical judgment remain unchanged.

    Frequently Asked Questions

    Is E-E-A-T a direct Google ranking factor?

    E-E-A-T is not a direct algorithmic ranking factor in the sense that there is no “E-E-A-T score” that Google outputs. It is a framework used by human quality raters whose evaluations inform algorithm development. Content that demonstrates strong E-E-A-T signals — verifiable authorship, named sources, accurate and updated information — performs better in rankings because those signals correlate with the content quality properties that Google’s algorithms directly measure: accuracy, depth, relevance, and trust.

    Can a law firm without a named attorney author still rank well?

    Increasingly difficult, especially post-2025 algorithm updates targeting YMYL content without verifiable expertise. Anonymous law firm content — attributed to “the firm” rather than a named attorney — is missing the Experience and Expertise signals that Google’s quality evaluators specifically look for in legal content. The practical fix is to attribute existing posts to named attorneys and create author bio pages with credential schema, which can be done retroactively without rewriting any content.

    How does E-E-A-T affect law firm content in AI search results?

    AI systems like ChatGPT, Perplexity, and Google AI Overviews use signals similar to E-E-A-T when evaluating which content to cite in synthesized answers. Named attorney credentials, specific legal entity references (named statutes, case law, bar association rules), and verifiable source citations make content machine-verifiable — which is the AI system equivalent of trustworthy. Legal content with strong E-E-A-T signals is significantly more likely to be cited by AI assistants when prospects research legal questions before contacting a firm.

    Sources: Google Search Quality Rater Guidelines (September 11, 2025 edition); Google Search Central, “Creating helpful, reliable, people-first content”; American Bar Association, Law Practice Magazine; BKND Development, “E-E-A-T in 2026: The Content Quality Signals That Actually Matter”; YMM Digital, “The Definitive Guide to Law Firm SEO in 2026”; Wellows, “E-E-A-T Checklist for SEO”
  • Law Firm Blog SEO: 4 Fixes for Posts That Don’t Rank

    Law Firm Blog SEO: 4 Fixes for Posts That Don’t Rank

    Tygart Media — Law Firm Content Strategy

    Why Law Firm Blog Posts Don’t Rank (And the 4 Fixes That Actually Work)

    By Tygart Media Updated: April 12, 2026
    The core problem: Most law firm blog posts are published correctly but optimized incorrectly — or not at all. They have no meta description, a title that doesn’t match search intent, no FAQ section, no schema markup, and no named entity references that signal domain expertise. Google can index them. It just has no reason to rank them. These four fixes address the most common gaps, in order of impact.

    The Publishing Trap: Why “Consistent Blogging” Isn’t Enough

    Comparison of Claude how-to fit versus local service page fit for assistants
    The publishing trap: consistent blogging is not enough.

    Law firms are frequently advised to “publish consistently” as the foundation of their SEO strategy. The advice is correct in principle — content volume matters — but incomplete in practice. A blog post that is published without a keyword-optimized title, a written meta description, a FAQ section, and proper schema markup is not an SEO asset. It’s a page that exists. Existence and visibility are different things.

    According to research on legal search behavior, consumers increasingly use online resources — including AI assistants — to understand their legal situation before contacting a firm. That means a law firm article about personal injury claims needs to be structured to answer those research questions directly, not just exist as a published piece of content. The gap between “published” and “optimized” is exactly where most law firm blog investment is lost.

    Why don’t law firm blog posts rank despite consistent publishing? Law firm blog posts fail to rank despite consistent publishing when they lack the optimization signals Google uses to evaluate relevance and authority: keyword-specific title tags (not just the article topic), written meta descriptions (not auto-generated excerpts), FAQPage schema targeting People Also Ask queries, and named entity references — ABA, specific statutes, legal doctrines — that signal genuine legal expertise. Publishing frequency without optimization depth produces a large library of invisible content.

    Fix 1: Rewrite the Title Tag for Search Intent, Not Article Description

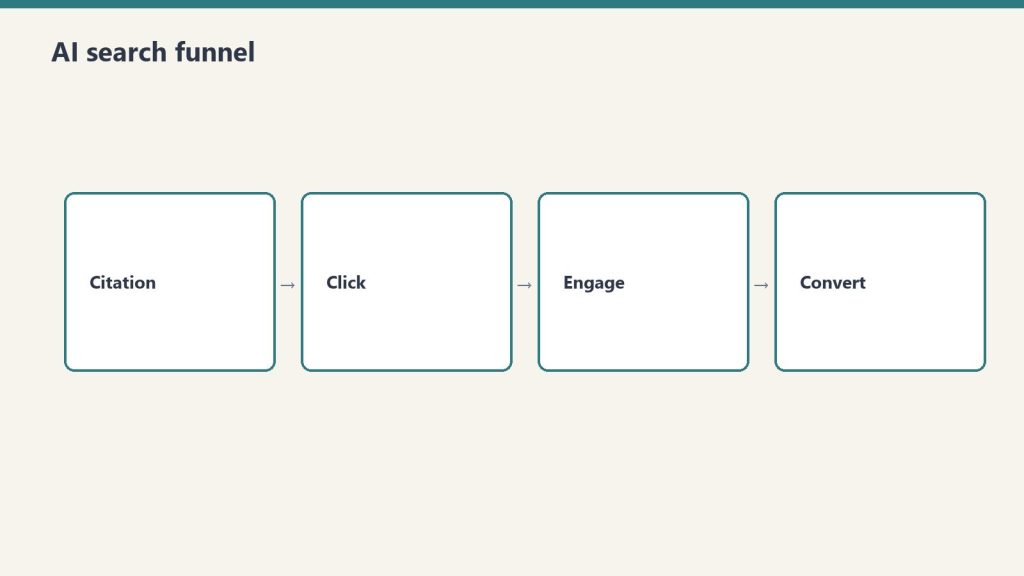
    Four-stage funnel: citation, click, engage, convert
    Fix 1: rewrite the title tag for search intent.

    The most common law firm blog title mistake is writing a title that describes the article rather than matching how a potential client searches. “Understanding Comparative Negligence in Personal Injury Cases” describes the article. “What Is Comparative Negligence and How Does It Affect My Case?” matches the actual search query.

    Title tags should be 50–60 characters, lead with the primary keyword, and reflect how the reader would phrase their question — not how a lawyer would title a legal memorandum. According to research on E-E-A-T and legal content, compelling, keyword-aligned title tags are among the highest-impact on-page signals for click-through rate from legal search results.

    Fix 2: Write Every Meta Description Manually

    WordPress auto-generates meta descriptions from the first paragraph of the post. Law firm posts almost universally have a scene-setting first paragraph that makes a poor meta description. “Personal injury law in Texas can be complex. If you’ve been injured in an accident, you may be wondering about your rights…” does not make a prospect click. A direct value statement does: “Injured in Texas? Learn how comparative negligence affects your case, what damages you can recover, and when you need to act. Free case review.”

    Meta descriptions should be 140–155 characters, include the primary keyword naturally, and end with a clear action signal. Every post needs one written from scratch — not auto-generated.

    Fix 3: Add a FAQ Section With FAQPage Schema

    People Also Ask placements in Google now appear for the majority of legal queries. These box placements appear above organic results and capture attention before the first blue link. Earning a PAA placement requires two things: a FAQ section with direct 40–60 word answers to specific questions, and FAQPage JSON-LD schema that tells Google’s systems exactly where those answers are.

    For a personal injury article, the FAQs that capture PAA placements are specific: “How long do I have to file a personal injury claim in Texas?”, “What does comparative negligence mean?”, “Do I pay a personal injury lawyer upfront?” — not generic “What is personal injury law?” questions that every directory already answers.

    Fix 4: Inject Named Legal Entities

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Fix 4: inject named legal entities into firm content.

    Google’s quality evaluators assess law firm content for Expertise and Authoritativeness by looking at entity signals — specific named references that demonstrate genuine legal knowledge. An article about personal injury law that references “the American Bar Association’s Model Rules of Professional Conduct,” cites “Texas Civil Practice and Remedies Code § 16.003” for the statute of limitations, and mentions “contributory negligence vs. modified comparative fault” as named legal doctrines signals legal expertise. The same article that says “you should contact a lawyer quickly because of time limits” signals nothing.

    This entity injection is also what determines whether your article gets cited by ChatGPT or Perplexity when a potential client asks an AI assistant about their legal situation.

    The four fixes above can be applied to your existing published posts without rewriting them. SiteBoost’s WordPress content optimization for law firms applies all four — title, meta, FAQ schema, and entity injection — systematically across your article library, with changes pushed live via the WordPress REST API.

    Related on Tygart Media: citing sources for E-E-A-T · information density · taxonomy architecture.

    Frequently Asked Questions

    How many blog posts does a law firm need to see SEO results?

    Volume matters less than optimization depth. Ten well-optimized posts — with intent-matched titles, written meta descriptions, FAQ schema, and entity injection — consistently outperform 50 unoptimized posts. The priority for most law firm blogs is not more content but better optimization of existing content. Start with your top 10 traffic-driving posts and apply all four fixes before publishing new content.

    Should law firm blog posts target practice area keywords or client question keywords?

    Both, but in different content types. Practice area keywords (“personal injury attorney Houston”) belong on service pages. Blog posts should target client question keywords — the long-tail informational queries people search when they’re researching their situation before hiring: “how long do I have to sue after a car accident in Texas”, “what happens if I’m partially at fault in an accident”, “can I sue if the accident was on private property.” These informational queries convert because they reach potential clients during active research.

    How often should a law firm blog be updated?

    Existing posts should be reviewed and updated whenever: a statute changes, a new case establishes relevant precedent, statistics are more than 12–18 months old, or the post is ranking on page 2 (positions 11–20) and could be pushed to page 1 with additional optimization. New posts should be published at a frequency the firm can sustain quality — one well-optimized post per month outperforms four thin posts per month in both rankings and E-E-A-T evaluation.

    Sources: Clio Legal Trends Report 2025; Google Search Quality Rater Guidelines; ALM Corp, “SEO for Law Firms: Advanced Tactics for 2026”; Grow Law, “SEO for Lawyers: How to Dominate the SERPs in 2026”
  • B2B SaaS Blog Optimization: Turn Traffic Into Pipeline

    B2B SaaS Blog Optimization: Turn Traffic Into Pipeline

    SiteBoost — Vertical Series

    SiteBoost for B2B SaaS: WordPress Blog Optimization for Software Companies That Need Pipeline, Not Just Traffic

    By Tygart Media — This page is built using the same SEO, AEO, and GEO techniques applied through SiteBoost. The entity density, schema, FAQ structure, and speakable blocks you see here are exactly what the service delivers to your WordPress blog.

    B2B SaaS WordPress Blog Optimization: The process of applying SEO (Search Engine Optimization), AEO (Answer Engine Optimization), and GEO (Generative Engine Optimization) to a software company’s existing WordPress blog posts — restructuring articles for buyer-journey intent, injecting product-category entities and integration references, adding FAQPage schema targeting decision-maker queries, and building speakable blocks so the company’s content gets cited by ChatGPT, Perplexity, and Google AI Overviews when buyers research software solutions.

    The B2B SaaS Content Problem: 50 Blog Posts, Zero Pipeline

    Most B2B SaaS companies have been publishing blog content for years. They have 30, 50, sometimes 100+ WordPress articles covering product features, integrations, use cases, and industry trends. Almost none of it converts — not because the content is bad, but because it was never optimized for how buyers actually search, compare, and decide in 2026.

    Google Ads CPCs for B2B SaaS have surged 40–50% since 2020. Yet the average SaaS company’s WordPress blog — the owned channel that compounds indefinitely — sits unoptimized. No FAQPage schema. No direct-answer formatting. No AI citation signals. No buyer-stage mapping. Articles that should be closing demos are instead ranking nowhere and converting nobody.

    Why do B2B SaaS blog posts fail to generate pipeline despite high traffic?
    B2B SaaS blog posts fail to generate pipeline when they target informational keywords without buyer-stage alignment, lack FAQPage schema to capture People Also Ask placements for decision-stage queries, and have no entity injection for the product category, integration ecosystem, or competitive alternatives that buyers compare during evaluation. Traffic without conversion intent signals — direct answers, comparison tables, and decision-stage CTAs — produces sessions, not demos.

    The Three Buyer Stages SaaS Blog Content Must Cover

    According to Gartner’s 2025 B2B Buying Report, 75% of B2B buyers prefer a rep-free sales experience. Your WordPress blog is the sales rep. It needs to work at every stage of a 40–90 day evaluation cycle — and most SaaS blogs only cover the awareness stage.

    Awareness

    Problem-Aware Content

    Informational posts explaining the problem your product solves. Most SaaS blogs have plenty of this. The optimization gap: no direct-answer formatting, no PAA targeting, no AI citation signals.

    Consideration

    Comparison & Evaluation

    “Best [software category] tools,” integration guides, use-case breakdowns. High-intent, often ignored. AEO + schema make these the highest-converting pages when optimized correctly.

    Decision

    Bottom-of-Funnel Content

    Pricing comparisons, implementation guides, ROI calculators, migration posts. Almost always missing FAQPage schema and the entity density needed to rank for “[competitor] alternative” searches.

    What Makes SaaS Content Different: The Entity Set That Signals Category Authority

    B2B software content has a specific entity vocabulary that signals authority to both Google and AI systems. Most SaaS WordPress blogs mention their own product name repeatedly but miss the named entities that establish category expertise and get content cited by AI research assistants.

    What named entities should B2B SaaS WordPress content include for AI citation?
    B2B SaaS content optimized for AI citation should reference: the product category standard (e.g., CRM, PLM, ERP, HRIS, CPQ), relevant industry analysts and reports (Gartner Magic Quadrant, Forrester Wave, G2 category leaders), integration ecosystem partners (Salesforce, HubSpot, Slack, Zapier, Workday, AWS), compliance and security frameworks relevant to the buyer’s industry (SOC 2 Type II, ISO 27001, GDPR, HIPAA, FedRAMP), and buyer-role terminology (Chief Revenue Officer, VP of Engineering, Head of Customer Success, Procurement). Entity density — not keyword density — determines whether AI systems treat a page as a citable authority.

    Hypothetical Before & After: A Typical B2B SaaS Blog Post

    This illustrates what SiteBoost applies to a typical SaaS company article about workflow automation — the kind of content most software companies publish and then wonder why it doesn’t convert:

    Before SiteBoost
    Title: “How Workflow Automation Saves Time for Your Team”

    Meta description: Empty — WordPress using post excerpt

    Word count: 680 words

    Buyer stage: Awareness only — no consideration or decision layer

    FAQ section: None

    Schema: None

    Entity density: Product name mentioned 8x. No integration names, no analyst references, no compliance entities

    AI visibility: Invisible — no speakable blocks, no LLMS.txt

    After SiteBoost
    Title: “Workflow Automation for B2B Teams: How to Eliminate Manual Handoffs and Accelerate Deal Cycles”

    Meta description: “Stop losing deals to slow handoffs. Workflow automation eliminates manual steps across your CRM, project management, and billing tools. See how.” (155 chars)

    Word count: 1,050 words (definition box + FAQ added)

    Buyer stage: Awareness → Consideration bridge added with comparison table and integration entity injection

    FAQ section: 6 questions — “How long does workflow automation take to implement?”, “Does it integrate with Salesforce?”, “What’s the ROI?” — all targeting PAA

    Schema: FAQPage + Article JSON-LD injected

    Entity density: Zapier, HubSpot, Salesforce, SOC 2, G2 Workflow Automation category, Gartner — all referenced naturally

    AI visibility: 2 speakable blocks targeting “what is workflow automation” and “how does workflow automation integrate with CRM”

    The AI Search Opportunity SaaS Companies Are Missing

    When a procurement manager asks ChatGPT “what’s the best workflow automation tool for a mid-market sales team?” or a CTO asks Perplexity “how does [software category] integrate with our existing Salesforce instance?” — the AI pulls from the most structured, entity-rich, authoritative content it can find. SaaS companies that have integration entity references, compliance framework mentions, and speakable answer blocks in their WordPress blog posts are dramatically more likely to be cited.

    This matters because B2B buyers increasingly start software research in AI assistants before they ever reach Google. A SaaS company cited by ChatGPT at the research stage has a meaningful advantage before the buyer even knows which vendors to evaluate.

    The Paid vs. Organic Math for B2B SaaS

    Channel Cost Per Click Monthly Spend (100 visits) Compounds? Scales?
    Google Ads (SaaS terms) $5–$15+ $500–$1,500/mo ❌ Stops when budget stops ❌ Linear cost increase
    LinkedIn Ads (B2B) $8–$25+ $800–$2,500/mo ❌ Stops when budget stops ❌ Linear cost increase
    Optimized WordPress blog (SiteBoost) $0 per click $47/post, one time ✅ Compounds over time ✅ Every optimized post is permanent

    SiteBoost Pilot for B2B SaaS: What You Get

    Deliverable Details
    Site Connection & Audit WordPress REST API connection, full blog inventory, buyer-stage mapping of existing content, schema gap report, entity gap analysis, Before Baseline Report
    10 Post Optimizations Full SEO + AEO + GEO on 10 highest-opportunity articles — buyer-stage restructuring, integration entity injection, FAQPage schema, speakable blocks targeting AI search
    60-Day Impact Report Before vs. after: rankings, PAA appearances, demo-stage keyword movement, AI citation visibility
    Buyer-stage prioritization We identify which of your posts are closest to consideration and decision stage and prioritize those — highest pipeline potential first
    Price $597 pilot — $767 value

    Interested in the SiteBoost Pilot for Your SaaS Site?

    We onboard sites personally. Email Will with your site URL and he’ll follow up within one business day.

    → Email Will — Start the Pilot

    Email only. No sales call required. No commitment to reply.

    Frequently Asked Questions: SiteBoost for B2B SaaS

    Our SaaS site runs on React/Next.js — can SiteBoost still help?

    SiteBoost optimizes WordPress blog content specifically. If your marketing blog runs on WordPress — which the majority of SaaS companies use for content, even when the product itself runs on React, Next.js, or another framework — SiteBoost connects to it via the REST API and applies all optimization layers. If your blog is not on WordPress, SiteBoost is not the right fit.

    Our SaaS blog already gets traffic. Why do we need optimization?

    Traffic without pipeline is a vanity metric. The most common pattern in B2B SaaS is thousands of monthly blog sessions and minimal demo requests from organic. The gap is almost always buyer-stage mismatch — content attracting awareness-stage readers when consideration and decision-stage content is what drives conversions. SiteBoost identifies which of your existing posts are closest to the consideration and decision stages and restructures them for conversion: direct answers, FAQ schema, integration entity injection, and bottom-of-funnel CTAs.

    How does SiteBoost handle technical SaaS terminology in content optimization?

    SiteBoost’s GEO layer injects named entities specific to your product category — integration partners, compliance frameworks, industry analyst reports, and buyer-role terminology. This is not generic keyword stuffing. For a B2B project management SaaS, this means naturally referencing Jira, Asana, Salesforce integrations, SOC 2 compliance, and Gartner PPM category context. For a CRM, it means referencing HubSpot, Salesforce, pipeline velocity, and MQL-to-SQL conversion. The entity set is customized to your product category before any post is touched.

    What does AEO optimization look like for B2B SaaS content specifically?

    For SaaS companies, AEO targets the questions buyers ask during software evaluation: “How long does implementation take?”, “Does it integrate with [tool]?”, “What’s the pricing model?”, “How is data security handled?”, “What’s the migration process from [competitor]?” These are high-intent, decision-stage queries that appear in Google’s People Also Ask boxes for competitive software searches. A FAQPage schema block targeting 6–8 of these questions, injected into an existing article, can earn PAA placements that your competitors are currently occupying.

    We have 80+ blog posts. How does SiteBoost decide which 10 to optimize in the pilot?

    The Before Baseline Report maps every post by word count, existing schema coverage, estimated keyword opportunity, and buyer stage. We then prioritize posts that are: closest to page 1 (positions 11–30 — near-miss opportunities), already targeting consideration or decision-stage intent, and missing schema or direct-answer structure. These are the highest-leverage posts — they already have Google’s attention and just need optimization depth to move up. You review and approve the priority list before we start.

    How does SiteBoost optimization affect our WordPress site’s technical performance?

    SiteBoost writes to post content and excerpt fields only via the WordPress REST API. It does not modify theme files, plugin settings, database configuration, or server-level settings. Changes are at the post level — content, title, slug, excerpt — and JSON-LD schema injected as HTML in the post body. There is zero impact on Core Web Vitals, page speed, or server configuration. The WordPress Application Password used is scoped to posts only.

  • Live SEO Case Study: Organic Traffic Value Meter | Tygart

    Live SEO Case Study: Organic Traffic Value Meter | Tygart

    The Distillery
    — Brew № — · Distillery


    The Tygart Media Distillery

    Brew #1 — Radon Mitigation

    A living knowledge base, distilled from zero, published in the open.

    LIVE
    loading…
    brewed since 2026-04-10

    Category Organic Value Meter
    $0
    PER MONTH — RADON MITIGATION CATEGORY
    Day 0. The zero timestamp is real.

    Ranked Keywords
    0
    in top 100 for radon category URLs

    Nodes Published
    0 / 150
    of target corpus

    Top 10 Placements
    0
    first page Google

    Days Brewing
    0
    since 2026-04-10

    This is an open kitchen. Every knowledge node in this category is being brewed and published in public, through an eight-pass distillation pipeline that cross-references EPA guidance, AARST standards, state health departments, and peer-reviewed radon literature. The meter above tracks the category’s real organic SEO contribution to tygartmedia.com, measured daily against DataForSEO and SpyFu. No projections. No theoretical ceilings. Just what Google actually thinks the work is worth, right now.

    Brew Progress by Wave

    Top Ranking Keywords

  • Compounding Content: Why the Knowledge Delta is the Asset

    Compounding Content: Why the Knowledge Delta is the Asset

    The Distillery
    — Brew № — · Distillery

    There is one thing that justifies the existence of any piece of information — whether it is a questionnaire answer, a blog post, a research paper, or a conversation. That thing is the delta.

    The delta is the gap between what was known before and what is known after. It is the only unit of measurement that matters in a knowledge economy. Everything else — word count, publication frequency, keyword coverage, contributor count — is a proxy metric. The delta is the real one.

    What the Delta Actually Measures

    Most information does not create a delta. It moves existing knowledge from one container to another. An article that summarizes three other articles, a questionnaire response that confirms what the system already knows, a report that restates findings from prior reports — none of these change the state of knowledge. They change the location of knowledge. That is a logistics operation, not a knowledge operation.

    A delta event is different. Something enters the system that was not there before. A practitioner documents a process that existed only in their head. A contributor surfaces an edge case that the general model did not account for. A writer names a pattern that everyone in an industry recognizes but no one has articulated. After the contribution, the knowledge base is genuinely different. The world knows something it did not know before. That difference is the delta. That is the asset.

    Why the Delta Compounds

    A piece of content that contains a genuine delta does not depreciate the way a paraphrase does. It becomes a reference point. Other content cites it, links to it, builds on it. AI systems trained on it carry it forward. People who read it share what they learned from it because they actually learned something. The delta propagates.

    A paraphrase, by contrast, is immediately superseded by the next paraphrase. It has no anchor in the knowledge base because it did not change the knowledge base. It cannot be built upon because it introduced nothing to build upon. It ages and falls away.

    This is why high-delta content from years ago still ranks, still gets cited, still drives traffic. It earned its place in the knowledge base by changing what the knowledge base contained. Low-delta content from last week is already invisible because it never earned that place.

    The Knowledge Token System as a Delta Detector

    The reason knowledge token systems score contributions on novelty, specificity, and density is that those three variables are proxies for delta magnitude. A novel answer changed the state of what is known. A specific answer created a precise, actionable change rather than a vague one. A dense answer created a large change relative to the effort of processing it.

    The token grant is not payment for time spent filling out a form. It is compensation for delta generated. A contributor who spends five minutes giving a genuinely novel, specific, dense answer earns more tokens than a contributor who spends an hour giving generic, vague, low-density answers. The system is not rewarding effort. It is rewarding contribution to the actual state of knowledge.

    This inverts the typical incentive structure of content production and knowledge collection, where volume is rewarded because volume is easy to measure. Delta is harder to measure — but it is the right thing to measure, and the systems that measure it correctly end up with knowledge bases that are actually valuable rather than merely large.

    The Delta Test for Content

    Every piece of content can be evaluated with a single question: what does the collective knowledge base contain after this piece exists that it did not contain before?

    If the answer is “the same information, arranged slightly differently” — the delta is zero. The piece is a redistribution event, not a knowledge event. It may serve a purpose — reaching a new audience, establishing a presence on a keyword — but it should not be confused with a knowledge contribution. It will not compound. It will not be cited. It will not earn its place in the knowledge base because it did not change the knowledge base.

    If the answer is “a named framework that did not previously exist,” or “a documented process that only existed in one practitioner’s head,” or “a specific finding that contradicts the prevailing assumption” — the delta is real. The piece has a reason to exist beyond its publication date. It becomes the reference, not one of many paraphrases pointing at a reference that does not exist.

    Building Toward Delta

    The practical implication is that delta-generating content requires something to say before the writing begins. Not a topic. Not a keyword. Something to say — a specific insight, a documented process, a named pattern, a genuine finding. The writing is the vehicle for the delta, not the source of it.

    This is why the Human Distillery model works. It does not start with a content calendar. It starts with people who know things that have not been written down. The extraction process — the interview, the questionnaire, the structured conversation — pulls the delta out of a practitioner’s head and into a form the knowledge base can absorb. The writing that follows is the articulation of something real. That is why it compounds.

    The knowledge token economy operationalizes the same logic. Contributors who have genuine deltas to offer — real expertise, specific processes, novel findings — earn meaningful access. Contributors who are redistributing existing knowledge earn little. The system is a delta detector, and it rewards accordingly.

    The Only Metric That Matters

    Publication frequency does not compound. Word count does not compound. Keyword coverage does not compound. Contributor volume does not compound.

    Delta compounds.

    A knowledge base built on genuine deltas — whether those deltas come from structured interviews, scored questionnaires, or pieces of content that actually changed what readers know — becomes more valuable over time in a way that a knowledge base built on redistributed information never will. The compounding is not metaphorical. It is structural. Each delta makes the base more complete, which makes each subsequent delta easier to identify because you can see exactly what is missing.

    The businesses, content operations, and API systems that understand this will build knowledge bases that are genuinely defensible. Not because they published more, but because they published things that changed the state of what is known. The delta is the asset. Everything else is overhead.