Tag: Internal Linking

  • The Second Brain Has a Front Door: Why a Maintained Website Learns From Everyone Who Walks In

    The Second Brain Has a Front Door: Why a Maintained Website Learns From Everyone Who Walks In

    A private second brain is built like a locked filing cabinet in a spare bedroom. You hook up your calendar, your email archive, your private notes, and your contacts; the software indexes what you already saw and hands it back when you ask. That works well when the job is remembering your own week. The trouble is its ceiling: a private second brain only ever knows what its owner remembered to file inside it.

    Our maintained websites work the other way around. The sites are the second brain. Writing a sourced guide or a company census is how the system learns a domain, and the published estate is the database. Instead of locking the shelves behind a password, we leave a front door open on the street. Readers catch stale figures, profiled companies correct their own entries, and the walking patterns of strangers decide which room gets built next.

    In Pay for Your Own Ticket, we walked the property from the sidewalk to verify that what returns HTTP 200 from the curb matches what we think we built inside — building on the owner-controlled files from The Shared Brain. This companion piece takes one step inside the threshold to watch what happens after the door swings open: how visitors garden the database, and where the metaphor bends.

    Printable Edition + Front-Door Card
    Download The Second Brain Has a Front Door (5-Page PDF)
    Includes both visual charts, the Page 5 Front-Door Second Brain Card, and verified primary sources.

    A Reader Gardened the Pricing Database

    Start with an ordinary correction that no private note system would ever receive. On November 20, 2026, Bohdan Shkliarchuk — founder and publisher of ToolsGavel, an independent software pricing-audit site — emailed to point out that our Microsoft 365 consumer prices were out of date. Checking Microsoft’s January 16, 2025 announcement and Microsoft’s live comparison page proved him right: Microsoft 365 Personal moved from $6.99/month to $9.99/month and Microsoft 365 Family moved from $9.99/month to $12.99/month when Copilot was bundled.

    Even checking live required looking past the surface: Microsoft’s store page currently prints a limited-time $6.99 first-month intro offer right beside the struck-through $9.99/month regular price. Fixing the flagged Copilot small-business vs. enterprise post (updating Personal, Family, and the derived $27/month total to $30/month alongside $20/month Copilot Pro) prompted a sweep of all 3,914 published documents on tygartmedia.com (3,699 posts and 215 pages). That sweep caught 1 sibling article (Copilot pricing compared), leaving 2 updated posts, rebuilt PDFs, and matching Markdown twins. A private note holding $6.99 stays stale in the dark; a page on the street gets checked by someone whose own work depends on the numbers.

    The Profiled Maintain Their Own Entries

    Reader emails happen when someone happens to stop by. Our publish-first census model turns that same loop into deliberate architecture: verify primary public sources, publish the profile live, and send a plain note inviting the subject to correct anything missing or out of date. Across 5 censuses — the Washington Space Cluster (41 profiled companies), the Washington AI Census (100 profiles), the AI Dev-Tools Census (34), the ESG Software Census (27), and the Facility Vendor Census (19) — outreach completed across November 20–21, 2026 for 95 Washington AI, 34 AI Dev-Tools, 27 BC ESG, and 13 Healthcare Facility Hub vendor contacts.

    The interview side follows the exact same discipline. Before K. Max Koonce’s Sedgwick claims interview, The Claim Is Decided in the First 24 Hours, published on November 20, Judy Molnar requested 2 specific edits: drop the email-provenance line and omit any bio link. Honoring both shaped the live piece — and when a follow-up check on November 21 caught a surviving top-deck provenance note, a cleanup pass stripped it across served HTML, the 4-page PDF, and the Markdown twin. The subjects of the database are better fact-checkers of their own records than any back-room scraper.
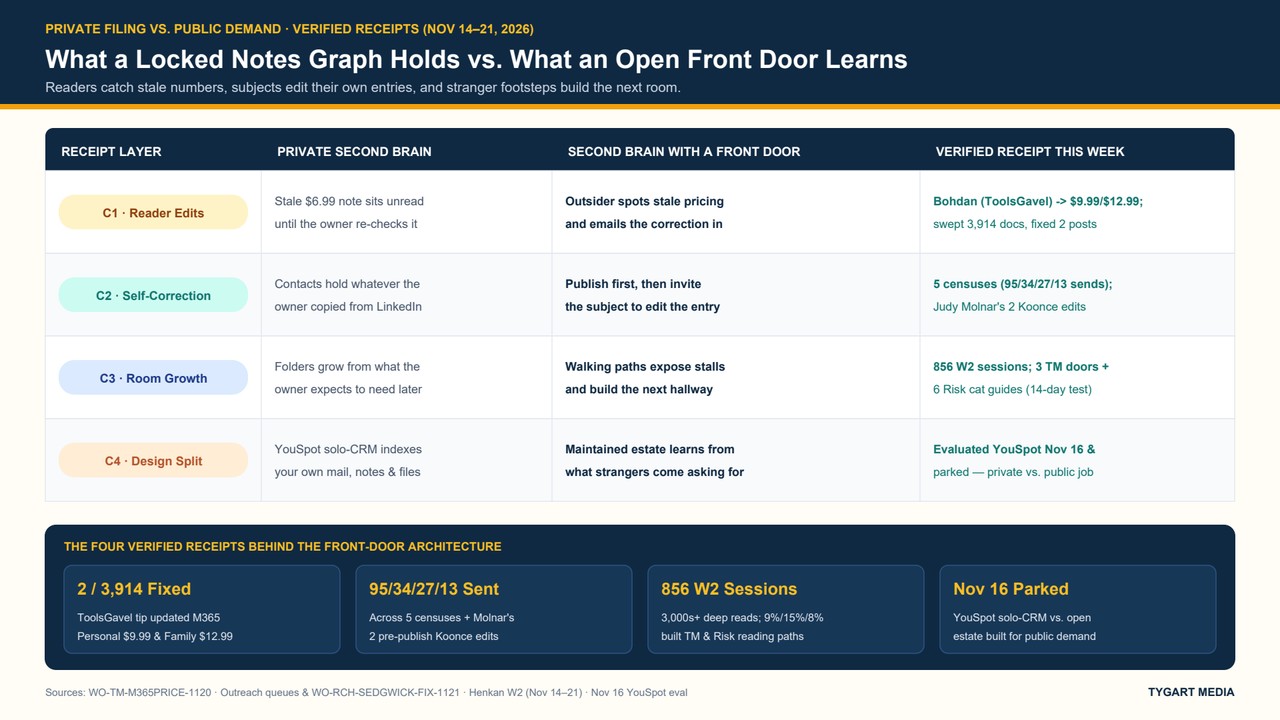
    Comparison chart contrasting a private second brain against a maintained website with an open front door across four verified November 2026 receipts: reader price correction (2 of 3,914 TM docs), self-maintained census entries (5 censuses; 95/34/27/13 sends; Judy Molnar's 2 Koonce edits), visitor-driven pathways (856 W2 human sessions; 3 TM doors + 6 Risk guides), and YouSpot solo-CRM evaluation.
    Private filing versus public demand across four verified receipts from November 2026.

    Footsteps Decide Which Room Gets Built Next

    Corrections keep existing shelves accurate; visitor movement decides where new carpentry goes. Over the first full week of Henkan Vision telemetry from November 14–21, 2026 (counting only engaged human sessions past the 30-second floor), our 7 enrolled sites logged 856 engaged human visits: 478 on tygartmedia.com, 224 on Healthcare Facility Hub, 65 on Risk Coverage Hub, 43 on BC ESG, 36 on Continuity Hub, 7 on Restoration Intel, and 3 on Universal Commerce Protocol. Hour-long single-page reads past 3,000 seconds (3,592s on HFH, 3,565s on BC ESG, 3,558s on Risk, 3,555s on TM) appeared alongside low multi-page rates: 42/478 (9%) on TM, 34/224 (15%) on HFH, and 5/65 (8%) on Risk.

    Visitors were not bouncing — they were walking in for a specific resource, studying one page hard, and leaving because the room had no obvious doorway into the next shelf. On November 21, 2026, following Google’s crawlable link guidance, we built two targeted responses directly from those tracks. On TM, 3 Claude pricing doors — Pro vs. Max (95), Team Usage Limits (44), and Team Seat Pricing (26) — drew 165/478 (34.5%) entries with only 6/165 (3.6%) multi-page (0/44 on limits); each got mid- and end-of-article cards routing across the cluster and into Don’t Hire a Finish Carpenter to Carry Drywall. On Risk, 6 catastrophe-modeling guides (led by the complete guide) drove 34/65 (52.3%) entries with 0/34 multi-page; all 6 were wired into a 12-link reading loop (2 per guide) plus 2 bridges into the Sedgwick interview. Like Leave the Pots in the Water, both pathways now sit untouched on a 14-day grading clock.

    FOUR RECEIPTS · NOVEMBER 14–21, 2026
    How an Open Front Door Updated This Estate in One Week
    Every figure below traces directly to this week's live audits, outreach logs, and human session records.
    C1 · READER GARDENING (NOV 20)
    Bohdan Shkliarchuk (ToolsGavel) flagged stale Microsoft 365 prices. Verified $9.99/month Personal and $12.99/month Family (since Jan 16, 2025), swept all 3,914 published TM docs (3,699 posts, 215 pages), and fixed 2 posts plus PDFs and .md twins.
    C2 · SELF-MAINTAINED ENTRIES (NOV 20–21)
    Publish-first censuses ran across 5 series with sends completed for 95 WA AI, 34 AI Dev-Tools, 27 BC ESG, and 13 HFH Vendors; Judy Molnar’s 2 pre-publish edits shaped the Sedgwick interview.
    C3 · FOOTSTEPS BUILD ROOMS (NOV 14–21)
    856 engaged human sessions (30-second floor) across 7 sites showed 3,000+-second deep reads and low multi-page rates (9% TM, 15% HFH, 8% Risk) — driving 3 TM pricing pathways and 6 Risk cat-modeling guides on Nov 21 (14-day clock).
    C4 · PRIVATE VS. PUBLIC CONTRAST (NOV 16)
    Evaluated YouSpot‘s solo-CRM on Nov 16, 2026 and parked it: a private notes graph holds what you file; a maintained website holds what the world comes asking for.

    Private Filing vs. Public Demand

    That contrast explains why William evaluated a commercial second-brain product — YouSpot, via its AI-native solo-CRM — on November 16, 2026 and parked it. YouSpot connects a member’s own mailboxes, calendar, contacts, notes, and files into a personal graph scoped strictly to the signed-in user. The parking decision was architectural, not a critique of the product: a private notes system holds what you already touched and filed; the public estate holds what the outside world comes asking for, and keeps teaching you where your knowledge is incomplete.

    Where the Gardening Metaphor Bends

    Four seams keep the metaphor honest. First, most visitors don’t garden: the majority of those 856 human visitors read one guide (often past 3,000 seconds) and walk out without emailing a fix or opening a second room. Second, some traffic tramples: crawlers, scrapers, and noisy scanners hit the same doorways as readers, which is why Standing in the Middle and The Audience That Never Says Thanks keep origin server-log counts strictly separate from engaged human telemetry.

    Third, the gardener still decides what to plant: visitor demand proposes, the owner disposes. Reader tips are checked against Microsoft’s primary pages before editing 2 posts out of 3,914, and walking patterns highlight missing hallways rather than dictating every topic. Fourth, a brain anyone can read is also one competitors can read: every profile, corrected figure, and House PDF sits in the open for rivals and outside AI models alike. That openness is the bet — the compounding correction loop on the sidewalk outweighs keeping the shelves locked in a back room.
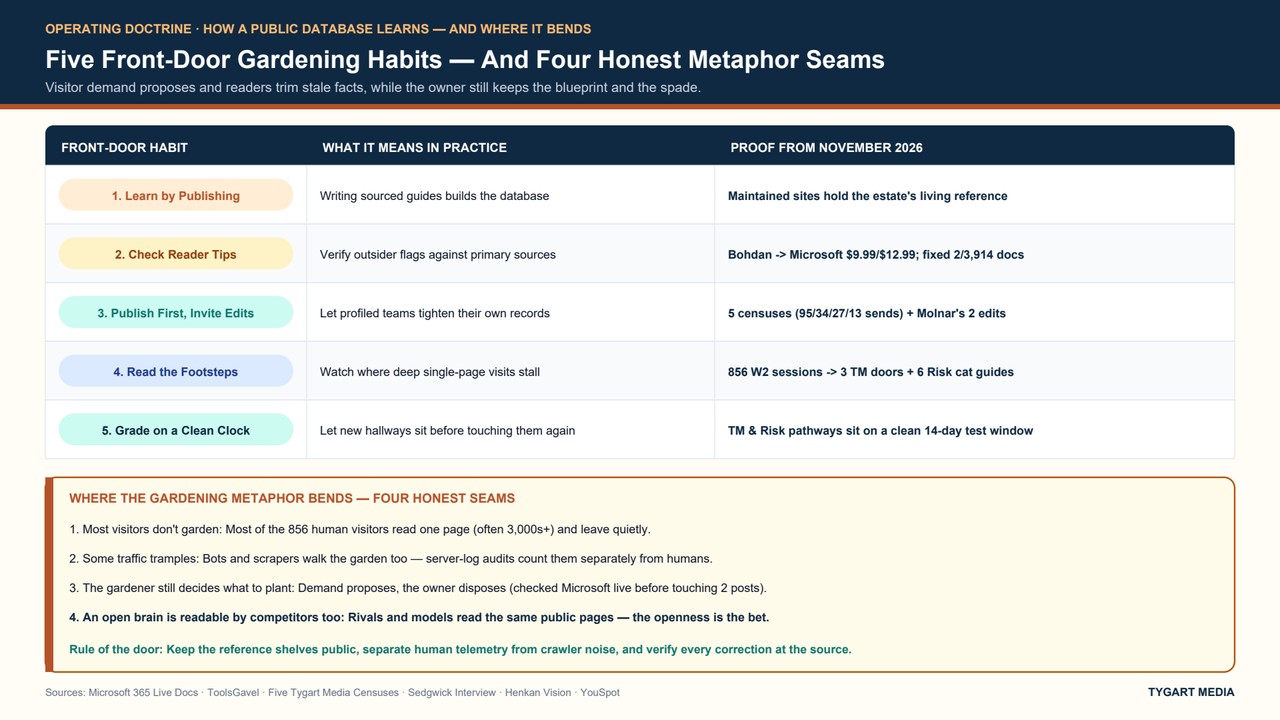
    Five Front-Door Gardening Habits paired with four honest seams where the gardening metaphor bends: most visitors do not garden, bots trample alongside humans, the owner decides what to plant, and an open brain is readable by competitors.
    Five front-door gardening habits — and the four seams where the metaphor bends.

    Keep your notes private when the job is personal memory. When the job is building durable domain authority, give the second brain a front door on the street, invite the people inside the data to fix what is wrong, watch where strangers stop and reach for the next shelf, and stay honest about the four places the garden still needs an owner’s hand.

    FRONT-DOOR REFERENCE WORK & AI CITATION RESTORATION · TYGART MEDIA
    We build and repair public reference estates through AI citation restoration — starting from live HTTP 200 URLs, verified sources, and real visitor paths. Review our bounded options on Tygart Media Pricing, or send us the hardest page on your site. We come from water damage — we open the front door, trace where readers stall or leave, and rebuild the rooms people actually came looking for.

    — Will Tygart, Tygart Media.
    Takeaway Edition
    Print the Essay & Tear-Out Front-Door Second Brain Card
    Keep the five front-door checks and verified reading map beside your desk.
  • Pay for Your Own Ticket: Running a Website From the Street, Like a Museum You Visit Yourself

    Pay for Your Own Ticket: Running a Website From the Street, Like a Museum You Visit Yourself

    Most people run their websites from the loading dock. They spend the week inside an admin back room, staring at database rows, preview links, and private dashboards that no reader, crawler, or citing AI agent will ever meet. From the back hallway, every room looks connected because you remember which folder you dropped it in. Walk out to the sidewalk and the building tells a different story.

    Working our sites strictly from the outside — public URLs and the WordPress REST API, honoring the uniform public interface Roy Fielding formalized for REST and the plain contract of HTTP semantics — is part of why the work stays honest. There is no privileged backstage view. What returns HTTP 200 from the street is the truth. Picture the site as a museum. From the sidewalk you check the entryway and the doors: can people get in, and do they understand what sits behind the wall? Inside, the work is curation: watch where visitors move piece to piece, see where friction sends them back to the curb for want of a second or third exhibit, then add, move, and connect rooms accordingly. The owner parks where everyone parks, comes through the same door, and pays for his own ticket.

    Two earlier pieces on this desk laid the threshold: Standing in the Middle forced bottom-up server truth to agree with top-down maps, and The Audience That Never Says Thanks measured how machines read our shelves without leaving a referrer behind. Until this week, the museum frame was still something I said aloud on a call. As of this morning, November 21, 2026, it has receipts and two live rooms attached.

    Printable Edition + Street-Walk Card
    Download Pay for Your Own Ticket (5-Page PDF)
    Includes both visual charts, the Page 5 Street-Walk Curation Card, and verified primary authorities.

    Half the Rooms Had No Hallway Leading In

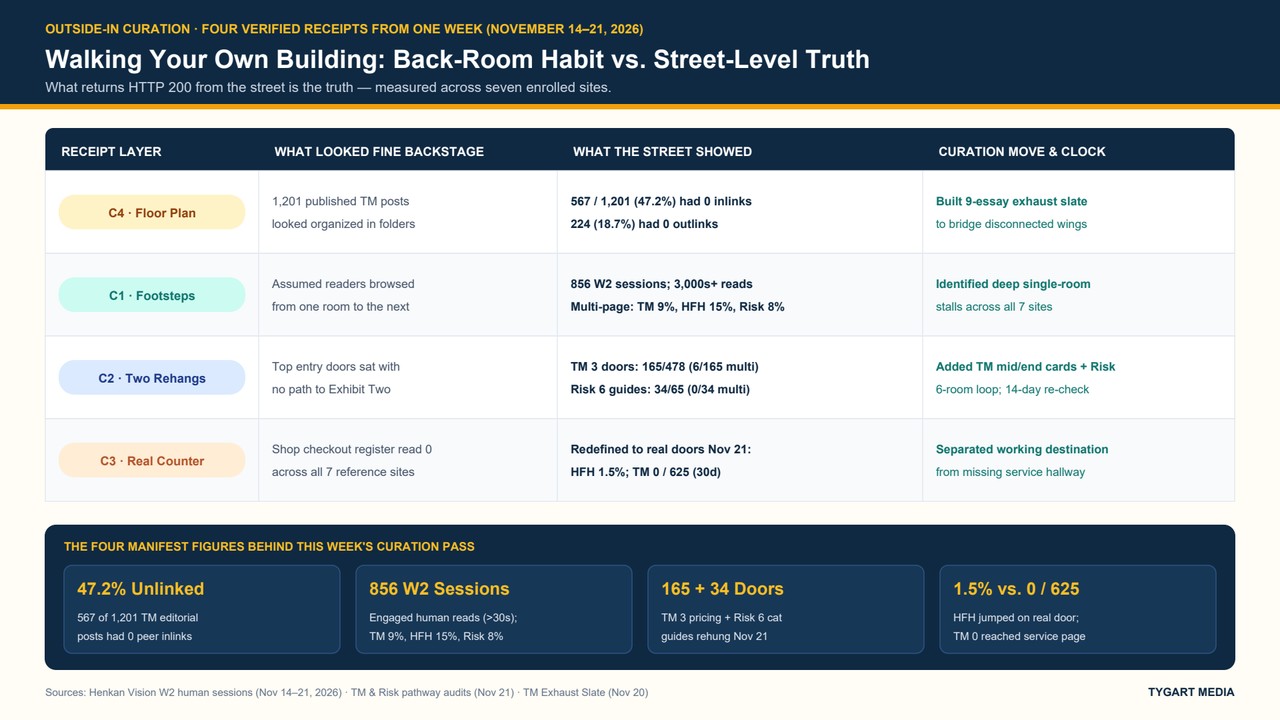
    Before you watch footsteps, check the floor plan. Yesterday, November 20, when we mapped tygartmedia.com to draw the nine-essay exhaust slate this piece closes, the numbers came back sharp: 567 of 1,201 editorial posts — 47.2% — had zero editorial inlinks from any peer article, and 224 (18.7%) had zero editorial outlinks either. We had hung careful work inside a museum where nearly half the rooms lacked a hallway leading in. Even siblings built from the same timber — The Quiet Door Into the Library and Factory Phil — stood in separate wings until we cut deliberate doorways between them.

    Then we watched real people inside the building. Over the first full week of Henkan Vision human telemetry (November 14–21, counting engaged visits past 30 seconds so the floor is real attention), our seven enrolled sites logged 856 engaged human sessions (478 Tygart Media, 224 Healthcare Facility Hub, 65 Risk Coverage Hub, 43 BC ESG, 36 Continuity Hub, 7 Restoration Intel, 3 Universal Commerce Protocol). Everywhere, one pattern dominated: the single-page deep read. Hour-long visits past 3,000 seconds on one page were common — 3,592 seconds on Healthcare Facility Hub, 3,565 on BC ESG, 3,558 on Risk Coverage Hub’s catastrophe-modeling guide, 3,555 on Tygart Media. People were not bouncing off the steps. They were studying one canvas for an hour and walking straight back to their cars. Multi-page rates sat at 42 of 478 (9%) on Tygart Media, 34 of 224 (15%) on Healthcare Facility Hub, and 5 of 65 (8%) on Risk Coverage Hub — yet when a fresh room did show the next door, readers took it: Leave the Pots in the Water drew an 845-second, 3-page walk straight out of the gate.

    Four-row street-level curation receipt chart contrasting back-room assumptions against verified telemetry across Floor Plan (567/1,201 or 47.2% unlinked), Footsteps (856 W2 human sessions; TM 9%, HFH 15%, Risk 8% multi-page), Two Rehangs (TM 165/478 + Risk 34/65), and Real Counter (HFH 1.5% immediately; TM 0/625 to service page).
    Back-room habits versus four verified street-level receipts from one week of outside-in curation.

    Two Galleries Rehung Before Lunch

    Growth, in this frame, is not chasing more people into the building. It is curating the best of what you have until people come for your reasons — clear sightlines and deliberate circulation, the same craft behind the Smithsonian exhibition guidelines and Google Search Central’s crawlable link guidance. This morning we rehung two live wings strictly from those footprints without rewriting a paragraph of working prose.

    On Tygart Media, three Claude pricing doors drove 165 of 478 Week 2 entries (34.5%): 95 on Claude Pro vs. Max, 44 on Claude Team Plan Usage Limits, and 26 on Claude Team Seat Pricing. Only 6 of 165 (3.6%) visited a second page (0 of 44 on usage limits). Today each door got a quiet mid-article and end-of-article path to the next exhibit — connecting the cluster and routing headroom buyers straight into Don’t Hire a Finish Carpenter to Carry Drywall.

    On Risk Coverage Hub, six catastrophe-modeling and model-governance guides drew 34 of 65 entries (52.3%) with 0 of 34 multi-page sessions despite 3,558-, 2,959-, and 2,951-second reads. Today all six rooms were wired into one reading loop (2 path links per guide, 12 total), plus 2 bridges to our Sedgwick chief claims officer interview, The Claim Is Decided in the First 24 Hours, placed only on the two guides where casualty litigation and claims AI genuinely fit — and left off the pure property-cat page where it did not. Neither rehang is a victory lap today; both stand for a 14-day test against their 42/478 and 5/65 baselines.

    FOUR RECEIPTS FROM ONE WEEK · NOVEMBER 14–21, 2026
    The Outside-In Ledger Behind the Museum Frame
    Every figure below comes straight from this week's live audits and human session records.
    C4 · UNCONNECTED ROOMS (NOV 20)
    567 of 1,201 editorial posts (47.2%) on tygartmedia.com had zero editorial inlinks when we drew the nine-essay slate (224, or 18.7%, had zero editorial outlinks).
    C1 · SINGLE-PAGE DEEP READS (NOV 14–21)
    856 engaged human sessions across seven sites in Henkan Vision (30-second floor). Hour-long single-page reads (3,000+ seconds) were common; multi-page rates sat at 42/478 (9%) TM, 34/224 (15%) HFH, and 5/65 (8%) Risk.
    C2 · TWO GALLERIES REHUNG (NOV 21)
    TM’s three Claude pricing doors (165/478 entries; 6/165 multi-page) each got mid-article and end-of-article paths. Risk’s six catastrophe guides (34/65 entries; 0/34 multi-page) were wired into one reading loop — both judged over 14 days.
    C3 · AIMING OUR OWN COUNTER (NOV 21)
    Redefining our counter from a shop checkout register to each site’s real destination moved HFH to 1.5% immediately at ICRA Readiness Check — and showed 0 of 625 TM sessions in 30 days had reached our service page.

    Pointing Our Own Counter at the Real Door

    The sharpest receipt this week was not a missing hallway — it was our own misreading of our own instrument. All week, the conversion counter across every site read 0. As we learned in Zero Miles Per Hour on the Generator, a sound instrument still reads zero when you bolt it to the wrong shaft. That error was ours, full stop. We had left a shop’s purchase register pointed at reference sites that sell nothing through a cart, while Henkan Vision faithfully showed us every deep human session and every stall in front of our eyes.

    This morning we redefined the counter to each site’s actual destination page. Two opposite truths jumped off the screen at once. On Healthcare Facility Hub, aimed at the ICRA Readiness Check, the counter moved immediately to 1.5%. On Tygart Media, aimed at our AI citation service page, it handed us a harder, cleaner truth: 0 of 625 sessions in 30 days had reached the service page at all. Before lunch, both sites looked identically frozen at zero. Standing on the street with an honest counter separated the room people already found from the hallway we still had to build.

    Where the Museum Metaphor Bends

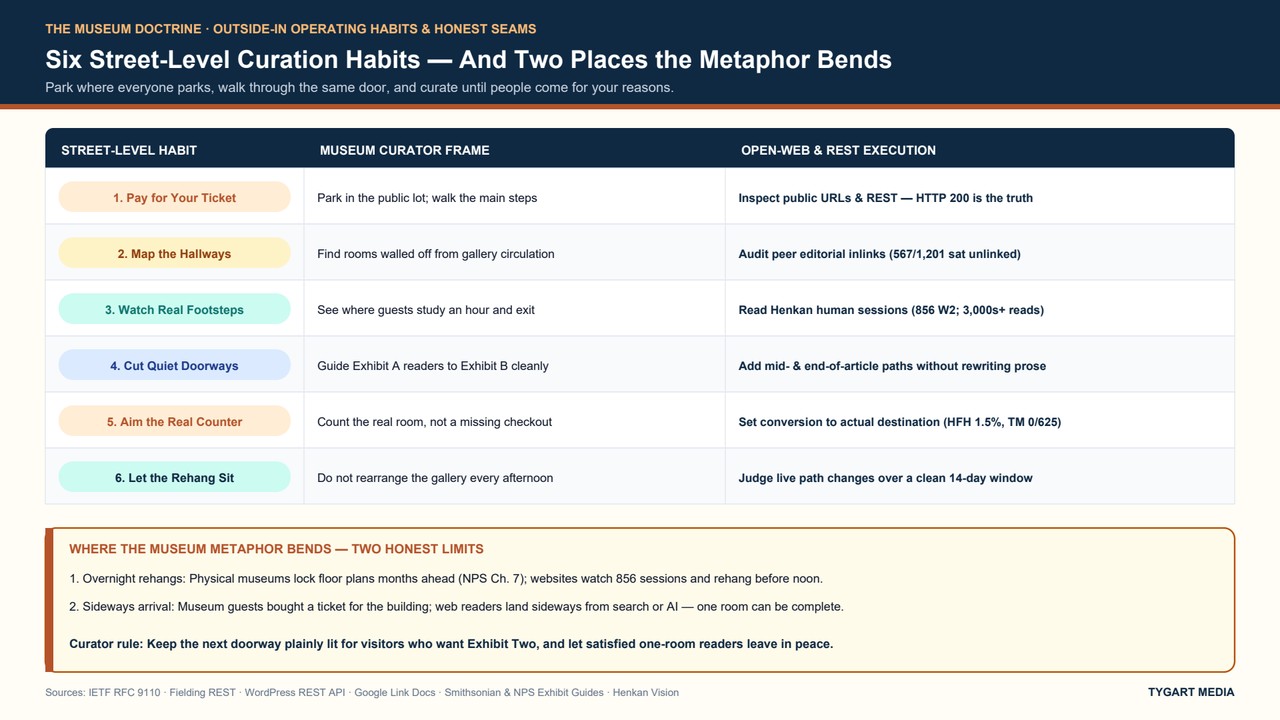
    Every good frame bends somewhere, and naming the seam keeps curation honest. First, a physical museum cannot watch each visitor’s path or rehang a room overnight — a website can. Physical teams lock traffic flow into blueprints months ahead, as the National Park Service Museum Handbook outlines; once drywall sets, a dead wing stays dead all season. We watched 856 sessions in a week and connected two galleries before noon — an advantage only if we resist fidgeting every afternoon and let the 14-day clock run.

    Second, a museum’s visitors bought a ticket on purpose for the whole building; a website’s visitors arrive sideways from a search result or an AI answer. Almost nobody climbs museum steps to read one footnote and leave. On the web, arriving sideways for one exact answer is normal — and often complete. An analyst who spends an hour on one treaty guide and closes the tab with the clause she needed did not fail your museum; your room worked. Good curation lights the doorway to Exhibit Two without nagging the satisfied one-room reader at the exit.

    Six Street-Level Curation Habits reference chart pairing museum curator habits with open-web REST execution (Pay for Your Ticket, Map the Hallways, Watch Real Footsteps, Cut Quiet Doorways, Aim the Real Counter, Let the Rehang Sit), plus two honest limits where the museum metaphor bends.
    Six outside-in museum curation habits — and the two seams where the metaphor bends on the web.

    That plain standard closes our nine-essay exhaust slate. From Factory Phil running dependable stock plastics to The Quiet Door Into the Library earning trust one room at a time, nothing here relies on noise. Park where everyone parks. Come through the same door. Pay for your own ticket. Trust what returns HTTP 200 from the street, point your counter at the real room, and curate the best of what you have until people come for your reasons.

    OUTSIDE-IN CURATION & AI CITATION RESTORATION · TYGART MEDIA
    We do AI citation restoration from the street — public URLs, HTTP 200 truth, and real visitor paths before changing a line of copy. Start with a bounded check on our pricing page or send us the worst mess you have. We come from water damage — we open the front door, check the hallways in daylight, and fix what the building actually needs.

    — Will Tygart, Tygart Media.
    Takeaway Edition
    Print the Essay & Tear-Out Street-Walk Curation Card
    Keep the five outside-in checks and Exhaust Slate capstone reading map beside your desk.
  • GA4 Exit Pages: Satisfied Exits vs. Abandoned Exits

    GA4 Exit Pages: Satisfied Exits vs. Abandoned Exits

    Related on Tygart Media: exit pages companion · bounce rate by time of day · engagement rate.

    GA4 shows you exit rate. It does not tell you whether that exit was a success or a failure. That distinction matters more than the number itself.

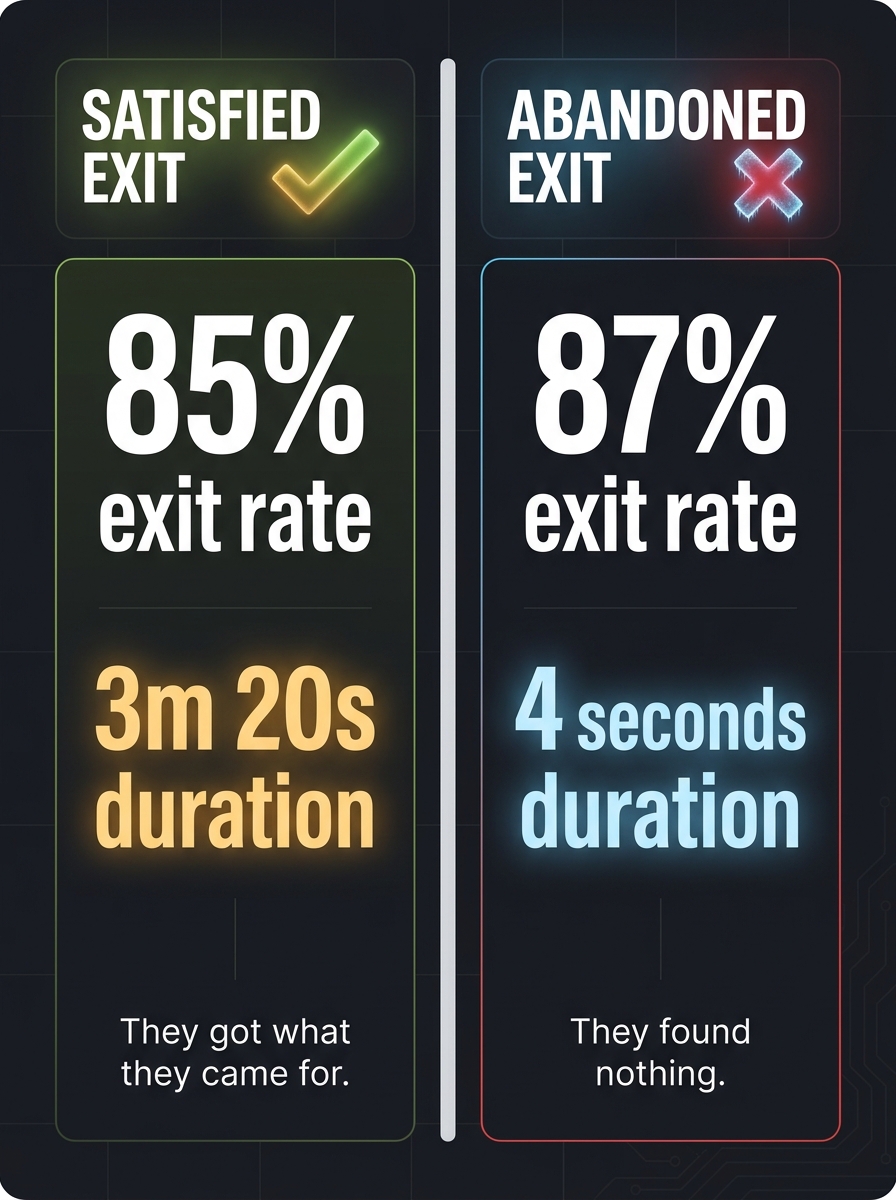
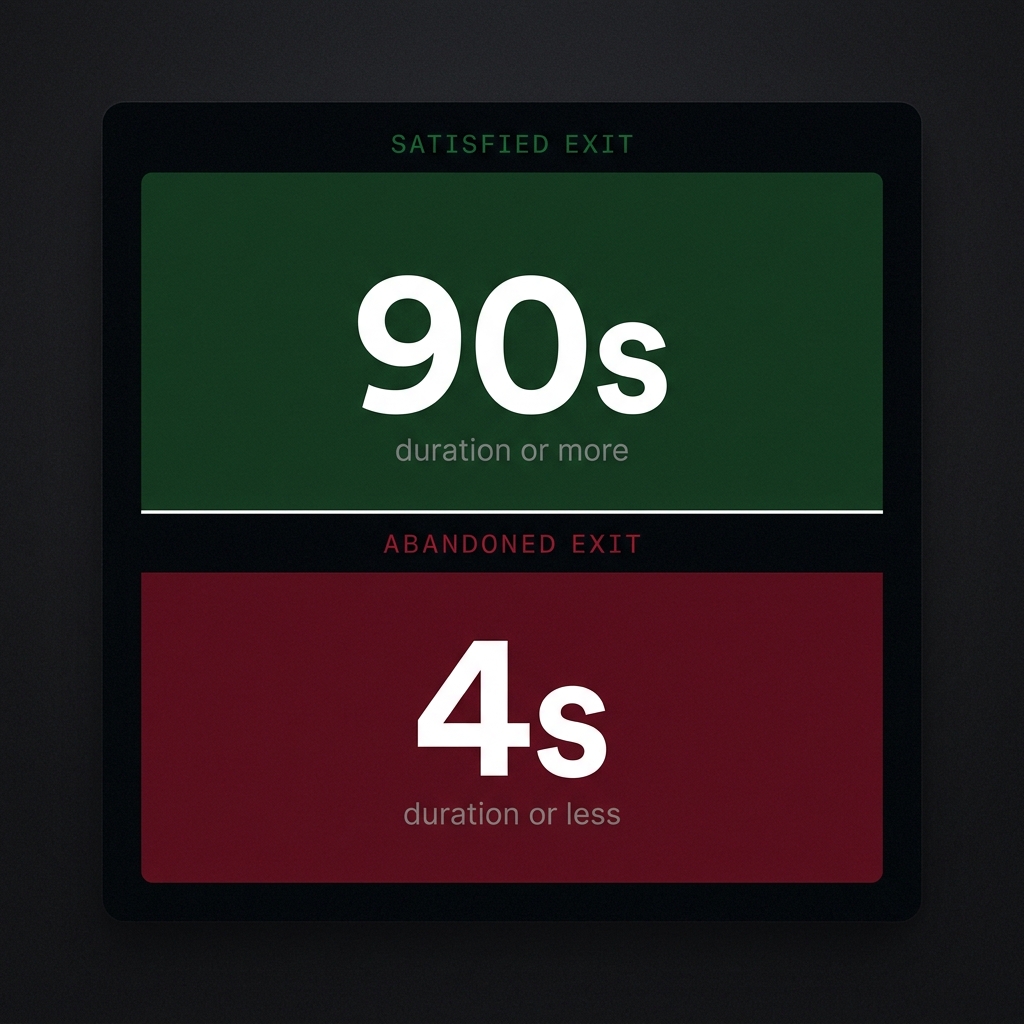
    An 85% exit rate on a page where users stay for three minutes means the page did exactly what it was supposed to do. Users arrived, found their answer, and left complete. An 85% exit rate with four seconds means the page failed immediately.

    Satisfied Exits vs Abandoned Exits

    Two cards: answer shown in overview versus optional click
    Satisfied exits vs abandoned exits.

    A satisfied exit has a high exit rate and high engagement duration — 90 seconds or more. The user read, completed their task, and left. Adding more CTAs to reduce the exit rate would interrupt a successful journey and make the page perform worse.

    An abandoned exit has a high exit rate and low engagement duration — under 30 seconds. The user arrived, found nothing useful, and left. This page needs attention: it is either attracting the wrong audience, delivering the wrong content, or failing to provide a next step.

    The diagnostic question for every high-exit-rate page is not “how do I reduce this?” It is “was this exit satisfied or abandoned?”

    The NYC Summer Internships Finding

    In a live audit on a real content site, the NYC Summer Internships guide showed an 85% exit rate with 3 minutes 20 seconds average duration. The first instinct — reduce the exit rate — would have been wrong. Users were spending over three minutes reading a comprehensive guide and leaving with the information they needed. The exit rate was a function of the page succeeding, not failing.

    Compare that to the same site’s homepage: 65% exit rate with 8-second duration. Lower exit rate, dramatically worse performance. The homepage was failing more users despite fewer exits.

    Dead-End Pages

    Seven cards naming common AI chatbot failure modes
    Dead-end pages.

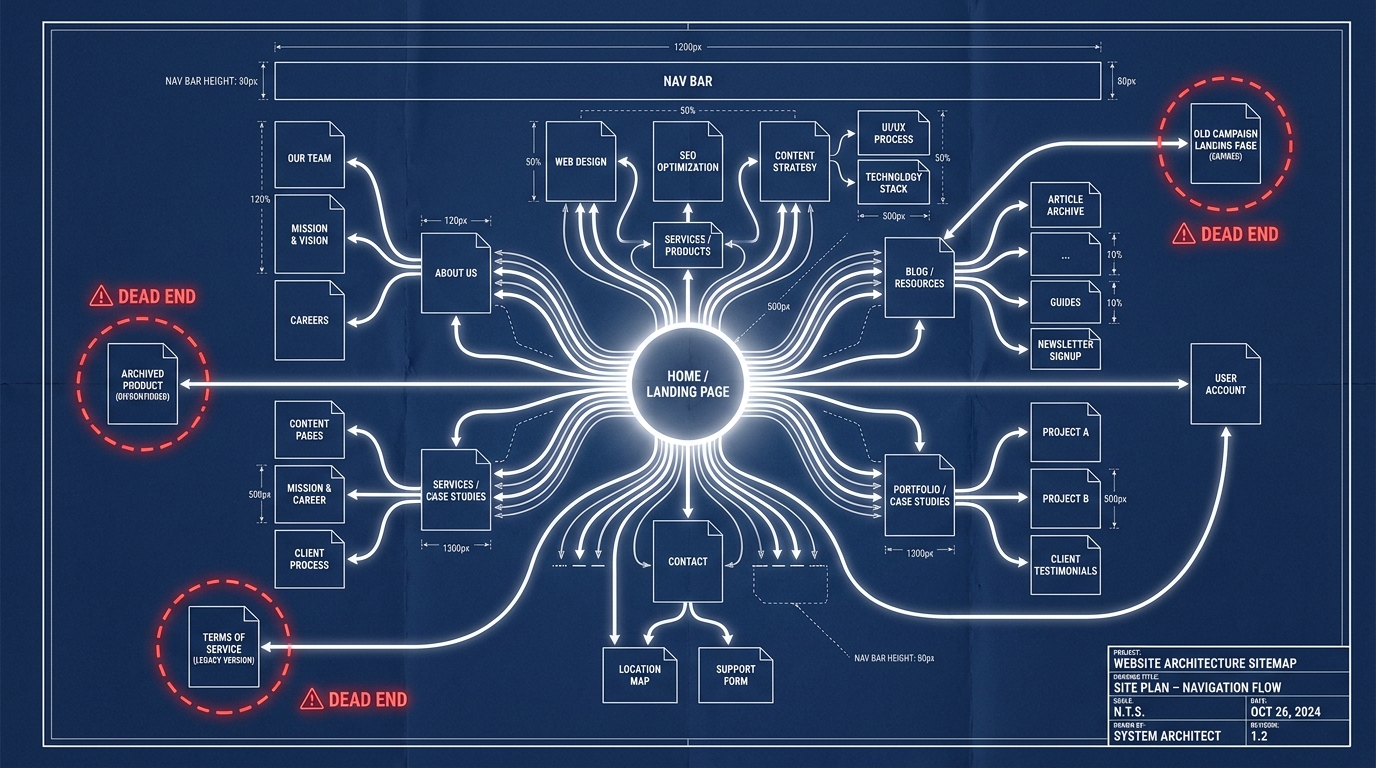
    A third pattern exists beyond satisfied and abandoned: the dead end. Users arrive with genuine interest, engage enough to stay, but then have nowhere to go next. No internal links, no navigation to adjacent topics, no next step. The exit is not because the page failed — the site architecture failed.

    Dead-end pages show moderate engagement duration and zero internal link click data. Adding one relevant internal link often produces measurable improvement in session depth without any content changes. It requires no developer, no design work, and no new content.

    The Internal Link Opportunity Map

    Three panels showing one problem, three options, one recommendation
    The internal link opportunity map.

    The most actionable output from an exit intelligence audit is a specific list of page pairings: which abandoned exit pages should link to which high-engagement destination pages. Google’s Analytics Advisor can generate these recommendations from your actual behavioral data — not guesswork about what users might want next.

    This analysis runs in one session using Claude-in-Chrome alongside Analytics Advisor. The methodology is packaged as the Books for Bots: GA4 Exit Intelligence Kit.

    Learn more about the GA4 Exit Intelligence Kit →

  • GA4 Exit Intelligence Kit: Analyze Exit Rates & Dead Ends

    GA4 Exit Intelligence Kit: Analyze Exit Rates & Dead Ends

    Aerial maze amber exit vs cold blue dead end

    BOOKS FOR BOTS — GA4 SERIES — BOOK 03

    GA4 Exit Intelligence Kit

    Where users leave your site — and what it means. Distinguish satisfied exits from abandoned ones, find your dead-end pages, and map your internal linking gaps.

    85% exit rate
    With 3m 20s duration — a satisfied exit, not a problem to fix
    COMING SOON — $27

    Not All Exits Are Failures

    A user who reads your guide for three minutes and then leaves got exactly what they needed. A user who hits your page and bounces in four seconds got nothing. GA4 treats them identically. This kit teaches you to tell the difference.

    Satisfied exit 85% 3m20s vs abandoned exit 87% 4 seconds

    FIELD FINDING — LIVE SESSION

    The NYC Summer Internships page has an 85% exit rate AND a 3m 20s average session. That is a satisfied exit. Adding CTAs to interrupt it would reduce performance, not improve it.

    90 seconds satisfied exit, 4 seconds abandoned exit

    Satisfied exit — man leaving library corridor through warm door

    Satisfied exit.

    Abandoned exit — man facing blank wall with no way out

    Abandoned exit.

    Website sitemap blueprint with dead-end pages circled in red

    What’s Inside

    • 7 copy-paste queries for Analytics Advisor — one session
    • Satisfied vs abandoned exit classification framework
    • Dead-end page audit — pages with zero internal link clicks
    • Homepage navigation effectiveness score
    • Internal link opportunity map — Advisor generates specific page pairings
    • Exit-to-content-gap mapping for abandoned pages

    What You Need

    • Claude-in-Chrome — free from Anthropic
    • Editor or Analyst access to a GA4 property
    • Analytics Advisor (BETA) enabled
    • 30–60 minutes

    THE KEY INSIGHT

    The internal link fix is the highest ROI action from this kit. No new content, no design changes, no developer. Add one sentence with a link on an abandoned exit page pointing to a relevant high-engagement page.

    Individual Kit — Instant PDF Download

    COMING SOON — $27

    No subscription.

    BUNDLE — ALL 6 KITS

    Get All 6 Kits for $97

    Every GA4 intelligence methodology in one purchase. Save $65.

    $162$97

    COMING SOON

    FREE STARTER

    Try Session 3 Free

    Seven queries revealing your ChatGPT vs Claude vs Copilot split in under 30 minutes. No purchase required.

    COMING SOON — FREE

    Validated on live GA4 properties. April 2026.

  • WordPress SEO Audit Template — 60-Point Notion Checklist

    WordPress SEO Audit Template — 60-Point Notion Checklist

    The same audit framework we use across a 27-site WordPress network — packaged for any site owner to run themselves.

    Why Most WordPress Sites Have Invisible Problems

    Comparison of Claude how-to fit versus local service page fit for assistants
    Why most WordPress sites have invisible problems.

    A WordPress site can look completely healthy and still be hemorrhaging organic traffic. Thin content flying under the radar. Orphan pages with no internal links. Schema that was never added. Category pages with no descriptions. Metadata that was written once in 2019 and never touched. None of this shows up as an error. None of it triggers an alarm. It just quietly costs you rankings, month after month.

    A proper audit catches all of it. The problem is that a proper audit from an agency costs more than most site owners want to spend on a site they think is probably fine. This template lets you run the same audit yourself — in the same Notion framework we use across 27 managed sites — for $29.

    What’s Inside

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What’s inside.
    • 60+ checkpoints across 6 audit categories — comprehensive enough to find real problems, organized enough to not be overwhelming
    • Technical SEO: crawlability, indexation, page speed signals, mobile rendering, Core Web Vitals basics, canonical tags, redirect chains
    • Content quality: thin content flags, duplicate content issues, missing meta descriptions, title tag optimization, heading structure
    • Schema and structured data: what types are present, what is missing, priority gaps by page type
    • Internal linking: orphan pages, link equity distribution, anchor text patterns, hub-and-spoke gaps
    • AI search visibility: entity structure, speakable content, GEO signals, LLMS.txt, FAQPage coverage
    • Priority scoring matrix: rank every finding by business impact and implementation effort — so you know exactly where to start
    • Remediation tracker: log findings, assign owners, track fix status over time

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who this is for.

    WordPress site owners who want to understand what is actually happening with their site before paying an agency to tell them. Marketers who manage WordPress properties and need a structured audit framework they can run repeatably. Freelancers and consultants who want a professional audit template they can brand and use with clients. Business owners who suspect their site has problems but do not know where to look.

    What Happens After the Audit

    The template gives you a prioritized fix list. You can implement the fixes yourself, hand them to a developer, or use them as the brief for an agency engagement. Every finding maps to a specific action — nothing is vague. And because the template lives in Notion, you can re-run it quarterly and track your progress over time.

    Related on Tygart Media: replace SEO agency kit · information density · taxonomy architecture.

    Frequently Asked Questions

    Do I need technical knowledge to use this?

    Basic WordPress familiarity is helpful. You should know how to navigate the WordPress admin, use a plugin like Yoast or Rank Math, and read your Google Search Console. The template explains what to look for at each checkpoint — you do not need to be an SEO expert going in.

    How long does a full audit take?

    Under two hours for a typical business site of 50 to 200 pages. Larger sites or sites with complex technical setups will take longer. The template is designed to be completable in a single focused session.

    Can I use this for client sites?

    Yes. The template is yours to use however you like after purchase. Many freelancers and consultants use it as their standard audit deliverable — white-label it, add your branding, charge accordingly.

    WordPress SEO Audit Template

    $29

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

  • Cross-Pollination Content Strategy for Multi-Site SEO

    Cross-Pollination Content Strategy for Multi-Site SEO

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench
    What Is Cross-Pollination Content Strategy?
    Cross-pollination is a multi-site content strategy where your highest-ranking authority pages on one domain generate locally-relevant variant articles on sister sites — each variant covering the same topic from a different geographic or audience angle, and each naturally linking back to the original authority page. The result is a network of content that reinforces each other’s authority instead of competing.

    Most multi-site operators make one of two mistakes: they either publish identical content across their site family (duplicate content penalty waiting to happen) or they treat each site as a silo with no connection to the others (wasted authority potential).

    Cross-pollination threads the needle. The Beverly Loan page ranking for “Rolex watch collateral loans” becomes the hub. New York Loan publishes “Rolex collateral loans in Manhattan” — genuinely different content for a different market — that links naturally to Beverly’s page. Palm Beach publishes the Florida angle. Each variant earns its own rankings and passes authority back to the hub.

    We built and executed this strategy for the Borro family of luxury lending sites. We’ve now productized it.

    Who This Is For

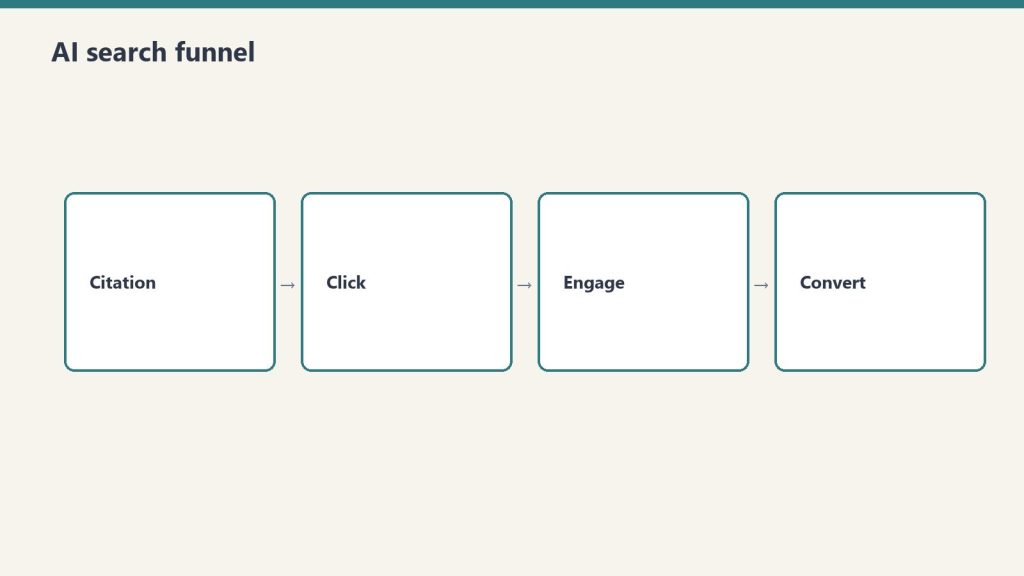
    Four-stage funnel: citation, click, engage, convert
    Cross-pollination content strategy — who it is for.

    Operators managing 2+ WordPress sites that share a business umbrella, a topic cluster, or a geographic network — and who want to build content that compounds across domains instead of starting from zero on each one.

    What the Strategy Delivers

    Comparison of Claude how-to fit versus local service page fit for assistants
    What the cross-pollination strategy delivers.
    • Authority page identification — DataForSEO scan of all sites in your family to find the highest-ranking pages by domain and topic cluster
    • Variant architecture — Mapping which authority pages generate variants on which sister sites, avoiding duplication and maximizing geographic or audience differentiation
    • Variant article writing — Locally-relevant articles (800–1,200 words each) with genuine local intelligence, not just search-replaced location names
    • Natural interlinking — Each variant links to the hub authority page in context, not in a footer link farm
    • Notion log — All executed clusters logged to prevent future duplication across sessions

    What We Deliver

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What we deliver from a cross-pollination content system.
    ItemIncluded
    DataForSEO authority page scan across all sites in family✅
    Cross-pollination map (which pages spawn which variants)✅
    First cluster execution (5 variant articles)✅
    Natural interlinking injection on all variants✅
    Notion execution log (prevents duplicate work)✅
    Ongoing cluster playbook for independent execution✅

    Are Your Sites Competing With Each Other or Compounding?

    Tell us the URLs of the sites in your family. We’ll pull a quick authority page scan and show you the first 3 cross-pollination opportunities.

    → will@tygartmedia.com

    Email only. No commitment to reply.

    Related on Tygart Media: AEO content cluster · information density · taxonomy architecture.

    Frequently Asked Questions

    Isn’t publishing similar content across sites a duplicate content risk?

    Only if the content is actually duplicated. Cross-pollination variants are genuinely different articles — different geographic market, different audience angle, different local entities and examples. They cover the same topic the way two local news outlets cover the same story: same subject, different perspective.

    How many sites do you need to run a cross-pollination strategy?

    A minimum of 2 sites sharing a topic cluster. The strategy compounds with more sites — a 4-site family generates significantly more interlinking opportunity than a 2-site pair.

    Does this work for geographically separate markets or topic-based site families?

    Both. Geographic families (same service, different cities) are the clearest use case. Topic-based families (sites covering different aspects of a shared industry) also work well — the variant logic is audience-based rather than location-based.

    Last updated: April 2026

    Visual summary

    Cross Pollination Sister Sites

    About this image. This image is part of the Article Hero Images collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication.

    • Format: WEBP
    • Collection: Article Hero Images
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress
  • Taxonomy Architecture: How Category Design Drives SEO

    Taxonomy Architecture: How Category Design Drives SEO

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Taxonomy Architecture: The deliberate design of a site’s category and tag classification system before content is written — treating content organization as infrastructure rather than an afterthought.

    Most WordPress sites treat categories the way most people treat junk drawers. Useful enough to have. Never really organized. Things get thrown in, labels get reused, and over time the whole system becomes a maze that nobody — human or machine — can navigate cleanly.

    This is a costly mistake, and it is invisible until you look at a site’s ranking trajectory and realize that topical authority is not accumulating anywhere.

    The sites that rank for clusters of related keywords — not just a single lucky post — almost always have one thing in common: a deliberate taxonomy architecture. Categories and tags that were designed before the first post was written. A system that treats content classification as infrastructure, not filing.

    What Taxonomy Actually Does for Search

    Four-stage funnel: citation, click, engage, convert
    What taxonomy actually does for search.

    A taxonomy, in the WordPress context, is the classification system that organizes your content. Categories define the major topical areas of your site. Tags define the more granular topics, formats, audiences, and themes that cut across categories.

    From a search engine’s perspective, taxonomy does two things. First, it creates topic signals at the category level. When a category page has many posts all covering different angles of the same subject, the category becomes a topical cluster — the machine observes significant depth on this subject and attributes topical authority accordingly.

    Second, it creates semantic connectivity through tags. A tag that appears across multiple categories signals that a topic is cross-cutting — relevant to multiple contexts — and that this site covers it from multiple angles. Neither signal accumulates if the taxonomy is a junk drawer.

    The Architecture Decision That Precedes Everything

    Comparison of Claude how-to fit versus local service page fit for assistants
    The architecture decision that precedes everything.

    Good taxonomy design starts before content planning, not after it. If you plan content first and then figure out which categories to put it in, you end up with categories that reflect what you happened to write rather than categories that map to how your audience thinks about the subject.

    The correct sequence:

    Step 1: Map the Topical Territory

    What are the three to five major subject areas that this site will be authoritative on? These become your primary categories. Broad enough to contain many posts, specific enough to signal a clear topical focus.

    Step 2: Map the Sub-Topics

    Within each primary category, what are the recurring sub-topics that individual posts will address? These may become sub-categories or tags, depending on expected content volume.

    Step 3: Design the Tag Taxonomy

    Tags should serve three functions: topic modifiers (specific angles within a broad category), format signals (FAQ, guide, comparison, case study), and audience signals (who the post is for). A well-designed tag set creates a three-dimensional classification system that makes content findable from multiple directions.

    Step 4: Write Content to Fill the Architecture

    Now you write. Each post is assigned to a category and a tag set before the first word is drafted. The classification is part of the brief, not an afterthought.

    What a Healthy Taxonomy Looks Like

    A healthy taxonomy has several observable characteristics. Balance — no single category is dramatically overpopulated relative to others. Intentionality — every category has a description, not the default empty field but an editorial statement about what this category covers and who it is for. Specificity — tags are meaningful at a granular level, not just broad topic umbrellas that apply to everything on the site. Stability — the category structure does not change with every content sprint; topical signals need time to accumulate.

    The Hub-and-Spoke Model in Practice

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Hub-and-spoke taxonomy in practice.

    The most effective category architecture follows a hub-and-spoke model. Each category is a hub. The posts within that category are the spokes. The category archive page becomes the authoritative landing page for the entire topical cluster.

    Posts within a category link to each other where relevant. They all exist under the same category URL. When the category page earns authority — through topical depth signals, through external links, through engagement — it distributes that authority to the posts beneath it. A post that belongs to a well-populated, well-maintained category benefits from being in that category.

    Taxonomy Debt: The Hidden SEO Tax

    Sites that ignored taxonomy design accumulate taxonomy debt — a mounting structural problem that silently suppresses rankings. The symptoms: posts tagged with one-off tags that never appear more than once or twice, categories with two posts each because someone created a new one instead of using an existing one, category pages with no description and no editorial identity, tags that duplicate category names and create competing signals.

    Fixing taxonomy debt is a maintenance operation. It requires auditing the existing classification system, merging redundant tags, consolidating thin categories, writing category descriptions, and reassigning posts to their correct homes. It is unglamorous work. It also consistently produces ranking improvements because scattered topical signals suddenly consolidate.

    The Compound Effect

    Taxonomy architecture matters because it determines whether your content investment compounds or disperses. Every post you publish is a bet that the topic it covers is worth covering. If that post is correctly classified within a coherent taxonomy, it adds to the authority of its category cluster. The cluster grows stronger with each post.

    If that post is incorrectly classified — or not classified at all — it sits in isolation. It may rank on its own merit, or it may not. But it does not strengthen anything around it.

    Content infrastructure compounds. Content without infrastructure disperses.

    Build the architecture first. Then fill it.

    Related on Tygart Media: information density · SEO vs social impressions · citing sources for E-E-A-T.

    Frequently Asked Questions

    What is WordPress taxonomy and why does it matter for SEO?

    WordPress taxonomy is the classification system that organizes content through categories and tags. For SEO, a well-designed taxonomy creates topical clusters that signal authority on specific subjects to search engines, helping sites rank for clusters of related keywords rather than just individual posts.

    What is topical authority and how does taxonomy build it?

    Topical authority is the degree to which a search engine recognizes a site as a reliable, comprehensive source on a specific subject. Taxonomy builds topical authority by grouping related posts under shared category structures, allowing depth signals to accumulate at the cluster level.

    What is taxonomy debt?

    Taxonomy debt is the accumulated structural cost of neglecting content classification — one-off tags, thin categories, duplicate classification systems, missing category descriptions, and misclassified posts. Fixing it consolidates scattered topical signals and typically produces ranking improvements.

    What is the hub-and-spoke model for WordPress SEO?

    The hub-and-spoke model treats each category as a hub and the posts within it as spokes. The category archive page becomes the authoritative landing page for the topical cluster, and authority earned at the hub level distributes to individual posts within it.

    How should you design a WordPress category architecture?

    Design in four steps: map the major topical areas that become primary categories, identify recurring sub-topics for secondary classification, design a tag taxonomy covering topic modifiers and audience signals, then write content to fill the architecture. Classification should be defined before the first post is drafted.

    Related: The full infrastructure model behind this approach — Your WordPress Site Is a Database, Not a Brochure.

  • WordPress Site Database: Why It Beats a Static Brochure

    WordPress Site Database: Why It Beats a Static Brochure

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    WordPress as a Database: Treating every WordPress post as a structured content record with queryable fields — taxonomy, schema, meta, internal links, and freshness signals — rather than a static page in a digital brochure.

    Most businesses treat their WordPress site like a brochure — something you print once, hand out, and update when the phone number changes. That mental model is costing them rankings, traffic, and revenue. The sites that win in search treat WordPress for what it actually is: a structured database of content records, each one a queryable, indexable, linkable data object.

    This distinction is not semantic. It changes everything about how you build, maintain, and scale a content operation.

    The Brochure Mindset (And Why It Fails)

    A brochure exists to describe. It has a homepage, an about page, a services page, and a contact form. It gets built once and left. Updates happen when someone complains that the address is wrong or the logo changed.

    Search engines do not care about brochures. They care about signals — freshness, depth, internal link structure, topical coverage, entity density, schema markup. A brochure has none of these things because a brochure was never designed to be read by a machine.

    The brochure mindset produces sites with a handful of published posts, no category structure, missing meta descriptions, zero internal linking, and content that was written once and never touched again. These sites rank for almost nothing, and the business owner wonders why.

    The Database Mindset (How Search Winners Think)

    When you treat your site as a database, every post is a record. Every record has fields: title, slug, excerpt, categories, tags, schema, internal links, author, publish date, last modified date. Every field matters. Every field is an opportunity to send a signal.

    A database mindset produces sites where:

    • Every post has a clean, keyword-rich slug
    • Every post has a meta description written for both humans and machines
    • Categories are not random buckets — they are a deliberate taxonomy that maps to how search engines understand topical authority
    • Tags are not afterthoughts — they are semantic connectors between related records
    • Internal links are not random — they form a hub-and-spoke architecture that concentrates authority where it matters
    • Schema markup tells machines exactly what type of content each record contains

    This is not a content strategy. This is content infrastructure.

    What Changes When You Adopt the Database Model

    Publishing Becomes Systematic, Not Creative

    You are not waiting for inspiration. You are filling gaps in a content map. Keyword research tools show you what topics exist in near-miss positions — those are content records waiting to be written. You write them, optimize them, and push them live. Repeat.

    Taxonomy Design Becomes the First Decision

    Before you write a single post, you map your category architecture. What are the major topical clusters? What are the sub-clusters? How do they relate? This is a database schema design exercise, not a content brainstorm.

    Every Post Connects to Every Relevant Post

    Orphan pages — posts with no internal links pointing to them — are database records that no one can find. The crawler hits a dead end. The reader hits a dead end. Internal linking is the JOIN statement that connects your records into a coherent knowledge graph.

    Freshness Becomes a Maintenance Operation

    A database record goes stale. You run an audit. You identify which records have not been updated in over a year, which records are missing fields, which records have thin content. You update them systematically, the same way a database administrator runs maintenance queries.

    The Practical System for Solo Operators

    You do not need a team of writers to run a database-model content operation. You need a system with four components:

    1. A Keyword Map

    Pull your target keywords, cluster them by topic, assign each cluster to a category, and identify which posts need to be written for full coverage. This is your content schema — the blueprint before anything gets built.

    2. A Publishing Pipeline

    Every article moves through the same stages: write, SEO-optimize, add structured data, assign taxonomy, add internal links, publish, verify. The pipeline is the same whether you are publishing one article or one hundred. Consistency is the point.

    3. An Audit Cadence

    Every quarter, run a site-wide audit. Identify gaps: missing meta descriptions, thin posts, posts with no internal links, categories with no description, tags that have drifted from your taxonomy design. Fix them systematically.

    4. A Freshness Protocol

    Every post over 12 months old gets reviewed. Some get minor updates. Some get full rewrites. Some get merged into stronger posts. The point is that the database never goes fully stale.

    Why This Matters More Now

    AI search systems — Google’s AI Overviews, Perplexity, and other generative search tools — are essentially running queries against the web’s content database. They are looking for well-structured, authoritative, entity-rich records that directly answer the question being asked.

    A brochure site does not get cited by AI. A database site does.

    When your posts have clean schema markup, speakable metadata, FAQ sections structured as direct answers, and authoritative entity references, you are making your records machine-readable in the way AI search systems prefer. You are not just optimizing for the ten blue links. You are building citations in a world where the search result is increasingly a synthesized answer pulled from the best-structured sources available.

    The Mental Shift That Precedes Everything

    Your WordPress site is not a place people visit. It is a dataset that machines query and humans consult.

    Every time you publish a post without a meta description, you are leaving a required field blank. Every time you publish a post with no internal links, you are inserting an orphan record into your database. Every time you ignore your taxonomy architecture, you are letting your schema drift.

    A well-maintained database compounds. Records reference each other. Authority accumulates. Coverage expands. Machines learn to trust the source.

    A brochure just sits there and ages.

    Build the database.

    Frequently Asked Questions

    What is the difference between a brochure website and a database website?

    A brochure website is static, rarely updated, and built for human readers only. A database website treats every page and post as a structured content record with fields that send signals to search engines and AI systems — including taxonomy, schema markup, meta descriptions, internal links, and freshness signals.

    Why does taxonomy matter for WordPress SEO?

    Taxonomy — your categories and tags — is the organizational architecture that tells search engines what topics your site covers and how they relate. A deliberately designed taxonomy creates topical clusters that concentrate authority around your key subjects, improving rankings across the entire cluster.

    How often should I update my WordPress content?

    Posts over 12 months old should be reviewed for freshness and accuracy. Thin posts should be expanded or merged. The goal is a site where every published record is complete, current, and connected to related content.

    What is schema markup and why does it matter?

    Schema markup is structured data in JSON-LD format that tells machines exactly what type of content a page contains. It improves how content appears in search results and increases the likelihood of being cited by AI search systems.

    What does internal linking do for SEO?

    Internal links connect your content records so search engines can understand your site architecture and distribute authority across posts. Posts with no internal links are orphans — they receive no authority from the rest of your site.

    How does treating WordPress as a database improve AI search visibility?

    AI search systems query the web looking for well-structured, authoritative content that directly answers questions. Sites with schema markup, FAQ sections, entity-rich prose, and clean taxonomy are more likely to be cited in AI-generated answers than sites with thin, unstructured content.

    Related: If this reframe resonates, the companion piece goes deeper on the quality of reach — Why SEO Impressions Beat Social Impressions Every Time.

    Visual summary

    Editorial illustration for Your Website Is a Database, Not a Brochure - Tygart Media AI-generated visual
    AI-generated editorial illustration — Vertex AI Imagen 4 Standard

    About this image. This image was generated by Google’s Vertex AI Imagen 4 model as the featured visual for Your Website Is a Database, Not a Brochure. Every image in the Tygart Media visual library is AI-generated, converted to WebP for optimal performance, and enriched with IPTC/XMP metadata for search engine discoverability.

    • Model: Vertex AI Imagen 4 Standard (imagen-4.0-generate-001)
    • Format: WebP (quality 90)
    • Aspect Ratio: 16:9
    • Metadata: IPTC/XMP injected (title, description, creator, rights, location)
    • Creator: Tygart Media — tygartmedia.com

    Part of The Studio collection — AI-generated visuals powering the Tygart Media content engine.

  • Internal Link Mapping: A Complete Step-by-Step SEO Guide

    Internal Link Mapping: A Complete Step-by-Step SEO Guide

    The Machine Room · Under the Hood

    What is internal link mapping? Internal link mapping is the process of auditing, visualizing, and strategically planning the internal links between pages on a website. It creates a navigational architecture that helps both search engines and users move efficiently through your content — and directly influences how Google distributes PageRank across your site.

    Let me paint you a picture. Imagine Google’s crawler shows up to your website like a delivery driver in an unfamiliar city. No GPS. No street signs. Just vibes and whatever roads happen to be in front of them. That’s what your website looks like without a solid internal link map — a confusing maze where some pages get visited constantly and others quietly rot in a corner, never seen by anyone, including Google.

    Internal link mapping is the process of actually drawing the map. And once you see the map, you can’t unsee the problem.

    What Internal Link Mapping Actually Is (Not the Boring Version)

    Every page on your website is a node. Every internal link is a road between nodes. An internal link map is just the visualization of all those roads — which pages link to which, how many links each page receives, and crucially, which pages are orphaned (no roads in, no roads out).

    When Google crawls your site, it follows those roads. Pages that get linked to from many places get crawled more often, indexed faster, and treated as more authoritative. Pages buried three clicks deep with one lonely inbound link? Google eventually finds them — but it doesn’t think they matter much.

    Here’s the part that gets interesting: PageRank — Google’s foundational signal for evaluating page authority — flows through internal links. You have a fixed amount of it across your domain. Internal linking is how you choose to distribute it. A bad internal link structure is essentially leaving PageRank sitting in a bucket on your best pages while your ranking-ready content starves for authority.

    What Does an Internal Link Map Actually Look Like?

    A basic internal link map is a table or visual diagram showing:

    • Source page — the page that contains the link
    • Destination page — where the link goes
    • Anchor text — the clickable text used
    • Link depth — how many clicks from the homepage to reach that page
    • Inbound link count — how many pages link to this destination

    At scale, this becomes a graph. Tools like Screaming Frog or Sitebulb will generate a visual spider diagram of your entire site structure. For most sites under 500 pages, a simple spreadsheet works just fine. The goal isn’t to make art — it’s to see what’s actually connected to what.

    The ugly truth that usually surfaces: most sites have 20% of their pages receiving 80% of their internal links — usually the homepage and a few top-nav pages. Meanwhile, the blog posts you actually want to rank? Three inbound links between them. From 2019.

    How to Build an Internal Link Map (Step by Step)

    You don’t need expensive tools for a working internal link map. Here’s the straightforward version:

    1. Crawl your site. Use Screaming Frog (free up to 500 URLs), Sitebulb, or even Google Search Console’s coverage report. Export all internal links: source URL, destination URL, anchor text.
    2. Count inbound links per page. Sort the destination column and count how many times each URL appears. Pages with zero inbound links are orphans. Pages with one are nearly orphans. Flag both.
    3. Identify your high-priority targets. These are the pages you want to rank — your best content, service pages, money pages. How many inbound internal links do they have? If the answer is fewer than five, that’s your problem right there.
    4. Map topic clusters. Group your content by topic. Every topic cluster should have a pillar page that receives internal links from all related posts. Every related post should link back to the pillar. This creates a hub-and-spoke structure that Google reads as topical authority.
    5. Identify anchor text patterns. Are you using descriptive, keyword-rich anchor text? Or generic phrases like “click here” and “read more”? Anchor text is a ranking signal. “Internal link mapping guide” is better than “this article.”
    6. Fix and document. Create a link injection plan — a spreadsheet of which pages need new internal links added and what the anchor text should be. Execute it methodically.

    One pass through this process typically surfaces dozens of quick wins — pages that are one or two good internal links away from ranking significantly better.

    The Most Common Internal Link Mistakes (That Are Quietly Killing Your Rankings)

    Orphan pages. These are pages with no internal links pointing to them. They exist, technically, but Google either doesn’t know about them or doesn’t think anyone cares about them. Both outcomes are bad. Orphan pages account for a surprising percentage of most sites’ content — often 15-30%.

    Over-linking the homepage. Every page on your site already links to your homepage through the logo/nav. You don’t need additional contextual homepage links buried in body copy. That PageRank you’re wasting on the homepage? Redirect it to something that needs help ranking.

    Generic anchor text at scale. “Click here,” “learn more,” “read this post” — all wasted signal. Use the actual topic phrase as anchor text. It helps Google understand what the destination page is about, and it’s one of the easiest ranking signal improvements you can make without touching the page itself.

    Flat site architecture. Every page is three clicks or fewer from the homepage — that’s the goal. Deeper pages get crawled less frequently. If your blog archives push important posts six or seven levels deep, Google will find them eventually, but won’t prioritize them.

    Ignoring older content as a link source. Your highest-traffic pages — often older posts that have earned backlinks over time — are PageRank goldmines. Adding a single, contextual internal link from a high-traffic older post to a newer post you want to rank is one of the highest-ROI moves in SEO. Most people never do it.

    Tools for Internal Link Mapping

    Screaming Frog SEO Spider — The industry standard crawler. Free up to 500 URLs, paid license for larger sites. Exports a full internal link report and can generate site architecture visualizations. For most agencies and small businesses, this is the right starting point.

    Sitebulb — More visual than Screaming Frog, better for client presentations. Built-in link graph visualizations make it easier to spot cluster problems at a glance.

    Google Search Console — The Links report shows you both internal and external links Google has discovered. It won’t show you everything, but it’s free and gives you Google’s actual view of your link structure.

    Ahrefs or Semrush — Both have internal link audit tools built into their site audit modules. If you’re already paying for one of these platforms, use the built-in internal link analysis before adding another tool.

    A spreadsheet — Underrated. For sites under 100 pages, a manually maintained internal link spreadsheet is often the most actionable format. The point isn’t the tool — it’s having a documented plan you actually execute.

    How Internal Link Mapping Fits into a Broader SEO Strategy

    Internal link mapping doesn’t exist in isolation. It’s one layer of a three-part site architecture strategy:

    The topical authority layer — defined by your content clusters — tells Google what your site is about and what topics you cover with depth. The internal link layer communicates the relationships between those topics and the relative importance of each page. The technical layer — crawl depth, canonicalization, indexing rules — determines whether Google can even access what you’ve built.

    A site with great content and bad internal linking is like a library with excellent books and no card catalog. The information is there. Nobody can find it. Internal link mapping is how you build the card catalog.

    At Tygart Media, we build internal link maps as part of every site optimization engagement. The SEO Drift Detector we built for monitoring 18 client sites — which watches for ranking decay week over week — consistently flags internal link structure as one of the first places ranking drops originate. Fix the map, and the ranking often recovers on its own.

    Frequently Asked Questions About Internal Link Mapping

    What is the difference between internal links and external links?

    Internal links connect pages within the same website. External links (also called backlinks) point from one website to another. Internal links distribute authority you already have across your own site. External links bring new authority in from outside. Both matter for SEO, but internal links are entirely within your control.

    How many internal links should a page have?

    There’s no hard rule, but most SEO practitioners recommend 2-5 contextual internal links per 1,000 words of content. More important than quantity is relevance — each internal link should point to content that genuinely extends what the reader just learned. Stuffing 20 links into a 600-word post helps no one.

    How often should I audit my internal link structure?

    For active content sites, a full internal link audit every six months is reasonable. Smaller sites can often get away with an annual audit plus a quick check whenever new content is published. The higher your publishing frequency, the more often orphan pages accumulate. Set a calendar reminder — you’ll always find problems worth fixing.

    Can internal linking hurt my SEO?

    Over-optimized anchor text (every link using the exact same keyword phrase) can look manipulative to Google. Excessive linking on a single page (dozens of links in the body) dilutes the value of each individual link. Linking to low-quality or irrelevant pages from important pages can also be a mild negative signal. The goal is natural, useful internal linking — not engineered at every opportunity.

    What is a hub-and-spoke internal link structure?

    A hub-and-spoke structure groups content into topic clusters. The hub (or pillar page) covers a broad topic comprehensively and receives internal links from all related spoke pages. Each spoke page covers a subtopic in depth and links back to the hub. This architecture signals topical authority to Google and creates a clear navigational hierarchy for users.

    What is an orphan page in SEO?

    An orphan page is any page on your website that has no internal links pointing to it. Orphan pages are difficult for Google to discover and rarely accumulate authority. They’re a common byproduct of frequent publishing without a documented internal linking strategy. Finding and linking to orphan pages is one of the fastest low-effort SEO wins available on most established sites.

  • SEO Website Architecture: Why Your Site is a Database

    SEO Website Architecture: Why Your Site is a Database

    The Machine Room · Under the Hood

    Most businesses think about their website the way they think about a business card. You design it once, print it, hand it out. It says who you are and how to reach you. Every few years, maybe you update it.

    This mental model is why most websites don’t work.

    A website is not a brochure. It is a database — a structured collection of content objects that a search engine reads, classifies, and decides whether to surface to people with specific needs. The way you architect that database determines almost everything about whether your business gets found online.

    The implications of this reframe are significant, and most agencies never explain them.

    What Search Engines Actually Do With Your Site

    When Google crawls your website, it’s not admiring the design. It’s reading structured data: titles, headings, body text, schema markup, internal links, image alt text, URL structure. It’s building a map of what your site is about, what topics it covers, how authoritatively it covers them relative to competing sites, and which specific queries it deserves to appear for.

    A brochure website gives Google almost nothing to work with. One services page that lists everything you do. An about page. A contact form. Maybe a blog with eight posts from 2021.

    Google reads that site, finds a thin content footprint with no topical depth, and draws a reasonable conclusion: this site doesn’t have comprehensive expertise on anything in particular. It will not rank for competitive terms.

    A database website is architected differently. Every service gets its own page with its own keyword target. Every service area gets its own page. Every question a customer might have gets an answer. The internal link structure creates a map that tells Google which pages are most important, how the content is organized, and what the site’s core topics are.

    This is not a design question. It’s an architecture question.

    The JSON-First Content Model

    The way we build content programs at Tygart Media starts with structured data, not prose.

    Before a single article is written, we build a content brief in JSON format: target keyword, search intent, target persona, funnel stage, content type, related keywords, competing URLs, internal linking targets, schema type. Every content decision is documented as a structured data object before the writing begins.

    This matters for a few reasons.

    First, it forces clarity. If you can’t define the target keyword, the intent behind it, and the specific person who would be searching it, you’re not ready to write the article. Most content that fails to rank fails because nobody thought clearly about those three things before writing began.

    Second, it makes the content pipeline scalable. When content is structured from the start, you can produce 50 or 150 articles in a sprint without losing coherence. Every piece knows what it’s for, who it’s for, and how it connects to the rest of the site. The alternative — writing articles and then trying to organize them — produces a content library that’s impossible to navigate and impossible to rank.

    Third, it enables automation without sacrificing quality. The brief is the seed. Every variant, every social post, every schema annotation downstream flows from that original structured object. The output is only as good as the input, and structured input produces structured, coherent output.

    Taxonomy Is Architecture

    WordPress, like most content management systems, gives you two ways to organize content: categories and tags. Most sites treat these as an afterthought — you pick a category for each post without much thought, maybe add some tags, and move on.

    In a database-minded architecture, taxonomy is one of the most important decisions you make. Categories define the topical pillars of your site. Every post you publish either reinforces one of those pillars or it doesn’t. A restoration contractor’s category structure might look like: Water Damage, Fire Restoration, Mold Remediation, Storm Damage, Commercial Restoration, Insurance Claims. Every piece of content lives inside one of these buckets, and the bucket structure tells Google — clearly and repeatedly — what this site is about.

    Tags create the cross-cutting relationships. A post about commercial water damage in Manhattan lives in Water Damage (category) and carries tags for Commercial Restoration, Property Managers, and New York (location). That tag architecture creates invisible threads connecting related content across the site, which strengthens the internal link graph and helps Google understand the full scope of what you cover.

    Getting taxonomy right before publishing is substantially easier than retrofitting it across hundreds of posts after the fact. We’ve done both. The retrofit takes three times as long and produces half the results.

    Internal Links Are the Database’s Index

    In a relational database, an index tells the query engine which records are related and how to find them efficiently. Internal links serve the same function in a content database.

    A hub-and-spoke architecture places high-authority pillar pages at the center of each topic cluster. Every supporting article on that topic links back to the pillar. The pillar links out to the supporting articles. Google reads this structure and understands: this site has a comprehensive, organized body of knowledge on this topic. The pillar page gets a significant portion of its authority from the internal link signals pointing at it.

    Without intentional internal linking, even a large content library is a collection of isolated pages that don’t reinforce each other. Each page competes as an island. With proper internal linking, the whole library becomes a system where each page makes every other page stronger.

    This is why the order of operations matters. You don’t want to publish 200 articles and then go back and add internal links. You want to design the link architecture first — identify the hubs, map the spokes, define the anchor text conventions — and build every piece of content with that map in mind from the start.

    Schema Markup: Telling the Database What Type Each Record Is

    Every record in a database has a type. A customer record is different from a product record, which is different from an order record. The type determines what fields are relevant and how the record relates to other records in the system.

    Schema markup does this for web content. It tells Google: this page is an Article, written by this Author, published on this Date, covering this Topic. Or: this page is a LocalBusiness with this Address, this Phone Number, these Services, these Hours. Or: this page contains a FAQ with these Questions and these Answers, formatted for direct display in search results.

    Without schema, Google has to infer all of this from the raw text. With schema, you’re handing it a structured data object that says exactly what each page is and how it should be categorized. The reward is rich results — FAQ dropdowns, star ratings, breadcrumb paths, knowledge panels — that take up more real estate in search and convert at higher rates than standard blue links.

    Schema is the metadata layer of the content database. Most sites don’t have it. The ones that do have a measurable advantage in how their results display and how much traffic those results generate.

    The Practical Difference

    Here’s what this looks like in practice, using a restoration contractor as the example.

    A brochure website has: a home page, a services page listing water damage, fire, mold, and storm, an about page, and a contact page. Maybe 5 pages total. Google has almost nothing to index.

    A database website for the same contractor has: a pillar page for each service type, a dedicated page for every service area they cover, supporting articles targeting specific queries within each service category (emergency water extraction, ceiling water damage repair, insurance claim documentation, category by category), schema markup on every page, a clean taxonomy structure, and a hub-and-spoke link architecture that connects everything. Potentially 200 to 400 pages, each doing a specific job.

    The brochure site is invisible. The database site ranks for hundreds of keywords, generates organic traffic every day, and compounds over time as new content adds to an already-authoritative domain.

    The content is not the hard part. The architecture is. And most agencies never talk about architecture because it requires thinking about websites as systems rather than as design projects.

    That’s the reframe. Your website is a database. Build it like one.


    Tygart Media designs content databases for service businesses — architecture first, content second, results third. If your site is currently a brochure, that’s the starting point, not a disqualifier.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Your Website Is a Database, Not a Brochure”,
    “description”: “Most agencies design websites like brochures. The ones that actually rank are built like databases — with architecture, taxonomy, schema, and internal linking d”,
    “datePublished”: “2026-04-02”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/website-is-a-database-not-a-brochure/”
    }
    }