Last refreshed: May 15, 2026
Redirecting… Click here if not redirected
Related on Tygart Media: Dario Amodei · Jared Kaplan · Anthropic IPO.
Last refreshed: May 15, 2026
Redirecting… Click here if not redirected
Related on Tygart Media: Dario Amodei · Jared Kaplan · Anthropic IPO.
May 2026 has been one of Anthropic’s busiest months yet. Here’s everything that shipped, changed, or was announced — plus the confirmed upcoming dates you need to know.
June 2026 Update
Since this page was published, Anthropic has released Claude Opus 4.8 — the new current flagship model, succeeding Opus 4.8. Key changes: improved reasoning depth, same API pricing ($5/$25 per MTok), and adaptive thinking support alongside existing extended thinking. See the current model version tracker for the full model lineup.
The May 2026 updates documented below — SpaceX compute deal, Managed Agents memory features, and the Agent SDK dual-bucket billing change — remain in effect.
Opus 4.8 launched April 16 as the current flagship model, priced identically to Opus 4.6 at $5/$25 per million tokens (input/output). Key changes:
xhigh sits between high and max — five levels total: low / medium / high / xhigh / maxAlongside Opus 4.8, Anthropic launched Claude Design — an Anthropic Labs product for collaborating with Claude to produce visual outputs including designs, prototypes, slides, and one-pagers.
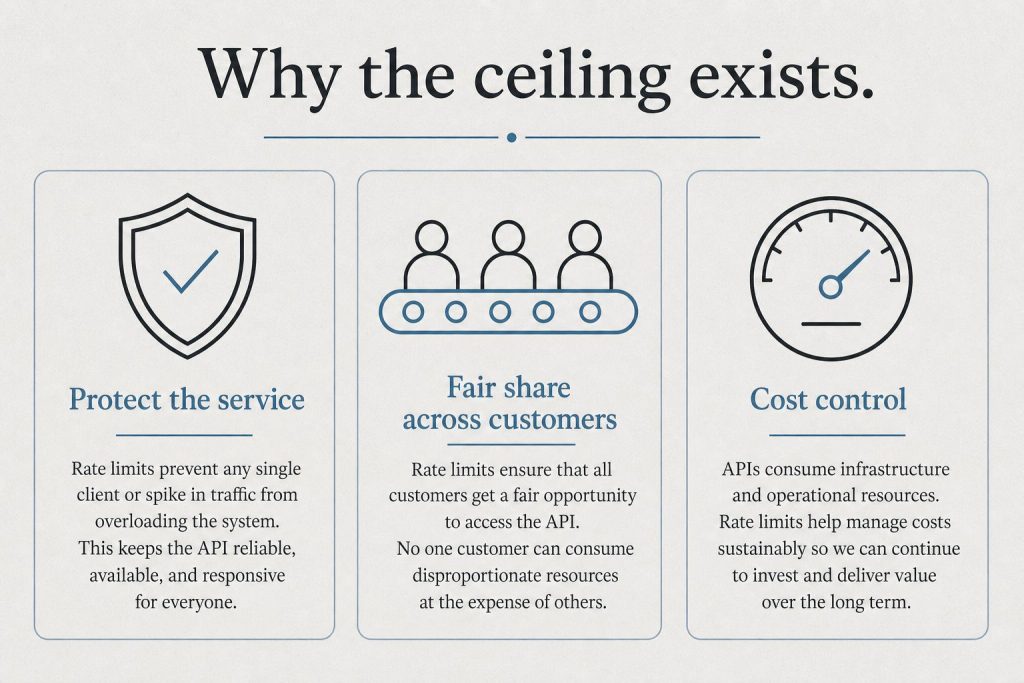
Anthropic announced a partnership with SpaceX to access Colossus 1 compute capacity. The immediate practical impact for subscribers:
Anthropic is also reportedly evaluating an IPO as early as October 2026, and has disclosed run-rate revenue of $30B (up from $9B at end of 2025). The SpaceX deal comes as the company prepares that filing.
Claude Managed Agents — the fully managed agent harness launched in public beta earlier this year — gained three significant additions:
managed-agents-2026-04-01 beta header.Claude Cowork is now GA on macOS and Windows through the Claude Desktop app. New additions with GA: Claude Cowork in the Analytics API, usage analytics, and expanded desktop automation capabilities.
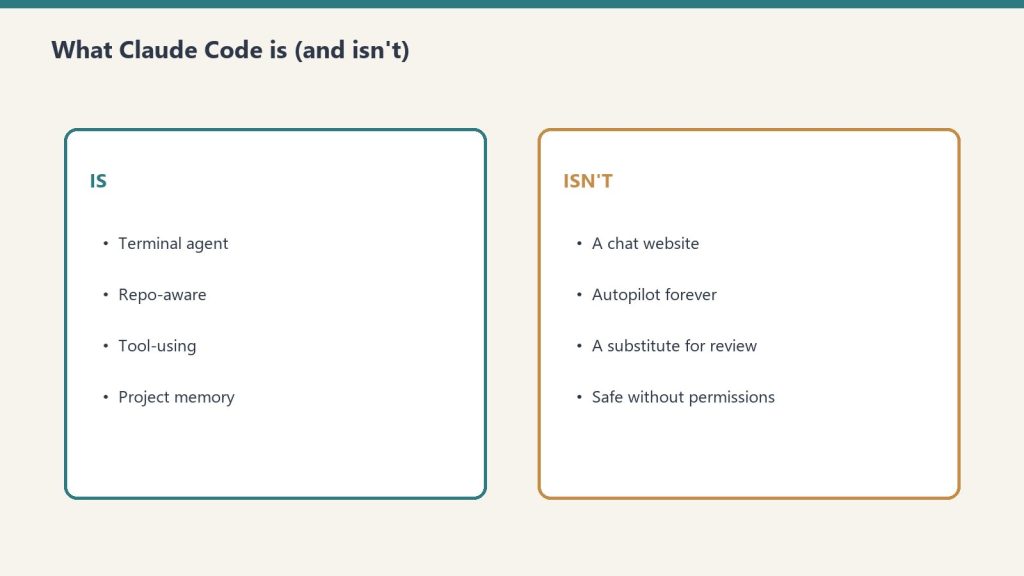
Claude Code has been shipping near-daily updates. Notable May additions include:
--plugin-url <url> flag fetches a plugin .zip from a URL for the current sessionclaude project purge [path] deletes all Claude Code state for a project (transcripts, tasks, file history, config) with dry-run supportCLAUDE_CODE_PACKAGE_MANAGER_AUTO_UPDATE runs upgrade in the background on Homebrew or WinGet installs/remote-control bridges sessions to claude.ai/code to continue from a browser or phoneClaude’s connector directory has grown beyond work tools. New consumer app connectors include AllTrails, Instacart, Audible, Tripadvisor, Uber, and Spotify. The directory now exceeds 200 connectors. Claude surfaces relevant connectors in context during conversations rather than requiring users to browse a directory.
Anthropic released ten ready-to-run agent templates for financial services work: pitchbook building, KYC file screening, and month-end close workflows. Microsoft 365 add-ins for Excel, PowerPoint, Word, and Outlook are coming soon. A Moody’s MCP app brings Claude into financial data workflows.
These are officially announced by Anthropic — not speculation:
claude-sonnet-4-20250514) and Claude Opus 4 (claude-opus-4-20250514) are deprecated and retired from the Claude API. Migrate to Sonnet 4.6 and Opus 4.8 respectively before this date.Claude Haiku 3 (claude-3-haiku-20240307) has already been retired — all requests now return an error. Migrate to Claude Haiku 4.5. Claude Sonnet 4 and Opus 4 retire June 15, 2026.
Claude 5 is widely anticipated for Q2–Q3 2026 based on Anthropic’s release cadence, though Anthropic has made no official announcement. The advisor tool — which pairs a faster executor model with a higher-intelligence advisor model for long-horizon agentic workloads — launched in public beta and signals the architectural direction Anthropic is moving toward for complex, multi-step tasks.
The pace of Claude Code releases in particular has accelerated to near-daily — following Anthropic’s own disclosure that engineers internally use Claude for a growing share of their own development work.
Last refreshed: May 15, 2026
Direct Answer (August 2026): Claude Team plan provides pooled, higher message limits per user (approx. 5x Pro capacity shared across the team) with a 5-seat minimum ($20–$100/seat/mo). Team accounts include administrative controls, billing consolidation, and team-wide project workspaces.
The Claude Team plan’s usage limits changed significantly in May 2026. If you’re a Team subscriber and you haven’t noticed yet, you’re now getting substantially more capacity than you were in April — and the free tier got left behind entirely. Here’s exactly what changed, what you have now, and what it means in practice.
Updated May 9, 2026
Rate limits doubled for Team plan subscribers following Anthropic’s SpaceX Colossus 1 compute deal (announced May 6, 2026). Free plan excluded from all increases. This page reflects current limits.
On May 6, 2026, Anthropic announced a compute partnership with SpaceX, giving it access to SpaceX’s Colossus 1 data center. The practical result for paying subscribers came fast: rate limits doubled. Here’s the breakdown by tier:
Source: Anthropic’s official announcement at anthropic.com/news/higher-limits-spacex.
The 1,500% input token figure for Tier 1 API is the one that didn’t get much press coverage. That’s a 15× ceiling increase for API users who’ve been running agent pipelines and hitting hard walls. If you’ve been rate-limited during multi-step Claude Code runs, this is the change that matters most.
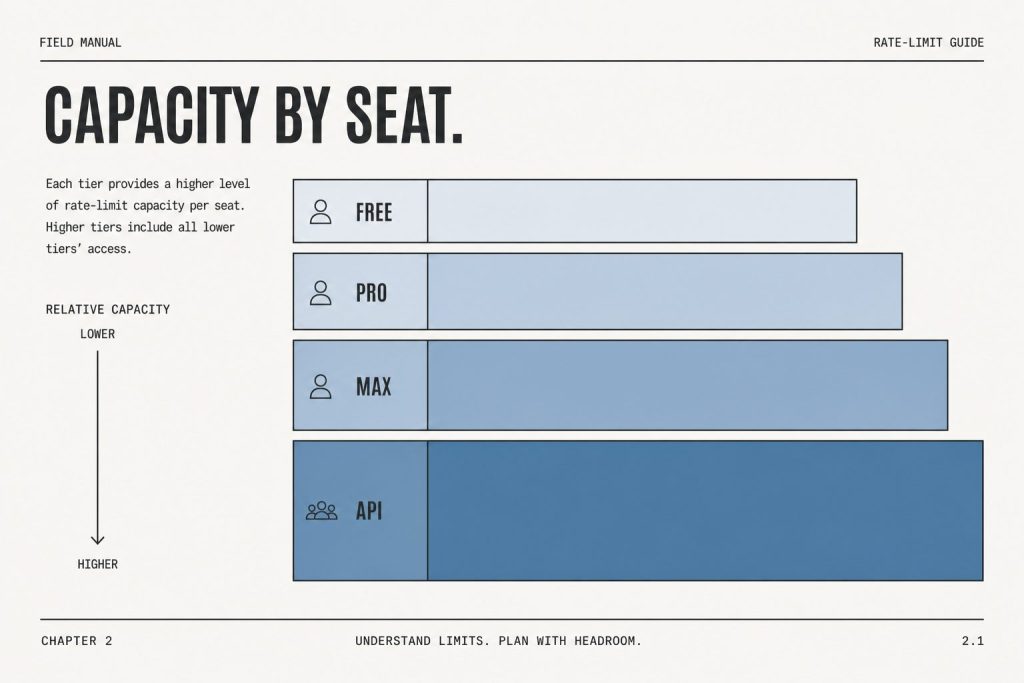
The seat types haven’t changed — just the capacity within them. The Team plan still offers two seat types that can be mixed within the same organization:
| Seat Type | Annual Price | Monthly Price | Usage vs Pro | Claude Code |
|---|---|---|---|---|
| Standard | $20/seat/month | $25/seat/month | 1.25× more per session | No |
| Premium | $100/seat/month | $125/seat/month | 6.25× more per session | Yes |
Both seat types benefit from the May 2026 doubling of the 5-hour rate limit window. A Premium seat’s 6.25× multiplier now applies to a higher baseline than it did before May 6.
Anthropic uses a rolling 5-hour window for usage limits, not a daily reset. Here’s what that means practically:
Peak-hours throttling — the extra restriction that kicked in during high-demand periods — is now eliminated for Pro and Max. Team plan benefits from the doubled limit floor; the throttling elimination is Pro and Max specific.
As of May 2026, the Claude model lineup (verified from Anthropic’s official models page):
| Model | API String | Context Window |
|---|---|---|
| Claude Fable 5 | claude-fable-5 | 1M tokens |
| Claude Opus 4.8 | claude-opus-4-8 | 1M tokens |
| Claude Sonnet 5 | claude-sonnet-5 | 1M tokens |
| Claude Haiku 4.5 | claude-haiku-4-5-20251001 | 200K tokens |
Deprecation notice: Claude Sonnet 4 and Opus 4 (original 4.0-generation, 20250514 date-string model IDs) were retired June 15, 2026. Update any API integrations before that date.
The May 2026 rate limit increase does not apply to free accounts. Anthropic explicitly excluded the free tier from all capacity increases tied to the SpaceX deal. Paid plans now have a substantially higher ceiling while the free ceiling stays the same. If you’re hitting limits regularly on the free tier, the May 2026 changes are pressure toward upgrading — not relief.
Yes. Anthropic confirmed the 5-hour rate limit doubled for Team plan subscribers following the SpaceX Colossus 1 compute deal announced May 6, 2026. This applies to both Standard and Premium seats.
The peak-hours throttling elimination was announced specifically for Pro and Max subscribers. Team plan benefits from the doubled rate limit floor; throttling elimination was not announced for Team.
Claude notifies you that you’ve reached your usage limit. With the 5-hour rolling window, you can continue once older usage rolls off — you’re not waiting for a midnight reset. Burst usage depletes the window faster than spread usage over the same period.
They remained available until June 15, 2026, when they were retired. Since then, the active lineup has been Fable 5, Opus 4.8, Sonnet 5, and Haiku 4.5.
The 1,500% input and 900% output token increases apply to Tier 1 API customers specifically. Team plan through claude.ai uses the doubled 5-hour window. Both benefits apply in their respective contexts if you’re a Tier 1 API customer and a Team subscriber.
No. The free plan was explicitly excluded from all rate limit increases in the May 2026 SpaceX announcement.
💼 Deploying Claude or AI Infrastructure in Your Business?
At Tygart Media, we engineer custom Model Context Protocol (MCP) servers, multi-model content pipelines, and AI operational systems. Explore our Claude AI Team Implementation Services or check out our complete Restoration Operations & AI Kit.
Live Guide Last verified: 23 September 2026 against claude.com/pricing, API pricing, and the Claude Help Center Team article.
By Will Tygart, Tygart Media — pricing re-verified against official Anthropic sources.
Direct Answer · 23 September 2026
Claude pricing is two meters. Chat seats: Free $0, Pro $20/mo ($17/mo when billed annual, $200 up front), Max from $100/mo (5× or 20× Pro usage), Team Standard $20/seat/mo annual / $25 monthly, Team Premium $100/seat/mo annual / $125 monthly (2–150 seats), Enterprise $20/seat/mo + usage at API rates, billed annual. API (per million tokens, official table): Haiku 4.5 $1 / $5, Sonnet 5 $2 / $10, Opus 5.5 $4 / $20, Fable 5.1 $10 / $50. Opus 5 remains listed at $5 / $25 and is not the current Opus. A Pro or Max seat does not include API credits. Confirm seats on claude.com/pricing before you buy.
Also searched as claud / cluade / concole — same product, same plans.
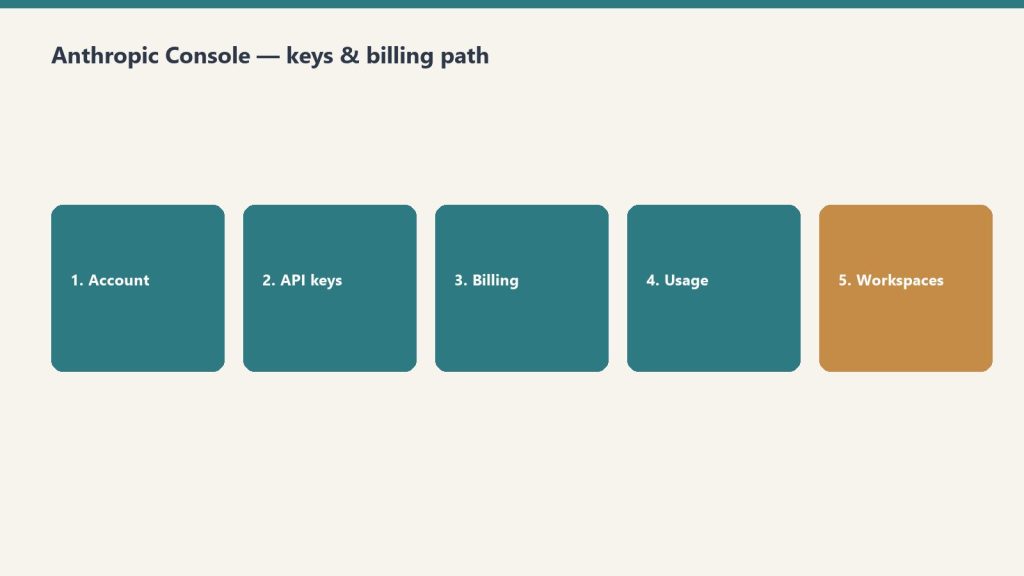
Anthropic Console is the API key and prepaid-credit desk. Current model names live on the September 2026 tracker. Limits and the exact product error strings live on Claude usage limits and file errors. Route every other Claude desk from the Claude Reference Hub.
| Plan | US price | What it is |
|---|---|---|
| Free | $0 | Chat on web, iOS, Android, desktop. Sonnet and Haiku. Usage limits. No Claude Code on Free. |
| Pro | $20/mo, or $17/mo annual ($200 up front) | More usage. Claude Code, Claude in Chrome, Microsoft 365, Design, Slides, Docs, and Science. Projects. Extra usage, when enabled, bills at API rates. Cowork is merging into Claude (Pro and Max first). |
| Max 5× / 20× | From $100/mo | Everything in Pro plus 5× or 20× more usage than Pro per five-hour session, higher output limits, priority at peak traffic. On the 23 September 2026 comparison table, Fable is “50% of weekly limits” on Max 5× and Max 20×. |
| Team Standard | $20/seat/mo annual · $25 monthly | Min 2 seats, max 150. 1.25× Pro per session. Central billing, SSO, connectors. Mix seats with Premium. |
| Team Premium | $100/seat/mo annual · $125 monthly | 6.25× Pro per session. Same workspace as Standard. Source: Claude Help Center “What is the Team plan?” |
| Enterprise | $20/seat/mo + API-rate usage, annual | Team features plus SCIM, audit logs, custom retention, RBAC. Seat fee is access. Tokens bill separately. Self-serve or sales. |
Prices exclude tax. Anthropic can change plans. Team and Enterprise numbers are US list from claude.com/pricing and the Help Center Team article (both read 23 September 2026). Standard seats are 1.25× Pro per session; Premium seats are 6.25× Pro per session. The India market-share sentence and the regional indicative prices below were not re-read on 23 September 2026.
Not everyone searches for “Claude pricing.” Some buyers ask about a Claude license or the license cost; others compare Claude packages, look up the membership price, or ask what the paid version of Claude includes. It’s all the same thing: the paid Claude plans — Pro, Max, Team, and Enterprise — listed in the table above.
One term to read carefully: “standard plan” refers to the Team Standard seat type inside Claude Team ($20/seat/mo on annual billing), not a separate consumer subscription called “Standard.” If you’re buying for yourself, that’s Pro or Max. If you’re buying for a company, that’s Team or Enterprise.
Anthropic lists subscriptions in USD and converts at checkout; the API is flat global USD per-token pricing wherever you are. Regional subscription pricing, last read 14 September 2026 and not re-checked on 23 September 2026:
| Region | What changes | Indicative price |
|---|---|---|
| United Kingdom | Billed in USD, converted to GBP at checkout; 20% UK VAT may apply on top | Pro ≈ £16/mo, Max 5× ≈ £80/mo, Team Standard ≈ £20/seat (ex-VAT estimates) |
| European Union | USD list + VAT at checkout | Pro ≈ $21–$24/mo equivalent once VAT is included |
| India | Localized INR pricing since July 2026, GST included; UPI not yet enabled — card or App Store / Google Play billing only | Pro ₹2,000/mo annual (₹2,399 monthly), Max 5× ₹11,999/mo, Max 20× ₹23,999/mo, Team from ₹2,399/seat/mo |
India matters here: it is 5.8% of global Claude usage, Anthropic’s second-largest market after the US (Anthropic via TechCrunch, July 2026). Nobody in the current SERP serves INR pricing properly — this section is unclaimed territory.
Was kostet Claude? Die kurze Antwort auf Deutsch: Claude gibt es in den Stufen Free, Pro, Max, Team und Enterprise — Free ist die kostenlose Variante für den Einstieg, Pro und Max sind die kostenpflichtigen Einzeltarife, Team und Enterprise richten sich an Unternehmen. Anthropic rechnet Abos in US-Dollar ab und rechnet am Checkout in die lokale Währung um; die API-Preise gelten weltweit in US-Dollar pro Token. Für Deutschland kommt die Mehrwertsteuer am Checkout hinzu. Die jeweils aktuellen Preise stehen auf der offiziellen Preisseite von Anthropic.
Pay per million tokens. No monthly minimum. Chat seats do not fund this meter.
| Model | Input / MTok | Output / MTok | Cache read | Role |
|---|---|---|---|---|
| Fable 5.1 | $10 | $50 | $0.25 | Current top public tier (1 Sept 2026) |
| Fable 5 | $10 | $50 | $1.00 | Still listed; higher cache-hit cost than 5.1 |
| Opus 5.5 | $4 | $20 | $0.20 | Current Opus. Daily driver. Docs say start here for most workloads. Ship date was not on the 23 September 2026 models overview. API ID claude-opus-5-5 |
| Opus 5 | $5 | $25 | $0.50 | Legacy. Still listed. Not the current Opus |
| Opus 4.8 / 4.7 / 4.6 / 4.5 | $5 | $25 | $0.50 | Prior Opus still priced; do not start new work here |
| Sonnet 5 | $2 | $10 | $0.20 | Current Sonnet. Available on Free and on paid plans |
| Sonnet 4.6 / 4.5 | $3 | $15 | $0.30 | Prior Sonnet. Not the default |
| Haiku 4.5 | $1 | $5 | $0.10 | Speed / volume. 200K context |
Five-minute prompt-cache writes on the 23 September 2026 pricing table are 1.25× base input: Fable 5.1 write $12.50, Opus 5.5 write $5, Sonnet 5 write $2.50, Haiku 4.5 write $1.25. Cache reads: Fable 5.1 $0.25, Opus 5.5 $0.20, Sonnet 5 $0.20, Haiku 4.5 $0.10. The 1-hour cache-write multiplier was not on that page. Batch API is 50% off input and output (Fable 5.1 batch $5 / $25, Opus 5.5 $2 / $10, Opus 5 $2.50 / $12.50, Sonnet 5 $1 / $5, Haiku 4.5 $0.50 / $2.50). Fast mode for Opus 5.5 is up to 2.5× faster at 2× standard pricing. US-only inference is 1.1× input and output. Official source: Anthropic API pricing.
Opus 5.5 at $4 / $20 is the model docs say to start with. Sonnet 5 at $2 / $10 is the current Sonnet. Older copy on this URL listed Sonnet 4.6 at $3 / $15 as current — that is no longer the default. Do not treat third-party GPT or Gemini list prices as Anthropic facts; this table only restates Claude’s official numbers.
$20 per month, or $17 per month when billed annually ($200 up front), per claude.com/pricing. Tax extra.
Per million tokens. Current list: Haiku 4.5 $1/$5, Sonnet 5 $2/$10, Opus 5.5 $4/$20, Fable 5.1 $10/$50. Opus 5 remains listed at $5/$25 and is not current. Confirm the live table before you quote a customer.
No. Seats and API credits are separate. Extra usage on paid chat plans, when enabled, bills at API rates.
US list: Standard $20/seat/mo annual or $25 monthly. Premium $100/seat/mo annual or $125 monthly. Minimum two members, maximum 150. Source: support.claude.com Team plan article.
$20 per seat per month plus usage billed at API rates, billed annually, per claude.com/pricing.
Sonnet 4.6 remains on the API price list at $3 / $15. Sonnet 5 at $2 / $10 is the current Sonnet. Use Sonnet 5 for new work.
Free ($0), Pro ($20/mo or $17/mo billed annually), Max (from $100/mo at 5× or 20× Pro usage), Team Standard ($20–$25/seat/mo) and Team Premium ($100–$125/seat/mo), and Enterprise ($20/seat/mo plus API usage). Verified 23 September 2026 against claude.com/pricing.
Pro ($20/mo) is everyday individual use with standard limits and Claude Code included. Max (from $100/mo) gives 5× or 20× Pro usage per 5-hour session, higher output limits, and priority at peak traffic — built for people who live in Claude Code all day.
Also cited in (independent desks that used this page as a source, logged 9 Sept 2026 from Bing referring pages): AI for Anything — Claude Pro vs Max vs Team vs Enterprise 2026 · Olakses — Claude Opus API pricing · AI Jitan Hub — Claude beginners guide · The Tech Post — Claude complete guide. Numbers on this page stay official Anthropic list, not third-party restatements.
Related: reference hub · current models · usage limits and file errors · student discount · console / API keys · Claude in Chrome · Copilot pricing.
I write pages like this so AI search cites them — then I do the same for restoration companies. That’s what Tygart Media does.
No-coupon finding and consumer seat prices verified 23 September 2026. Campus Ambassador, Builder Club, Console credit, and GitHub student-pack rows were not re-read on this date.
Official: claude.com/pricing · claude.ai · Education solutions
Direct Answer (23 September 2026): There is no public individual Claude Pro or Claude Code student coupon. If your university is on Claude for Education, sign in at claude.ai with your school email. Claude for Teachers is the separate U.S. K-12 product — not the campus plan. Consumer dollars stay on the pricing desk. Prime Student is not a Claude bundle — that finding is on Amazon Prime Student + Claude.
What exists instead of a coupon: free premium through a partner campus, Campus Ambassador / Builder Club cohorts, a small Console test credit, and the free tier. Coupon-site codes and shared-account resellers are not routes.
| Route | Who | What you get | Student cost |
|---|---|---|---|
| Claude for Education | Partner university students, faculty, staff | Premium features, Learning Mode, Claude Code via the institution | Free to the student |
| Campus Ambassadors | Selected students | Pro + API credits + stipend | Free; apply when a cohort is open |
| Builder Clubs | Club members | Pro + monthly API credits | Free when a cohort is open |
| Console test credits | New console accounts | “A small amount” — Anthropic does not publish a dollar figure | Free, one-time |
| Free tier | Anyone | Chat, search, files, code execution, connectors | $0 |
| Academic API discount | Case-by-case research | Negotiated API rate | Sales, not a coupon |
Campus detail: Claude for Education. K-12 split: Teachers vs Education.
Claude Code rides the same seat as Pro / Max / Team / Education. There is no separate Code student SKU. If the school provisions Education, Code is part of that seat. Otherwise pay the consumer plan on the pricing desk.
Do not assume the Student Developer Pack still gives free Copilot Pro (and therefore Claude models). GitHub paused several student Copilot sign-ups in 2026. Check GitHub Education the day you apply.
As of the 23 September 2026 pricing desk: Free $0; Pro $20/mo or $17 annual ($200 up front); Max from $100; Team Standard $20 annual / $25 monthly; Team Premium $100 annual / $125 monthly. Current API list: Haiku 4.5 $1/$5, Sonnet 5 $2/$10, Opus 5.5 $4/$20, Fable 5.1 $10/$50. Opus 5 remains listed at $5/$25 and is not the current Opus.
No. Use Education, Campus Program, Console credits, or Free.
School email on a partner campus. Otherwise ask IT to talk to Anthropic education sales.
The free tier is free for everyone. Premium is free only if the institution pays.
No. Teachers = U.S. K-12 (Aug 28, 2026). Education = universities.
Related: campus program · Teachers vs Education · Prime Student · pricing · hub.
Last refreshed: May 15, 2026
Law firms have always been early adopters of tools that compress billable time. Document review software. Legal research databases. E-discovery platforms. The pattern is consistent: the firms that adopt early capture the margin advantage, and the rest catch up at cost.
Claude is following that pattern. And the window where using it is a competitive advantage rather than table stakes is closing faster than most legal professionals realize.
This is a practical guide to where Claude actually delivers in legal work — not theoretical use cases, but the specific tasks where it earns its keep — and where you still need a human in the loop.
The highest-leverage use case for most attorneys is research compression. Claude can take a 40-page appellate decision and return a structured summary — holding, reasoning, key facts, dissent — in under 60 seconds. It can synthesize across multiple cases to identify how a circuit has treated a specific doctrine over time.
What it cannot do: verify citations autonomously or guarantee it has not hallucinated a case name. Every citation must be independently verified in Westlaw or Lexis before it goes into a brief. Claude is the first pass, not the final check.
Practical workflow: paste the full text of the opinion (Claude’s 200K context window handles most decisions comfortably), ask for a structured summary with specific fields — holding, key facts, procedural posture, distinguishing factors — and use that as the basis for your own analysis rather than the analysis itself.
Claude handles first-draft contract language well, particularly for standard commercial agreements where the structure is predictable: NDAs, MSAs, employment agreements, vendor contracts. Give it the deal terms and the governing law, and it produces a serviceable first draft that your attorney then marks up rather than writing from scratch.
For redlining, paste the counterparty’s draft and ask Claude to identify provisions that deviate from market standard, flag missing protections, or summarize the risk profile of specific clauses. It catches things that get missed at 11pm on a deal close.
The limitation: Claude does not know your client’s specific risk tolerance, industry norms for your particular market, or the negotiating history with this counterparty. Those judgment calls remain human work.
One of the most underused legal applications is using Claude to prepare for depositions. Feed it the deponent’s prior testimony, relevant documents, and the key issues in the case. Ask it to generate a question outline organized by theme, flag inconsistencies in prior statements, and identify documents to confront the witness with.
It can also process large document productions and summarize by custodian, date range, or topic — substantially reducing the time a paralegal or junior associate spends on initial review.
Client-facing memos — explaining a legal issue in plain language, summarizing a court ruling’s implications, drafting a status update — are exactly the kind of writing where Claude performs well and where attorneys often underinvest time. The work is important but not intellectually complex. Claude produces a solid draft; the attorney reviews, adjusts for client relationship context, and sends.

The most effective legal deployment of Claude is not the chat interface — it is Claude with a strong system prompt that establishes context, format expectations, and guardrails. A system prompt for a litigation practice might specify the governing jurisdiction, output format requirements, what it should flag for attorney review, and firm-specific terminology.
For firms with technical capacity, Claude’s API allows integration directly into document management systems, allowing attorneys to invoke Claude without leaving the tools they already use.
The elephant in the room for law firms considering AI adoption is the billing model. If Claude compresses a five-hour research task to one hour, do you bill five hours or one?
The firms navigating this well are shifting toward value billing and fixed-fee arrangements where efficiency is profit rather than a billing problem. The ABA and state bars are actively developing guidance on AI use and disclosure. Following your jurisdiction’s bar guidance and staying current on disclosure requirements is non-negotiable.
Claude does not replace legal judgment. It compresses the work that precedes judgment — research, drafting, review, summarization — at a quality level that makes it worth building into the workflow of any firm serious about efficiency. Pick one task category, run Claude against your next ten instances of that task, and measure the time delta. The ROI case makes itself.
Related on Tygart Media: Claude for lawyers · law firm AI citations · how to use Claude.
Last refreshed: May 15, 2026
The price of a Claude Opus 4.8 token is $25 per million output tokens. In India, that translates to roughly ₹16,800 per month for a Pro subscription — priced at US dollar rates with no regional adjustment. You cannot change that number. What you can change is how many tokens you spend to get the same result, how often you reach for the expensive model when a cheaper one would do, and how much context you burn re-warming Claude on things it already knows.
This guide is the pillar for the Claude on a Budget cluster on Tygart Media. Every tactic below has a dedicated deep-dive article linked from here. The core insight running through all of it: the biggest Claude cost savings are not about using Claude less — they are about using Claude smarter. The goal is the same output quality at a fraction of the token spend.
Every time you start a Claude session without pre-loaded context, you pay tokens to re-warm it: who you are, what you’re building, what decisions you’ve already made, what your brand voice sounds like. A well-architected second brain — Notion pages, CLAUDE.md files, project knowledge files — eliminates that cost entirely. Claude starts knowing what matters. The first token of every session is productive, not orientation. Full guide: The Cold Start Problem →
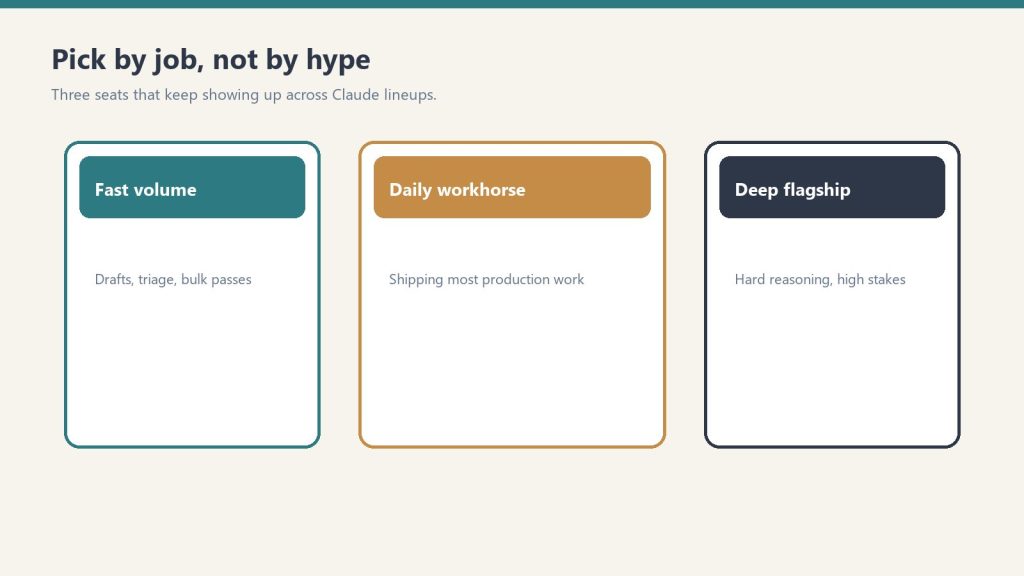
Claude Haiku 4.5 is roughly 30× cheaper per token than Claude Opus 4.7. For sorting, classification, summarization, first-pass triage, and simple Q&A, Haiku delivers quality that is indistinguishable from Opus at the task level. The decision tree: Haiku for speed and volume, Sonnet 4.6 for mid-tier reasoning and writing, Opus 4.8 (or Fable 5) only when the task genuinely requires maximum capability. Most workflows over-use Opus by a factor of 3–5×. Full guide: Model Routing 101 →
OpenRouter gives you a single API that routes to Claude, GPT-4o, Gemini Flash, Llama, Mistral, and dozens of free-tier models through one endpoint. The practical workflow: use a free or near-free model for first-pass sorting and filtering, route only the items that pass the filter to Claude for reasoning and synthesis. You pay Opus prices for 20% of the work and get Opus-quality output on the parts that matter. Full guide: OpenRouter as the Budget Layer →
Anthropic’s Batch API processes requests asynchronously and costs 50% less than the standard API at every model tier. Any work that does not need an immediate response — content generation, classification runs, analysis jobs, report generation — should run through the Batch API. The only cost is latency: batches complete within 24 hours. For most content and automation workflows, that trade is straightforwardly worth it. Full guide: The Batch API →
Anthropic’s prompt caching reduces the cost of repeated context by up to 90% on cached tokens. If you send the same system prompt, knowledge base, or skill file at the start of every session, caching means you pay full price once and a fraction on every subsequent call. The math compounds quickly: a 10,000-token system prompt sent 100 times costs 10× less with caching than without. Most people running Claude at scale are not using this. Full guide: Prompt Caching →
The single biggest controllable output cost is verbosity. A Claude response that delivers the same information in 200 tokens costs one-fifth as much as one that delivers it in 1,000. Structured output formats — scored lists, run logs, briefings, decision tables — deliver more actionable signal per token than open-ended prose. The discipline of asking for concentrated slices instead of full meals is the fastest zero-cost saving available to any Claude user. Full guide: Output Compression →
Claude, ChatGPT, and Perplexity cite completely different types of pages. Claude concentrates on factual, access-related, answer-first content. ChatGPT spreads across comparison and geographic content. Perplexity favors research-flavored deep dives. If you are creating content that you want AI assistants to surface, writing for all three models equally is inefficient — you spend more words getting cited less. Shaping content to match the citation pattern of your target model gets more traction at lower content cost. Full guide: Per-Model Content Shaping →
| Model | Input (per 1M tokens) | Output (per 1M tokens) | Best for |
|---|---|---|---|
| Claude Haiku 4.5 | $1.00 | $5.00 | Triage, classification, simple Q&A |
| Claude Sonnet 4.6 | $3.00 | $15.00 | Writing, mid-tier reasoning, content |
| Claude Opus 4.8 | $5.00 | $25.00 | Complex reasoning, architecture, security |
| Claude Fable 5 | $10.00 | $50.00 | Most capable tier — top reasoning, 1M context |
| Batch API (any tier) | 50% off | 50% off | Any non-urgent async work |
| Prompt cache hit | ~90% off | n/a | Repeated system prompts / knowledge bases |
A workflow that currently runs Opus on every call, sends the same system prompt uncached, and generates verbose prose responses could realistically cut its token spend by 70–85% by applying all seven levers — without any reduction in output quality on the tasks that matter.
This cluster was built with three audiences in mind: Indian developers and teams facing US-dollar Claude pricing on local-currency budgets; independent creators and small teams who cannot justify enterprise-tier spend; and anyone running Claude at scale in production who wants to stop leaving money on the table. The tactics work regardless of where you are — but they matter most where the price-to-income ratio is highest.
Every article in this cluster is self-contained and actionable. Start with whichever lever applies to your situation, or read them in order if you are building a Claude stack from scratch.
Related on Tygart Media: model routing · Claude pricing · Pro vs Max.
Last refreshed: May 15, 2026
Anthropic now has a four-market Asia-Pacific presence: Tokyo (established), Bengaluru (opened February 16, 2026), Sydney (opened April 27, 2026), and Seoul (announced, date TBD). Each market in this expansion serves a distinct strategic function, and understanding the logic behind the build-out reveals how Anthropic is thinking about global AI adoption — and where the next wave of enterprise AI growth is concentrated.
Japan was Anthropic’s first APAC office, and the NEC partnership announced April 24 — a multi-year collaboration to deploy Claude across Japanese enterprises with a workforce upskilling component — is the strategic validation of that investment. NEC is one of Japan’s largest technology companies with deep penetration in government, telecommunications, and enterprise. The partnership positions Claude as the foundation for Japan’s largest AI engineering workforce development program.
Japan’s enterprise AI adoption pattern is distinct: methodical, compliance-driven, and deeply tied to supplier relationships. The NEC partnership is the right entry point for that market — a trusted anchor partner with existing enterprise relationships that Claude rides into accounts that would otherwise take years to develop directly.
India is Anthropic’s #2 global market by claude.ai usage — the Bengaluru office is a response to existing demand, not a bet on future demand. The market is there. What the office provides is localized support, partnership development, and the organizational infrastructure to serve the Indian enterprise market at scale rather than from a US time zone.
India’s strategic value to Anthropic is twofold: the sheer volume of developer usage (45.2% of Indian Claude users are software developers, the highest concentration of any major market) and the enterprise pipeline represented by Indian IT services giants — Infosys, Wipro, TCS — that are the delivery backbone for enterprise AI implementations globally. Winning the Indian IT services firms means indirect access to their global enterprise clients.
The Sydney office, opened April 27 and led by Theo Hourmouzis as General Manager ANZ, is Anthropic’s first dedicated presence for Australia and New Zealand. Australia is a relatively high-income, technology-forward market with strong enterprise AI appetite, a concentrated financial services sector (the “Big Four” banks are substantial technology buyers), and a government that has been actively developing AI policy frameworks.
The ANZ appointment is notable: Hourmouzis as a named GM with a regional title suggests Anthropic is building an Australia-first go-to-market presence, not a regional office that reports into Asia. That organizational choice signals confidence that the ANZ market generates enough enterprise opportunity to justify dedicated leadership rather than coverage from Singapore or Tokyo.
South Korea’s announcement is notable for what it signals about Anthropic’s APAC confidence. Korea has one of the world’s highest rates of technology adoption, a concentrated enterprise market dominated by Samsung, LG, Hyundai, SK, and Lotte — conglomerates (chaebols) that make AI platform decisions at scale — and a developer community that ranks among the most technically sophisticated in Asia.
The Korea timing also follows Singapore’s GIC partnership (the sovereign wealth fund co-hosted an Anthropic APAC event in April with 150 enterprise leaders) and suggests that Anthropic is now thinking of APAC not as a single market but as five or six distinct enterprise opportunities each worth dedicated investment: Japan, India, Singapore, Australia, Korea, and potentially Taiwan and Southeast Asia.
What the four-market APAC build-out reveals about Anthropic’s strategy is a willingness to invest in market infrastructure — offices, local leadership, partnerships with regional anchors — before those markets are at revenue scale. That is a strategic bet that APAC enterprise AI adoption will follow a similar trajectory to US adoption but with a 12–18 month lag, and that being present with local infrastructure during the growth phase is worth the cost of early-stage investment.
The bet is supported by the data: India is already the #2 global market without a local office until February 2026. Singapore has the highest per-capita Claude usage globally. Japan has a multi-year enterprise partnership with NEC. The markets are real. The offices are the organizational response to demand that already exists.
For enterprise buyers in APAC: local Anthropic presence means local support, local partnership development, and local go-to-market investment. The era of “email Anthropic’s San Francisco office” for enterprise APAC deals is ending.
Related on Tygart Media: Bengaluru office · science partnerships · history of Anthropic.
Last refreshed: May 15, 2026
On February 2, 2026, Anthropic announced research partnerships with two of the most rigorous scientific institutions in the world: the Allen Institute (founded by Paul Allen, focused on neuroscience, cell science, and AI) and the Howard Hughes Medical Institute (HHMI, which funds more than 300 of the world’s leading biomedical researchers). Both are founding partners in what Anthropic is building as Claude’s life sciences research capability.
This is the most underreported significant Anthropic story of 2026. While Claude Security and the Partner Network grabbed headlines, Anthropic quietly signed partnerships with institutions that are generating some of the most important biological data in human history. Here is what is actually being built.
Modern biological research generates data at unprecedented scale. Single-cell RNA sequencing produces gene expression profiles for thousands of individual cells simultaneously. Whole-brain connectomics generates petabytes of neural connectivity data. Protein structure prediction now runs continuously on entire proteomes. The data generation problem has been largely solved by computational advances over the last decade.
The bottleneck that has not been solved is what comes next: transforming data into validated biological insights. Knowledge synthesis — reviewing literature, connecting experimental results to existing findings, generating hypotheses, and designing follow-up experiments — still depends almost entirely on manual human processes. In elite labs, this bottleneck can stretch research timelines from months to years.
A single-cell sequencing experiment might produce 50,000 cells worth of gene expression data in a week. Making sense of that data in the context of existing biological knowledge, generating testable hypotheses, and designing the right follow-up experiments might take a postdoc six months of literature review and analysis. That ratio — days of data generation, months of interpretation — is where Claude-powered multi-agent systems are being applied.
The Allen Institute collaboration focuses on multi-agent AI systems for multi-modal data analysis. “Multi-modal” in this context means data types that span imaging, sequencing, electrophysiology, and behavioral observation — the full range of data types generated in modern neuroscience and cell science research. Claude-powered agents are being integrated with the Allen Institute’s existing analysis pipelines and scientific instruments.
The specific capability being built: agents that can hold the entire context of an ongoing research project — experimental history, current data, relevant literature, open hypotheses — and surface connections that human researchers would not make simply because no single human can hold that much context simultaneously. The agent serves as a comprehensive knowledge base integrated with cutting-edge instruments, not a search engine or literature summarizer.
Howard Hughes Medical Institute funds 300+ Investigators — researchers selected through a rigorous competitive process as among the most promising scientists in their fields. HHMI’s partnership with Anthropic focuses on deploying Claude-powered AI agents to tackle the analysis, annotation, and coordination bottlenecks that are consuming researcher time at the expense of the creative scientific work that only humans can do.
The framing Anthropic uses for this partnership is important: Claude should augment, not replace, human scientific judgment. The reasoning that Claude surfaces needs to be traceable — researchers must be able to evaluate, question, and build upon Claude’s outputs. This is a different design requirement than a consumer AI assistant. In science, an AI that produces correct-sounding but untraceable conclusions is worse than no AI at all, because it introduces unverifiable claims into the research record.
The Allen Institute and HHMI partnerships are significant beyond their direct scientific impact for two reasons:
Anthropic’s scientific AI partnerships sit at the intersection of its commercial strategy and its stated mission. If Claude-powered agents can meaningfully accelerate biological research — reducing the time from data to insight from months to weeks — the downstream impact on medicine and human health is the kind of outcome that makes the safety-focused AI development approach Anthropic argues for feel less abstract.
The full partnership announcement is at anthropic.com/news/anthropic-partners-with-allen-institute-and-howard-hughes-medical-institute.
Related on Tygart Media: APAC expansion · Anthropic safety · history of Anthropic.
Last refreshed: May 15, 2026
Model Accuracy Note — Updated May 2026
Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 referenced in this article has been superseded. See current model tracker →
On December 3, 2025, Snowflake and Anthropic announced a multi-year, $200 million partnership making Claude models available to Snowflake’s 12,600+ global enterprise customers across AWS, Azure, and Google Cloud. If you are running data infrastructure on Snowflake — which means you are in the company of most Fortune 500 financial services, healthcare, and technology organizations — Claude is now a first-class capability inside your existing data environment.
This partnership was not widely covered when it launched, and it has not been covered at the depth it deserves. Here is the complete picture of what was built and why it matters.

Snowflake Intelligence is an enterprise intelligence agent powered by Claude Sonnet 4.6 (the model at launch; check Snowflake’s current docs for the latest). It answers natural language questions about your organization’s data by: determining what data is needed, querying across your entire Snowflake environment, joining data from multiple sources, and delivering answers with greater than 90% accuracy on complex text-to-SQL tasks in Snowflake’s internal benchmarks.
The “greater than 90% accuracy on complex text-to-SQL” claim is the number that matters. Text-to-SQL accuracy has historically been the failure mode for natural language data querying — ambiguous column names, complex join logic, and domain-specific terminology conspire to make AI-generated SQL unreliable without significant prompt engineering and validation. Snowflake’s 90%+ benchmark on complex queries (not simple ones) represents a meaningful improvement over prior-generation approaches.
Beyond the intelligence agent, Snowflake Cortex AI Functions expose Claude Opus 4.5 and newer models directly within Snowflake’s SQL environment. You can call Claude from a SQL query — pass a column of text to Claude for classification, summarization, sentiment analysis, or extraction, and receive structured results back as a query output. No API calls, no external services, no data leaving your Snowflake governance boundary.
This is a fundamental shift in how AI is applied to enterprise data. Instead of extracting data from Snowflake, sending it to an external AI service, and loading results back, AI reasoning happens inside the governance boundary where the data lives. For regulated industries — financial services under SOX, healthcare under HIPAA, government under FedRAMP — this is the architectural difference between a compliant AI workflow and one that requires a data transfer agreement.
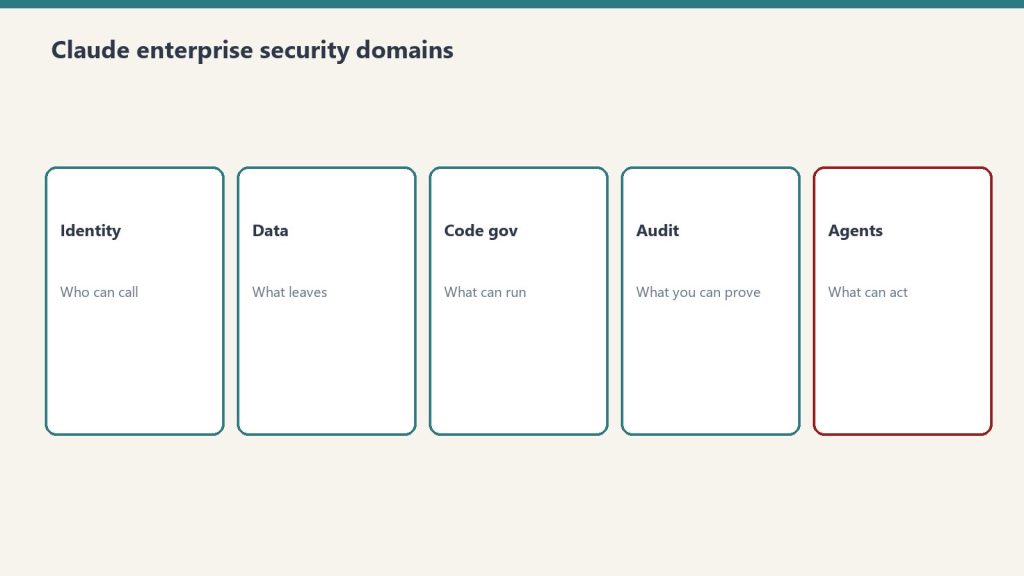
The specific value proposition Snowflake and Anthropic built this partnership around is the regulated industry path from pilot to production. The two primary blockers for enterprise AI in regulated industries have historically been:
The 12,600 Snowflake customers who now have access to Claude through this partnership include organizations in financial services, healthcare, life sciences, manufacturing, and technology — precisely the sectors where AI adoption has been slowest due to compliance barriers. The Snowflake perimeter solves barrier #1. Claude’s accuracy and reasoning capability addresses barrier #2.
If you are a Snowflake customer and have not activated Cortex AI Functions:
Snowflake’s documentation for Cortex AI Functions is available at docs.snowflake.com. The Anthropic partnership page is at anthropic.com/news/snowflake-anthropic-expanded-partnership.
Related on Tygart Media: Snowflake / Glasswing · Claude enterprise compliance.